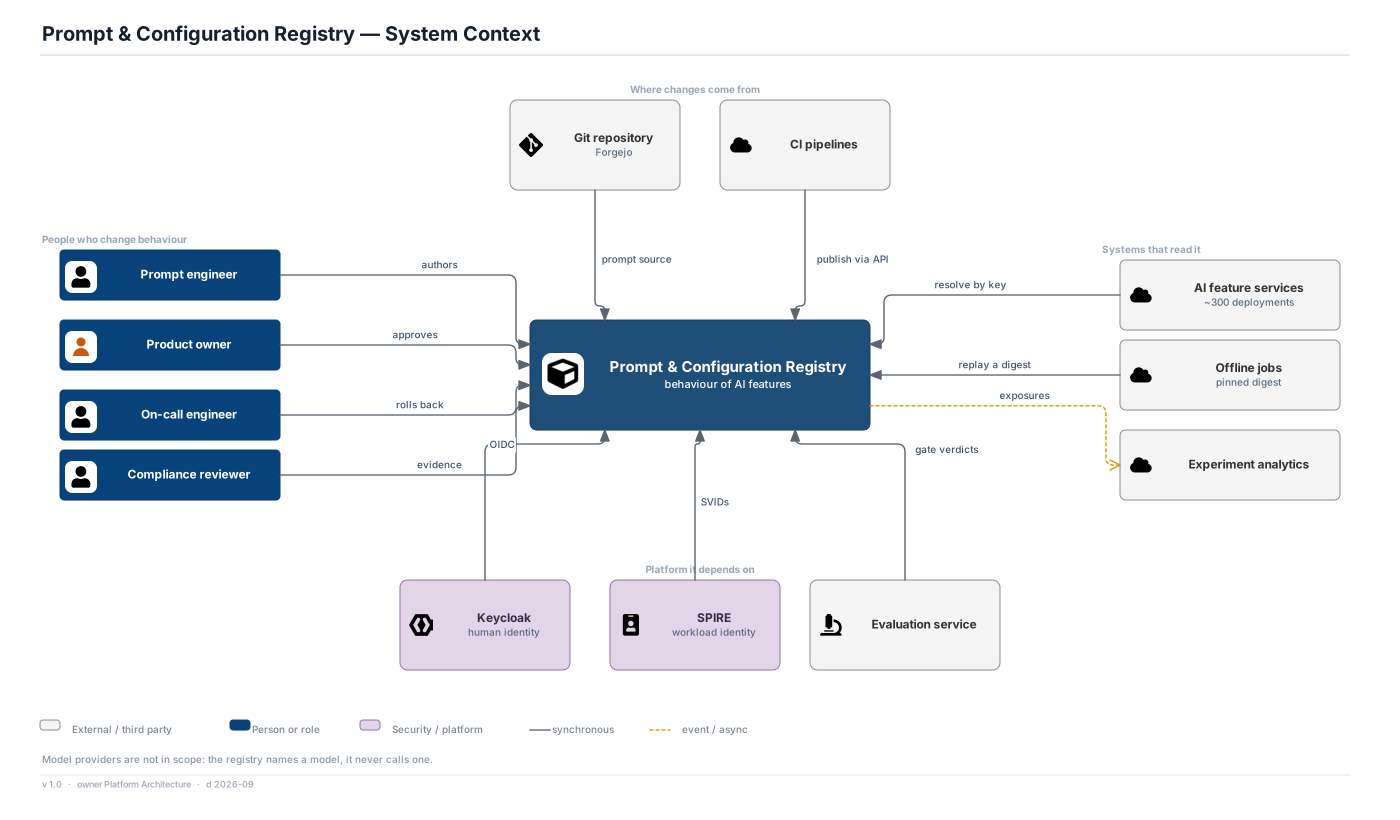
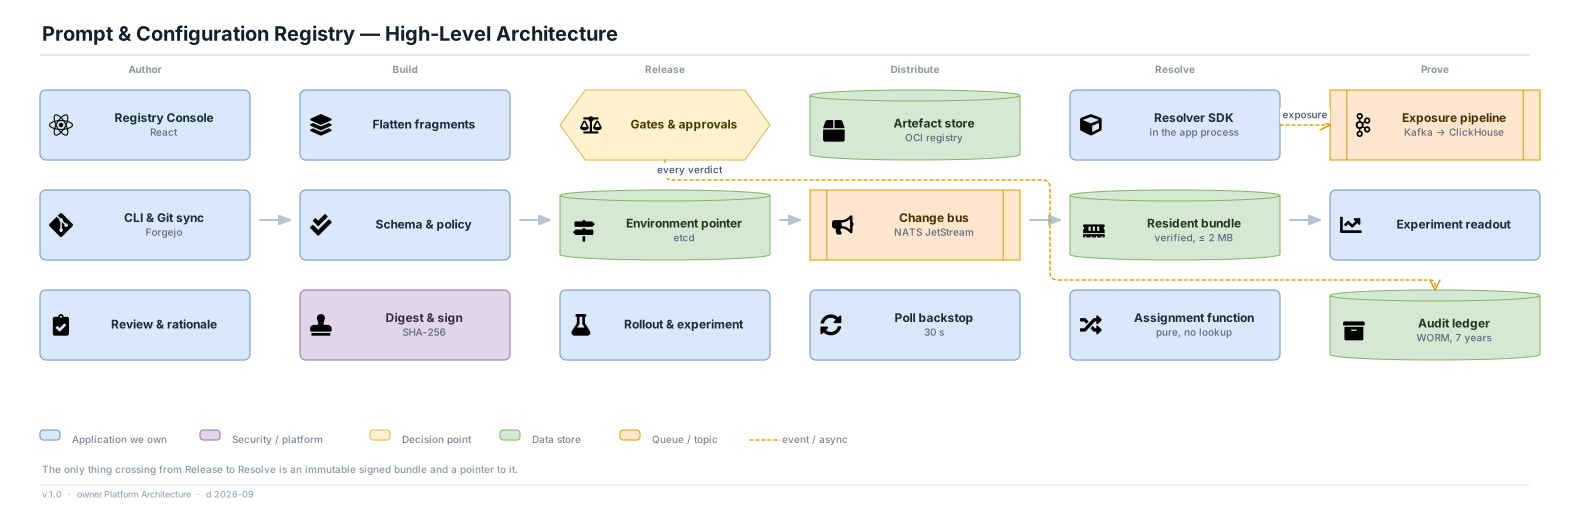
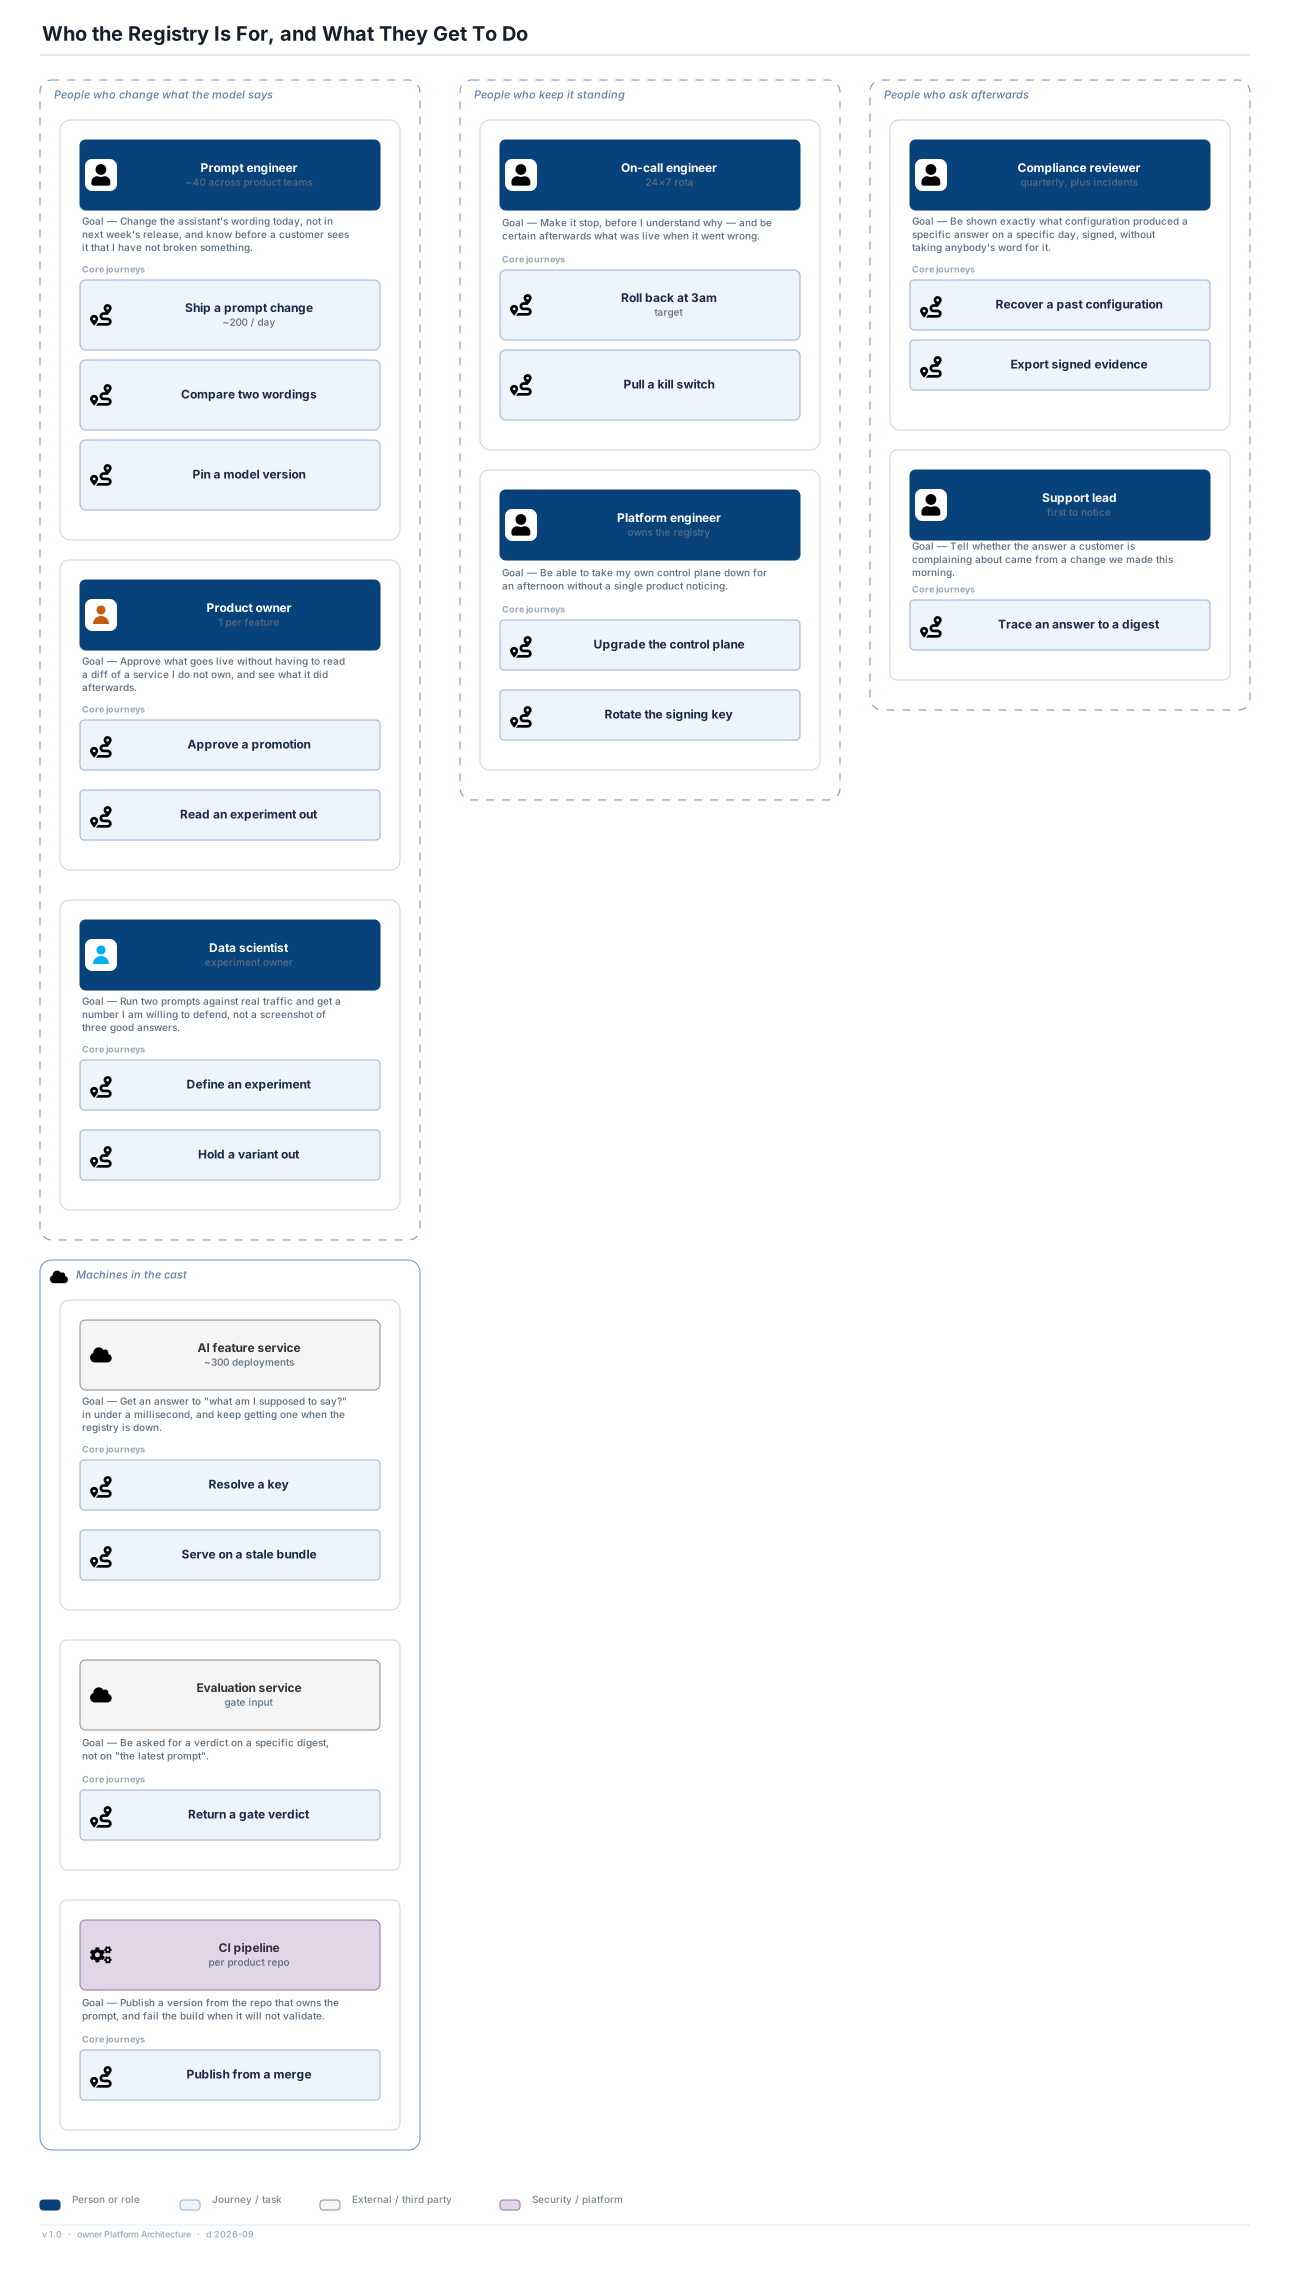
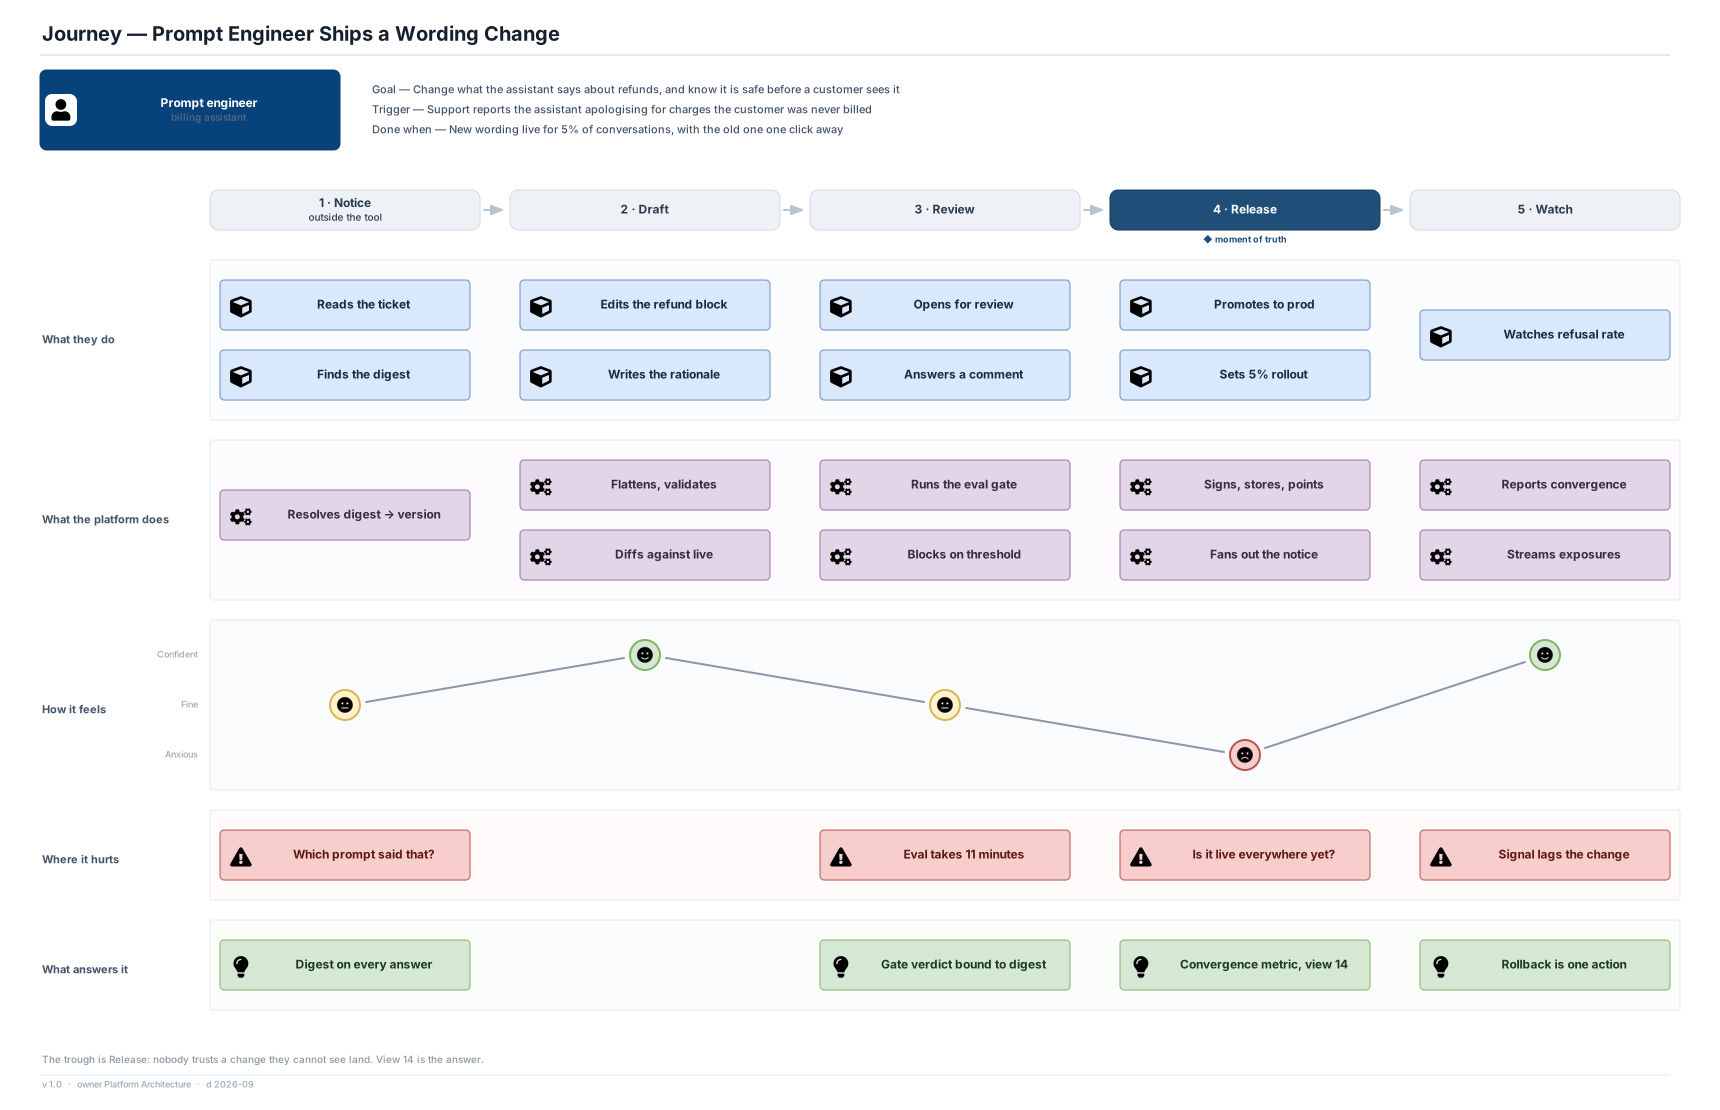
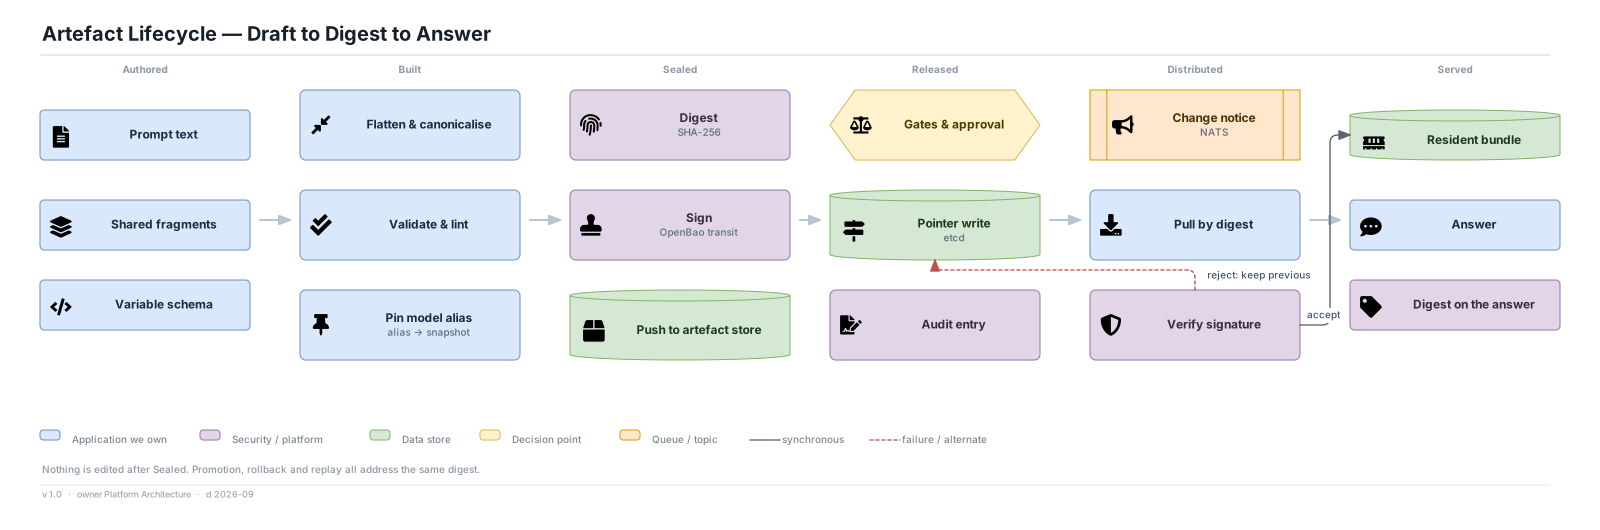
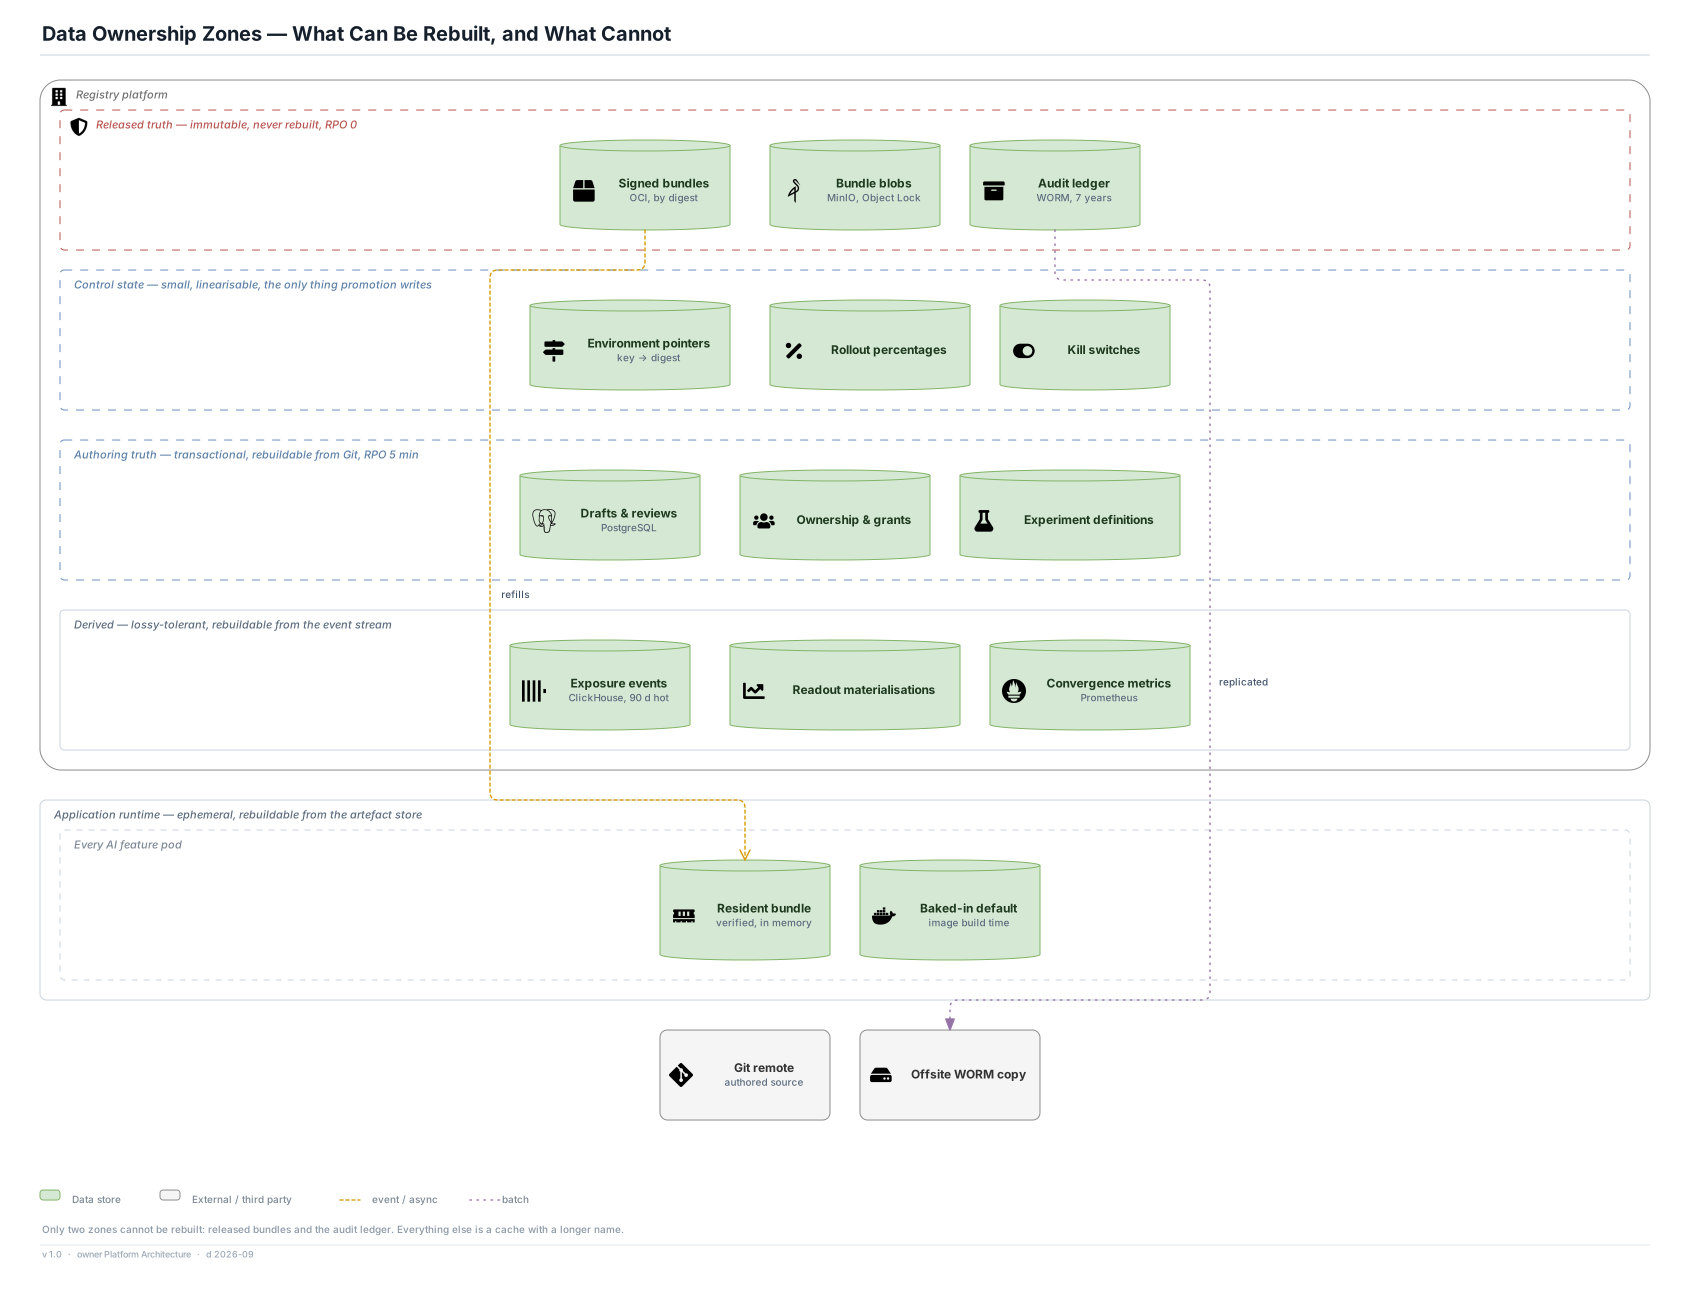
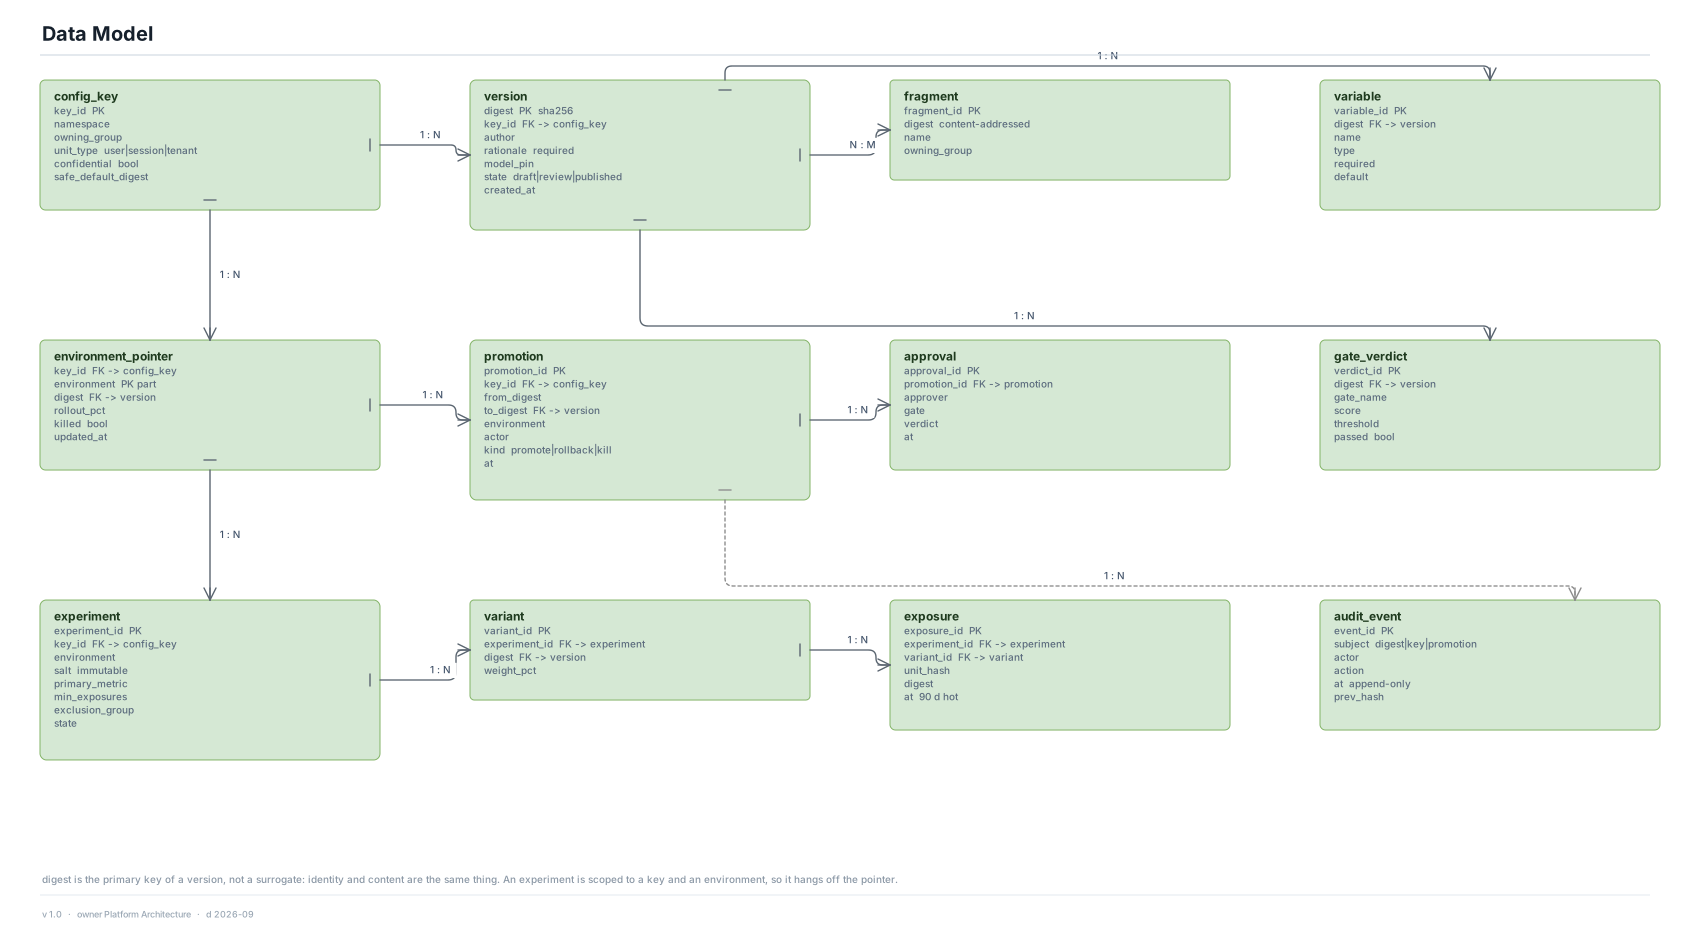
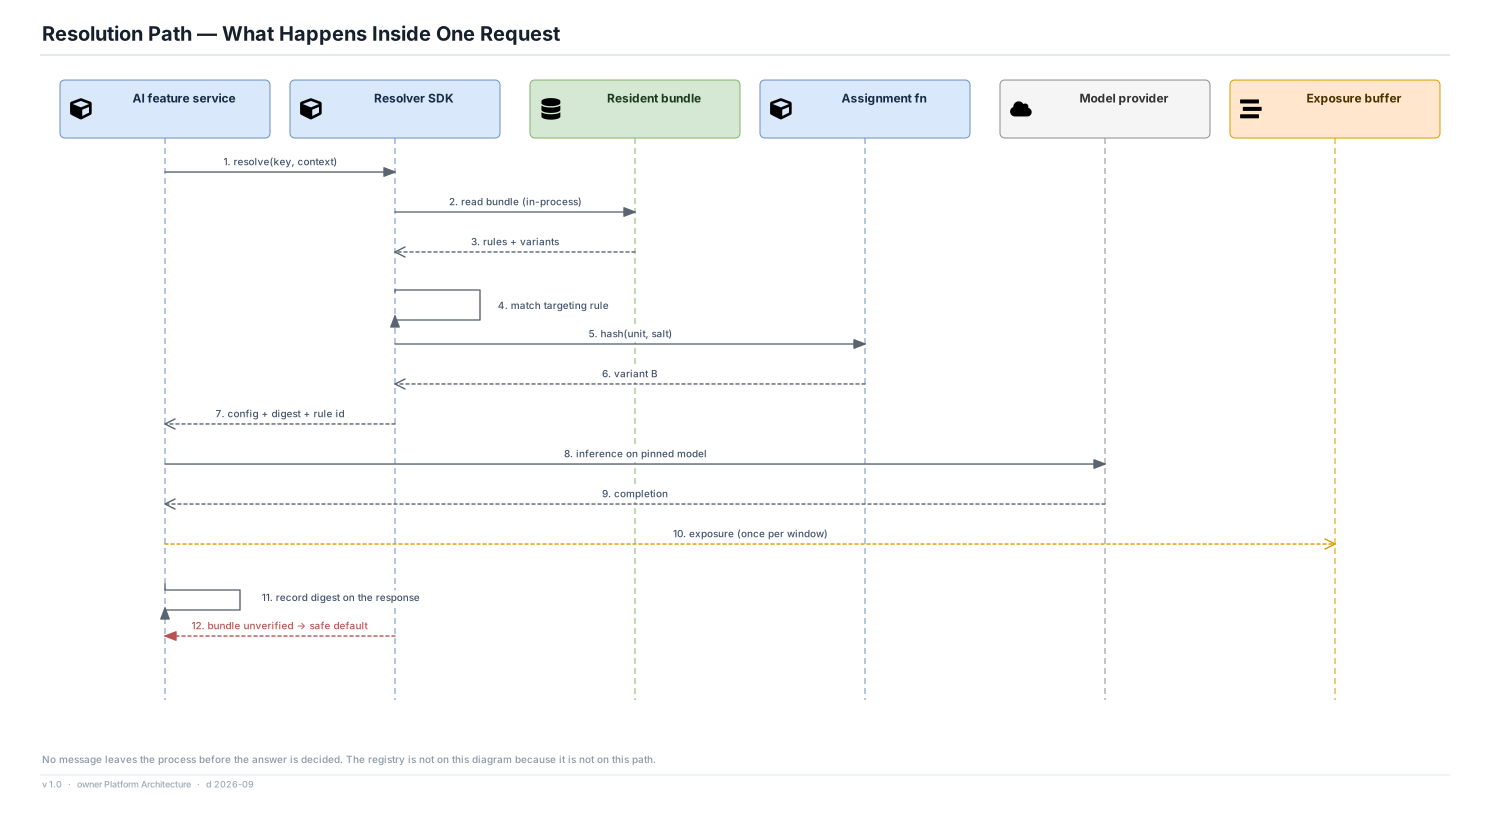
Prompt & Configuration Registry · Solution Architecture v1.0 · open source, self-hosted on Kubernetes · Platform Architecture · 2026-09 · 21 views · 17 architecture decision records
The argument these decisions serve is summarised in the Architecture One-Pager.
Seventeen decisions make up this architecture. Everything else across the twenty-one views is convention, sizing or consequence. Each record states the forcing question, the context that makes it hard, what was decided, how it is realised on a self-hosted open-source stack, the options weighed, what the choice buys and costs, the conditions that would flip it, why it should still be right in ten years, and the lesson that transfers to a system that is not this one.
Status of this document. This is a design, not a report on a running system. The rates, latencies, volumes, retentions and thresholds are the requirement's stated assumptions for a mid-sized organisation running AI features across a few hundred services — 2,000 configuration keys, 25,000 published versions in year one, ≈ 300 consuming deployments, 40,000 resolutions/second per region, 500 million exposure events a day — invented to be defensible and arguable rather than absent, and to be replaced by measured traffic before build. Four of them are the first numbers real data should overturn: the 2 MB bundle ceiling, which is what makes a fully resident bundle affordable and therefore makes the whole boundary viable; the 10 s / 60 s propagation SLO, which decides whether push is load-bearing or merely an optimisation; the ≤ 0.1% assignment-stability budget, which is what an experiment's validity actually rests on; and the 11-minute evaluation latency, which decides whether the eval gate sits inside the promotion flow or in front of it.
How to read a record
- Question: The forcing question: why a decision was needed at all.
- Context: The requirement, the scale and the constraint that make it hard.
- Decision: What this architecture does, stated so it can be checked.
- How it is realised on Google Cloud: The concrete mechanism: which service or package, configured how, in which project.
- Options weighed: Chosen, rejected, deferred, or right elsewhere, with the reason for each.
- Consequences: What the choice buys and what it costs, both kept visible.
- Choose differently when: The conditions that would flip the decision for your system.
- Why it holds up over time: What keeps the decision right as scale, staff and technology change.
- Lesson: The principle that transfers beyond this platform.
Decision map
The boundary: What a request is allowed to depend on, where resolution executes, and what happens when the thing it depends on is unreachable.
- ADR-01 · The resolution plane never reads the authoring store
- ADR-02 · Resolution is a library in the application process, not a sidecar or a service
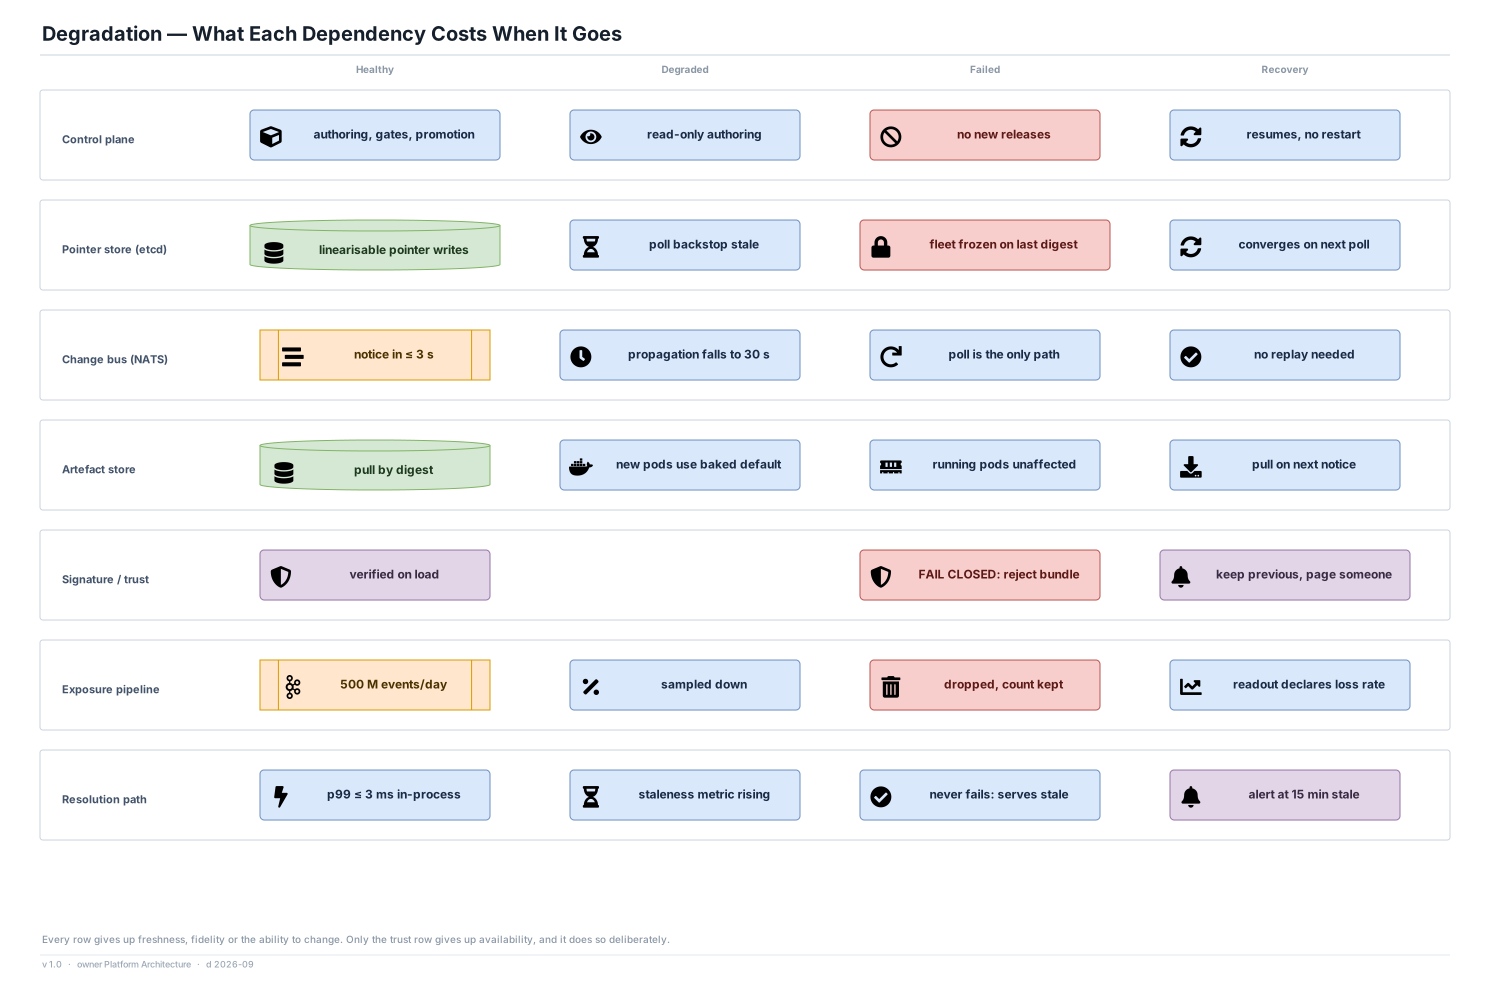
- ADR-03 · Availability failures fail static; integrity failures fail closed
The artefact: What is actually distributed, what its identity is, and why every hard question about correctness is answered before it is built rather than while it is being read.
- ADR-06 · A version's identity is its content digest, stored as an OCI artefact
- ADR-07 · The unit of distribution is a whole-environment bundle with a hard size ceiling
- ADR-08 · All validation happens at build time; the resolver validates nothing
- ADR-13 · Model aliases are resolved and pinned at build time
Release and reversal: How a change becomes live, how it stops being live, and why those are the same operation pointed in opposite directions.
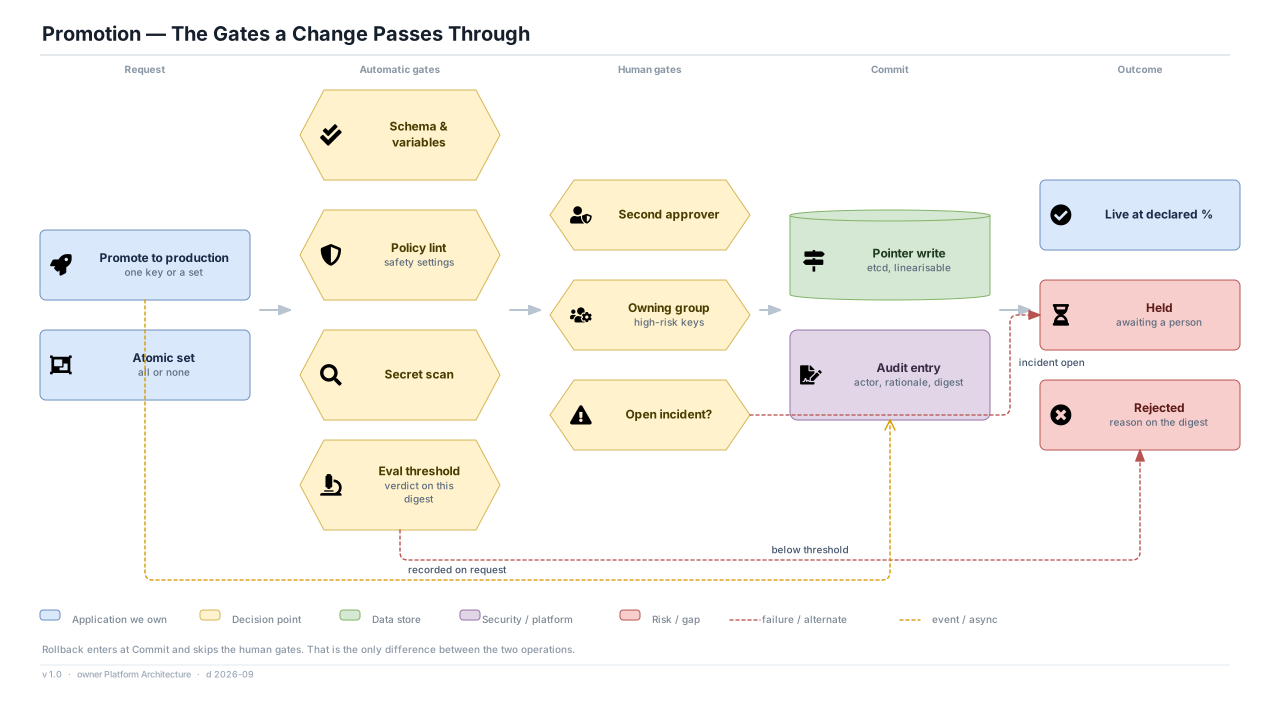
- ADR-04 · Rollback is promotion run backwards, with no approval gate
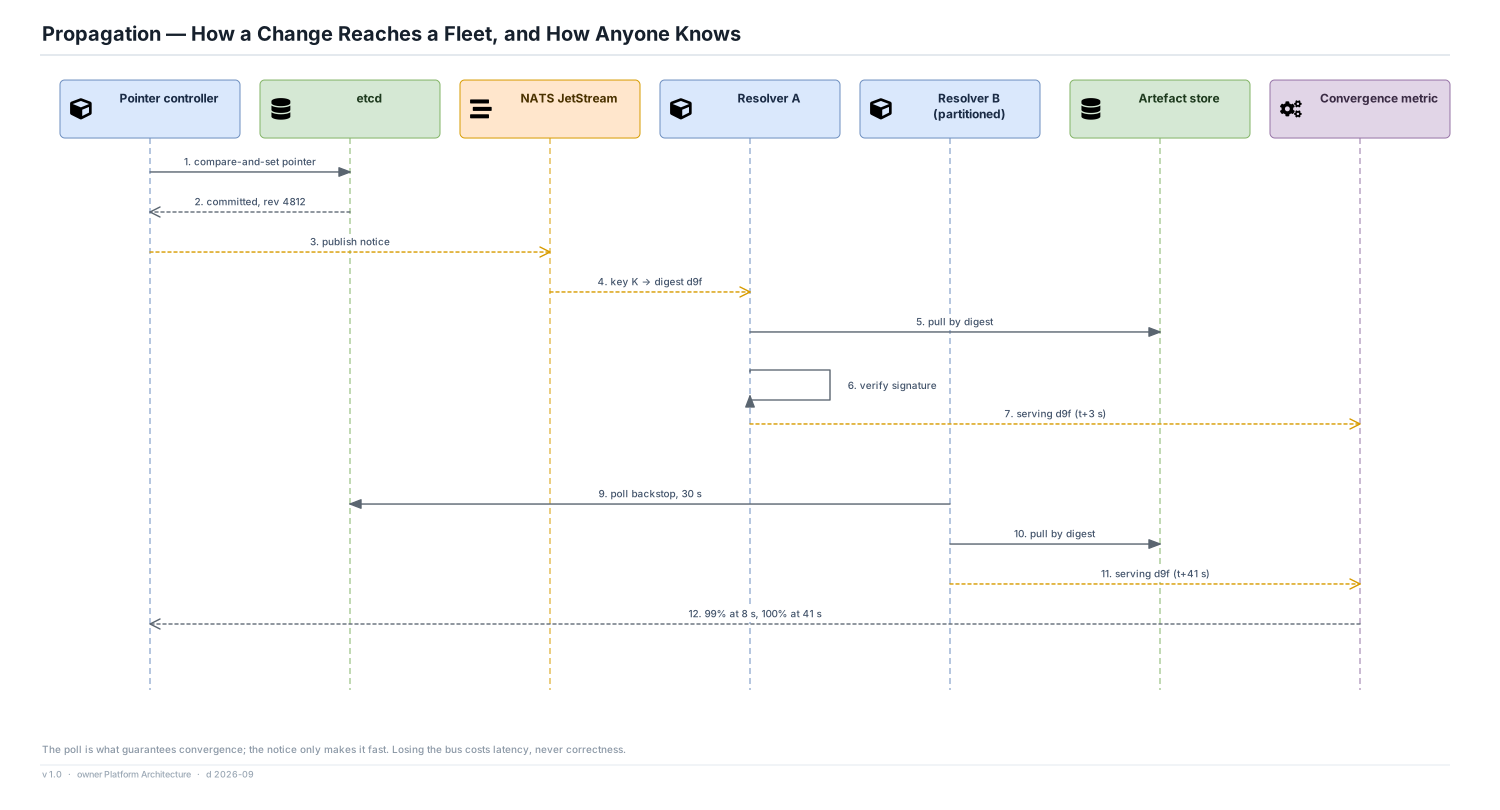
- ADR-05 · The poll guarantees convergence; the notice only makes it fast
- ADR-17 · One writable site; the secondary carries artefacts and cannot promote
Experiments and evidence: How two prompts are compared against real traffic, and what is kept afterwards so the comparison — and any single answer — can be defended.
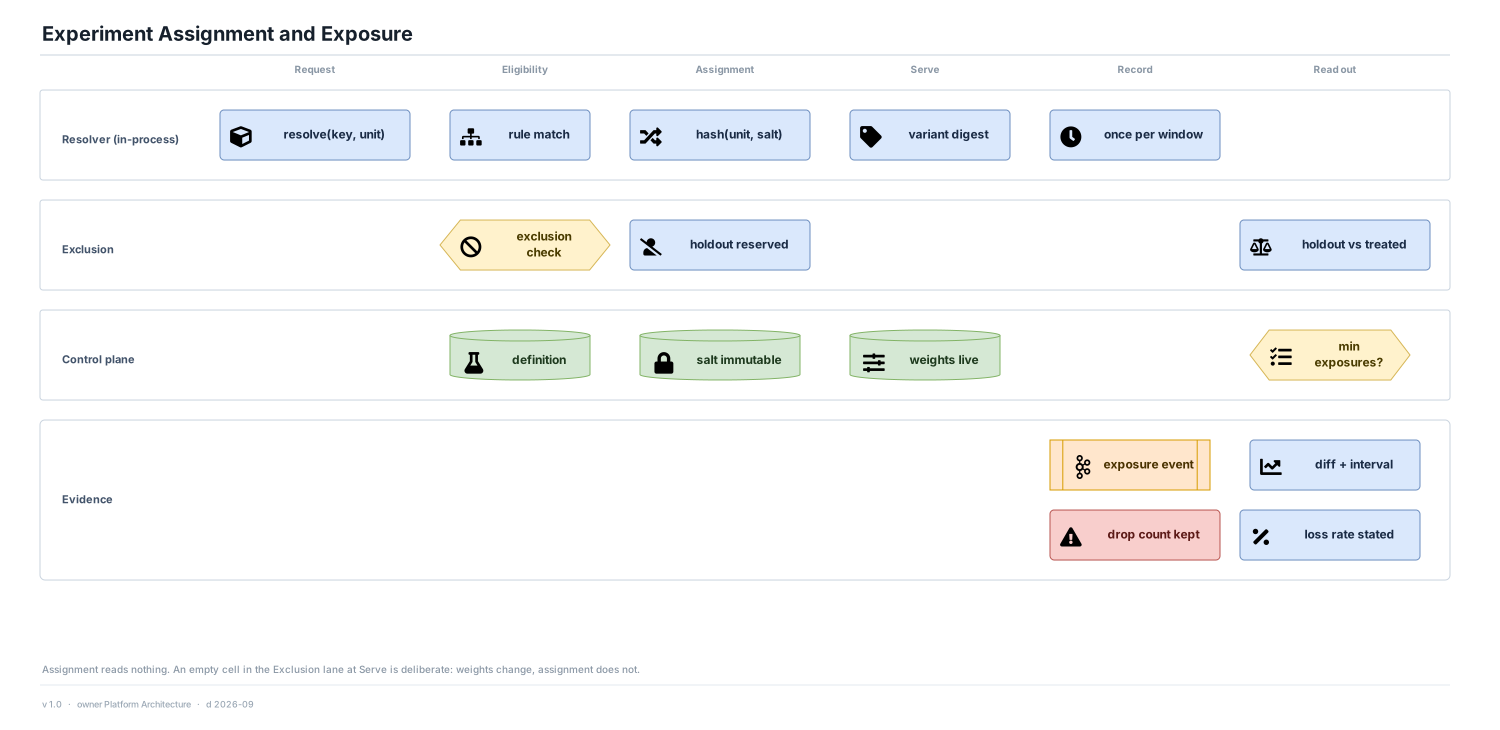
- ADR-09 · Variant assignment is a pure function of unit and salt
- ADR-10 · The registry owns prompt-experiment assignment for now, and states the trigger to hand it over
- ADR-14 · Reproducibility retains the digest, not the rendered prompt
- ADR-15 · A guardrail breach pages a human; it does not roll back automatically
- ADR-16 · Exposure telemetry is droppable and declares its loss; the audit ledger is not and does not
Trust and custody: Who may change what, who signs, and what a compromised component is able to reach.
- ADR-11 · Authoring, approval and promotion are three separate grants
- ADR-12 · Bundles are signed with a sign-only role, and trust distribution leads key rotation
Technology by capability
Every capability mapped to what realises it, what the obvious alternative was, and why the choice fell where it did. An open-source, self-hosted stack was chosen for stack rotation across this practice — the six use cases before this one all ran on a hyperscaler — and because this topic belongs to no cloud: the hard parts are content-addressed versioning and fan-out, which open-source primitives express directly, and teams keep prompts off third-party SaaS for reasons that are about intellectual property rather than about architecture. Every component below is assumed to exist already in the estate except the registry's own services.
| Capability |
Choice |
Origin |
Credible alternative |
Why this one |
Record |
| Authored source of truth |
Forgejo — prompts and fragments as reviewable text in the repository that owns the feature |
Open source, self-hosted |
A database-backed editor as the only authoring path |
Prompt changes need line-by-line review by people who already review code, and a repository gives that for free. The database-backed console still exists for non-engineering authors; it writes through the same build, so neither path is privileged. |
ADR-11 |
| Build and validation |
Argo Workflows — flatten, validate, lint, scan, pin, canonicalise, digest, sign |
Open source on Kubernetes |
A bespoke build service inside the Config API |
The build is a directed pipeline of steps with retries and artefacts, which is what a workflow engine is. Building it into the API would couple authoring availability to build availability, which ADR-01 spends effort separating. |
ADR-08 |
| Artefact store |
OCI registry with blobs in MinIO under Object Lock |
Open source, self-hosted |
A purpose-built blob store keyed by digest |
Content addressing, immutability, referring artefacts for signatures, replication and mirroring are already solved in OCI, and operators already know how to run one. A bespoke store means re-solving all of it and getting garbage collection wrong. |
ADR-06 |
| Pointer store |
etcd, 3-node quorum — key+environment to digest, rollout percentage, kill switch |
Open source, self-hosted |
The PostgreSQL authoring database, with a pointer table |
The pointer store is the only thing the fleet polls and the only thing promotion writes; it needs linearisable writes, a tiny dataset and independence from the authoring store's availability. Putting pointers in PostgreSQL would couple the two planes in exactly the place ADR-01 separates them. |
ADR-01 |
| Change propagation |
NATS JetStream for the notice, with a 30 s poll against etcd as the guarantee |
Open source, self-hosted |
Kafka for the notice, or push-only with acknowledgements |
The notice is small, per-key, and needs no retention: JetStream is right-sized where Kafka is not. The poll is load-bearing, so the bus is allowed to be ordinary infrastructure. |
ADR-05 |
| Authoring store |
PostgreSQL with Patroni — drafts, reviews, ownership, experiment definitions |
Open source, self-hosted |
The same store used for pointers and artefacts |
Authoring is genuinely relational and genuinely transactional, and it is allowed to be unavailable. Keeping it separate is what makes a 5-minute RPO acceptable here and RPO 0 mandatory next door. |
ADR-01 |
| Signing and key custody |
OpenBao transit with an HSM seal; the signer holds a sign-only role |
Open source, self-hosted |
A signing key mounted into the build controller |
A mounted key can be exfiltrated by anything that compromises the build; a sign-only role can be used but not read. The difference is the whole value of signing. |
ADR-12 |
| Workload identity |
SPIRE — short-lived SVIDs for every resolver pulling artefacts |
Open source, self-hosted |
A long-lived pull credential distributed with the application |
A long-lived credential in ~300 deployments is 300 opportunities to leak one, and rotating it is a fleet campaign. SVIDs make the pull credential a property of where the workload runs. |
ADR-12 |
| Human identity |
Keycloak — OIDC for the console and CLI, groups as the grant subject |
Open source, self-hosted |
Registry-local accounts and roles |
Authoring, approval and promotion grants must follow people as they change teams, which means they belong to the organisation's directory rather than to this platform's own user table. |
ADR-11 |
| Exposure telemetry |
OpenTelemetry collection, Kafka buffer, ClickHouse store |
Open source, self-hosted |
Writing exposures directly to the transactional store |
500 million append-only events a day with 90-day hot retention is a columnar workload. Putting it in PostgreSQL would make the largest, least important data the constraint on the smallest, most important. |
ADR-16 |
| Audit ledger |
Hash-chained append-only records in MinIO under Object Lock, 7-year retention |
Open source, self-hosted |
An audit table in the authoring database |
The claim is that the ledger is readable but not mutable by anyone including platform operators. A table an operator can update does not support that claim, however carefully the application is written. |
ADR-12 |
| Resolution |
Go, Python and TypeScript SDKs against a shared conformance suite |
Built |
A sidecar, or a central resolution service |
Sub-millisecond resolution and resolution context that never leaves the caller, at the cost of three implementations and slow upgrades. The alternatives and their triggers are recorded rather than dismissed. |
ADR-02 |
| Runtime and delivery |
Kubernetes with Argo CD reconciling the platform's own manifests |
Open source, self-hosted |
Whatever the estate already uses for stateful services |
The registry is an ordinary platform service and gets no special treatment. Its own configuration is delivered the way everything else is, so the team operating it learns nothing bespoke. |
ADR-17 |
| Observability |
Prometheus, Loki and existing tracing; convergence and staleness as first-class metrics |
Open source, self-hosted |
A registry-specific dashboard and alerting path |
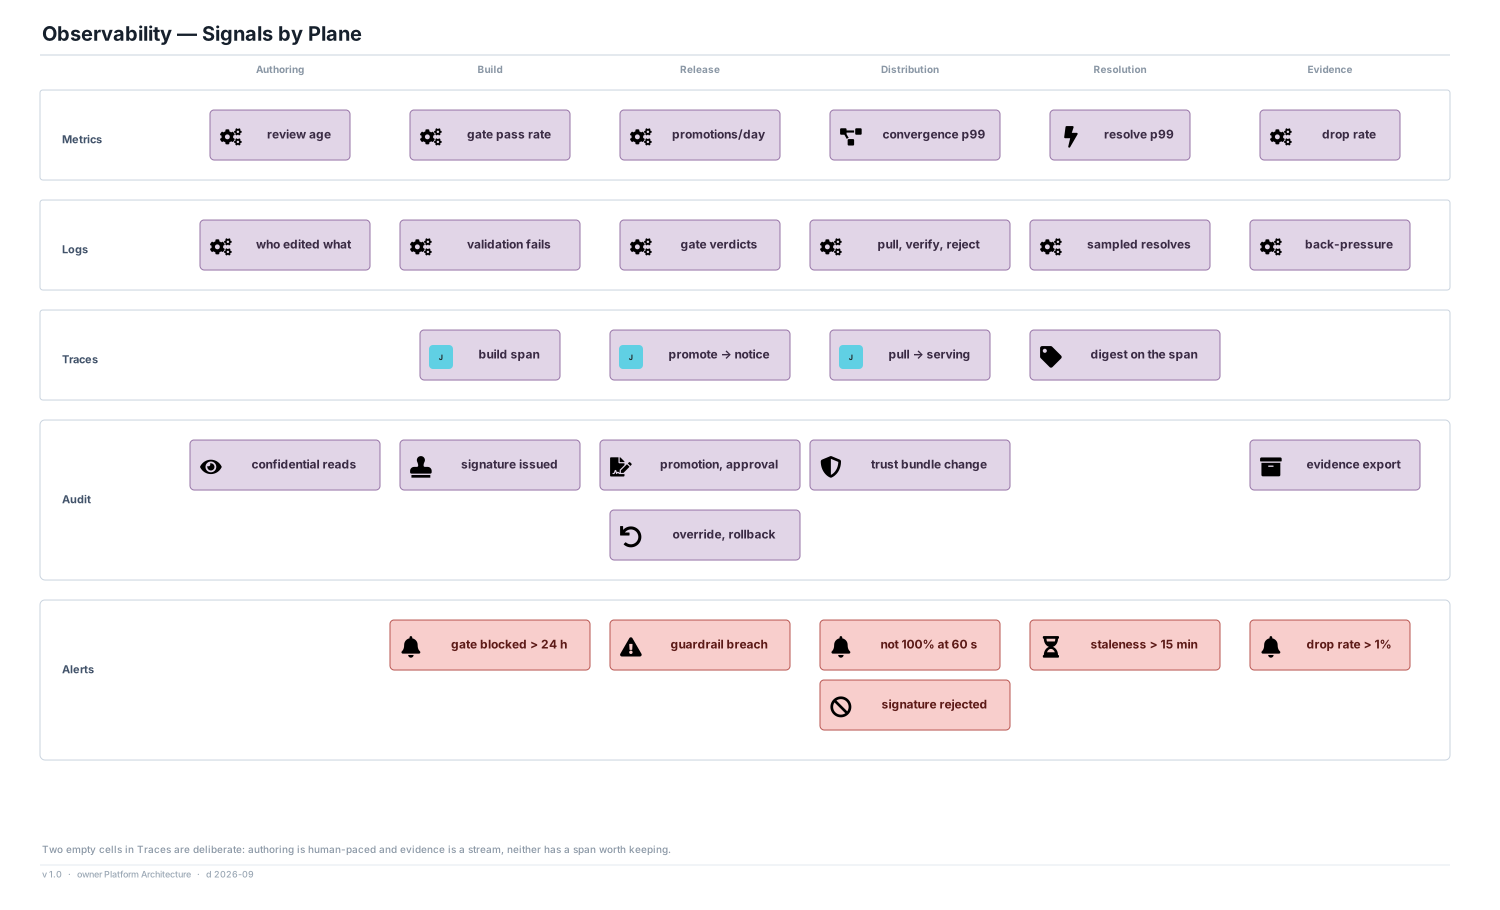
The two signals that matter — convergence and staleness — are ordinary gauges, and putting them in the estate's existing stack means on-call sees them beside everything else rather than in a tool they open once a quarter. |
ADR-05 |
The decisions, and the alternatives that lost
The boundary
What a request is allowed to depend on, where resolution executes, and what happens when the thing it depends on is unreachable.
ADR-01 · The resolution plane never reads the authoring store
Status: Accepted · Shown on views: 07, 12, 16
When an application needs to know which prompt, model, tool list or policy applies to the request it is handling, may it look that up while the request is waiting?
Context. Every capability of a configuration registry naturally wants a lookup. Targeting wants the rule table. Experiments want the assignment store. Prompt retrieval wants the content store. Each lookup is individually reasonable and individually fast, and together they make the availability of every AI feature in the organisation the product of this platform's availability and its own. The failure mode is not gradual. A registry deploy that adds 40 ms to a read becomes a 40 ms regression on every AI interaction in the company; a registry outage becomes an outage of three hundred features whose own services are healthy and whose model providers are up. The registry then acquires an availability requirement that is the union of every product that reads it, which is a requirement no team of this size can meet and none should try to.
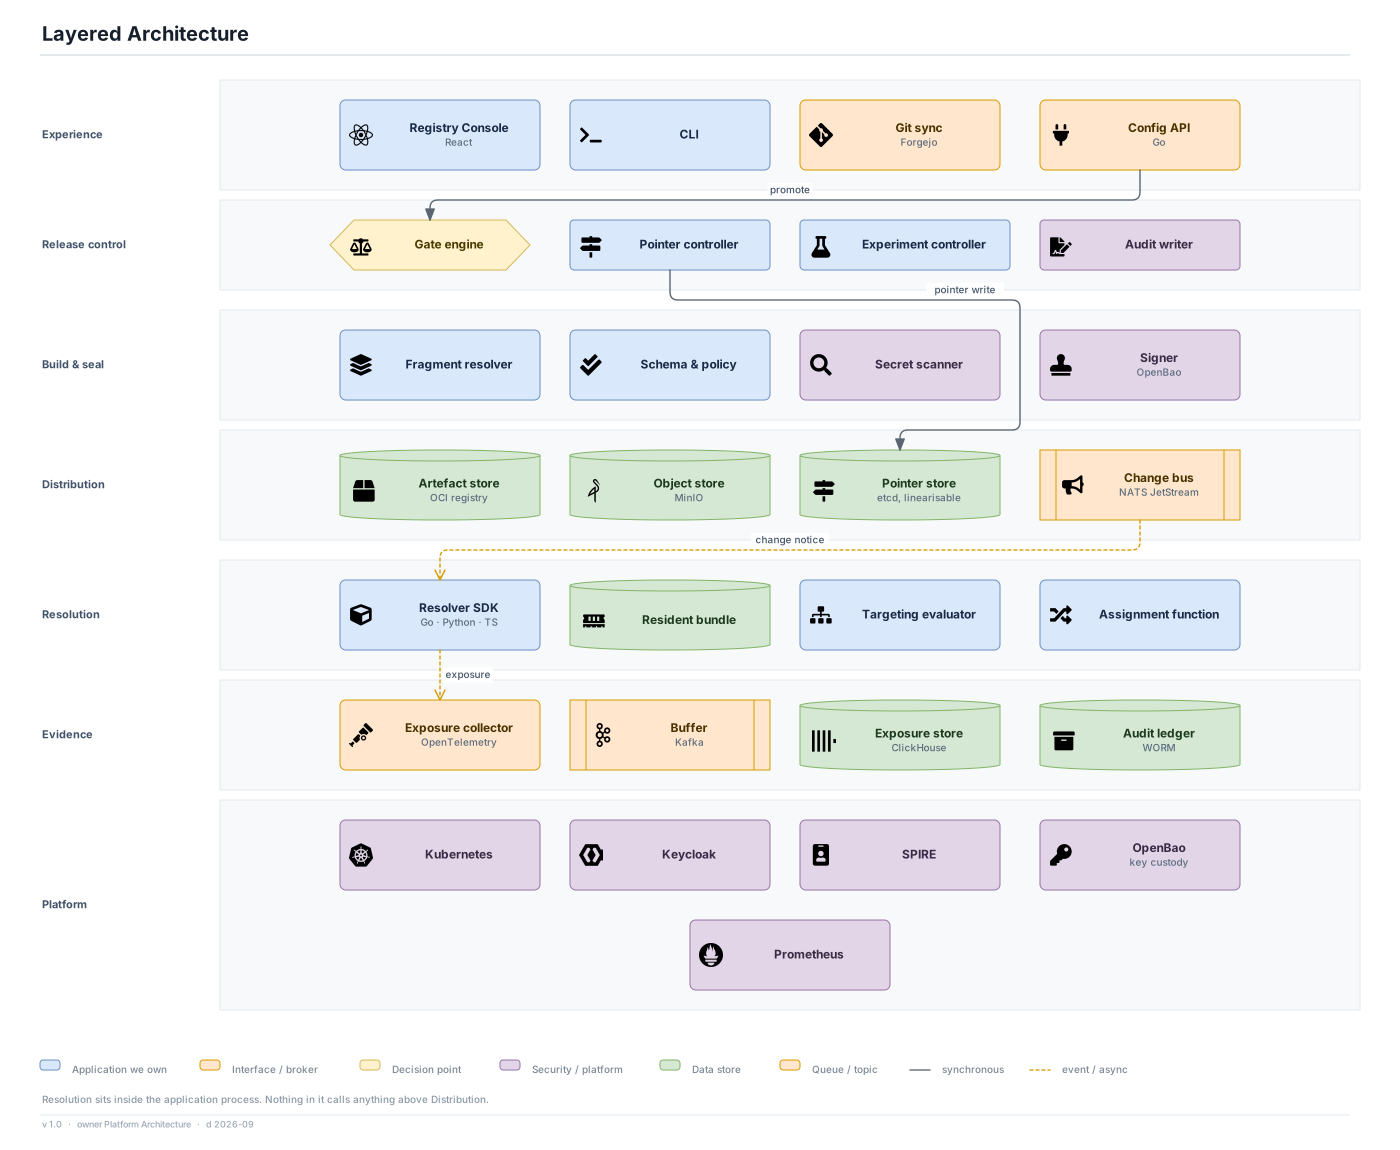
Decision. Every per-request decision is made from state already resident in the calling process: one verified, immutable bundle holding the configuration, the targeting rules and the variant definitions for the keys that application uses. The authoring store, the review service, the gate engine and the experiment controller are never called during a request. The resolution path reads exactly two kinds of thing, and both are asynchronous: an artefact addressed by digest, and a pointer naming which digest is current.
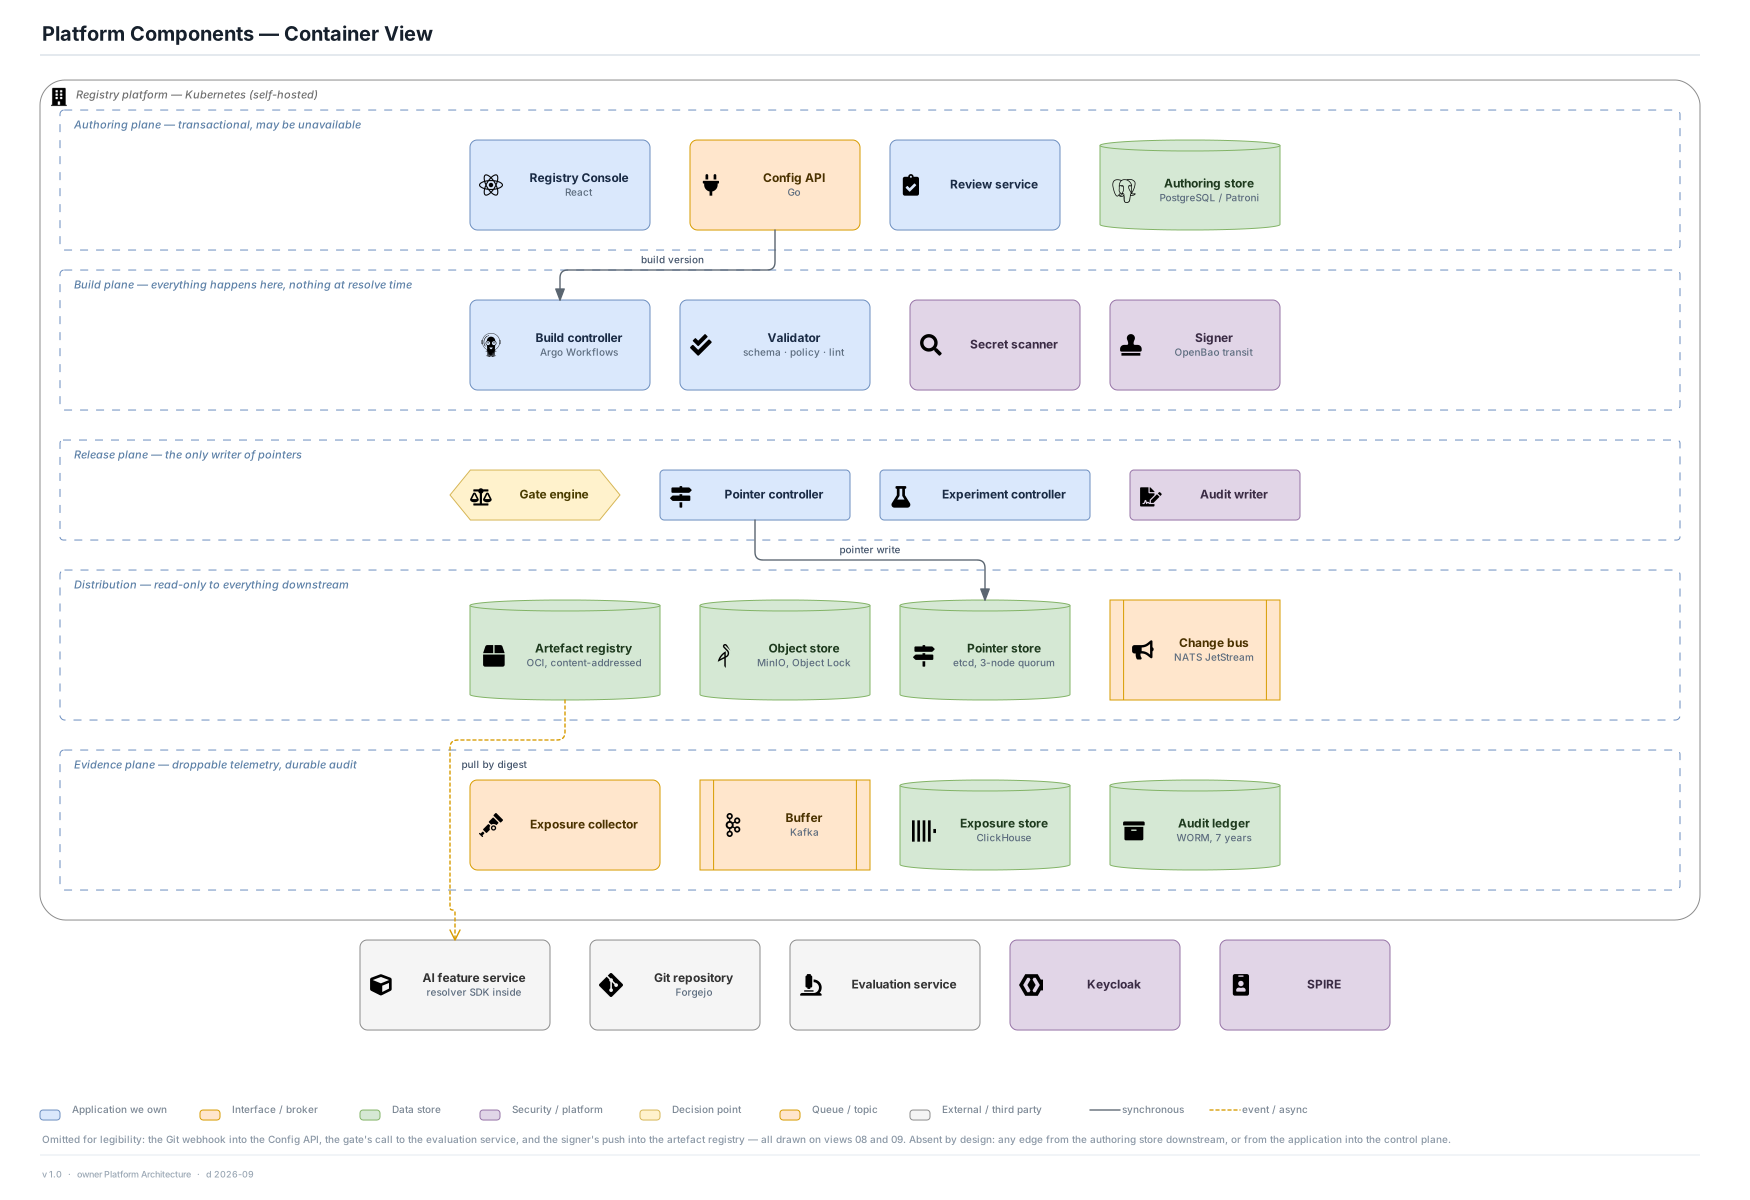
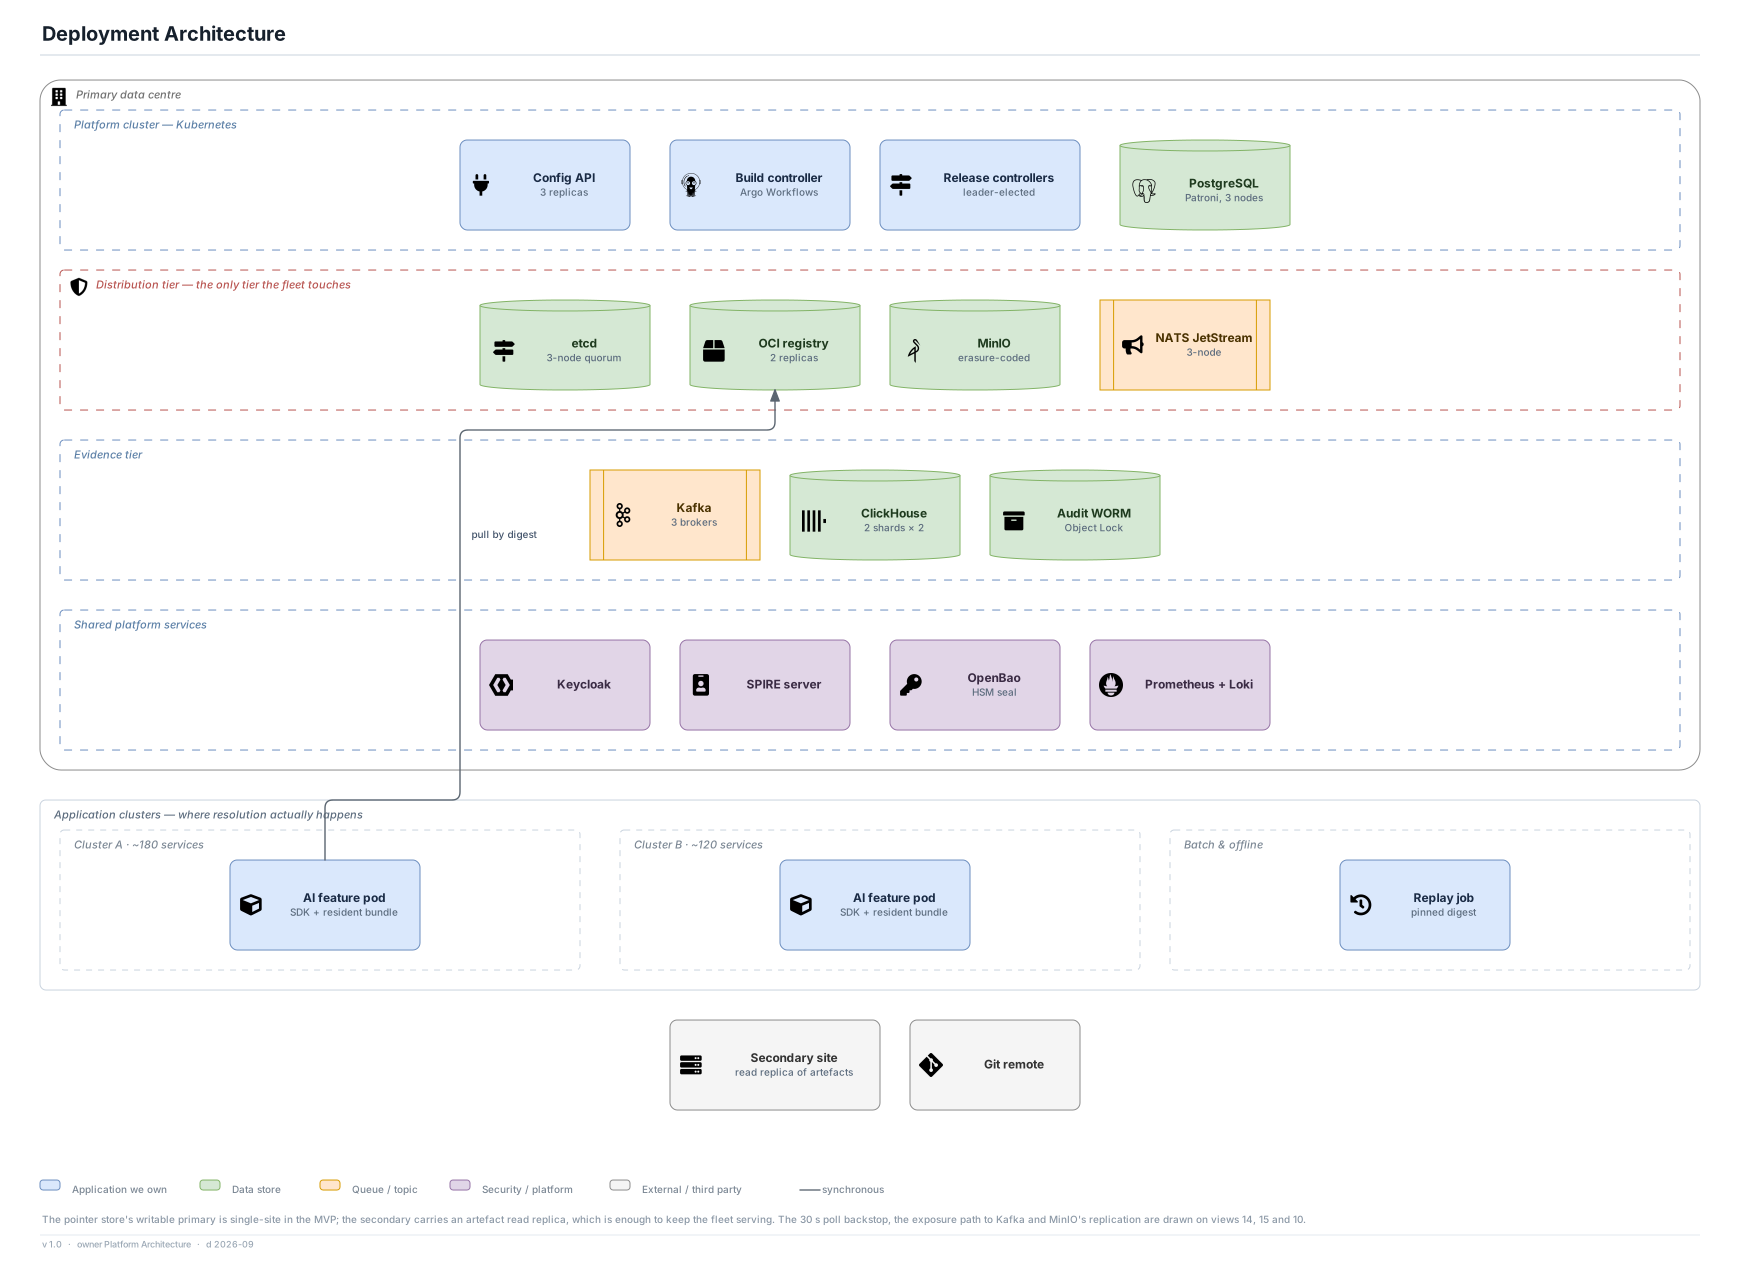
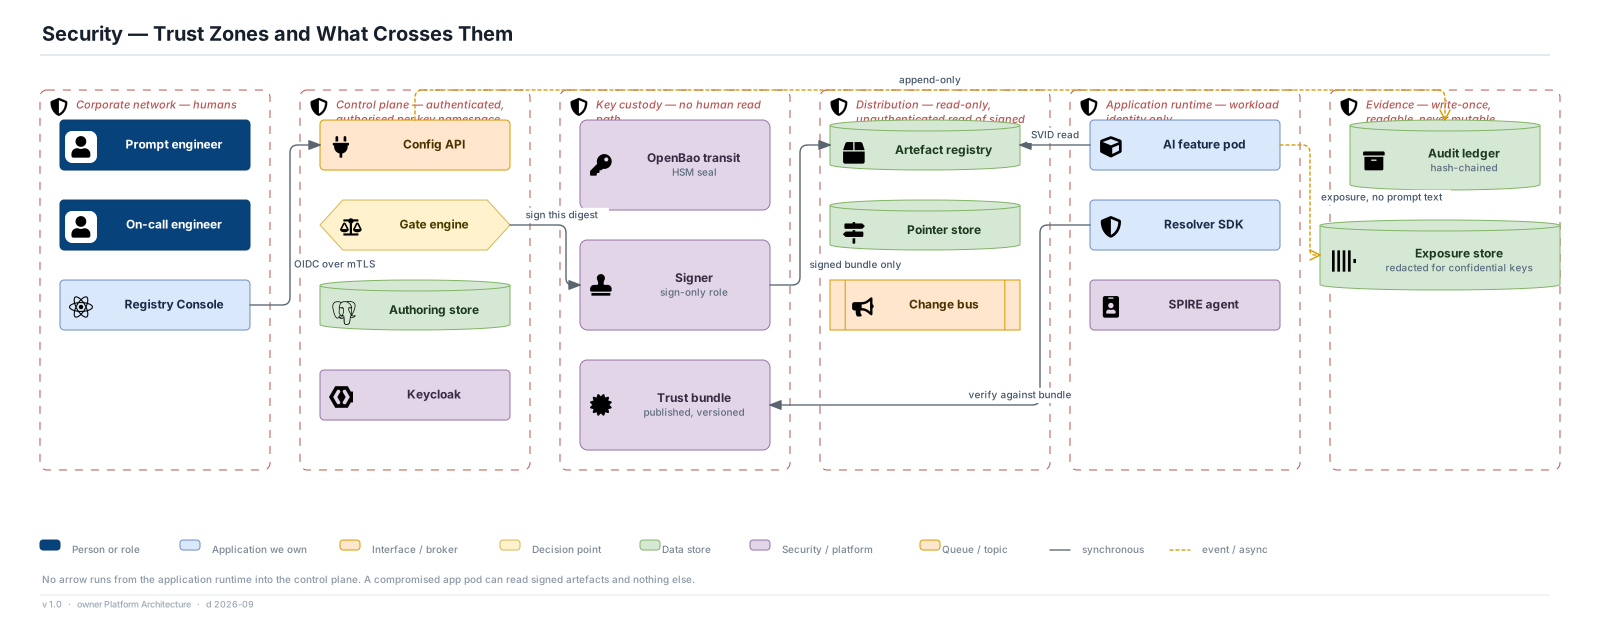
How it is realised on Google Cloud. The resolver SDK holds the bundle in process memory, pulled from an OCI artefact registry over an SVID-authenticated connection and refreshed from a change notice on NATS with a 30 s poll against etcd as the backstop. PostgreSQL, the Config API and the release controllers have no ingress path from application workloads at all — enforced by Kubernetes network policy and by SPIRE registration entries, not by convention. View 07 draws the absence of those edges explicitly so that adding one is visibly a change to the architecture rather than an implementation detail.
| Option |
Verdict |
Reasoning |
| Resident state only; the control plane refreshes asynchronously |
Chosen |
Makes the control plane's availability target legitimately lower than the applications', and puts a hard ceiling on resolution latency. Costs eventual consistency on every kind of change, which is why propagation becomes a measured SLO in ADR-05 and why version skew becomes something to observe rather than prevent in ADR-03. |
| Lookup against a resolution service with an aggressive cache |
Rejected |
This is what most teams build, and it works until the cache misses during the incident. A cache is a latency optimisation, not an availability boundary: its cold path is still a dependency, and cold paths concentrate exactly when a fleet is restarting. |
| Configuration compiled into the application image |
Rejected |
Perfectly available and perfectly useless: it reintroduces the deploy cycle the registry exists to remove. It survives as the cold-start fallback in ADR-03, which is the only role it deserves. |
What it buys
- A control-plane outage stops change and changes nothing about traffic, which is what makes a 99.9% control-plane target defensible alongside a 99.99% resolution target.
- Resolution p99 contains no network round trip at all, so the latency budget is a property of the library rather than of the slowest managed service.
- Every dependency on view 16 degrades a dimension instead of availability, because the dependencies were removed from the path before the failure analysis started.
What it costs
- Every change is eventually consistent, so each one needs a stated propagation SLO and the machinery to measure it.
- A key cannot be revoked instantly; the best the platform can promise is a propagation time, which is why the kill switch is a fast pointer change rather than an immediate guarantee.
- Application memory becomes a sizing constraint, which is what forces the bundle ceiling in ADR-07.
Choose differently when. Flip this if the catalogue grows past what a process can hold — a genuinely per-tenant configuration space, for instance, where each pod would need a slice it cannot predict. At that point resident state stops being possible and the honest answer is a resolution service with an explicit, published availability target that the consuming services design around, rather than a cache pretending to be a boundary.
Why it holds up over time. The rule names no technology. It is a statement about which dependencies may sit on a request, and it survives a change of language, cloud, artefact format and model provider. It is also the easiest property for a future team to give away, one convenient lookup at a time, which is why the absent edges are annotated on view 07 rather than merely missing.
Lesson. Availability is bought by removing dependencies from the path, not by making the dependencies more available. A team that cannot make its own service reliable enough for the request path should ask whether the request path needs it at all.
ADR-02 · Resolution is a library in the application process, not a sidecar or a service
Status: Accepted · Shown on views: 06, 12
ADR-01 says resolution reads resident state. Where does the code that reads it actually run?
Context. Three shapes are available and each is defensible. An in-process library is the fastest and keeps the resolution context — which may contain user identifiers, locale, tenant and arbitrary product attributes — inside the caller, but it multiplies by the number of languages in use and makes every upgrade a fleet-wide campaign the platform team cannot run. A sidecar decouples the upgrade cycle and gives one implementation, at the cost of a local hop, a deployment requirement on every workload, and a second container's memory per pod across ~300 deployments. A central resolution service gives one implementation and instant upgrades, and puts the registry straight back on the request path, which ADR-01 has just removed it from.
Decision. Resolution ships as a library for Go, Python and TypeScript — the three languages that cover the estate — compiled into the application. The resolution context is assembled by the caller and never leaves the process. Targeting evaluation and variant assignment both execute locally. A shared conformance suite, run in each SDK's CI, is the mechanism that keeps the three implementations honest.
How it is realised on Google Cloud. One specification document and one conformance corpus: a set of bundles, contexts and expected outcomes including assignment buckets, rule precedence, default fallback and malformed-bundle behaviour. Each SDK must pass it to be released. The bundle format is language-neutral and the assignment function is specified as an exact algorithm — a named hash over a canonical byte string — rather than as a description, because "hash the unit id" produces three different answers in three languages.
| Option |
Verdict |
Reasoning |
| In-process SDK in three languages, held together by a conformance suite |
Chosen |
Lowest latency, no extra container, and resolution context never crosses a process boundary. Costs three implementations and an upgrade cadence set by the slowest consuming team. |
| Sidecar container per pod |
Rejected |
Right answer for an estate with six or more languages, or where a targeting bug must be fixable centrally within hours. Costs a hop, a deployment requirement on every workload, and a per-pod memory tax across the fleet — and it still does not let the platform team upgrade without touching the workloads. |
| Central resolution service |
Rejected |
One implementation, instant upgrades, and a direct contradiction of ADR-01. It also requires user attributes to be sent to the registry, which turns a configuration platform into a processor of personal data. |
What it buys
- Resolution costs a function call, so the registry is invisible in the caller's latency budget and nobody is tempted to route around it.
- Resolution context — including user attributes — never leaves the calling process, which keeps the registry out of scope for a whole category of privacy obligations.
- No extra container, no extra failure domain, no extra thing to deploy alongside every workload.
What it costs
- Three implementations of the same semantics, and therefore three chances to diverge; the conformance suite is a permanent cost, not a one-off.
- A targeting-logic bug is fixed at the speed the slowest team redeploys, which may be months.
- A fourth language in the estate is a real project, not a configuration change.
Choose differently when. Flip to a sidecar on the first targeting-logic defect that cannot be worked around by a configuration change — that is the condition, stated in advance so the decision is not made during the incident. A fourth or fifth language entering the estate is the second trigger: at that point the cost of implementations exceeds the cost of a hop.
Why it holds up over time. The trade — latency and data locality against upgrade velocity and implementation count — is stable across decades and technologies; only the weights move. What ages is the language list, which is why the decision is framed around the count and the conformance suite rather than around Go, Python and TypeScript specifically.
Lesson. A library is a deployment decision disguised as a packaging decision. Choosing one means accepting that you cannot ship a fix to your own code without someone else's release.
ADR-03 · Availability failures fail static; integrity failures fail closed
Status: Accepted · Shown on views: 16, 09, 21
A resolver cannot get what it needs. Does it serve what it has, refuse, or fall back to a default — and is the answer the same whether the cause is an unreachable store or an unverifiable artefact?
Context. A single posture is always wrong somewhere. "Never reject" means a corrupt or unsigned artefact eventually serves, which turns a supply-chain problem into a behaviour problem across the fleet. "Always reject" means a network partition takes down three hundred features that were serving correct configuration a second earlier. The distinction that matters is not how bad the failure looks but what the failure tells you: an unreachable store says nothing about whether the bundle in memory is still correct, whereas a signature that does not verify says exactly that the bundle in hand cannot be trusted.
Decision. Split the posture by cause. Availability failures — control plane down, pointer store unreachable, bus partitioned, artefact store refusing connections — fail static: the resolver keeps serving its last verified bundle indefinitely, exports its staleness, and is alerted on at 15 minutes. Integrity failures — invalid signature, unknown signing key, digest mismatch, malformed bundle — fail closed on the artefact: it is rejected, the previous bundle is retained, and a high-severity alert is raised. A resolver with no bundle at all serves the configuration baked into its container image, and if that is absent, the declared safe default, reporting degraded in both cases.
How it is realised on Google Cloud. The SDK verifies the signature against a published, versioned trust bundle before a fetched artefact replaces the resident one — never after. Staleness is a gauge in seconds since the resident bundle was confirmed current, exported per pod and alerted on as a population statistic. The image-baked bundle is produced by the application's own build from the then-current production digest, so its age is a property someone can see.
| Option |
Verdict |
Reasoning |
| Fail static on availability, fail closed on integrity |
Chosen |
The only posture where both a four-hour partition and a corrupt artefact have the right outcome. Costs an unbounded staleness window for a partitioned resolver, bounded in practice by the staleness alert. |
| Fail static on everything |
Rejected |
Serves an unverifiable artefact rather than reject it, which is the one failure this system must not have: it converts a compromised or corrupt build into fleet-wide behaviour nobody authored. |
| Fail closed on everything |
Rejected |
Makes the registry's availability the fleet's availability, undoing ADR-01 entirely. It is also the posture that feels safest in a design review and is worst in an incident. |
What it buys
- A total control-plane outage is a non-event for traffic, which is what the 99.99% resolution target actually rests on.
- No unverified artefact is ever served, so the signing chain is a real control rather than a formality.
- Staleness becomes a first-class operational signal instead of an invisible condition discovered during an incident.
What it costs
- A partitioned resolver can serve a stale bundle for an unbounded period, including one whose key was revoked for a safety reason.
- Two postures mean two behaviours to explain, and engineers reliably remember the wrong one under pressure; the alert text has to state which happened.
- The image-baked fallback is an artefact whose freshness nobody owns unless it is made someone's job.
Choose differently when. Flip the staleness tolerance — not the posture — if a regulatory obligation requires a configuration withdrawal to be effective within a bounded time. That turns indefinite fail-static into fail-static-with-a-ceiling, at which point a resolver past the ceiling stops serving the key and falls to its safe default. The posture itself only flips if artefacts stop being signed, which would be a different architecture.
Why it holds up over time. "What does this failure tell me about the thing in my hand?" is the question, and it does not age. Any future dependency added to this system can be classified by it, which is why the rule is written as a principle rather than as a list of the failures known in 2026.
Lesson. Fail-open and fail-closed is the wrong axis. Classify failures by what they tell you about the data you are holding, and the correct posture for each falls out without a debate.
The artefact
What is actually distributed, what its identity is, and why every hard question about correctness is answered before it is built rather than while it is being read.
ADR-06 · A version's identity is its content digest, stored as an OCI artefact
Status: Accepted · Shown on views: 09, 11, 10
What is a published version, how is it named, and where does it live?
Context. The reproducibility requirement — recover exactly what served a given answer, for seven years — can be met two ways. Either the version has a surrogate identifier and the content is recovered by replaying history, which is only as good as the history's integrity and gets slower and more fragile with age; or the identifier is the content, in which case recovery is a lookup and integrity is checkable by anyone holding the identifier. The same choice decides whether "is this the same configuration?" is a comparison or an inference.
Decision. A published version is identified by the SHA-256 digest of the canonical serialisation of its flattened content — resolved fragments, variable schema, decoding parameters, tool definitions, policy flags and the pinned model identifier. Two versions with identical content are the same version. Bundles are stored as OCI artefacts in an existing registry, with blobs in MinIO under Object Lock. The canonicaliser is itself versioned, and its version is part of the digest input.
How it is realised on Google Cloud. The build controller flattens, canonicalises and hashes, then pushes the bundle as an OCI artefact whose tag is the digest and whose signature is attached as a referring artefact. An existing OCI registry is used rather than a bespoke blob store because content addressing, immutability, garbage-collection policy, replication and mirroring are already solved there, and because operators already know how to run one.
| Option |
Verdict |
Reasoning |
| Content digest as identity, OCI artefact as the container |
Chosen |
Reproducibility, deduplication and integrity checking all come from the same property. Costs a versioned canonicaliser, and a future canonicaliser change is a migration that touches every digest. |
| Monotonic version number with content in a relational store |
Rejected |
Human-readable and easy to reason about, and it makes identity a claim about a row rather than a fact about the bytes. Recovery becomes a query against history whose integrity nobody can independently check. |
| Git commit SHA as the version identity |
Rejected |
Tempting, since Git is already an authoring source. Rejected because a commit identifies the source, not the built artefact: two commits can flatten to identical configuration, and one commit can build differently as fragments move underneath it. |
What it buys
- Recovery of a past configuration is a lookup by digest, not a reconstruction, and it stays a lookup at seven years.
- Identical content deduplicates automatically, so a revert-and-re-revert costs nothing and is visibly the same artefact.
- Anyone holding a digest can verify the content independently, including an auditor who does not trust the platform.
What it costs
- Digests are unreadable, so every interface needs a human-facing label beside them and the console must never make someone type one.
- The canonicaliser is load-bearing and permanent: changing it changes every future digest, and the migration has to be planned rather than discovered.
- The registry inherits an OCI registry as an operational dependency with its own garbage-collection semantics, which must be configured never to collect a referenced bundle.
Choose differently when. Flip the storage, not the identity, if the estate stops running an OCI registry — plain object storage with a digest-keyed layout gives the same properties with more of the operational work done in-house. The identity decision flips only if configuration stops being serialisable to a canonical form, which would mean it had stopped being configuration.
Why it holds up over time. Content addressing is how container images, Git objects and package lockfiles became trustworthy, and it will be how whatever replaces prompts becomes trustworthy. The decision is about identity, which is the most durable kind of decision a data model makes.
Lesson. If you want to be able to prove what happened, make the identifier the content. Everything else is a promise that the history has not been edited.
ADR-07 · The unit of distribution is a whole-environment bundle with a hard size ceiling
Status: Accepted · Shown on views: 09, 12, 17
Does a resolver hold one artefact for everything it might need, or fetch each key separately?
Context. Per-key artefacts make each change cheap and independent, and then atomicity has to be rebuilt on top: a change spanning three keys needs a manifest, a generation number or a two-phase visibility switch, and until that exists a fleet can serve half of a coordinated change. A whole-environment bundle gives atomicity for free and makes verification a single operation, and then every change rebuilds and redistributes everything, and the artefact has a size beyond which holding it resident stops being reasonable. The second problem has a floor — a catalogue only grows — so the ceiling is the thing that has to be decided in advance.
Decision. One signed bundle per key namespace and environment, holding every key that namespace's consumers may resolve. A promotion spanning several keys produces one new bundle and one pointer change, so it becomes visible atomically. The compressed bundle size is capped at 2 MB; a build that would exceed it fails, forcing the namespace to be split rather than the resolver to be slowed.
How it is realised on Google Cloud. Namespaces are the unit of bundling and are aligned with ownership, so a team's consumers hold that team's keys and not the whole organisation's. The build reports bundle size on every build, not only when it fails, so a namespace approaching the ceiling is visible months before it is a problem. Splitting a namespace is a supported operation that produces two bundles and two pointers, and it costs the atomicity guarantee across the split — which is the reason the split is deliberate rather than automatic.
| Option |
Verdict |
Reasoning |
| Whole-environment bundle per namespace, 2 MB ceiling enforced at build |
Chosen |
Atomic multi-key change, one verification per artefact, and a failure mode that is a failed build rather than a degraded fleet. Costs a full rebuild per change and an eventual namespace split. |
| Per-key artefacts with a manifest for atomicity |
Rejected |
The right answer at a catalogue size where bundles cannot fit, and the right answer if most changes genuinely touch one key and nothing else. Costs a hand-built atomicity mechanism, which is the part that will be subtly wrong. |
| One bundle for the whole organisation |
Rejected |
Maximum atomicity and maximum blast radius: every team's change rebuilds and redistributes every other team's configuration, and the size ceiling arrives immediately. |
What it buys
- A change across three keys is one transition, so a partially applied behaviour change is structurally impossible rather than merely unlikely.
- One signature verification per artefact rather than per key, which keeps the integrity path simple and cheap.
- Resident memory per pod is bounded and predictable, which is what makes ADR-01 affordable at fleet scale.
What it costs
- Every change to any key in a namespace rebuilds and redistributes the whole bundle, so build and distribution cost scale with catalogue size rather than with change size.
- The ceiling will eventually be hit, and the split that follows costs the atomicity guarantee across the boundary.
- A single oversized prompt can push a whole namespace over the ceiling, which is a coupling between unrelated teams' content.
Choose differently when. Flip to per-key artefacts when a realistic catalogue cannot be held under the ceiling even after ownership-aligned splitting, or when measurement shows that multi-key changes are rare enough that atomicity is not worth the rebuild cost. The prototype measures bundle size against a realistic catalogue precisely so this is decided on data.
Why it holds up over time. The trade — atomicity against rebuild cost and resident size — is the same trade that decides page size in a database and chunk size in a distribution system. Only the numbers move, and stating the ceiling makes the moment of the move visible rather than gradual.
Lesson. Put the limit in the build. A ceiling enforced at build time is a failed pipeline; the same ceiling discovered at runtime is a slow fleet nobody can explain.
ADR-08 · All validation happens at build time; the resolver validates nothing
Status: Accepted · Shown on views: 09, 13, 12
Where are schema violations, undeclared variables, policy breaches and secrets in content caught?
Context. It is tempting to validate in both places — belt and braces, and the resolver is the last line of defence. But a resolver that can reject a bundle for being malformed is a resolver that can fail a request, and the failure arrives at the worst possible moment: mid-incident, on a fleet that is restarting, on a bundle that was fine yesterday. Worse, validation logic in the resolver is validation logic that must be identical in three SDKs and must be upgraded across the fleet whenever a rule changes, which is precisely the property ADR-02 says is slow.
Decision. Schema conformance, variable declaration, template well-formedness, policy lint and secret scanning all run in the build plane and nowhere else. A bundle that reaches the artefact store is structurally valid by construction. The resolver performs exactly one check — the signature — and that check is about trust, not about correctness. If a bundle verifies, the resolver uses it; there is no third outcome.
How it is realised on Google Cloud. The build controller runs the validator, the policy linter and the secret scanner as ordered steps before canonicalisation, and none of them can be skipped by a flag. The bundle format carries a format version so a resolver meeting a newer format refuses it as unverifiable-in-kind rather than trying to parse round it — which is an integrity failure under ADR-03 and therefore fails closed on the artefact while continuing to serve the previous one.
| Option |
Verdict |
Reasoning |
| Build-time validation only; the resolver checks the signature and nothing else |
Chosen |
Keeps the request path free of any code that can decide a request is invalid. Costs a strict dependency on the build being correct, since there is no second line of defence. |
| Validate at build and again at resolve |
Rejected |
Feels safer and moves the failure into the request path. It also puts validation rules into three SDKs, so tightening a rule becomes a fleet upgrade rather than a build change. |
| Validate lazily, at first use of a key |
Rejected |
Concentrates the failure at exactly the wrong time — first request after a restart, across a fleet, during whatever caused the restart. |
What it buys
- The resolution path has no branch that can reject a request for a content reason, which is what makes the latency and availability numbers trustworthy.
- Tightening a validation rule is a build change that takes effect on the next version, with no fleet upgrade involved.
- A malformed bundle cannot exist downstream, so every failure mode on view 16 is about reachability or trust rather than about content.
What it costs
- There is no safety net: a validator defect ships a bad bundle, and the only controls after that are the eval gate, progressive rollout and rollback.
- The build gets slower as rules accumulate, and build latency is felt by every author on every save.
- A format-version change is a coordinated rollout: resolvers must understand the new format before any bundle uses it.
Choose differently when. Flip only for a check that genuinely cannot be made at build time because it depends on request-time state — a rule referencing a context attribute whose existence varies by caller, for instance. Even then, the resolver's response is to fall through to the default and record it, never to fail the request.
Why it holds up over time. "Validate where failure is cheap" is a property of every pipeline that separates authoring from serving, and it is the reason compilers exist. It survives any change to what is being validated.
Lesson. Every validation you put on the request path is a new way for the request path to fail. Move the check to where failure costs a red build instead of a red dashboard.
ADR-13 · Model aliases are resolved and pinned at build time
Status: Accepted · Shown on views: 09, 12
A version names a model. If the provider changes what that name points at, has the configuration changed?
Context. Naming an alias is portable and gets improvements for free, and it means behaviour can change overnight with no change in the registry and no entry in any audit log. Every past digest then becomes a weaker claim than it appears: the configuration is recoverable, the behaviour is not, and an auditor asking what produced an answer gets a prompt plus a model name whose meaning has moved. Pinning to a dated snapshot makes the digest mean something and turns every provider deprecation into migration work on a schedule the platform does not control.
Decision. The build resolves the model alias to the provider's dated snapshot identifier and freezes that identifier into the flattened content, so it is covered by the digest. A version therefore names a specific model, not a moving name. When an alias moves, the next build of any version referencing it produces a different digest, and the change is visible as a diff before it is promoted.
How it is realised on Google Cloud. Alias resolution happens in the build plane, from a provider-capability table maintained as configuration in the same registry. A version whose pinned snapshot has been deprecated by the provider fails its next build with a named error rather than silently falling back to the alias, which converts a future runtime failure into a present build failure.
| Option |
Verdict |
Reasoning |
| Resolve the alias at build and pin the snapshot into the digest |
Chosen |
The digest means what it says, and drift becomes a diff. Costs a migration whenever a provider deprecates a snapshot, on the provider's timetable. |
| Serve the alias and accept drift |
Rejected |
Free improvements and no migration work, at the price of the reproducibility claim being false in a way nobody notices until it matters. It is the right choice for an internal tool and the wrong one for anything auditable. |
| Serve the alias and run continuous regression evaluation to detect drift |
Rejected |
Detects the problem without preventing it, at a recurring token cost, and still leaves past digests ambiguous. Worth doing alongside pinning; not a substitute for it. |
What it buys
- A digest identifies behaviour as closely as the provider allows, so reproducibility is a defensible claim rather than a hopeful one.
- A provider moving an alias produces a visible diff on the next build instead of an invisible change in production.
- Deprecation surfaces as a failed build on someone's screen rather than as an inference error at three in the morning.
What it costs
- Migration work arrives on the provider's schedule, not the organisation's, and it touches every version pinned to the retired snapshot.
- Improvements in a newer snapshot are not adopted until someone rebuilds, so the platform trades freshness for stability.
- The provider-capability table is a piece of configuration that must be maintained or the build will pin something stale.
Choose differently when. Flip for keys explicitly marked as tracking-latest — internal experimentation, non-customer-facing tooling — where drift is acceptable and migration cost is not. That should be a declared key property with its reproducibility consequence stated on the key, never a default.
Why it holds up over time. The question is not about models. Any external dependency named by a mutable identifier makes every past record ambiguous, which is why lockfiles exist. Pinning at build time is the same answer that package management arrived at, and it will keep being the answer.
Lesson. If you reference something by a name someone else can repoint, you have not recorded what you ran. Resolve the name at build time and keep what it resolved to.
Release and reversal
How a change becomes live, how it stops being live, and why those are the same operation pointed in opposite directions.
Status: Accepted · Shown on views: 05, 13, 18
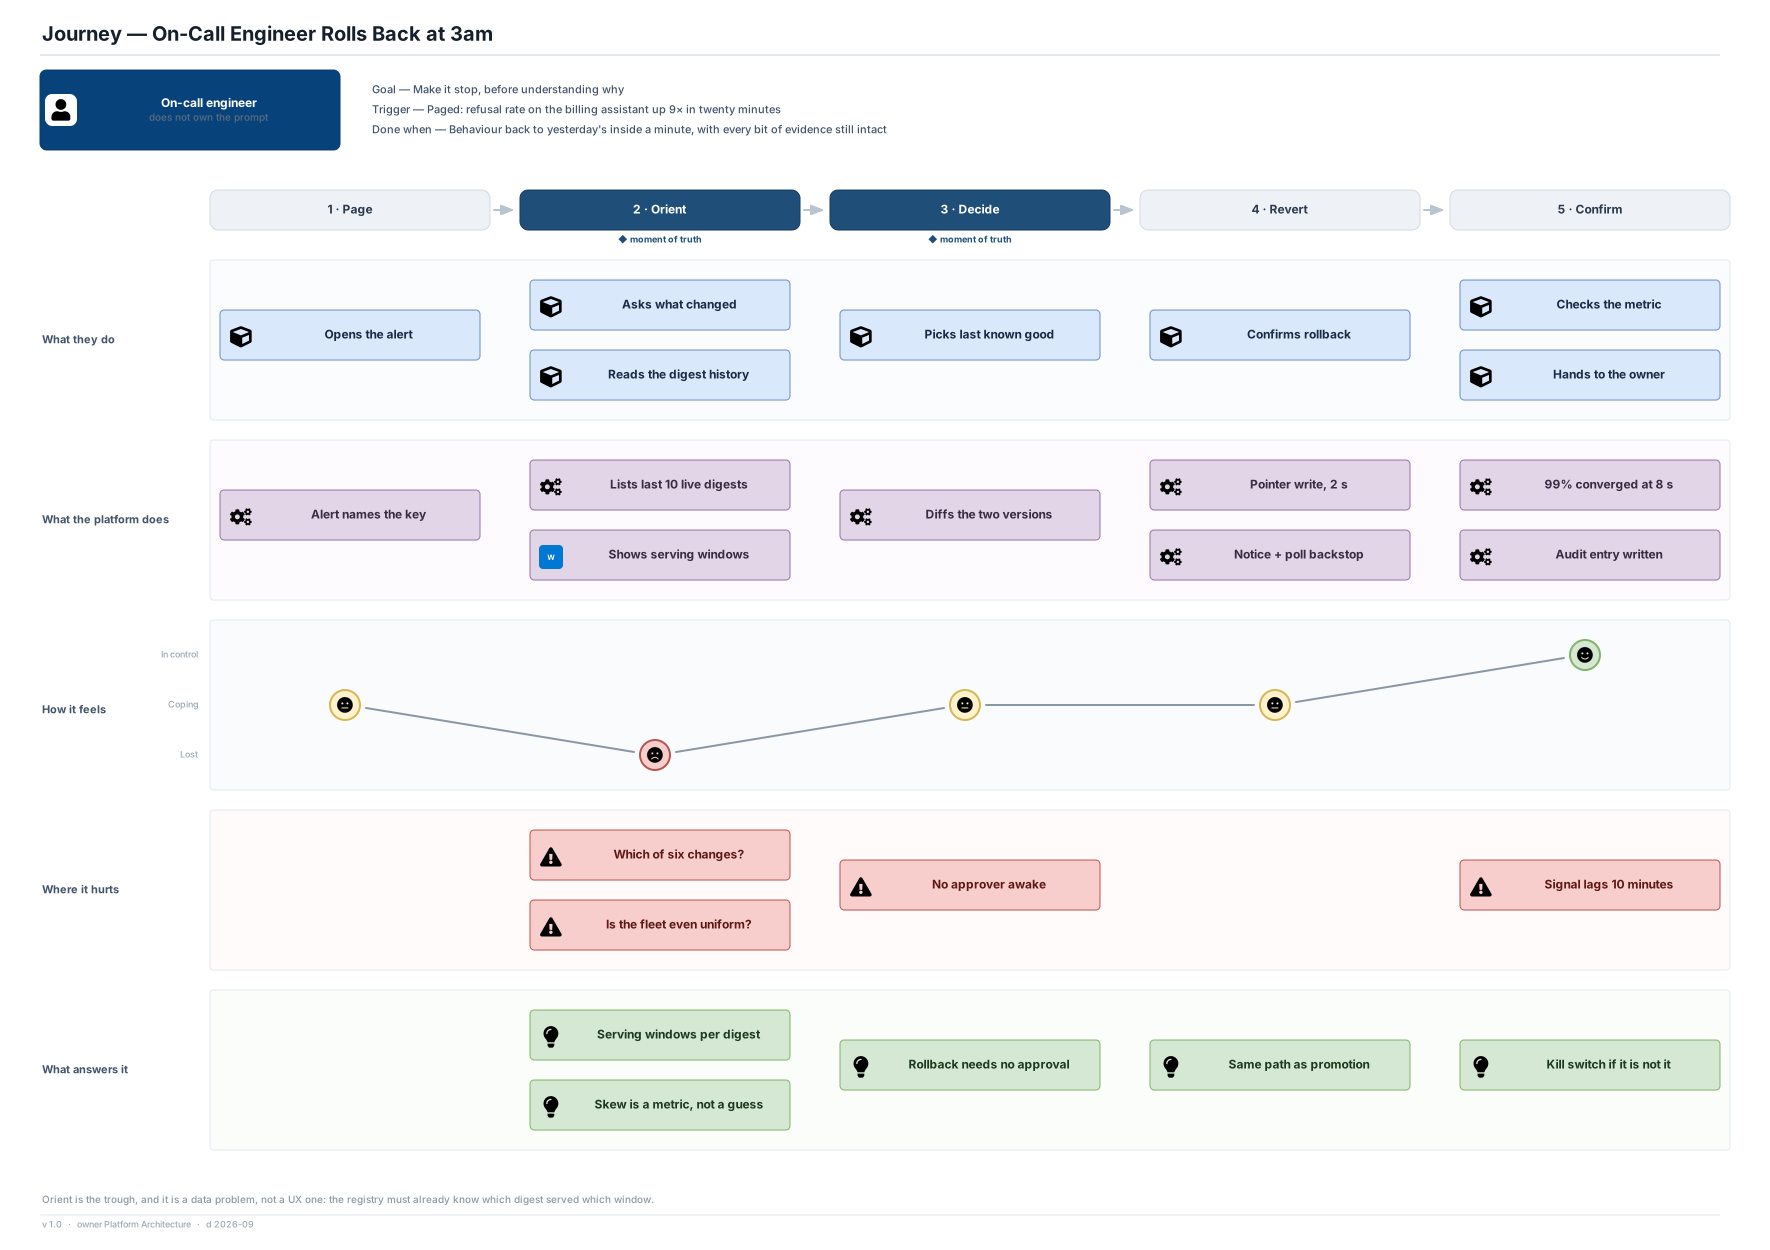
How does a change stop being live, who is allowed to do it, and is it the same machinery that made it live?
Context. Most release systems grow a fast path for emergencies, and the fast path rots because it is used once a quarter by someone who has never used it. The alternative failure is worse: requiring the same approvals to revert as to promote, which means at three in the morning the on-call engineer needs an approver who is asleep, for an operation that restores a state the organisation already approved. Meanwhile the target of a rollback is not a hypothetical: it is an artefact that already exists, that already passed every gate, and that was serving production traffic an hour ago.
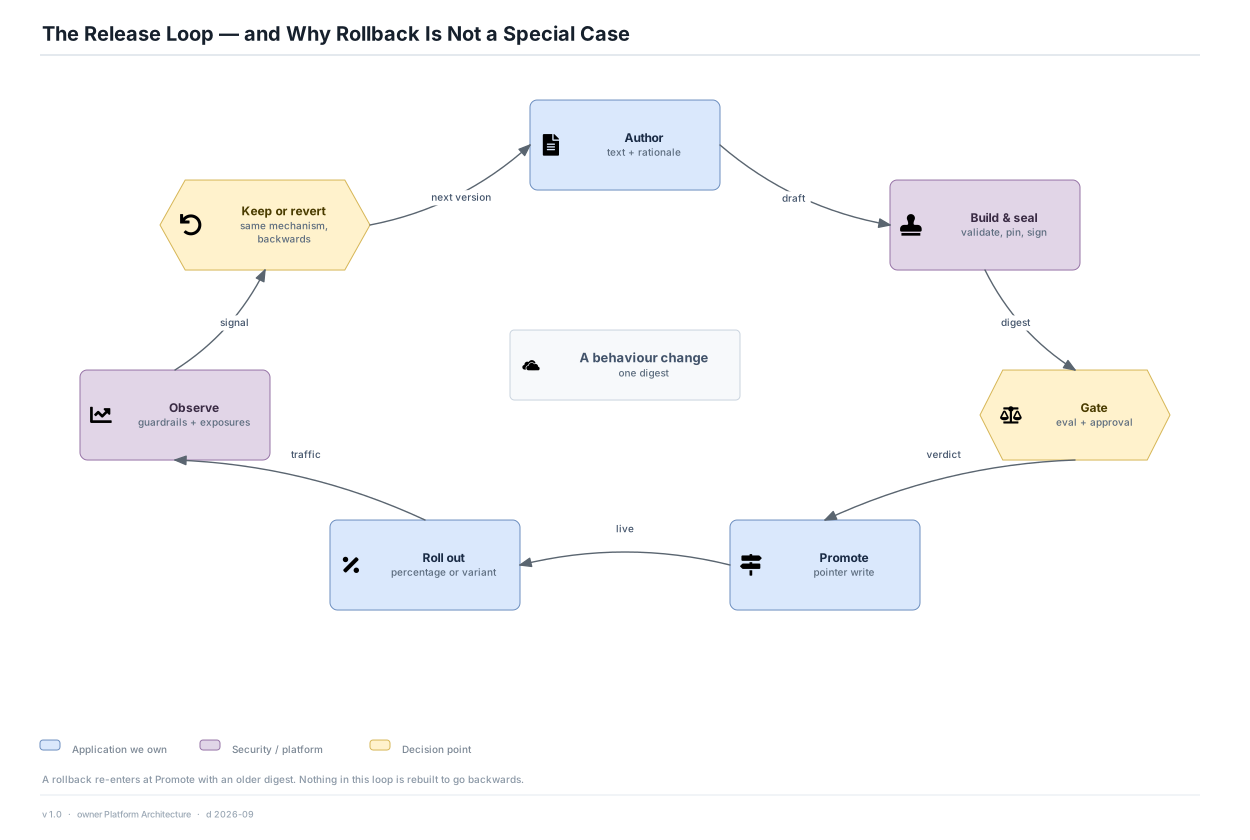
Decision. Rollback is a pointer write to a previously published digest, using the identical mechanism, controllers and audit path as promotion. It requires no review and no approval, because the version being restored has already been through both. It does record who ran it and why, and it is subject to the same atomicity rules for multi-key sets. A per-key kill switch exists alongside it for the case where no previous version is known to be good: it detaches the key from every experiment and serves the declared safe default in one action.
How it is realised on Google Cloud. The pointer controller exposes one operation — set(key, environment, digest) — and promotion, rollback and kill are all calls to it with different arguments and different gate configurations. The console offers rollback from the same screen that performed the promotion, pre-populated with the last ten digests that served production and the window each one served, because an engineer choosing a rollback target should be choosing from evidence rather than from memory.
| Option |
Verdict |
Reasoning |
| Same mechanism, no approval, full audit |
Chosen |
Exercised every day, so it works when it matters. Costs the possibility of an unreviewed reversion of a change someone wanted, which the audit trail and the serving history make recoverable. |
| Rollback requires the same approvals as promotion |
Rejected |
Defensible on paper and indefensible at 03:00. It converts an availability control into an availability risk, and teams respond by building an undocumented bypass. |
| A separate emergency rollback path with its own tooling |
Rejected |
Two mechanisms means the rarely-used one is the broken one. Every argument for a separate path is really an argument for making the ordinary path fast enough. |
What it buys
- The reverse operation is exercised continuously rather than rehearsed, so it works under pressure.
- Rollback targets an artefact that already exists and was already verified, so there is nothing to rebuild and nothing new to go wrong.
- An on-call engineer who does not own the key can act on it, which is the population that actually gets paged.
What it costs
- Someone can revert a deliberate change without asking the owner, and will occasionally do so wrongly.
- The kill switch degrades a feature to its default, which is a visible product regression and needs to be communicated, not just logged.
- "No approval" is a control that will be questioned by every audit, and the answer has to be the audit trail rather than a gate.
Choose differently when. Flip only if reversion itself becomes the dangerous operation — a domain where returning to a previous state has regulatory consequences of its own, such as reinstating a disclosure that has since been withdrawn. Then the correct answer is not an approval gate but a narrower rollback target set: only digests still marked compliant.
Why it holds up over time. The principle — the reverse of an operation must be the ordinary operation, not a special one — applies to anything with a direction. It predates this system and will outlast it, and it is the most transferable line in this record.
Lesson. If your rollback path has its own tooling, your rollback path is broken and nobody has found out yet.
ADR-05 · The poll guarantees convergence; the notice only makes it fast
Status: Accepted · Shown on views: 14, 16, 02
Push and poll both work. Which one is the platform's actual promise, and which one is an optimisation it can lose?
Context. A push over a durable bus converges in seconds and makes the bus a correctness dependency: lose it, or lose one subscriber's connection silently, and that resolver serves the old configuration indefinitely with no mechanism to notice. A poll converges in the poll interval, scales with fleet size as a steady read load, and is trivially recoverable. Running both is the obvious answer and it hides the real question, which is which of the two the propagation SLO is actually a promise about. Systems that never answer that question end up with a bus that is quietly critical and a poll interval nobody has tested.
Decision. Both run, and the poll is load-bearing. Every resolver polls the pointer store every 30 seconds and converges on that alone; the change notice over the bus exists solely to shorten the common case from tens of seconds to a few. The published propagation SLO — 99% of resolvers within 10 s, 100% within 60 s — is stated so that its upper bound is satisfiable by the poll alone, which means a bus outage costs propagation latency and never correctness.
How it is realised on Google Cloud. The change notice carries the key and the new digest and nothing else; a resolver receiving one performs the same fetch-and-verify it would have performed on its next poll. Coverage is measured from the resolvers themselves: each reports the digest it is serving after verification, and the convergence metric is derived from those reports rather than from the bus's delivery counts, because a delivery count measures the bus and not the fleet.
| Option |
Verdict |
Reasoning |
| Push for speed, poll for the guarantee, SLO satisfiable by the poll |
Chosen |
The bus becomes ordinary infrastructure rather than critical infrastructure. Costs a steady poll load proportional to fleet size, and a convergence time under bus failure that is visibly worse but still bounded. |
| Push only, with acknowledgement and retry |
Rejected |
Converges fastest and requires the bus, the subscription state and the acknowledgement path all to be correct. It also gives a bad change the fastest possible route to the entire fleet, which is a property worth thinking about twice. |
| Poll only |
Rejected |
Simplest and entirely defensible; rejected because a 30 s floor on rollback propagation is too slow for the three-in-the-morning journey, and shortening the interval to fix that multiplies the read load on the pointer store. |
What it buys
- A bus outage degrades propagation from seconds to tens of seconds and nothing else, so the bus can be operated as a normal service.
- A resolver that was disconnected for an hour converges by itself on reconnection with no replay, no backfill and no operator action.
- Convergence is measured from the fleet, which means the metric describes reality rather than describing the bus.
What it costs
- Every pod polls the pointer store every 30 seconds, a load that grows with the fleet and eventually forces a fan-out tier.
- Two propagation paths means two sets of failure behaviour to reason about, and a notice that arrives during a poll must be idempotent.
- Rollback propagation is bounded by the poll interval in the worst case, which is what makes the 30 s figure in the rollback SLO rather than something smaller.
Choose differently when. Flip the poll to a fan-out tier — resolvers polling a regional cache rather than etcd directly — past roughly 20,000 pods, which is where the steady read load stops being negligible. Flip to push-only never: the property being bought is that no subscription state has to be correct for the system to converge.
Why it holds up over time. The question generalises to every eventually consistent distribution problem: name which mechanism is the guarantee and which is the optimisation, before both are built. Systems that skip that step discover the answer during an outage.
Lesson. When two mechanisms do the same job, the one you have not tested is the one you are relying on. Decide which is load-bearing, then make the SLO satisfiable by that one alone.
Status: Accepted for the MVP, deferred as Phase 3 · Shown on views: 17, 16
Does the control plane need to be writable in more than one place?
Context. A writable multi-site control plane means a consensus problem for the pointer store, split-brain handling for promotion, and conflict resolution for authoring — considerable work for a system that performs a couple of hundred writes a day. The thing that genuinely must survive a site loss is not the ability to promote but the ability to keep serving, and ADR-01 has already made that independent of the control plane. The honest question, then, is how bad a frozen fleet is: one that keeps serving correct configuration and cannot be changed until the secondary is promoted by hand.
Decision. One writable site holds the authoring store, the pointer store's primary and the release controllers. The secondary site carries an asynchronously replicated read replica of the artefact store and nothing writable. A site loss freezes every key on its current digest — the fleet keeps serving, nothing can be promoted or rolled back until the secondary is promoted manually, with a 15-minute control-plane RTO. Writable multi-site is deferred to Phase 3.
How it is realised on Google Cloud. Artefact replication is asynchronous and continuous, so the secondary is always able to serve pulls. Promotion of the secondary is a documented, rehearsed manual procedure rather than an automatic failover, because an automatic failover of a linearisable pointer store is the split-brain risk the design is avoiding, and a frozen fleet is a far better failure than two sites disagreeing about which digest is current.
| Option |
Verdict |
Reasoning |
| Single writable site; secondary carries artefacts; manual promotion |
Chosen |
Cheap, simple, and the failure is frozen rather than wrong. Costs a window in which no key can be changed or rolled back, which is the uncomfortable part. |
| Writable multi-site with a consensus pointer store |
Rejected |
The right answer when the inability to roll back for fifteen minutes is itself unacceptable. Costs consensus across sites, cross-site write latency, and a split-brain story for a system doing 200 writes a day. |
| Automatic failover of the pointer store primary |
Rejected |
Removes the fifteen minutes and introduces the possibility of two sites disagreeing about which digest is current — which is a correctness failure in the one component whose correctness everything else assumes. |
What it buys
- The resolution path is unaffected by a site loss, because it needs artefacts and a pointer it already has.
- No consensus across sites, no cross-site write latency, and no split-brain semantics to get subtly wrong.
- The failure mode is frozen configuration, which is comprehensible, safe and recoverable.
What it costs
- For up to fifteen minutes after a site loss, nothing can be promoted and nothing can be rolled back — including a bad change that is already live.
- Secondary promotion is a manual procedure, so it must be rehearsed or it will not work when it is needed.
- Asynchronous artefact replication means a bundle published seconds before the loss may not be on the secondary.
Choose differently when. Flip when the inability to roll back for fifteen minutes becomes unacceptable — which is a statement about the blast radius of the features this registry governs, not about the registry. The first incident where a live bad change could not be reverted during a site event is the trigger, and it should be treated as one rather than absorbed.
Why it holds up over time. Choosing frozen over wrong, and manual over automatic, for a low-write control plane whose data plane is already independent, is a pattern that keeps being right. What changes is the tolerance for the freeze, which is why the trigger is a stated condition rather than a date.
Lesson. Work out what actually has to survive the site loss before designing for multi-site. Often it is the serving path, and the serving path was already independent.
Experiments and evidence
How two prompts are compared against real traffic, and what is kept afterwards so the comparison — and any single answer — can be defended.
ADR-09 · Variant assignment is a pure function of unit and salt
Status: Accepted · Shown on views: 15, 11
When a unit must be placed in a variant, is that decision computed or looked up?
Context. A lookup gives complete control: arbitrary assignment, mid-experiment reassignment, exclusion handled centrally, and a record of every decision. It also puts a store on the request path — the thing ADR-01 exists to prevent — and makes assignment stability a property of that store's correctness. A computed assignment has none of that flexibility and one very large advantage: it cannot be unavailable, cannot drift, and can be recomputed years later by someone holding only the unit identifier and the salt.
Decision. Variant membership is hash(unit identifier, experiment salt) mod 100, compared against the declared cumulative weights. There is no assignment store and no assignment service. The salt is fixed when the experiment is created and is immutable thereafter. Changing rollout weights moves the boundary of the bucket range, which keeps already-assigned units where they are.
How it is realised on Google Cloud. The hash is specified exactly — a named algorithm over a canonical byte string of unit identifier and salt — in the SDK specification, and the conformance suite includes bucket assignments for a fixed corpus so a divergence between SDKs is a failed build rather than a corrupted experiment. Exposure records carry a pseudonymised unit hash rather than the identifier, so an analyst can recompute the assignment without the platform storing the raw identifier.
| Option |
Verdict |
Reasoning |
| Deterministic hash, no store |
Chosen |
No dependency, no drift, offline recomputable, and stability comes free. Costs the ability to reassign a unit deliberately, and makes the salt a permanently load-bearing value. |
| Central assignment service with a persisted record |
Rejected |
Right when assignment must be arbitrary, or when membership must be changeable after the fact. Costs a request-path dependency and makes stability a property of a database rather than of arithmetic. |
| Assignment computed once and cached in the application's session |
Rejected |
Stable within a session and unstable across sessions and devices, which is the worst of both: it looks correct in testing and corrupts long-running experiments. |
What it buys
- No assignment dependency means no assignment outage, and no request-path cost beyond a hash.
- An analyst can reconstruct exactly which variant a unit saw, for any past experiment, from the salt alone.
- Assignment stability is arithmetic rather than an operational property, so it does not degrade as the fleet changes.
What it costs
- A unit cannot be moved between variants deliberately, which rules out some legitimate designs such as forced enrolment for a support case.
- The salt is immutable and load-bearing: changing it silently reassigns everyone, which looks like a result rather than a bug.
- Exclusion between experiments must be computed too, which is harder than a lookup and is the weakest part of the design (ADR-10).
Choose differently when. Flip if forced assignment becomes a real requirement — enrolling a named customer into a variant to reproduce a complaint, for instance. The right answer then is an override list distributed inside the bundle, consulted before the hash, rather than a store consulted during the request.
Why it holds up over time. Determinism as a substitute for coordination is one of the oldest moves in distributed systems, and it keeps working. What ages is the hash function, which is why it is specified by name and version in the conformance suite rather than left to each implementation.
Lesson. Before adding a store, ask whether the value can be computed. A pure function has no availability, no consistency model and no migration.
ADR-10 · The registry owns prompt-experiment assignment for now, and states the trigger to hand it over
Status: Accepted, with a named trigger · Shown on views: 15, 03
Should prompt experiments run inside this platform, or inside the organisation's existing experimentation platform?
Context. Owning assignment keeps a prompt change and its measurement in one tool, which is what makes the ship-a-change journey coherent: the same screen that promotes can split traffic and read the result. Delegating means prompt experiments participate in the same mutual exclusion, holdout and metric framework as pricing and interface experiments, which matters the moment a prompt change and an interface change fight over the same users and neither result can be attributed. The trouble is that the argument for delegation gets stronger over time and the cost of migrating gets higher, so a decision made by default is a decision made badly.
Decision. The registry owns assignment, exposure emission and a two-variant readout for the MVP, with exclusion groups supported only within the registry's own experiments. The trigger for handing assignment to the organisation's experimentation platform is stated now: the first prompt experiment that must be mutually exclusive with a non-prompt experiment, or the first readout whose result is disputed on the grounds of an uncontrolled concurrent change.
How it is realised on Google Cloud. The assignment function and the exposure schema are specified so that the experimentation platform could compute and consume them — a named hash, a declared salt, a pseudonymised unit hash — which keeps the migration a matter of who calls the function rather than a rewrite. The readout deliberately reports an observed difference with an uncertainty interval and never declares a winner, so the registry is not building an inference engine it would then have to retire.
| Option |
Verdict |
Reasoning |
| Registry owns it now; trigger stated for handing it over |
Chosen |
Keeps the MVP coherent and cheap, and makes the migration a decision rather than a discovery. Costs a duplicated concept of an experiment in two systems for as long as it lasts. |
| Delegate to the experimentation platform from day one |
Rejected |
Correct if that platform can carry long text as a variant payload and can be asked for an assignment without a network call. Rejected here because neither is true of most such platforms, and a per-request call to one would violate ADR-01. |
| Do not support experiments at all; ship percentage rollout only |
Rejected |
Tempting and honest, and it leaves the most valuable question — did the new wording actually work? — to a screenshot of three good answers, which is how prompt changes are evaluated today. |
What it buys
- A prompt change can be split, measured and reverted in one tool, which is the journey view 04 describes.
- No request-path dependency on an external experimentation platform, so ADR-01 holds.
- The migration path is cheap because assignment is a specified function rather than a service's internal behaviour.
What it costs
- Two systems believe they own the concept of an experiment, and a user in both is a user whose result is confounded.
- Holdouts, sequential testing and multiple-comparison correction are not built here and will be asked for.
- The exclusion lane on view 15 is deliberately thin, which is honest and is still a gap.
Choose differently when. The trigger is stated in the decision and should be honoured when it fires rather than argued about. If the experimentation platform gains the ability to serve a variant payload from resident state, that is a second and stronger trigger, because it removes the objection that caused this split in the first place.
Why it holds up over time. The underlying question — does this capability belong to the system that produces the change, or to the system that measures all changes? — recurs for every platform that touches user-visible behaviour. Naming the trigger in advance is the durable part; the answer itself is expected to change.
Lesson. When you build a capability that clearly belongs somewhere else eventually, write down the condition that means eventually has arrived. Otherwise it never does.
ADR-14 · Reproducibility retains the digest, not the rendered prompt
Status: Accepted · Shown on views: 10, 11, 19
To reproduce a past answer, what exactly is stored, and for how long?
Context. Three levels are available and each buys something different. The digest alone is tiny, cheap and permanent, and reproduces the configuration rather than the answer. The digest plus the resolved variables reproduces the exact prompt that was sent, and means this platform retains user content — inheriting every privacy obligation attached to it, in a system whose reach is every AI feature in the organisation. Storing the model response as well makes reproduction trivial and retention very expensive. The right level depends on a question nobody in the design asks out loud: is reproduction required to be byte-exact, or behaviourally equivalent?
Decision. The registry retains the digest and the matching rule identifier, for the full seven-year retention, and does not retain resolved variable values or model responses. The claim it makes is behavioural equivalence — given the digest, the exact configuration that served is recoverable and can be re-run — not byte-exactness of the prompt that was sent. The application may retain the rendered prompt under its own retention policy; the registry does not do it on the application's behalf.
How it is realised on Google Cloud. Exposure records carry a pseudonymised unit hash, a digest and a variant, and no prompt content. Keys marked confidential are additionally redacted from exposure telemetry entirely. The evidence export for a digest contains the content, its provenance, its promotion history and its approvals — everything the platform actually knows — and states plainly what it does not include.
| Option |
Verdict |
Reasoning |
| Digest and rule identifier only; behavioural equivalence claimed |
Chosen |
Permanent, cheap and keeps the registry out of the business of holding user content. Costs the ability to answer "what exactly was sent?" without the application's own logs. |
| Digest plus resolved variables |
Rejected |
Reproduces the exact prompt and makes the largest AI platform in the organisation also a store of user content, with the erasure obligations that follow. The right answer only where the obligation genuinely demands it and the privacy programme is funded. |
| Full request and response capture |
Rejected |
Reproduction becomes trivial and retention becomes the dominant cost of the platform, for a capability most organisations want for a small fraction of traffic rather than for all of it. |
What it buys
- Seven-year retention of every version is affordable because what is retained is small and does not grow with traffic.
- The registry holds no user content by default, which keeps a whole category of obligations outside its boundary.
- The evidence export states its own limits, so nobody discovers the gap during an audit.
What it costs
- "What exactly was sent to the model?" cannot be answered by this platform alone, and somebody will eventually ask.
- Correlating a complaint to a digest depends on the application recording the digest, which is a conformance requirement on ~300 services.
- The pseudonymised unit hash is still personal data and must be treated as such, which is easy to forget because it looks like a hash.
Choose differently when. Flip to retaining resolved variables for a named subset of keys if a regulator requires byte-exact reproduction for a specific product. That should be a per-key property with its own retention and erasure handling, not a platform-wide default — the cost is a privacy programme, not a schema change.
Why it holds up over time. The ladder — identity, inputs, outputs — and the trade it encodes between evidentiary strength and privacy obligation is stable, and it applies to any system asked to explain a past decision. Only the regulator's position on which rung is required moves.
Lesson. Decide whether you owe byte-exactness or behavioural equivalence before you design retention. They are different systems, and the cheap one cannot be upgraded quietly.
ADR-15 · A guardrail breach pages a human; it does not roll back automatically
Status: Accepted for the MVP, deferred as Phase 3 · Shown on views: 18, 19, 04
When a metric says the new version is worse, does the platform revert it on its own?
Context. Automatic rollback bounds the damage of a bad prompt to the detection window, which is the strongest argument available and it rests on the signal being fast and trustworthy. The signals that matter for AI behaviour are neither: quality scores, escalation rate and refusal rate lag by minutes to hours and vary with traffic mix, time of day and whatever else shipped that morning. Automation on a noisy signal reverts good changes, and a good change reverted for a reason nobody can explain is more corrosive than a bad change left running for an extra twenty minutes — it teaches teams not to trust the platform, and the next thing they do is route around it.
Decision. For the MVP, a guardrail breach raises an alert against the key with the offending digest, the rollback target pre-selected, and the on-call engineer decides. Automatic rollback is deferred to Phase 3 and is scoped then to fast, low-variance signals only — error rate, latency, hard safety-filter triggers — never to quality or satisfaction metrics.
How it is realised on Google Cloud. Guardrails are declared per key with a metric, a threshold and a window. A breach produces a page and a pre-populated rollback rather than an action, which makes the human decision cheap — the journey on view 05 exists to make it a sub-thirty-second one. The distinction between a fast signal and a slow one is recorded on the guardrail definition now, so the Phase 3 scoping is already in the data.
| Option |
Verdict |
Reasoning |
| Page a human, with the rollback pre-selected |
Chosen |
Accurate, and only as fast as the human plus the thirty-second rollback. Costs an unbounded exposure window if nobody answers the page, which is an on-call problem rather than an architecture one. |
| Automatic rollback on any guardrail breach |
Rejected |
Bounds the damage and reverts good changes on noise. It also makes the platform an actor in a product decision it cannot explain, which is the part teams object to and are right to. |
| Automatic for fast signals, human for slow ones, from day one |
Rejected |
The correct end state and too much for an MVP: it needs a signal taxonomy nobody has validated yet. Deferring it while recording the taxonomy on the guardrail definition is the cheap half of it. |
What it buys
- No good change is reverted by a noisy metric, which is what keeps teams using the platform rather than around it.
- The human decision is cheap because the rollback is one action against a pre-selected target.
- The Phase 3 scoping is already encoded in the guardrail definitions, so it is a feature rather than a redesign.
What it costs
- A bad change runs until someone answers the page, and at three in the morning that is minutes rather than seconds.
- Guardrail alerts on noisy metrics will themselves be noisy, and a noisy page is a page that stops being answered.
- The platform declines to act on information it has, which is uncomfortable to defend after an incident.
Choose differently when. Flip for a named signal once it has a measured false-positive rate low enough to justify it — error rate and hard safety-filter triggers are the first candidates. The condition is a measurement, not an opinion, and the guardrail definition already records which class a signal is in.
Why it holds up over time. The trade between a bounded automated harm and an unbounded automated mistake recurs wherever a control loop runs on a lagging, noisy signal. The durable rule is to match the automation to the signal's latency and variance rather than to the severity of what it is watching.
Lesson. Do not automate a decision on a signal you would not trust a junior engineer to act on alone. Automation does not improve the signal; it only removes the person who would have noticed.
ADR-16 · Exposure telemetry is droppable and declares its loss; the audit ledger is not and does not
Status: Accepted · Shown on views: 10, 15, 19
The evidence the platform keeps is of two kinds. Do they get the same durability?
Context. Exposure events arrive at 500 million a day and are the input to experiment readouts. Promotions, approvals, rollbacks and overrides arrive at a few hundred a day and are the input to an audit. Treating them the same means either paying transactional durability for half a billion daily events, or accepting loss on the record of who changed what — and the second is not a trade anyone would make deliberately, which is exactly why it happens by accident when the two share a pipeline.
Decision. Two paths with two guarantees. Exposure events go through a collector, a Kafka buffer and ClickHouse; they may be sampled down and then dropped under back-pressure, and every drop is counted. Any readout computed over a window states the loss rate for that window. Audit events are written to a hash-chained append-only ledger under Object Lock before the promotion is acknowledged, are never sampled, and have no degraded mode.
How it is realised on Google Cloud. The audit write is synchronous with respect to the promotion: a promotion that cannot be recorded does not complete. Exposure emission is fire-and-forget from the application with a bounded local buffer, so back-pressure in the pipeline can never become latency in the resolution path. The drop counter is exported per collector and surfaces in the readout rather than only on a dashboard.
| Option |
Verdict |
Reasoning |
| Droppable telemetry with a declared loss rate; durable audit written before acknowledgement |
Chosen |
Each kind of evidence gets the durability its use actually needs. Costs two pipelines and the discipline of never letting a convenient field migrate from one to the other. |
| One durable pipeline for both |
Rejected |
Pays transactional durability for half a billion daily events, and makes the exposure pipeline capable of back-pressuring a promotion. The cost lands on the wrong side. |
| One best-effort pipeline for both |
Rejected |
Cheap, and it means the record of who promoted what is lossy — which is discovered during the incident review where it is needed. |
What it buys
- The largest data volume in the system cannot affect the smallest and most important, in either direction.
- A readout over a lossy window says so, so a result computed on 96% of exposures is visibly a different claim from one computed on all of them.
- Audit completeness is 100% by construction rather than by monitoring, because an unrecorded promotion does not happen.
What it costs
- Two pipelines to run, two retention policies to manage, and a permanent temptation to put an exposure-shaped field in the audit path or vice versa.
- A promotion fails if the ledger is unavailable, which makes the ledger a control-plane dependency — acceptable, and it must be sized and operated as one.
- Loss rates have to be surfaced in the readout, which makes experiment results look less clean than teams would like.
Choose differently when. Flip the exposure path to durable delivery only if an exposure record becomes the basis of something with a financial or regulatory consequence — per-variant billing, for instance. At that point it is no longer telemetry and should move to the audit path rather than having the audit path's guarantees bolted onto it.
Why it holds up over time. Classifying data by what its loss costs, rather than by where it comes from, is the durable move. It applies to every platform that produces both operational telemetry and a record of authority, and the two are always tempted to share a pipeline because they share a shape.
Lesson. Separate the evidence you may lose from the evidence you may not, at the pipeline, not at the retention policy. Anything else is a promise that the pipeline will behave.
Trust and custody
Who may change what, who signs, and what a compromised component is able to reach.
Status: Accepted · Shown on views: 20, 21, 13
Who is allowed to change what a model says, and is that the same person who is allowed to make the change live?
Context. A prompt is text, and text feels low-risk to grant. It is also the most direct instruction a model receives, so authoring rights on a customer-facing key are the ability to change what a company says to its customers, at the speed of a save. The people best placed to write the words are usually not the people accountable for them, and the person who should be woken to revert a change is usually neither. Collapsing these into one permission is the default that every system arrives at when nobody decides, and it is discovered during the first incident where the change had no second reader.
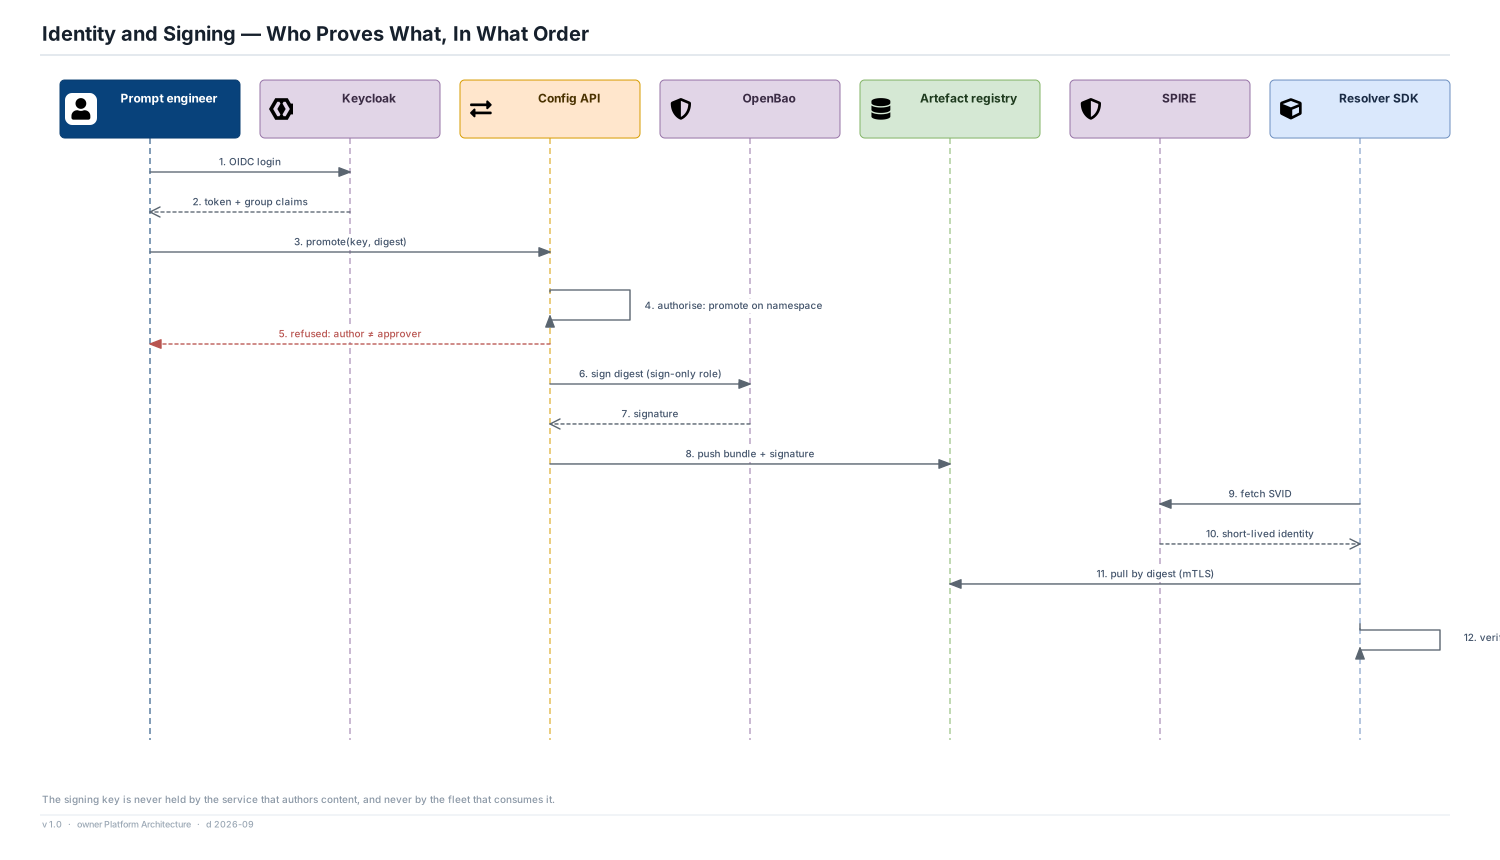
Decision. Read, author, approve and promote are distinct permissions, granted per key namespace and per environment, held by directory groups rather than by individuals. Authoring permission never implies promotion permission in a protected environment. A promotion into production requires at least one approver other than the author, and for keys marked high-risk, an approver from a named owning group. Rollback deliberately requires none of this (ADR-04).
How it is realised on Google Cloud. Grants are Keycloak group memberships mapped to namespace-scoped roles; the Config API evaluates them and refuses the promotion call before any build or signature is involved, so an unauthorised promotion never produces an artefact. Risk classification of a key is owned outside the team that promotes it, because a team able to mark its own keys low-risk has an approval gate it can remove.
| Option |
Verdict |
Reasoning |
| Four distinct grants, group-held, namespace and environment scoped |
Chosen |
Matches the three populations on view 03 and survives people changing teams. Costs administrative work and a gate that will be felt on a 200-a-day flow. |
| One grant per key: whoever can edit can promote |
Rejected |
Simple, fast and the reason most incidents of this kind have no second reader. It also makes the audit record meaningless, since author and approver are the same name. |
| Approval by any two people with access |
Rejected |
Cheap to satisfy and therefore satisfied by whoever is nearest, which is approval theatre. The owning-group requirement on high-risk keys exists precisely to prevent it. |
What it buys
- Every production promotion has two names against it, which is what makes the audit ledger worth keeping.
- Grants follow people through team changes because they are group memberships, not per-user grants on a key.
- The most dangerous action — changing what a customer-facing assistant says — has a second reader by construction.
What it costs
- Seven gates on a 200-a-day flow is a strong incentive to classify keys as low-risk, which is why the classification is owned elsewhere.
- An approver must be available, which creates a latency that the rollback exemption deliberately does not inherit.
- Group administration is real work that belongs to somebody, and if it belongs to nobody the grants drift.
Choose differently when. Flip the granularity, not the separation, if the namespace turns out to be too coarse — per-key grants are the finer alternative and cost far more administration. Collapsing author and promoter flips only for keys that are genuinely internal and never customer-facing, and that exemption should be an explicit key property rather than an informal habit.
Why it holds up over time. Separation of duties on a change that alters what a system says to customers is an obligation that predates language models and will outlast them. What changes is what the change is made of; the obligation does not.
Lesson. Grant the ability to write and the ability to release separately, or the audit trail records one person agreeing with themselves.
ADR-12 · Bundles are signed with a sign-only role, and trust distribution leads key rotation
Status: Accepted · Shown on views: 21, 20, 09
What stops a bundle that the registry did not build from being accepted by the fleet, and who is able to produce a signature?
Context. The whole integrity story rests on the resolver refusing an artefact it cannot verify, which is only meaningful if producing a valid signature is hard. A signing key mounted into the build controller can be exfiltrated by anything that compromises that controller, and a compromised build controller is exactly the scenario signing is supposed to survive. Rotation brings a second hazard of its own: if a new key signs before the fleet trusts it, the fail-closed posture from ADR-03 turns into a fleet-wide refusal of every new artefact, which is the only way this design can cause an outage.
Decision. Signing is a call to OpenBao transit under a role that can sign and cannot export; the key material never exists in the build controller's memory. Verification is against a published, versioned trust bundle distributed to resolvers ahead of any key change, with the outgoing key trusted throughout an overlap window long enough for every resolver to converge under the propagation SLO. Trust-bundle distribution always leads key rotation; a rotation is not started until convergence on the new trust bundle is at 100%.
How it is realised on Google Cloud. OpenBao is sealed with an HSM. The signer's role is the only principal permitted to invoke the sign operation, and its use is logged to the audit ledger. The trust bundle is itself a versioned artefact distributed on the same path as configuration, so the convergence metric that proves a promotion landed also proves the trust bundle landed — one mechanism, measured once.
| Option |
Verdict |
Reasoning |
| Sign-only role in a sealed KMS; trust distribution leads rotation |
Chosen |
A compromised build controller can sign a bad bundle but cannot steal the ability to sign, and rotation has a stated ordering that prevents the fleet-wide refusal. Costs an operational dependency on OpenBao during builds. |
| Signing key mounted into the build controller |
Rejected |
Simpler and removes a build-time dependency, and it means compromising the build is compromising the key permanently rather than for the duration of the compromise. |
| No signing; rely on network controls around the artefact store |
Rejected |
Makes integrity a property of the perimeter, which means a single misconfigured policy is a fleet-wide behaviour change. It also leaves the compliance reviewer with nothing to verify independently. |
What it buys
- Compromising the build controller yields the ability to sign during the compromise, not a portable key afterwards.
- A compliance reviewer can verify a bundle independently, without trusting the platform's own records.
- Trust-bundle distribution reuses the configuration distribution path, so it is measured by a metric that already exists.
What it costs
- Builds depend on OpenBao being available, which is a control-plane dependency — acceptable because it is not on the resolution path.
- Rotation has a mandatory ordering, and getting it wrong is the one failure mode that can refuse the whole fleet's new artefacts.
- An operator with OpenBao administrative rights can grant themselves the sign role; separation here is policy backed by audit, not cryptography.
Choose differently when. Flip to a transparency log in addition to signatures if the organisation ever needs to prove that a signature was not issued out of band — the properties are complementary, and the cost is an extra witness rather than a redesign. Nothing flips the sign-only role short of the key store disappearing.
Why it holds up over time. "A signature is only worth the difficulty of producing one" and "distribute trust before you use it" are the two rules, and they are the same rules that govern certificate rollouts, package signing and firmware updates. Neither depends on this decade's key technology.
Lesson. Rotate the trust anchor before you rotate the key, always, and make the convergence of the trust anchor something you can see rather than something you assume.
Every package used, in one table
The nouns this package uses in a particular way. Where a term is ordinary but the role it plays here is not, the role is what is written down.
| Package |
What it is |
What it does here |
Considered instead |
| Configuration unit (key) |
The smallest thing that can be versioned and released: prompt text, model selection, decoding parameters, tool definitions, retrieval parameters and policy flags, under one name. |
The unit of ownership, of permission, of rollout and of rollback. Everything the platform grants or gates is granted or gated on a key. |
Calling it a flag, which imports a feature-flag product's assumptions about short text and boolean values. |
| Version / digest |
An immutable published configuration, identified by the SHA-256 of its canonical flattened serialisation. |
Identity and content are the same thing, which is what makes reproducibility a lookup rather than a reconstruction. |
A monotonic version number, which identifies a row rather than a set of bytes and cannot be independently checked. |
| Bundle |
The signed OCI artefact actually distributed: every key in a namespace, for one environment, flattened and canonicalised. |
The only content that crosses from the authoring plane to the resolution plane, and the unit of both verification and atomicity. |
Treating the bundle and the version as the same thing — a bundle holds many versions, one per key. |
| Pointer |
A row saying which digest is current for a key in an environment, plus its rollout percentage and kill state. |
The only thing promotion writes. Promotion, rollback and kill are all writes to this row; the history lives elsewhere. |
Calling it the current version, which suggests the content lives here. It does not: the pointer is a name, not a thing. |
| Resolution |
Answering, inside the calling process, which configuration applies to this request — and returning the digest that answered. |
The operation whose availability and latency the whole architecture is organised around. It reads resident state and nothing else. |
Calling it a lookup, which implies something is being looked up somewhere. |
| Fail static |
Continuing to serve the last verified bundle when the registry is unreachable, for as long as it stays unreachable. |
The reason a control-plane outage is not a product outage. Distinct from fail open, which implies a control has been bypassed. |
Fail open, which here would mean serving unverified content and is exactly what ADR-03 forbids. |
| Exposure |
A record that a unit was served a particular experiment variant, emitted at most once per unit per decision window. |
The evidence an experiment readout is computed from. Droppable by design, with the loss rate declared alongside the result. |
Logging every resolution, which multiplies volume by conversation length and measures traffic rather than assignment. |
| Assignment function |
hash(unit identifier, experiment salt) mod 100, compared against declared variant weights. |
A pure function with no store behind it, identical on every resolver and recomputable offline by an analyst. |
An assignment service or table, which is a dependency on the request path and a thing that can drift. |
| Staleness |
Seconds since a resolver last confirmed its resident bundle was current. |
The operational signal that makes indefinite fail-static acceptable: unbounded in principle, alerted on at 15 minutes in practice. |
Measuring bundle age, which says how old the content is rather than how long since anyone checked. |
| Model pin |
The dated model snapshot a version names, resolved from an alias at build time and frozen into the digest. |
What stops a provider moving an alias from silently changing the meaning of every past digest. |
Naming a model alias in the served configuration, which makes the digest a weaker claim than it looks. |