Usage Metering & Billing Pipeline

Architecture Views

22 views, in reading order. Every view ships three ways: an HTML page, an SVG that re-opens in diagrams.net fully editable, and draw.io source.

The metering-to-invoice backbone behind a usage-based product: it turns raw usage events into a priced, auditable invoice, and can still explain that invoice line by line months later. Read it in order — the argument runs from the boundary, through the people it serves, to the structure, the data, the runtime, the operations and finally the assurance. One decision governs the whole set: the event ledger is the system of record, and every priced figure is a recomputable projection of it. Every number in these pages is a stated assumption from the requirement document, chosen to be argued with.

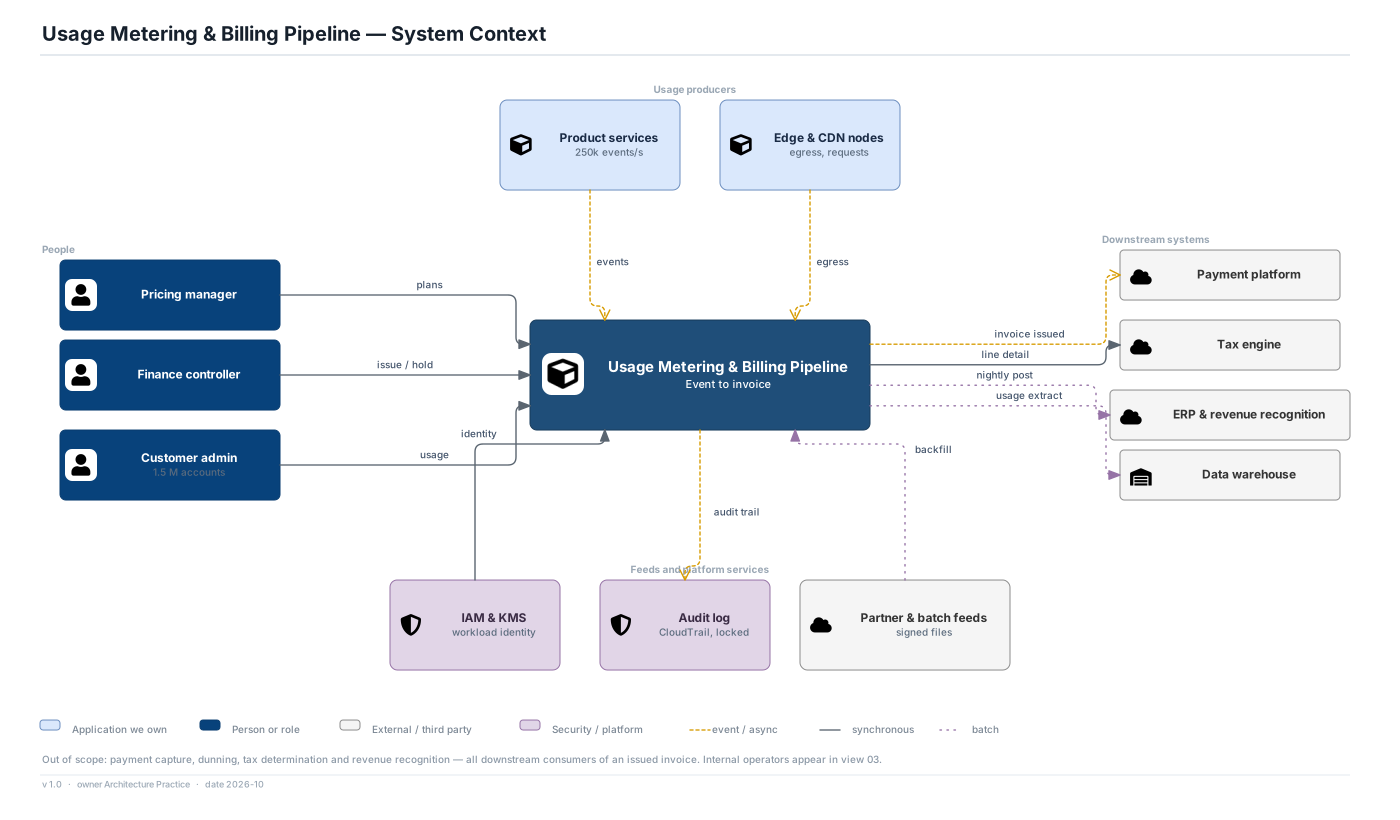
Context and scope

What sits inside the boundary, who feeds it, who consumes it, and what is deliberately somebody else's problem.

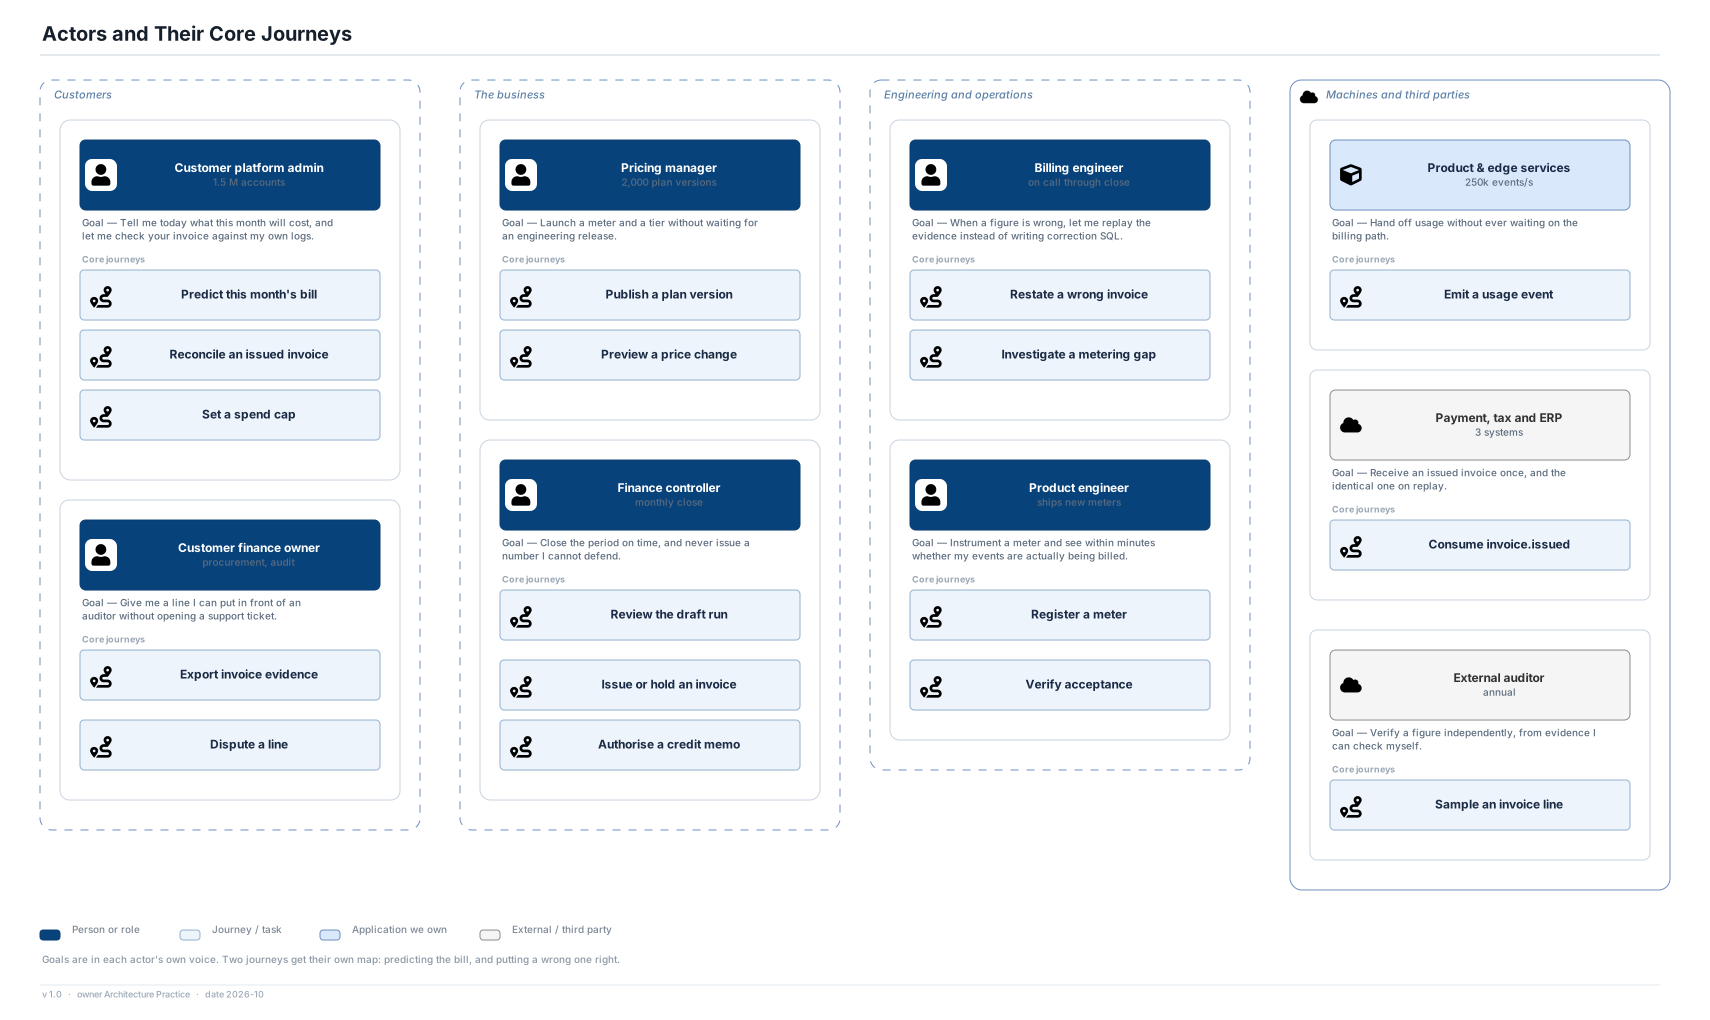
People and journeys

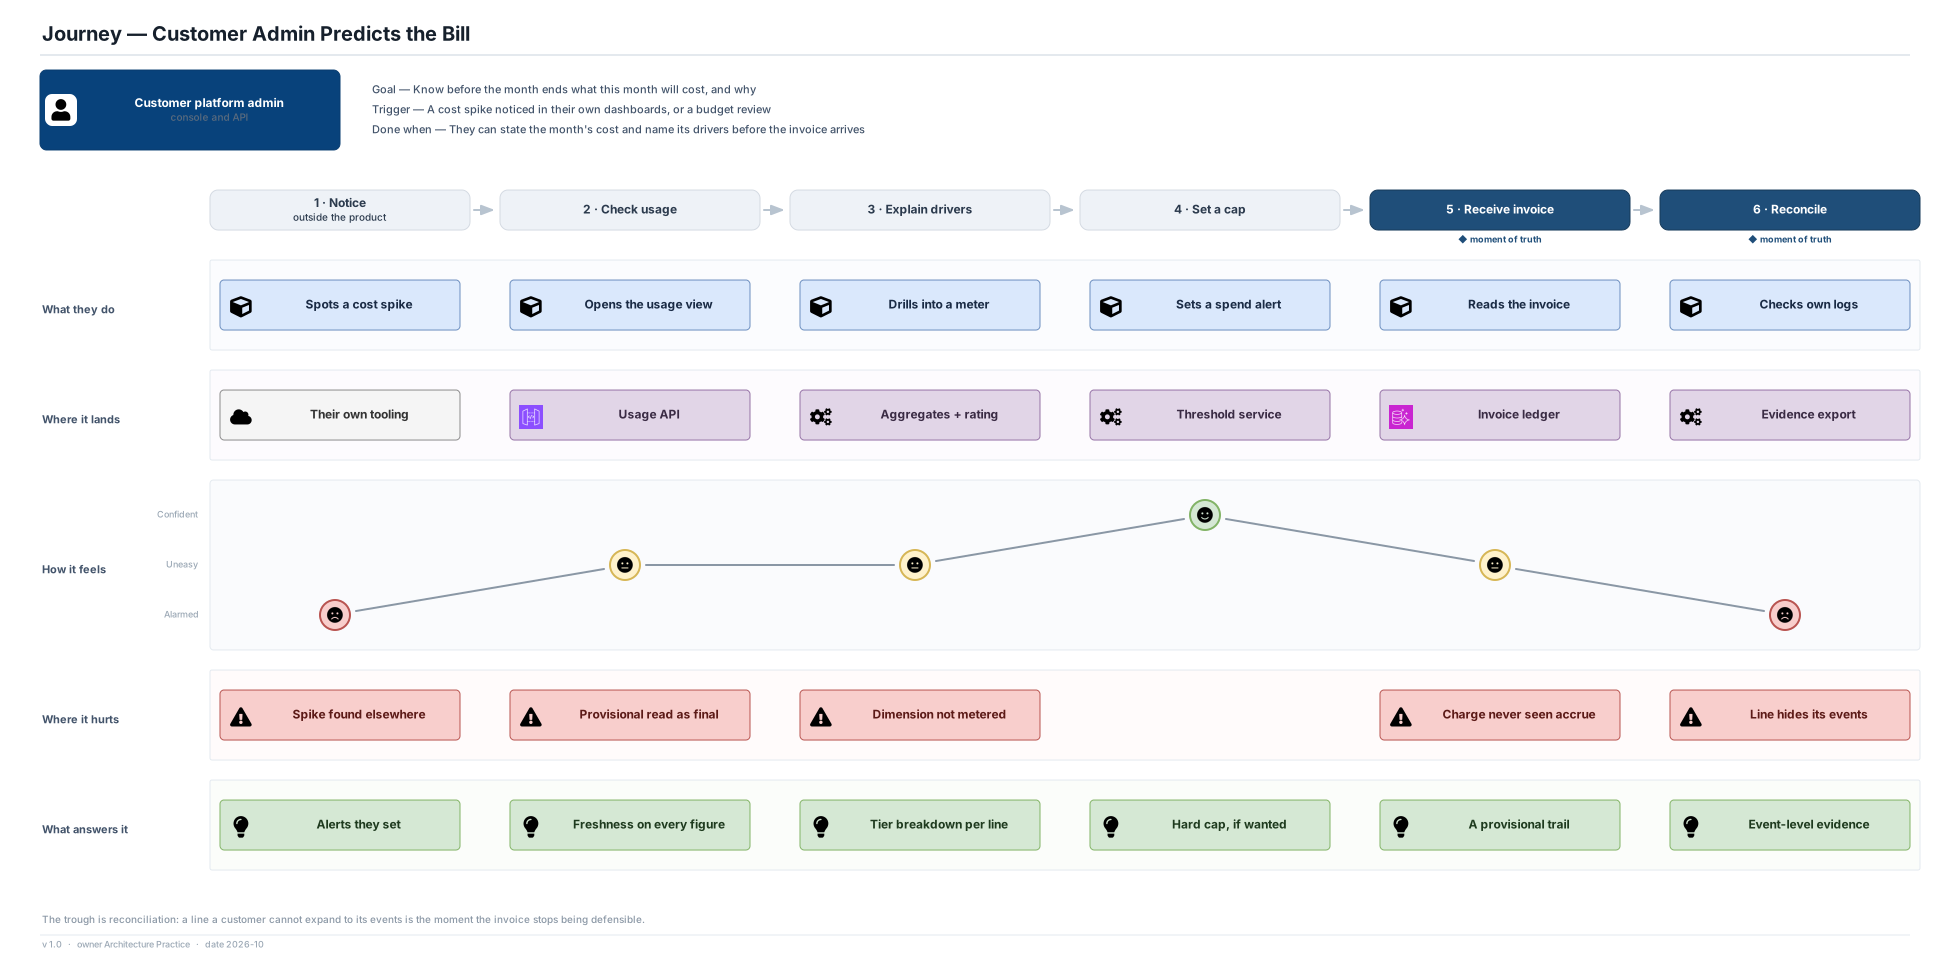
Who the platform is for, what each of them gets to do, and the two moments where the design either earns trust or loses it.
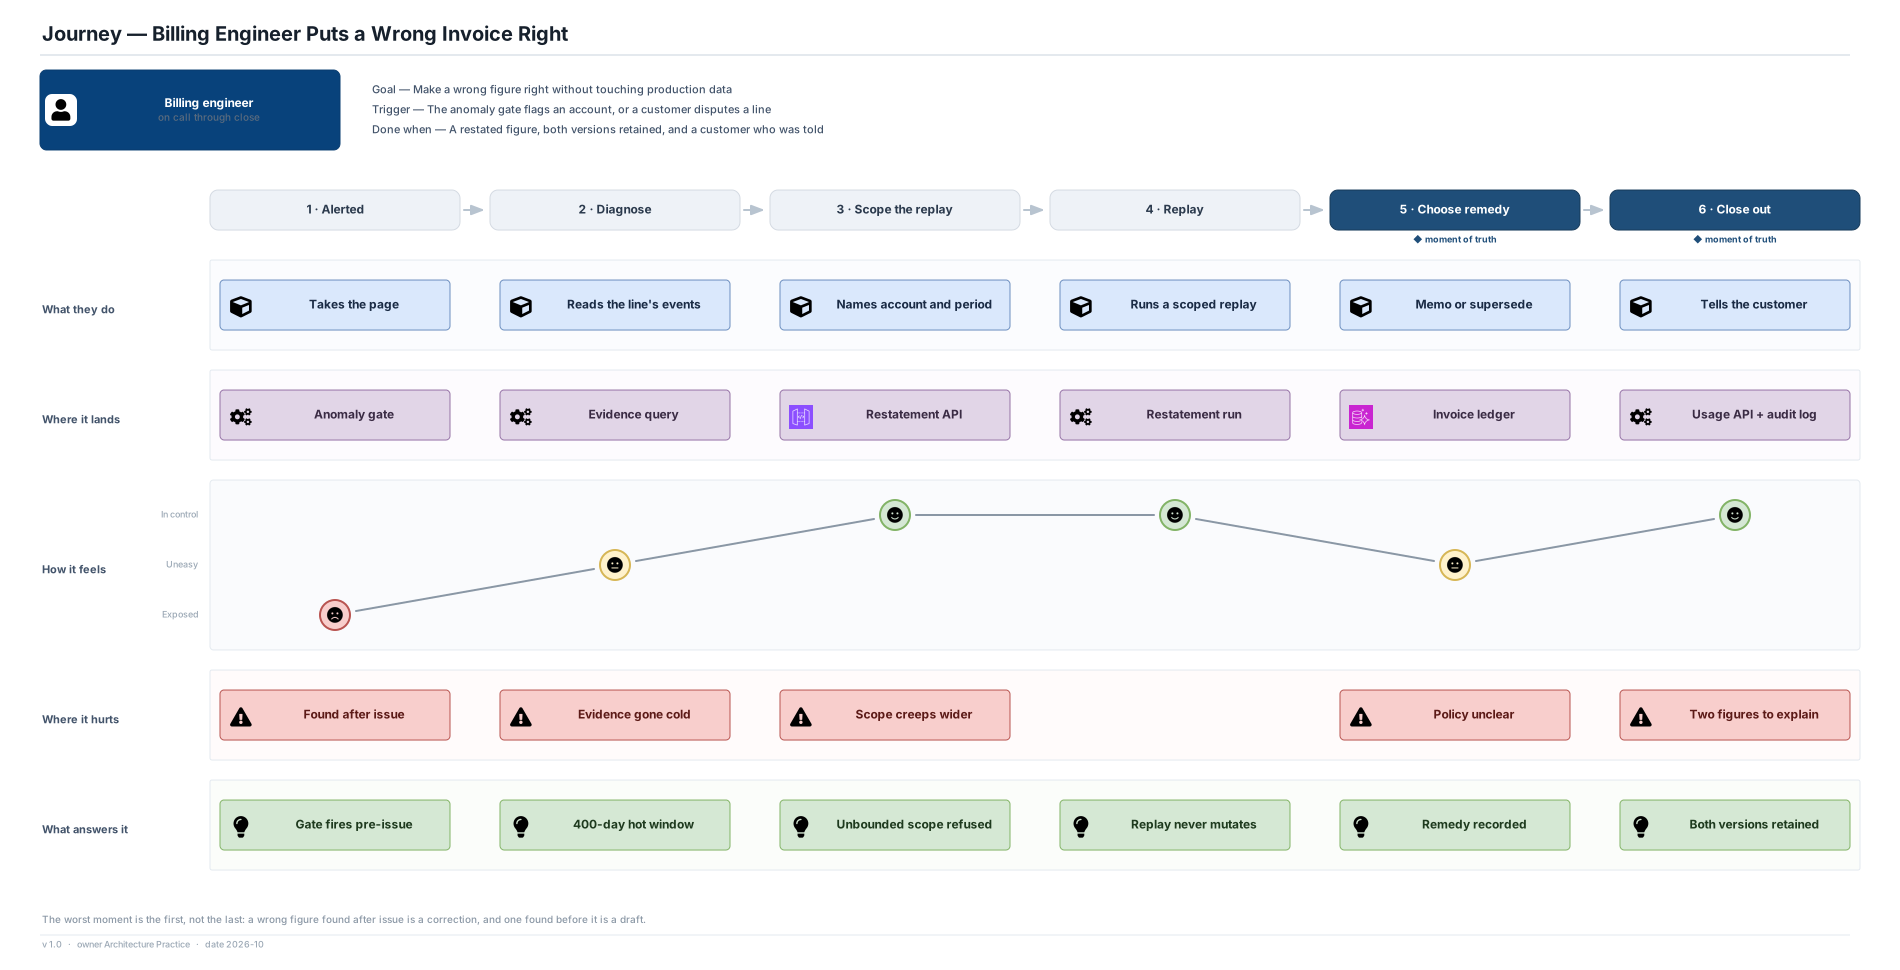
03 Customers Customer platform admin 1.5 M accounts Goal — Tell me today what this month will cost, and let me check your invoice against my own logs. Core journeys Predict this month's bill Reconcile an issued invoice Set a spend cap Customer finance owner procurement, audit Goal — Give me a line I can put in front of an auditor without opening a support ticket. Core journeys Export invoice evidence Dispute a line The business Pricing manager 2,000 plan versions Goal — Launch a meter and a tier without waiting for an engineering release. Core journeys Publish a plan version Preview a price change Finance controller monthly close Goal — Close the period on time, and never issue a number I cannot defend. Core journeys Review the draft run Issue or hold an invoice Authorise a credit memo Engineering and operations Billing engineer on call through close Goal — When a figure is wrong, let me replay the evidence instead of writing correction SQL. Core journeys Restate a wrong invoice Investigate a metering gap Product engineer ships new meters Goal — Instrument a meter and see within minutes whether my events are actually being billed. Core journeys Register a meter Verify acceptance Machines and third parties Product & edge services 250k events/s Goal — Hand off usage without ever waiting on the billing path. Core journeys Emit a usage event Payment, tax and ERP 3 systems Goal — Receive an issued invoice once, and the identical one on replay. Core journeys Consume invoice.issued External auditor annual Goal — Verify a figure independently, from evidence I can check myself. Core journeys Sample an invoice line Actors and Their Core Journeys Person or role Journey / task Application we own External / third party Goals are in each actor's own voice. Two journeys get their own map: predicting the bill, and putting a wrong one right. v 1.0 · owner Architecture Practice · date 2026-10 Actors and Their Core Journeys Four groups, nine actors, and what each of them is actually trying to get done. HTML page SVG draw.io

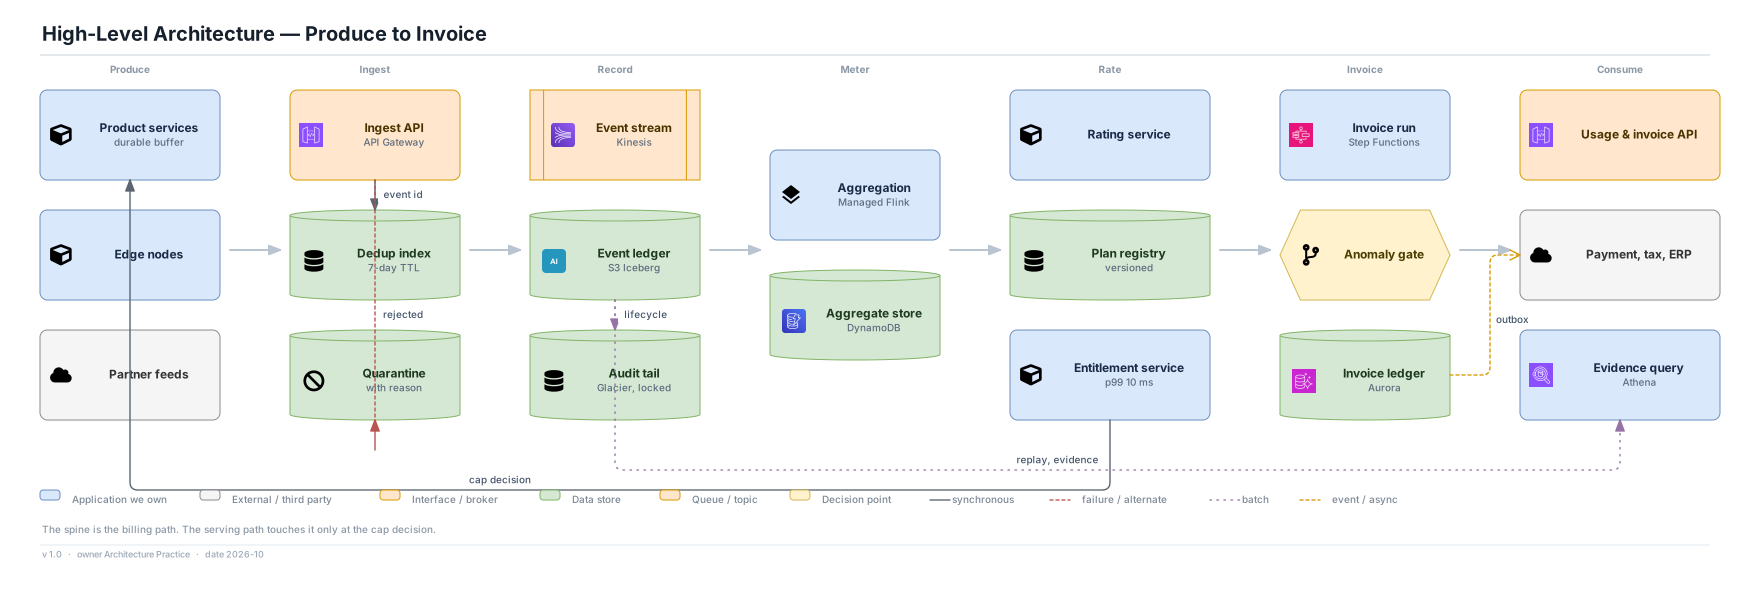
Structure

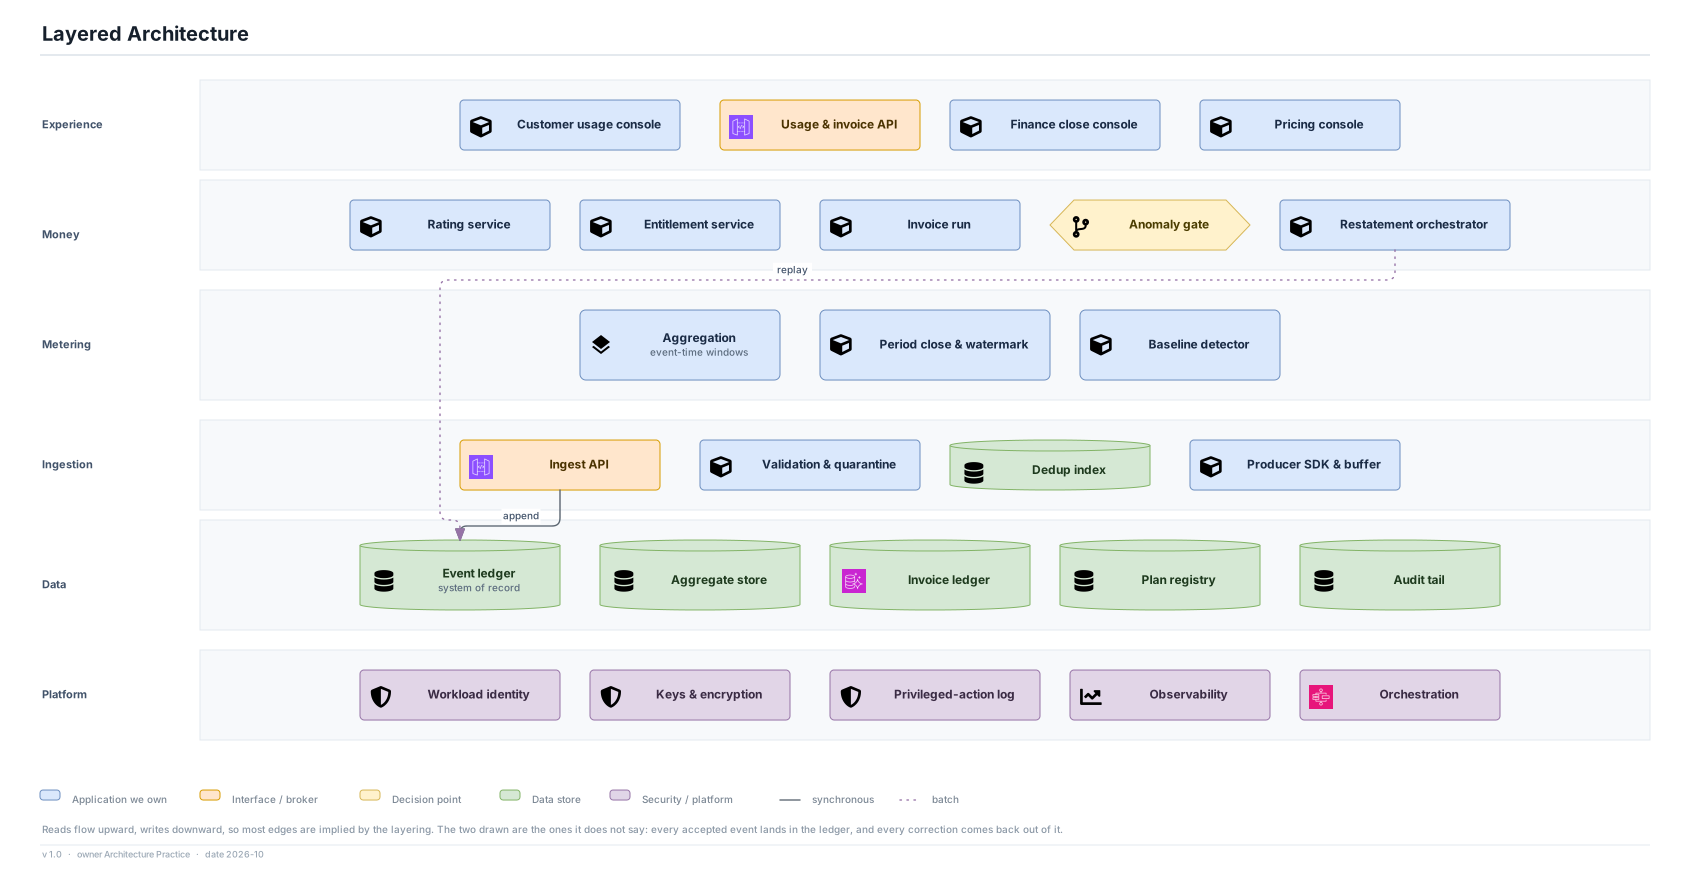
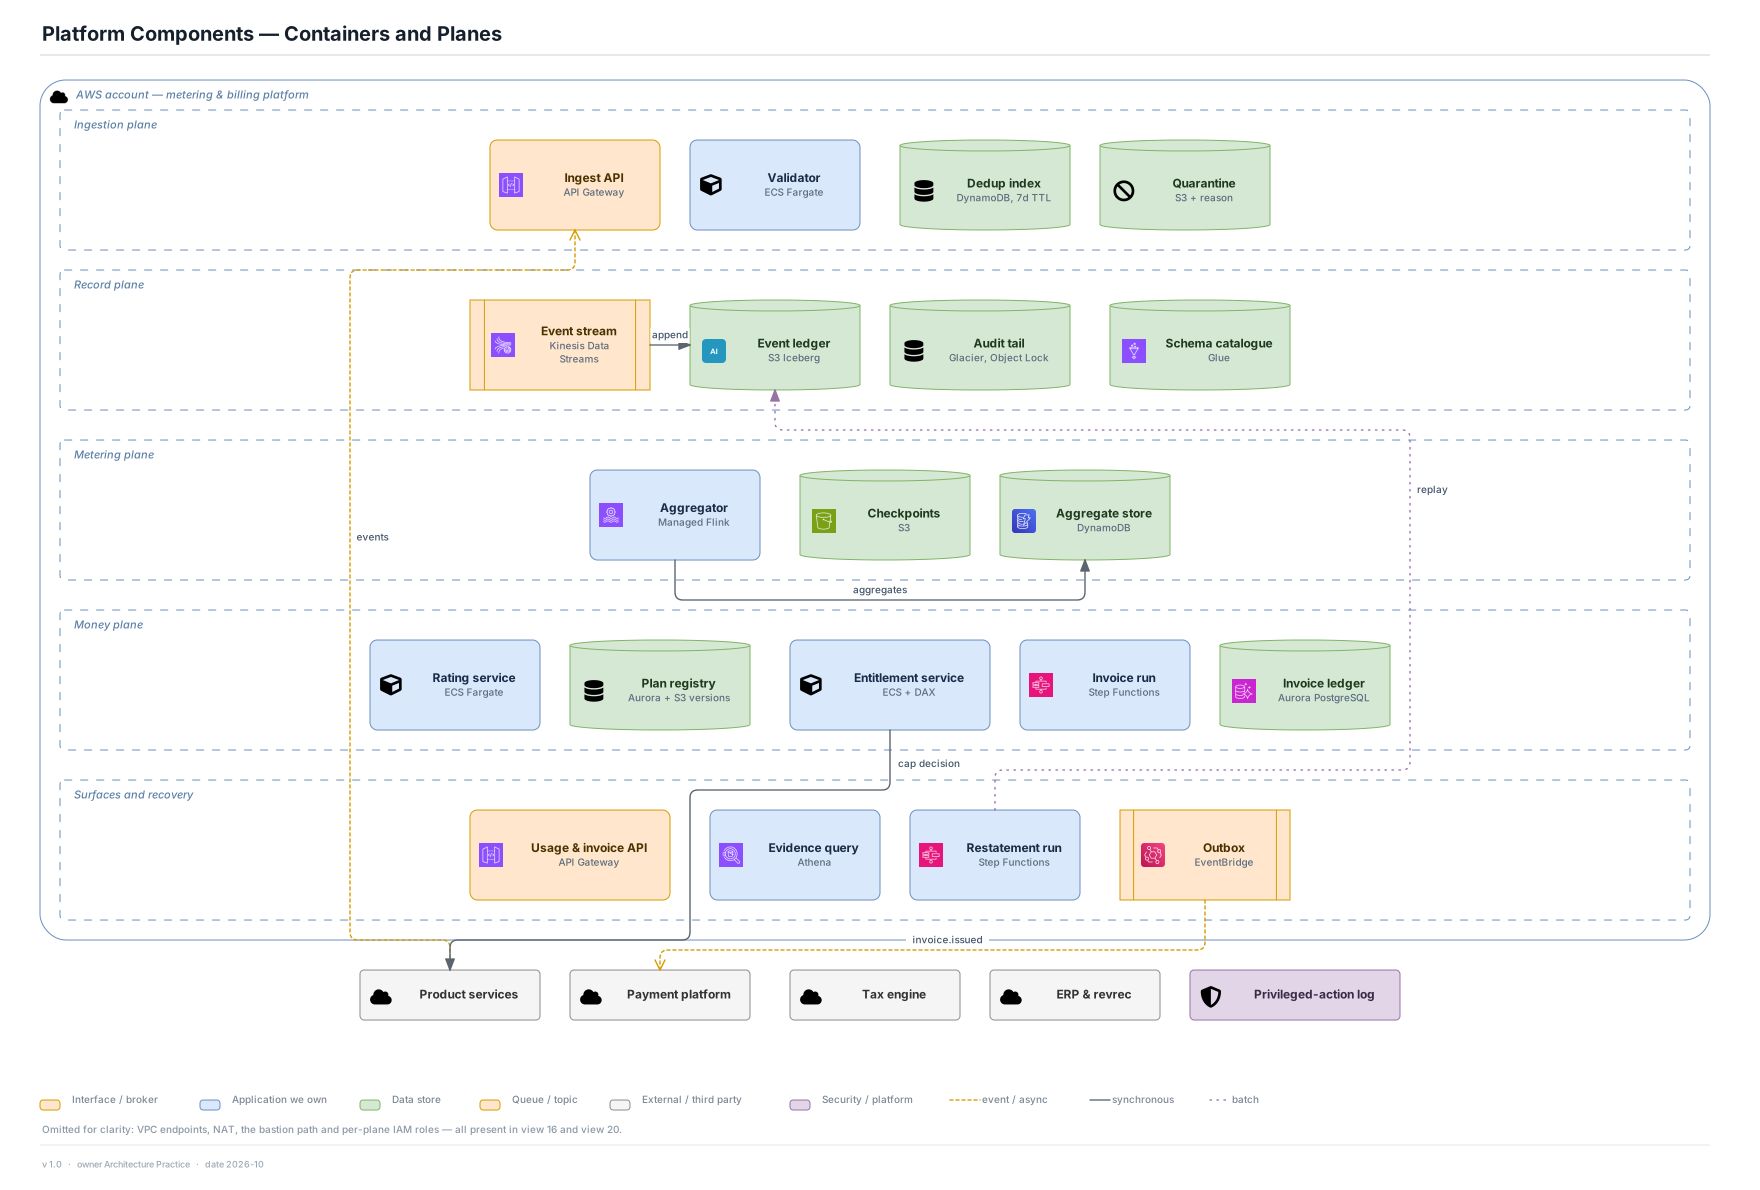
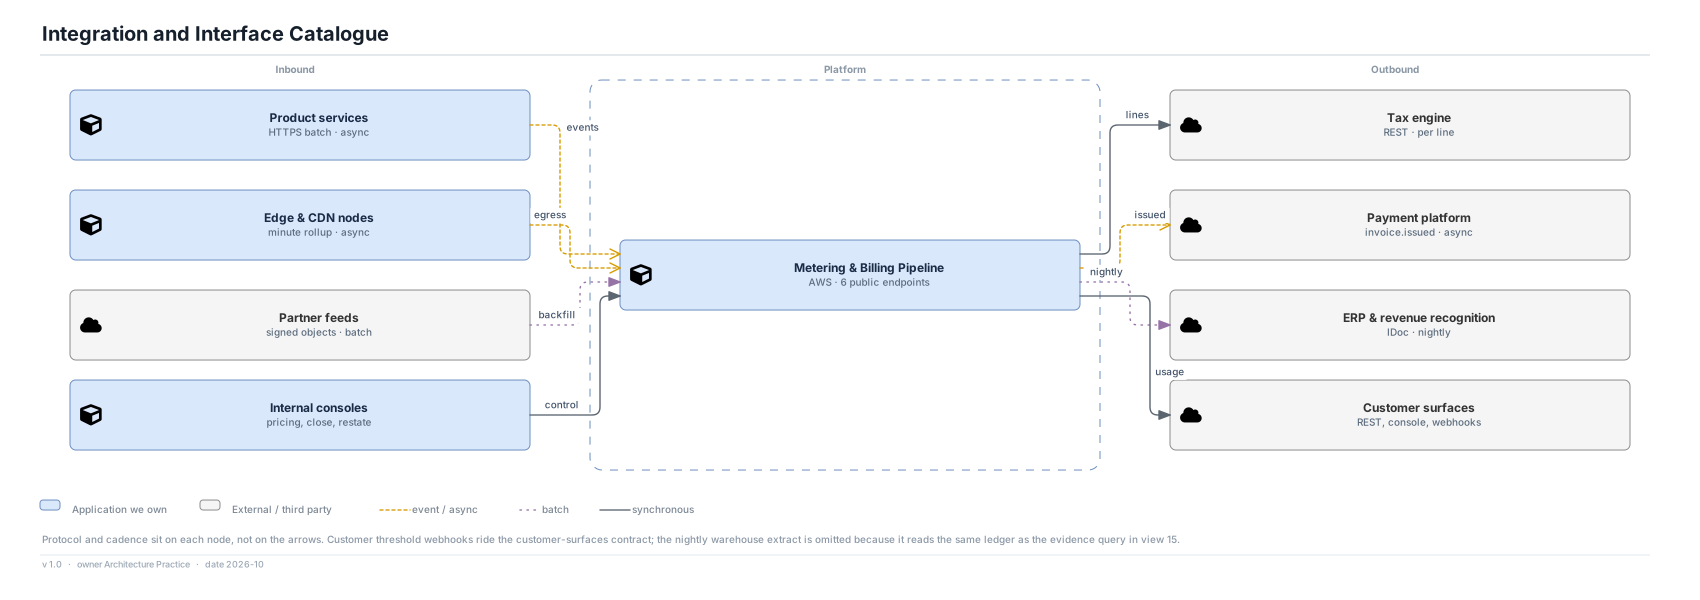
The parts, their planes, and the interfaces across the boundary.

Data

What is stored, which stores are truth, which are disposable, and how a figure traces back to its evidence.

Runtime

What actually happens when an event arrives, a period closes, and a figure turns out to be wrong.

Operations

How the platform is deployed, how pricing changes reach production, and what is watched.

Assurance

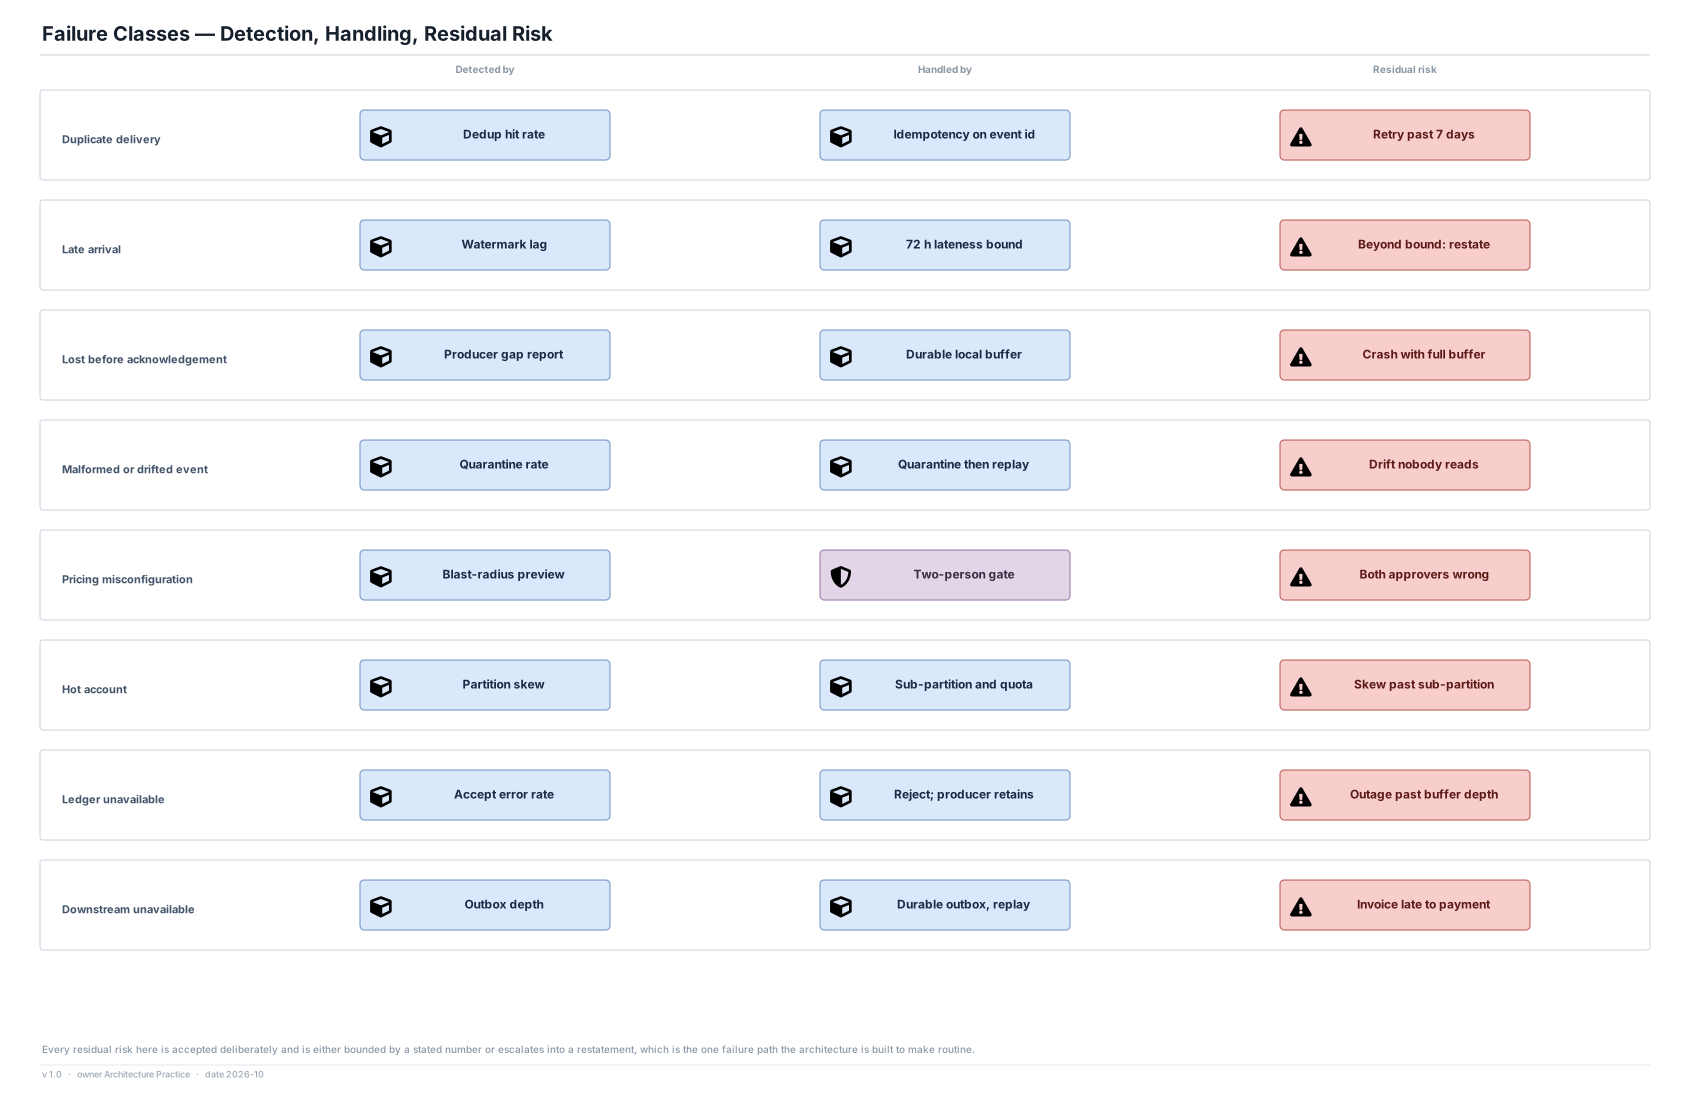
Why this is safe to run against revenue, and what is accepted as residual risk.

Architecture One-Pager

The problem, the shape of the answer, the decisions that carry it, and what a prototype should prove.

The event ledger is the system of record; every priced figure is a recomputable projection of it, so a correction is a replay and never an edit.

A customer calls 41.2 million times, streams 2.3 TB and holds 1,204 seat-days, and at the end of the month we send them one number. That number has to be right, has to be explainable line by line, and has to stay explainable months later when their auditor asks or their own logs disagree with ours. An analytics pipeline that loses a thousandth of its events is healthy; a billing pipeline that loses a thousandth has quietly given away revenue, and one that double-counts a thousandth has overcharged customers and will be found out. Meanwhile pricing changes faster than engineering releases, the free tier has to be enforced without putting a billing dependency in the product's request path, and the first time a figure is wrong there must be a remedy that is not correction SQL against production.

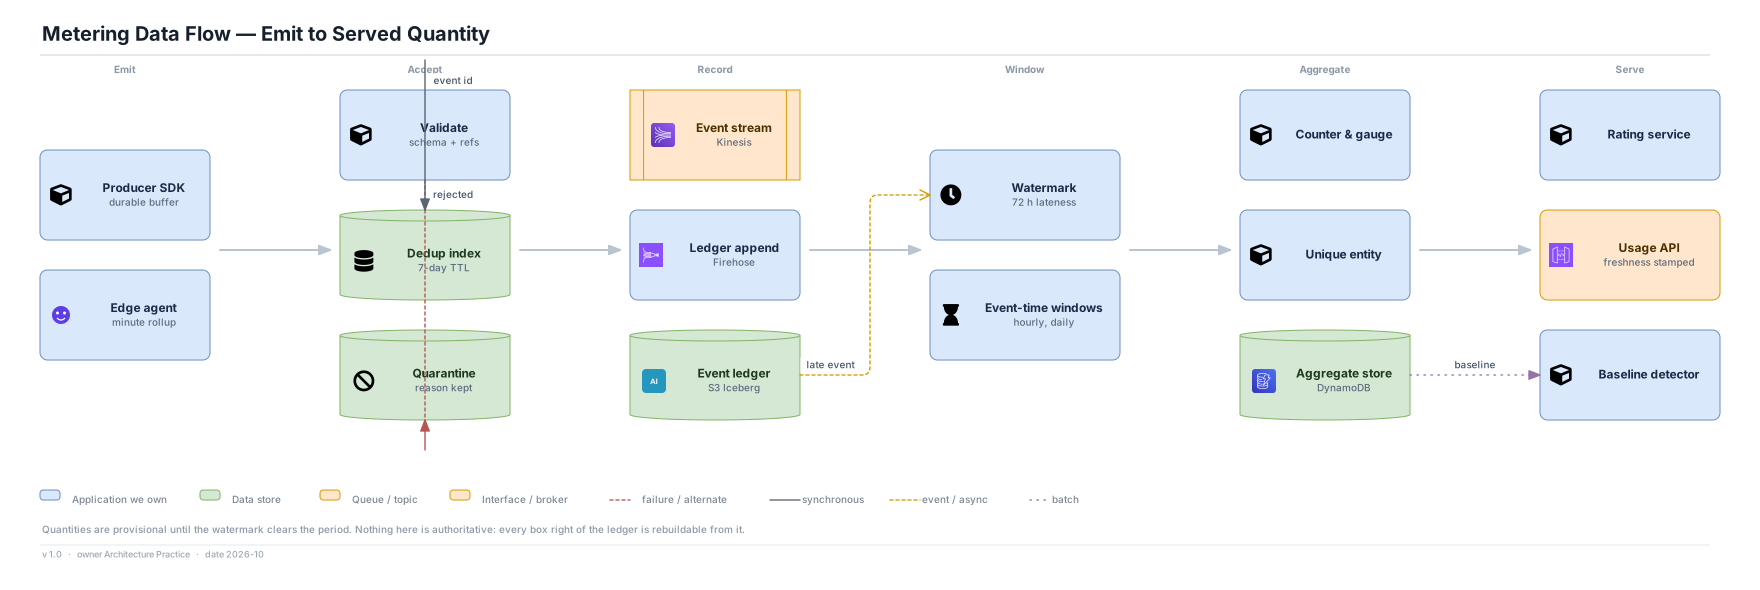
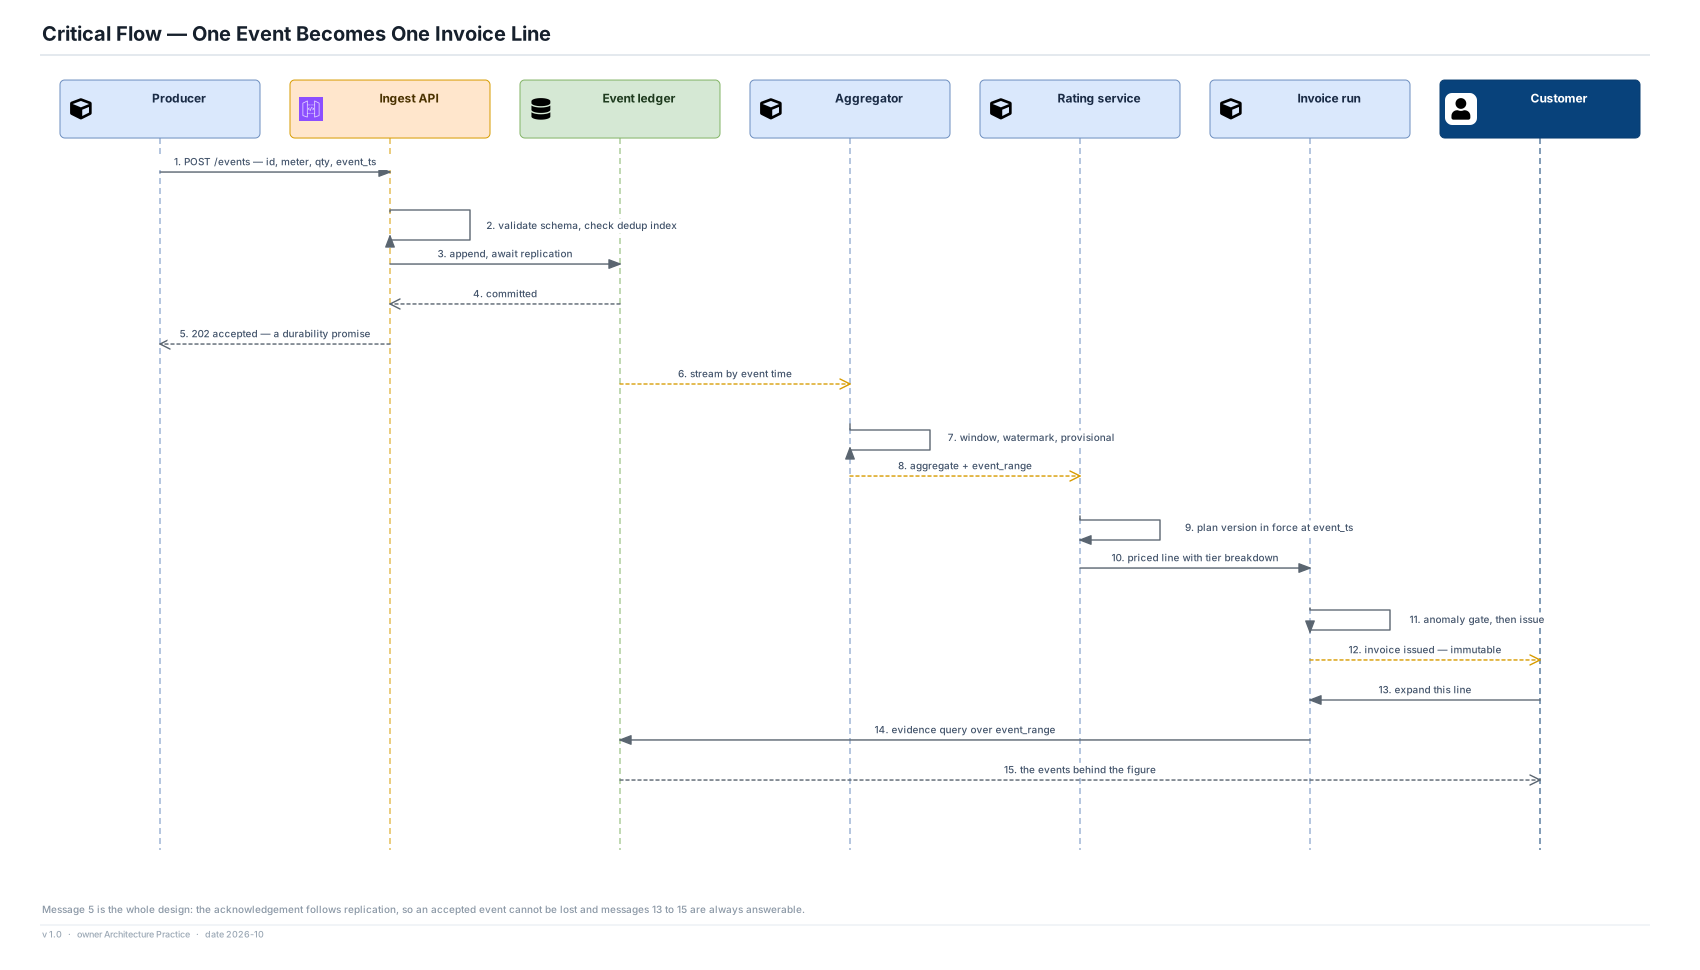
Accept usage events over one contract from product services, edge nodes and partner feeds, deduplicate on a producer-assigned identifier, and acknowledge only after the event is durably replicated into an append-only event ledger — so a 202 is a billing guarantee rather than a receipt. Aggregate from that ledger on event time, with an explicit watermark and a stated lateness bound, into per-account per-meter quantities that stay marked provisional until the period closes. Price the closed quantities against the plan version that was in force when the usage happened, apply credits and commitments in a documented order, assemble a draft invoice, pass it through an anomaly gate and a human, and issue it as an immutable record handed downstream through a replayable outbox. Everything downstream of the ledger — aggregates, priced lines, invoices — is a projection that can be deleted and rebuilt, which makes every class of error have the same remedy: a scoped, authorised replay that produces a second figure and retains the first.

What it is, and what it is not

An append-only event ledger as the system of recordRunning counters as truth, with raw events kept briefly for debugging
Event-time attribution with a stated lateness boundArrival-time counting, which moves revenue between months whenever a producer was offline
An acknowledgement that follows durable replicationA fast 202 that means the request was received
Corrections as scoped replays retaining both figuresCorrection SQL against the invoice, or a quiet edit before anyone notices
Pricing as versioned, immutable, two-person-gated configurationPrices in code, or a price row anyone in revenue operations can update
An invoice line that expands to its constituent eventsA total the customer is asked to trust

The decisions that are the architecture

01The ledger is the record; every priced figure is a projection

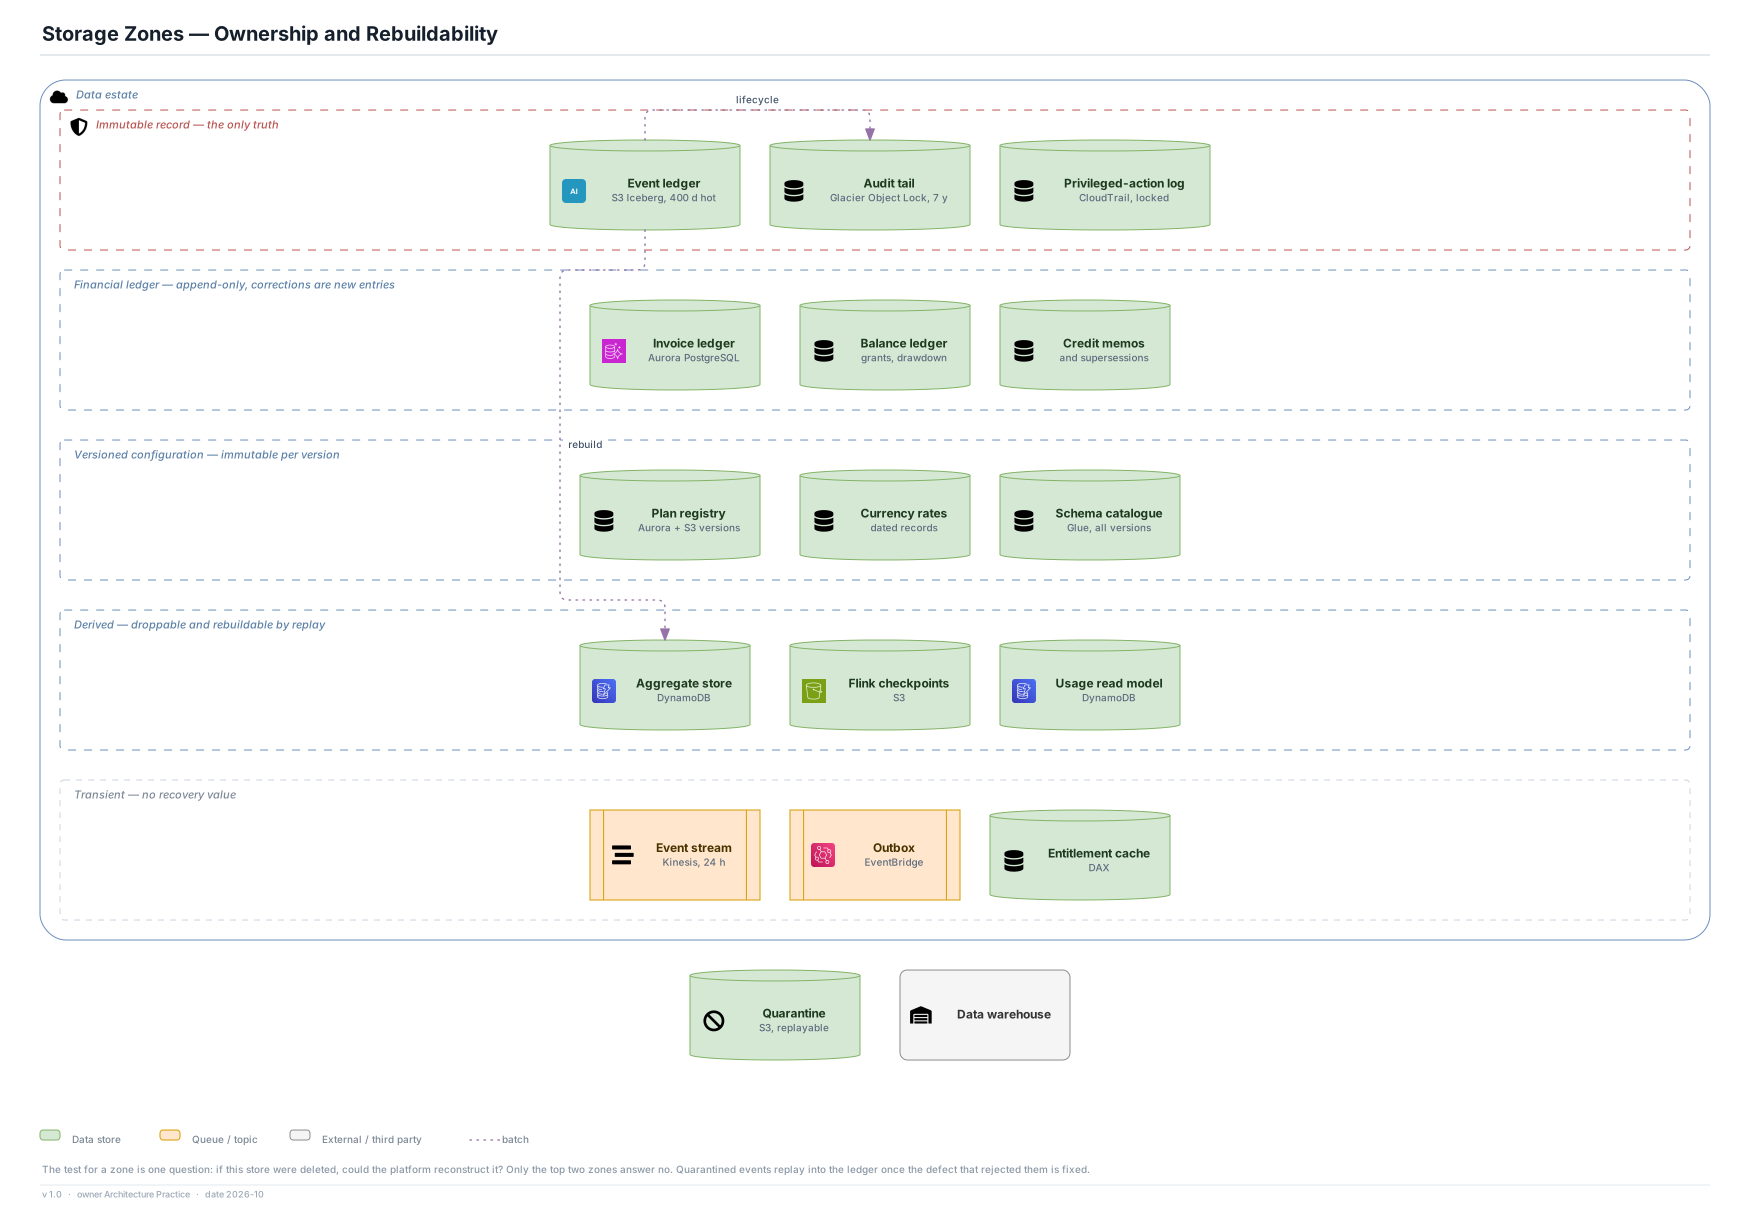
Aggregates, priced lines and invoices exist for performance and presentation. All of them can be deleted and rebuilt from retained events without changing a number, provided the rating configuration that applied at the time is still available — which is why plan versions are immutable and currency rates are dated. A bad transform, a wrong tier, a corrupt partition and an operator error therefore share one remedy instead of needing four.

ADR-01

02Corrections are replays; an issued invoice is superseded, never rewritten

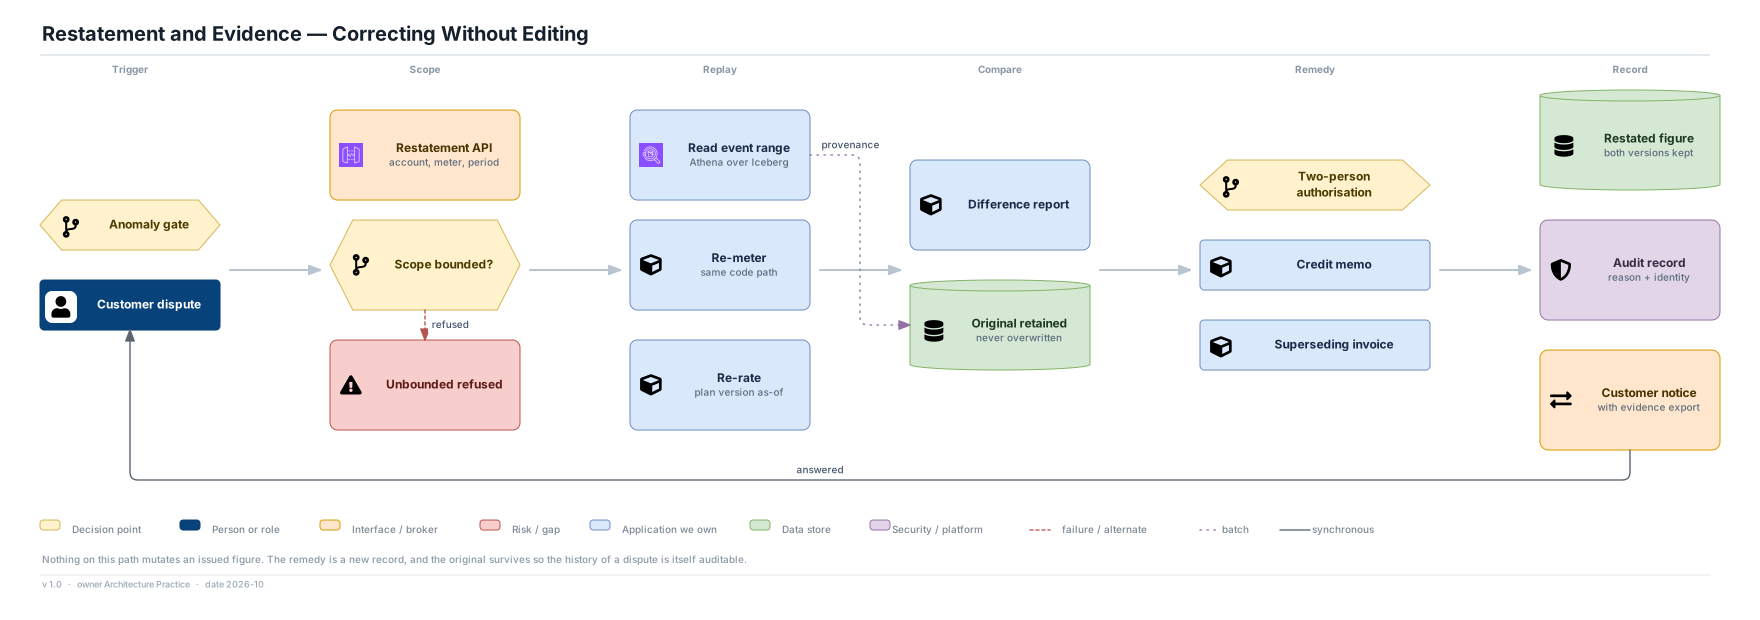
Nothing issued is mutated. A difference found after issue becomes a credit memo or a superseding invoice, both figures survive with the reason and the authorising identity, and the history of a disputed invoice is itself auditable. This is what makes the first wrong figure an incident with a procedure rather than an incident with a lawyer.

ADR-02

03Acknowledge only after durable replication

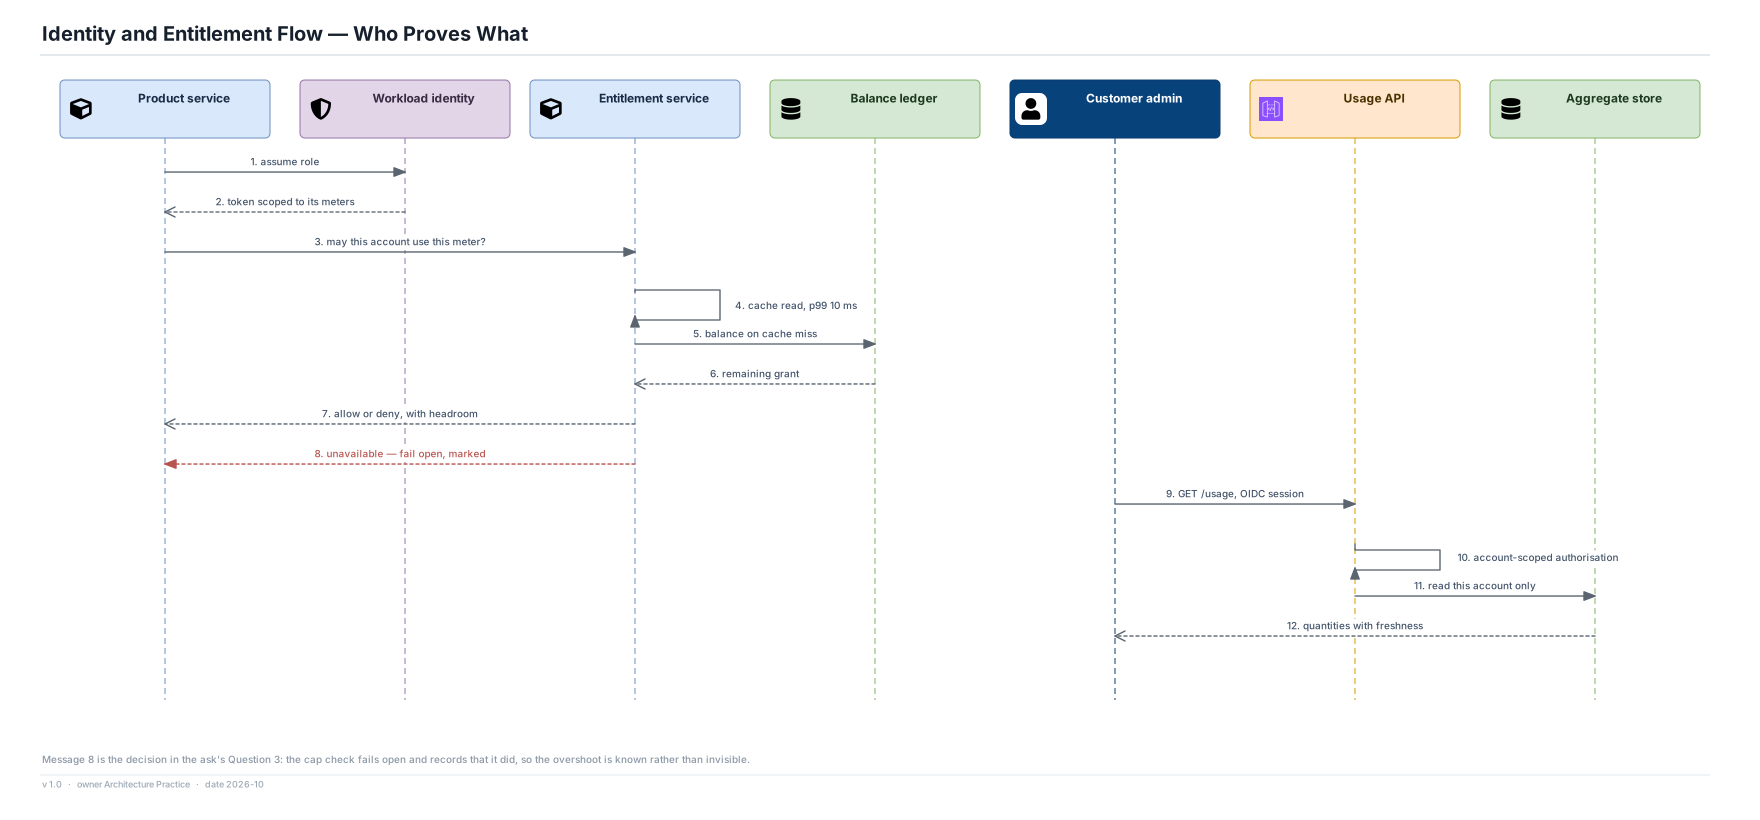
Ingestion fails closed and serving fails open: where durability cannot be guaranteed the event is rejected so the producer keeps it, and the product keeps serving regardless of the metering path's health. If an accepted event can be lost, the ledger is not the system of record and nothing in this design can be proved.

ADR-05

04Pricing is immutable configuration behind a blast-radius gate

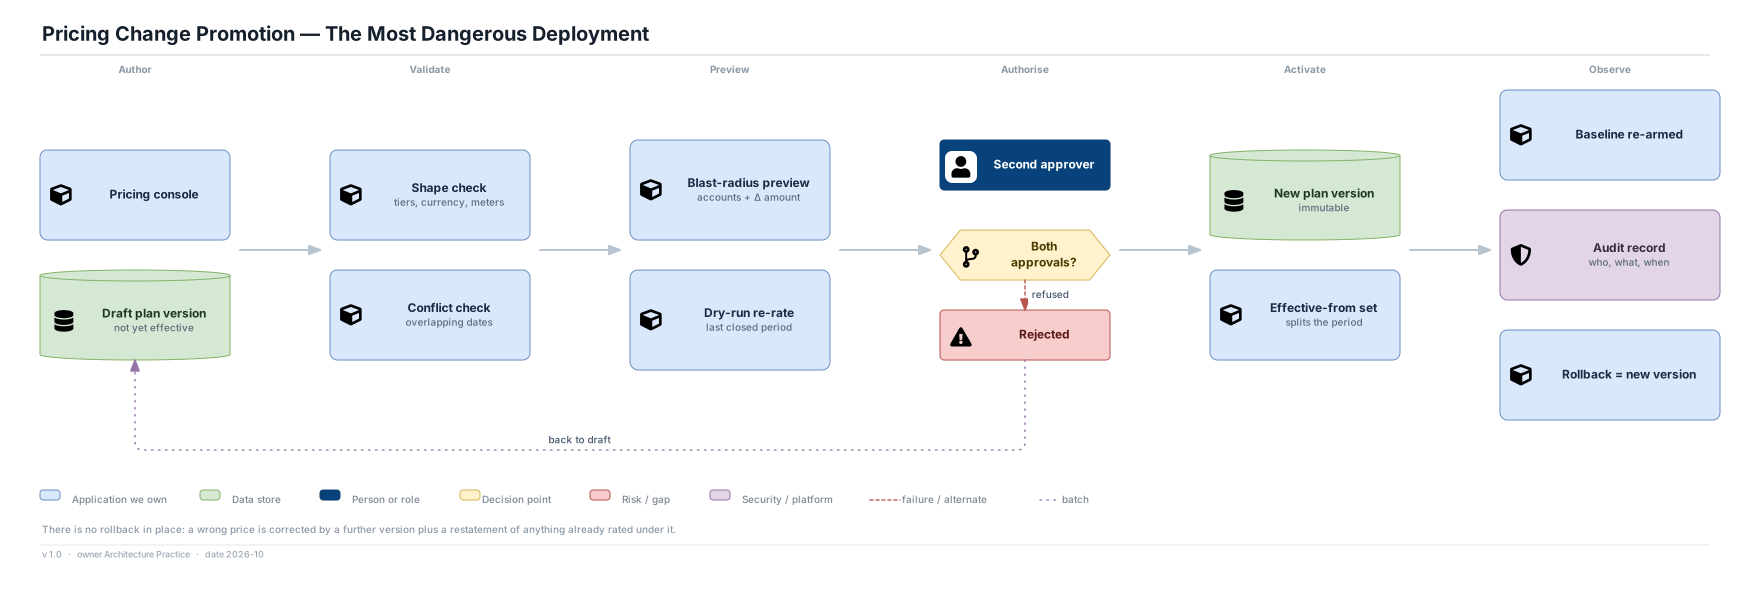
A new price is a new plan version with an effective-from date, never a mutation of a version already applied to issued invoices. Activation requires a preview of the accounts affected and the aggregate change in charged amount, plus two human approvals — because it is the one change in the platform applied uniformly to every affected account at once.

ADR-08

05Caps are enforced synchronously and fail open, marked

The product consults a sub-10 ms entitlement decision where a hard cap is required, and nothing else. When that decision is unavailable the call fails open and records that it did, so the overshoot is known rather than invisible. The alternative trades unbillable usage for refusing a paying customer during a billing outage.

ADR-11

06Partition by account; sub-partition the one that outgrows it

Keeping an account's events together makes per-account replay and dispute resolution a bounded scan rather than a full-period one, which is the operation the whole evidence story depends on. It also guarantees the largest customer eventually exceeds one partition, so sub-partitioning on the hot key is designed in rather than discovered.

ADR-12

Why this should still be right in ten years

Managed stream processors, event buses, relational engines and object stores will all be replaced inside a decade, and the billing SaaS market will have consolidated twice. The parts of this design that should outlive them are the ones that are claims about authority, evidence and blast radius rather than claims about products.

The seam is not a technology

"The ledger is the record and every priced figure is a projection" is a statement about which store is allowed to be wrong. It survives replacing Kinesis with Kafka, Flink with something newer, Aurora with anything transactional and S3 with any durable object store, because none of those changes where authority lives.

Provable arithmetic outlives every pricing model

Packaging fashions turn over every few years — seats, then consumption, then outcomes, then tokens. The requirement that every number be reproducible from retained evidence is indifferent to all of them, and it is the requirement that makes a new pricing model a configuration exercise rather than a migration.

Event time is a property of the world

Attributing usage to the period in which it occurred rather than the period in which it arrived is not an implementation detail that a better pipeline would remove. Producers will keep being offline, clocks will keep disagreeing, and a lateness bound will keep being the honest way to say when a period is final.

The three dangerous actions do not change

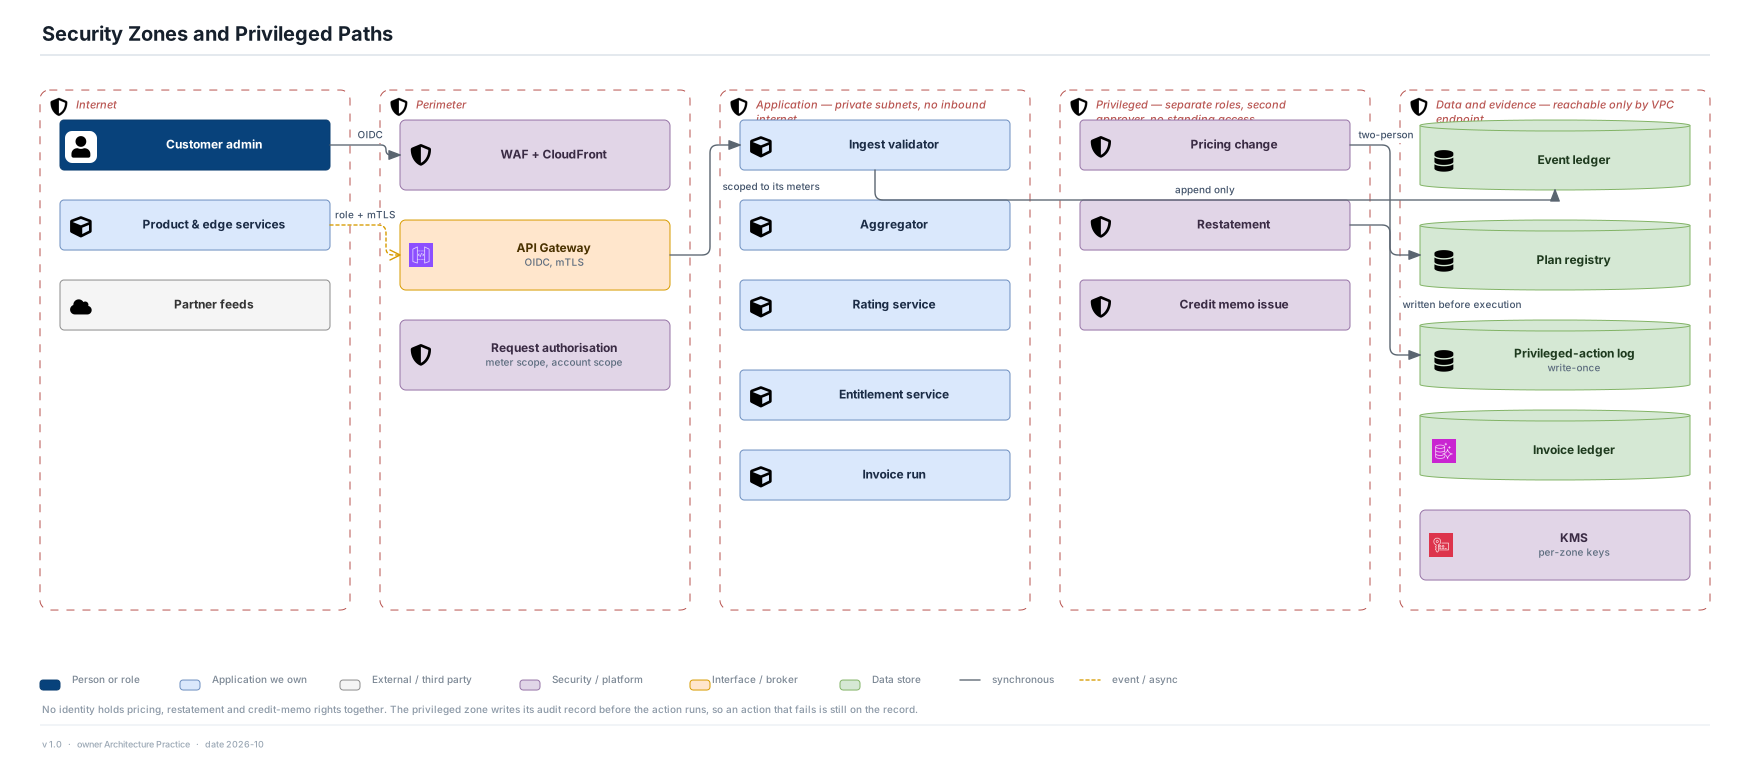
Changing a price, restating a figure and issuing a credit are the three ways to lose a lot of money quickly. Separating them across identities, requiring a second human, and writing the audit record before the action runs will still be the right controls when none of the services named here exist.

What is deliberately left replaceable

Rating and invoicing are the parts most likely to be bought rather than built later, so they are kept behind their own interface with the ledger upstream of them. A future decision to delegate rating to a billing platform costs a reconciliation obligation, not a rebuild — which is exactly the optionality ADR-14 is protecting.

Non-functional targets

Every figure below is a stated assumption for this design, taken from the requirement document and intended to be argued with. The view column points at where each one is visible in the set.

QualityTargetHow it is metView
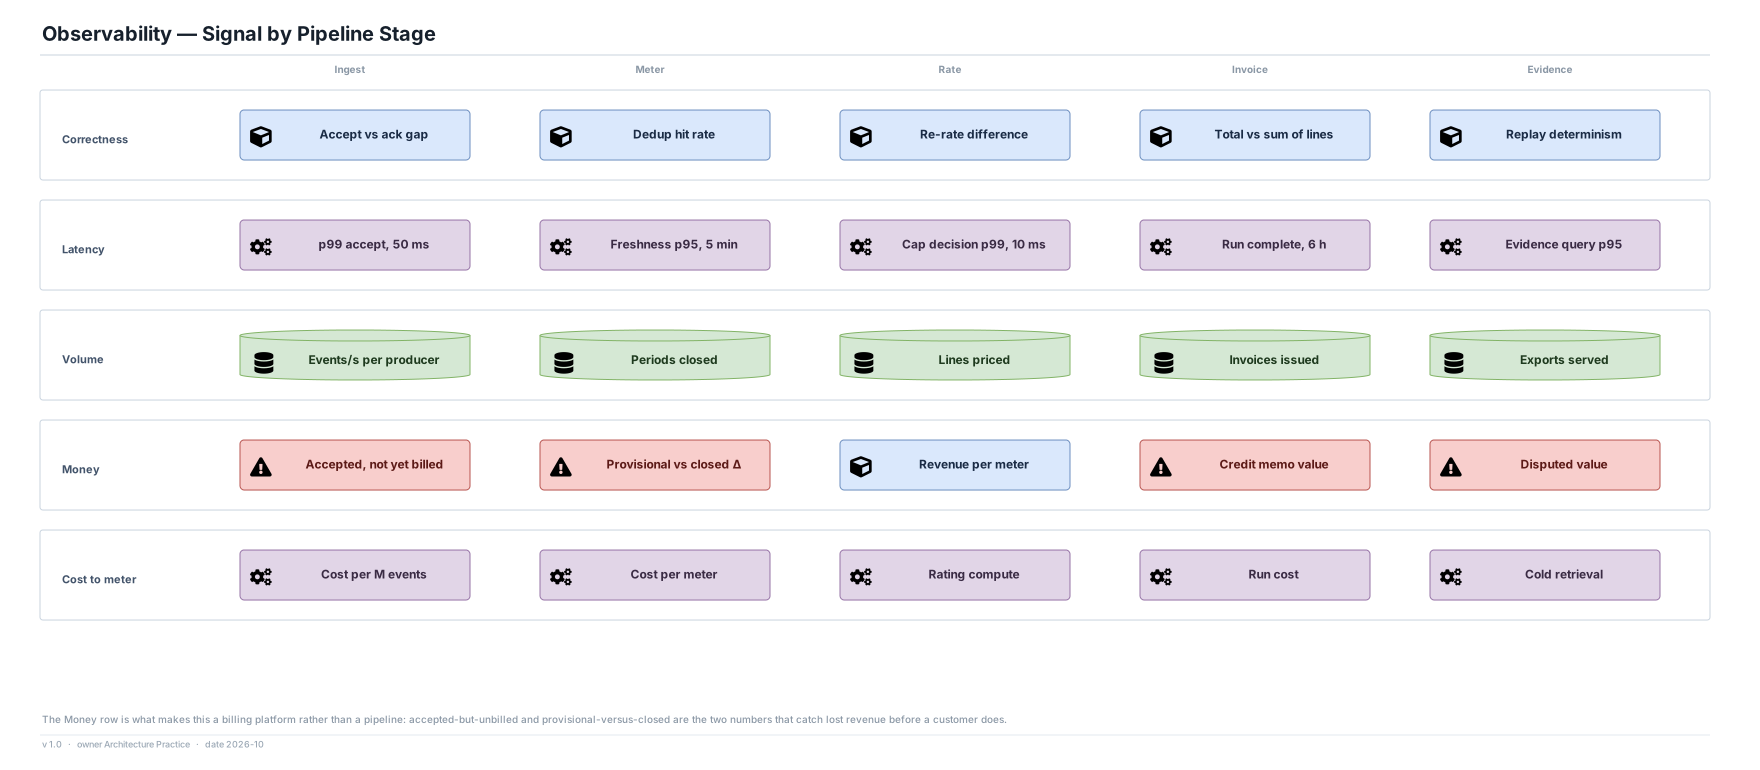
Billing accuracy ≤ 1 in 10^6 accepted events lost or double-counted after reconciliation Idempotency on the producer-assigned identifier, acknowledge-after-replication, idempotent aggregation, and a correctness signal row that compares invoice totals against the sum of their lines 18
Ingestion availability ≥ 99.99% monthly successful acceptance Zone-redundant stateless ingest behind a regional gateway, with a durable producer-side buffer so a rejection is recoverable rather than lost 16
Entitlement availability ≥ 99.99% monthly Cached decisions with a balance read only on miss; fails open and marks the overshoot when unavailable 21
Event acceptance latency p99 ≤ 50 ms, p99.9 ≤ 200 ms in-region Replication inside the accept path, kept affordable by batching 500 events per request from the producer SDK 12
Cap decision latency p99 ≤ 10 ms in-region In-region cache in front of the balance ledger; the figure that decides whether synchronous caps are viable at all 21
Usage freshness p95 within 5 min of the event, p99 within 15 min Continuous event-time aggregation into a read model, with freshness stamped on every figure served 09
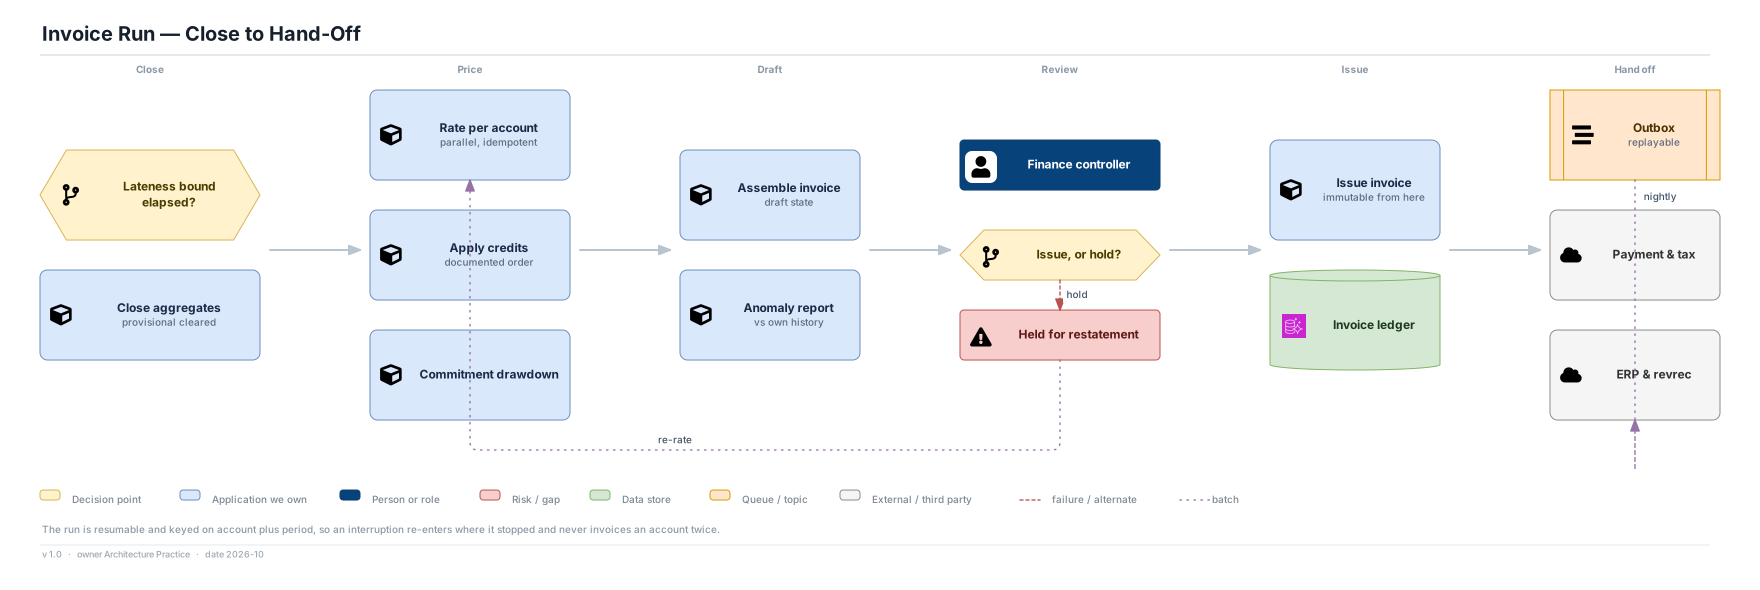
Invoice run All accounts closed within 6 h of period close; RTO 4 h Idempotent run parallel across accounts, resumable and keyed on account plus period 13
Throughput 250,000 events/s per region, 5× burst for 10 min Partitioned ingestion and aggregation on account, with sub-partitioning available for a hot account 07
Volume and scale 1.5 M accounts, 400 meters, 2,000 plan versions, ~20 TB/month compressed Columnar event ledger with lifecycle tiering; meters and pricing shapes held as configuration rather than code 10
Retention Events queryable 400 days, cold 7 years; dispute window 60 days Hot Iceberg tables sized for an annual cycle plus the dispute window, then write-once cold storage for statutory audit 10
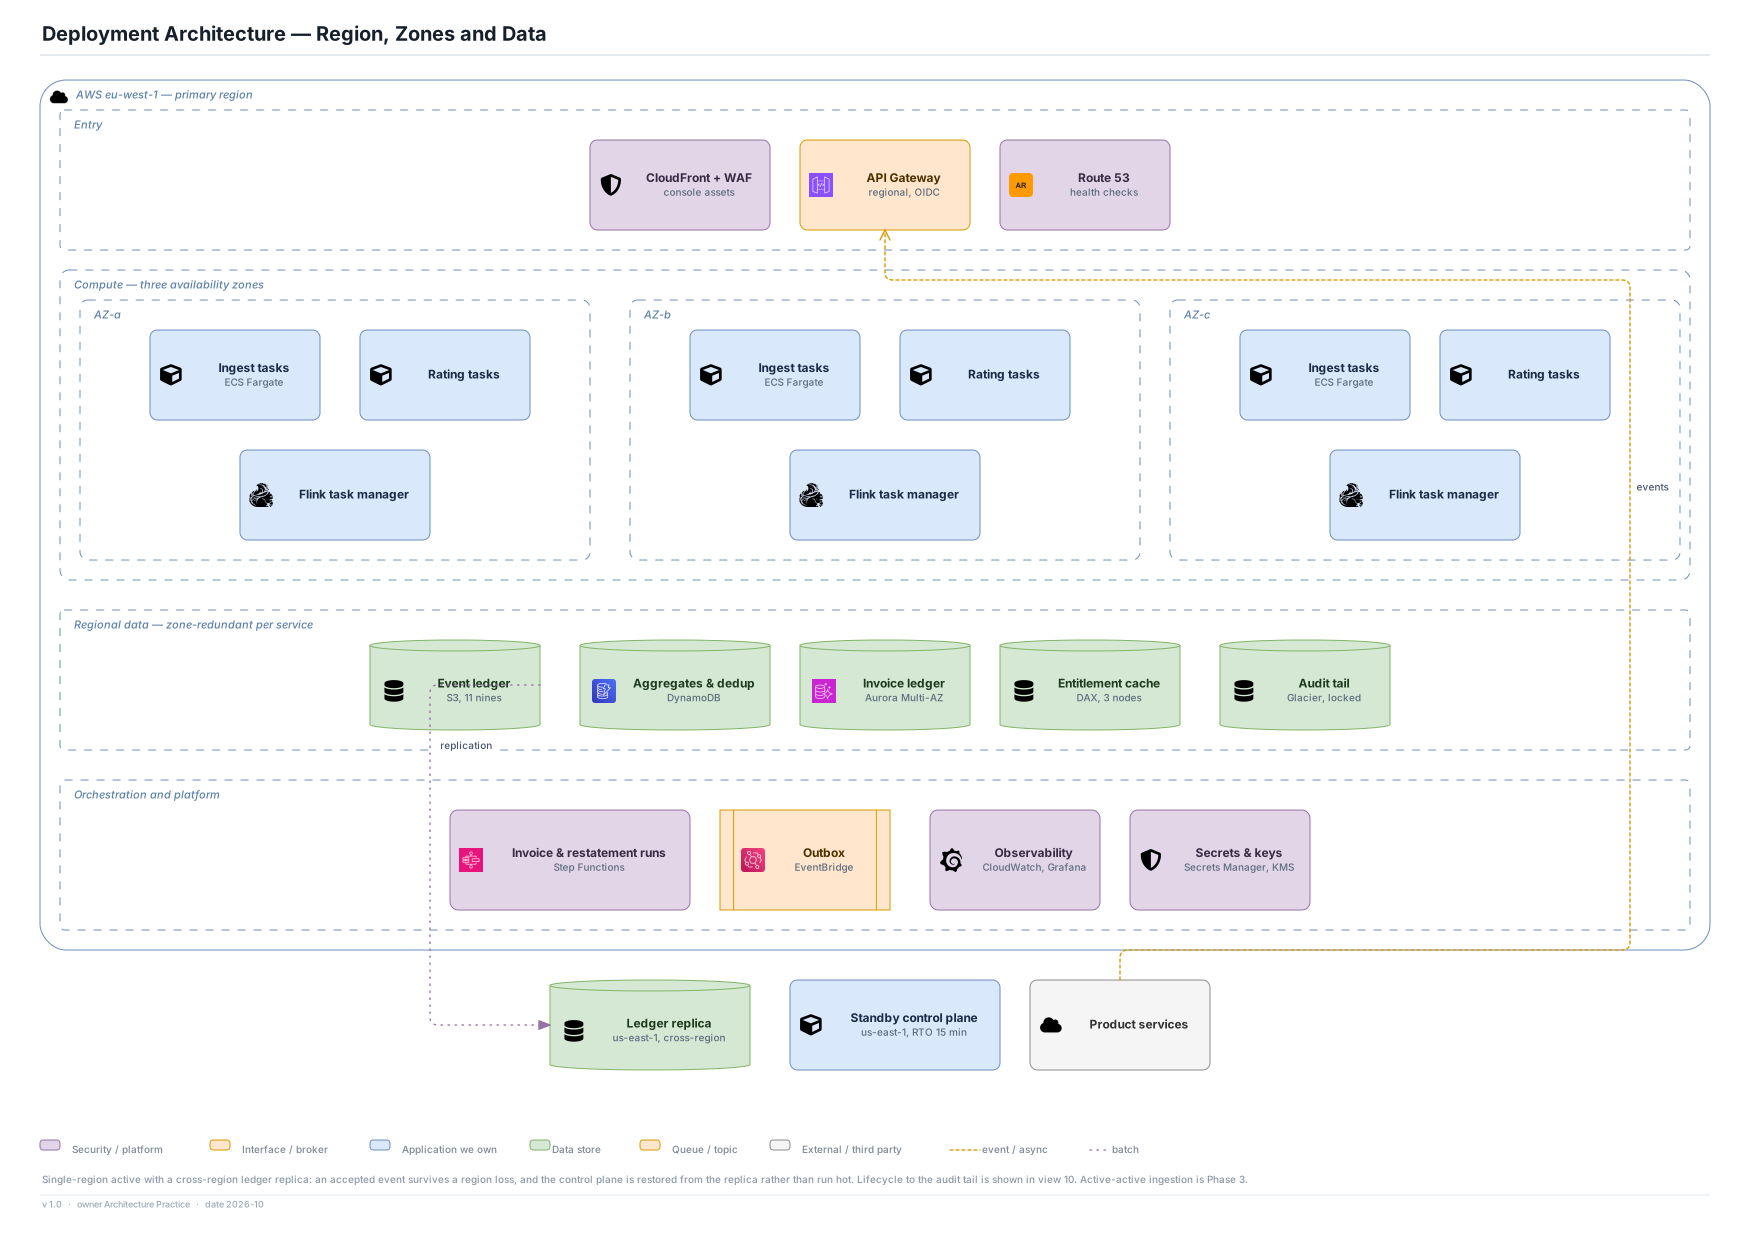
Recovery point RPO 0 for acknowledged events Acknowledgement follows durable replication, so there is no window of accepted-but-lost usage; a cross-region replica survives the loss of the region 16
Restatement One account's 90 days replayed through metering and rating within 30 min Bounded scan over the account's own ledger partition, through the same code path as the original 15
Pipeline cost < 0.5% of metered revenue, reported monthly Incremental aggregation, compressed columnar storage, cold tiering, and cost reported per meter so an unprofitable dimension can be found 18

Scope

In scope

  • One documented inbound event contract for product services, edge nodes, batch jobs and partner feeds, with workload-identity authentication scoped to specific meters
  • An append-only event ledger as the system of record, queryable for the dispute window and write-once beyond it
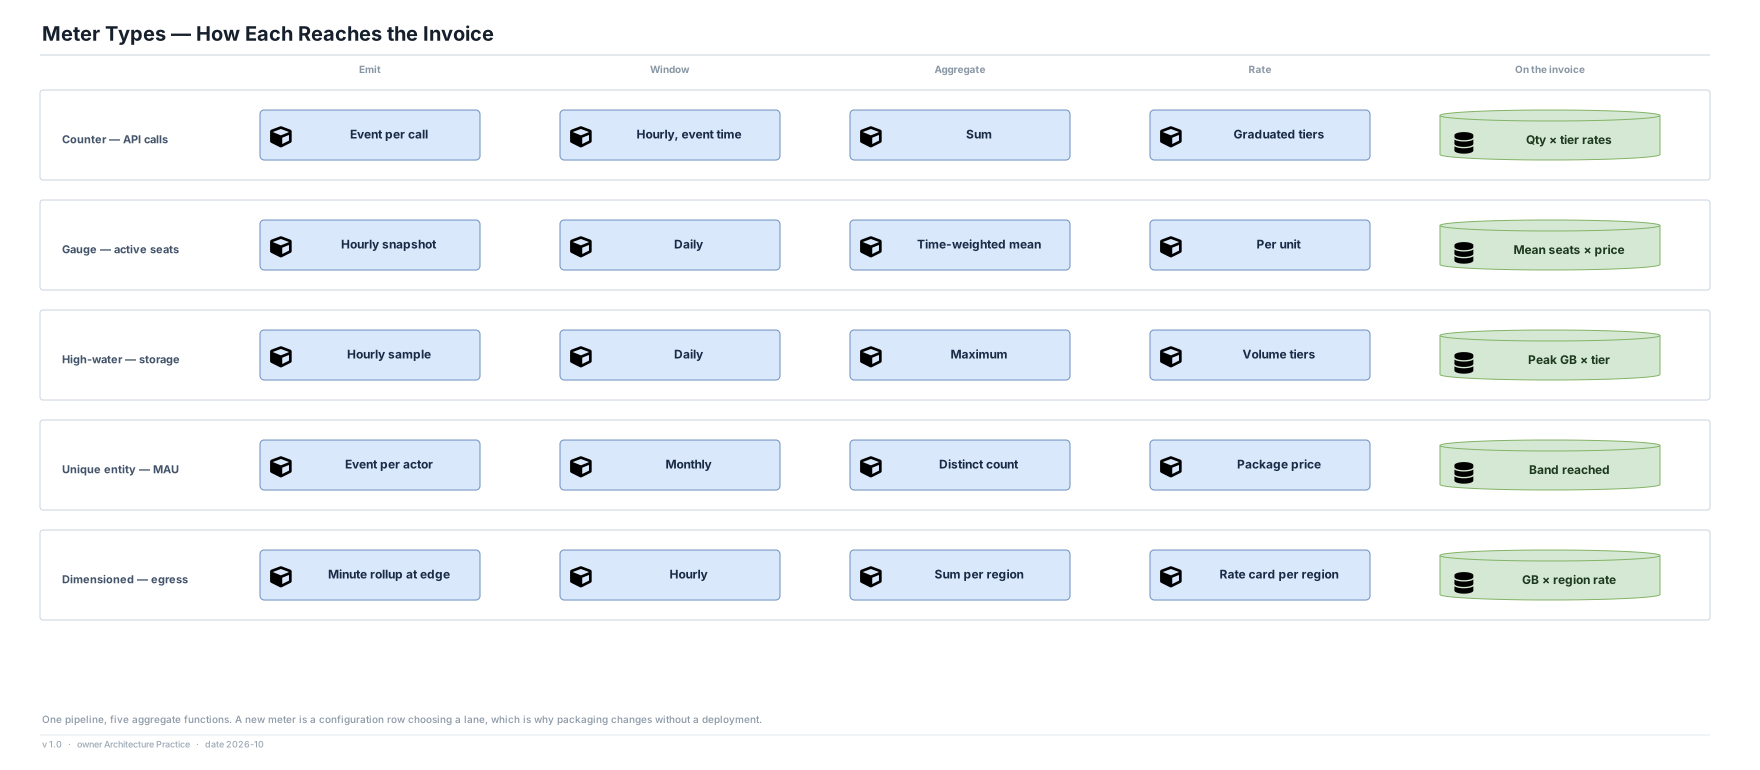
  • Event-time aggregation with watermarks and a stated lateness bound, for counter, gauge, high-water-mark, unique-entity and dimensioned meters
  • Versioned immutable plan configuration with volume and graduated tiers, commitments, discounts and dated currency rates
  • Rating at period close, credit and commitment drawdown in a documented order, and an idempotent resumable invoice run with a draft state and an anomaly gate
  • A low-latency entitlement decision for hard caps, and threshold events on allowances, caps and commitments
  • Customer-facing usage and invoice surfaces at the same grain over API and console, with freshness labelled and event-level evidence on request
  • Scoped, authorised restatement retaining both figures, and an immutable audit record of every privileged action

Explicitly out of scope

  • Payment capture, dunning and collections — a downstream consumer of an issued invoice, with its own owner
  • Tax determination and revenue recognition — the platform supplies line detail and posts, and determines neither
  • Pricing strategy and packaging design — the platform makes a new shape cheap to express, and takes no view on whether it is a good idea
  • The product's own instrumentation decisions: which meters exist is a product question, and a dimension never emitted cannot be backfilled
  • Customer entitlement modelling beyond balances, caps and commitments — contract management lives elsewhere

What a four-week prototype should prove

The prototype's job is to falsify the two claims the whole design rests on: that an acknowledgement can be a durability guarantee inside a 50 ms budget, and that a restatement can be a routine replay rather than an incident. Everything else is engineering.

  1. One meter of each of the five types, 50,000 events/s sustained for an hour, from a producer SDK with a durable buffer
  2. A ledger partition for one synthetic account large enough to exceed a single partition's capacity, so sub-partitioning is exercised rather than designed
  3. Two plan versions with an effective-from date inside the period, to prove a mid-period change splits rather than reprices
  4. A full close-to-issue run over 10,000 accounts, interrupted halfway and resumed
  5. A scoped replay of one account's 90 days, compared byte-for-byte against the original figure
  • The ingest task is killed between the ledger write and the acknowledgement: the producer retries, the duplicate is suppressed on event id, and the account's total is unchanged
  • An event arrives 70 hours late and lands in the correct closed-pending period; one arriving at 74 hours is refused into the period and surfaced as needing restatement
  • The aggregate store is deleted entirely and rebuilt by replay: every closed period reproduces its exact prior quantity
  • A price is published with a wrong tier boundary, caught by the blast-radius preview before activation, and then — deliberately activated anyway — corrected by a further version plus a restatement of the accounts already rated
  • The entitlement cache is made unavailable: the product keeps serving, the overshoot is recorded, and the recorded overshoot reconciles against the events actually metered

Open risks, carried rather than hidden

RiskIf it landsResponse
The deduplication index is the cost surprise: every event identifier held for 7 days at 250,000 events/s A line item that can rival the cost of the ledger itself, discovered after the architecture has committed to producer-assigned identifiers Size it explicitly in the prototype, keep the window at the shortest value the longest producer retry actually needs, and treat a shorter window plus a content fingerprint as the documented fallback rather than a redesign
Replay determinism is assumed, not proven A non-deterministic aggregate — an unordered distinct count, a floating-point sum — would make every restatement arguable and quietly destroy the evidence story Make replay determinism a watched signal with a daily scheduled replay of a known account, and keep unique-entity counting exact rather than approximate until a cost argument forces otherwise
The anomaly gate trains its reviewers to approve A fast-growing account trips the baseline every month, reviewers learn to click through, and the one real error arrives looking like all the false ones Baseline against the account's own trajectory rather than a flat threshold, re-arm on deliberate price changes, and report gate precision as a signal so a useless gate is visible
A single monthly run concentrates all the risk into one window A defect found during close has hours rather than days, and the remedy competes with the run itself for the same people Per-account cycle anchors spread the load across the month from the start; staggering is in the MVP precisely because retrofitting it means restating the accounts that moved
Fail-open entitlement during a long outage produces usage nobody is entitled to Unbillable consumption that is recorded but not recoverable, concentrated in exactly the accounts with the least headroom Bound it with a secondary local limit in the producer SDK — not in the MVP, and the first thing to add if the recorded overshoot ever exceeds the accuracy target
An open dimension map is an open cardinality risk A producer that puts a request identifier in the dimension map makes the aggregate grain per-event, multiplying metering cost without changing revenue Report storage and compute cost per meter, alert on dimension cardinality growth, and make meter registration the place where a new dimension key is reviewed rather than discovered

Architecture Decision Record

Why every component and every technology on these 22 views is what it is, and what each choice costs.

Fifteen decisions make up this architecture. Everything else across the twenty-two views is a consequence of one of them, and each record carries the question that forced it, how it is realised on Amazon Web Services, the alternatives including the ones that are right for a different organisation, the conditions that would flip the choice, why it should still hold as scale and technology change, and the transferable lesson. Seven of the records answer a Core Architecture Question from the requirement document; two of those questions are deliberately left open and say so.

Status of this document. This is a design, not a report on a running system. Every rate, latency, volume, retention and cost figure in this package is a stated assumption, chosen to be defensible for a usage-based SaaS at roughly Series-C to growth scale and sized from a reference workload of 1.5 million billable accounts, 400 distinct meters, 2,000 live plan versions and 250,000 usage events a second. They are written as numbers so that they can be argued with and corrected: an explicit figure forces the architecture to commit, and a vague one cannot be reviewed. Where a number drives a decision, the record says which way the decision goes if the number turns out to be wrong.

How to read a record

QuestionThe forcing question: why a decision was needed at all.
ContextThe requirement, the scale and the constraint that make it hard.
DecisionWhat this architecture does, stated so it can be checked.
How it is realised on AWSThe concrete mechanism: which service or package, configured how, in which subscription.
Options weighedChosen, rejected, deferred, or right elsewhere, with the reason for each.
ConsequencesWhat the choice buys and what it costs, both kept visible.
Choose differently whenThe conditions that would flip the decision for your system.
Why it holds up over timeWhat keeps the decision right as scale, staff and technology change.
LessonThe principle that transfers beyond this platform.

Decision map

Truth and recomputation 3

The decisions that make every figure in the platform derivable rather than precious.

ADR-01The event ledger is the system of record; every priced figure is a recomputable projection ADR-02Corrections are recomputations; an issued invoice is superseded, never rewritten ADR-03Every aggregate carries the event range that produced it

Capture and delivery 4

What it takes for an accepted event to be billable exactly once, and for a late one to land in the right month.

ADR-04Idempotency sits on a producer-assigned event identifier, with a seven-day window ADR-05Acknowledge only after durable replication — fail closed on acceptance, open on serving ADR-06Usage is attributed by event time, with a 72-hour lateness bound and provisional periods ADR-07Rejected events are quarantined with their reason and replayed, never discarded

Money and policy 3

Where pricing lives, when it is applied, and who is allowed to change it.

ADR-08Pricing is versioned immutable configuration behind a blast-radius gate and two approvals ADR-09Rate at period close; stream-rated provisional figures are a second-phase addition ADR-10The remedy for a post-issue error is left to accounting policy, and recorded per correction

Enforcement and the serving path 1

How much of the billing platform the product is allowed to depend on.

ADR-11Hard caps are enforced synchronously, and the check fails open with the overshoot recorded

Scale and retention 2

The two axes that decide what this costs: how events are partitioned, and how long they are kept.

ADR-12Partition the ledger by account, and sub-partition the account that outgrows a partition ADR-13Raw events stay queryable for 400 days and write-once cold for seven years

Control and assurance 2

The controls that make a revenue platform safe to operate, and the boundary that keeps a future build-or-buy decision cheap.

ADR-14Own metering and the ledger; keep rating and invoicing behind an interface so delegation stays cheap ADR-15No identity holds pricing, restatement and credit-memo rights together, and the audit record is written first

Technology by capability

Amazon Web Services was chosen for this exercise deliberately. None of the six existing use cases in the cost-and-efficiency area uses it, and it sits below Azure and open-source-on-premises on this practice's repository-wide table, which is the rotation this library exists for. It also fits the topic honestly: a billing platform wants an append-only object store with a table format and write-once retention, a managed event-time stream processor, and a transactional relational engine for the financial ledger, and AWS supplies all three as first-party services without the design becoming a tour of one vendor's catalogue. Every requirement in ask.md stays vendor-neutral; the choices below are this package's realisation of it, and each one names the alternative it was chosen over.

Open source This design
CapabilityChoiceOriginCredible alternativeWhy this oneRecord
Event ingestion API Gateway with ECS Fargate validators, batching 500 events per request Amazon Web Services Direct Kinesis PutRecords from producers; Lambda per request; a self-hosted collector Validation, deduplication and per-account quota need somewhere to live that is not the producer; batching is what makes replication inside the 50 ms accept budget affordable ADR-05
Durable transport Kinesis Data Streams, partitioned on the account-to-bucket mapping Amazon Web Services MSK or self-managed Kafka; SQS; EventBridge Managed, ordered within a partition, and keyed identically to the ledger so stream skew and ledger skew are one problem; Kafka is more flexible and adds a stateful component on the revenue path ADR-12
Event ledger S3 with Iceberg tables, partitioned by account bucket and period Amazon Web Services and open source Delta Lake; plain partitioned Parquet; a time-series database; a relational event table Eleven nines of durability, a table format that supports schema evolution and bounded scans, and lifecycle tiering to write-once cold storage — the exact properties ADR-01 and ADR-13 require ADR-01
Audit tail Glacier with Object Lock, seven-year retention Amazon Web Services S3 Glacier Instant Retrieval; a third-party archive; tape Write-once retention the platform's own operators cannot shorten, at the price point a seven-year tail needs; retrieval cost and latency become a constraint on the dispute process and are stated as such ADR-13
Deduplication index DynamoDB, conditional write, seven-day TTL Amazon Web Services Redis or ElastiCache; a Bloom filter; a Flink keyed state Durable, predictable single-digit-millisecond conditional writes at rate; a cache would make deduplication best-effort, which is not a guarantee this platform can offer ADR-04
Event-time aggregation Amazon Managed Service for Apache Flink, checkpointing to S3 Amazon Web Services and open source Spark Structured Streaming; Kinesis Data Analytics SQL; a scheduled batch job over the ledger Event-time windows, watermarks, allowed lateness and exactly-once checkpointing are the hard part and are not worth rebuilding; a batch job over the ledger is the documented fallback and costs freshness ADR-06
Aggregate store DynamoDB, keyed on account, meter, dimension hash and period Amazon Web Services Aurora; ElastiCache; a columnar store queried directly Write throughput and a partition key that matches the aggregation key; the aggregate store is derived and droppable, so durability guarantees beyond this would be paid for nothing ADR-03
Financial ledger Aurora PostgreSQL, Multi-AZ, append-only by role Amazon Web Services DynamoDB; a double-entry ledger service; the ERP's own tables Invoices, balances and memos want transactions, constraints and joins; the append-only property is enforced by the database role the invoice service holds rather than by application discipline ADR-02
Plan registry Aurora with each version also written to a versioned S3 object Amazon Web Services A Git repository with a deploy pipeline; AppConfig; DynamoDB Rating needs relational lookups by effective date; the immutable S3 copy means the configuration that priced an invoice exists outside the database that issued it ADR-08
Entitlement decision ECS Fargate behind DAX, over the Aurora balance ledger Amazon Web Services ElastiCache; a local sidecar cache; DynamoDB with a Lambda authorizer The 10 ms p99 assumes a better-than-95% cache hit rate, and DAX gives that in front of the store that holds the authoritative balance; this figure is what decides whether synchronous caps are viable at all ADR-11
Invoice and restatement runs Step Functions with ECS tasks, idempotent and resumable per account and period Amazon Web Services Airflow or MWAA; Batch; a cron-driven service Resumability and per-account parallelism are workflow properties rather than serving ones, and an interrupted run that must not double-issue is exactly what a durable state machine is for ADR-02
Evidence query Athena over the Iceberg ledger, bounded by the aggregate's event range Amazon Web Services and open source Redshift Spectrum; EMR; a dedicated query service No cluster to keep warm for a workload measured in disputes per week, and a bounded scan over an ordered partition is what makes the 30-minute restatement target reachable ADR-03
Downstream hand-off EventBridge as a durable replayable outbox Amazon Web Services SNS and SQS per consumer; direct API calls; a nightly file drop An invoice run must complete regardless of the payment platform's health, and consumers must receive the identical invoice on replay — which needs a durable outbox rather than a call ADR-02
Identity and audit IAM roles with no overlapping trust policy, KMS per zone, CloudTrail plus an Object Lock prefix Amazon Web Services A third-party PAM product; application-level approvals; a self-hosted audit store Separation of the three privileged actions has to be enforced by the identity system rather than by application code, and the audit store has to be one the platform's operators can write but not delete ADR-15

The decisions, and the alternatives that lost

Truth and recomputationThe decisions that make every figure in the platform derivable rather than precious.

ADR-01

The event ledger is the system of record; every priced figure is a recomputable projection

Accepted

When an aggregate, a priced line or an invoice disagrees with the raw events, which one is wrong?

Context
The cheapest metering system to build keeps running counters. A service increments a counter per event, the counter is read at period end, and the raw events are retained briefly for debugging because keeping all of them looks expensive. It works, it is what most metering becomes under cost pressure, and it is unrecoverable: the first time a counter is wrong there is no evidence left to establish what the right figure was, and the only available response to a customer dispute is to believe the customer. Every correctness problem then becomes a negotiation rather than a procedure.
Decision
An append-only, immutable event ledger sits between ingestion and everything else and is the only system of record. Aggregates, priced lines and invoices are projections that exist for query performance and presentation, and all of them can be deleted and rebuilt from retained events without changing a single number — provided the rating configuration that applied at the time is still available, which is why plan versions are immutable and currency rates are dated. No projection is ever authoritative for its own contents, and none is repaired in place.
How it is realised on AWS
Accepted events are written to Kinesis Data Streams and landed by Firehose into S3 as Iceberg tables partitioned by account and period, with a lifecycle rule to Glacier under Object Lock beyond the queryable window. Managed Flink reads the stream on event time and writes aggregates to DynamoDB, each carrying the event identifier range that produced it. Aurora PostgreSQL holds the priced lines, balances and invoices. Every store except S3 and Aurora can be dropped and rebuilt; Aurora holds published facts, which is a different kind of permanence covered in ADR-02.
Options weighed
  • ChosenImmutable event ledger as the record, everything downstream a projection: One remedy — replay — for every class of error downstream of ingestion, and an invoice line that can always be expanded to its evidence.
  • RejectedRunning counters authoritative, events retained briefly for debugging: Materially cheaper and genuinely unrecoverable: a wrong counter leaves nothing to establish the right figure from.
  • RejectedAggregates authoritative with the ledger kept as an audit trail: The worst of both — an audit trail nobody reconciles against is not evidence, and the aggregate still cannot be rebuilt.
  • Right elsewhereDelegate the whole thing to a billing platform and keep no ledger: Right for a company whose packaging is conventional and whose volume is modest; the reconciliation obligation is covered in ADR-14.
Consequences
What it buys
  • A bad transform, a wrong tier boundary, a corrupt partition and an operator error all have the same remedy, so recovery is routine rather than improvised.
  • A new consumer of usage data — a warehouse extract, a cost dashboard, a partner report — costs a read of the ledger rather than a change to capture.
  • Any invoice line can be expanded to its constituent events, which is what makes the figure defensible to a customer and to an auditor.
What it costs
  • Raw events retained at full grain for 400 days, which is the single largest storage line in the design and is justified by the dispute and audit tail rather than by query need.
  • An extra durable hop before anything is counted, which is why usage freshness is measured in minutes rather than seconds.
  • Every projection needs an idempotent rebuild path, which is more engineering than a counter that is simply correct.
Choose differently when
If usage were cheap enough that no dispute was ever worth the cost of answering it, and no auditor or regulator could compel event-level evidence, running counters with a short event retention would be the better design. The decision should also be revisited if retention economics ever make a full-grain ledger of this volume disproportionate to the revenue it meters — but the honest first response to that is a shorter queryable window, not a counter.
Why it holds up over time
This is a statement about which store is allowed to be wrong, not about a product. It survives replacing the stream, the stream processor, the object store and the relational engine, because none of those changes where authority lives.
LessonDecide, before building, whether a figure is allowed to be wrong and recoverable or must be right and precious. In a billing system every figure except the issued invoice should be the former, and the architecture that makes it so is the one with an immutable ledger in the middle.
Shown on views02 10 12
ADR-02

Corrections are recomputations; an issued invoice is superseded, never rewritten

Accepted

A figure already sent to a customer turns out to be wrong. What happens to the original?

Context
The instinct is to fix it. The invoice is a row, the amount is a column, and the customer has not paid yet — so update the amount and resend. That instinct is why billing systems acquire a folder of correction scripts and why the question "what did we actually charge them in March" eventually has no answer. An issued invoice is not an internal record: it has been filed against, posted to a ledger, possibly paid, and quite possibly submitted to a tax authority. Changing it in place destroys the only evidence of what was claimed.
Decision
An issued invoice is immutable. A difference discovered afterwards is resolved by a credit memo or a superseding invoice according to accounting policy, both the original and the restated figures are retained with the reason and the authorising identity, and the remedy used is recorded per correction. Upstream, the same rule applies one level down: a closed period is reopened only by an explicit authorised restatement, never by the ordinary arrival of a late event.
How it is realised on AWS
The Aurora schema gives invoice an issued_at and a status that only moves forward, with credit_memo and a supersedes reference as separate rows rather than nullable columns. Restatement is its own entity holding the scope, the reason, the authorising identity and both amounts. The restatement workflow runs as a Step Functions execution that writes new rows only; there is no update path from the application to an issued invoice, which is enforced by the database role the invoice service holds.
Options weighed
  • ChosenImmutable issue, correction by credit memo or superseding invoice: The history of a disputed invoice is itself auditable, and the question "what did we charge in March" always has an answer.
  • RejectedAmend the invoice in place before payment: Cheap, intuitive, and it destroys the evidence of what was claimed — including for the periods nobody disputed.
  • Right elsewhereImmutable issue, but corrections only as credit memos: Right where accounting policy forbids superseding documents; this design keeps both and records which was used, because policy varies by case.
  • RejectedSoft-delete and reissue under a new identifier: A superseding invoice with an explicit reference, which is the same thing done honestly, rather than a deletion the downstream systems have to infer.
Consequences
What it buys
  • A dispute is answerable with a narrative — here is what we charged, here is why it was wrong, here is the corrected figure and who authorised it.
  • Downstream financial systems can be idempotent on invoice identifier, because an identifier's content never changes.
  • A restatement is a bounded, auditable operation rather than an improvised intervention under pressure.
What it costs
  • Two figures for one period, which the customer and the account team have to understand; the usage surfaces have to show both rather than the latest.
  • More rows and more joins than a mutable invoice table, and a reporting layer that must know which figure is current.
  • The remedy choice is a policy decision the platform cannot make for itself, which ADR-10 leaves deliberately open.
Choose differently when
Nothing within the plausible range of this system flips it. The nearest case is a pre-issue draft, which is mutable by design — and the whole point of the draft state in the invoice run is to make as many corrections as possible happen while mutation is still legitimate.
Why it holds up over time
Immutability of a published financial document is an accounting property, not a technology one. It will outlive every store named here and is the same rule a paper ledger followed.
LessonSeparate the moment a figure is published from the moment it is computed. Before publication, mutate freely; after it, only ever add. Most of the pain in financial systems comes from systems that do not know which side of that line they are on.
Shown on views13 15 19
ADR-03

Every aggregate carries the event range that produced it

Accepted

A customer asks which events make up this invoice line. How is that answered without scanning the period?

Context
An aggregate is a number: account, meter, period, quantity. That is enough to price and enough to display, and it is not enough to defend. Without provenance, answering "which events" means re-scanning the whole period for that account and meter and hoping the scan reproduces the original set — which it will not, if a late event landed in between, or if the aggregate was computed under an earlier schema version. The evidence path then becomes a re-derivation that may legitimately disagree with the figure it is supposed to explain.
Decision
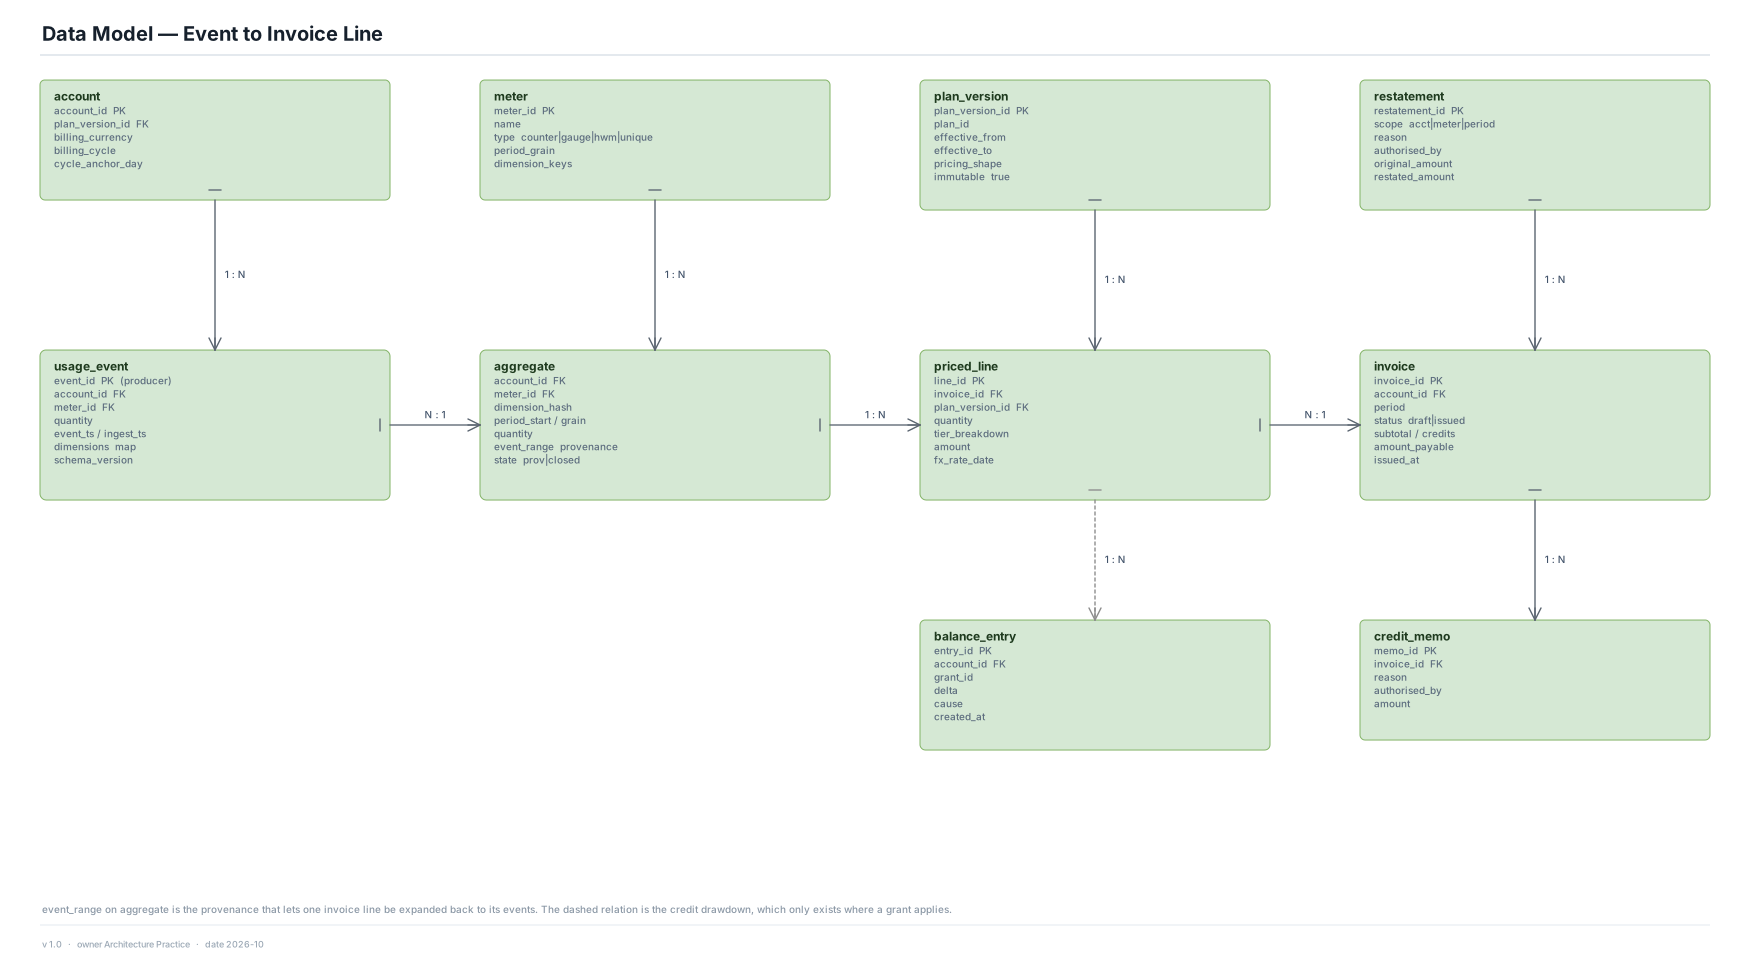
Every aggregate records the identifier range or checksum of the events that produced it, together with the schema version and the aggregate function applied. An invoice line therefore expands to a bounded, exact set of events rather than to a query that approximates one. The same provenance is what makes a restatement comparable to the original rather than merely adjacent to it.
How it is realised on AWS
The DynamoDB aggregate item carries event_range and dimension_hash alongside the quantity and the provisional-or-closed state; the range is a pair of ledger positions within the account's own Iceberg partition. The evidence query is an Athena scan bounded by that range, which is why the restatement target of 30 minutes for 90 days of one account is reachable at all. Glue holds every historical event schema version so a five-year-old event is still readable under the schema it was written in.
Options weighed
  • ChosenEvent range plus schema version on every aggregate: An invoice line expands to an exact set, and a replay is comparable to the original rather than a second opinion.
  • RejectedAggregate holds only the quantity; evidence is re-derived by query: Cheaper to write and the re-derivation can legitimately disagree with the figure, which is the worst possible answer to a dispute.
  • RejectedStore every event identifier that contributed, not a range: Exact and enormous: at 250,000 events/s the provenance would rival the ledger in size for no gain over a range within an ordered partition.
  • Right elsewhereDerive evidence from the stream processor's own state: Workable where state is retained indefinitely; here state is checkpointed for recovery, not for evidence, and is dropped on a rebuild.
Consequences
What it buys
  • The evidence export is a bounded scan, which is what keeps a dispute inside a working day.
  • A restatement's difference report compares like with like, because both figures name the events they counted.
  • Schema evolution does not break historical re-rating, because the aggregate says which schema it read.
What it costs
  • Aggregates become wider and the aggregation job has to thread provenance through every function, including the ones where it is awkward — distinct counts especially.
  • Provenance is only as good as partition ordering; this decision is what makes ADR-12's partitioning choice load-bearing rather than merely operational.
Choose differently when
If disputes were never answered at event level — no auditor, no large customer with its own telemetry — the provenance field is overhead and a quantity alone would do. That is the same condition that flips ADR-01, and in practice the two stand or fall together.
Why it holds up over time
Provenance on a derived figure is a general property of auditable systems. The specific encoding — a position range within an ordered partition — may change; the requirement that a derived number name its inputs will not.
LessonA derived figure that cannot name its inputs is not evidence, it is an assertion. If a number will ever be challenged, store what it was computed from at the same time you store the number.
Shown on views11 12 15

Capture and deliveryWhat it takes for an accepted event to be billable exactly once, and for a late one to land in the right month.

ADR-04

Idempotency sits on a producer-assigned event identifier, with a seven-day window

Accepted

Two identical-looking events arrive. Are they one event retried, or two things that really happened?

Context
This is Question 1 of the requirement and it has no free answer. A producer-assigned identifier is exact: the producer knows whether it is retrying, and nothing else does. It also depends on every producer getting it right — including partner feeds, third-party SDKs and the batch job somebody wrote in a hurry — and a producer that generates a fresh identifier on retry will quietly double-bill. A server-side content fingerprint needs nobody's cooperation, and cannot distinguish two genuinely identical events a millisecond apart, which for a per-call meter is a real and common case.
Decision
The producer-assigned event identifier is the idempotency key, and a repeat of an identifier already accepted within the deduplication window is discarded without erroring the producer. The window is seven days, chosen to cover the longest expected producer retry. Producer SDKs generate the identifier at the point of measurement and persist it with the buffered event, so a retry after a crash carries the same identifier.
How it is realised on AWS
A DynamoDB table keyed on event identifier with a seven-day TTL, written conditionally in the accept path. The producer SDK is the controlled surface: it assigns the identifier, writes it into its local durable buffer before the first attempt, and reuses it across retries and restarts. Partner feeds are required to supply an identifier per row as part of the inbound contract, and a feed that cannot is onboarded with a content fingerprint computed at ingest and documented as such.
Options weighed
  • ChosenProducer-assigned identifier, 7-day window: Exact where it matters, and the SDK makes correctness the default for the producers we control.
  • RejectedServer-side content fingerprint: Needs no cooperation and cannot tell two real identical events apart — unacceptable for a per-call meter.
  • Right elsewhereBoth: identifier when present, fingerprint as fallback: What this design actually does for partner feeds; as a general rule it doubles the dedup cost and hides which guarantee an account is getting.
  • RejectedNo deduplication; rely on at-most-once delivery: At-most-once means lost revenue on every transient failure, which is the error this platform is least able to tolerate.
Consequences
What it buys
  • A retry storm after an ingestion outage is free rather than catastrophic, which is what makes the producer buffer safe to use aggressively.
  • Deduplication is a single conditional write in the accept path, with a predictable latency contribution to the 50 ms budget.
  • The guarantee each producer gets is explicit, per producer, rather than an assumption about the whole estate.
What it costs
  • Every event identifier held for seven days at 250,000 events/s — the most likely cost surprise in the design, and sized explicitly in the prototype for that reason.
  • A producer that regenerates identifiers on retry will double-bill, and nothing in the platform can detect it from the inside; this is why per-producer dedup hit rate is a watched signal.
  • A retry arriving on day eight is a duplicate the platform will accept.
Choose differently when
If the dedup index's cost turns out to dominate the ledger's, the documented fallback is a shorter window plus a content fingerprint for the long tail — a narrower guarantee, stated per producer, rather than a redesign. If the producer estate were mostly third-party and uncontrollable, the fingerprint becomes the primary and the identifier the optimisation.
Why it holds up over time
Where the idempotency boundary sits is a question about trust between components, and it will be asked the same way whatever the transport. The specific window length is a cost and retry-behaviour parameter that should be revisited yearly.
LessonIdempotency is not a property you add to a pipeline; it is a decision about which component is trusted to know it is repeating itself. Make that decision explicitly, and then make it easy for that component to be right.
Shown on views09 11 22
ADR-05

Acknowledge only after durable replication — fail closed on acceptance, open on serving

Accepted

The ledger write is slow or failing. Does the platform accept the event anyway?

Context
Accepting first and persisting later is the standard way to make an ingest endpoint fast, and for telemetry it is the right trade. For billing it quietly inverts the whole design: if an accepted event can be lost, the ledger is not the system of record, the accuracy target is unmeasurable, and the honest answer to "are we billing for everything" becomes no. The opposite failure matters too, in the other direction: if the product's request path waits on metering, a billing incident becomes a product outage, and the business will — correctly — demand that metering be bypassed.
Decision
An acknowledgement follows durable replication, so a 202 is a billing guarantee rather than a receipt. Where durability cannot be guaranteed the event is rejected so that the producer retains it in its own durable buffer. Separately and in the opposite direction, the product's serving path never waits on metering: event submission is asynchronous and fire-and-forget, and the only synchronous dependency the product has on this platform is the entitlement decision of ADR-11.
How it is realised on AWS
The accept path writes to Kinesis with the shard-level durability the service provides and returns only on success; a write failure returns a retryable status rather than a 202. The producer SDK holds events in a local durable buffer and retries with backoff, reusing the identifier from ADR-04. The 50 ms p99 budget is made affordable by batching up to 500 events per request, so replication cost is amortised rather than paid per event.
Options weighed
  • ChosenAcknowledge after durable replication; reject when it fails: RPO 0 for acknowledged events, which is what makes every other guarantee in the design provable.
  • RejectedAcknowledge on receipt, persist asynchronously: Faster and standard for telemetry; for billing it means an accepted event can vanish and the accuracy target becomes unmeasurable.
  • RejectedAcknowledge after a local write, replicate later: A middle that looks safe and is not: the window of accepted-but-unreplicated usage is exactly the window an AZ loss falls into.
  • RejectedSynchronous metering inside the product's request path: Would make every metering incident a product outage, and the business would be right to demand a bypass — which is a worse design than this one.
Consequences
What it buys
  • There is no window of accepted-but-lost usage, so RPO 0 is a property of the protocol rather than a claim about storage.
  • A metering outage degrades into producer buffering, which is recoverable, rather than into silent revenue loss, which is not.
  • The product's availability is independent of the billing platform's, except at one well-named point.
What it costs
  • Replication inside the accept path, which is the largest single contributor to the 50 ms p99 and the reason batching is mandatory rather than optional.
  • Producers must carry a durable buffer, which is real work in every language the product is written in and makes the SDK a first-class deliverable.
  • An outage longer than producer buffer depth is unbilled usage — accepted explicitly in ADR-12's single-region posture.
Choose differently when
If usage were so cheap per event that a thousandth of loss were immaterial, acknowledging on receipt would be the better trade and would buy a much faster endpoint. The decision also softens if producers could be relied upon to buffer for days rather than minutes, which would make rejection nearly free.
Why it holds up over time
"An acknowledgement means durable" is a protocol contract, not an implementation. It is the same contract a database makes on commit and will outlive every service named here.
LessonDecide what your acknowledgement means and then make it true. Most data-loss incidents are not storage failures; they are systems whose acknowledgement promised more than the write behind it delivered.
Shown on views12 16 22
ADR-06

Usage is attributed by event time, with a 72-hour lateness bound and provisional periods

Accepted

An event for the 30th arrives on the 2nd. Which month is it billed in?

Context
Arrival-time counting is simpler in every respect: no watermarks, no provisional state, no late-arrival policy, and a period that is final the instant it ends. It is also wrong in a way customers notice. A mobile client offline over a weekend, an edge node with a buffered minute rollup, a partner feed delivered a day late — each moves revenue between months, and the customer who was billed twice for the 30th in two different months will be the one who notices.
Decision
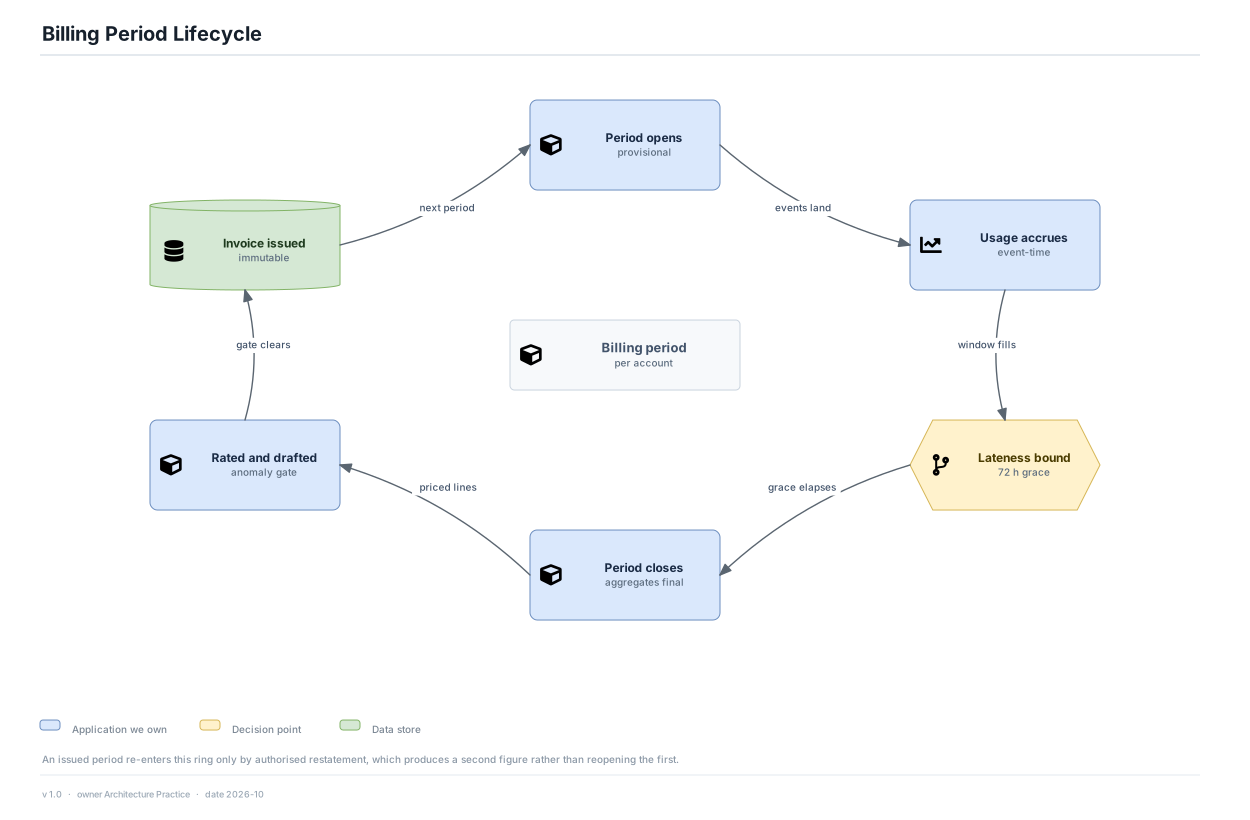
Usage is attributed to the period in which it occurred, using the event timestamp the producer recorded. Aggregation runs on event time behind an explicit watermark, and a period is marked provisional until the lateness bound has elapsed. The bound is 72 hours, chosen to cover an offline edge or mobile producer plus a long weekend and short enough that a period can still close inside the invoice run's window. An event arriving beyond the bound is attributed by authorised restatement rather than silently absorbed.
How it is realised on AWS
Managed Flink windows on event time with a 72-hour allowed lateness and watermarks derived per partition; both event_ts and ingest_ts are retained on every event so clock skew is visible rather than silently trusted, and skew beyond a bound is flagged. Aggregates carry a provisional-or-closed state, and the usage surfaces stamp freshness on every figure they serve so a provisional number is never presented as a final one.
Options weighed
  • ChosenEvent-time attribution, 72-hour bound, provisional until close: Usage belongs to the month it happened in, and the platform says plainly when a figure is still moving.
  • RejectedArrival-time attribution: Much simpler, and it moves revenue between months whenever a producer was offline — the error a customer is most likely to find.
  • RejectedEvent time with no bound: periods never finally close: Correct and unusable: an invoice cannot be issued against a quantity that may still change.
  • Right elsewhereEvent time with a 24-hour bound: Right where all producers are server-side and online; here it would push a predictable weekend tail into restatement every week.
Consequences
What it buys
  • A period's figure means what a customer thinks it means, which removes an entire class of dispute.
  • Provisional state is explicit, so the transition to closed is a visible event rather than a surprise.
  • Retaining both timestamps makes clock skew an observable rather than a mystery.
What it costs
  • Window state is held for the duration of the bound, which is the largest contributor to aggregation memory and therefore to its cost.
  • A 72-hour bound means a period cannot close for three days, so the monthly close is genuinely later than the month end.
  • A watermark that advances on an idle partition can close a period early for that partition — a configuration detail with a revenue consequence.
Choose differently when
Shorten the bound if every producer becomes server-side and reliably online; lengthen it if a significant feed is habitually later than three days, accepting the window state cost. If a regulator ever required that usage be billed in the period it was received, the decision inverts — and the retained event_ts would make the migration possible.
Why it holds up over time
Producers will keep being offline and clocks will keep disagreeing. Event-time attribution with a stated bound is the honest way to express that and will not be made obsolete by a better pipeline.
LessonThe hard part of event time is not the windowing, it is admitting that a period is not final when it ends. Name the bound, mark everything before it provisional, and the rest of the design follows.
Shown on views09 19 22
ADR-07

Rejected events are quarantined with their reason and replayed, never discarded

Accepted

An event fails validation. Is that usage, or is it noise?

Context
A validation failure in a telemetry pipeline is noise and dropping it is correct. In a billing pipeline it is almost always a defect on our side — a new product version shipped a field the schema does not know, a dimension key changed case, a partner feed added a column — and the usage underneath it is real and billable. A dropped event is indistinguishable from usage that never happened, and the discovery mechanism is a customer asking why their bill fell.
Decision
An event that fails schema or referential validation is routed to a quarantine store with the reason attached, and never discarded. Once the defect is fixed the quarantined events are replayed through the normal path, where ADR-04's deduplication makes a double replay harmless. Quarantine rate is a watched signal per producer, because a rising rate on a new product version is the earliest possible notice of a metering defect.
How it is realised on AWS
The validator writes rejected payloads to an S3 prefix partitioned by day, producer and reason code, with the original request body intact. Replay is a Step Functions execution that reads a prefix and resubmits through the ingest path rather than around it, so validation, deduplication and ledger append all apply exactly as they would have originally.
Options weighed
  • ChosenQuarantine with reason, replay after fix: A schema defect costs a replay rather than a month of unbillable usage, and the reason code names the defect.
  • RejectedReject at the API and let the producer retry: Pushes the fix to every producer and loses everything buffered before anyone noticed; also turns a schema mistake into a producer outage.
  • RejectedAccept everything and validate downstream: Puts unvalidated payloads into the system of record, which makes the ledger something less than a record.
  • Right elsewhereDead-letter with automatic expiry: Standard for messaging and wrong here: an expiry on quarantined billing events is a scheduled deletion of revenue.
Consequences
What it buys
  • A schema drift costs a replay rather than a gap, and the gap it would have caused is measurable while it is open.
  • Reason codes per producer turn quarantine into the fastest defect-detection channel the platform has.
  • Replay goes through the ingest path, so there is exactly one validation and deduplication implementation.
What it costs
  • Quarantine is unbounded storage until someone acts on it, and the unglamorous operational work of acting on it is real.
  • An event sitting in quarantine is accepted-but-unbilled, which means it must be counted in that signal rather than forgotten.
  • A systematic defect can fill quarantine faster than anyone reads the alert — which is the residual risk named in view 22 as drift nobody reads.
Choose differently when
Nothing plausible flips the no-discard rule. What should change over time is the retention and triage policy: a quarantine prefix nobody has read in a year is evidence that the reason codes are not reaching anyone, not that the events were worthless.
Why it holds up over time
"A rejected measurement is a defect report, not noise" is a property of systems that bill. It will hold whatever the transport and whatever the schema technology.
LessonIn any system where the input is money, a validation failure is a bug in the system and not in the input. Keep the input, name the reason, and make replay the normal remedy.
Shown on views09 10 22

Money and policyWhere pricing lives, when it is applied, and who is allowed to change it.

ADR-08

Pricing is versioned immutable configuration behind a blast-radius gate and two approvals

Accepted

A price needs to change on Monday. What stops that change being applied to the wrong accounts, or to the right accounts retroactively?

Context
Pricing configuration is the smallest and most dangerous data in the platform. It is read-heavy, a few thousand rows, and an error in it is applied uniformly to every affected account at once — the only change in the system with that property. It is also the data most people want to change without an engineering release, which is a legitimate requirement and exactly why it cannot be a table that revenue operations can update. The worst case is not an outage, it is a month of invoices that were all computed correctly from a wrong number.
Decision
Plans are held as versioned, immutable configuration: a new price is a new plan version with an effective-from date, never a mutation of a version already applied to issued invoices. Activation requires a shape check, an overlapping-date conflict check, a blast-radius preview naming the accounts affected and the aggregate change in charged amount, a dry-run re-rate of the last closed period, and two human approvals. There is no rollback in place — a wrong price is corrected by a further version plus a restatement of anything already rated under it.
How it is realised on AWS
Plan versions live in Aurora with the version document also written to a versioned S3 object, so the configuration has an immutable copy outside the database that issued the invoice. Rating resolves the version in force for each sub-period, which is what makes a mid-period change split the period rather than reprice it. The preview and dry run run as a Step Functions execution against live aggregates; the two-person gate is an IAM and workflow control, and the audit record is written before activation.
Options weighed
  • ChosenImmutable versions, effective-from dates, preview plus two approvals: Self-service pricing without the one failure mode that hits every account simultaneously.
  • RejectedMutable price rows with an audit trail: Audit tells you afterwards what went wrong; it does not make a historical re-rate reproduce the original amount.
  • RejectedPrices in code, deployed through the normal pipeline: Safe and slow, and it makes the pricing manager's goal impossible — which pushes pricing into spreadsheets and manual invoices instead.
  • Right elsewhereSingle approver with a preview: Reasonable in a small company where the approver is the founder; at this scale the second approver is the control, not the ceremony.
Consequences
What it buys
  • A historical period re-rates to exactly the original amount, which is what makes ADR-01's rebuild claim true rather than approximate.
  • A mid-period change splits the period, so a customer is never retroactively repriced for usage they already incurred.
  • The blast radius of a pricing mistake is known before it is taken, in the only units that matter: accounts and money.
What it costs
  • Plan version count grows monotonically — 2,000 live versions is assumed — and rating must resolve the right one per sub-period, which is more work than reading a current price.
  • Two approvals during month-end, which is when the assumption that a second approver is available is under most pressure.
  • Both approvers can be wrong together, and the preview is only as honest as the period it dry-runs; this is named as residual risk rather than engineered away.
Choose differently when
If pricing were genuinely static — one plan, changed yearly, by an engineer — versioned configuration with a preview is overhead and code would do. The gate should also be relaxed for a change whose preview shows it affects no account with usage, which is a common and genuinely safe case.
Why it holds up over time
Treating the most widely-applied configuration as a deployment, with a preview and a second human, is a control that transfers to any system where one row changes everyone's outcome. The pricing shapes will change; this will not.
LessonFind the configuration in your system whose error is applied to every customer at once, and put it behind a deployment gate. Audit logs catch it afterwards; a blast-radius preview catches it before.
Shown on views17 20 22
ADR-09

Rate at period close; stream-rated provisional figures are a second-phase addition

Accepted

Is a price applied when the event arrives, or when the period closes?

Context
This is Question 2 of the requirement. Pricing on arrival gives the customer a near-real-time spend figure and spreads the compute evenly across the month, and it bakes a price into a record that a retroactive plan change, a late event or a corrected quantity may invalidate — so the stream-rated figure has to be recomputed anyway, and now there are two numbers that must agree. Rating at close always uses the final quantity and is far simpler to reason about, but leaves the customer blind until the bill lands and concentrates a month of rating compute into the close window.
Decision
The MVP rates at period close, which is authoritative, and serves customers unrated quantities with freshness labelled so prediction is still possible from the usage view. Stream-rated provisional spend is a Phase 2 addition, explicitly for display, with the close-time rating remaining the only authoritative path. Where both exist, a divergence between them is a platform defect and a watched signal, not a rounding difference to be explained.
How it is realised on AWS
Rating runs inside the invoice-run Step Functions execution, parallel across accounts and idempotent per account and period, reading closed aggregates from DynamoDB and plan versions from Aurora. The usage API serves quantities and, in Phase 2, a stream-rated estimate from the same rating library compiled into the aggregation path — one implementation, two invocation points, which is the only version of the hybrid worth having.
Options weighed
  • ChosenRate at close; unrated quantities for display, stream rating in Phase 2: One authoritative path on day one, with the customer still able to predict from quantities and their own rate card.
  • RejectedStream rating as the authoritative path: Every retroactive change and every late event invalidates a priced record, so the recompute happens anyway and the stream figure becomes a second truth.
  • Right elsewhereClose-time rating only, no provisional spend at all: Right where every customer is on a flat rate they can compute themselves; here it leaves the admin's primary goal unmet.
  • RejectedTwo rating implementations, one streaming and one batch: Guarantees the two will diverge, and the divergence will be discovered by a customer rather than by a test.
Consequences
What it buys
  • One authoritative rating path, so there is one answer to what an account owes.
  • A retroactive plan change needs no invalidation sweep, because nothing was priced early.
  • Rating compute is a single sized workload with a stated window rather than a continuous cost.
What it costs
  • The customer cannot see money accruing in the MVP, only quantities — which is a real gap against the journey in view 04 and is why Phase 2 exists.
  • A month of rating compute lands in one window, so the 6-hour close budget is load-bearing.
  • When Phase 2 arrives there are two invocation points to keep in agreement, which needs a test rather than a convention.
Choose differently when
If customers demand live spend before Phase 2 can be built, or if the close window proves too tight at a larger account count, stream rating for display moves forward. If pricing ever became genuinely immutable once published — no retroactive changes at all — stream rating could become authoritative, and the design would be simpler for it.
Why it holds up over time
The trade between fresh and final is permanent in any system that both reports and bills. The resolution — one authoritative path, with anything faster marked provisional — transfers unchanged.
LessonWhen a figure must be both fast and final, do not compromise: make one of them authoritative and label the other. Two numbers of equal standing will diverge, and the divergence will be found by whoever trusts them most.
Shown on views13 14 04
ADR-10

The remedy for a post-issue error is left to accounting policy, and recorded per correction

Open — deliberately unresolved

A figure is wrong after issue. Credit memo on the next invoice, or a superseding invoice for this one?

Context
This is Question 6 of the requirement and it is genuinely open. A superseding invoice shows the customer one correct document, which is what most customers want, and it means the figure they already filed against has changed — a real problem for a customer who has posted it or submitted it for tax. A credit memo on the following invoice leaves history untouched, at the cost of a bill that no longer matches the period it covers, which is awkward for anyone reconciling period by period. The right answer depends on accounting policy, on whether the error favoured the customer or the vendor, and on how far back the correction reaches.
Decision
The platform supports both and chooses neither. Every correction records which remedy was used and why, the original and restated figures are both retained, and the decision is made per correction by the finance controller under a policy the platform does not encode. What the platform does require is that the remedy be authorised, recorded, and visible to the customer alongside the original.
How it is realised on AWS
credit_memo and a supersedes reference are separate structures in the Aurora schema, both reachable from the restatement entity that holds the reason and the authorising identity. The restatement workflow presents both options with the difference report and records the choice. No code path prefers one, and the usage surfaces render whichever was used with the original still visible.
Options weighed
  • ChosenSupport both, record the choice, encode no policy: Keeps the architecture out of an accounting decision it cannot make correctly for every case.
  • Right elsewhereCredit memo only: Right where accounting policy forbids superseding documents outright; simpler, and it loses the clean-document option customers prefer.
  • Right elsewhereSuperseding invoice only: Right where invoices are rarely filed against before payment; it breaks badly for customers who post on receipt.
  • RejectedAutomatic rule by error direction and age: Attractive and premature: the rule would be guessed now and discovered wrong during the first material dispute.
Consequences
What it buys
  • Finance keeps a decision that is properly theirs, and the platform keeps an auditable record of how it was exercised.
  • A policy that emerges from practice can later be encoded, with real cases to encode it from.
  • Neither remedy is a special case in the schema, so adopting a policy later costs configuration rather than migration.
What it costs
  • A per-case human decision on every post-issue correction, which does not scale if corrections become common — and if they do, that is the signal to fix the cause rather than the remedy.
  • Two remedy shapes for downstream systems to handle, both of which must be idempotent on replay.
  • An open decision in a shipped design, which has to be stated as such rather than quietly defaulted.
Choose differently when
This closes the moment finance writes the policy down — most likely after the first material dispute, which is when the trade-offs stop being hypothetical. The platform should then encode the policy as a default with an override, not as a hard rule.
Why it holds up over time
Whether to amend or credit is an accounting question that long predates software and will outlast it. What transfers is the discipline of recording which was used.
LessonSome decisions are not the architecture's to make. Build both paths, record which was taken, and resist the urge to encode a policy you have no cases for — a guessed rule is harder to remove than a missing one.
Shown on views15 13

Enforcement and the serving pathHow much of the billing platform the product is allowed to depend on.

ADR-11

Hard caps are enforced synchronously, and the check fails open with the overshoot recorded

Accepted

A prepaid balance is exhausted mid-request. Does the product refuse the call, and what happens if the entitlement service cannot answer?

Context
This is Question 3 of the requirement. A synchronous entitlement check stops a customer exceeding a prepaid balance, and it puts a sub-10 ms dependency with a 99.99% availability requirement on the product's request path — which raises the question nobody wants to answer during an incident: what does the product do when that check is unavailable. Asynchronous enforcement — meter, detect, then throttle — removes the dependency entirely and accepts a window of usage that was incurred and may be unbillable. For cheap usage the overshoot is a rounding error; for a few minutes of unthrottled inference it is real money.
Decision
Where a hard cap is required the product consults a synchronous entitlement decision with a p99 of 10 ms in-region, and that is the only synchronous dependency the product has on this platform. When the decision cannot be made the call fails open and the platform records that it did, so the overshoot is known and reconcilable rather than invisible. Caps are opt-in per meter and per account: a meter whose overshoot is immaterial does not pay the latency or the dependency.
How it is realised on AWS
The entitlement service runs on ECS behind DAX in front of the Aurora balance ledger, and the 10 ms p99 assumes a better-than-95% cache hit rate. A fail-open decision is emitted as an event into the ledger, so the unentitled usage appears in the accepted-but-unbilled signal and can be reconciled against what was actually metered. Threshold events fire at configured fractions of an allowance so the common case is a customer who topped up before reaching the cap.
Options weighed
  • ChosenSynchronous check, opt-in per meter, fail open and record: Caps work, the product's blast radius is one well-named dependency, and the cost of a billing outage is measurable.
  • RejectedSynchronous check that fails closed: Turns a billing outage into refused requests for paying customers, which is a worse business outcome than recorded overshoot.
  • Right elsewhereAsynchronous enforcement: meter, detect, throttle: Right where usage is cheap per unit; removes the dependency entirely and accepts an unbounded overshoot window.
  • RejectedEnforcement entirely inside the product from its own counters: Fast and local, and the counters would be a second truth about balances — the exact failure ADR-01 exists to prevent.
Consequences
What it buys
  • A prepaid balance means something, which is what makes prepaid credits a sellable product rather than a promise.
  • The product's dependency on billing is one endpoint with one stated budget, rather than diffuse.
  • A fail-open window produces a number, so the business can decide whether it matters instead of guessing.
What it costs
  • A 99.99% availability requirement on a billing-owned service, driven by the product's requirements rather than billing's.
  • A cold cache after deployment puts the balance ledger on the request path at the worst moment.
  • Fail-open during a long outage produces usage nobody was entitled to; a secondary local limit in the producer SDK would bound it and is not in the MVP.
Choose differently when
If the recorded overshoot ever exceeds the accuracy target, the secondary local limit moves into the SDK. If the p99 or the cache hit rate proves unreachable, synchronous caps are not viable and enforcement becomes asynchronous — with the business told plainly that a cap is now a strong suggestion.
Why it holds up over time
The question "how much of the billing system is the product allowed to depend on" is permanent. Answering it with exactly one endpoint, a stated budget and an explicit failure direction transfers to any platform in this position.
LessonWhen one system must depend on another synchronously, make it exactly one call, give it a number, and decide the failure direction in advance. The decision made calmly beforehand is almost always better than the one made at 3 a.m.
Shown on views21 02 22

Scale and retentionThe two axes that decide what this costs: how events are partitioned, and how long they are kept.

ADR-12

Partition the ledger by account, and sub-partition the account that outgrows a partition

Accepted

What is the ledger's partition key, and what happens when the largest customer exceeds one partition?

Context
This is Question 4 of the requirement. Partitioning by account keeps a customer's events together, which makes per-account replay and dispute resolution a bounded scan rather than a full-period one — and that bounded scan is the operation the entire evidence story depends on. It also guarantees that the largest customer eventually exceeds a single partition's capacity, because usage distributions in a SaaS business are not merely skewed, they are heavy-tailed. Partitioning by meter spreads load evenly and scatters an account's evidence across every partition, turning a restatement into a full scan.
Decision
Partition by account, with sub-partitioning on a secondary key available for an account whose volume exceeds one partition. Sub-partitioning is designed in rather than discovered: the evidence query and the restatement path both accept a set of partitions for one account, so promoting an account to sub-partitioned is an operational action and not a schema change. Per-account ingestion quotas sit in front of this so one customer's instrumentation bug cannot starve another's metering.
How it is realised on AWS
Iceberg tables partitioned by account bucket and period; the account-to-bucket mapping is explicit configuration rather than a hash, so a hot account can be moved to its own bucket set without rewriting history. Kinesis partition keys derive from the same mapping, and the aggregator keys its windows identically, so skew in the ledger and skew in the stream are the same problem with one remedy.
Options weighed
  • ChosenAccount partitioning with explicit mapping and sub-partitioning: Per-account replay stays a bounded scan, and the known future problem of the largest customer has a designed answer.
  • RejectedPartition by meter: Even load and an account's evidence scattered across every partition, which makes every restatement a full scan.
  • RejectedAccount hash with no explicit mapping: Simpler until the first hot account, which then cannot be moved without rewriting history.
  • Right elsewherePartition by period only: Right for a warehouse that answers period questions; useless for the per-account questions this platform is asked.
Consequences
What it buys
  • A 90-day single-account replay inside 30 minutes is reachable, which is the figure the dispute process is built on.
  • A hot account is an operational promotion rather than a migration.
  • Ledger skew and stream skew are the same problem, so there is one thing to monitor and one remedy.
What it costs
  • Uneven partition sizes by construction, which means capacity planning per bucket rather than in aggregate.
  • An explicit mapping is state that has to be versioned and consistent across ingestion, aggregation and query.
  • Skew beyond what sub-partitioning absorbs is the scheme's scale limit, and it will arrive with a single customer rather than gradually.
Choose differently when
If the account distribution turned out to be nearly uniform, a hash would be simpler and the explicit mapping is overhead. If per-account evidence ceased to matter — no disputes, no auditor — meter partitioning becomes the better choice, which is the same condition that flips ADR-01 and ADR-03.
Why it holds up over time
Partitioning to match the query you must always be able to answer, rather than to balance load, is a durable principle. The query here is "show me this account's events for this period", and it is not going to change.
LessonPartition for the question you will be forced to answer under pressure, not for the even load you would like in steady state. Load can be managed operationally; a scattered evidence trail cannot.
Shown on views07 16 10
ADR-13

Raw events stay queryable for 400 days and write-once cold for seven years

Accepted

How long are raw events kept at full grain, and at what point does the platform stop being able to answer at event level?

Context
This is Question 5 of the requirement. Keeping every event queryable for the full audit period makes any dispute answerable and any period re-ratable, at a storage and query cost that grows without bound. Rolling up to aggregates after the dispute window is far cheaper, and then a dispute or audit outside that window can only be answered at the aggregate level — which is to say, by restating the figure rather than evidencing it. The decision turns on the real length of the dispute and audit tail, the cost and latency of cold-tier retrieval, and whether a regulator or a large customer can compel event-level evidence after the window has closed.
Decision
Raw events stay queryable for 400 days and move to write-once cold storage for seven years. Four hundred days covers a full annual cycle — so any period has a comparable one still at full grain — plus the 60-day dispute window with margin. Seven years is statutory audit. Aggregates and financial records are retained for the full seven years in queryable form, because they are small. Nothing is rolled up to replace an event: the cold tier holds the same grain, just slower and dearer to read.
How it is realised on AWS
Iceberg tables on S3 with a lifecycle transition to Glacier under Object Lock at 400 days, and Glue retaining every historical schema version so a six-year-old event is still readable under the schema it was written in. Athena queries the hot tier directly; a cold-tier dispute is a restore with a stated latency and a retrieval charge, and the dispute process says so rather than discovering it.
Options weighed
  • Chosen400 days queryable, 7 years write-once cold, same grain throughout: Any dispute is answerable, the common ones are fast, and the rare ones are slow and chargeable rather than impossible.
  • RejectedRoll up to aggregates after the dispute window: Much cheaper and it converts a late audit question from evidence into assertion, which is the thing this design exists to avoid.
  • Right elsewhereEverything queryable for 7 years: Right where query cost is immaterial or regulation demands it; here it multiplies the largest storage line by six for a tail nobody reads.
  • Rejected90 days queryable, matching the dispute window alone: Loses year-on-year comparison at full grain, which is what the anomaly baseline and most real investigations actually use.
Consequences
What it buys
  • A dispute inside 60 days is answered in minutes, and one at five years is answered at all.
  • Year-on-year comparison at full grain is available, which the baseline detector and most investigations need.
  • Schema versioning means age does not make an event unreadable, only slower to reach.
What it costs
  • The largest storage line in the design, justified by the audit tail rather than by query volume.
  • Cold retrieval cost and latency are a constraint on the dispute process, which has to be written into it rather than discovered during the first late audit.
  • Object Lock means a retention mistake is not reversible — which is the point, and needs to be a deliberate decision rather than a default.
Choose differently when
Shorten the queryable window if cost pressure demands it, taking the year-on-year comparison loss knowingly; lengthen it if disputes routinely arrive past 400 days. The one change that should not be made quietly is rolling up to replace events, because it silently converts the platform from evidencing figures to asserting them.
Why it holds up over time
Retention sized from the dispute and audit tail, rather than from storage price, is a durable way to decide. The numbers should be revisited yearly; the method should not.
LessonSet retention from the questions you will be asked and who can compel an answer, not from what storage costs this year. Storage gets cheaper every year; the obligation to answer does not.
Shown on views10 15 18

Control and assuranceThe controls that make a revenue platform safe to operate, and the boundary that keeps a future build-or-buy decision cheap.

ADR-14

Own metering and the ledger; keep rating and invoicing behind an interface so delegation stays cheap

Accepted

Build the rating engine, or delegate it to a billing platform?

Context
This is Question 7 of the requirement. A bought billing platform arrives with tiers, commitments, proration, tax and dunning already correct and with somebody else maintaining them; it also means usage data crossing a boundary, a pricing vocabulary the platform does not control, and a per-event or revenue-share cost that scales with success. Building keeps the data and the pricing model in hand and costs a team indefinitely. The common compromise — own metering and the event ledger, delegate rating and invoicing — creates a reconciliation obligation between two systems that must agree to the cent.
Decision
Metering and the event ledger are built and owned, because they are where the accuracy and evidence requirements live and because they are the part no vendor can own on our behalf. Rating and invoicing are built for the MVP but kept behind their own interface with the ledger upstream of them, so a later decision to delegate costs a reconciliation obligation rather than a rebuild. The decision is deliberately kept reversible rather than made once.
How it is realised on AWS
Rating reads closed aggregates through a defined contract and writes priced lines through another; nothing in the aggregation path knows how a price is computed. The plan registry's version documents are exportable configuration rather than code, so the pricing model can be described to a third party. The outbox already speaks in issued invoices, which is the interface a billing platform would consume or produce.
Options weighed
  • ChosenOwn metering and the ledger, build rating behind an interface: Keeps the irreplaceable part in hand and the replaceable part replaceable, at the cost of building rating once.
  • Right elsewhereDelegate rating and invoicing from the start: Right where packaging is conventional and the team is small; the reconciliation obligation and the revenue-share cost both arrive on day one.
  • RejectedDelegate metering as well: Puts the system of record outside the boundary, which makes the evidence and retention decisions somebody else's to change.
  • RejectedBuild everything with no delegation boundary: Saves one interface now and makes the build-or-buy question unaskable later, which is the expensive kind of saving.
Consequences
What it buys
  • The part of the platform that cannot be bought — provable arithmetic over our own usage — is the part we own.
  • A future delegation is an interface and a reconciliation, not a migration.
  • The pricing model is exportable configuration, which is what makes a vendor conversation possible at all.
What it costs
  • Rating, proration, tiers and commitments are built and maintained, which is a standing team cost for capability a vendor already has.
  • An interface that exists for optionality rather than for a current consumer, which is a cost paid now for a decision deferred.
  • If delegation ever happens, two systems must agree to the cent — the reconciliation is real work and should be budgeted when the decision is taken, not after.
Choose differently when
Delegate rating when the packaging stops being unusual, or when the maintenance cost of tax and proration exceeds a vendor's fee — whichever comes first. Do not delegate metering: that is the decision this record is protecting, and the condition that would justify it is the same one that dismantles ADR-01.
Why it holds up over time
Separating the part that must be owned from the part that could be bought is a durable structural decision. Which vendors exist will change entirely; where the seam goes should not.
LessonBefore building something a vendor already sells, work out which part of it you could never delegate, and put a seam around the rest. The seam is cheap now and is the only thing that makes the question askable later.
Shown on views07 08 13
ADR-15

No identity holds pricing, restatement and credit-memo rights together, and the audit record is written first

Accepted

Which single compromised or mistaken identity could cost the most money, and what stops it?

Context
Three actions in this platform can move a lot of money quickly: changing a price, restating a figure, and issuing a credit memo. Each is legitimate, each is needed, and each is performed under time pressure at month end. An identity holding all three can both create a wrong figure and make it disappear, and the platform's own operators are therefore an in-scope threat — not because anyone expects malice, but because a design that only works when everyone is careful and honest is not a control.
Decision
The three privileged actions are separated across identities, none can be exercised without a second approver, and no identity holds all three without one. Each privileged action's audit record is written before the action runs, into a store the platform's operators cannot delete from, so an action that failed is still on the record. There is no standing access to the privileged zone: rights are assumed for a bounded session and the assumption itself is recorded.
How it is realised on AWS
Separate IAM roles with no overlapping trust policy, assumed for a bounded session; the audit record goes to CloudTrail and to an S3 prefix under Object Lock that the platform roles can write but not delete. Account-scoped authorisation on every customer read path is verified by an automated test on every change to a read path, because a cross-tenant usage leak is a breach and not a bug. Producers authenticate as workload identities authorised to specific meters, so a compromised service can only fabricate usage on its own meters.
Options weighed
  • ChosenSeparated roles, second approver, write-ahead audit, no standing access: The expensive mistakes need two people, and every attempt is on a record nobody in the platform can erase.
  • RejectedOne privileged operator role with full audit: Operationally convenient, and the audit is written by a system the operator controls — which is not evidence.
  • Right elsewhereSecond approver only for pricing changes: A reasonable staging for a small team; restatement and credit memo are the two a customer dispute puts most pressure on.
  • RejectedAudit written after the action completes: Loses exactly the records that matter most: the attempts that failed, and the ones that failed halfway.
Consequences
What it buys
  • The three highest-value actions require collusion rather than a single mistake.
  • A failed or partial privileged action is still on the record, which is the case an after-the-fact log misses.
  • Workload identity scoped per meter bounds the blast radius of a compromised product service to its own meters.
What it costs
  • Two humans during month-end, which is when the second approver is most resented and most necessary.
  • Write-once audit retention is not reversible, so a retention misconfiguration is permanent by design.
  • Both approvers can still be wrong together — named as residual risk in view 22, because a control that assumed otherwise would be a fiction.
Choose differently when
Nothing within this platform's plausible range relaxes the separation. What should change with scale is the approval mechanics: a two-person gate that is slow enough to be worked around has stopped being a control, so the right response to friction is faster approval rather than fewer approvers.
Why it holds up over time
Separation of duties and a write-ahead audit record are controls older than computing and will outlive every service named here. What changes is the mechanism, never the requirement.
LessonName the two or three actions in your system that could lose the most money in one step, and make each of them need someone else. Then write the audit record before the action, not after — the attempts that fail are the ones worth having.
Shown on views20 22 17

Every package used, in one table

These terms are used precisely in this package. Several are used loosely in the wider literature on usage-based billing, and the loose readings are what make metering designs disagree with one another — most often over what "usage", "accurate" and "final" mean.

PackageWhat it isWhat it does hereConsidered instead
Usage event One measured occurrence: producer-assigned event identifier, account, meter, quantity, event timestamp, ingest timestamp, open dimension map and schema version. The unit of transport, deduplication, attribution and evidence — and the only thing in the platform that is a record rather than a derivation. A "usage record" or "metering datum", which hide whether the producer's own identifier and timestamp are carried.
Meter A named quantity with a type — counter, gauge, high-water mark, unique entity — a period grain and a set of dimension keys pricing may depend on. The configuration row that decides which aggregate function a usage event meets, which is why a new meter ships without a deployment. A "metric", which in most systems is something nobody bills against and is allowed to be approximate.
Aggregate A quantity for one account, meter, dimension set and period, carrying the event range that produced it and a provisional-or-closed state. The input to rating and the bridge back to evidence; derived, droppable and rebuildable by replay. A "rollup" or "summary", which usually implies the detail behind it has been discarded.
Provisional A state, not a caveat: the period's lateness bound has not yet elapsed, so the quantity may still change. What every customer-facing figure is until close, and what must never be presented in a way mistakable for a final charge. "Estimated", which suggests a model rather than an incomplete count.
Lateness bound The interval after a period's end during which a late event is still attributed to that period — 72 hours here, as a stated assumption. The line between an ordinary late arrival and a restatement, and the reason a period closes three days after it ends. "Grace period", which is usually about payment rather than measurement.
Plan version An immutable pricing document with an effective-from date: tiers, discounts, commitments and the meters it prices. What rating resolves per sub-period, which is what makes a mid-period change split the period rather than reprice it. A "price list" or "rate card", which are usually mutable and therefore cannot reproduce a historical amount.
Priced line One charge: meter, quantity, plan version, tier breakdown, currency rate date and amount. The unit of an invoice and the thing a customer disputes; expands to its events through the aggregate's event range. A "line item", which rarely carries the plan version and rate date that make it reproducible.
Restatement A scoped, authorised replay of a stated account, meter and period, producing a second figure and retaining the first. The single remedy for every class of error downstream of ingestion, and the reason nothing is ever edited. A "correction" or "adjustment", which usually means the original was overwritten.
Entitlement decision A synchronous answer to whether an account may incur more usage on a meter right now, with a 10 ms p99 and an explicit failure direction. The only synchronous dependency the product's serving path has on this platform. A "quota check" or "rate limit", which are usually about protecting the service rather than about money owed.
Accepted-but-unbilled Usage the platform acknowledged — and therefore promised to bill — that has not yet reached a priced line. The signal that catches lost revenue before a customer does; a normal backlog while a period is open, and a billing incident if it persists past close. "Lag" or "backlog", which measure a pipeline's health rather than a revenue exposure.
Open svg/<view>.svg or drawio/<view>.drawio in draw.io Desktop or at app.diagrams.net to edit. The SVG carries the diagram inside it, so it is both the picture and the source. This folder is self-contained — copy it whole and every link still resolves.