Certificate Lifecycle Service

Architecture Views

21 views, in reading order. Every view ships three ways: an HTML page, an SVG that re-opens in diagrams.net fully editable, and draw.io source.

Twenty-one views in seven acts, for a service that issues, renews, verifies and revokes every X.509 certificate a mid-size B2B SaaS depends on — 24,000 customer custom domains on public trust, 3,800 workload identities on private trust. Read them in order: the argument runs from what sits inside the boundary, through who the system is for and what they get to do, to the structure, the data, the runtime, the operations and finally the assurance. One rule decides the shape of everything after act 2: the issuance log is not the truth, the endpoint is.

Context and scope

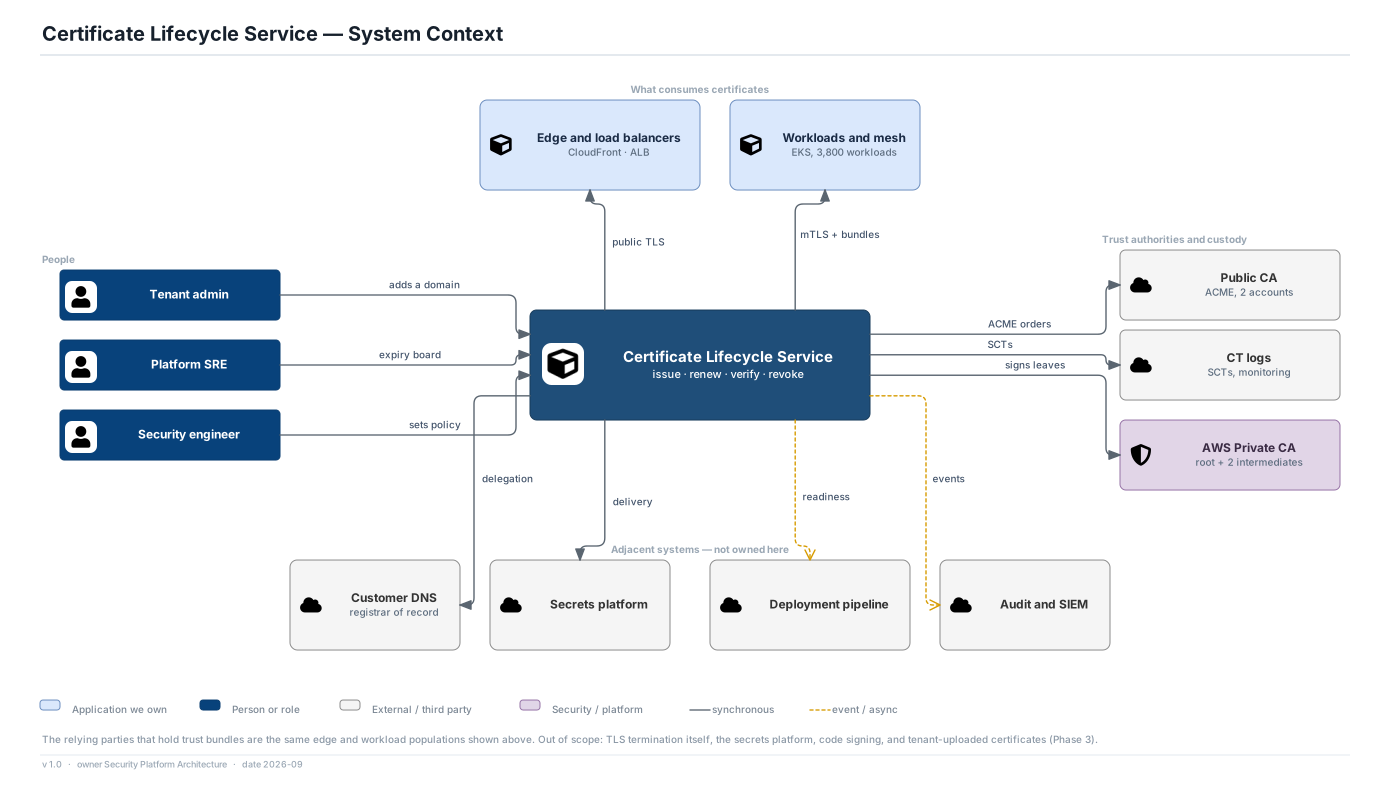
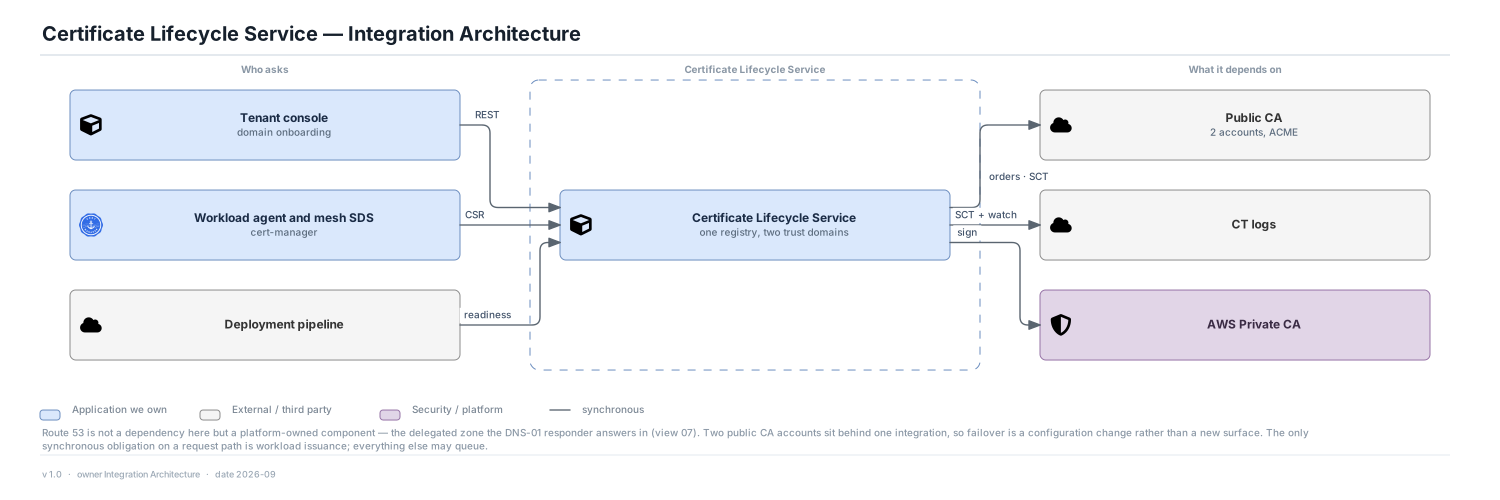
What sits inside the boundary, what the platform depends on, and what it deliberately does not own.

People and journeys

Who this is for, what each of them is trying to do, and the two moments where the design either earns its place or does not.
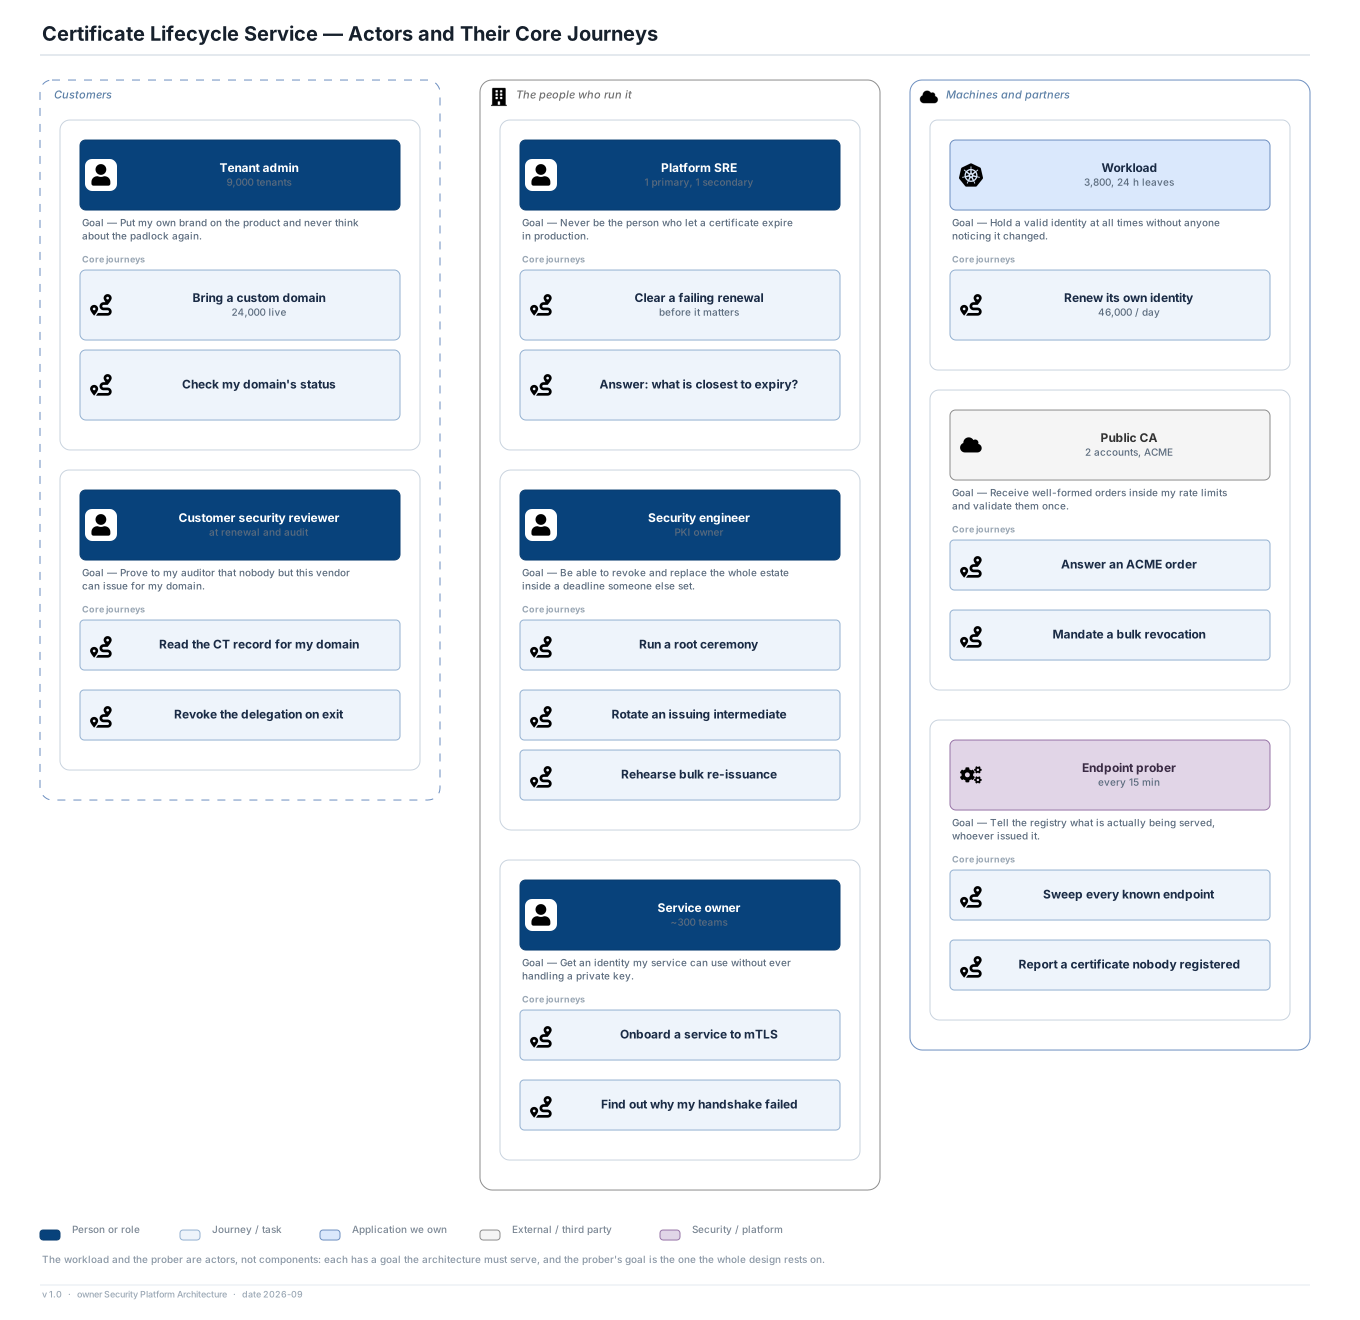
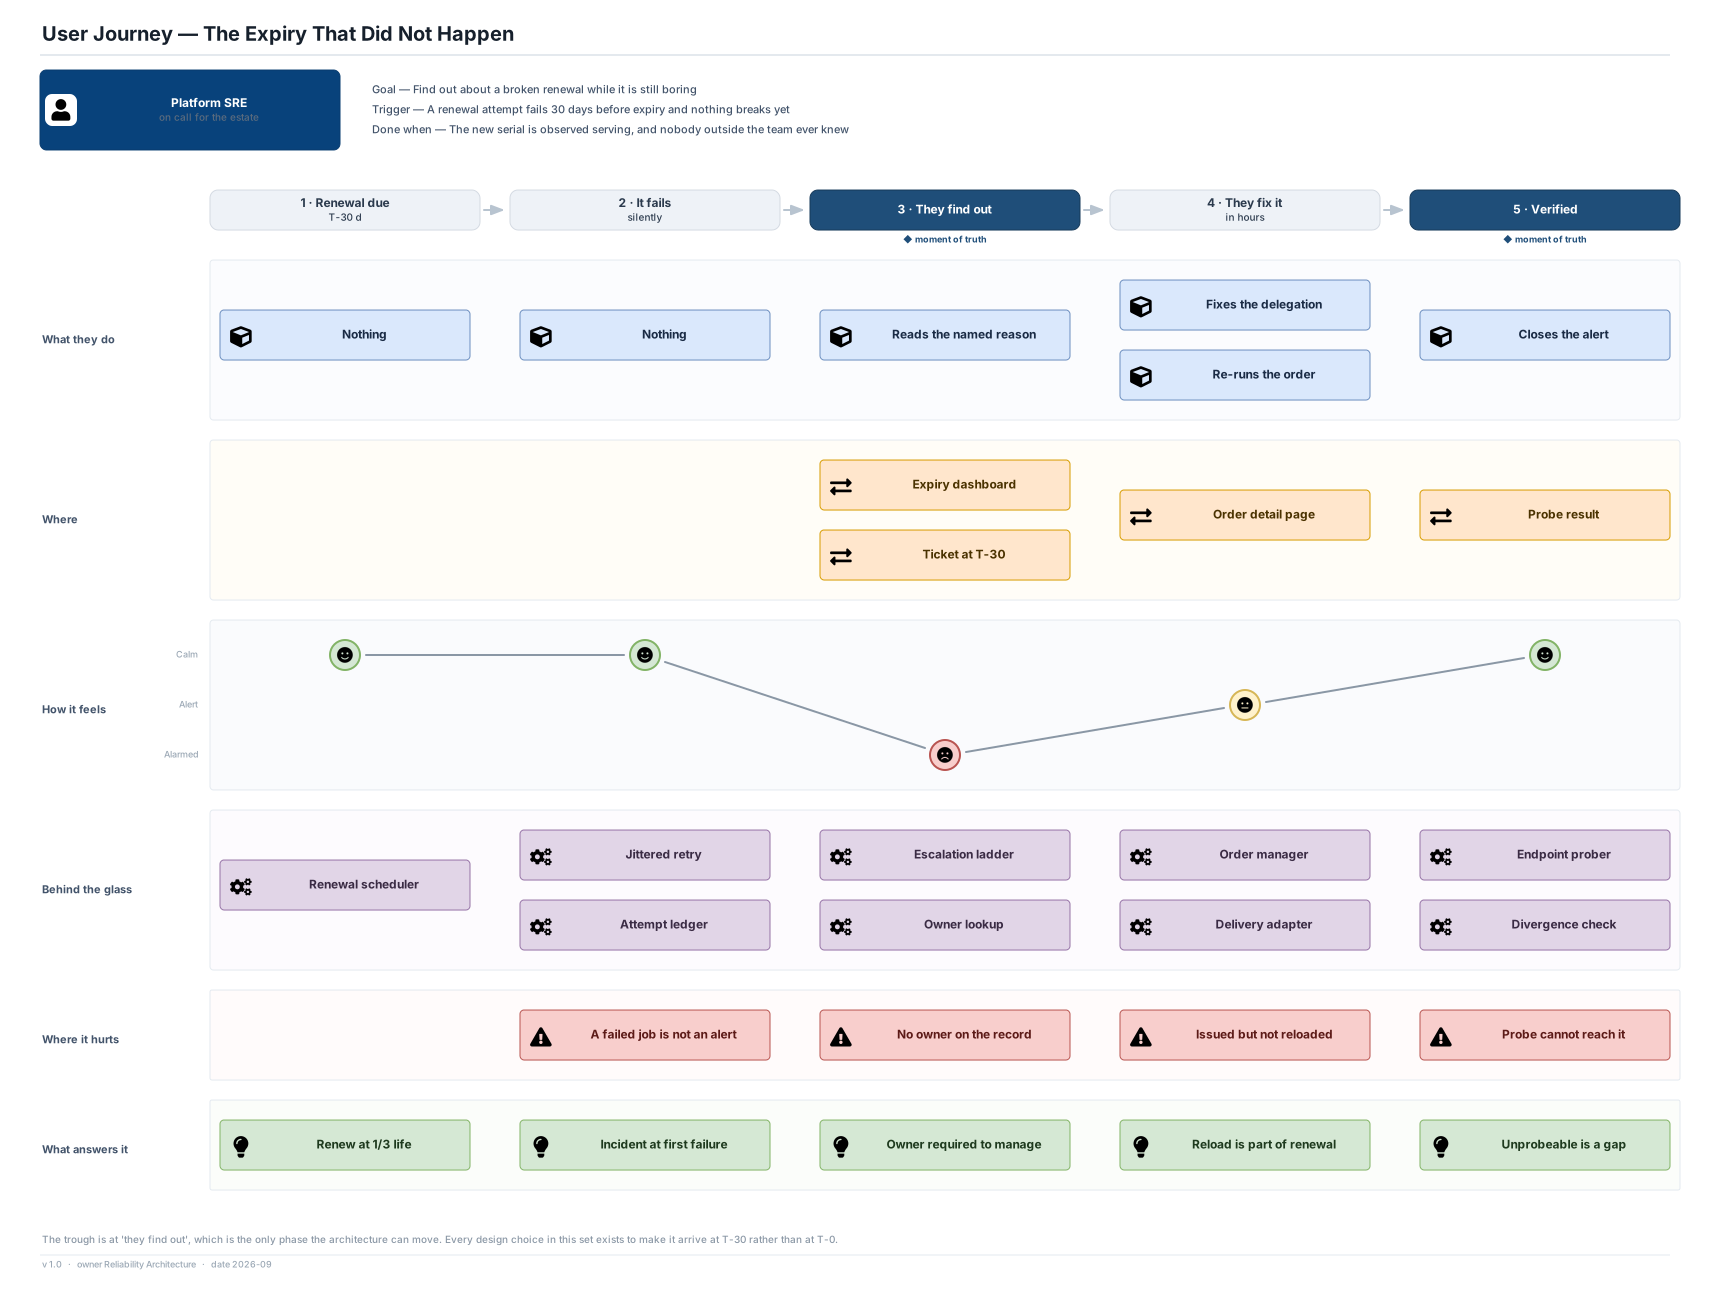
03 Customers Tenant admin 9,000 tenants Goal — Put my own brand on the product and never think about the padlock again. Core journeys Bring a custom domain 24,000 live Check my domain's status Customer security reviewer at renewal and audit Goal — Prove to my auditor that nobody but this vendor can issue for my domain. Core journeys Read the CT record for my domain Revoke the delegation on exit The people who run it Platform SRE 1 primary, 1 secondary Goal — Never be the person who let a certificate expire in production. Core journeys Clear a failing renewal before it matters Answer: what is closest to expiry? Security engineer PKI owner Goal — Be able to revoke and replace the whole estate inside a deadline someone else set. Core journeys Run a root ceremony Rotate an issuing intermediate Rehearse bulk re-issuance Service owner ~300 teams Goal — Get an identity my service can use without ever handling a private key. Core journeys Onboard a service to mTLS Find out why my handshake failed Machines and partners Workload 3,800, 24 h leaves Goal — Hold a valid identity at all times without anyone noticing it changed. Core journeys Renew its own identity 46,000 / day Public CA 2 accounts, ACME Goal — Receive well-formed orders inside my rate limits and validate them once. Core journeys Answer an ACME order Mandate a bulk revocation Endpoint prober every 15 min Goal — Tell the registry what is actually being served, whoever issued it. Core journeys Sweep every known endpoint Report a certificate nobody registered Certificate Lifecycle Service — Actors and Their Core Journeys Person or role Journey / task Application we own External / third party Security / platform The workload and the prober are actors, not components: each has a goal the architecture must serve, and the prober's goal is the one the whole design rests on. v 1.0 · owner Security Platform Architecture · date 2026-09 Actors and Their Core Journeys Three populations with almost nothing in common, and two of the actors are not people. HTML page SVG draw.io
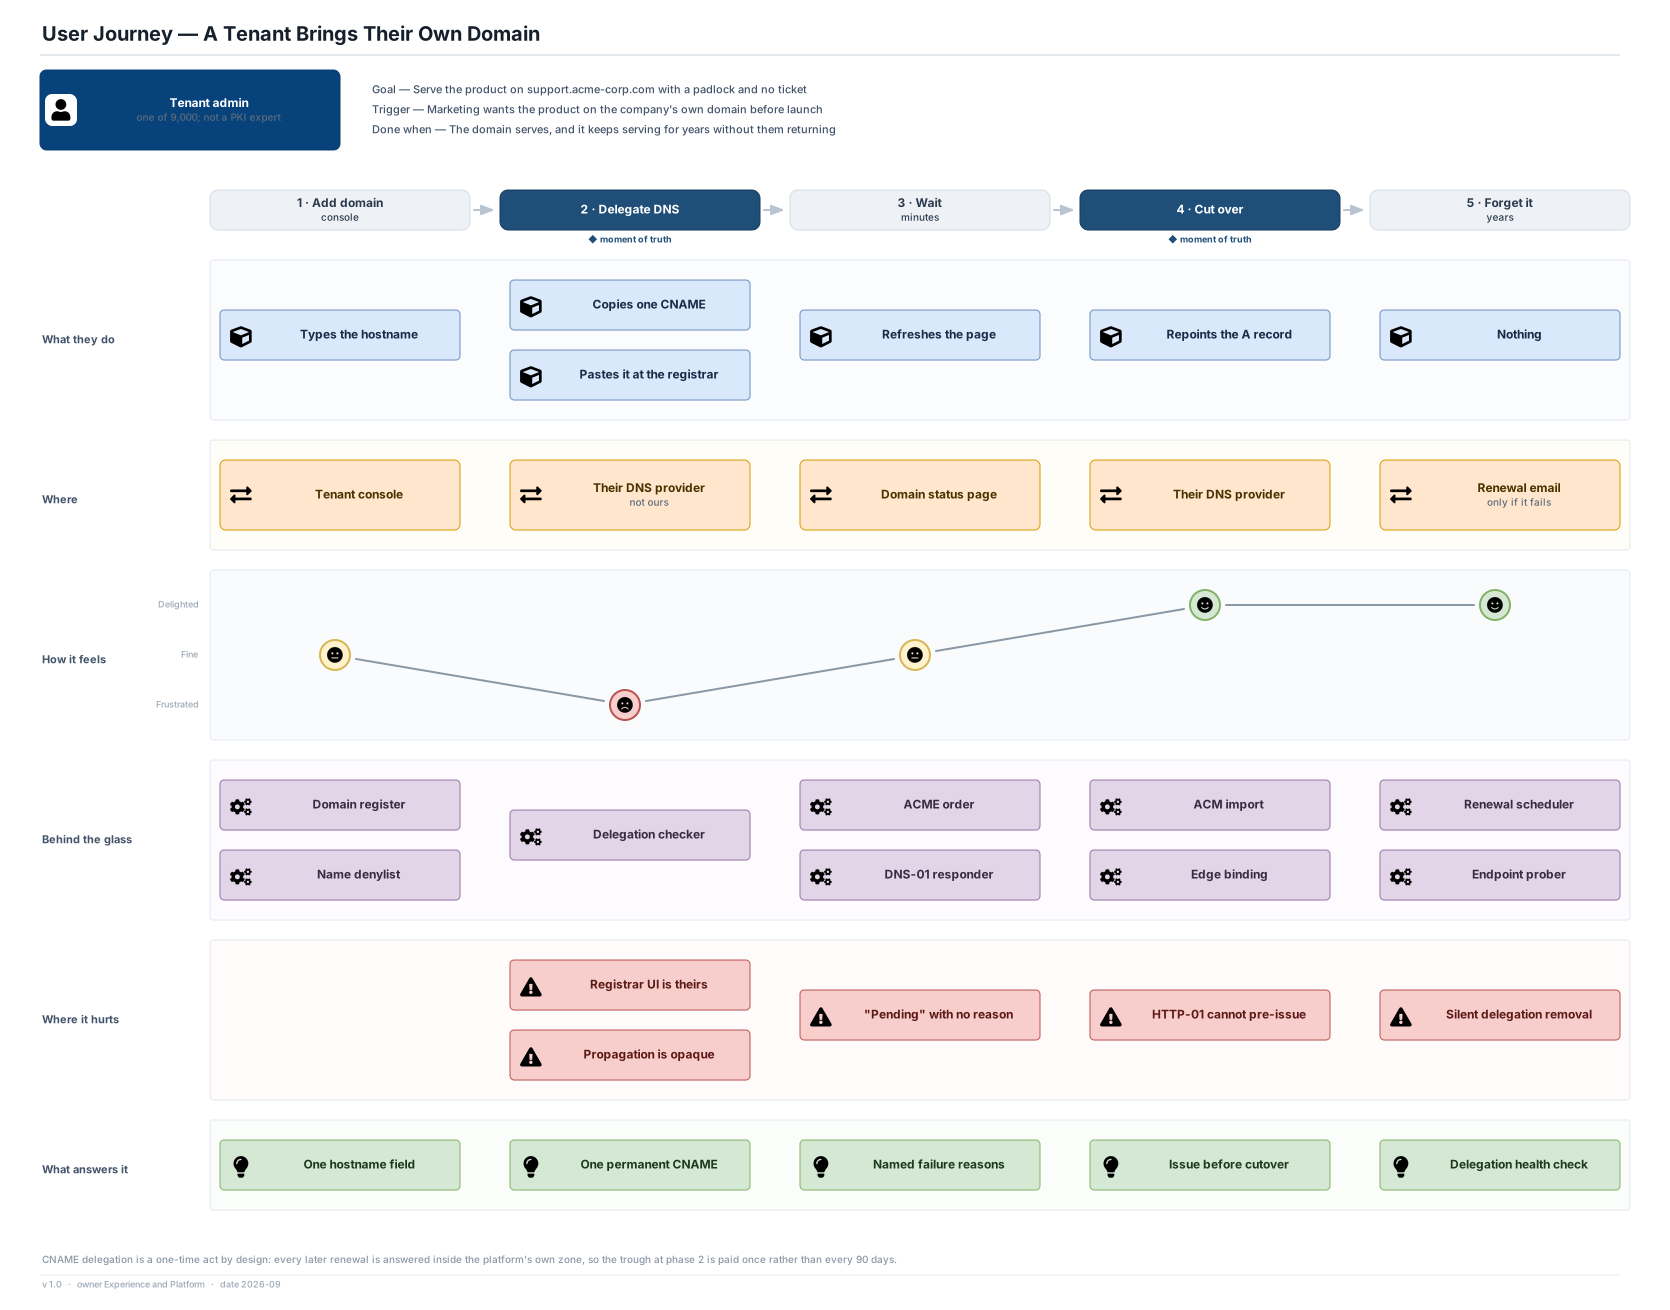
04 Tenant admin one of 9,000; not a PKI expert Goal — Serve the product on support.acme-corp.com with a padlock and no ticket Trigger — Marketing wants the product on the company's own domain before launch Done when — The domain serves, and it keeps serving for years without them returning 1 · Add domain console 2 · Delegate DNS ◆ moment of truth 3 · Wait minutes 4 · Cut over ◆ moment of truth 5 · Forget it years What they do Types the hostname Copies one CNAME Pastes it at the registrar Refreshes the page Repoints the A record Nothing Where Tenant console Their DNS provider not ours Domain status page Their DNS provider Renewal email only if it fails How it feels Delighted Fine Frustrated Behind the glass Domain register Name denylist Delegation checker ACME order DNS-01 responder ACM import Edge binding Renewal scheduler Endpoint prober Where it hurts Registrar UI is theirs Propagation is opaque "Pending" with no reason HTTP-01 cannot pre-issue Silent delegation removal What answers it One hostname field One permanent CNAME Named failure reasons Issue before cutover Delegation health check User Journey — A Tenant Brings Their Own Domain CNAME delegation is a one-time act by design: every later renewal is answered inside the platform's own zone, so the trough at phase 2 is paid once rather than every 90 days. v 1.0 · owner Experience and Platform · date 2026-09 Journey — A Tenant Brings Their Own Domain Five phases, one trough, and a design choice that makes the trough a one-time cost instead of a quarterly one. HTML page SVG draw.io

Structure

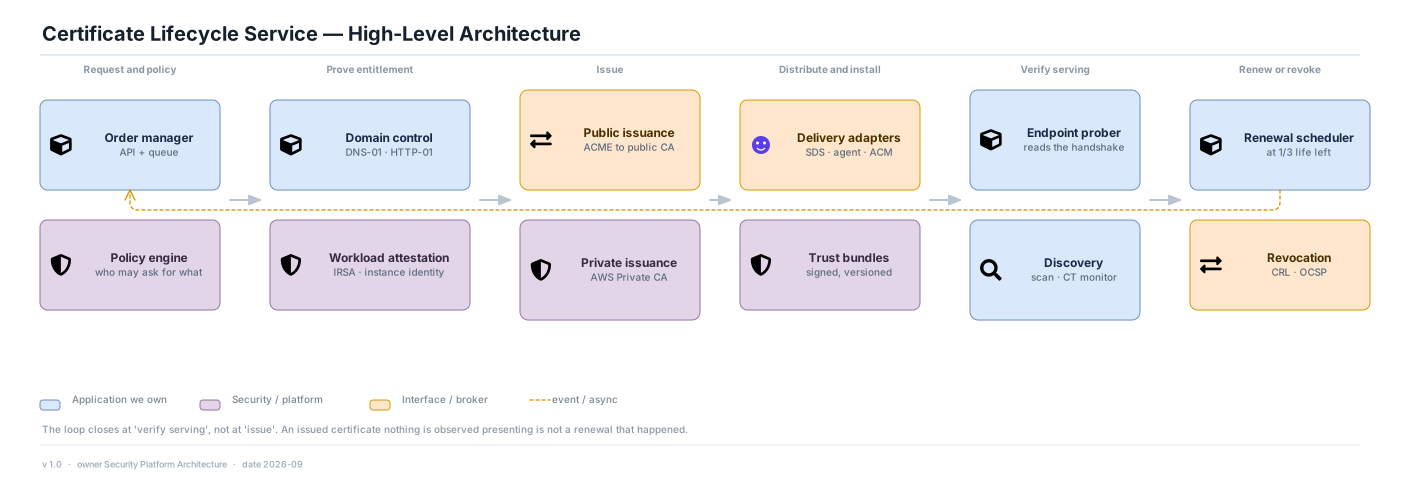
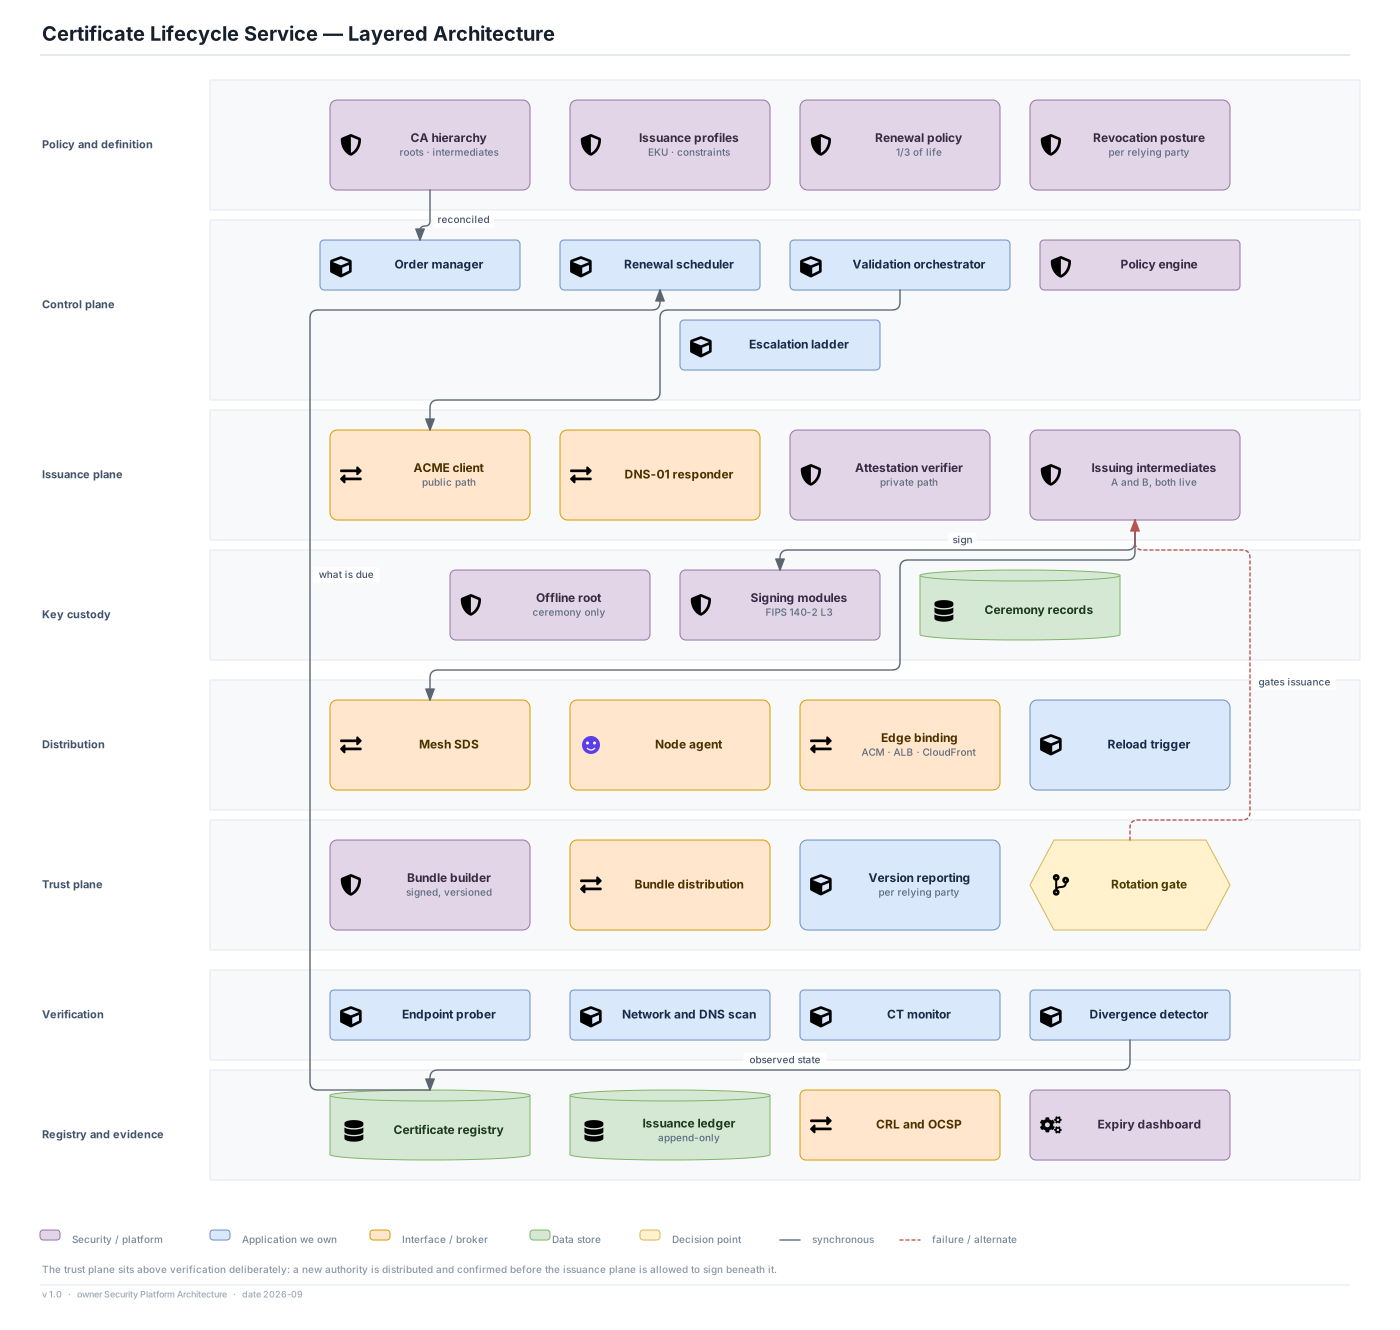
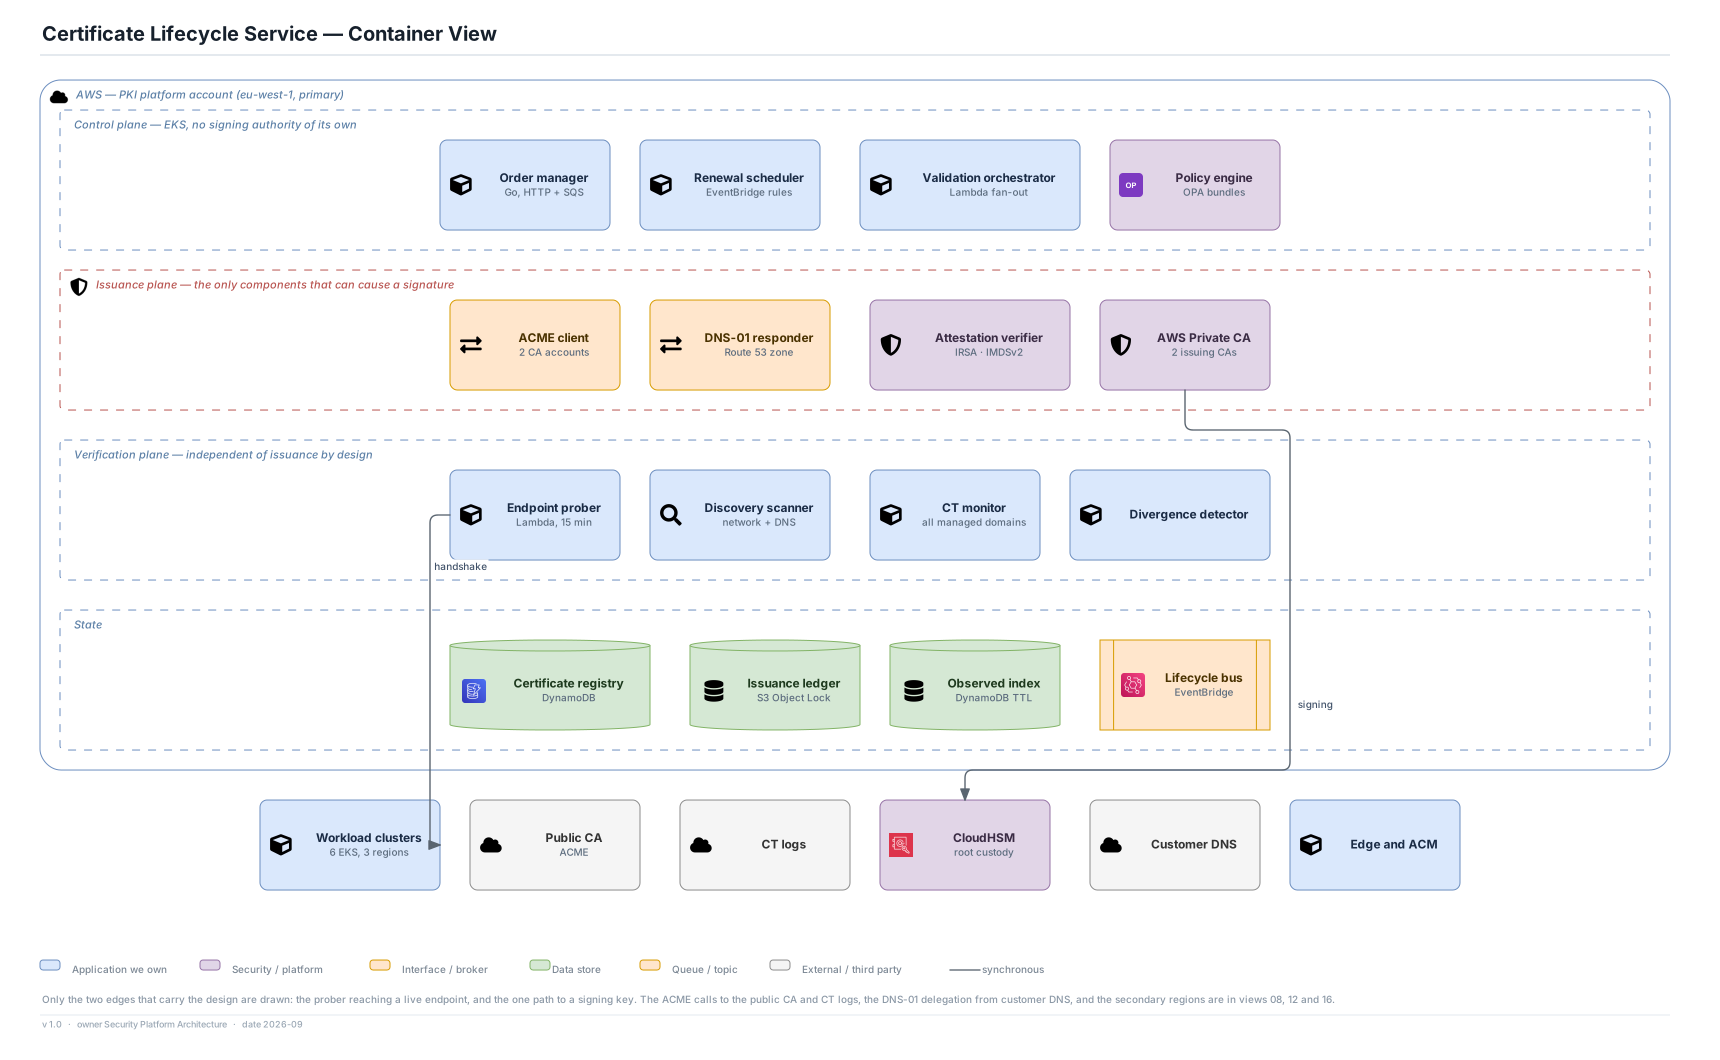
The layers, the deployable units and every surface the platform exposes or consumes.

Data

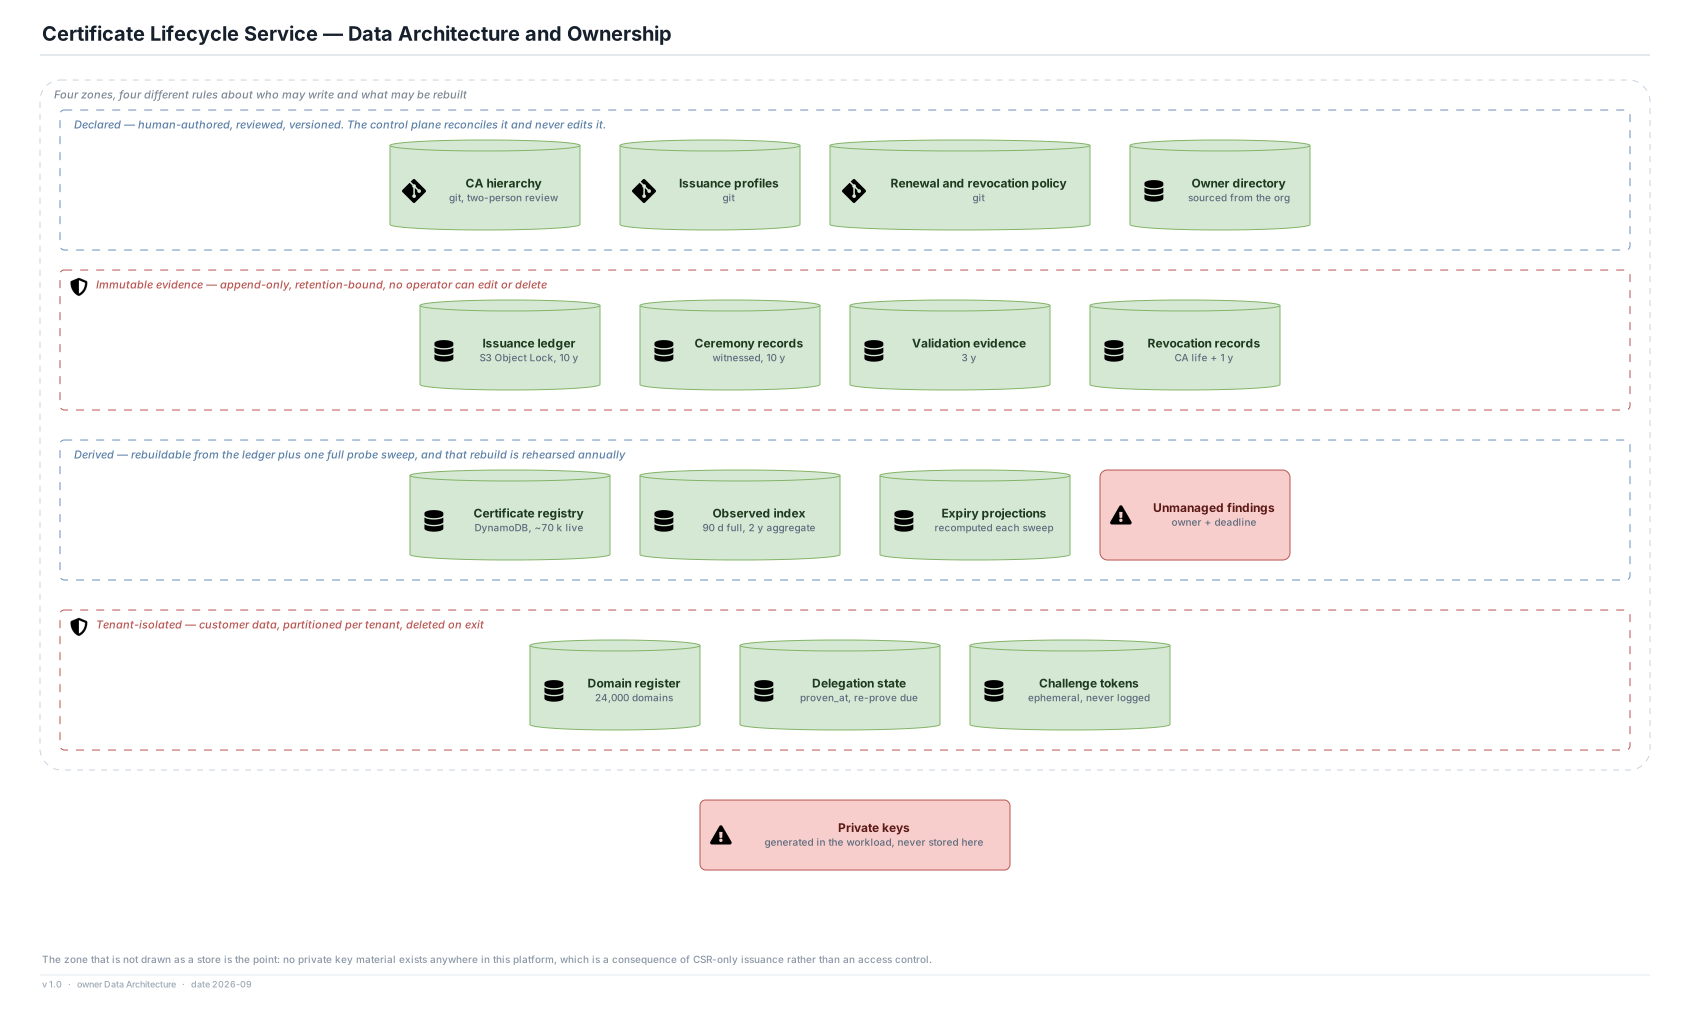
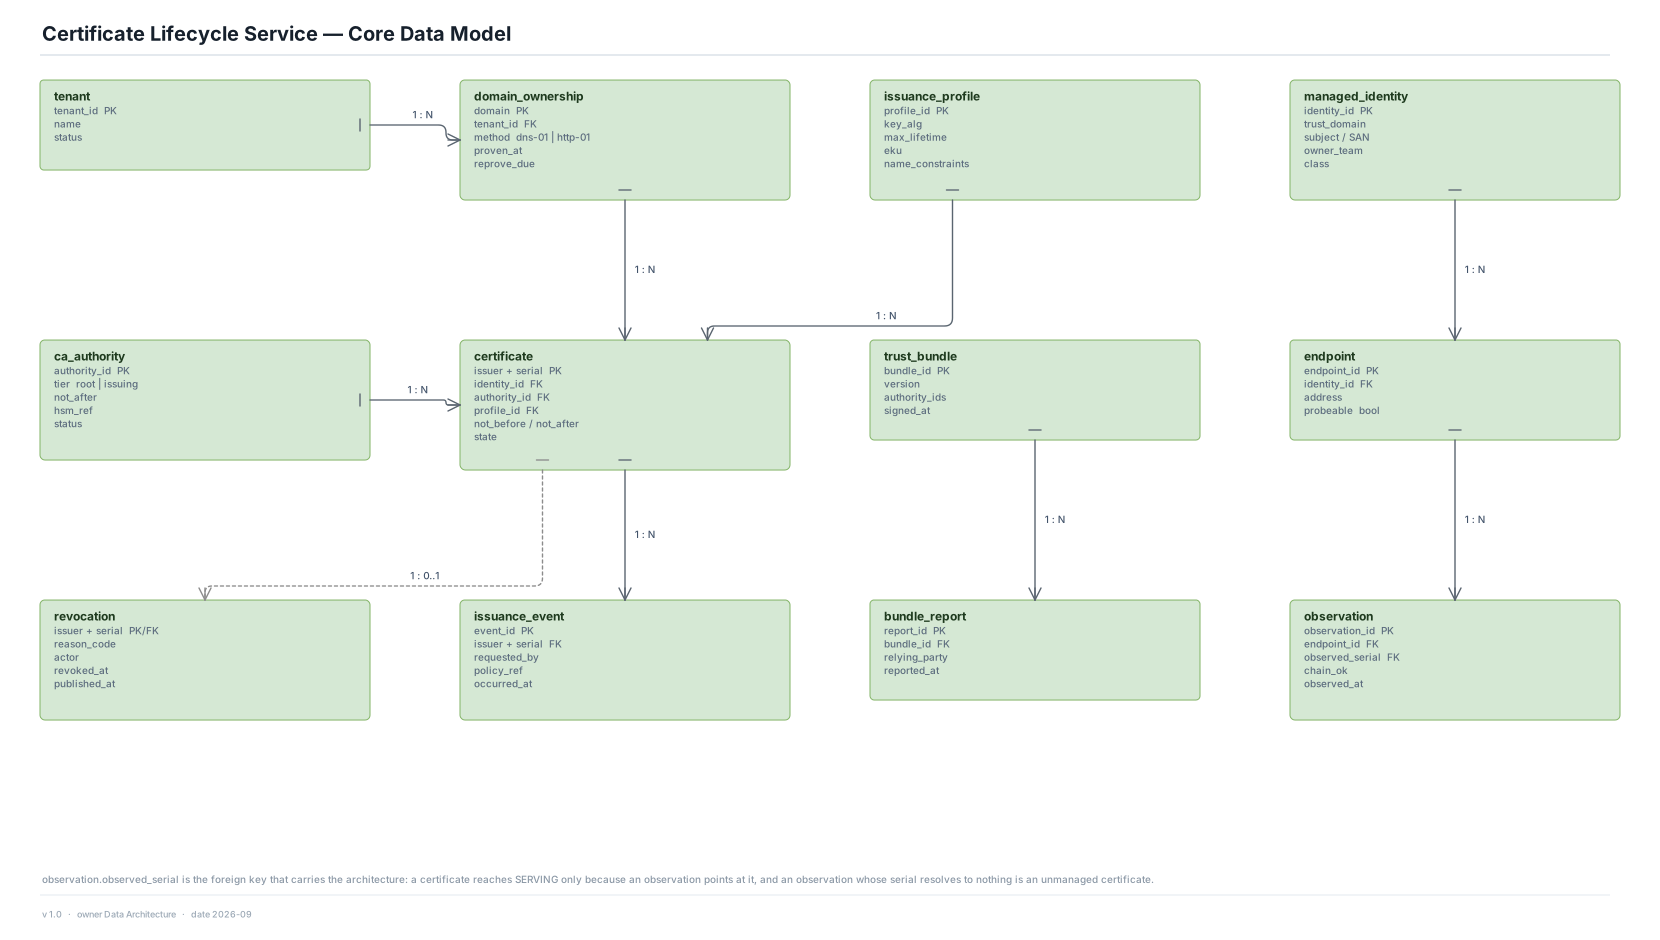
What is declared, what is evidence, what is merely derived — and the one foreign key the architecture rests on.

Runtime

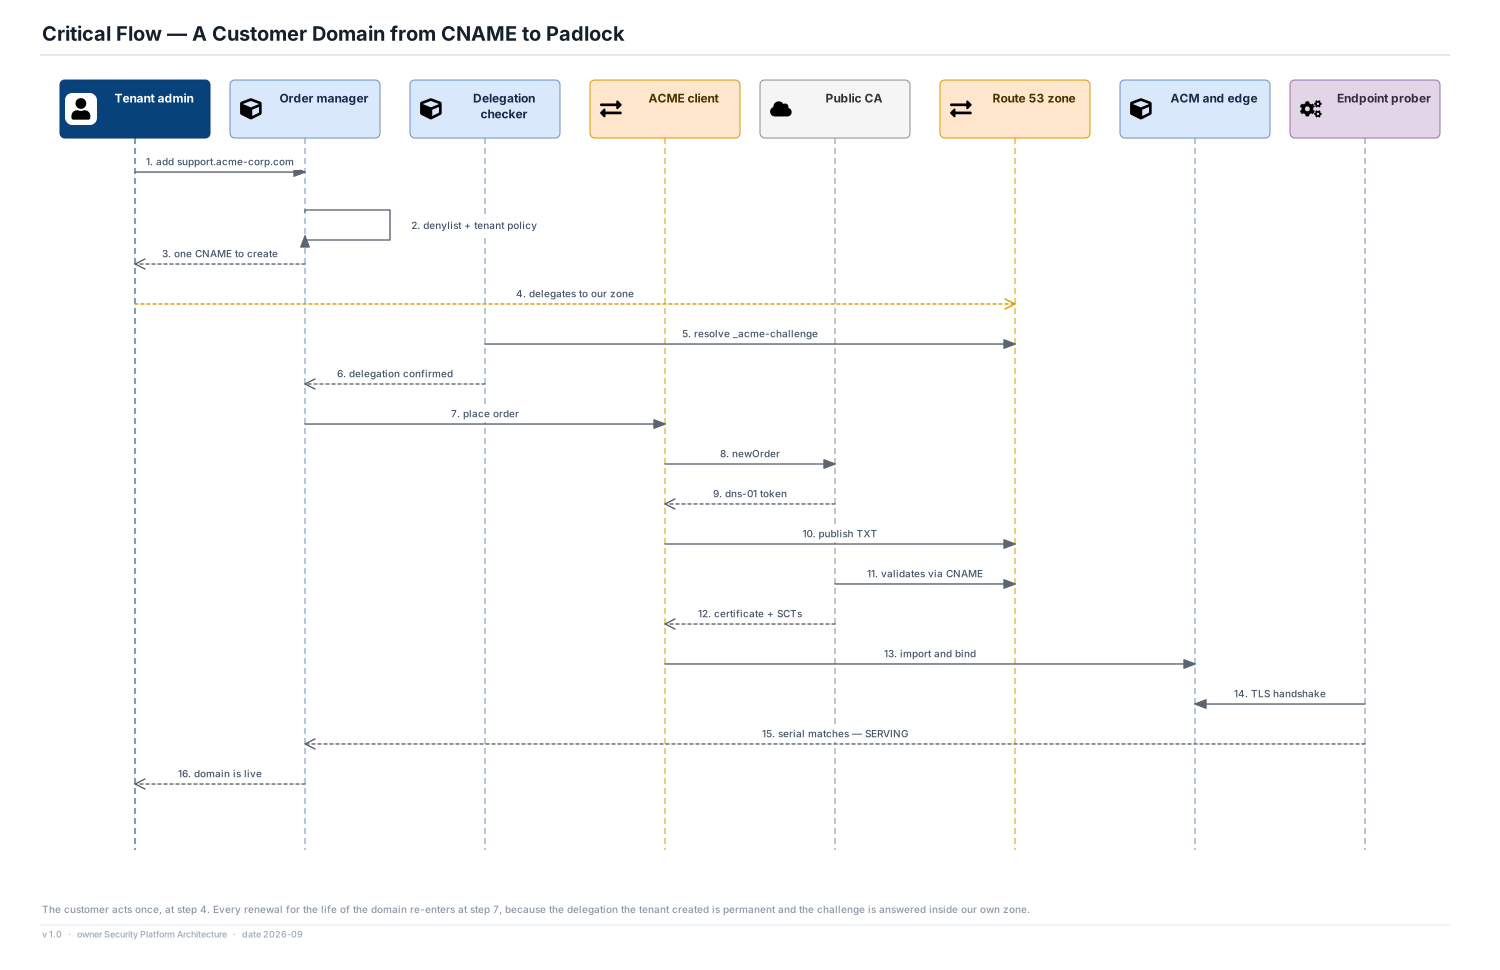
What actually happens when a domain is onboarded, when a certificate renews, and when the whole estate has to be replaced against a deadline.

Operations

Where it runs, how an authority is rotated without breaking anything, and what is watched.

Assurance

Why the keys are safe, and which request the platform exists to refuse.

Architecture One-Pager

The problem, the shape of the answer, the decisions that carry it, and why it should still be right in ten years.

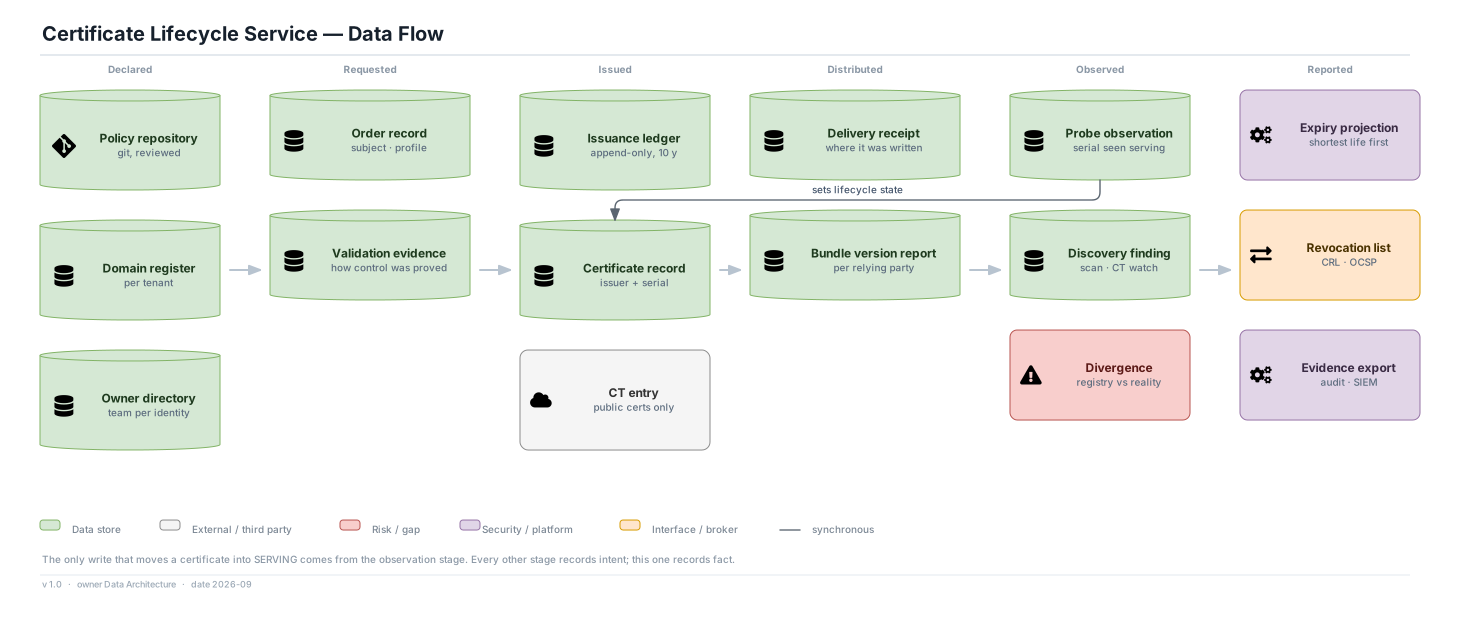
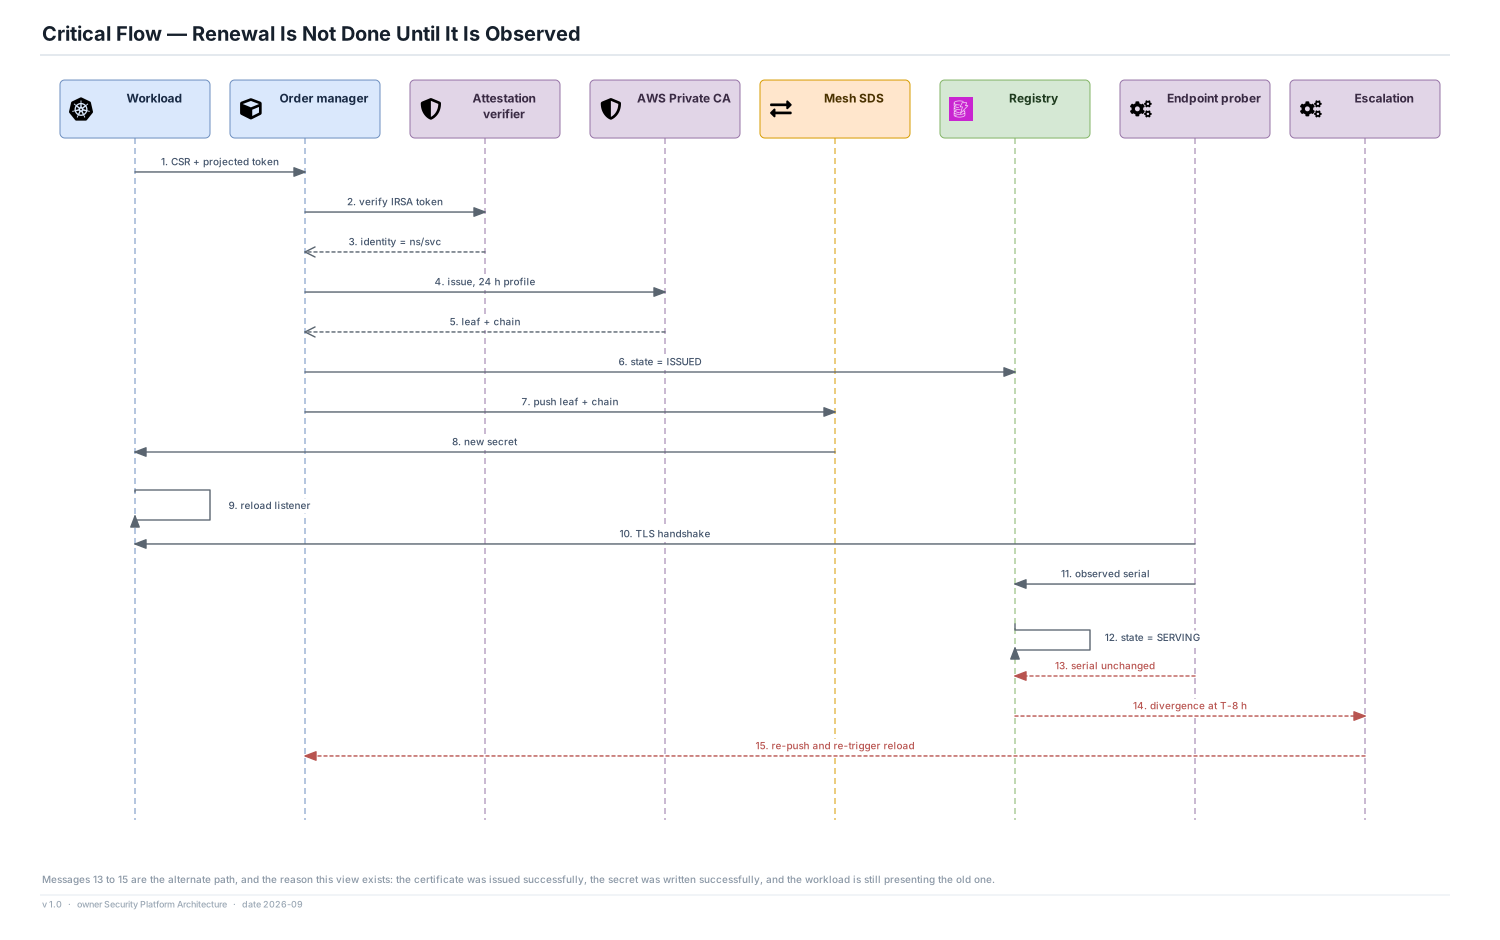
The issuance log is not the truth. The endpoint is. A certificate is SERVING because something was observed presenting it, never because an issuance succeeded.

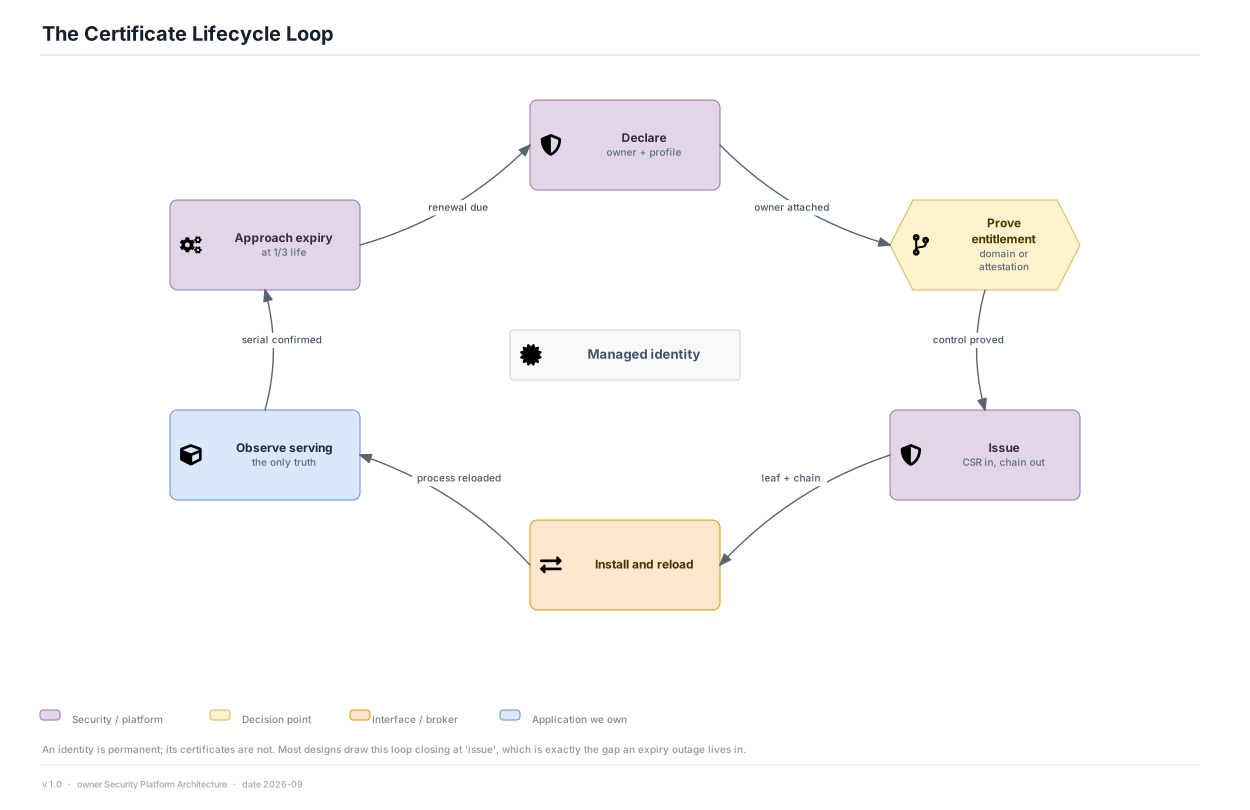
A mid-size B2B SaaS depends on two populations of certificate that behave nothing alike. Twenty-four thousand customer-owned domains are pointed at the platform by tenants who expect a padlock in browsers the platform has no relationship with; three thousand eight hundred internal workloads authenticate each other over mTLS under a certificate authority the platform runs itself. Both populations expire. Expiry is the most preventable failure in production software — a known date, in a machine-readable field, on a certificate the company usually issued to itself — and it still takes down household-name services every year. It does so for a reason that is architectural rather than operational: almost every certificate lifecycle system treats successful issuance as successful renewal. The platform issues, writes the new certificate to a secret store, marks the task complete, and moves on, while the process that actually terminates TLS is still holding the old certificate in memory, having never been told to reload. The issuance log says green. The endpoint says thirty days. Nothing errors, nothing alerts, and the gap between the two is where the outage lives.

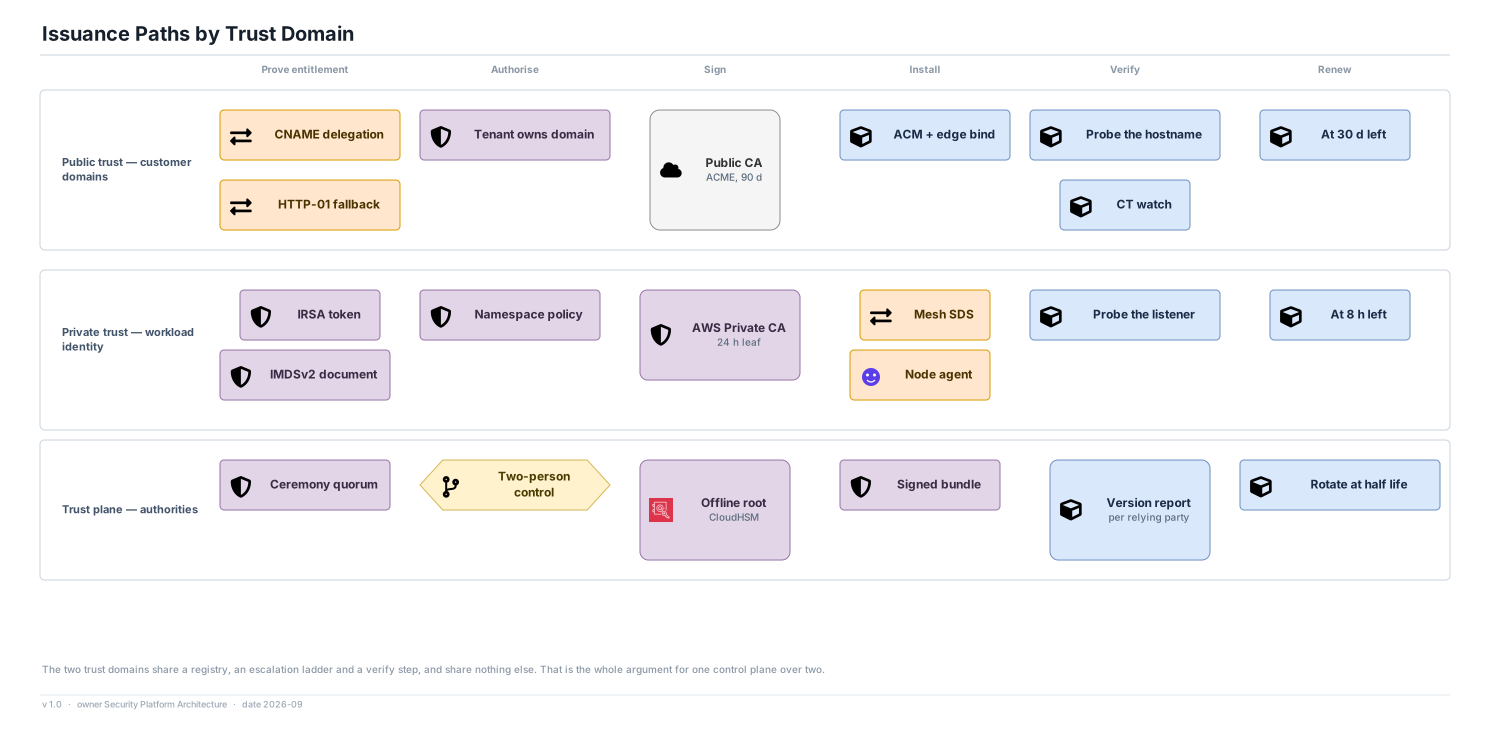
A managed identity is the durable object: it carries an owner, a trust domain, a subject and a compromise history, and it outlives every certificate it holds. Entitlement to a certificate is proved differently per trust domain — a one-time CNAME delegation for a customer's public domain, an attested platform credential for a workload — and authorised by policy before any signature is requested. Issuance is the only plane that can cause a signature: an ACME client against two pre-validated public CA accounts on one side, AWS Private CA under CloudHSM custody on the other. Certificates are delivered through a small set of supported adapters, with the reload trigger inside the renewal transaction rather than downstream of it. Then the design turns: an independent verification plane, deployed per region outside the control plane's failure domain, opens a TLS connection to every known endpoint on a fifteen-minute cadence and writes what it actually saw. That write is the only one that moves a certificate into SERVING, and the renewal scheduler reads what is due from observed state rather than from issuance records — so a renewal that did not take effect stays due. Around it sit the consequences: a registry that is a projection rather than a ledger, discovery and CT monitoring as inputs to the same state machine rather than an audit feature, a trust plane gated strictly ahead of issuance, and a revocation path published independently of everything else.

What it is, and what it is not

A record of what is being serveda record of what was issued, trusted to still be true.
A platform whose renewal completes when a process reloadsone whose renewal completes when a CA responds.
One inventory across two trust domainsone issuance mechanism across two trust domains — they share almost nothing.
A system that treats a failed renewal at T-30 as an incidenta cron job whose failures become incidents at T-0.
A certificate authority operatora TLS terminator — it supplies and verifies the edge and the mesh, and owns neither.
A platform that never holds a private keya platform that holds private keys carefully.
Fail static under its own outagefail closed — nothing already serving is ever invalidated by this platform being down.
Sized to an external revocation deadlinesized to its own convenience, then surprised by a CA's 24-hour clock.

The decisions that are the architecture

01The endpoint is the system of record

Lifecycle state is derived from what endpoints are observed presenting. The issuance log records what was attempted; only an observation records what is true.

ADR-01

02ISSUED and SERVING are different states

They are reached by different mechanisms — one by the issuer, one by the prober — and collapsing them is the defect this architecture exists to prevent.

ADR-02

03Verification does not share a failure domain with issuance

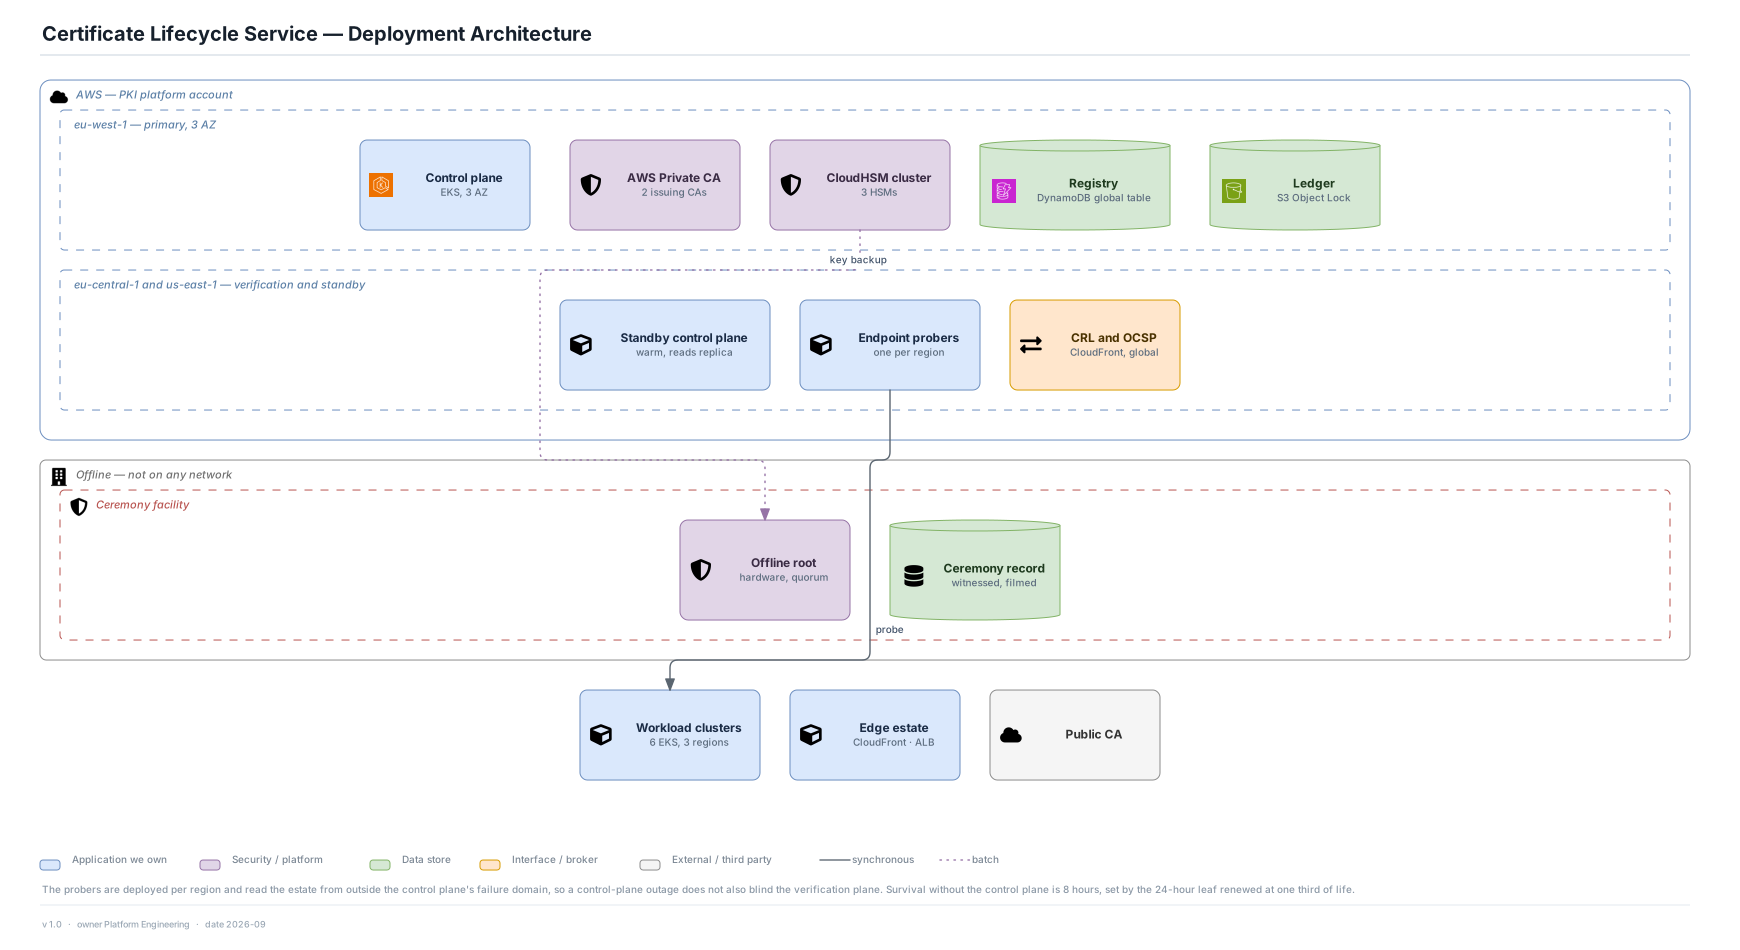
Probers are deployed per region, outside the primary control plane, so an issuance outage does not also blind observation.

ADR-03

04Discovery is an input, not an audit feature

A certificate the platform did not issue is still the platform's outage, so scanning and CT monitoring write into the same state machine as issuance.

ADR-04

05One control plane, two trust domains

Public and private trust share a registry, an escalation ladder and a verify step. They share no protocol, authority, validation mechanism or lifetime, and the design does not pretend otherwise.

ADR-05

06Renewal at a fraction of life, not a fixed number of days

One third remaining, so the policy survives the industry shortening maximum certificate lifetimes again — which it will.

ADR-09

07A failed renewal is an incident from the first attempt

Escalation is measured against remaining validity, not against job status, which is what moves discovery from T-0 to T-30.

ADR-10

08Fail static

An outage of this platform never invalidates anything already serving. Issuance queues, traffic continues, and the estate's survival time without the control plane is a published number.

ADR-12

09Trust before issuance, mechanically

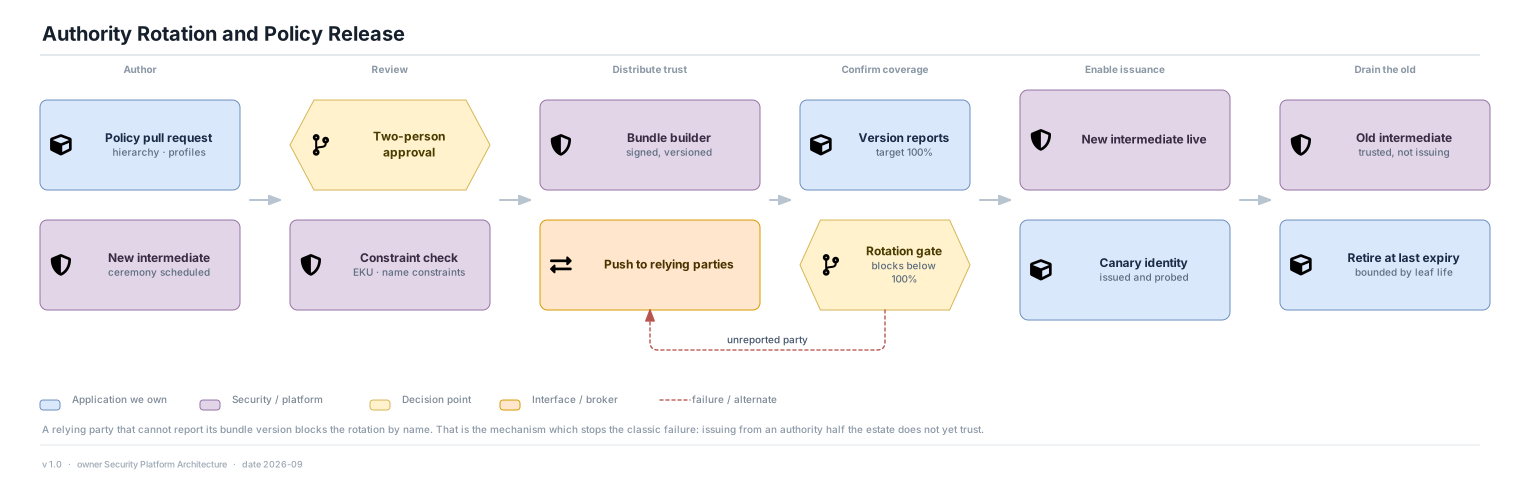
A new authority is distributed and confirmed everywhere before a leaf is signed beneath it, and a relying party that cannot report its bundle version blocks the rotation by name.

ADR-13

10Re-issue precedes revoke

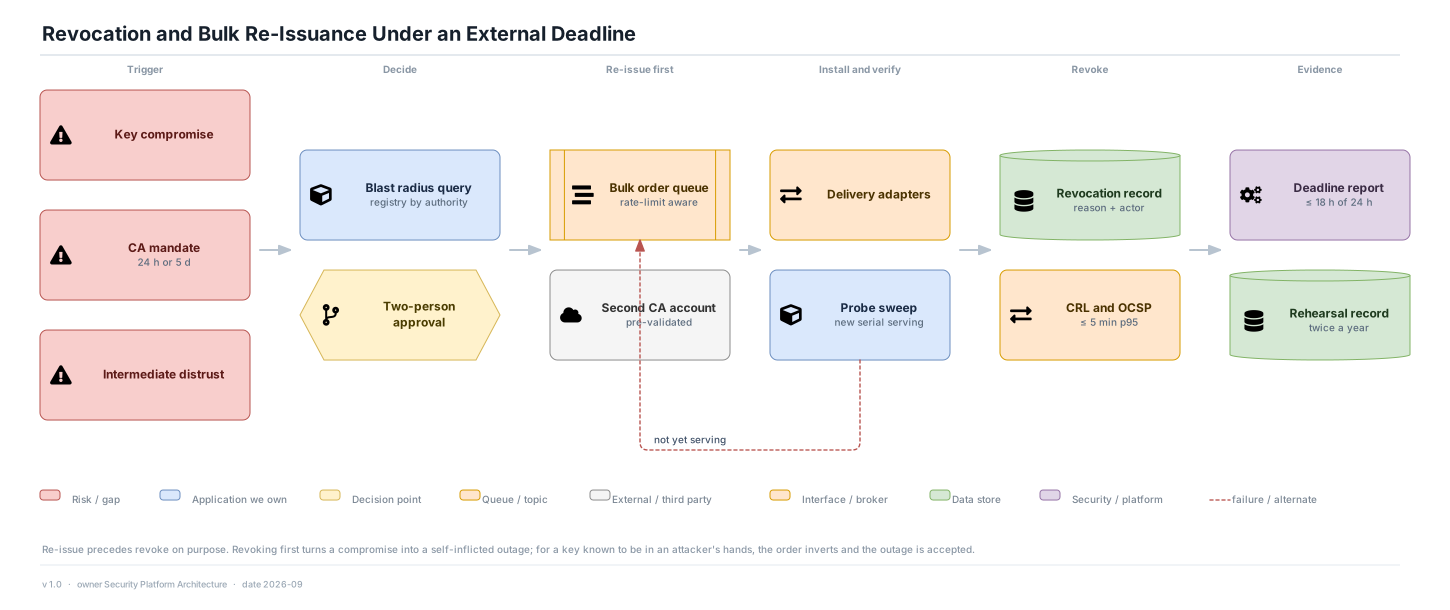
Revoking first turns a compromise notice into a self-inflicted outage. The order inverts only for a key known to be in an attacker's hands, and that inversion has an approver.

ADR-15

11Private keys never travel

Keys are generated inside the consuming workload and only a CSR crosses the network, so the platform's databases hold no key material to lose.

ADR-18

12Authorisation is policy over attested identity

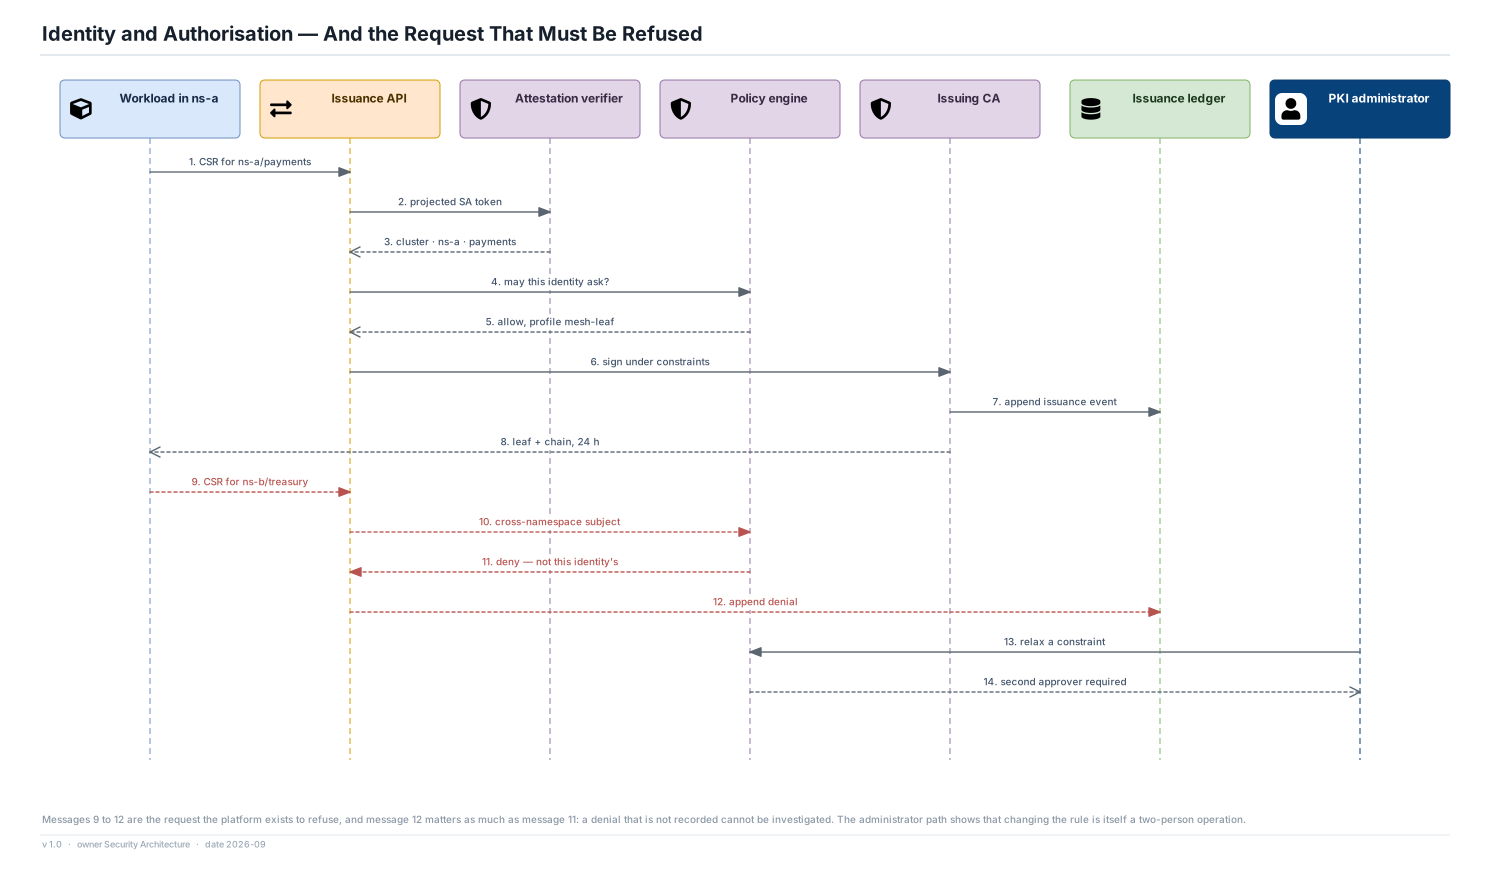
Identity comes from a platform-attested credential, never a self-asserted subject, and every denial is recorded — a refusal nobody can investigate is not a control.

ADR-20

Why this should still be right in ten years

Certificate infrastructure outlives almost everything around it: a root signed today is still signing when the team that made it has gone, and the rules it has to obey are set by a standards body nobody in this organisation sits on. These are the properties that should survive a change of cloud, a change of CA, and another round of the industry shortening certificate lifetimes.

The truth rule names no technology

ADR-01 depends on nothing about DynamoDB, AWS, ACME or X.509. It is a statement about which of two sources to believe when they disagree, and it survives replacing every component underneath it. It is also the property a future team would most easily discard — by adding a fast path that marks a renewal complete on issuance — which is why SERVING is a state only the prober can write.

Renewal policy expressed as a fraction is future-proof by construction

Maximum public certificate lifetimes have fallen from years to months and are still falling. A policy that says "renew 30 days before expiry" quietly becomes a policy of renewing at half of life, then at all of it. A policy that says "one third of lifetime remaining" needs no change at all.

External deadlines only get tighter

The obligation to revoke and replace inside 24 hours is imposed from outside and has never been relaxed. Designing the bulk path as a rehearsed capability with a measured duration, rather than as an emergency, is the property that stops the next CA incident being an existential one.

Short lifetimes make the design more correct, not less

Every industry trend — shorter certificates, automated issuance, ubiquitous mTLS — increases issuance volume and decreases the value of revocation infrastructure. Both movements favour this architecture: lifetime becomes the control, and the renewal machinery is exercised continuously rather than discovered during an incident.

The verification plane is where the value accrues

As the estate grows, the registry's belief and reality drift further apart, and the cost of being wrong rises. The one component that would be tempting to cut in year one — the prober — is the one that becomes indispensable in year five.

Non-functional targets

Every number here is a stated assumption from the requirement, chosen to be argued with rather than believed. The right-hand column names the view where the mechanism that meets it is drawn.

QualityTargetHow it is metView
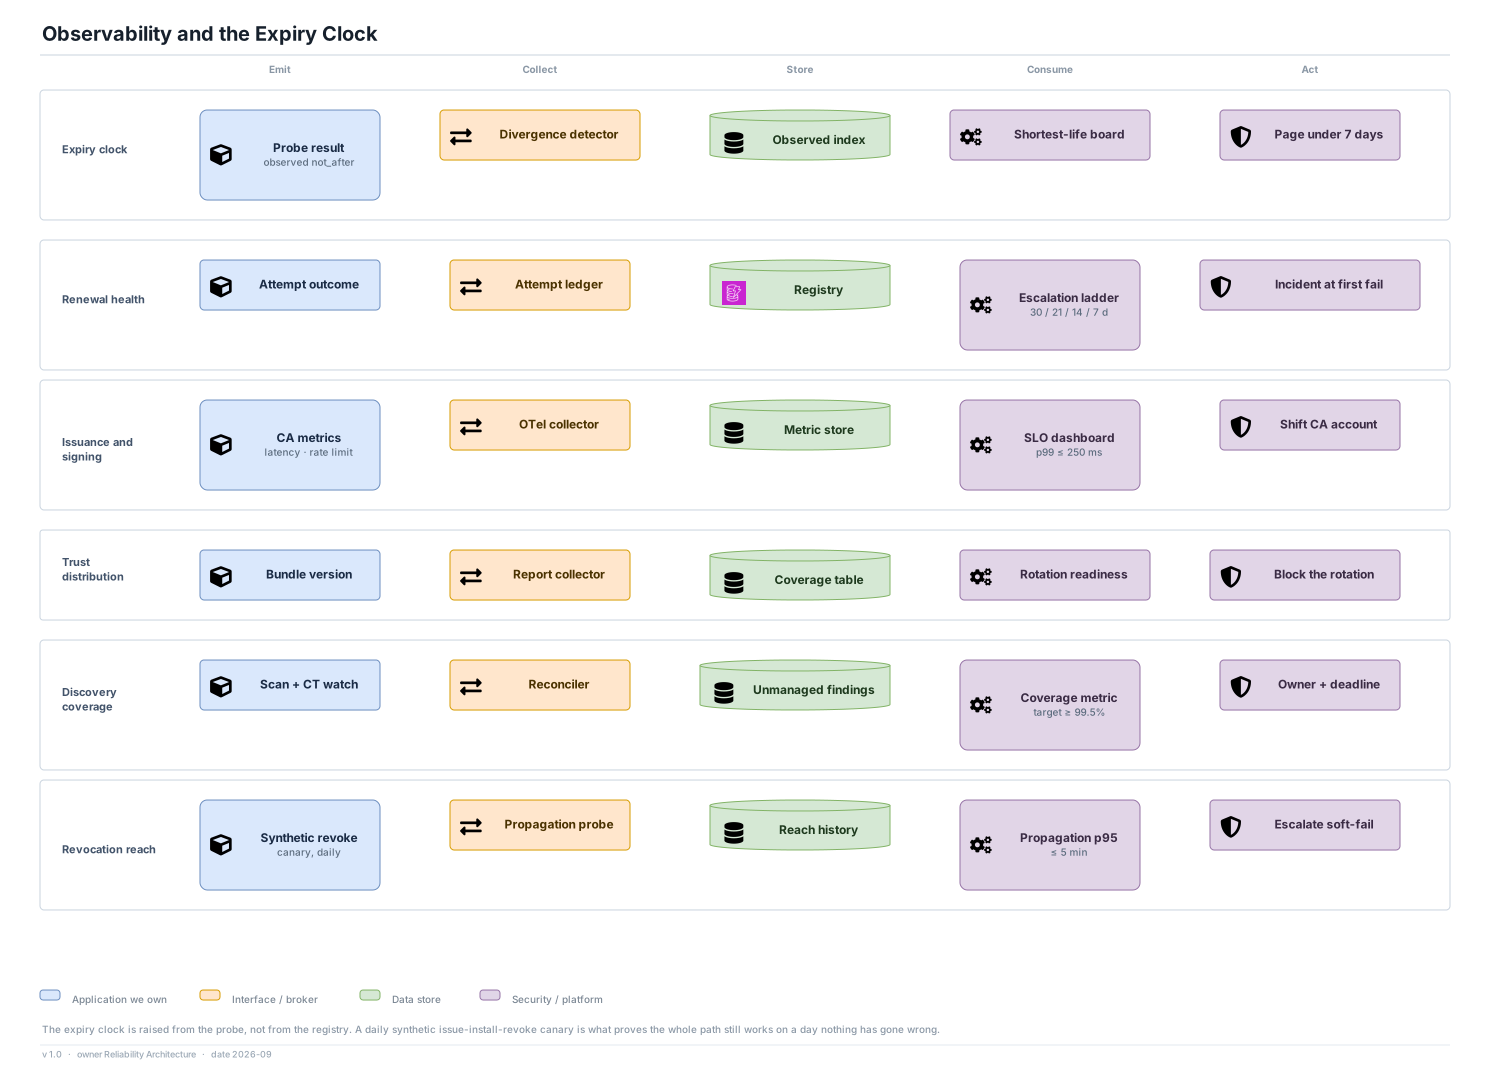
Certificates expiring while serving Zero, Sev-1 with a written review Expiry clock raised from the probe, not the registry; escalation ladder driven by remaining validity from the first failed attempt. 18
Private leaf issuance latency p95 ≤ 120 ms, p99 ≤ 250 ms in-region Attestation verified locally against a projected token; AWS Private CA called directly by the issuance plane with no control-plane hop on the hot path. 13
Public certificate, order to installed p95 ≤ 90 s, p99 ≤ 10 min Delegation already in place, so the challenge is answered inside the platform's own Route 53 zone; DNS propagation dominates the tail. 12
New domain to padlock ≤ 15 min p95, no support interaction Self-service CNAME delegation, named failure reasons on every validation outcome, issue before cutover. 04
Expiry detection delay ≤ 15 min p95 Regional probers sweep every known endpoint on a 15-minute cadence and compare the observed serial against the registry. 18
Renewal verified serving ≤ 10 min p95 after issuance Reload trigger inside the renewal transaction, followed by a targeted probe rather than the next scheduled sweep. 13
Revocation propagation ≤ 5 min p95, ≤ 15 min p99 CRL and OCSP published through CloudFront on a path independent of issuance; measured by a daily synthetic issue-install-revoke canary. 18
Bulk re-issuance of public trust ≤ 18 h, inside a 24 h mandate Rate-limit-aware bulk order queue across two pre-validated CA accounts; rehearsed twice a year against a representative subset. 15
Trust bundle distribution ≤ 4 h p95 to 100% of reporting parties Signed versioned bundle on its own lifecycle, with per-relying-party version reporting and a rotation gate that blocks below full coverage. 17
Private issuance availability ≥ 99.95% monthly Issuance plane across three AZ; a workload that cannot renew keeps serving until its leaf expires, which is the 8-hour margin. 16
CRL and OCSP availability ≥ 99.99% monthly Read-only, globally cached, published independently so that an issuance outage cannot prevent a revocation from being seen. 20
Estate survival without the control plane ≥ 8 h, published as a metric 24-hour leaf renewed at one third of life; fail static, so an outage stops change and stops nothing else. 16
Managed coverage of TLS endpoints ≥ 99.5%, remainder named and dated Network and DNS scanning plus CT monitoring reconciled against the registry; unmanaged findings carry an owner and a deadline. 09
Registry-to-reality divergence ≤ 0.1% at any probe cycle Divergence detector compares observed serial against registry state on every sweep and raises the gap as its own signal. 18
Registry recovery RPO 0, RTO ≤ 30 min DynamoDB global table; full rebuild from the append-only ledger plus one probe sweep, rehearsed annually. 10
Issuing intermediate replacement Live and distributed ≤ 4 h Two issuing intermediates kept live at all times, both already in every distributed trust bundle. 17
Root recovery RTO ≤ 72 h, human in the path by design Witnessed ceremony from hardware backup under two-person control; the one recovery path deliberately not automated. 16

Scope

In scope

  • A certificate registry spanning both trust domains, with an explicit lifecycle state model in which SERVING is reachable only by observation.
  • Public-trust issuance for customer custom domains over ACME, with DNS-01 CNAME delegation as the primary validation path and HTTP-01 as a stated-trade-off fallback.
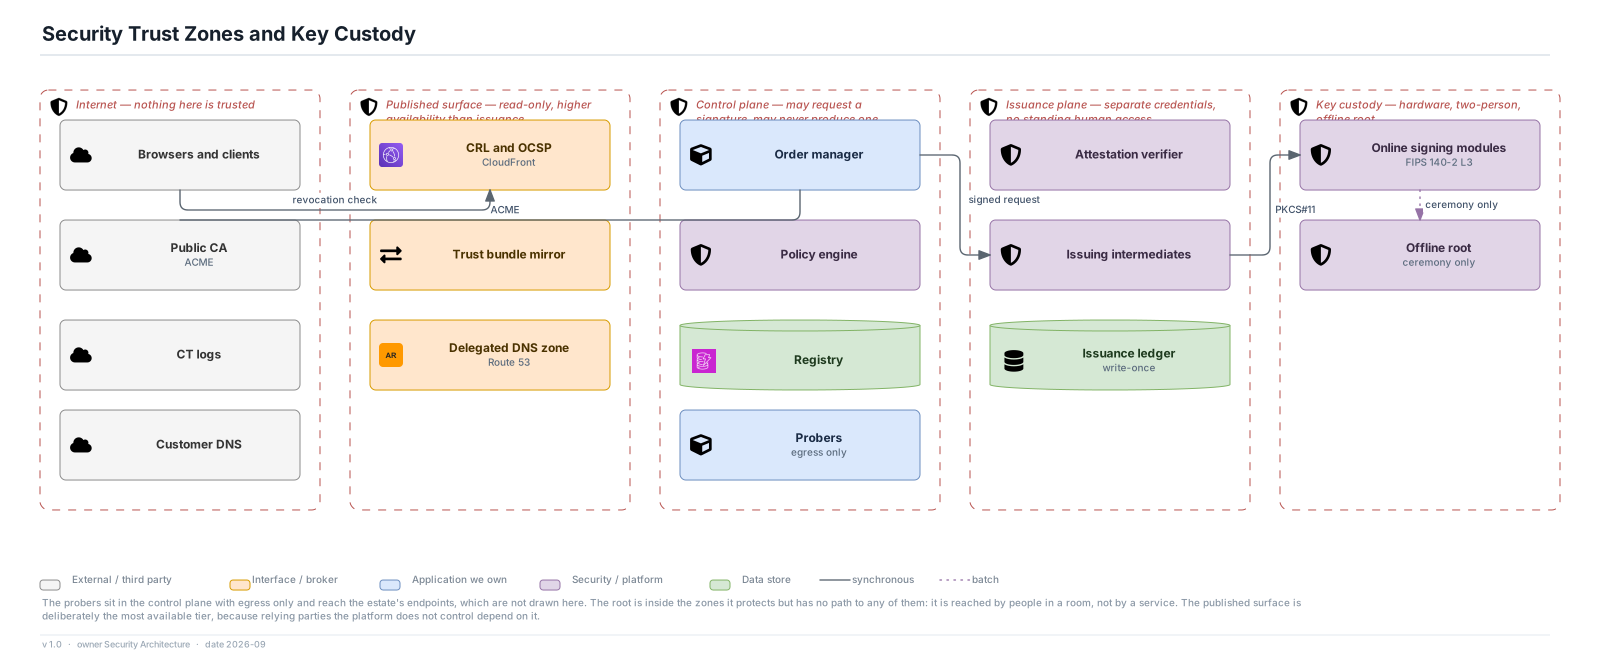
  • Private PKI: an offline root, two live issuing intermediates, HSM custody, and short-lived workload leaves issued against attested platform identity.
  • Automated renewal at a fraction of lifetime remaining, with a jittered retry and an escalation ladder measured against remaining validity.
  • Delivery through a small set of supported adapters — mesh SDS, node agent, edge and ACM binding, secrets platform — with the reload trigger inside the renewal transaction.
  • Signed, versioned trust bundle distribution with per-relying-party version reporting and a mechanical gate ahead of issuance.
  • An independent verification plane: endpoint probing, network and DNS discovery, Certificate Transparency monitoring, divergence detection.
  • Revocation through CRL and OCSP on an independently published path, plus rehearsed bulk revocation and re-issuance against an external deadline.
  • An append-only issuance ledger, per-issuance attribution, ceremony records and the evidence exports compliance will ask for.

Explicitly out of scope

  • TLS termination itself. The platform supplies certificates to the edge and the mesh, and verifies them; it does not terminate.
  • The secrets platform, used as one delivery channel among several and owned elsewhere.
  • Code signing, document signing and any non-TLS use of the hierarchy.
  • Customer-supplied certificate upload, deferred to Phase 3 with its own renewal-reminder path.
  • Running the customer's DNS. The platform holds a delegated zone and answers challenges in it; the customer's registrar remains theirs.
  • The CMDB and service catalogue, which consume lifecycle events rather than being maintained here.

What a four-week prototype should prove

Four of this architecture's claims are cheap to test and expensive to be wrong about. A prototype that proves these can be built on; one that skips them is a demonstration of calling an ACME client, which is the easy half.

  1. The truth rule end to end: renew a certificate, deliberately suppress the reload, and confirm the platform holds the certificate at ISSUED, keeps it due for renewal, and escalates — rather than reporting success.
  2. Probe reach: instrument a representative slice of the estate and measure what fraction of TLS endpoints the prober can actually reach. The ≥ 99.5% coverage target is the number most likely to be wrong, and the unreachable remainder is the real blind spot.
  3. Delegation durability: onboard a domain with a CNAME delegation, then renew it three times across an artificially compressed schedule, confirming the tenant is never asked to act again and that a removed delegation is detected before it causes a failed renewal.
  4. Bulk capacity: time the re-issuance of a representative subset against both CA accounts under real rate limits, and extrapolate honestly. If 18 hours is not achievable, the architecture needs to know before a CA sets the clock.
  • Issued but not reloaded: renew a certificate, suppress the reload signal, and confirm the platform holds it at ISSUED, keeps it due, and escalates — rather than reporting a successful renewal.
  • Delegation withdrawn: remove a test tenant's _acme-challenge CNAME and confirm the delegation health check raises it long before the next renewal is due.
  • Control plane down: stop the control plane for four hours and confirm every workload keeps serving, orders queue rather than error, and the probers keep reporting.
  • Unreportable relying party: introduce a consumer that cannot report its trust bundle version and confirm the rotation gate blocks and names it, rather than proceeding.
  • Unmanaged certificate: stand up a TLS endpoint with a certificate the platform never issued and confirm discovery finds it, files it as UNMANAGED, and demands an owner.

Open risks, carried rather than hidden

RiskIf it landsResponse
The prober cannot reach enough of the estate If a material fraction of TLS endpoints is unprobeable, the truth rule degrades to belief for exactly the population most likely to be forgotten, and the headline guarantee weakens without any alarm firing. Measure coverage in the prototype. Unprobeable endpoints become a named architectural gap with an owner — a local agent, an exposed health surface, or an accepted exception — rather than an invisible remainder (ADR-03, ADR-04).
Short private leaves overrun the signing budget A 24-hour leaf at 3,800 workloads is 46,000 issuances a day before churn; a fleet-wide rollout is 37× steady state in ten minutes. Signing throughput is the binding constraint and it is not elastic. Size against measured AWS Private CA throughput early and treat leaf lifetime as the tuning dial. Lengthening the leaf relaxes the signing budget and lengthens the compromise window in the same move (ADR-08).
A relying party that cannot report its bundle version blocks rotation indefinitely The rotation gate is deliberately strict. A single legacy consumer with no reporting path can stall an authority rotation that has a deadline behind it. Inventory reporting capability before the first rotation, and treat an unreportable consumer as a migration item with a date. The escape hatch — an explicit, expiring, attributed exception — is a decision with an approver, never a flag (ADR-13).
Tenant churn leaves standing authority to issue A one-time CNAME delegation is the reason renewal is frictionless and also the reason the platform can issue for a customer's domain long after the relationship ends. Re-prove control on a declared cadence, check delegation health continuously, and retire on a schedule when a domain is repointed — with the contractual position stated rather than assumed (ADR-07).
Revocation is soft-fail in the clients that matter Most browsers do not hard-fail on an unreachable revocation check, so the propagation target can be met while the revocation has no practical effect. Declare a fail posture per relying-party class and treat an undeclared class as a defect. For workload identity, lean on lifetime rather than revocation, which is why the leaf is 24 hours (ADR-08, ADR-17).

Architecture Decision Record

Why every component and every technology on these 21 views is what it is, and what each choice costs.

Twenty decisions make up this architecture. Everything else across the twenty-one views is convention, sizing or consequence. Each record states the forcing question, the context that makes it hard, what was decided, how it is realised on AWS, the options weighed, what the choice buys and costs, the conditions that would flip it, why it should still be right in ten years, and the lesson that transfers beyond this platform.

Status of this document. This is a design, not a report on a running system. The rates, latencies, volumes, retentions and thresholds are the requirement's stated assumptions for a mid-size B2B SaaS — 9,000 tenants, 24,000 customer custom domains, 3,800 internal workloads across six clusters in three regions — invented to be defensible and arguable rather than absent. They are to be replaced by measured telemetry before build, and four of them in particular are the first numbers real data should overturn: the 24-hour private leaf lifetime that sets both the issuance volume and the control-plane survival time, the 15-minute probe cadence that sets the expiry detection delay, the 18-hour bulk re-issuance target inside a 24-hour CA deadline, and the ≥ 99.5% managed-coverage figure, which is the one number that depends entirely on how much of the estate the prober can actually reach.

How to read a record

QuestionThe forcing question: why a decision was needed at all.
ContextThe requirement, the scale and the constraint that make it hard.
DecisionWhat this architecture does, stated so it can be checked.
How it is realised on AWSThe concrete mechanism: which service or package, configured how, in which project.
Options weighedChosen, rejected, deferred, or right elsewhere, with the reason for each.
ConsequencesWhat the choice buys and what it costs, both kept visible.
Choose differently whenThe conditions that would flip the decision for your system.
Why it holds up over timeWhat keeps the decision right as scale, staff and technology change.
LessonThe principle that transfers beyond this platform.

Decision map

Truth and verification 4

Which of two disagreeing sources the platform believes, and what follows from choosing the harder one.

ADR-01The endpoint is the system of record, not the issuance log ADR-02ISSUED and SERVING are distinct lifecycle states reached by different mechanisms ADR-03The verification plane does not share a failure domain with the issuance plane ADR-04Discovery is an input to the core state machine, not an audit feature

Trust domains and hierarchy 3

Two populations of certificate that share an inventory and nothing else, and the authorities beneath them.

ADR-05One control plane spans both trust domains; the issuance mechanics stay separate ADR-06A three-tier hierarchy with an offline root and two live issuing intermediates ADR-07Customer domain control is proved once by CNAME delegation, and re-proved on a cadence

Lifetime, renewal and expiry 5

The failure this service exists to abolish, and the four decisions that actually abolish it.

ADR-08Workload leaves live 24 hours, and lifetime is the revocation mechanism for private trust ADR-09Renewal triggers at a fraction of lifetime remaining, never at a fixed number of days ADR-10A failed renewal is an open incident from the first failed attempt ADR-11The reload trigger is part of the renewal transaction, not a downstream courtesy ADR-12Fail static: an outage of this platform never invalidates what is already serving

Trust distribution and rotation 2

Moving an authority through an estate without breaking the half that has not heard yet.

ADR-13Trust distribution is gated ahead of issuance, and an unreportable relying party blocks the rotation ADR-14Issuing intermediates drain rather than cut over

Revocation and compromise 3

What happens when the deadline is set by someone else.

ADR-15Re-issue precedes revoke, except for a key known to be compromised ADR-16Bulk re-issuance capacity is designed to an external deadline and rehearsed twice a year ADR-17Revocation publication is independent of issuance and held to a higher availability tier

Custody, identity and authorisation 3

Where keys live, who may ask for a certificate, and what a refusal has to leave behind.

ADR-18Private keys are generated in the consuming workload; the platform accepts only CSRs ADR-19Signing keys live in non-exportable hardware; the root is offline and moved only by witnessed ceremony ADR-20Authorisation is policy over attested identity, and every denial is recorded

Technology by capability

Every capability and what it is realised with, the origin of that choice, the alternative that was weighed, and the record that argues it. The requirement stays vendor-neutral throughout; this table is where the architecture commits to Amazon Web Services.

Open source This design
CapabilityChoiceOriginCredible alternativeWhy this oneRecord
Certificate registry DynamoDB global table, partitioned by managed identity AWS Aurora PostgreSQL The dominant access pattern is a point read or a small range scan per identity at high rate from three regions, with a rebuildable dataset of ~70,000 live rows — a replicated key-value store fits it better than a relational engine that would need cross-region replication built around it. ADR-01
Issuance ledger S3 with Object Lock in compliance mode AWS QLDB or an append-only table The requirement is that no operator can edit or delete a record for ten years. Object Lock enforces that at the storage layer rather than through an access policy somebody can later widen. ADR-01
Private certificate authority AWS Private CA, two issuing authorities AWS step-ca or Vault PKI on EKS Managed authority lifecycle, native CRL and OCSP publication, and IAM-scoped issuance remove the operational surface that a self-run CA adds. The per-authority monthly charge is the reason authorities are consolidated rather than issued per team. ADR-06
Root key custody CloudHSM, module offline between ceremonies AWS On-premises HSM appliance FIPS 140-2 Level 3, non-exportable keys, quorum-controlled. An on-premises appliance is equally defensible and adds a facility and a supply chain the rest of the estate does not have. ADR-19
Public certificate issuance ACME client against two public CA accounts Open source + external ACM-managed public certificates only ACM issues and renews well for AWS-terminated endpoints, and does not give the platform a second, independent CA relationship — which is the whole mitigation for a CA outage or distrust event. ADR-16
Public certificate binding ACM import, bound to CloudFront and ALB AWS Certificate files on the load balancer host The edge terminates on managed services, so the certificate has to reach them through their own API; import keeps one delivery adapter rather than one per listener type. ADR-11
Domain validation Route 53 delegated zone answering DNS-01 AWS Running an authoritative DNS server for the challenge zone The challenge zone is small, highly available and write-heavy in short bursts. A managed authoritative service removes an availability dependency the platform would otherwise own on the customer onboarding path. ADR-07
Workload attestation IRSA projected service-account tokens; IMDSv2 for EC2 AWS + Kubernetes A bootstrap secret per workload A platform-attested credential the workload cannot forge is the only basis on which an identity can be issued without a human in the loop. A bootstrap secret is a long-lived credential protecting a short-lived one. ADR-20
Workload certificate delivery cert-manager and mesh SDS Open source A bespoke node agent SDS delivers to the proxy without the certificate ever touching disk, and cert-manager is what the clusters already run. A bespoke agent would be a third thing to operate for no gain. ADR-11
Control plane runtime EKS across three AZ AWS ECS Fargate, or Lambda throughout The order manager holds long-running work with queue semantics and steady load; the estate already operates EKS. Probing and validation, which are bursty and stateless, go to Lambda instead. ADR-03
Verification plane Regional Lambda probers on independent schedules AWS A probing service inside the control plane Independence from the control plane's failure domain is the requirement; per-region Lambda with its own EventBridge schedule is the cheapest way to get it and scales with endpoint count rather than with certificate count. ADR-03
Lifecycle event spine EventBridge AWS SNS plus SQS fan-out Consumers — the mesh, the CMDB, deployment pipelines, alerting — subscribe to lifecycle events with content-based filtering rather than polling, and new consumers do not require a change here. ADR-02
Issuance queue SQS with per-endpoint ordering and a redrive policy AWS Kafka Bulk re-issuance and fleet-restart bursts need back-pressure and prioritised draining, not a durable ordered log. The prioritisation — renewals near escalation ahead of new issuance — is a consumer-side concern either way. ADR-16
Policy evaluation OPA bundles, built from the policy repository Open source IAM policy alone The question "may this identity obtain this subject under this profile" is richer than IAM expresses, and it has to be evaluated identically in CI and at issuance time. ADR-20
Revocation publication CRL and OCSP through CloudFront AWS Publication from the issuance plane's own endpoints Relying parties the platform does not control depend on this path, so it is held to a higher availability tier than issuance and must survive an issuance outage entirely. ADR-17
Certificate Transparency monitoring CT log polling per managed domain Open source + external A commercial CT monitoring product The signal needed is narrow — any certificate for a managed domain from a CA the platform did not use — and it feeds the same registry as everything else rather than a separate console. ADR-04
Discovery scanning Scheduled network and public DNS enumeration Open source AWS Config plus service inventories Config knows about AWS-managed certificates. The certificates that cause outages are the ones nothing knows about, which only a scan of the actual TLS surface finds. ADR-04

The decisions, and the alternatives that lost

Truth and verificationWhich of two disagreeing sources the platform believes, and what follows from choosing the harder one.

ADR-01

The endpoint is the system of record, not the issuance log

Accepted

When the issuance log and the live endpoint disagree about which certificate is in use, which one is the platform's truth?

Context
The natural design stores what the platform did: order placed, certificate issued, secret written, task complete. It is cheap, immediate, complete, and wrong in a way that only surfaces as an outage. Between the issuer and the socket there is a process that has to load the new certificate, and that process is outside the platform's control — a web server that was never signalled, a container that caches on startup, a load balancer whose listener still references the old ARN, an operator who copied a file. Every one of those is ordinary, none of them errors, and each leaves the issuance log green while the endpoint counts down. The public postmortems are consistent on this point: the certificate almost always existed somewhere before it expired somewhere else.
Decision
The certificate registry is a projection of what endpoints are observed serving, reconciled against what the platform issued. An independent verification plane opens a TLS connection to every known endpoint on a fifteen-minute cadence and records the serial, chain and not_after it actually received. That observation is authoritative: the expiry clock is raised from it, the renewal scheduler reads due work from it, and lifecycle state changes on it.
How it is realised on AWS
Regional Lambda probers sweep endpoints listed in DynamoDB and write to an observed index with its own TTL; a divergence detector compares observed serial against registry state on every sweep and emits an EventBridge event when they differ. The registry's `state` column is writable by the prober's role and by nothing else on the SERVING transition.
Options weighed
  • ChosenObservation is authoritative; the registry is a projection: Closes the gap the outage lives in. Costs a probing plane, and makes unreachable endpoints an explicit architectural gap rather than an invisible one.
  • RejectedThe issuance log is authoritative; probing is a monitor beside it: This is what most tooling does. The monitor raises a warning that competes with every other warning, and the state machine keeps saying the renewal succeeded — so the escalation ladder never fires.
  • RejectedTrust the delivery adapter's acknowledgement: An adapter can confirm it wrote the file. It cannot confirm the process read it, which is precisely the step that fails.
Consequences
What it buys
  • A renewal that did not take effect stays due, so the failure is caught by the mechanism already built to catch failures rather than by a separate alert nobody owns.
  • Certificates the platform never issued enter the same state machine as the ones it did, because the prober does not care who issued what it sees.
  • The headline metric — certificates expiring while serving — becomes measurable rather than merely asserted.
What it costs
  • A whole verification plane exists that a belief-based design does not need, with its own deployment, network reach and cost.
  • Endpoints the prober cannot reach degrade to belief, and the platform has to say so out loud rather than quietly averaging them into a coverage figure.
Choose differently when
If every TLS terminator in the estate could be made to report its own live certificate attestably — a mesh where the control plane already knows each proxy's loaded secret version — observation could move from an external probe to an inbound attestation, which is cheaper and has better reach. The rule would not change; only who produces the observation.
Why it holds up over time
The rule names no technology. It survives replacing DynamoDB, AWS, ACME and X.509 itself, because it is a statement about which of two sources to believe. It is also the property a future team would most easily discard, by adding a fast path that marks a renewal complete on issuance to reduce probe cost — which is why SERVING is a state only the prober's role can write.
LessonWhen a system's job is to keep something true in the world, the record of its own actions is not evidence that the world changed. Somebody has to go and look.
Shown on views02 09 11 13 19
ADR-02

ISSUED and SERVING are distinct lifecycle states reached by different mechanisms

Accepted

Should the lifecycle model collapse "the platform has a certificate" and "the endpoint is using it" into one state?

Context
Most certificate tooling has a status field with values like pending, active and expired. Active means issued. The model has no vocabulary for the most common real condition — a valid certificate exists, and something is still presenting the previous one — so that condition is unrepresentable and therefore unreportable. A state machine that cannot express a failure cannot escalate it.
Decision
The lifecycle model carries REQUESTED, ISSUED, INSTALLED, SERVING, SUPERSEDED, REVOKED and EXPIRED as distinct states. ISSUED is written by the issuance plane; INSTALLED by a delivery adapter's acknowledgement; SERVING only by an observation. A certificate never reaches SERVING without a probe, and the difference between ISSUED and SERVING is queryable, reportable and alarmable.
How it is realised on AWS
State transitions are recorded as events on the EventBridge lifecycle bus and projected into the registry. The SERVING transition is written by the prober's IAM role; the issuance plane's role has no permission to write it, so the distinction is enforced by access control rather than by discipline.
Options weighed
  • ChosenSeven explicit states, SERVING written only by observation: Makes the failure representable, which is the precondition for escalating it. Costs a richer state machine and more transitions to reason about.
  • RejectedThree states — pending, active, expired: Simple, conventional, and unable to describe the condition that causes the outage.
  • RejectedOne state plus a "verified" boolean: A flag beside a state is a state nobody joins on. Reports are written against the state; the flag drifts into decoration.
Consequences
What it buys
  • "How many certificates are issued but not serving" is a single query, and it is a standing platform metric rather than an investigation.
  • SUPERSEDED, distinct from EXPIRED, makes it visible when an old certificate is still being presented after a successful renewal.
  • The escalation ladder can be driven by state plus remaining validity, with no special-casing.
What it costs
  • More states to document, test and explain to every consuming team.
  • Endpoints that cannot be probed sit permanently at INSTALLED, which is honest but looks like an unresolved backlog — and is one.
Choose differently when
If probe coverage were to fall well below the estate — say a platform dominated by managed services that expose no probeable surface — the distinction would produce more noise than signal, and INSTALLED would have to become the terminal healthy state for those classes, with the weakness declared per class rather than hidden.
Why it holds up over time
The state names are protocol-agnostic and survive any change of issuance mechanism. The valuable part is the separation of who may write which transition, which is an access-control shape rather than a schema, and stays correct as components are replaced.
LessonA status model is a theory of what can go wrong. If the worst realistic failure has no name in it, the system will not report that failure — not because of a bug, but because it has nowhere to put it.
Shown on views11 13
ADR-03

The verification plane does not share a failure domain with the issuance plane

Accepted

Can observation run inside the same control plane that performs issuance?

Context
Co-locating them is obviously cheaper: one deployment, one set of credentials, one on-call. It also means that the outage most likely to cause a certificate problem — the control plane being unavailable — is the same outage that removes the platform's ability to notice one. The period during which the estate is most at risk becomes exactly the period during which the platform is blind, and the blindness is silent, because a prober that is not running produces no findings rather than an alarm.
Decision
Probers are deployed per region, in their own compute, with their own schedule and their own egress path, outside the primary control plane's failure domain. Probe liveness is itself monitored: an absence of observations is treated as a failure signal, not as an absence of problems.
How it is realised on AWS
Lambda-based probers in eu-west-1, eu-central-1 and us-east-1, each triggered by its own EventBridge schedule, writing to a DynamoDB global table. Each region's sweep completeness is a published metric; a region that stops reporting alarms within one cadence.
Options weighed
  • ChosenIndependent per-region probers with liveness monitoring: Observation survives a control-plane outage. Costs three deployments and cross-region data movement.
  • RejectedProbing as a job inside the control plane: Cheapest, and blind exactly when it matters. A silent absence of findings is indistinguishable from good news.
  • RejectedA third-party external monitoring service: Genuinely independent and good at public endpoints, but it cannot reach internal mTLS listeners, which is the larger population. Worth keeping as a corroborating signal on public hostnames.
Consequences
What it buys
  • The expiry clock keeps running during a control-plane outage, so the incident does not also consume the platform's visibility.
  • Regional probers naturally observe regional differences — a certificate rolled out unevenly is visible as disagreement between regions.
  • Probe liveness becomes a first-class signal, which closes the "no findings" ambiguity.
What it costs
  • Three deployments to operate and keep in step, and a real possibility of version skew between them.
  • Cross-region writes to the observed index, with the latency and cost that implies.
Choose differently when
In a single-region estate with a genuinely independent control-plane availability story, one prober deployment with strong liveness monitoring would be defensible. The independence, not the multiplicity, is what matters.
Why it holds up over time
"Do not let the watcher share the failure domain of the watched" is older than any of this technology and applies to every monitoring decision the platform will make later. The specific realisation will change; the constraint will not.
LessonAn absence of alerts means nothing unless you separately know the thing producing alerts is alive.
Shown on views07 16
ADR-04

Discovery is an input to the core state machine, not an audit feature

Accepted

Where do certificates the platform never issued belong — in the registry, or in a separate compliance report?

Context
Every estate has them: a certificate uploaded by hand during an incident three years ago, a vendor appliance with its own self-signed chain, a marketing microsite somebody stood up on a subdomain. They are not managed, so a platform organised around its own issuance has no row for them. They are also, disproportionately, the ones that expire — precisely because nothing is renewing them. Treating them as a compliance finding puts them in a report with a quarterly cadence, while the outage they cause has a date.
Decision
Network and DNS scanning and Certificate Transparency monitoring write into the same registry as issuance. A discovered certificate the platform did not issue becomes a first-class registry entry in an UNMANAGED state with a required remediation path, an owner and a deadline. The count of unmanaged certificates is a standing platform metric, not an audit artefact.
How it is realised on AWS
A discovery scanner enumerates the estate's network surfaces and public DNS; a CT monitor watches every managed domain. Findings are reconciled against the registry and published as an unmanaged-coverage metric alongside expiry. CT alerting fires on any certificate issued for a managed domain by a CA the platform did not use.
Options weighed
  • ChosenDiscovery writes into the registry as UNMANAGED: One inventory, one clock, one escalation ladder. Costs a permanently visible backlog nobody enjoys looking at.
  • RejectedDiscovery produces a separate compliance report: Moves the riskiest population out of the mechanism designed to protect it, on a slower cadence than the risk.
  • RejectedDo not discover; manage only what the platform issued: Defines the problem away. The estate does not agree, and the postmortem will be about a certificate nobody had a row for.
Consequences
What it buys
  • The riskiest certificates are tracked by the same expiry clock as the safest ones.
  • CT monitoring gives a real detection path for mis-issuance against a customer's domain by a CA the platform never used.
  • Coverage becomes an honest number: managed as a fraction of discovered, not of registered.
What it costs
  • A standing backlog that will be uncomfortable for a long time, and a metric that looks worse the better the discovery gets.
  • Scanning an estate produces false positives and touches surfaces other teams own, which needs a social agreement as much as a technical one.
Choose differently when
In an estate where every TLS surface is provably provisioned through one paved road with no exceptions, discovery would be redundant. No estate of this size has ever been that estate, but a greenfield one might be for its first two years.
Why it holds up over time
The principle — the inventory is of what exists, not of what you created — outlives any scanning technology. As CT coverage broadens and service meshes report their own inventories, the discovery mechanism gets cheaper while the decision stays the same.
LessonA system that only tracks what it created will be most confident about exactly the population that is least likely to hurt it.
Shown on views09 10 18

Trust domains and hierarchyTwo populations of certificate that share an inventory and nothing else, and the authorities beneath them.

ADR-05

One control plane spans both trust domains; the issuance mechanics stay separate

Accepted

Are public-trust certificates for customer domains and private-trust workload identities one system or two?

Context
They share almost nothing operationally. Public trust means ACME, an external CA with rate limits, domain control validation, Certificate Transparency, 90-day lifetimes and deadlines set by a standards body. Private trust means an authority the platform owns, attestation instead of validation, 24-hour lifetimes and no external clock at all. The failure modes, the latency budgets and the people who care are all different. Two systems would keep those differences clean. But both populations expire, both need an owner, both need an escalation ladder, and an organisation that runs two certificate inventories has, in practice, two incomplete ones.
Decision
One control plane, one registry, one escalation ladder and one verification plane span both trust domains. The issuance planes beneath them are separate: different protocols, different authorities, different validation, different lifetimes, and no shared code path for signing. What is shared is inventory, escalation and truth.
How it is realised on AWS
A single certificate registry keyed on issuer-and-serial with a `trust_domain` attribute on the managed identity; two distinct issuance paths — an ACME client with two CA accounts, and AWS Private CA behind attestation — both emitting to the same EventBridge lifecycle bus.
Options weighed
  • ChosenShared inventory and escalation, separate issuance planes: One answer to "what is closest to expiry". Costs a control plane that must abstract two genuinely different things without pretending they are the same.
  • RejectedTwo independent services: Cleaner blast radius, and nobody can answer the estate-wide question without joining two systems by hand — which is the state most organisations are already in.
  • RejectedOne system all the way down, with a common issuance abstraction: The abstraction leaks immediately: rate limits, CT, attestation and lifetime have no common shape, and forcing one produces a lowest-common-denominator API that serves neither path well.
Consequences
What it buys
  • One expiry dashboard covers the estate, which is the question the platform exists to answer.
  • The escalation ladder, ownership model and evidence trail are built once and behave identically for both populations.
  • The verification plane is trust-domain agnostic by construction: a TLS handshake does not care who signed.
What it costs
  • A public-path incident shares a control plane with workload issuance, so blast radius is wider than two services would give.
  • The control plane carries branching that two separate services would not need, and that branching is where the subtle bugs will live.
Choose differently when
If the public-trust population were to become a genuinely separate product — a customer-facing certificate service with its own SLA and its own team — the shared control plane would become a coordination cost rather than a saving, and splitting with a federated registry would be right.
Why it holds up over time
The dividing line chosen here — share the inventory, separate the mechanics — is the one that survives new trust domains. A future third population (device certificates, a post-quantum hierarchy running in parallel) joins the registry and brings its own issuance plane, without renegotiating the architecture.
LessonWhen deciding whether two things are one system, ask what question the organisation needs answered across both. Share whatever answers it, and nothing else.
Shown on views01 08 14
ADR-06

A three-tier hierarchy with an offline root and two live issuing intermediates

Accepted

How many tiers should the private hierarchy have, and how many issuing authorities should be live at once?

Context
A two-tier hierarchy — root signing leaves directly — means the root key is online and in constant use, so a compromise is unrecoverable without replacing the trust anchor in every relying party. A single issuing intermediate is the common compromise, and it produces a single point of failure with a long tail: replacing it means distributing a new authority to the entire estate under time pressure, which is the operation most likely to go wrong. Meanwhile the root itself has an expiry date, typically years out, which is exactly long enough for everyone who understood it to have moved on.
Decision
Three tiers: an offline root used only in a witnessed ceremony, two independent issuing intermediates live at all times, and short-lived leaves beneath them. Either intermediate can carry all issuance, so retiring one is a planned operation rather than an emergency. CA certificates are tracked in the same registry, on the same expiry clock, as leaves, and rotated at half of remaining life.
How it is realised on AWS
Root key in CloudHSM, module offline between ceremonies, quorum-controlled. Two AWS Private CA issuing authorities, both present in every distributed trust bundle from the day they are created. `ca_authority` rows carry `not_after` and appear on the expiry dashboard alongside leaves.
Options weighed
  • ChosenOffline root, two live issuing intermediates: Replacement is a 4-hour operation because the replacement is already trusted. Costs a second managed authority's standing charge.
  • RejectedOffline root, one issuing intermediate: Cheaper, and makes intermediate replacement an estate-wide emergency involving trust distribution under pressure — the worst possible time to discover which relying parties cannot report their bundle version.
  • RejectedTwo-tier: root signs leaves: Simplest, and puts the trust anchor's key online in the hot path. A compromise then requires replacing the anchor everywhere, which is the outcome the hierarchy exists to avoid.
Consequences
What it buys
  • Losing an issuing intermediate costs a planned switch, not a distribution emergency.
  • Rotation can be rehearsed against the real estate because a second authority is genuinely live rather than theoretical.
  • Root expiry — the multi-year failure nobody is on shift for — appears on the same dashboard as tomorrow's leaf.
What it costs
  • Two managed authorities cost roughly twice one, and that charge is per month regardless of use.
  • Chain construction and trust bundle composition are more complex, and every relying party must trust both.
Choose differently when
If issuance volume and blast radius were small enough that an intermediate replacement could genuinely be done in an hour by hand, one intermediate would be defensible. At 3,800 workloads across three regions, it is not.
Why it holds up over time
Hierarchy depth and the two-live-authorities pattern are independent of vendor and of algorithm. When a post-quantum or hybrid algorithm arrives, the same structure carries the migration: a third intermediate goes live under the new algorithm, is distributed, and issuance shifts — which is the rotation this design already rehearses.
LessonThe spare is only a spare if it is already trusted. A standby that has to be introduced during the incident is not a standby, it is a second incident.
Shown on views06 16 20
ADR-07

Customer domain control is proved once by CNAME delegation, and re-proved on a cadence

Accepted

How does a tenant prove they own a domain, and how often should they have to prove it again?

Context
The platform issues publicly trusted certificates for domains it does not own, on behalf of customers, tens of thousands of times. Validation is the only thing standing between that capability and mis-issuance. Per-renewal validation is the safest model and the most fragile: at 24,000 domains on 90-day certificates, it means asking customers to act roughly 400 times a day, and every one of those is a support ticket waiting to happen. One-time delegation is frictionless forever and grants the platform standing authority over a customer's namespace indefinitely, including after the customer has left.
Decision
DNS-01 with CNAME delegation is the primary path: the tenant creates one permanent `_acme-challenge` CNAME into a platform-controlled zone, and the platform answers every subsequent challenge itself. HTTP-01 is offered as a fallback with its trade-off stated — it requires traffic to already be arriving, so it cannot complete before cutover. Control is re-proved on a declared cadence rather than trusted indefinitely, delegation health is checked continuously, and a domain that is repointed or has its delegation removed stops renewing and retires on a schedule.
How it is realised on AWS
A delegated Route 53 zone holds the challenge records; the DNS-01 responder publishes TXT records there during an order. A delegation checker resolves the customer's `_acme-challenge` CNAME on a schedule and raises an early failure long before a renewal is due. Domain rows carry `proven_at` and `reprove_due`.
Options weighed
  • ChosenOne-time CNAME delegation, plus continuous health checks and periodic re-proof: Frictionless renewal with the standing-authority risk managed rather than ignored. Costs a delegated zone and a contractual conversation about what the delegation grants.
  • RejectedValidate on every renewal: Safest in principle. In practice it converts a silent, working system into 400 customer actions a day, and the failure mode is a customer outage caused by the vendor's own safety mechanism.
  • RejectedHTTP-01 only: No standing DNS authority, which is genuinely attractive — but it cannot issue before traffic arrives, so every cutover has a window with no certificate.
Consequences
What it buys
  • The tenant acts once, and renewal for the life of the domain needs nobody.
  • Delegation removal is detected by a health check rather than by a failed renewal months later.
  • The platform can issue for a new subdomain of an already-delegated domain without asking again, which matters for product features that mint hostnames.
What it costs
  • The platform holds standing authority to issue for a customer's domain, which is a real trust concession that belongs in the contract and in the security review, not in a footnote.
  • A churned tenant who never removes the CNAME leaves that authority in place, so retirement has to be driven from the platform side.
Choose differently when
If a regulator or a large customer required per-issuance proof of control, the design supports it — the validation orchestrator is already per-order — at the cost of the frictionless property. The decision would then be per-tenant rather than global.
Why it holds up over time
ACME and DNS-01 are stable and widely implemented, and the delegation pattern is now the industry norm for multi-tenant custom domains. If validation requirements tighten — shorter validation reuse windows are already being discussed — the continuous health check is what makes tightening a configuration change rather than a redesign.
LessonA safety mechanism that requires a human to act repeatedly will be routed around. Design for the one-time act, then monitor continuously for the thing you traded away.
Shown on views04 12

Lifetime, renewal and expiryThe failure this service exists to abolish, and the four decisions that actually abolish it.

ADR-08

Workload leaves live 24 hours, and lifetime is the revocation mechanism for private trust

Accepted

For workload identity, is revocation infrastructure load-bearing, or is a short lifetime the control?

Context
Revocation is weak where it matters most. CRLs grow and go stale; OCSP is soft-fail in most clients, which means an attacker who can block the check has defeated it. Building revocation infrastructure that relying parties genuinely hard-fail on is possible inside a controlled estate and expensive. The alternative is to make certificates expire faster than a compromise can be exploited, which converts a distributed consistency problem into a scheduling one — at the cost of multiplying issuance volume and shortening how long the estate survives without the control plane.
Decision
Private workload leaves live 24 hours and renew at 8 hours remaining. Expiry is the primary containment mechanism for a compromised workload key; CRL and OCSP exist for the private hierarchy but are the exception path, not the design. The estate's survival time without the control plane is therefore 8 hours, and that number is published rather than discovered.
How it is realised on AWS
A 24-hour issuance profile in AWS Private CA, with cert-manager and mesh SDS renewing at one third of life. The resulting steady state is roughly 46,000 issuances a day, ~32 per minute, with a fleet-restart burst of about 20 per second.
Options weighed
  • Chosen24-hour leaves; lifetime as the control: Compromise window bounded by construction, and the renewal machinery runs continuously so it is known to work. Costs signing throughput and a short control-plane outage budget.
  • Rejected90-day leaves with hard-fail OCSP inside the estate: Far less signing load, and it makes revocation correctness load-bearing across every relying party — including the ones that will silently soft-fail and nobody will notice until an incident.
  • RejectedOne-hour leaves: A tighter compromise window and roughly 24× the issuance volume, with control-plane survival falling to about 20 minutes. The signing budget and the outage tolerance both become the binding constraint.
Consequences
What it buys
  • A stolen workload key is worthless within a day without any revocation reaching anybody.
  • The renewal path is exercised tens of thousands of times a day, so it is never the untested code path during an incident.
  • Rotation of an issuing intermediate drains in 24 hours, because that is the longest-lived leaf beneath it.
What it costs
  • Signing throughput becomes the binding scalability constraint, and it is not elastic.
  • The control plane's tolerable outage is 8 hours, which is a real operational commitment.
  • A fleet-wide rollout is 37× steady state in ten minutes, which has to be absorbed without starving unrelated issuance.
Choose differently when
If measured AWS Private CA throughput or cost cannot carry the volume, lengthening the leaf is the dial — and it lengthens the compromise window and the control-plane survival budget in the same move. Those are one decision, not three, and the record should be updated as one.
Why it holds up over time
The industry is moving decisively toward shorter certificates and automated issuance; nothing here fights that current. If maximum lifetimes fall further, this design needs no change, because it already treats renewal as continuous rather than exceptional.
LessonDistributed revocation is a consistency problem with no good answer at the edge. Where you control the lifetime, spend it instead — and then be honest that you have bought availability risk with it.
Shown on views14 15
ADR-09

Renewal triggers at a fraction of lifetime remaining, never at a fixed number of days

Accepted

Should the renewal threshold be expressed in days, or as a proportion of the certificate's lifetime?

Context
"Renew 30 days before expiry" is the conventional rule and it was written when certificates lived for two or three years. Maximum public certificate lifetimes have fallen from 39 months to 90 days within a decade and are still falling; proposals for 47-day and shorter maximums are already in flight. A fixed 30-day threshold against a 90-day certificate renews at one third of life, which is sensible. Against a 47-day certificate it renews at two thirds. Against anything shorter it becomes "renew immediately, always", and the policy silently stops meaning what it said.
Decision
Renewal triggers at one third of lifetime remaining, expressed as a fraction, for every certificate in the estate regardless of trust domain. On a 90-day public certificate that is 30 days; on a 24-hour workload leaf it is 8 hours. The escalation ladder is likewise expressed against remaining validity rather than absolute dates.
How it is realised on AWS
The renewal policy in the versioned repository carries a fraction, not a duration. The scheduler computes the due time per certificate from its own validity window, and spreads renewals with jitter so that certificates issued in one batch do not come due in one hour.
Options weighed
  • ChosenA fraction of lifetime remaining: Survives every future shortening of certificate lifetimes with no change. Costs a slightly less intuitive policy to explain.
  • RejectedA fixed number of days: Intuitive, conventional, and quietly wrong the next time the industry halves certificate lifetimes — with no error to signal that it has stopped working.
  • RejectedPer-class thresholds, tuned individually: Maximum flexibility and a configuration surface that will drift, with each class becoming a separate thing to remember when lifetimes change.
Consequences
What it buys
  • One policy covers 24-hour leaves and 90-day public certificates with no special cases.
  • The retry window is always two thirds of the certificate's life, which is a meaningful budget at every scale.
  • The next industry-wide lifetime reduction requires no change to this platform.
What it costs
  • "One third remaining" is harder to explain to a service owner than "30 days before", and will be asked about repeatedly.
  • Very short lifetimes make the renewal window small in absolute terms, which puts pressure on retry and on issuance availability.
Choose differently when
If a particular class of certificate had a hard external constraint expressed in days — a partner integration requiring a fixed rotation date, for instance — that class would need an absolute override, declared and justified rather than inherited.
Why it holds up over time
This is the single cheapest decision in the record and the one most likely to still be paying off in ten years, precisely because certificate lifetimes will keep falling and nothing here has to change when they do.
LessonExpress a threshold in the same units as the thing it constrains. A constant that happens to be correct at today's scale is a bug with a delay on it.
Shown on views05 19
ADR-10

A failed renewal is an open incident from the first failed attempt

Accepted

When does a failing renewal become somebody's problem — at the first failure, or when expiry is imminent?

Context
A renewal job that fails and retries is, in most systems, a log line. It becomes an alert when a threshold is crossed, and the threshold is usually close to expiry, because alerting earlier is assumed to be noisy. The result is a long silent period during which the system knows it is failing and nobody who could fix it does. The 3 a.m. page at T-0 and the quiet ticket at T-30 are the same information, discovered at two very different costs — and the platform has the information from the first attempt.
Decision
A failed renewal opens an incident at the first failed attempt, with severity driven by remaining validity rather than by attempt count: notify the owner at 30 days, alarm at 21, page at 14, escalate to the platform on-call at 7. Retries continue with jittered backoff across the whole remaining window, so a transient CA outage costs retries rather than an outage. Any managed certificate reaching 7 days remaining is a page-worthy defect regardless of whether anything has broken.
How it is realised on AWS
Every attempt writes an outcome to the attempt ledger; the escalation ladder is an EventBridge rule set evaluating remaining validity against the registry, with owner lookup from the managed identity. An owner is mandatory for a certificate to be managed at all, so there is always somebody to notify.
Options weighed
  • ChosenIncident from the first failure, severity from remaining validity: Discovery moves to T-30. Costs early, low-severity noise that has to be kept genuinely actionable or it will be ignored.
  • RejectedAlert when expiry is imminent: Quiet, conventional, and it discards a month of warning the system already had.
  • RejectedAlert after N consecutive failures: Attempt count is the wrong unit: five failures on a 24-hour leaf is an emergency, and five on a 90-day certificate is a Tuesday.
Consequences
What it buys
  • Nearly every renewal failure is fixed in working hours by the person who owns it.
  • The escalation path is identical for both trust domains because it is expressed in remaining validity.
  • A systemic failure — a CA outage, a broken adapter — shows up as many simultaneous low-severity notifications, which is a recognisable signature.
What it costs
  • Low-severity notifications arrive for problems that would often have resolved themselves on the next retry, and that class has to stay small or it trains people to ignore it.
  • Every managed certificate needs a real owner, which is an organisational cost before it is a technical one.
Choose differently when
If the first-failure notification proves to be dominated by self-resolving transients, the right adjustment is a short confirmation window — two consecutive failures, or one hour — not a move back to alerting near expiry. The unit stays remaining validity.
Why it holds up over time
Severity as a function of time-to-consequence rather than of failure count is a general alerting principle. It transfers directly to certificate rotation, token expiry, licence renewal and every other deadline the platform will acquire.
LessonIf the system knows something is broken, the only question left is how long you are going to let it keep that to itself.
Shown on views05 18
ADR-11

The reload trigger is part of the renewal transaction, not a downstream courtesy

Accepted

Is a renewal complete when the new certificate has been delivered, or when the consuming process is serving it?

Context
Delivery and use are separated by a step nobody owns. A file lands on a volume, a secret is updated, a listener's certificate is replaced — and the process that terminates TLS carries on with what it loaded at startup. Some servers watch for changes; many do not. Some reload on SIGHUP; some need a restart. The platform's delivery adapter can honestly report success while the endpoint is unchanged, and this is the single most common way a correct renewal produces an outage.
Decision
Triggering reload of every consumer is part of the renewal transaction. The platform detects and reports consumers holding a certificate older than the registry's current one, and a targeted probe follows the reload rather than waiting for the next scheduled sweep. Delivery without a reload path is not a supported integration.
How it is realised on AWS
Mesh SDS pushes to the proxy without touching disk, which makes reload implicit. The node agent signals the process it serves. Edge and ACM binding is an API call that replaces the listener's certificate directly. Any integration that cannot offer one of these is refused rather than accommodated with a manual step.
Options weighed
  • ChosenReload inside the renewal transaction, with a targeted probe: Closes the gap at the point it opens. Costs a supported-integration list and the refusal of ad-hoc delivery.
  • RejectedDeliver and let consumers pick it up: The path of least resistance, and it puts the most failure-prone step outside the platform's responsibility while leaving the platform accountable for the outcome.
  • RejectedDeliver, and rely on the next scheduled probe to catch failures: Better than nothing — the truth rule would eventually catch it — but it converts a deterministic step into a detection latency for no benefit.
Consequences
What it buys
  • The most common renewal failure is eliminated at the source rather than detected afterwards.
  • The list of supported integrations becomes an architectural statement instead of a support policy.
  • Targeted probing after reload gives a ≤ 10 minute p95 verification, far faster than the sweep cadence.
What it costs
  • Teams with bespoke TLS termination must adopt a supported adapter, which is migration work the platform is imposing.
  • Every new adapter carries a reload obligation, which makes adding one more expensive.
Choose differently when
If every consumer in the estate ran a proxy with hot-reload semantics — a fully meshed environment with no direct termination — the reload trigger would be redundant and delivery alone would suffice. The probe would still be needed for certificates the mesh does not carry.
Why it holds up over time
As service meshes and managed load balancers displace process-local TLS termination, this decision gets cheaper to honour rather than harder. The refusal to support ad-hoc delivery is what keeps that trend from being undermined by one exception.
LessonIf a step outside your system has to happen for your work to have any effect, either own that step or measure it. Assuming it is the way most of these outages start.
Shown on views13
ADR-12

Fail static: an outage of this platform never invalidates what is already serving

Accepted

What happens to the estate when the certificate service itself is unavailable?

Context
A platform that sits on the trust path has two tempting postures and one correct one. Fail closed — refusing traffic when the platform cannot confirm a certificate is valid — is the instinct borrowed from authorisation systems, and here it would take down the entire estate to prevent a theoretical staleness. Fail open in the sense of relaxing validation is worse. The correct posture is neither: the platform's unavailability should stop change and change nothing that is already running.
Decision
Fail static. No failure of the certificate service can revoke, shorten or invalidate a certificate already serving traffic. Issuance queues rather than errors. The estate coasts on remaining validity, and the coasting time — 8 hours, set by the 24-hour leaf renewed at one third of life — is published as a first-class operational metric.
How it is realised on AWS
Certificates live in the consuming workload and at the edge, not in a store the platform must be available to serve. The revocation publication path is independent of issuance, so a revocation can still be seen while issuance is down. Survival time is computed from the shortest live certificate lifetime and published on the expiry dashboard.
Options weighed
  • ChosenFail static, with survival time published: The estate survives a platform outage. Costs an explicit, defensible commitment to an outage budget measured in hours.
  • RejectedFail closed: Turns a control-plane outage into an estate-wide outage. The certificate service becomes the least available thing in the critical path, which inverts its purpose.
  • RejectedPre-issue longer-lived fallback certificates: Extends survival, and does it by widening exactly the compromise window ADR-08 spent signing throughput to narrow. Reconsider only if measured availability proves 8 hours insufficient.
Consequences
What it buys
  • A platform incident is a change freeze, not an outage.
  • The outage budget is a known number that operations can plan against and that appears in the SLO conversation honestly.
  • Revocation remains possible during an issuance outage, because the two paths do not share a dependency.
What it costs
  • Eight hours is a real commitment: an outage longer than that begins expiring workload leaves, and the recovery is then a mass re-issuance.
  • Publishing the survival number invites the question of whether it is long enough, which is uncomfortable and correct.
Choose differently when
If the control plane's measured availability made an 8-hour outage plausible rather than remote, the answer is a regionally independent issuance capability — which widens the key exposure surface — rather than longer certificates. That trade is stated in the requirement as a genuinely open question.
Why it holds up over time
Fail-static is the correct posture for any platform that provisions credentials rather than authorising requests, and the distinction will keep mattering as more of the estate moves to short-lived credentials of other kinds.
LessonAsk what your system's outage should cost. If the answer is "everything that depends on it stops", you have built a dependency, not a platform.
Shown on views16 18

Trust distribution and rotationMoving an authority through an estate without breaking the half that has not heard yet.

ADR-13

Trust distribution is gated ahead of issuance, and an unreportable relying party blocks the rotation

Accepted

How does the platform know it is safe to start issuing from a new authority?

Context
The classic PKI outage is not expiry, it is ordering: a new intermediate or root goes live, leaves are issued beneath it, and some fraction of relying parties has not received the new trust bundle. The failure is immediate, total for the affected population, and hard to diagnose from the issuing side because everything on that side worked. The usual control is a runbook step — distribute first, then switch — and runbook steps get abbreviated under exactly the time pressure that forces a rotation.
Decision
A new authority is added to every trust bundle and confirmed distributed before any certificate is issued from it, enforced mechanically by a rotation gate rather than by procedure. Relying parties report the bundle version they hold; the gate blocks issuance below full coverage. A consumer that cannot report its bundle version blocks the rotation by name and is an architectural gap with an owner, not an inconvenience to be waived.
How it is realised on AWS
Signed versioned bundles are published to the trust plane's distribution path; each relying party reports its held version, and the coverage table drives a rotation-readiness query. The issuance plane refuses to sign under an authority whose bundle coverage is below 100%, and a canary identity is issued and probed before any real leaf.
Options weighed
  • ChosenMechanical gate on reported coverage, unreportable parties block: Makes the ordering unskippable. Costs a reporting obligation on every consumer, and a rotation that a single legacy consumer can stall.
  • RejectedDistribute first, then switch, by runbook: Works until the rotation that matters, which is always the urgent one.
  • RejectedCross-sign the new authority from the old one: A legitimate technique that preserves validation for clients with a stale bundle, at the cost of a more complex chain and a weaker claim about what is trusted. Worth holding as the escape hatch for a rotation that cannot wait for coverage.
Consequences
What it buys
  • The ordering failure becomes impossible rather than unlikely.
  • Bundle coverage is a continuously known number, so "is it safe to rotate" is a query rather than an argument.
  • Consumers that cannot report are surfaced early, in daylight, rather than during a rotation.
What it costs
  • One legacy consumer with no reporting path can stall a rotation that has a deadline behind it.
  • Every relying party acquires a reporting obligation, which is integration work across the estate.
Choose differently when
Under a genuine emergency rotation with a deadline shorter than the remaining migration, cross-signing is the escape hatch — taken as an explicit, attributed, expiring exception with an approver, never as a flag somebody sets.
Why it holds up over time
The gate is about ordering, not about X.509. The same shape applies to any credential-issuing system where verifiers must learn a new key before issuers start using it, which includes every signing-key rotation the platform will ever do.
LessonIf correctness depends on doing two things in the right order, make the second one impossible until the first is confirmed. A runbook is a wish with formatting.
Shown on views06 17
ADR-14

Issuing intermediates drain rather than cut over

Accepted

When retiring an issuing intermediate, do you re-issue everything beneath it or let it empty naturally?

Context
Three techniques exist. Forced re-issuance is fastest and is the emergency path, but it is also a mass event that puts the whole estate through issuance at once for a planned change. Cross-signing preserves validation for clients with stale bundles and complicates the chain. Natural drain — stop issuing from the old authority, keep it trusted, retire it when its last leaf expires — is the safest and its duration is bounded by the longest leaf lifetime beneath it, which this architecture has already made short.
Decision
Planned intermediate retirement drains: the outgoing authority stays trusted and stops issuing, and retires when its longest-lived leaf expires naturally. Because private leaves live 24 hours, that drain is a day rather than a quarter. Forced re-issuance is reserved for compromise, where the speed is worth the disruption.
How it is realised on AWS
Both intermediates are always in the distributed bundle, so stopping issuance from one is a policy change rather than a distribution event. The overlap window is computed from the longest live leaf under the outgoing authority and published on the rotation dashboard.
Options weighed
  • ChosenNatural drain, bounded by leaf lifetime: Safest, and short precisely because ADR-08 made leaves short. Costs an overlap window during which two authorities are live.
  • RejectedForced re-issuance of every leaf: Fast, and it makes a routine retirement into an estate-wide event with a mass-issuance burst. Kept as the compromise path.
  • RejectedCross-sign the new authority from the old: Right where relying parties pin or cannot be updated. Here the bundle coverage gate already guarantees they can be.
Consequences
What it buys
  • Rotation is a boring, rehearsable operation rather than a scheduled outage risk.
  • The drain duration is a computed, published number rather than an estimate.
  • Short leaf lifetimes pay for themselves a second time here, which is a real argument for ADR-08 beyond compromise containment.
What it costs
  • Two authorities are live throughout the overlap, which is a wider signing surface than one.
  • Public-trust certificates at 90 days make the equivalent drain three months, so the two trust domains rotate on very different timescales.
Choose differently when
If the estate ever acquires a relying party that pins an intermediate — a mobile client, an embedded device — drain stops being sufficient and cross-signing becomes necessary. That is a reason to know where pinning exists before it is discovered during a rotation.
Why it holds up over time
Drain-over-cutover is the general pattern for retiring any signing key, and it gets easier as credential lifetimes shorten across the industry.
LessonThe cost of retiring something is set by the lifetime of what it produced. Shortening that lifetime buys you cheap change later, not just cheap recovery.
Shown on views17

Revocation and compromiseWhat happens when the deadline is set by someone else.

ADR-15

Re-issue precedes revoke, except for a key known to be compromised

Accepted

In a bulk revocation event, does the platform revoke first and then replace, or replace first and then revoke?

Context
A CA mandate to revoke within 24 hours is a deadline, not an instruction about ordering. Revoking first is the literal reading and, for a population of live customer-facing certificates, it is a decision to break every affected endpoint for however long re-issuance takes. Replacing first means running slightly past the moment the platform could have revoked, in exchange for continuity. The two orderings are correct in different circumstances, and the difference is whether the key is believed to be in an attacker's hands.
Decision
For a mandated revocation, a CA distrust event or an intermediate retirement, the platform re-issues and verifies serving before revoking. For a key known or strongly suspected to be compromised, the order inverts: revoke immediately and accept the outage. The inversion is an explicit decision with an approver, recorded with its reason, never an improvisation at 2 a.m.
How it is realised on AWS
The bulk path drives a rate-limit-aware order queue across both CA accounts, with the probe sweep confirming the new serial is serving before the revocation record is written and published. A compromise trigger sets a flag on the operation that reverses the ordering and requires two-person approval to proceed either way.
Options weighed
  • ChosenRe-issue then revoke, inverted on known compromise: Continuity by default, decisiveness when it is warranted. Costs a slightly longer window during which the old certificate is still valid.
  • RejectedAlways revoke first: The literal reading of a mandate, and it converts a compliance event into a self-inflicted customer outage across tens of thousands of domains.
  • RejectedAlways re-issue first: Safe for availability and wrong for a live compromise, where every minute the old certificate remains valid is the attacker's.
Consequences
What it buys
  • A CA mandate is absorbed without customer impact, which is the difference between a difficult week and a public incident.
  • The compromise path is pre-decided, so nobody is weighing continuity against containment under pressure.
  • Both orderings are rehearsed, so the inversion is not the untested branch.
What it costs
  • The old certificate stays valid for the duration of re-issuance, which is a real if bounded exposure and has to be defensible to an auditor.
  • Two-person approval on the bulk path adds latency to an operation with a deadline.
Choose differently when
If a CA mandate ever came with an ordering requirement rather than only a deadline, the default would have to invert, and the platform's job would become minimising the outage rather than avoiding it — which makes the 18-hour bulk capacity even more load-bearing.
Why it holds up over time
The reasoning — availability by default, containment when the threat is live, with the switch decided in advance — transfers to every credential revocation the platform will ever perform.
LessonDecide the order of your emergency steps before the emergency. The wrong order is rarely obvious at the time, and it is always obvious afterwards.
Shown on views15
ADR-16

Bulk re-issuance capacity is designed to an external deadline and rehearsed twice a year

Accepted

How fast must the platform be able to replace its entire public-trust population, and how is that claim kept true?

Context
The CA/Browser Forum's revocation deadlines are measured in hours and days, and they apply whether the platform is ready or not. Recent industry events have forced large operators to replace their entire certificate estate on a 24-hour or five-day clock, and the organisations that struggled were not the ones without a plan — they were the ones whose plan had never been run. Capacity here is not a property that emerges; it is a number that must be designed to and then defended against drift.
Decision
Bulk re-issuance of the full public-trust population completes in ≤ 18 hours, sized to finish inside a 24-hour mandate with margin. Two public CA accounts are live and pre-validated so that all new issuance can shift to the second within one hour. The bulk path is rehearsed at least twice a year against a representative subset, and an unrehearsed bulk path is treated as untested.
How it is realised on AWS
A rate-limit-aware bulk order queue tracks each CA's per-registered-domain and per-account limits and queues rather than failing as a limit is approached. Rehearsals run against a fixed representative subset and publish a measured duration that is extrapolated honestly rather than asserted.
Options weighed
  • ChosenDesigned capacity, two live CA accounts, twice-yearly rehearsal: The deadline becomes a number the platform can meet and prove. Costs a second CA relationship and two rehearsals a year.
  • RejectedOne CA account, bulk path built if needed: Cheaper, and it makes the next CA incident an existential one — the plan is written during the deadline it is supposed to meet.
  • RejectedThree or more CA accounts: More headroom, more relationships to keep validated, and diminishing returns once the second account can carry the whole population.
Consequences
What it buys
  • A CA distrust event becomes an operational day rather than a crisis.
  • Rate-limit behaviour is known from rehearsal instead of discovered under load.
  • The measured duration keeps the claim honest as the domain population grows — a rehearsal that slows down is an early warning.
What it costs
  • Two CA relationships to maintain, validate and keep warm.
  • Rehearsals consume real issuance quota and real engineering time twice a year for an event that may never come.
Choose differently when
If the 18-hour target proves unachievable against real rate limits, the architecture must know before a CA sets the clock — and the answer is more pre-validated accounts or a smaller blast radius per account, not a revised target with no mechanism behind it.
Why it holds up over time
External deadlines have only ever tightened. Designing to a measured, rehearsed capacity rather than to an assumption is the property that survives whatever the next requirement turns out to be.
LessonA capability nobody has exercised is a claim, not a capability. Rehearsal is the only thing that converts one into the other.
Shown on views15 18
ADR-17

Revocation publication is independent of issuance and held to a higher availability tier

Accepted

Should revocation be published by the same components that issue, and to what availability target?

Context
Revocation is consumed by relying parties the platform does not control, on a path the platform cannot observe, in clients that mostly soft-fail. That combination means two things: the publication path must be more available than anything else in the design, because a check that cannot complete is a check that passes; and it must not share a dependency with issuance, because the single most likely reason to need an urgent revocation is a problem in the issuance plane.
Decision
CRL and OCSP are published on a path independent of issuance, held to ≥ 99.99% monthly — a higher tier than issuance itself. Responses are signed with lifetimes that survive a publication outage. A fail posture is declared per relying-party class, and an undeclared class is treated as a defect: a soft-fail check nobody decided to soft-fail is revocation theatre. Propagation is measured by a daily synthetic canary rather than assumed.
How it is realised on AWS
Publication through CloudFront with globally cached, signed responses, sourced from a path that does not traverse the issuance plane. A daily synthetic issue-install-revoke-recheck canary measures end-to-end propagation and holds the ≤ 5 minute p95 target honest.
Options weighed
  • ChosenIndependent publication at a higher availability tier, with measured propagation: Revocation survives an issuance outage and the propagation claim is evidence rather than assertion. Costs a separately operated path.
  • RejectedPublish from the issuance plane: One fewer thing to run, and it couples revocation to the component most likely to be the reason for revoking.
  • RejectedRely on short lifetimes and publish nothing: Defensible for private workload identity, where ADR-08 already makes this the primary mechanism. Not available for public-trust certificates, where publication is a CA-level obligation.
Consequences
What it buys
  • An issuance outage cannot prevent a revocation from being seen.
  • Propagation time is a measured number with a canary behind it, not a design assumption.
  • Declaring a fail posture per class forces an honest conversation about which revocations actually have effect.
What it costs
  • A separate publication path to operate and to keep more available than the rest of the platform.
  • The honest conversation reveals that for most browser clients the revocation is advisory, which is uncomfortable and true.
Choose differently when
If short-lived certificates ever became universal for public trust as well — which the industry is moving toward — revocation infrastructure would shrink toward the exception path on both sides, and this tier could be relaxed.
Why it holds up over time
The principle that a verification path must be more available than the issuance path it checks applies to every credential system, and it is consistently the part that gets under-provisioned because it is invisible when it works.
LessonA check that fails open is only as good as its availability. If you cannot keep it up, you have not built a control, you have built a formality.
Shown on views08 16 20

Custody, identity and authorisationWhere keys live, who may ask for a certificate, and what a refusal has to leave behind.

ADR-18

Private keys are generated in the consuming workload; the platform accepts only CSRs

Accepted

Who generates the private key, and does it ever cross the network?

Context
Central generation is convenient: the platform makes the key, packages it with the certificate, and delivers both, which simplifies onboarding and makes recovery possible. It also means key material traverses the network, exists in the platform's memory, likely reaches a store, and is therefore present in backups, in logs if anyone is careless, and in the blast radius of any compromise of the platform. For a platform whose administrative surface is the highest-value target in the estate, that is a large concession for an onboarding convenience.
Decision
Every private key is generated inside the consuming workload; the platform accepts only a CSR and returns only a certificate and chain. No private key material exists anywhere in this platform, which is a property of the issuance protocol rather than an access control on a store. CSR contents beyond the public key, and full validation tokens, are never logged.
How it is realised on AWS
cert-manager and mesh SDS generate keys in the workload and present a CSR. The registry schema has no column for key material, so there is nothing to protect rather than something protected. Key possession is therefore never recoverable by the platform, which is the intended property.
Options weighed
  • ChosenWorkload-generated keys, CSR-only issuance: A full compromise of the platform's databases yields no key. Costs the ability to recover a key for a workload that lost one — which is correct, because that certificate should be reissued instead.
  • RejectedCentral generation with distribution: Simpler onboarding, and it puts every key in the platform's blast radius, its backups and its restore path.
  • RejectedCentral generation with immediate destruction after delivery: Better, and it depends on a deletion path being correct everywhere forever, including in a backup taken between generation and destruction.
Consequences
What it buys
  • A backup restore cannot revive a key that should be gone, because no backup ever held one.
  • The compromise story for the platform itself is dramatically narrower: an attacker with the registry has public material and metadata.
  • Key possession is proof of identity in a way the platform cannot undermine even accidentally.
What it costs
  • Every consumer must be able to generate a key and produce a CSR, which excludes some appliances and legacy software.
  • There is no recovery path for a lost key; the answer is always re-issuance, which requires the attestation path to be reliable.
Choose differently when
A class of device genuinely incapable of key generation would need a separate, isolated provisioning path with its own record — and that path would be an exception with a named owner, not a relaxation of this rule.
Why it holds up over time
CSR-only issuance is the direction of travel everywhere, reinforced by hardware-backed key storage becoming ubiquitous. The rule will get easier to hold, not harder.
LessonThe most reliable way to protect a secret is to arrange never to have it. Ask what your system would have to lose in a total compromise, then design that list to be short.
Shown on views10 13 21
ADR-19

Signing keys live in non-exportable hardware; the root is offline and moved only by witnessed ceremony

Accepted

Where do the CA private keys live, and what does it take to use the root?

Context
The root key is the trust anchor for every private certificate in the estate. Its compromise is not recoverable by rotation, because rotation means replacing the anchor in every relying party — the operation this architecture spends a rotation gate and two live intermediates trying to avoid doing under pressure. The root is also used rarely: a handful of times in its life, to sign intermediates. A key that is rarely used and catastrophically valuable should not be reachable from anything that runs continuously.
Decision
Every CA private key is held in FIPS 140-2 Level 3 or equivalent hardware, non-exportable. The root module is physically offline between ceremonies. Two-person control is required for root ceremonies, issuing-intermediate creation, any relaxation of a profile constraint, and any manual issuance outside a profile. Root recovery is a witnessed ceremony from hardware backup with an RTO of 72 hours — the one recovery path with a human in it by design.
How it is realised on AWS
CloudHSM holds signing keys with quorum-controlled access; the root's module is offline between ceremonies, and ceremony records are witnessed, recorded and retained ten years alongside the issuance ledger. Issuing intermediates carry name constraints where the technology permits, bounding what a compromised private intermediate could mint.
Options weighed
  • ChosenHardware custody, offline root, two-person ceremony: The trust anchor is not reachable by any running system. Costs a facility, a rehearsed ceremony, and a 72-hour recovery.
  • RejectedOnline root in an HSM: Operationally simpler and puts the unrecoverable key on a network. The convenience is worth very little given how rarely the root is used.
  • RejectedSoftware-held keys with strict IAM: Cheapest, and it makes key exfiltration a permissions bug away. For a trust anchor, that is not a defensible posture.
Consequences
What it buys
  • No running system can reach the root, so no software compromise reaches the trust anchor.
  • Name constraints bound what a compromised issuing intermediate could do, which is the realistic compromise rather than the theoretical one.
  • Ceremony records give a decade-long, auditable account of every time the anchor was used.
What it costs
  • Ceremonies are expensive, slow and need people with specific roles available, which makes intermediate creation a scheduled event.
  • A 72-hour root recovery is a long time, and it is accepted deliberately rather than engineered away.
Choose differently when
Nothing plausible flips hardware custody. What could change is where it lives: a regulatory requirement for sovereign key custody would move the modules on-premises without altering any of the reasoning.
Why it holds up over time
Offline roots and quorum ceremonies predate all of this technology and will outlast it. When a post-quantum hierarchy is needed, it will be created by exactly this ceremony, which is an argument for keeping the ceremony rehearsed rather than merely documented.
LessonMatch the protection to the recoverability, not to the frequency of use. The things you touch least are often the things you cannot replace.
Shown on views16 20
ADR-20

Authorisation is policy over attested identity, and every denial is recorded

Accepted

On what basis is an issuance request authorised, and what happens to the requests that are refused?

Context
The naive issuance API takes a subject and returns a certificate for it. That makes the requester the authority on its own identity, which means any workload that can reach the API can obtain any identity in the trust domain — and mTLS authorisation downstream is then worthless, because the identity it checks can be minted on demand. Separately, the requests that get refused are the most interesting security signal the platform produces, and they are the ones most commonly discarded.
Decision
Identity is derived from a platform-attested credential the workload cannot forge, never from a self-asserted subject in the CSR. Identity is encoded in a structured SAN — trust domain, namespace, service — so that policy can be written against a parseable identity rather than a string convention. Authorisation is policy: which identities may obtain which subjects under which profile. Every denial is appended to the issuance ledger with the requester, the requested subject and the rule that refused it, and the denial rate is a standing security signal.
How it is realised on AWS
IRSA projected service-account tokens for Kubernetes workloads and IMDSv2 identity documents for EC2 are verified by the attestation verifier; OPA bundles built from the policy repository evaluate the request. A workload in one namespace cannot obtain a certificate for a service in another. Relaxing a constraint requires a second approver and is audited immutably.
Options weighed
  • ChosenAttested identity, structured SAN, policy authorisation, recorded denials: Makes downstream mTLS authorisation meaningful. Costs an attestation dependency on every issuance path and a policy surface to maintain.
  • RejectedAuthenticate the requester, trust the requested subject: Common, simple, and it lets any authenticated workload impersonate any other — which silently voids every authorisation decision made downstream.
  • RejectedEncode identity in the common name by convention: Works until a name contains a separator character or a team invents a new convention. Policy written against a string convention is policy written against a bug.
Consequences
What it buys
  • mTLS authorisation downstream means something, because identities cannot be minted by the workloads that would benefit.
  • The denial log is a genuine detection signal for lateral movement and for misconfiguration alike.
  • Changing the rules is itself two-person and audited, so the control cannot be quietly widened.
What it costs
  • Every issuance path needs a working attestation mechanism, which constrains where workloads can run.
  • The policy surface must be kept current as namespaces and services are created, or it becomes the thing teams route around.
Choose differently when
If the estate adopted a workload identity standard that already carries attestation and authorisation — SPIFFE with a fully trusted node attestor, for example — this policy layer would become a thin adapter over it rather than a component in its own right.
Why it holds up over time
Attested, structured, policy-authorised identity is where the industry has converged and where it is staying. The realisation will change as attestation mechanisms improve; the three properties will not.
LessonIf a caller can tell you who it is, you have authentication theatre. And the requests you refuse are worth more than the ones you grant — if you kept them.
Shown on views14 21

Every package used, in one table

The terms this package uses in a specific way, and what each one is doing in the architecture.

PackageWhat it isWhat it does hereConsidered instead
Managed identity The durable subject a certificate is issued for: trust domain, subject and SANs, owning team, class. The row that persists across every certificate and every compromise. Ownership, policy and compromise history attach here, not to a certificate that will expire and take the record with it. Treating the certificate as the primary object, which loses the history every time one expires.
SERVING The lifecycle state a certificate reaches when an observation records an endpoint presenting it. The architecture's load-bearing state. Only the prober's role can write it, which is what makes the truth rule enforceable rather than aspirational. Treating ISSUED as healthy, which is the defect this whole design exists to prevent.
Observation A record of what a TLS handshake against a known endpoint actually returned: serial, chain, not_after, time. The only evidence of reality in the system. The expiry clock and the renewal schedule are both derived from it. Inferring liveness from a delivery adapter's acknowledgement, which confirms a write and not a load.
Divergence A difference between the certificate the registry considers current and the one an endpoint is observed presenting. A first-class signal with its own alarm, and the earliest detectable symptom of the issued-but-not-reloaded failure. Treating the difference as staleness to be reconciled silently, which hides the failure it represents.
Trust domain Public-trust (browsers and clients the platform has no relationship with) or private-trust (an authority the platform runs and every relying party is its own). The attribute that routes an identity to one issuance plane or the other, while both share the registry and the escalation ladder. Pretending the two are variants of one issuance mechanism, which produces an abstraction that serves neither.
CNAME delegation A permanent `_acme-challenge` CNAME the tenant creates once, pointing into a platform-controlled DNS zone. What makes renewal for a customer domain fully automatic forever after a single tenant action. Per-renewal validation, which is safer and converts a silent system into hundreds of customer actions a day.
Trust bundle A signed, versioned artefact listing the authorities a relying party should trust, distributed on its own lifecycle. The thing that must arrive everywhere before issuance switches to a new authority. Its version is a reportable property of every relying party. Shipping roots alongside leaves, which makes the ordering accidental rather than enforced.
Rotation gate A mechanical block on issuing from an authority until every relying party has reported the bundle version containing it. Converts "distribute trust before you issue" from a runbook step into something that cannot be skipped under pressure. A checklist, which is exactly what gets abbreviated during the incident that forced the rotation.
Fail static The posture where an outage of this platform stops change and changes nothing already running. Distinguishes this platform from a fail-closed control: certificates already serving are never invalidated by the certificate service being unavailable. Fail closed, which would let a control-plane outage take down the estate it exists to protect.
Survival time How long the estate keeps working with the control plane entirely unavailable — the renewal margin on the shortest-lived certificate. Published as an operational metric, currently 8 hours, so the tolerable outage is a known commitment rather than an incident-time discovery. Leaving it implicit, which means it is measured for the first time during the outage.
Unmanaged certificate A certificate discovered serving on the estate that the platform did not issue and has no record of. A first-class registry state with an owner and a deadline, and a standing platform metric — because this population is where expiry outages concentrate. A quarterly compliance finding, on a slower cadence than the risk it describes.
Bulk re-issuance Replacing the entire public-trust population inside an externally imposed deadline, typically 24 hours. A designed, measured, twice-yearly-rehearsed capability with a stated duration, rather than an improvisation under a clock nobody here controls. Assuming it can be done when needed, which is how a CA incident becomes an existential one.
Open svg/<view>.svg or drawio/<view>.drawio in draw.io Desktop or at app.diagrams.net to edit. The SVG carries the diagram inside it, so it is both the picture and the source. This folder is self-contained — copy it whole and every link still resolves.