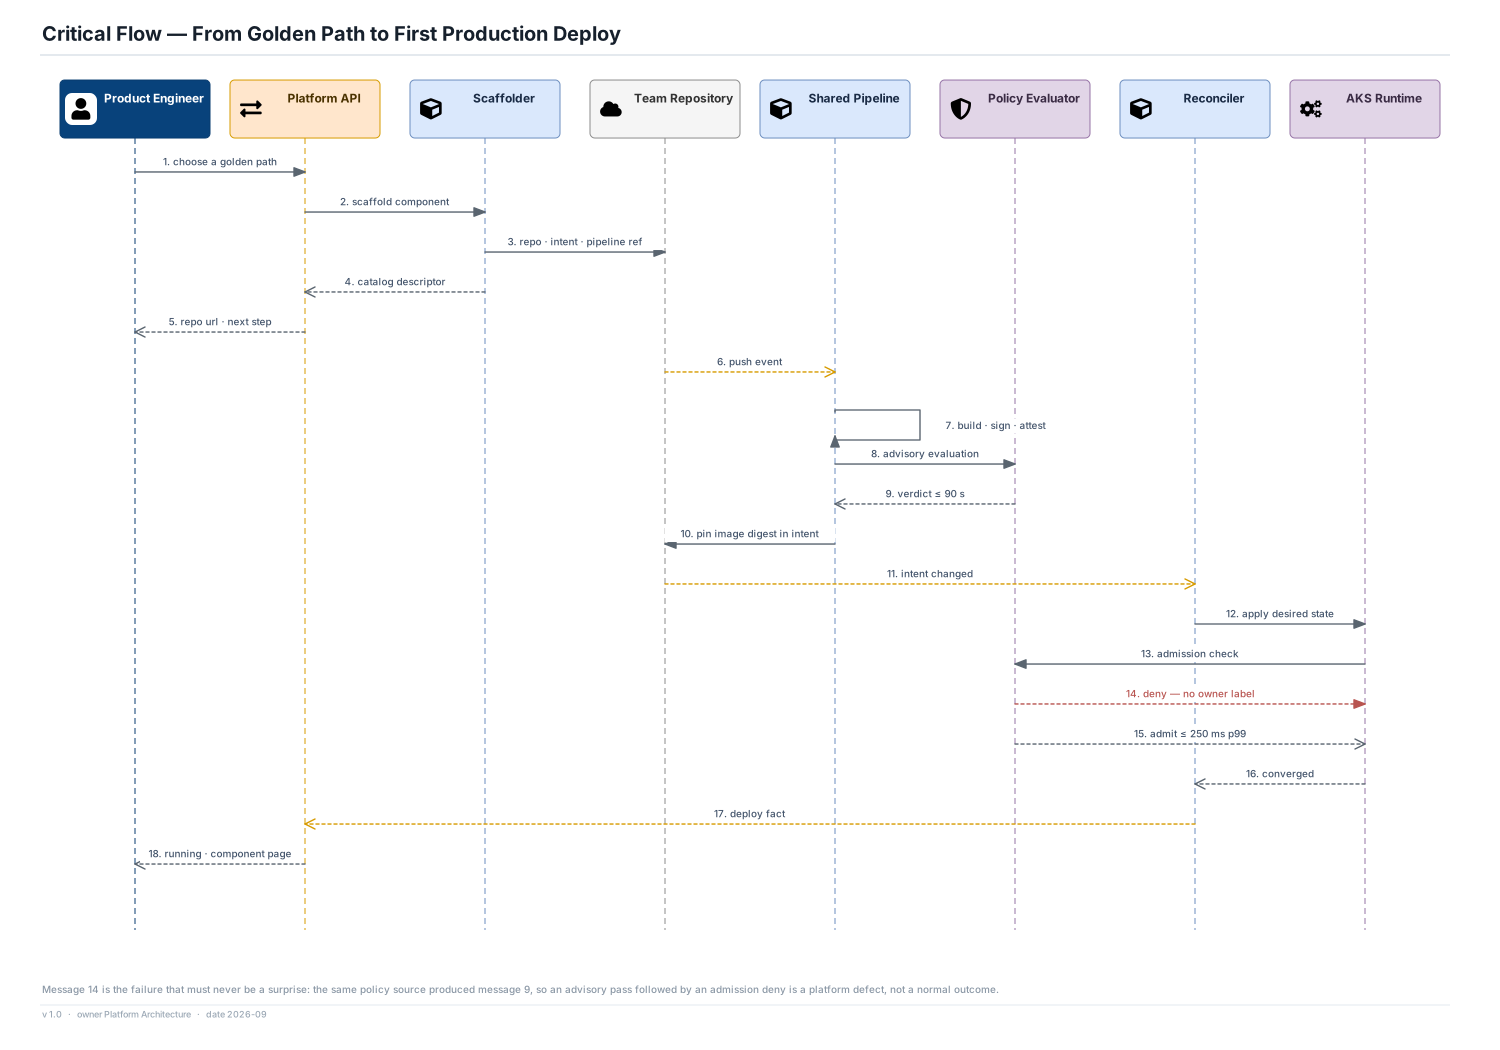
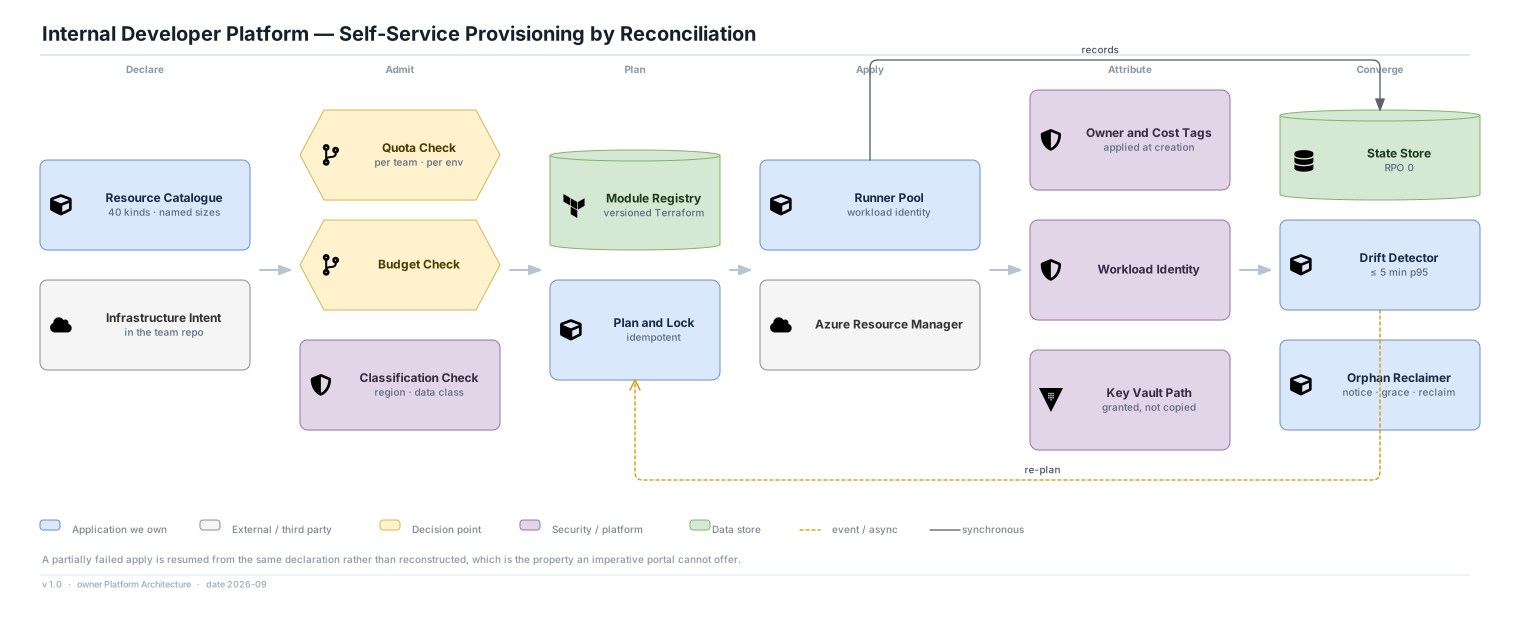
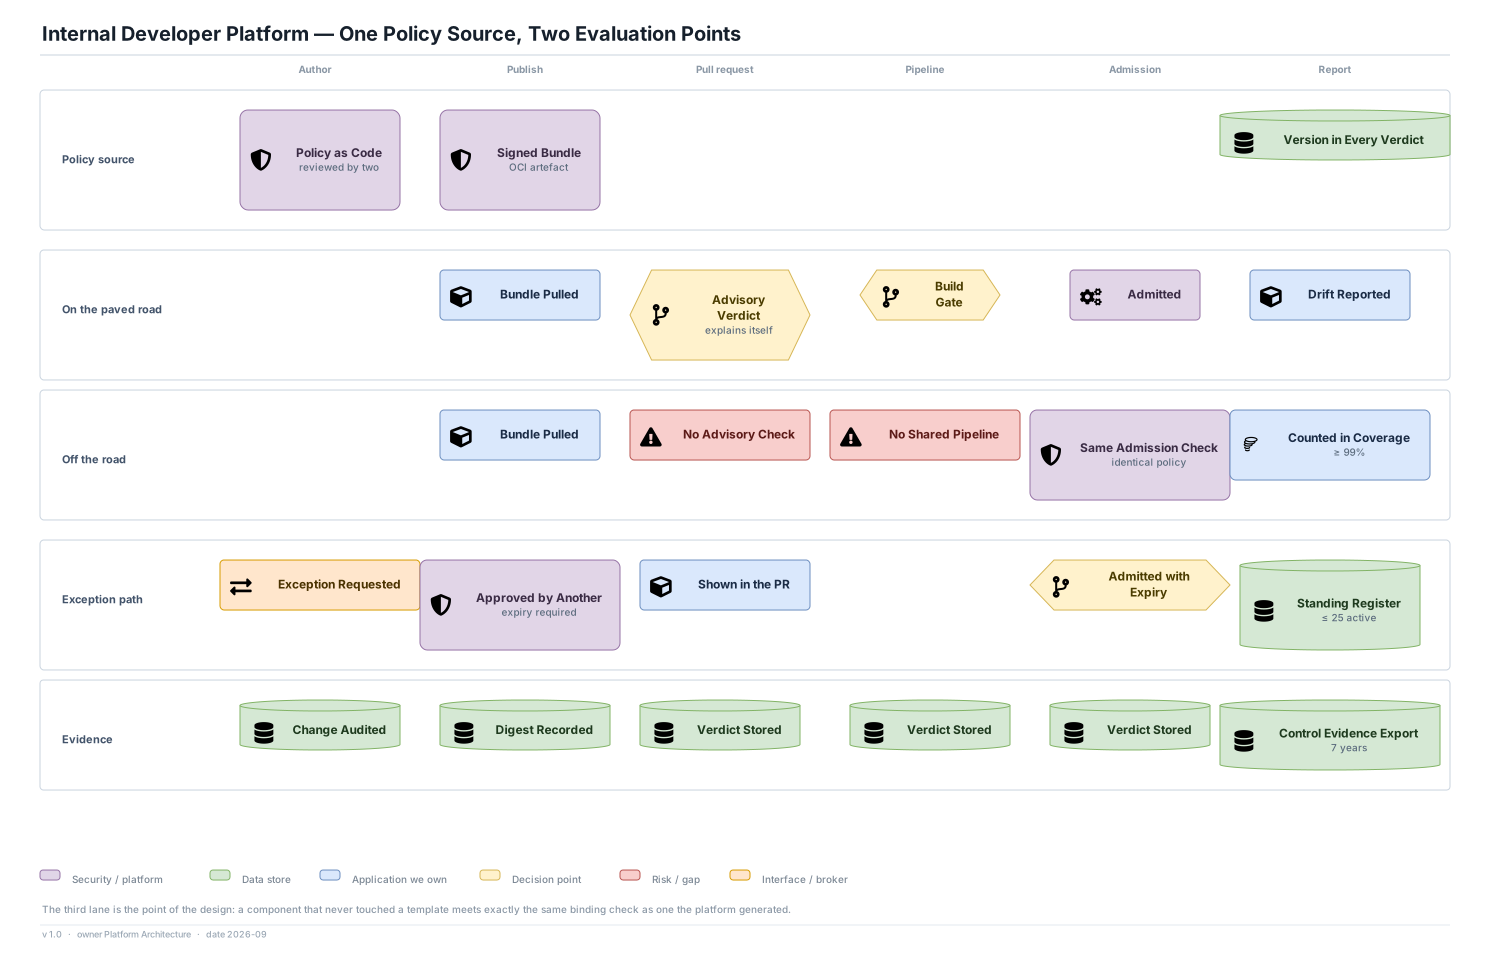
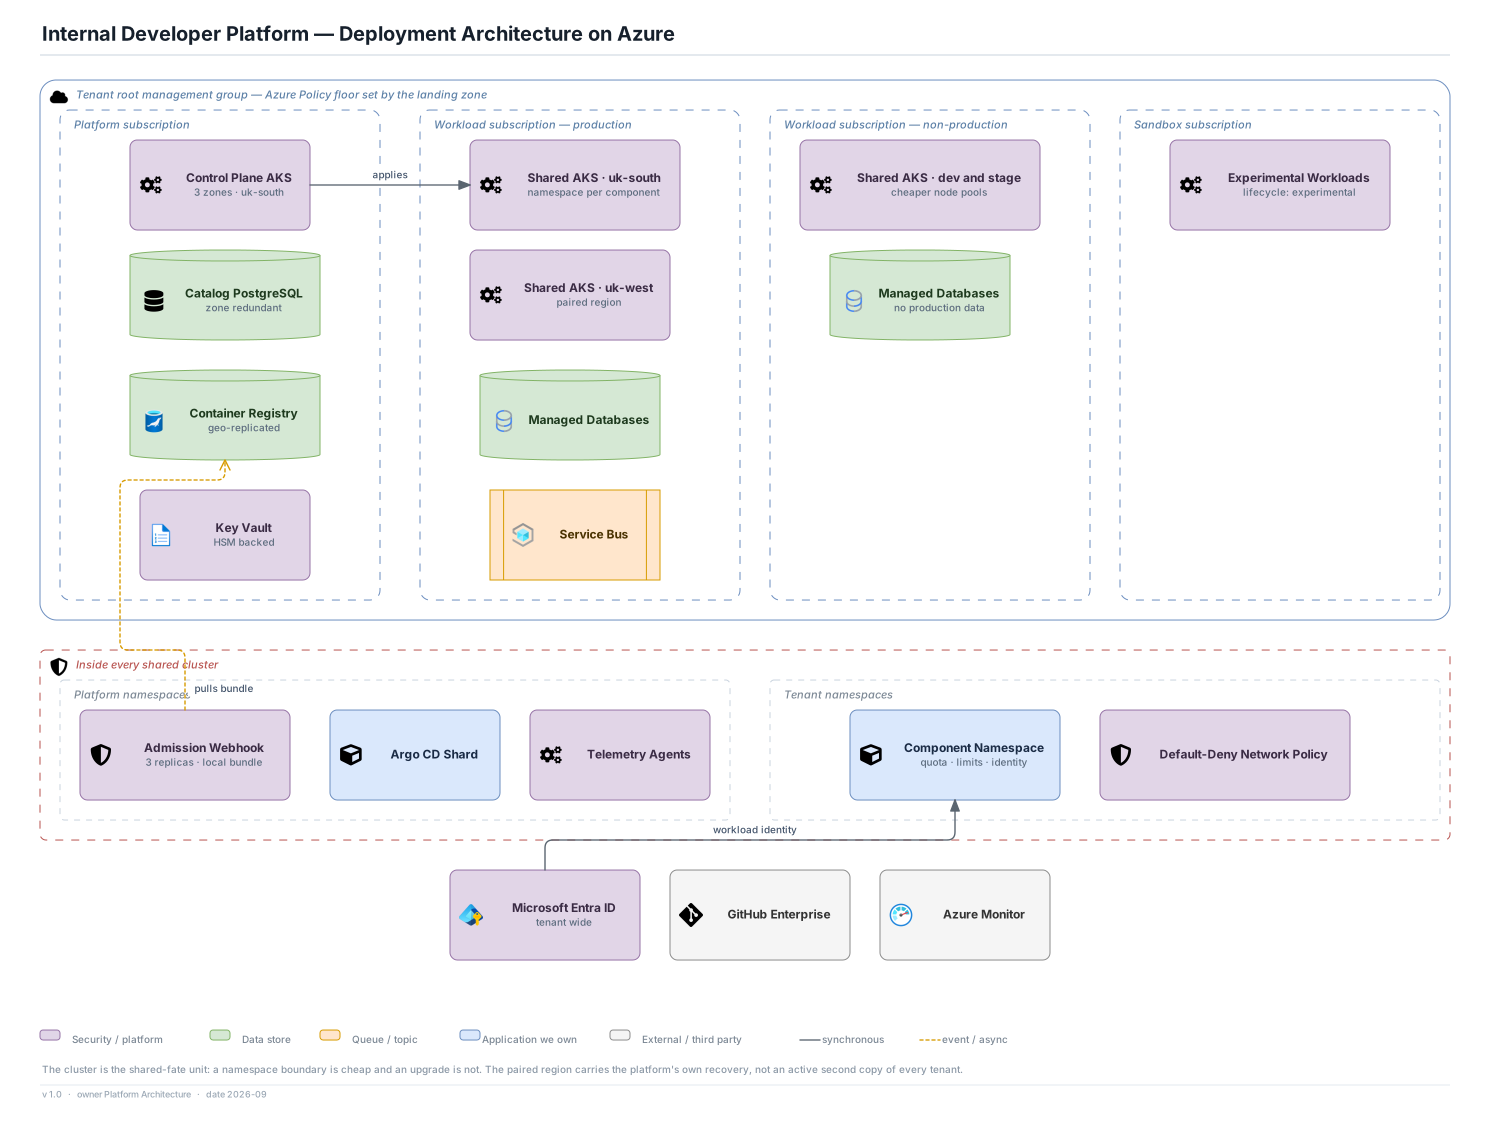
Internal Developer Platform

Architecture Views

21 views, in reading order. Every view ships three ways: an HTML page, an SVG that re-opens in diagrams.net fully editable, and draw.io source.

The platform that takes a product engineer from "we need a new service" to running, observable, compliant production code without a ticket. Read it in seven acts: what sits inside the boundary, who it serves and what they get to do, how it is put together, what it stores, what happens when someone actually uses it, how it is operated, and why it is safe. One rule runs through every view — the paved road is a product a team may decline, and the guardrails are controls it cannot.

Context and scope

What the platform takes responsibility for, who asks it for things, and what belongs to somebody else.

People and journeys

The three engineer-facing personas, and the moments where each journey actually fails.
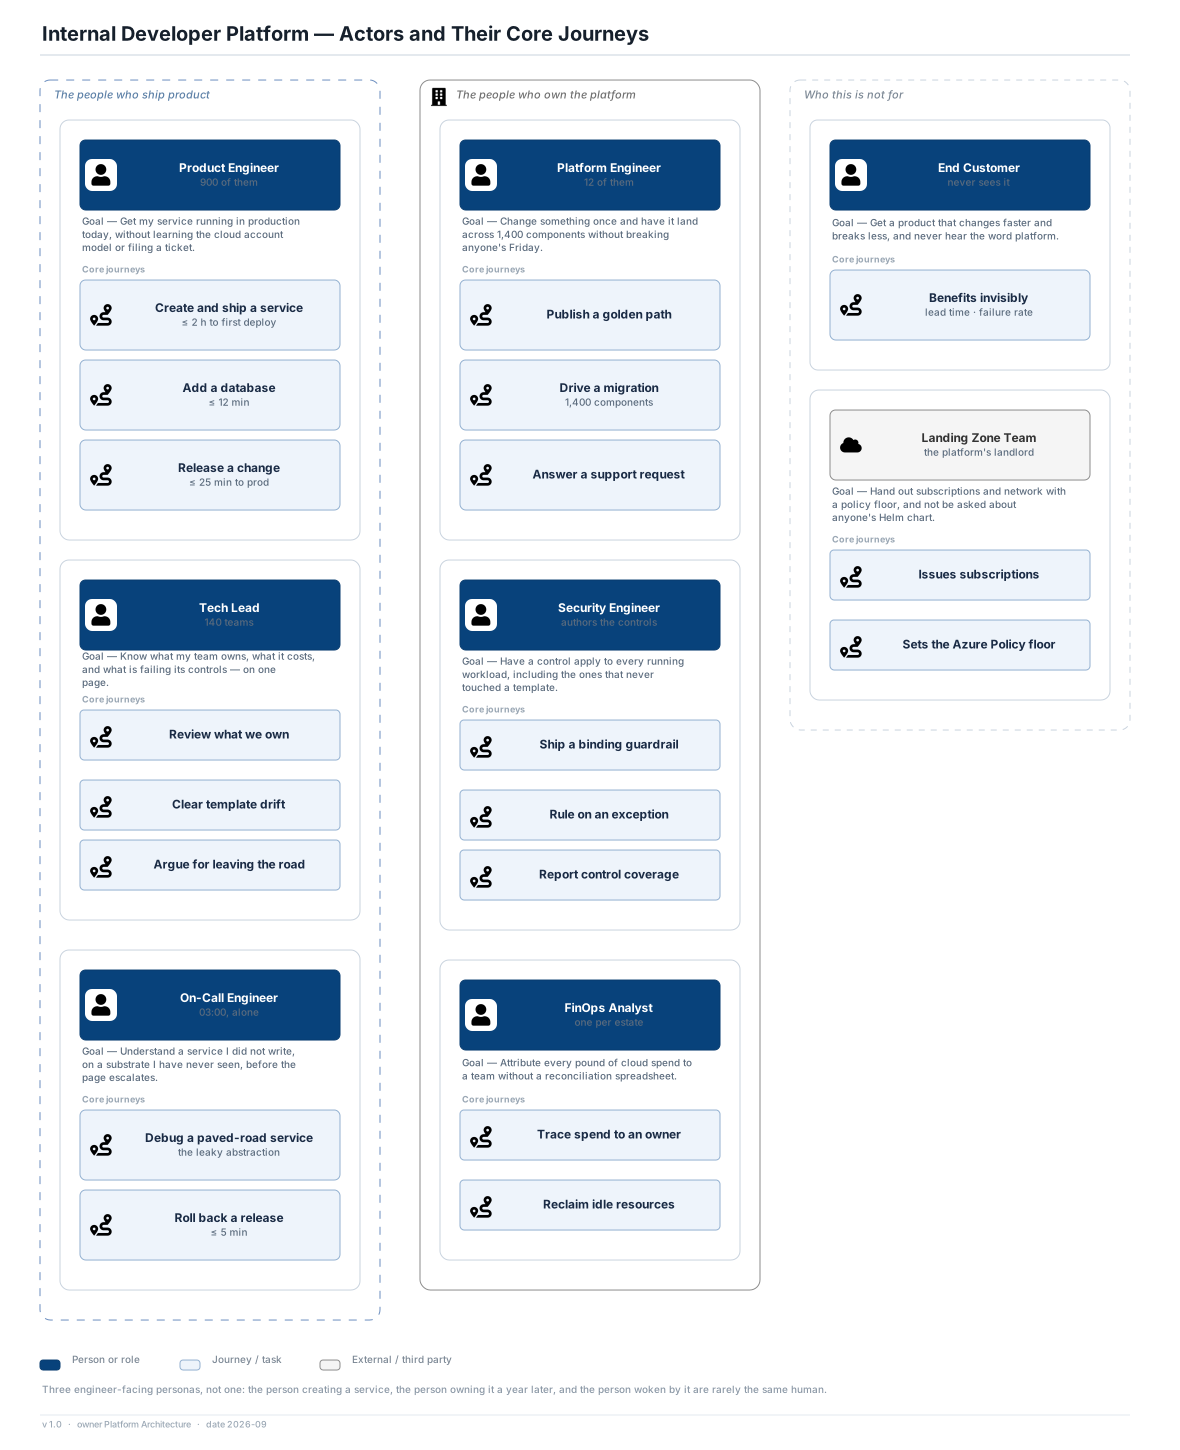
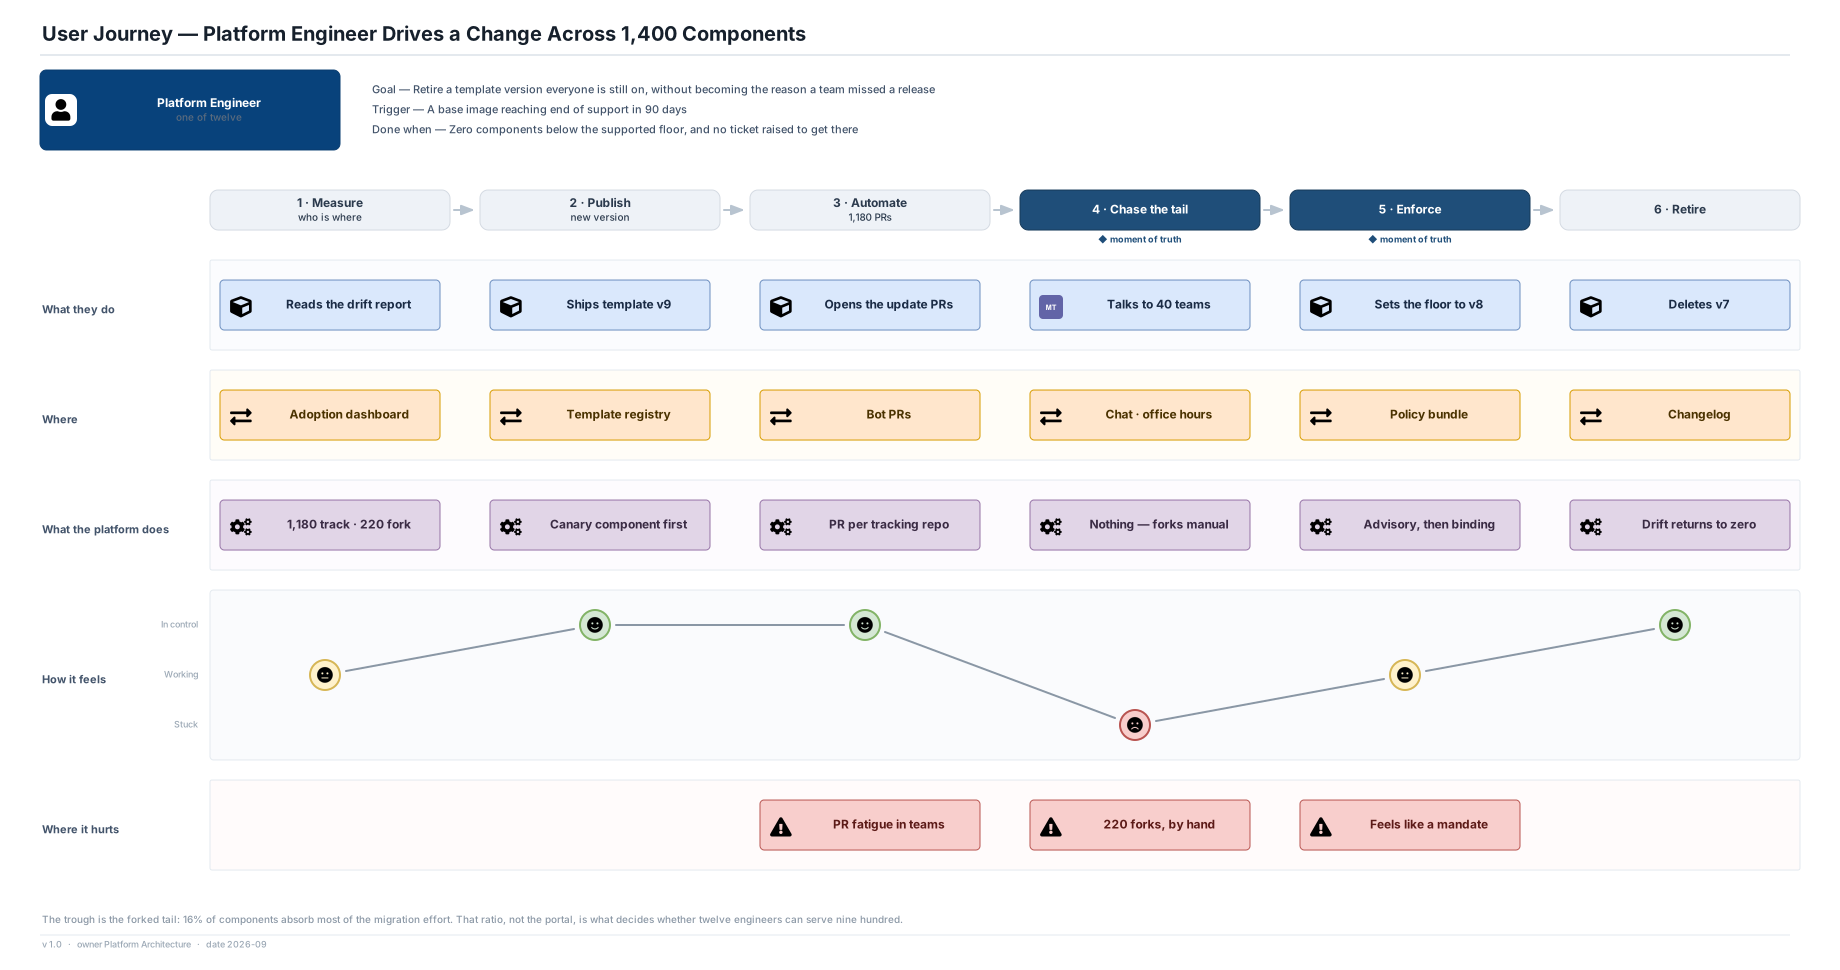
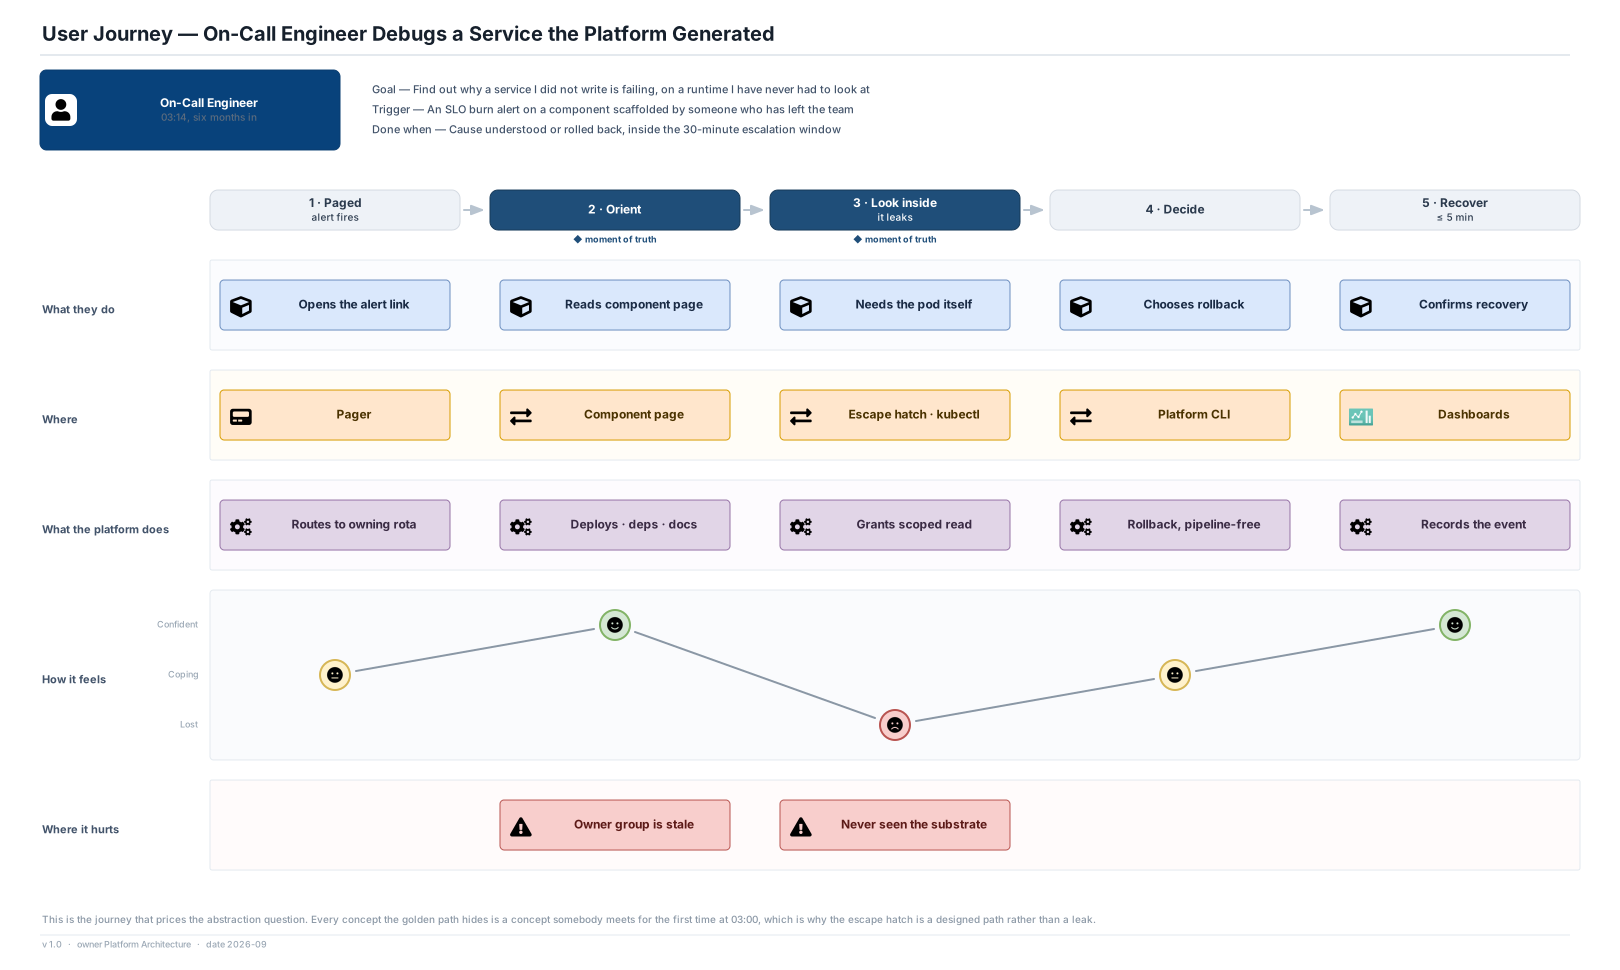
03 The people who ship product Product Engineer 900 of them Goal — Get my service running in production today, without learning the cloud account model or filing a ticket. Core journeys Create and ship a service ≤ 2 h to first deploy Add a database ≤ 12 min Release a change ≤ 25 min to prod Tech Lead 140 teams Goal — Know what my team owns, what it costs, and what is failing its controls — on one page. Core journeys Review what we own Clear template drift Argue for leaving the road On-Call Engineer 03:00, alone Goal — Understand a service I did not write, on a substrate I have never seen, before the page escalates. Core journeys Debug a paved-road service the leaky abstraction Roll back a release ≤ 5 min The people who own the platform Platform Engineer 12 of them Goal — Change something once and have it land across 1,400 components without breaking anyone's Friday. Core journeys Publish a golden path Drive a migration 1,400 components Answer a support request Security Engineer authors the controls Goal — Have a control apply to every running workload, including the ones that never touched a template. Core journeys Ship a binding guardrail Rule on an exception Report control coverage FinOps Analyst one per estate Goal — Attribute every pound of cloud spend to a team without a reconciliation spreadsheet. Core journeys Trace spend to an owner Reclaim idle resources Who this is not for End Customer never sees it Goal — Get a product that changes faster and breaks less, and never hear the word platform. Core journeys Benefits invisibly lead time · failure rate Landing Zone Team the platform's landlord Goal — Hand out subscriptions and network with a policy floor, and not be asked about anyone's Helm chart. Core journeys Issues subscriptions Sets the Azure Policy floor Internal Developer Platform — Actors and Their Core Journeys Person or role Journey / task External / third party Three engineer-facing personas, not one: the person creating a service, the person owning it a year later, and the person woken by it are rarely the same human. v 1.0 · owner Platform Architecture · date 2026-09 Actors and Their Core Journeys Who the platform is for, in their own words, and what each of them gets to do with it. HTML page SVG draw.io

Structure

The planes, the components inside them, and the surfaces other systems touch.
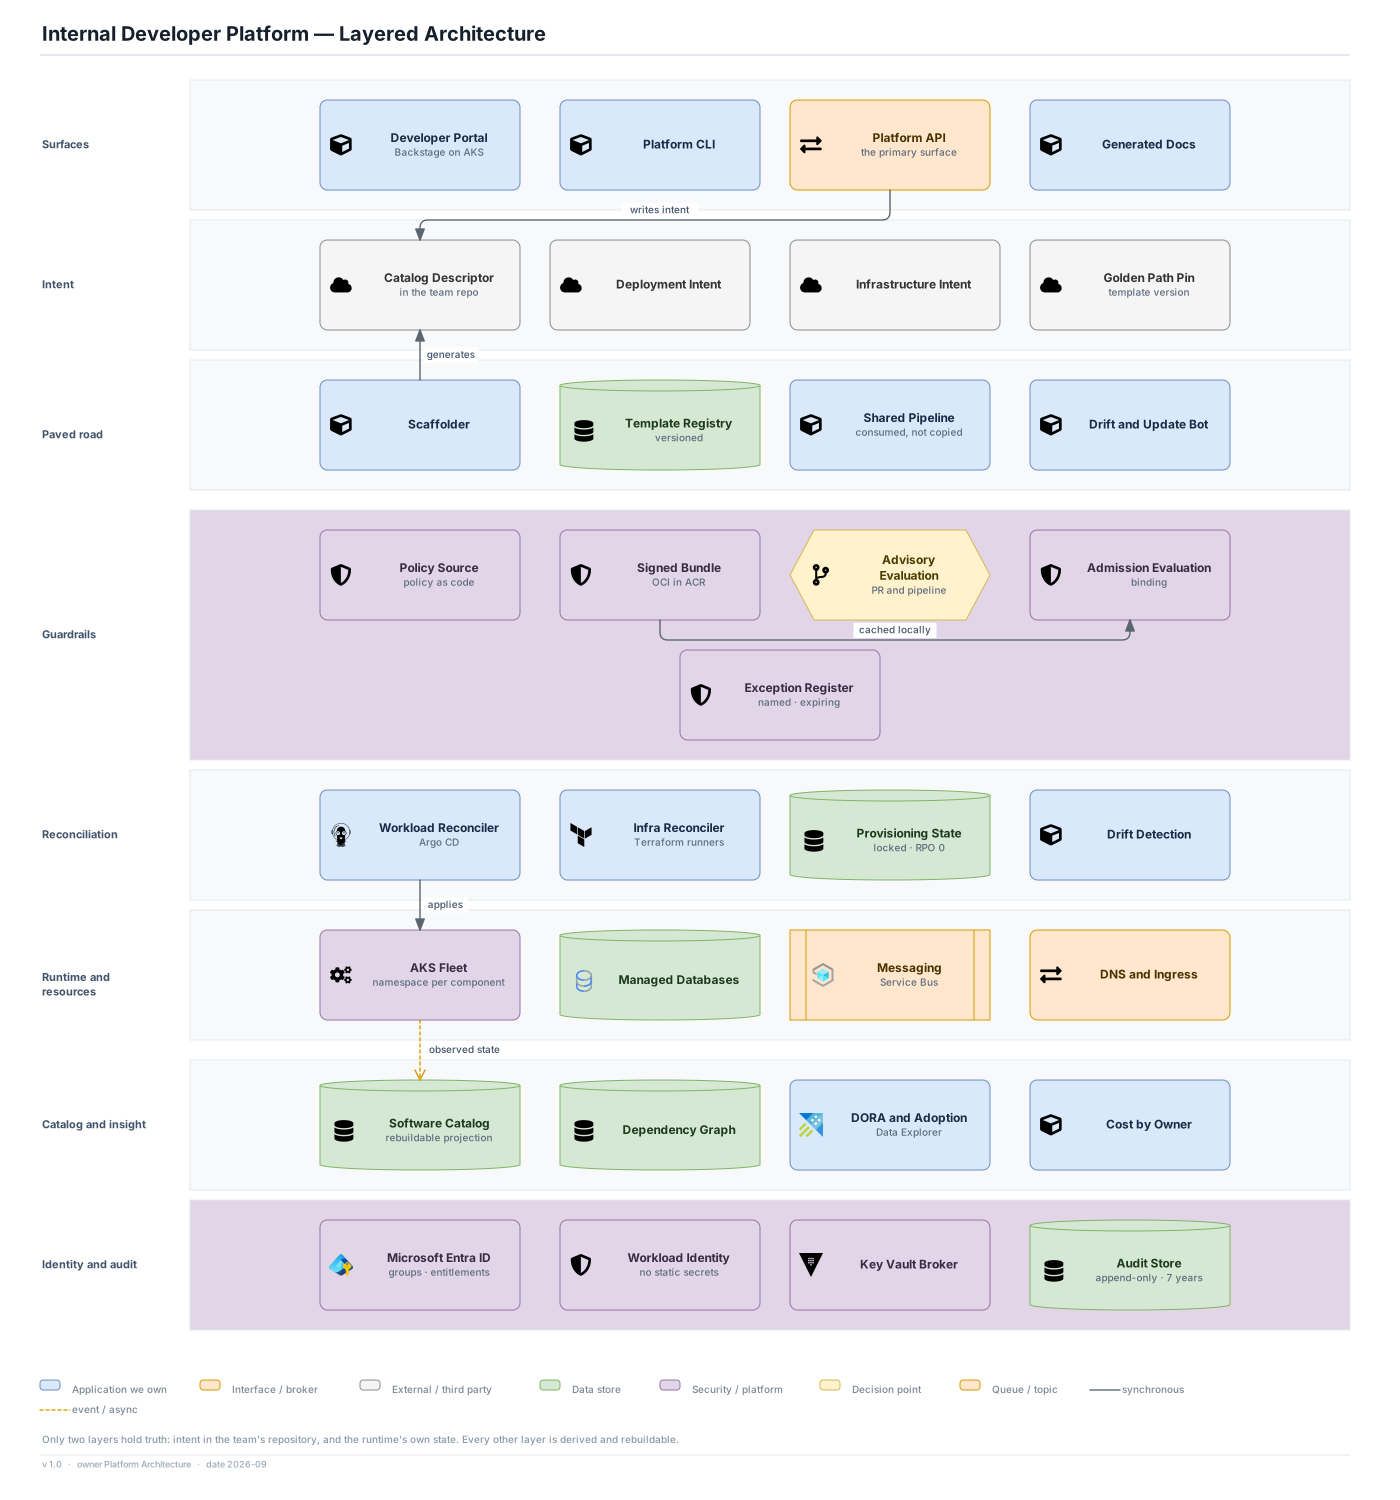
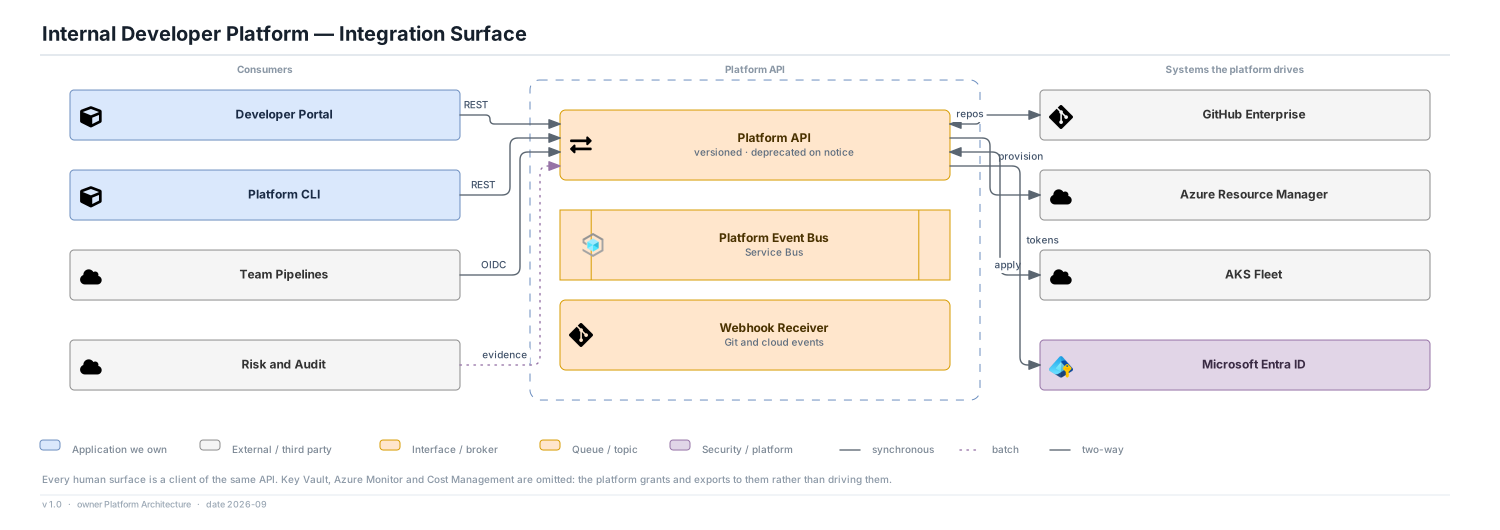
07 Surfaces Developer Portal Backstage on AKS Platform CLI Platform API the primary surface Generated Docs Intent Catalog Descriptor in the team repo Deployment Intent Infrastructure Intent Golden Path Pin template version Paved road Scaffolder Template Registry versioned Shared Pipeline consumed, not copied Drift and Update Bot Guardrails Policy Source policy as code Signed Bundle OCI in ACR Advisory Evaluation PR and pipeline Admission Evaluation binding Exception Register named · expiring Reconciliation Workload Reconciler Argo CD Infra Reconciler Terraform runners Provisioning State locked · RPO 0 Drift Detection Runtime and resources AKS Fleet namespace per component Managed Databases Messaging Service Bus DNS and Ingress Catalog and insight Software Catalog rebuildable projection Dependency Graph DORA and Adoption Data Explorer Cost by Owner Identity and audit Microsoft Entra ID groups · entitlements Workload Identity no static secrets Key Vault Broker Audit Store append-only · 7 years writes intent generates cached locally applies observed state Internal Developer Platform — Layered Architecture Application we own Interface / broker External / third party Data store Security / platform Decision point Queue / topic synchronous event / async Only two layers hold truth: intent in the team's repository, and the runtime's own state. Every other layer is derived and rebuildable. v 1.0 · owner Platform Architecture · date 2026-09 Layered Architecture Eight layers, of which exactly two hold truth. HTML page SVG draw.io
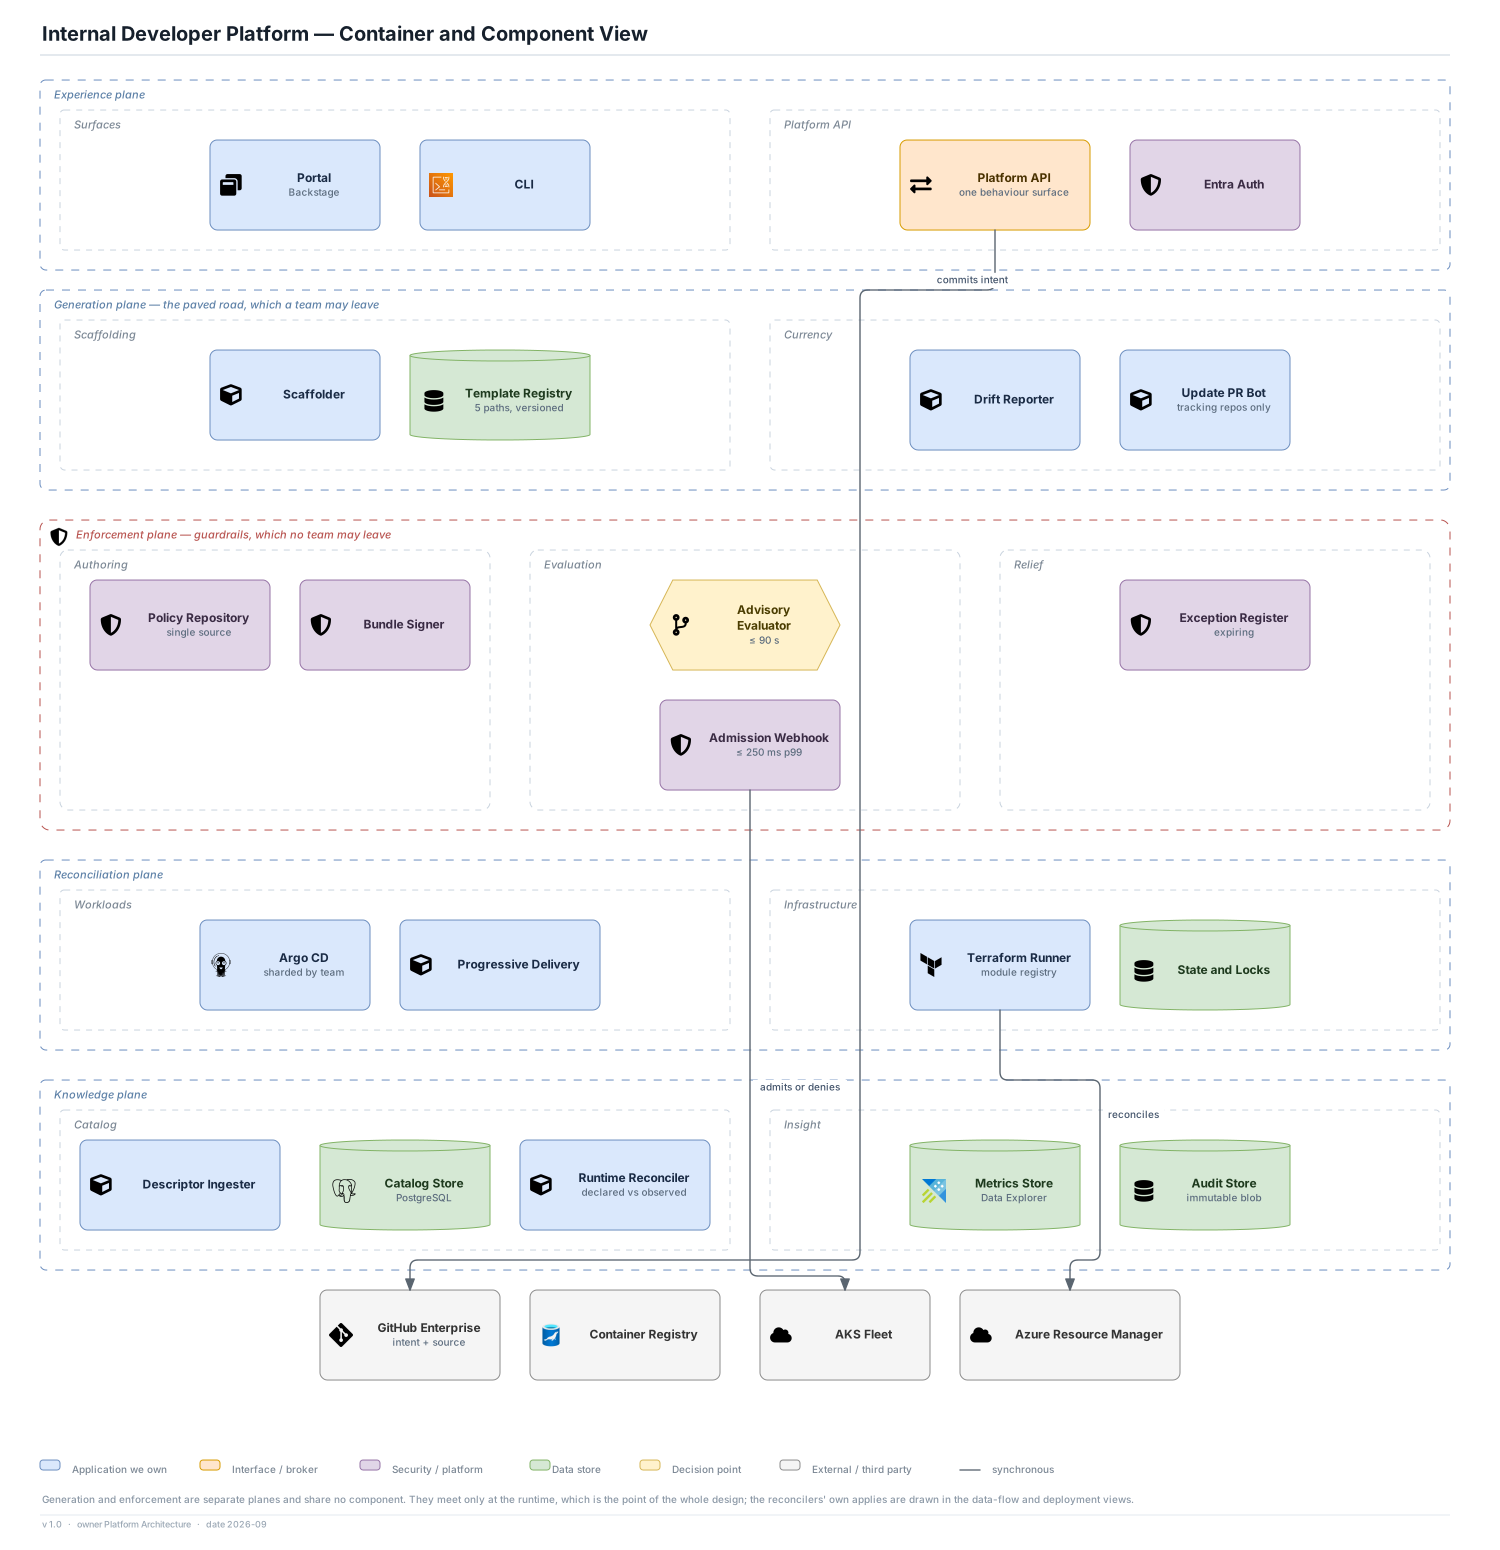
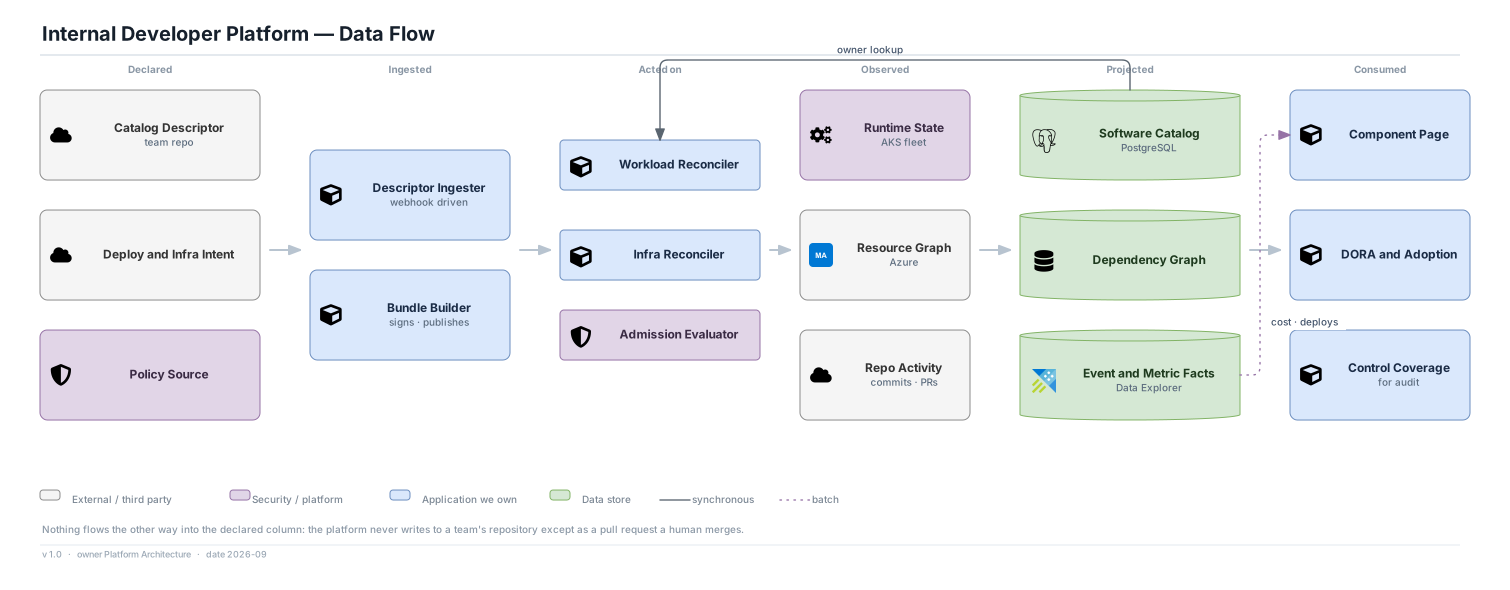
08 Experience plane Surfaces Portal Backstage CLI Platform API Platform API one behaviour surface Entra Auth Generation plane — the paved road, which a team may leave Scaffolding Scaffolder Template Registry 5 paths, versioned Currency Drift Reporter Update PR Bot tracking repos only Enforcement plane — guardrails, which no team may leave Authoring Policy Repository single source Bundle Signer Evaluation Advisory Evaluator ≤ 90 s Admission Webhook ≤ 250 ms p99 Relief Exception Register expiring Reconciliation plane Workloads Argo CD sharded by team Progressive Delivery Infrastructure Terraform Runner module registry State and Locks Knowledge plane Catalog Descriptor Ingester Catalog Store PostgreSQL Runtime Reconciler declared vs observed Insight Metrics Store Data Explorer Audit Store immutable blob GitHub Enterprise intent + source Container Registry AKS Fleet Azure Resource Manager commits intent admits or denies reconciles Internal Developer Platform — Container and Component View Application we own Interface / broker Security / platform Data store Decision point External / third party synchronous Generation and enforcement are separate planes and share no component. They meet only at the runtime, which is the point of the whole design; the reconcilers' own applies are drawn in the data-flow and deployment views. v 1.0 · owner Platform Architecture · date 2026-09 Container and Component View The five planes, and the fact that generation and enforcement share nothing. HTML page SVG draw.io

Data

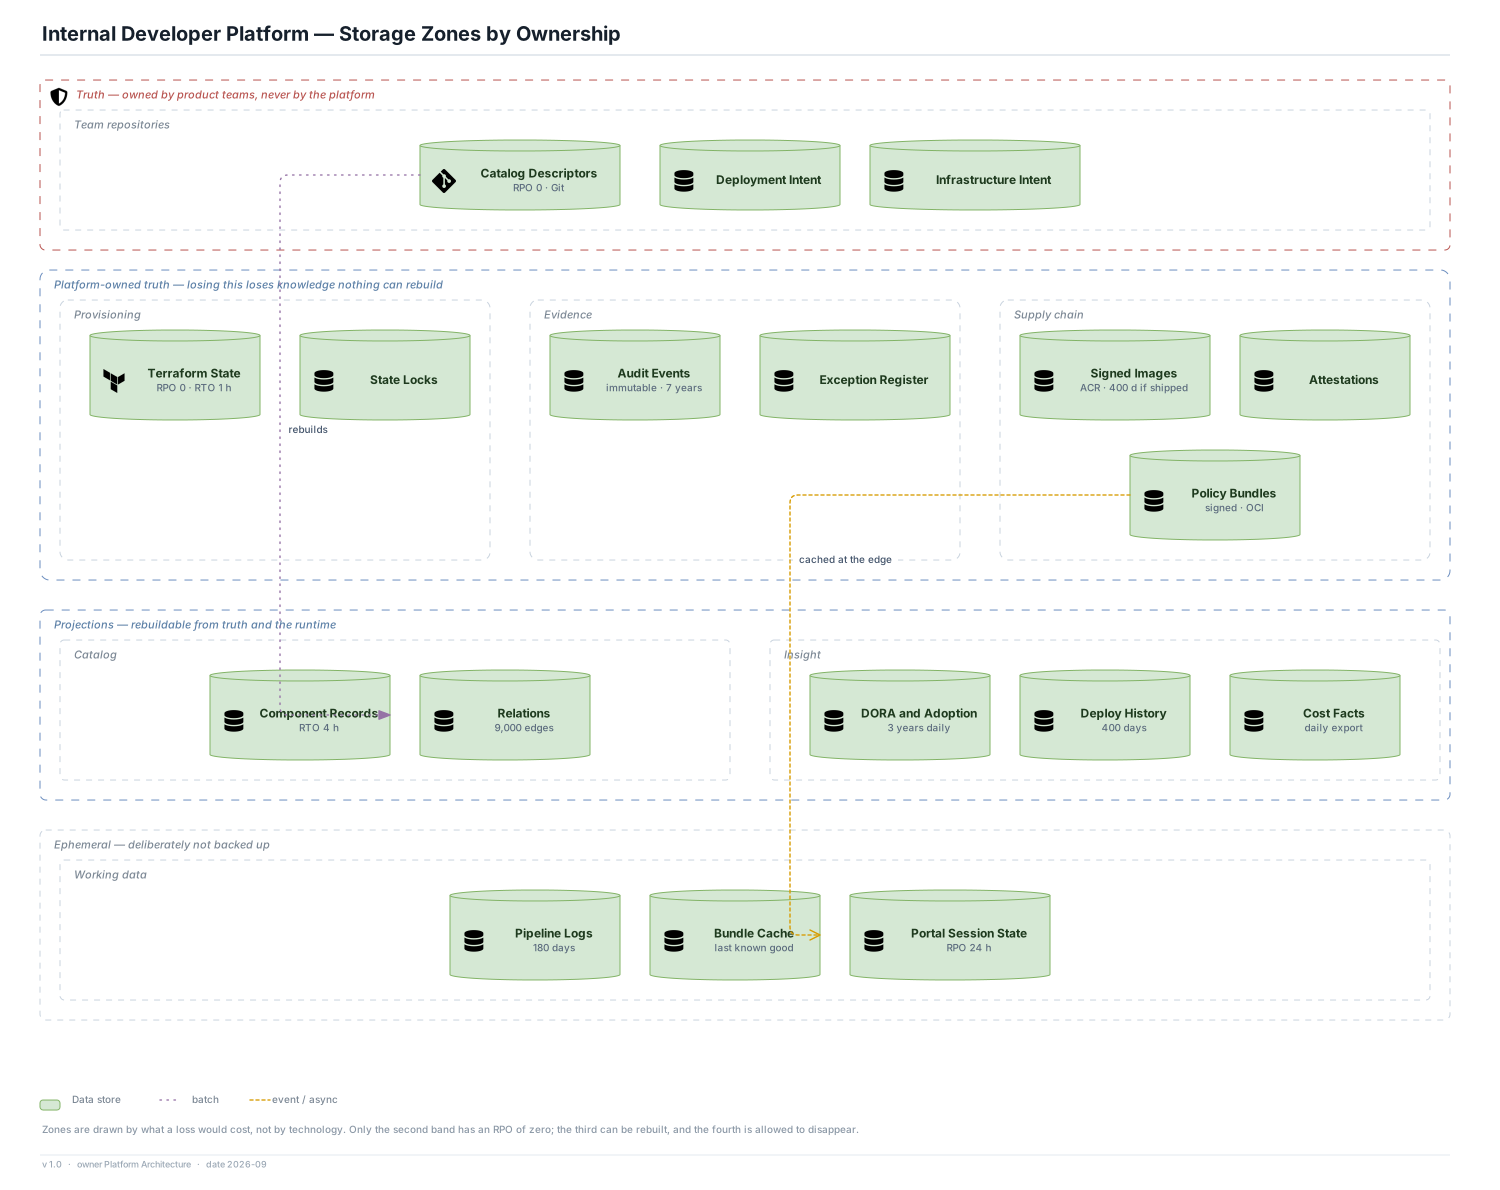
Which stores hold truth, which are projections, and what a loss of each would actually cost.
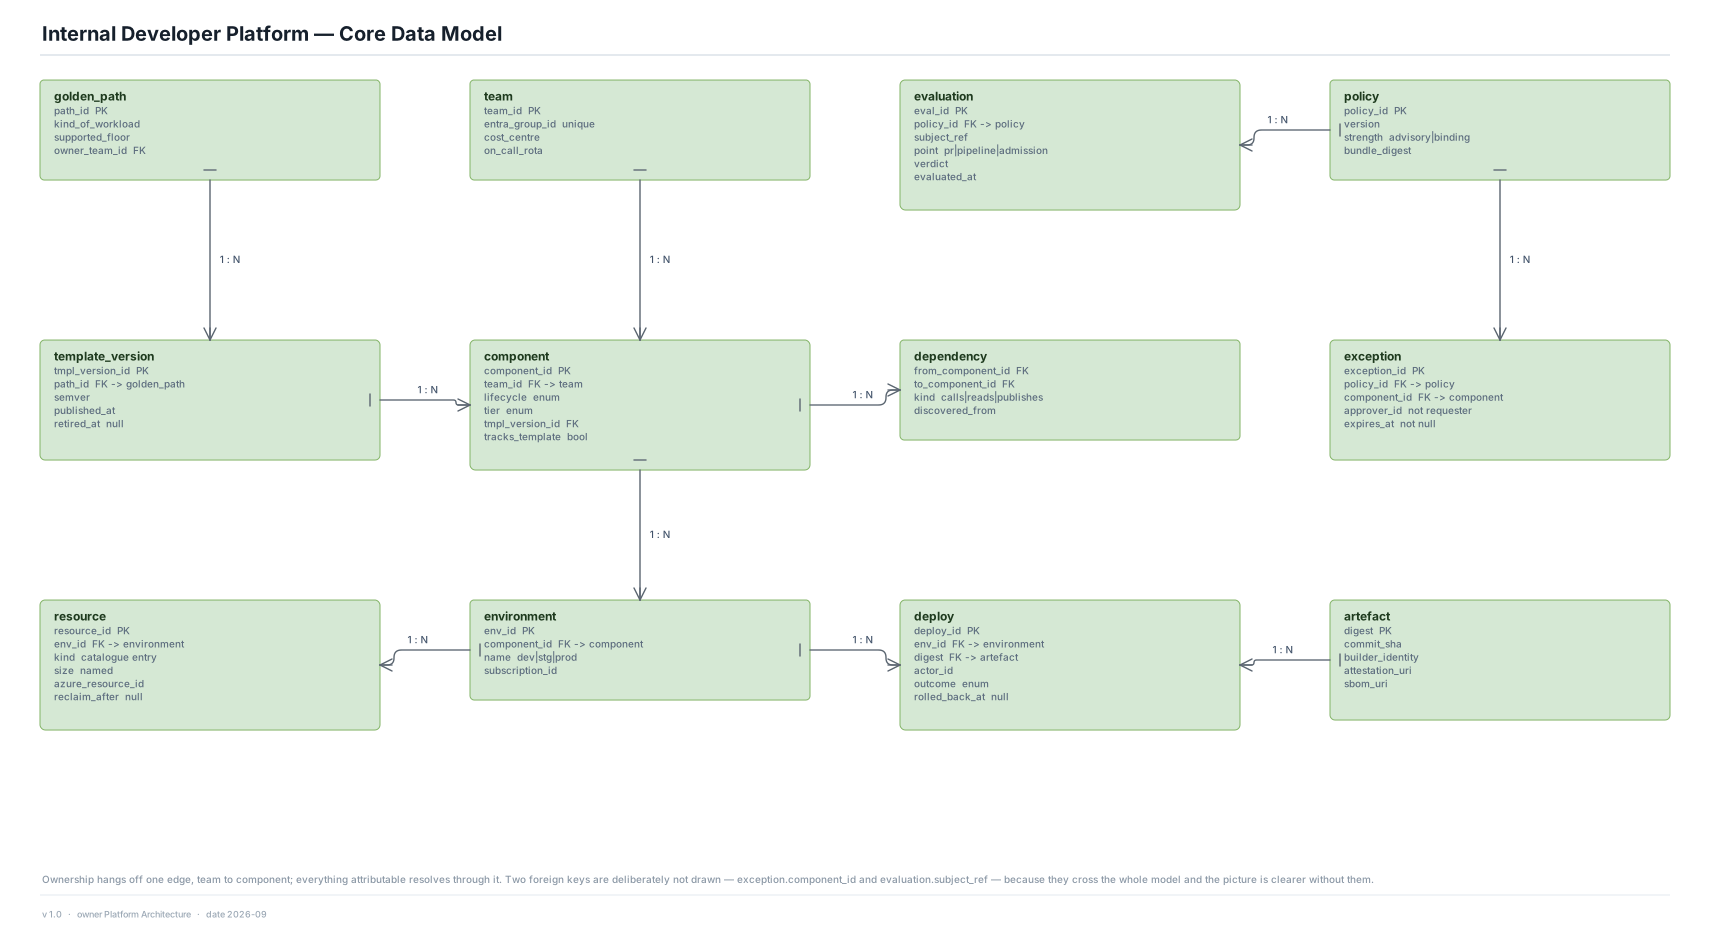
12 team team_id PK entra_group_id unique cost_centre on_call_rota component component_id PK team_id FK -> team lifecycle enum tier enum tmpl_version_id FK tracks_template bool golden_path path_id PK kind_of_workload supported_floor owner_team_id FK template_version tmpl_version_id PK path_id FK -> golden_path semver published_at retired_at null environment env_id PK component_id FK -> component name dev|stg|prod subscription_id resource resource_id PK env_id FK -> environment kind catalogue entry size named azure_resource_id reclaim_after null deploy deploy_id PK env_id FK -> environment digest FK -> artefact actor_id outcome enum rolled_back_at null artefact digest PK commit_sha builder_identity attestation_uri sbom_uri policy policy_id PK version strength advisory|binding bundle_digest evaluation eval_id PK policy_id FK -> policy subject_ref point pr|pipeline|admission verdict evaluated_at exception exception_id PK policy_id FK -> policy component_id FK -> component approver_id not requester expires_at not null dependency from_component_id FK to_component_id FK kind calls|reads|publishes discovered_from 1 : N 1 : N 1 : N 1 : N 1 : N 1 : N 1 : N 1 : N 1 : N 1 : N Internal Developer Platform — Core Data Model Ownership hangs off one edge, team to component; everything attributable resolves through it. Two foreign keys are deliberately not drawn — exception.component_id and evaluation.subject_ref — because they cross the whole model and the picture is clearer without them. v 1.0 · owner Platform Architecture · date 2026-09 Core Data Model Twelve entities, and the one edge every attribution resolves through. HTML page SVG draw.io

Runtime

What happens when an engineer scaffolds, provisions and deploys — and where a policy verdict is produced.

Operations

How work reaches production, what is watched, and how a component ages out.

Assurance

Where the trust boundaries sit, and how a person's identity becomes a workload's short-lived credential.

Architecture One-Pager

The problem, the shape of the answer, the decisions that carry it, and why it should still be right in ten years.

The paved road is a product teams may decline; the guardrails are controls they cannot. Generation and enforcement are separate planes, and they meet only at the runtime.

Creating a new service at this organisation takes nineteen working days and touches seven teams: a repository request, a pipeline request, a namespace request, a database request, a DNS and certificate request, a secrets onboarding request, and a security review that arrives after the architecture is already built. Every step is a form filled in by an engineer who does not want to be an expert in the thing the form is about, and read by a specialist who is the bottleneck for four hundred other engineers. The cost is not only the nineteen days. It is the services that never get split because splitting is expensive, the security review that lands too late to change anything, and the gradual accumulation of workloads nobody can attribute to a team. The platform's job is to make the distance between an engineer's intent and a production-grade running system as short as it can honestly be — without making the result less safe, and without becoming a ticket queue with a nicer interface.

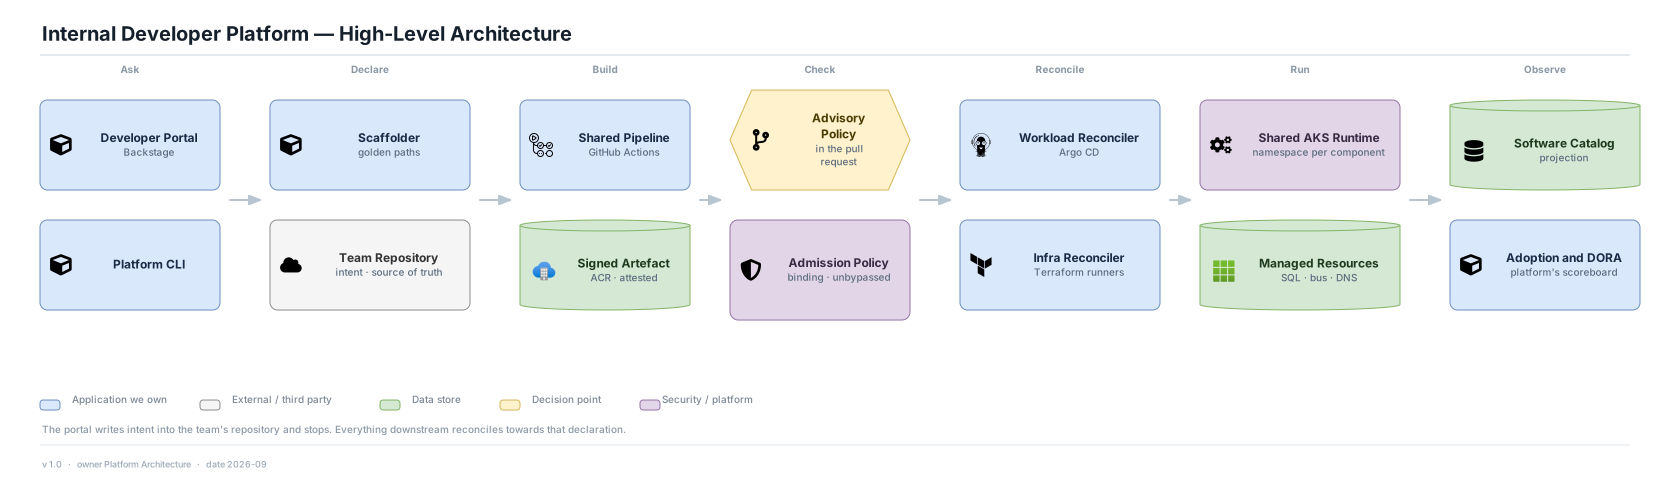
An engineer picks a golden path in the portal or the CLI. The scaffolder creates the repository with its catalog descriptor, deployment intent, infrastructure intent, a reference to the shared pipeline, and the observability and on-call wiring already in place. Everything the engineer declares lives in their own repository; the platform's surfaces write intent and then stop. Two reconcilers converge the world on that declaration — one for workloads into a shared AKS fleet, one for infrastructure through Terraform against Azure Resource Manager — and both are idempotent, resumable and drift-detecting. Alongside them, and sharing no component with them, runs the enforcement plane: policy authored as code, signed into a bundle, cached locally at every evaluation point, advisory in the pull request and binding at admission into the cluster. A component that never touched a golden path meets exactly the same binding checks. Everything that results — what is running, who owns it, what it cost, what it is failing — is projected into a catalog that is rebuildable rather than authoritative, and into the adoption and DORA metrics by which the platform judges itself.

What it is, and what it is not

A product engineers choose because it is faster than the alternativea mandated standard whose adoption figure is 100% by definition and therefore says nothing.
A set of controls enforced where workloads runa template that happens to contain the right settings until someone forks it.
A mechanism that reconciles towards intent the team ownsa database of other people's configuration with a form in front of it.
A system that may fail without production noticinga portal in the path of anyone's deploy, rollback or running traffic.
An answer that arrives in minutes and explains its own refusalsa ticket queue with better typography.

The decisions that are the architecture

01Guardrails live in the runtime, not the template

Enforcement is a property of admission into the cluster, authored and signed separately from any golden path. A fork removes the template and never the control.

ADR-05

02One policy source, two evaluation points

Advisory in the pull request to teach, binding at admission to hold. A CI-pass-then-admission-fail is defined as a platform defect and measured as one.

ADR-06

03Intent lives in the team's repository

The portal writes intent and owns nothing. The platform's catalog is a projection, which is what lets it be rebuilt rather than protected at RPO 0.

ADR-01

04Provision by reconciliation

Declared state converged on continuously, so a partial failure resumes and a console edit becomes a detected event rather than invisible drift.

ADR-02

05Track the template by default; forking is recorded

The fork ratio is the number that predicts migration cost, and the pipeline is consumed by reference so the most change-prone artefact is not part of the fork surface.

ADR-03

06Attribution at creation

Owner, cost centre, tier and data classification are enforced properties applied when a thing is made, because nothing acquires an owner afterwards.

ADR-11

07Entitlement derives from ownership

Catalog ownership resolves to a live identity group, so a reorganisation moves access with the components and there is no second list to decay.

ADR-10

08The platform is never in the critical path

A portal outage costs the ability to change, never the ability to serve. Running workloads are never evicted because the platform cannot evaluate them.

ADR-12

09Exceptions are named, approved by another, expiring and published

Relief always exists; making it visible is what stops it becoming a quiet policy edit for the loudest team.

ADR-08

10A thin abstraction with a designed escape hatch

Every concept the golden path hides is met for the first time at 03:00, so the substrate stays addressable and access to it is an entitlement rather than an incident favour.

ADR-07

Why this should still be right in ten years

An internal platform outlives the tools it was built from — the portal, the reconcilers, probably the cloud. These are the properties that should survive all of that, and the ones a future team would most easily discard without noticing what they were for.

The plane separation names no technology

ADR-05 says that evidence of a control must come from where the workload runs, not from how it was created. That is true of Kubernetes admission, of whatever replaces it, and of a substrate that has no admission point at all — in which case the architecture must say honestly that its coverage claim has weakened, rather than quietly keep making it.

Ownership of truth decides ownership of the system

Keeping intent in the team's repository is not a Git preference. It is the reason the platform can be rebuilt without asking 140 teams what they had, and the reason the platform team is never asked to act as the owner of somebody else's configuration on the worst day.

Optional adoption keeps the feedback signal alive

A mandate would raise coverage and destroy the only honest measurement of whether the paved road is good. The shadow estate is uncomfortable to report and is the most valuable number the platform produces.

Cognitive load is a budget that will be spent if it is not defended

Every golden path will want one more concept, and each addition is individually reasonable. Stating the budget as a design constraint is what makes the tenth addition arguable rather than inevitable.

The control plane stays out of the data path

The rule that a platform outage may cost the ability to change but never the ability to serve is the one that decides whether the platform survives its first bad day. It is also the first rule broken under deadline, which is why the SLOs are published to tenants.

What is rebuildable and what is not is a permanent question

The storage classification in ADR-16 is a method rather than a configuration: ask of every store what it could be reconstructed from, and protect only the ones with no answer. That survives any change of database, cloud or retention regime.

Non-functional targets

Every number here is a stated assumption from the requirement, chosen to be argued with rather than believed. The right-hand column names the view where the mechanism that meets it is drawn.

QualityTargetHow it is metView
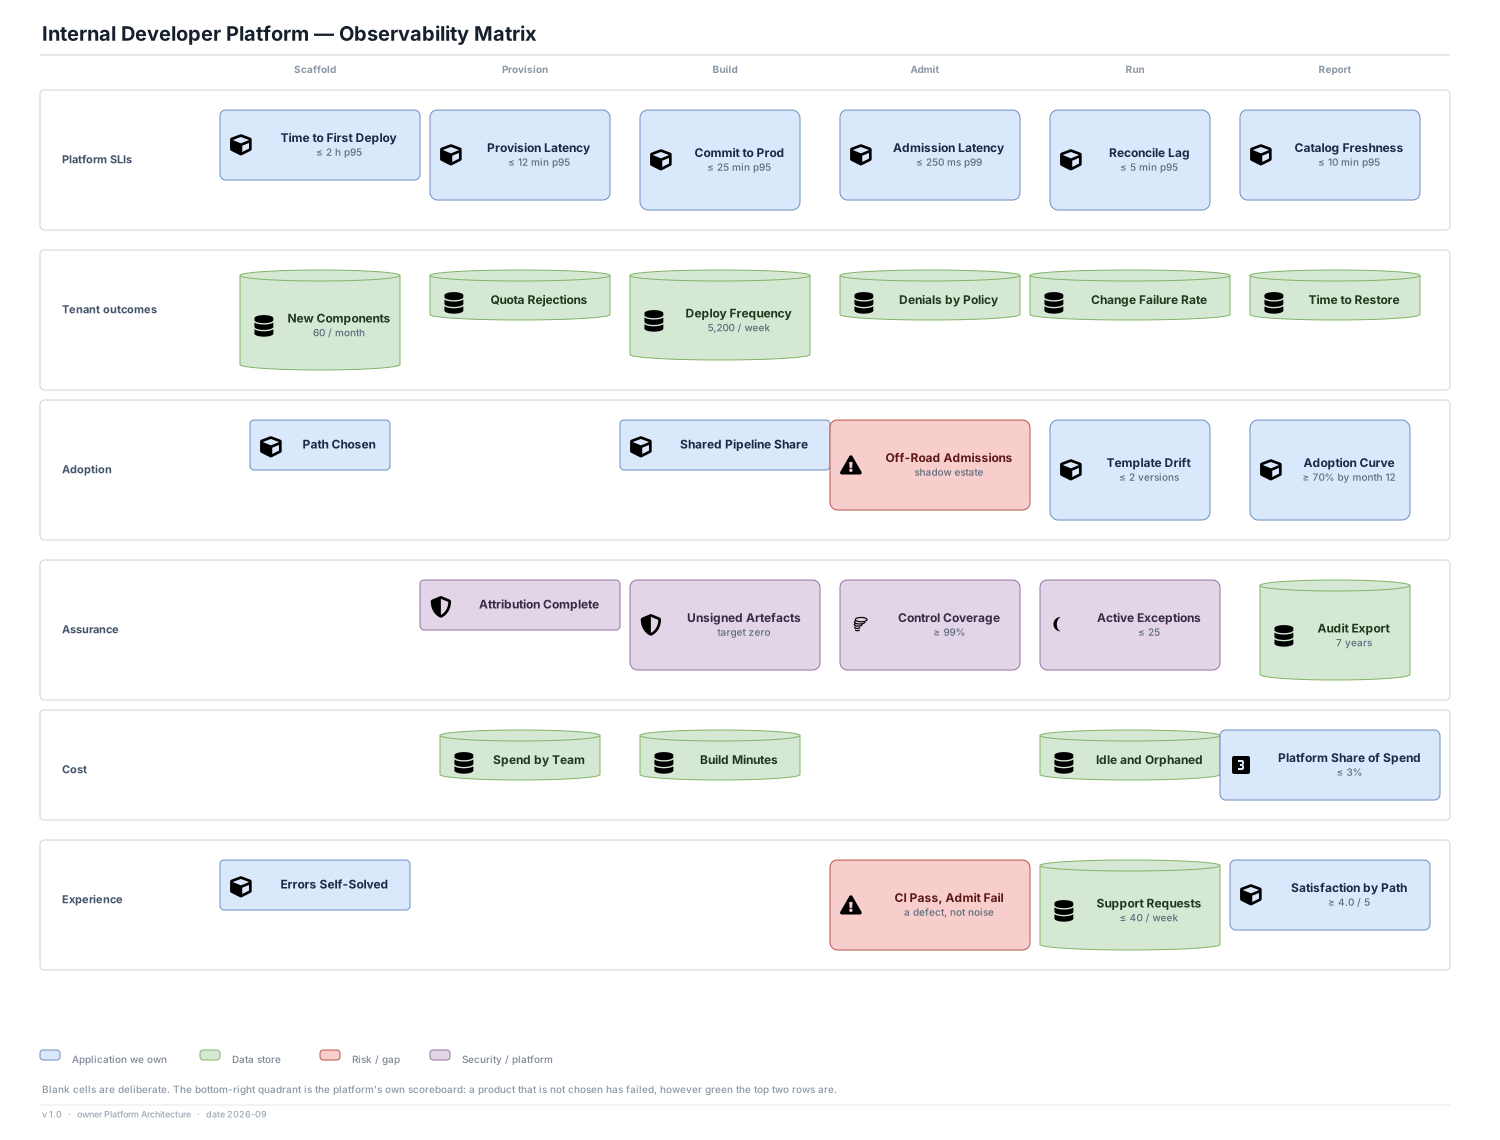
Time to first production deploy ≤ 30 min p50, ≤ 2 h p95 for a new component One scaffold action produces repository, pipeline reference, manifests, observability wiring and catalog entry; provisioning runs in parallel with the engineer writing code. 04
Self-service provisioning latency ≤ 12 min p95 for the golden-path resource set Declared intent admitted against quota, then reconciled by a runner pool with idempotent, resumable applies. 14
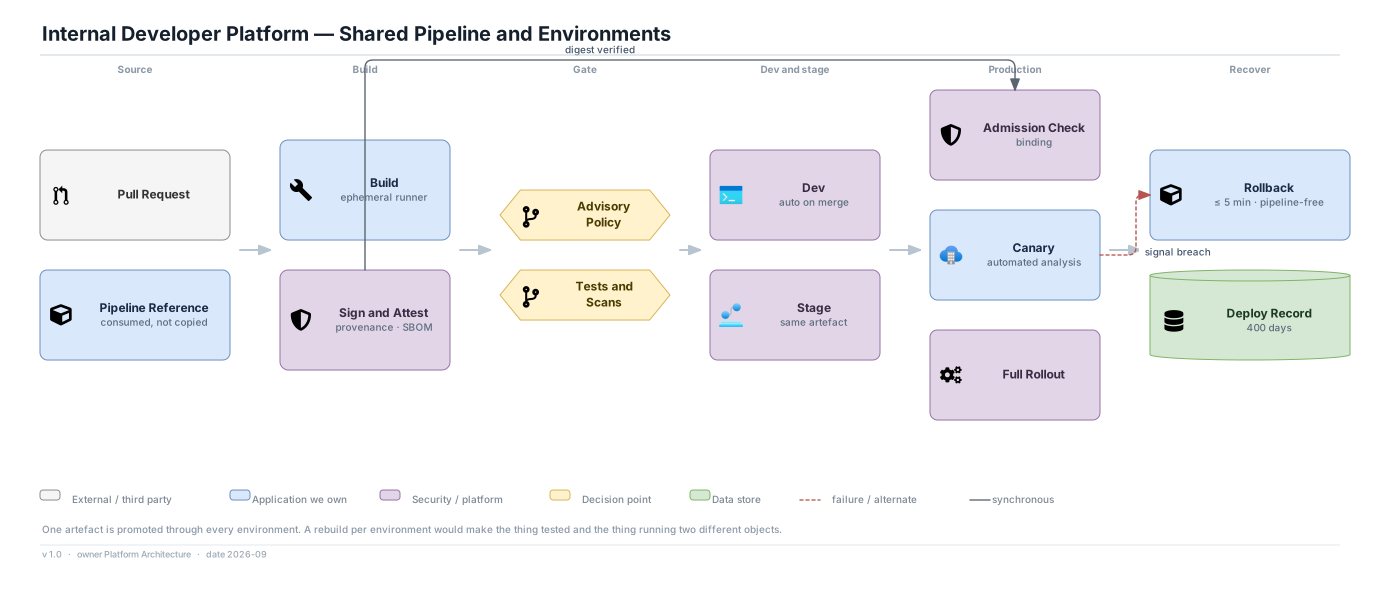
Commit to production ≤ 25 min p95 on the paved road Shared pipeline consumed by reference, one artefact promoted unchanged, reconciler applies without a second build. 17
Binding guardrail evaluation ≤ 250 ms p99, ≥ 99.95% monthly Three admission webhook replicas per cluster evaluating a locally cached signed bundle — no network call to a central service on the admission path. 15
Advisory guardrail feedback ≤ 90 s p95 in the pull request Same bundle, evaluated in the pipeline; a divergence from the admission verdict is instrumented as a defect. 15
Rollback ≤ 5 min p99 to serving the previous version Reconciler-level revert to the previously converged state, independent of the pipeline and of a fresh build. 17
Reconciliation lag ≤ 5 min p95, ≤ 20 min p99 Sharded reconcilers with bounded worst-case lag, plus drift detection on resource-graph change events. 14
Catalog freshness ≤ 10 min p95 after a deploy or ownership change Webhook-driven descriptor ingestion with a periodic full reconcile as the backstop. 10
Platform availability Portal ≥ 99.5%, build and deploy control plane ≥ 99.9%, admission ≥ 99.95% Availability is graded by what each component is in the path of; the portal holds no truth and is in no production path. 16
Guardrail coverage ≥ 99% of production workloads, off-road included Enforcement at admission rather than in templates, so coverage describes what is running rather than how it was made. 15
Adoption ≥ 70% on a current golden path by month 12; shadow estate ≤ 10% Measured from the catalog's projection of declared and observed state, and reported as the platform's own scoreboard. 18
Recovery Provisioning state RPO 0 / RTO 1 h; catalog RPO 15 min / RTO 4 h; portal RPO 24 h Storage classified by what a loss would cost, with a full control-plane rebuild exercised twice a year. 11

Scope

In scope

  • A software catalog with enforced ownership, lifecycle state and tier, reconciled against the runtime in both directions.
  • Golden paths that scaffold repository, pipeline reference, manifests, observability wiring and catalog descriptor in one action, with drift measurement and automated update pull requests.
  • Self-service provisioning by declared intent for a bounded catalogue of resource kinds, admitted against quota, budget and data classification.
  • A shared build and deploy path producing signed, attested, content-addressed artefacts promoted unchanged through environments, with progressive delivery and pipeline-independent rollback.
  • Policy-as-code guardrails evaluated advisorily in the pull request and bindingly at admission, with a named, expiring exception register.
  • Portal, CLI and API over one behaviour surface, with a single component page carrying health, deploys, dependencies, on-call, cost and open findings.
  • Workload identity everywhere, brokered secrets, and an append-only audit of every privileged action.
  • Adoption, DORA and control-coverage reporting, including the shadow estate.

Explicitly out of scope

  • Product code, product architecture and product on-call. The platform paves the road; the teams drive on it.
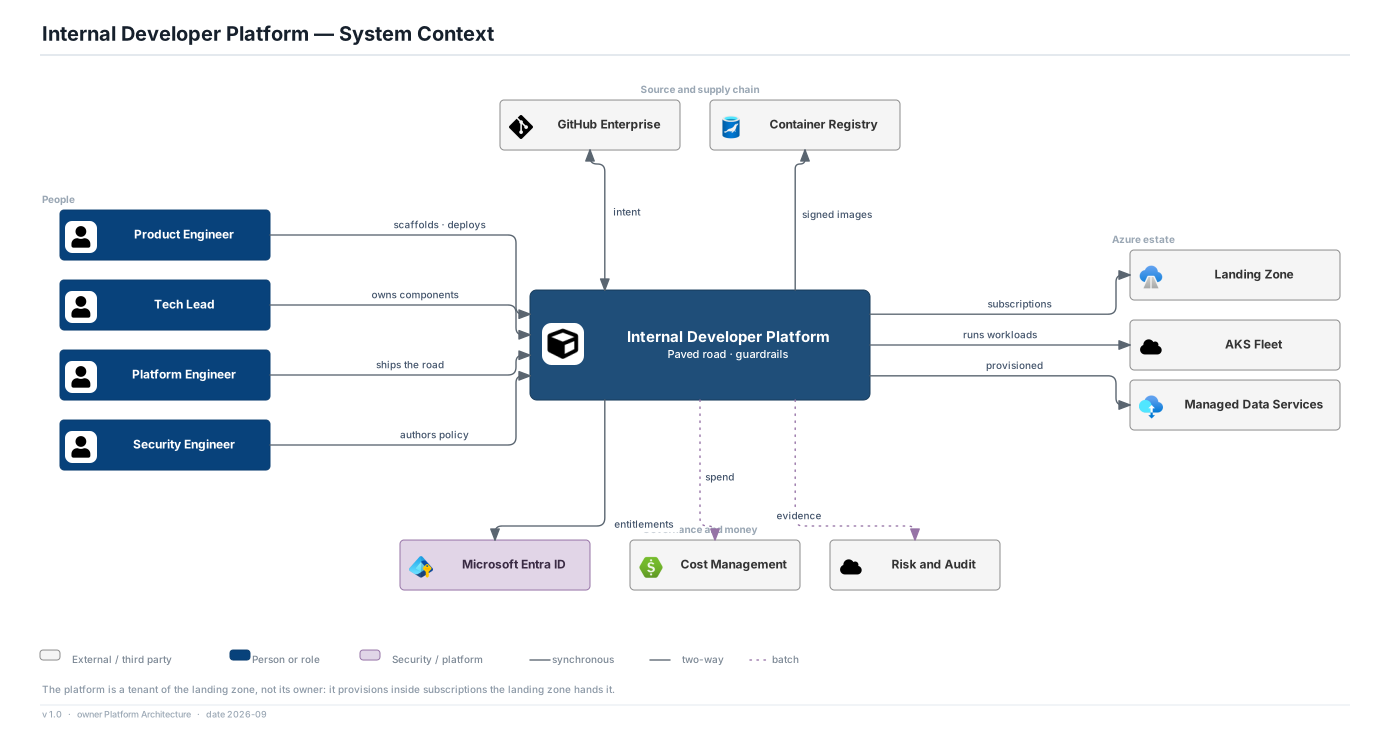
  • The landing zone: subscription vending, network topology and the organisation's Azure Policy floor. The platform is its tenant.
  • Being an approval workflow. A request the platform accepts and then queues for a human has already failed at its only job.
  • Owning tenant multi-region strategy — the platform's paired region carries its own recovery, not an active copy of every tenant.
  • Per-pull-request ephemeral environments and self-service golden-path authoring, both deferred to Phase 3.

What a six-week prototype should prove

Four of this architecture's claims are cheap to test and expensive to be wrong about. A prototype that proves these can be built on; one that only demonstrates scaffolding a repository has proved the easy half.

  1. Plane separation end to end: scaffold a component, fork its template so every generated control is deleted, deploy it, and confirm the binding admission checks still refuse it for exactly the same reasons. Then deploy a vendor Helm chart that was never scaffolded and confirm it meets the same checks.
  2. One policy source, two points: take a real control, evaluate it in the pull request and at admission from the same signed bundle, then deliberately desynchronise the bundle and confirm the divergence is detected and reported rather than silently tolerated.
  3. Reconciliation under failure: kill a provisioning run halfway through a multi-resource set, confirm it resumes from the declaration without a human reconstructing state, then change a resource in the Azure console and confirm the drift is detected, attributed and reported within the lag budget.
  4. The migration lever: scaffold twenty components, publish a template change, and measure what fraction land automatically, how long the tail takes, and what it costs a platform engineer per forked component. That ratio, more than any latency number, decides whether twelve people can serve nine hundred.
  • Fork a scaffolded component's template so every generated control is deleted, deploy it, and confirm admission refuses it for exactly the same reasons — then deploy a vendor Helm chart that was never scaffolded and confirm it meets the same checks.
  • Desynchronise the policy bundle between the pipeline evaluator and the admission webhook, and confirm the divergence is detected and reported rather than experienced by an engineer on a Friday.
  • Kill a provisioning run halfway through a multi-resource set and confirm it resumes from the declaration, with no human reconstructing which half exists.
  • Change a provisioned resource in the Azure console and confirm the drift is detected, attributed to the owning team and reported inside the lag budget.
  • Take the portal down entirely and confirm a deploy, a rollback and a reconciliation all still complete.
  • Delete the identity group that owns a running component and confirm it is quarantined and reported rather than continuing to run unattributed.
  • Publish a template change across twenty scaffolded components and measure what lands automatically, how long the tail takes, and the platform-engineer cost per forked component.

Open risks, carried rather than hidden

RiskIf it landsResponse
Adoption stalls below the threshold where the platform pays for itself Twelve engineers maintaining a paved road most teams decline is a worse outcome than no platform, because the guardrails still have to be run and the shadow estate still has to be supported. Adoption and satisfaction reported per path from day one, with a declining path treated as a signal about the path. The requirement leaves the mandate question explicitly open, and the answer changes the business case rather than the architecture.
Advisory and binding verdicts diverge in practice Engineers stop believing the pull-request verdict, and every control is met for the first time at admission — the experience that makes platforms hated and routed around. One signed bundle for both points, the divergence rate instrumented as a defect class in view 18, and a narrower advisory set if identical evaluation proves impossible at some stage.
The forked tail consumes the platform team If the fork ratio is materially above the assumed 16%, migrations stop being automatable and the 1:75 staffing ratio fails quietly — as unshipped fixes rather than as an incident. Measure the ratio in the prototype. The lever is moving more of the template into artefacts consumed by reference, so that forking the repository does not fork the pipeline.
The abstraction is wrong for the on-call population Too thin and every engineer pays learning costs the platform was meant to remove; too thick and the person paged at 03:00 meets the substrate for the first time under pressure. Escape-hatch usage is measured, and a spike names the abstraction that is failing. This is the requirement's most openly unresolved question, and the substrate is kept addressable so the line can move in either direction without a rewrite.
Shared-cluster upgrades become the platform's dominant risk One upgrade can affect every tenant in a cluster, and a bad policy bundle can stop deploys fleet-wide. Staged fleet rollout with automated tenant smoke checks and abort-and-hold, a canary component per golden path walking the whole path continuously, and staged reversible policy publication.
Provisioning state is lost or corrupted The platform stops knowing what it created; recovery becomes reconciliation by hand across an estate of 1,400 components. RPO 0 with versioning and locking, restore exercised twice a year rather than assumed, and a rebuild path from declared intent as the backstop of last resort.

Architecture Decision Record

Why every component and every technology on these 21 views is what it is, and what each choice costs.

Sixteen decisions make up this architecture. Everything else across the twenty-one views is convention, sizing or consequence. Each record states the forcing question, the context that makes it hard, what was decided, how it is realised on Azure, the options weighed, what the choice buys and costs, the conditions that would flip it, why it should still be right in ten years, and the lesson that transfers beyond this platform.

Status of this document. This is a design, not a report on a running system. The rates, latencies, volumes, retentions and targets are the requirement's stated assumptions for a mid-size engineering organisation — 900 engineers, 140 teams, 1,400 components, 5,200 deploys a week, a platform team of twelve — invented to be defensible and arguable rather than absent. They are to be replaced by measured telemetry before build, and four in particular are the first numbers real data should overturn: the 19-working-day baseline the whole business case rests on, the 16% fork ratio that predicts migration cost, the ≥ 70% adoption target at month 12, and the assumption that twelve platform engineers can serve nine hundred.

How to read a record

QuestionThe forcing question: why a decision was needed at all.
ContextThe requirement, the scale and the constraint that make it hard.
DecisionWhat this architecture does, stated so it can be checked.
How it is realised on Google CloudThe concrete mechanism: which service or package, configured how, in which project.
Options weighedChosen, rejected, deferred, or right elsewhere, with the reason for each.
ConsequencesWhat the choice buys and what it costs, both kept visible.
Choose differently whenThe conditions that would flip the decision for your system.
Why it holds up over timeWhat keeps the decision right as scale, staff and technology change.
LessonThe principle that transfers beyond this platform.

Decision map

The two planes 2

Why generation and enforcement are separate machinery, and where each one binds.

ADR-05Guardrails are enforced at the runtime, never inside the templates that generate components ADR-06One policy source, two evaluation points; fail closed on new admissions and open on running workloads

Intent and reconciliation 3

Where truth about what should exist lives, and how the world is moved towards it.

ADR-01Intent lives in the team's repository; the portal writes it and owns nothing ADR-02Provision by reconciling declared intent, not by calling the cloud from the portal ADR-04Quota, budget and data classification are checked at admission, and a rejection is written for the requester

Knowledge and attribution 4

What the platform knows about the estate, and how every running thing keeps an owner.

ADR-09The catalog is a projection, reconciled against the runtime in both directions ADR-10Ownership resolves to a live identity group, and entitlement derives from it ADR-11Owner, cost centre, tier and classification are applied at creation as enforced properties ADR-16Storage is classified by what a loss would cost, and only one band carries RPO 0

Identity, secrets and the control plane 2

Who may do what, and the fact that the platform is the most privileged thing in the estate.

ADR-08Exceptions are named, approved by someone else, expiring and published ADR-15Workload identity everywhere, and the control plane is held to the controls it enforces

The runtime and the fleet 2

The tenancy boundary, and recovery that does not depend on the machinery that broke.

ADR-13Rollback does not depend on the pipeline that produced the deploy ADR-14Namespace per component in shared clusters, with staged fleet upgrades and a canary component per path

Platform as a product 3

The decisions that only make sense if teams are allowed to say no.

ADR-03Components track their golden-path template by default, and forking is a recorded, supported choice ADR-07A thin abstraction with strong defaults, and an escape hatch that is a designed path ADR-12The API is primary, and no platform component sits in the critical path of running production

Technology by capability

The platform is built on Microsoft Azure with open-source platform components running on it. Azure was chosen for rotation — the four use cases before this one ran on Google Cloud and AWS — and because an internal developer platform's two hardest questions, who is entitled to provision what and where the isolation boundary sits, map onto Entra entitlements and the management-group hierarchy rather than having to be invented on top of a flat account model. Everything in the requirement document outside its first section is vendor-neutral, and the table below is where the cloud is actually chosen.

Open source This design
CapabilityChoiceOriginCredible alternativeWhy this oneRecord
Developer portal Backstage, self-hosted on the control-plane AKS cluster Open source A bespoke portal, or a commercial IDP product The portal is a client of the platform API (ADR-12), so its replaceability matters more than its features. Backstage supplies the catalog model and plugin surface without owning any truth. ADR-12
Intent and source of truth GitHub Enterprise repositories owned by product teams Existing A platform-owned configuration database Review, history, blame and revert for infrastructure then use the tooling every engineer already has, and the platform's own stores become rebuildable projections. ADR-01
Infrastructure reconciliation Terraform modules from an internal registry, run by a pool on AKS with workload identity, state in Azure Storage with locking Open source on Azure Crossplane compositions reconciled in-cluster; Bicep with deployment stacks A mature module ecosystem and an explicit plan step the platform can gate on, against a state object that can be backed up and locked. Crossplane remains the natural successor if resource kinds become more platform-specific than cloud-specific. ADR-02
Workload reconciliation Argo CD, sharded by team, one instance per cluster Open source Flux; a push-based deploy step in the pipeline Pull-based reconciliation keeps the deploy path alive when the pipeline is not, and makes drift in the cluster a detected event rather than an assumption. ADR-13
Policy authoring and evaluation Policy-as-code compiled to a signed OCI bundle in ACR, evaluated by admitting webhooks in every cluster and by the pipeline evaluator Open source on Azure Azure Policy for Kubernetes alone; a hosted policy service called at admission One artefact drives both evaluation points, and a locally cached bundle removes a central service from the critical path of every admission. Azure Policy remains the landing zone's floor beneath it. ADR-06
Build plane GitHub Actions with ephemeral self-hosted runners on AKS, reusable workflows consumed by reference Existing + Azure Azure Pipelines; per-team runners Keeping the pipeline a referenced artefact rather than a copied file is what makes a fix shippable once; ephemeral runners keep build identity scoped to one component. ADR-03
Artefact registry and supply chain Azure Container Registry, geo-replicated, with signing and provenance attestations Azure A self-hosted registry; a third-party artefact platform The registry is also where the policy bundle lives, so one trust story and one replication story cover both the images and the controls that judge them. ADR-16
Runtime Shared AKS clusters, namespace per component, split by environment and subscription Azure Cluster per team; Azure Container Apps for the stateless golden path A twelve-person platform team cannot operate 140 clusters. The namespace boundary is cheap and the cluster upgrade is not, which is the trade stated openly in ADR-14. ADR-14
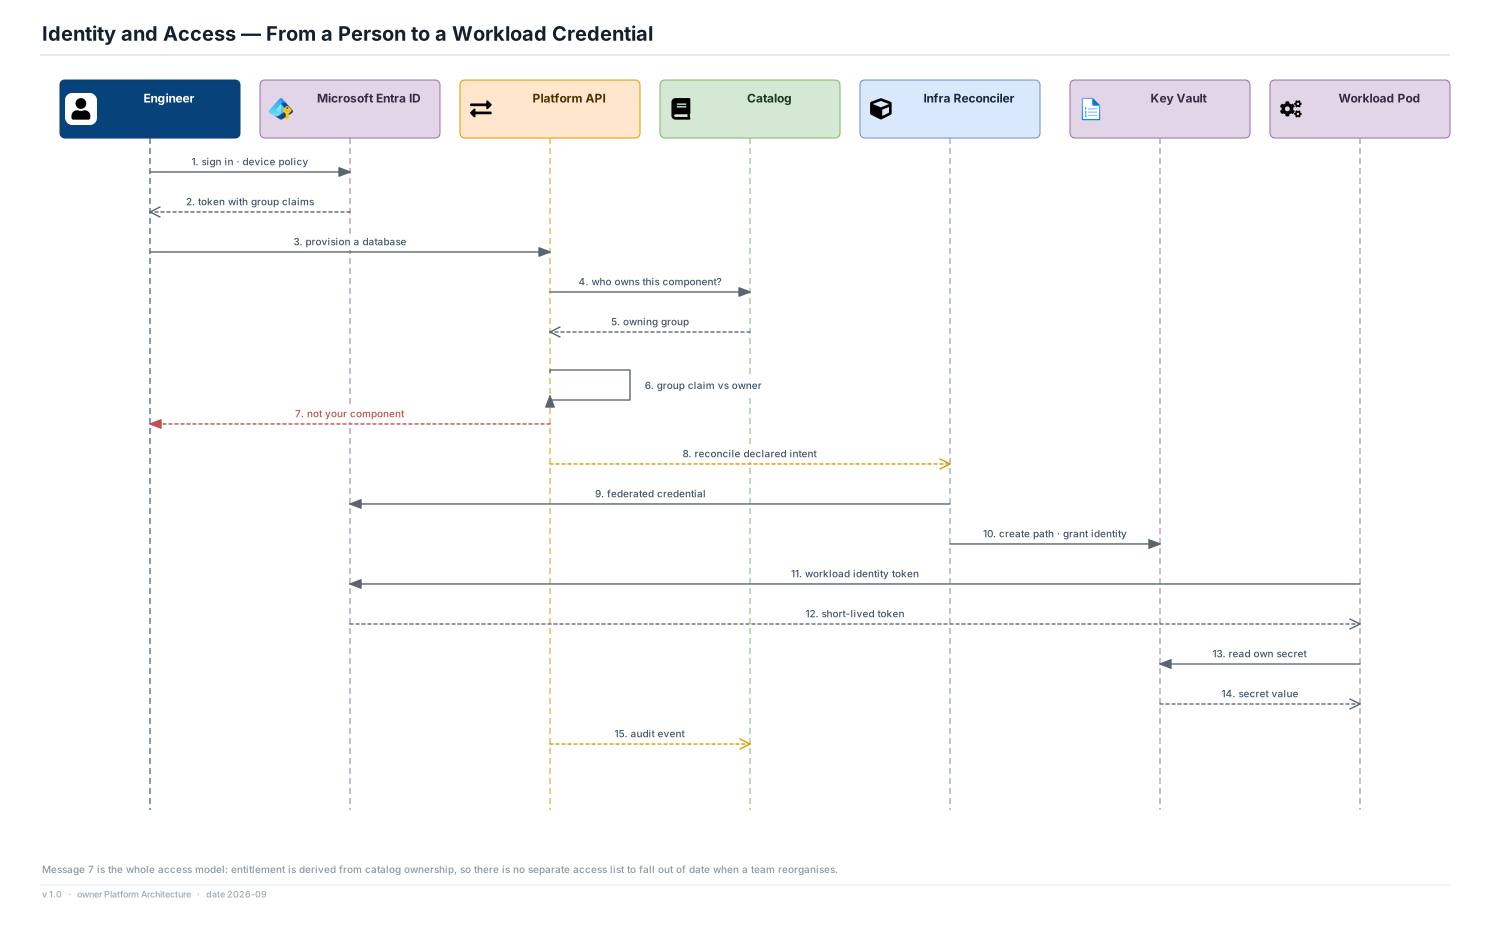
Identity and entitlement Microsoft Entra ID groups, Conditional Access, and workload identity federation Azure A platform-local role model synchronised from the directory Entitlement is derived from catalog ownership resolved against live groups, so there is no second access list to fall out of date when a team reorganises. ADR-10
Secrets Azure Key Vault, paths created by the platform and bound to workload identities Azure A self-hosted secret manager; sealed secrets in the repository The platform grants access to a path and never reads or holds secret material, which keeps plaintext out of the catalog, the portal and every pipeline log. ADR-15
Catalog store Azure Database for PostgreSQL Flexible Server, zone redundant Azure A graph database; the portal's own storage The catalog is a projection with a four-hour RTO (ADR-09); a well-understood relational store with recursive queries covers 9,000 relations without adding an engine to operate. ADR-09
Metrics and insight Azure Data Explorer for DORA, adoption, drift and cost facts Azure Log Analytics alone; a warehouse The questions are time-series and high-cardinality — per team, per path, per component, over three years — and they are asked interactively in reviews. ADR-12
Telemetry OpenTelemetry collectors into Azure Monitor, Managed Prometheus and Managed Grafana Azure + open source A self-hosted observability stack The golden path wires a component's observability at scaffold time; the value is in the wiring being automatic, not in owning the backend. ADR-11
Audit evidence Append-only blob storage with immutability policy and legal hold, separate from operational stores Azure Audit rows in the catalog database The platform's own operators are in scope as a threat; the audit store is the one place they cannot write, which is only true if it is not a table they administer. ADR-16
Cost attribution Azure Cost Management daily exports, joined to catalog ownership Azure A third-party FinOps platform Attribution is applied at creation as tags (ADR-11), so the export needs no reconciliation step — the join is already correct when the data arrives. ADR-11

The decisions, and the alternatives that lost

The two planesWhy generation and enforcement are separate machinery, and where each one binds.

ADR-05

Guardrails are enforced at the runtime, never inside the templates that generate components

Accepted

Is a control something a golden path produces, or something the runtime insists on?

Context
The natural build puts the controls in the template: the pipeline that scans the image, the manifest with the right security context, the module with the right network rules. One artefact, one review, one place to change things — and on day one every component is generated from it and every component is compliant. The failure arrives about nine months later. A team forks the template to do something reasonable it does not support. Another deploys a vendor Helm chart that was never scaffolded. A third pins an old version because the new one broke their build. None of these is misbehaviour; each is the normal cost of a platform real teams use. But each silently removes the controls along with the template, and the platform cannot know, because the only evidence a control was ever in force was that a template produced it. The estate's compliance figure is now a statement about how components were created, not how they are running.
Decision
Enforcement is a property of the runtime. Guardrails are authored as policy-as-code, versioned and signed independently of templates, and evaluated at admission into the cluster. They apply identically to a component the platform scaffolded and to one that never touched a golden path. No template, fork, portal action or pipeline change can remove a binding control.
How it is realised on Google Cloud
Policy in its own reviewed repository, built into a signed OCI bundle in ACR, pulled and cached by admission webhooks running in every cluster. The minimum binding set: workload identity present and no static cloud credentials; image from a trusted registry with a valid attestation and no unmitigated critical vulnerability; resource requests and limits declared; owner and cost tags present; no unauthenticated ingress for an internal component; storage region appropriate to the declared data class.
Options weighed
  • ChosenEnforce at the runtime, independently of generation: Two artefacts to maintain instead of one, and a compliance figure that describes reality rather than provenance.
  • RejectedEnforce through templates: Simplest on day one and silently wrong by month nine. A fork deletes the control and nothing reports it.
  • RejectedEnforce in the shared pipeline only: Better, and bypassed by any deploy path that does not use the pipeline — which is exactly the population that needs the control.
Consequences
What it buys
  • Coverage is measurable against the running estate: ≥ 99% of production workloads, off-road ones included.
  • The golden path is freed to be judged purely on whether it is good, which is what makes the adoption number meaningful (ADR-12).
  • A control change ships without touching 1,400 repositories.
What it costs
  • Policy and templates must be kept coherent by discipline rather than by being the same file.
  • The runtime becomes a harder dependency: a broken policy bundle can stop every deploy in the fleet (ADR-06).
  • Standing pressure to soften a policy for the loudest team, answered by the exception register rather than by a quiet edit (ADR-08).
Choose differently when
In an organisation where every deploy provably passes one pipeline and no other path exists, pipeline enforcement is equivalent and cheaper. If a future runtime offered no admission interception point at all, enforcement would have to move to the provisioning boundary — and the platform would have to say honestly that it no longer covers what it used to.
Why it holds up over time
This is a statement about where evidence of a control comes from, not about Kubernetes. Any substrate with an admission decision can carry it; any substrate without one forces the question to be answered again, honestly.
LessonA control you can only demonstrate by pointing at how something was created is not a control. Enforce where the thing runs, because that is the only place that is still true a year later.
Shown on views07 08 15 18
ADR-06

One policy source, two evaluation points; fail closed on new admissions and open on running workloads

Accepted

If the unbypassable check happens at admission, what is the point of checking in the pull request — and what happens when the evaluator is unavailable?

Context
Admission is the right place to be binding and the worst place to be informative: the verdict arrives on a Friday afternoon, after the build, in a message written for a platform engineer. Checking in the pull request is fast, teachable and trivially bypassed. Doing both is obviously right and introduces the failure that destroys trust faster than having no pull-request check at all — a control that passes CI and fails at admission. The availability question is the same decision viewed from the other side: a policy evaluator that fails closed on everything can evict a healthy production estate, and one that fails open admits unevaluated change.
Decision
Both evaluation points are driven from one signed policy bundle. Advisory evaluation in the pull request and pipeline exists to explain and to be useful; binding evaluation at admission exists to be unbypassable. A divergence between the two is defined as a platform defect and instrumented as such. When the evaluator cannot reach a current bundle it uses the last known good one; when it cannot evaluate at all it fails closed for new and changed admissions and open for already-running workloads.
How it is realised on Google Cloud
Signed bundle in ACR, pulled and cached locally by three webhook replicas per cluster and by the pipeline evaluator, so evaluation never requires a call to a central service on the deploy path. Admission budget ≤ 250 ms p99. The CI-pass-then-admission-fail rate is a first-class metric in view 18.
Options weighed
  • ChosenOne source, advisory plus binding, asymmetric failure mode: Fast feedback and an unbypassable floor, at the price of a divergence class that must be watched rather than assumed away.
  • RejectedBinding only: Unbypassable and hostile. Engineers meet every control for the first time at the worst moment, and route around the platform to avoid it.
  • RejectedSeparate policy definitions for CI and admission: Two truths about one control. They diverge within a quarter and nobody can say which is authoritative.
  • RejectedFail closed on everything, including running workloads: Turns a platform outage into a production outage, which violates the rule that the platform is never on the critical path of running production (ADR-12).
Consequences
What it buys
  • Engineers meet a control in the pull request, where it can teach, and the floor still holds at admission.
  • A cached local bundle means a control-plane outage degrades authoring, not enforcement.
  • The asymmetric failure mode is explicit, so nobody has to guess what happens during an incident.
What it costs
  • The admission webhook is now in the path of every workload admission across the fleet, with the availability obligation that implies (≥ 99.95%).
  • A bad policy bundle is a fleet-wide incident; publishing is staged and reversible for that reason.
  • Keeping advisory and binding verdicts identical is continuous work, not a property that holds by itself.
Choose differently when
If divergence between the two points proved impossible to eliminate — different inputs available at different stages, say — the honest response is to narrow the advisory set to the checks that can be evaluated identically, rather than keep a check that lies. If admission latency could not be held under budget, evaluation would have to move to a pre-admission controller with a reconciliation sweep, accepting a window of unevaluated state.
Why it holds up over time
Local evaluation from a signed, distributed artefact is how policy scales anywhere, because it removes a network call from the critical path and removes a central service from the blast radius. That outlives any particular engine.
LessonTwo checks are only better than one if they can never disagree. The moment they can, the friendly one stops being believed and the strict one becomes the only one anybody reads.
Shown on views02 13 15 18

Intent and reconciliationWhere truth about what should exist lives, and how the world is moved towards it.

ADR-01

Intent lives in the team's repository; the portal writes it and owns nothing

Accepted

When an engineer asks the platform for something, where does the record of what they asked for live?

Context
The obvious design stores the request in the platform's own database: the portal is a form, the database is the system of record, and the platform reconciles the world towards its own rows. It is simple, it gives synchronous feedback, and it quietly makes the platform the owner of every team's configuration. The consequences arrive later. A team cannot review a change to their own infrastructure in the same place they review their code. A platform outage becomes an outage of the ability to describe anything. Restoring the platform's database restores somebody else's intent from a backup they never saw. And the one artefact that should be readable, diffable and blameable by the team who owns it is inside a system they cannot query.
Decision
The catalog descriptor, the deployment intent and the infrastructure intent are files in the component's own repository. The platform's surfaces — portal, CLI, API — write those files, through a commit or a pull request, and then stop. The platform's own stores hold projections, provisioning state and evidence, never the declaration of what should exist.
How it is realised on Google Cloud
A scaffolded repository contains `catalog-info.yaml`, a deployment manifest directory reconciled by Argo CD, and a Terraform intent file consumed by the infrastructure reconciler. The platform API commits to those paths using a GitHub App installation scoped to the component's repository. Portal actions that change infrastructure produce a pull request, not a write.
Options weighed
  • ChosenIntent in the team's repository, platform writes and reconciles: The team can read, review, diff and revert everything about their own component in one place, and the platform can be rebuilt without asking anyone what they had.
  • RejectedIntent in the platform's database, repository holds only code: Makes the platform the owner of 140 teams' configuration and its backup the authority on their infrastructure. Also turns every audit question into a platform query.
  • RejectedBoth, synchronised: Two sources of truth and a reconciliation loop between them. The interesting question becomes which side wins, and the honest answer is that it depends on the bug.
Consequences
What it buys
  • Review, history, blame and revert for infrastructure use the tooling every engineer already knows.
  • The platform's catalog becomes a rebuildable projection (ADR-09), which is what lets it carry a four-hour RTO instead of a zero-loss obligation.
  • An audit answer — what was this component allowed to be, on that date — is a Git history question rather than a platform database restore.
What it costs
  • Every platform action is asynchronous from the engineer's point of view: submitted, converging, converged.
  • The platform depends on the availability of the source control system for authoring, and must degrade clearly when it is unavailable.
  • Bulk changes across 1,400 repositories become 1,400 pull requests, which is the migration cost ADR-03 has to carry.
Choose differently when
If the organisation moved to a monorepo with a single reviewed configuration tree, the repository boundary would stop being the team boundary and the decision would need restating — the principle survives, the file layout does not. If source control were unavailable often enough to block authoring, a durable write-ahead queue in front of the commit would be the first concession, not a move of truth.
Why it holds up over time
Nothing in this decision names Git, GitHub or Terraform. It says that the description of a system belongs to the team that owns the system, and that the platform is a mechanism rather than an owner. That survives a change of source control, of cloud, and of the platform team.
LessonWhoever holds the source of truth owns the thing. If a platform holds the description of every team's system, it has quietly taken ownership of all of them, and it will be asked to act like an owner on the worst day.
Shown on views02 07 10 11
ADR-02

Provision by reconciling declared intent, not by calling the cloud from the portal

Accepted

Does a provisioning request execute an imperative sequence of cloud API calls, or declare a desired state that a controller converges on?

Context
An imperative portal is faster to build and immediately satisfying: press the button, watch the resources appear, get an error you can read. It fails in three specific ways at scale. A run that dies halfway leaves a half-built resource set and no record of which half, so somebody reconstructs state by hand. A change made in the cloud console is invisible, because the portal has no opinion about what should exist — only about what it did. And a retry is dangerous rather than boring, because the operation was never idempotent.
Decision
Provisioning requests are written as declarative intent (ADR-01) and reconciled continuously by controllers that hold state and locks. Every apply is idempotent and resumable; drift between declared and actual is detected, reported to the owning team, and either reverted or recorded as an exception.
How it is realised on Google Cloud
Terraform modules from a versioned internal registry, executed by a runner pool on AKS with workload identity, against state in an Azure Storage account with locking. Drift detection re-plans on a schedule and on resource-graph change events, with a target reconciliation lag of ≤ 5 minutes p95.
Options weighed
  • ChosenDeclarative intent, continuous reconciliation: Partial failures resume, console edits are caught, retries are safe, and the desired state is reviewable.
  • RejectedImperative calls from the portal, with a job record: Fast and satisfying until the first mid-run failure, after which the platform team becomes a state-reconstruction service.
  • RejectedTicket a specialist, who does it carefully: The 19-day baseline. Correct, auditable, and the reason this platform exists.
Consequences
What it buys
  • A partially failed provision is resumed from the same declaration rather than reconstructed.
  • Out-of-band changes become detectable events instead of permanent invisible divergence.
  • The same mechanism serves creation, change and de-provisioning, so there is one path to operate rather than three.
What it costs
  • Latency: an engineer sees 'converging' rather than 'created', and the 12-minute p95 target has to be defended.
  • A stuck reconciliation is harder for a non-specialist to debug than a failed API call, so the platform must explain convergence state in the engineer's terms.
  • State becomes the most dangerous object in the estate, which is why it carries RPO 0 and an exercised restore (ADR-16).
Choose differently when
For a genuinely trivial resource kind with no dependents — a DNS record, say — an imperative path is defensible and the indirection buys nothing. If the estate were small enough that drift never happened and a human could reconstruct any failure in ten minutes, this machinery would be overhead.
Why it holds up over time
Reconciliation towards a declaration is the same idea whether the controller is Terraform, Crossplane, an operator or something not yet written, and whether the target is Azure or not. The decision constrains the shape of the system, not its tools.
LessonThe difference between a portal and a platform is what happens on the failure. A portal tells you the call failed; a platform already knows what should exist and keeps trying.
Shown on views10 14 16
ADR-04

Quota, budget and data classification are checked at admission, and a rejection is written for the requester

Accepted

When a request cannot be satisfied, when does the requester find out, and in whose language?

Context
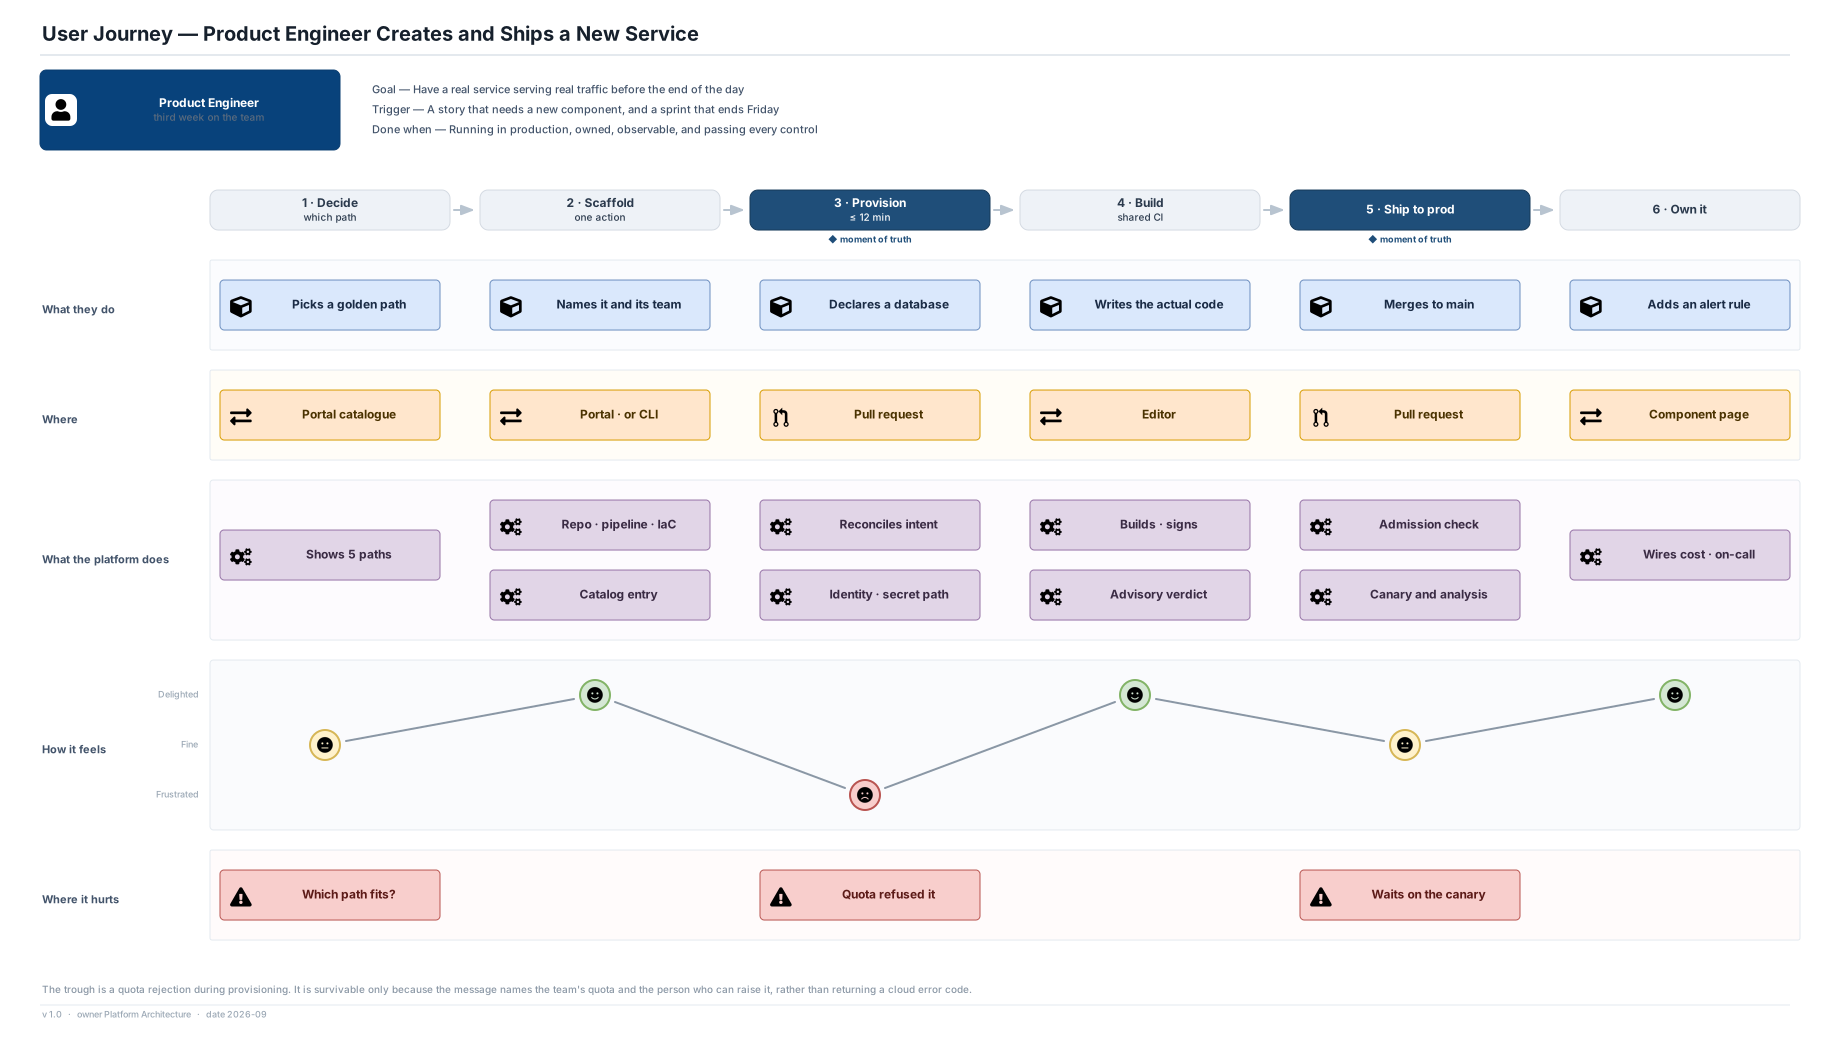
Cloud limits are real and arrive as provider errors halfway through an apply: a subscription quota, a regional capacity limit, a policy assignment the landing zone set. An engineer who meets one of these mid-provision has a half-built resource set and an error message written for a cloud operator. That moment is the trough of the journey in view 04, and it is where a self-service platform loses people back to tickets — not because the answer was no, but because the answer was unintelligible.
Decision
Quota, budget and data-classification checks run at admission, before any resource is created. A rejection names the constraint in the team's terms — which quota, how much is in use, who can raise it — and the request is never partially executed. Classification determines permitted regions and storage, and is checked against the declared data class rather than inferred.
How it is realised on Google Cloud
Admission checks run in the pull-request evaluation and again in the reconciler before plan. Quota state is tracked per team per environment; subscription headroom is monitored continuously so that a provider limit is anticipated rather than discovered.
Options weighed
  • ChosenCheck at admission, reject with an actionable message: Costs a quota-tracking system the platform has to keep accurate, and buys the survivability of the worst moment in the primary journey.
  • RejectedAttempt and surface the provider error: Cheap to build. Converts a self-service platform into a ticket generator at exactly the moment the engineer has committed.
  • RejectedPre-provision generous quota and hope: Works until it does not, and hides the cost signal that the budget check exists to provide.
Consequences
What it buys
  • No partially created resource sets from a foreseeable limit.
  • Budget enforcement happens before spend rather than in a monthly report.
  • An engineer can resolve their own rejection, which is what the ≥ 60% self-resolution target in view 18 measures.
What it costs
  • The platform must model quota accurately enough to be trusted, and a wrong rejection is worse than none.
  • Tracking headroom across subscriptions is ongoing work that grows with the estate.
Choose differently when
If provider quota errors became rare and cheap to recover from, attempt-and-report would be defensible. If the estate were small enough that one subscription served everything, headroom tracking would be a dashboard rather than a control.
Why it holds up over time
Every platform that hands out constrained resources eventually learns that the refusal is part of the product. That is independent of cloud, quota model and era.
LessonDesign the rejection as carefully as the success path. Users forgive a no; they do not forgive a no they cannot act on.
Shown on views04 14

Knowledge and attributionWhat the platform knows about the estate, and how every running thing keeps an owner.

ADR-09

The catalog is a projection, reconciled against the runtime in both directions

Accepted

Is the platform's picture of the estate built from what teams declared, or from what is actually running?

Context
A catalog built from declarations is intentional, reviewable and always somewhat wrong, because reality drifts. One discovered from the runtime is always accurate about the present and cannot express ownership, intent, or anything not yet deployed. Holding both forces a rule about who wins when they disagree, and that rule is an architectural decision rather than a data-quality preference: it decides whether an undeclared running workload is an error or simply a fact.
Decision
The catalog is a projection over declared intent and observed runtime state, rebuildable from both. Divergence is reported in both directions — a declared component with nothing running, and a running workload with no catalog entry — and neither is silently resolved. Declaration wins for ownership and intent; observation wins for what exists now.
How it is realised on Google Cloud
Descriptor ingestion is webhook-driven with a periodic full reconcile as the backstop. A runtime reconciler reads cluster state and the Azure resource graph. Catalog freshness target ≤ 10 minutes p95; RPO 15 minutes, RTO 4 hours, because it can be rebuilt.
Options weighed
  • ChosenProjection over both, divergence reported: Costs a reconciliation loop and a divergence backlog somebody has to work. Buys a catalog that is honest about being wrong.
  • RejectedDeclaration only: Cannot see the shadow estate, which is the metric the platform is judged on.
  • RejectedDiscovery only: Accurate and ownerless. Cannot answer the question the catalog exists to answer.
Consequences
What it buys
  • Off-road components appear in the estate picture, which is what makes ≥ 99% control coverage a measurable claim.
  • The catalog's rebuildability lets it sit in the projection tier of the storage model with an RTO rather than RPO 0.
  • Catalog accuracy becomes an SLO with a number, not an aspiration.
What it costs
  • A standing divergence backlog that will never be empty and must not be allowed to become noise.
  • Owner lookup during reconciliation is the one place the catalog sits in a critical path; it is cached and degrades to last-known-good.
Choose differently when
If ownership could be inferred reliably from runtime metadata alone — enforced at creation and never editable afterwards — discovery-only would become viable and the declaration path could shrink to intent. That is close to what ADR-11 aims at, and this decision would deserve revisiting once attribution is provably complete.
Why it holds up over time
Declared versus observed is a permanent tension in any inventory system. Naming the rule for who wins, per field rather than per system, is what keeps it from being relitigated every time the two disagree.
LessonAn inventory that can only be right is an inventory that lies. Build the one that can say where it disagrees with reality.
Shown on views02 10 11 12
ADR-10

Ownership resolves to a live identity group, and entitlement derives from it

Accepted

How does the platform know who may act on a component, and what happens when that answer goes stale?

Context
The usual design keeps an access list beside the component: who can deploy, who can provision, who can read the secrets. It is correct on the day it is written and decays from then on, because teams reorganise and people move and nobody remembers the platform's list. Meanwhile the organisation already maintains an accurate, audited answer to the same question in its identity provider, updated by joiner-mover-leaver processes that exist whether the platform uses them or not.
Decision
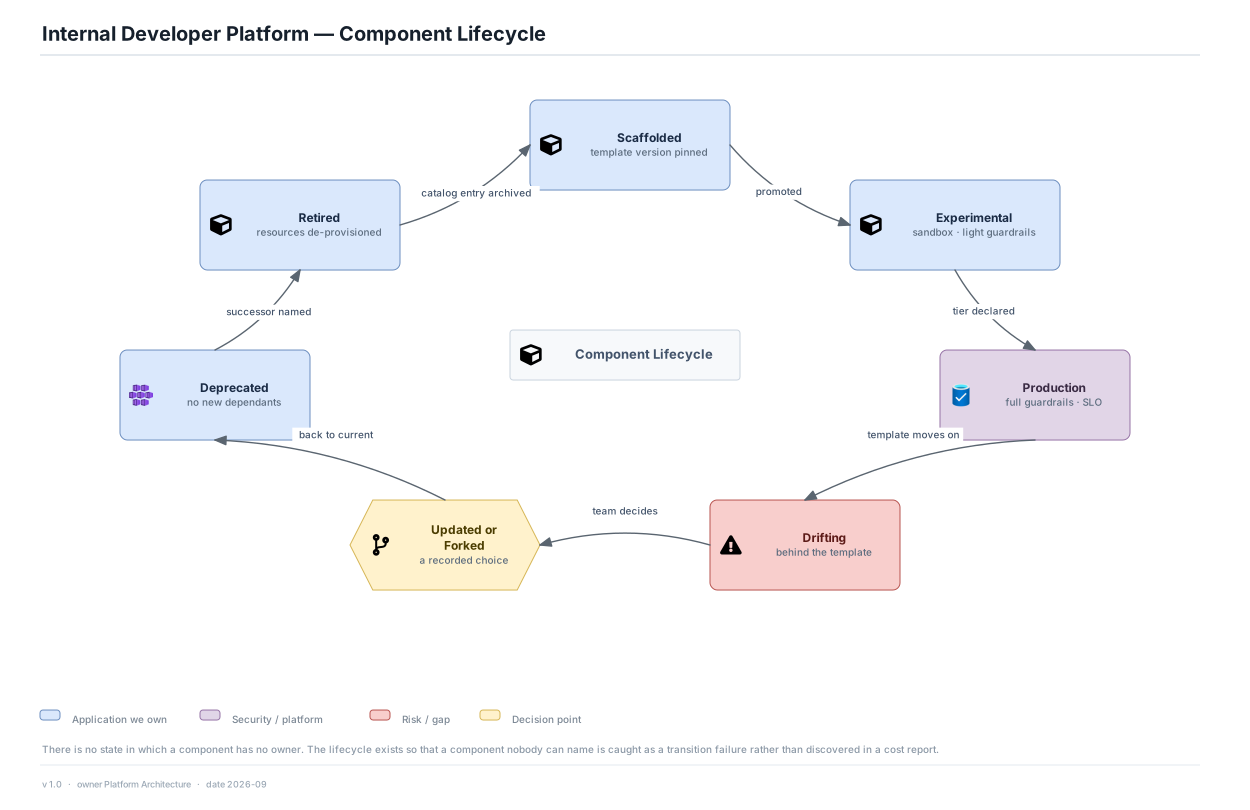
A component's owning team resolves to an identity group with live membership. Entitlement to deploy, provision, read secrets and grant access is derived from that ownership rather than from a separate list. A component whose owning group is empty or deleted is an incident: it is quarantined, reported and reclaimed on a declared schedule rather than left running unattributed.
How it is realised on Google Cloud
`team.entra_group_id` is unique and required; the platform API resolves the caller's group claims against catalog ownership on every request. Orphan detection runs continuously. Bulk re-attribution is supported for reorganisations, and ownership history is retained.
Options weighed
  • ChosenDerive entitlement from catalog ownership against live groups: One place to be wrong instead of two, and the place that is already maintained.
  • RejectedA platform-local access list per component: Accurate on creation day. A permanent, silently decaying second source of truth thereafter.
  • RejectedCloud-native role assignments per resource: Correct at the resource layer and unusable at the component layer, where the question is actually asked.
Consequences
What it buys
  • A reorganisation moves entitlements with the components, in one operation, with history.
  • There is no separate access review for the platform: reviewing group membership reviews platform access.
  • Orphaned components are caught as a transition failure rather than discovered in a cost report.
What it costs
  • A wrong owner in the catalog is now an access-control fault, not a metadata fault, which raises the stakes on descriptor quality.
  • The platform inherits the identity provider's latency and availability on the authorisation path, so group claims are cached with a short lifetime.
  • Quarantining an orphan is an unpopular act that must be preceded by notice and a grace period.
Choose differently when
In an organisation whose identity groups do not reflect engineering teams — where the directory models cost centres or legal entities instead — deriving entitlement from it would be worse than a maintained list. The precondition is explicit, and it is an assumption rather than a fact.
Why it holds up over time
Deriving authorisation from a single, independently maintained ownership fact is a pattern that survives any identity technology. The failure it prevents — a second list nobody updates — is as old as access control.
LessonEvery access list you maintain is a list you will be wrong about. Derive authority from a fact somebody else is already obliged to keep true.
Shown on views12 19 21
ADR-11

Owner, cost centre, tier and classification are applied at creation as enforced properties

Accepted

When does a resource acquire the metadata that makes it attributable?

Context
Attribution added afterwards is never complete. A tagging campaign reaches the resources somebody remembered, an untagged resource has no owner to ask, and the gap grows faster than the campaign closes it. The FinOps reconciliation spreadsheet exists because attribution was optional at the moment of creation. The same is true of data classification, which decides permitted regions and storage, and of tier, which decides which guardrails and which SLO expectations apply.
Decision
Owner, cost centre, lifecycle state, tier and data classification are applied to every provisioned resource and every deployed workload at creation, as enforced properties rather than conventions. A workload without them is not admitted; a resource without them is not created. Cost is shown on the component page at the point of change, not only in a monthly report.
How it is realised on Google Cloud
Tags applied by the provisioning modules and required by binding admission policy, sourced from the catalog descriptor. Cost Management daily exports join directly to catalog ownership with no reconciliation step, because the join key was correct when the data was produced.
Options weighed
  • ChosenEnforced at creation: Makes an unattributable resource impossible to create rather than expensive to find later.
  • RejectedPeriodic tagging campaigns and reports: Permanently behind, and the untagged residue is exactly the population nobody can identify.
  • RejectedInfer ownership from usage patterns: Plausible, wrong occasionally, and wrong in a way that assigns somebody else's bill.
Consequences
What it buys
  • Cost attribution needs no reconciliation exercise, and idle-resource reclamation has an owner to notify.
  • Data classification is available to policy at admission, so region and storage rules can be enforced rather than audited.
  • The tier drives which guardrails apply, which is what makes an experimental sandbox defensible.
What it costs
  • Every provisioning path must carry the metadata, including paths added later — a standing discipline on the platform team.
  • A team that genuinely does not yet know its cost centre is blocked at creation, which needs a sane default rather than an exception.
Choose differently when
If the cloud provider offered reliable ownership inference from its own control-plane records, the enforcement could relax to verification. It does not, and inferred ownership is the specific failure mode this decision exists to prevent.
Why it holds up over time
Attribution at the point of creation is the only form of attribution that stays complete, on any platform and in any era. Retrofitting it has never worked anywhere.
LessonMetadata that is optional at creation is metadata you do not have. Make the thing impossible to create without it, or plan to spend years asking.
Shown on views14 18 19
ADR-16

Storage is classified by what a loss would cost, and only one band carries RPO 0

Accepted

Which of the platform's stores must never lose data, and which are allowed to be rebuilt?

Context
The default answer — back everything up, aim for zero loss everywhere — is expensive, and worse, it hides which stores actually matter. A platform holds several very different kinds of data: declarations it does not own, state it cannot reconstruct, projections it can rebuild in an afternoon, and working data whose loss nobody would notice. Treating them alike means the genuinely irreplaceable object gets the same attention as a pipeline log.
Decision
Four bands. Truth owned by teams lives in their repositories and is not the platform's to protect. Platform-owned truth — provisioning state, audit evidence, signed artefacts and policy bundles — carries RPO 0 with an exercised restore. Projections — catalog, dependency graph, insight stores — carry an RTO and are rebuildable from truth and the runtime. Working data is explicitly not backed up, and saying so is what stops it acquiring a policy nobody needs. One artefact, signed and attested, is promoted unchanged through every environment, so what was tested is what runs.
How it is realised on Google Cloud
Terraform state: RPO 0, RTO ≤ 1 hour, versioned and locked. Audit: RPO 0, immutable with legal hold, unwritable by platform operators. Catalog: RPO 15 minutes, RTO 4 hours. Portal: RPO 24 hours. Full control-plane rebuild from source and backup exercised at least twice a year.
Options weighed
  • ChosenFour bands by cost of loss, with an exercised restore for the RPO 0 band: Concentrates protection where reconstruction is impossible, and makes the rest legibly cheap.
  • RejectedUniform backup and RPO 0 everywhere: Expensive, and obscures which object is the one that must never be lost.
  • RejectedBack up the databases, treat everything else as disposable: Loses Terraform state and audit evidence, which are the two things a database backup does not cover.
Consequences
What it buys
  • The dangerous object is named: provisioning state, whose loss means the platform no longer knows what it created.
  • The catalog's rebuildability is a designed property that keeps a large store out of the zero-loss tier.
  • A restore that is exercised twice a year is a restore that works.
What it costs
  • Rebuild paths for the projection tier must actually be maintained and tested, or the RTO is fiction.
  • Immutable audit storage with legal hold is a cost that grows for seven years and cannot be trimmed retrospectively.
Choose differently when
If the catalog acquired data that exists nowhere else — a manually curated field, a human annotation — it would leave the projection tier that day. The classification has to be re-examined whenever a store gains a write that nothing else can reproduce.
Why it holds up over time
Classifying storage by reconstructability rather than by technology is a method, not a configuration. It applies unchanged to whatever stores the platform uses in ten years.
LessonAsk of every store: if this vanished tonight, what could we rebuild it from? The ones with no answer are the only ones that need zero-loss protection — and they are usually not the ones with the dashboards.
Shown on views11 17 20

Identity, secrets and the control planeWho may do what, and the fact that the platform is the most privileged thing in the estate.

ADR-08

Exceptions are named, approved by someone else, expiring and published

Accepted

What happens when a binding guardrail blocks something the organisation has decided to do anyway?

Context
Relief always exists. If the architecture does not provide it, it appears as a quiet policy edit for the loudest team, as a permanently disabled check, or as a team routing around the platform entirely. Each of those is worse than an exception, and each is invisible. The question is therefore not whether to allow exceptions but what an exception has to cost in visibility.
Decision
A binding guardrail may be excepted for a named component, by an approver who is not the requester, with a stated reason and a mandatory expiry. Every active exception appears on a standing register that is reported alongside coverage. Expiry and a distinct approver are schema constraints, not process guidance. Authoring a policy, approving an exception to it, and deploying are three separate entitlements.
How it is realised on Google Cloud
`exception` carries `approver_id` (constrained to differ from the requester) and a non-null `expires_at`. Active exceptions are surfaced in the pull request of the component they cover, on the component page, and in the coverage report. Target: ≤ 25 active exceptions, each expiring inside 90 days.
Options weighed
  • ChosenNamed, approved by another, expiring, published: Makes relief legitimate and visible, and makes the accumulation of relief a metric rather than a discovery.
  • RejectedNo exceptions — the control is the control: Sounds strong. Produces quiet policy edits and shadow deployments, which is the same relief with none of the evidence.
  • RejectedPermanent exceptions by request: An exception with no expiry is a policy change made by whoever asked, recorded in the wrong place.
Consequences
What it buys
  • The exception register becomes an honest measure of where policy and reality disagree.
  • A control waived more often than it blocks is visible as a policy defect rather than a security success.
  • Auditors get a complete answer: the control, its coverage, and every documented departure with an owner.
What it costs
  • Expiry means recurring renewal work for genuinely long-lived exceptions, which teams experience as friction.
  • A separate approver requires enough people with the entitlement that approval is not itself a queue.
Choose differently when
For a small number of controls — a hard regulatory floor, for example — no exception path is correct, and the architecture supports declaring a policy unexceptable. The general mechanism is still needed for everything else.
Why it holds up over time
Every enforcement system that lasts grows an exception path. Designing it deliberately, with expiry and attribution, is what separates a control that is trusted from one that is quietly disabled.
LessonIf your control has no legitimate relief valve, you do not have a strong control — you have an unmeasured one, and someone has already routed around it.
Shown on views08 15 20
ADR-15

Workload identity everywhere, and the control plane is held to the controls it enforces

Accepted

What credentials exist in this system, and who guards the thing that guards everything?

Context
The platform can provision, deploy and grant across the entire estate. It is, by construction, the highest-privilege system in the organisation, and it is usually the one exempted from its own controls because its team wrote them. Meanwhile static credentials accumulate wherever a pipeline needs to reach a cloud: in a secret store, in a variable, in a repository, in somebody's notes.
Decision
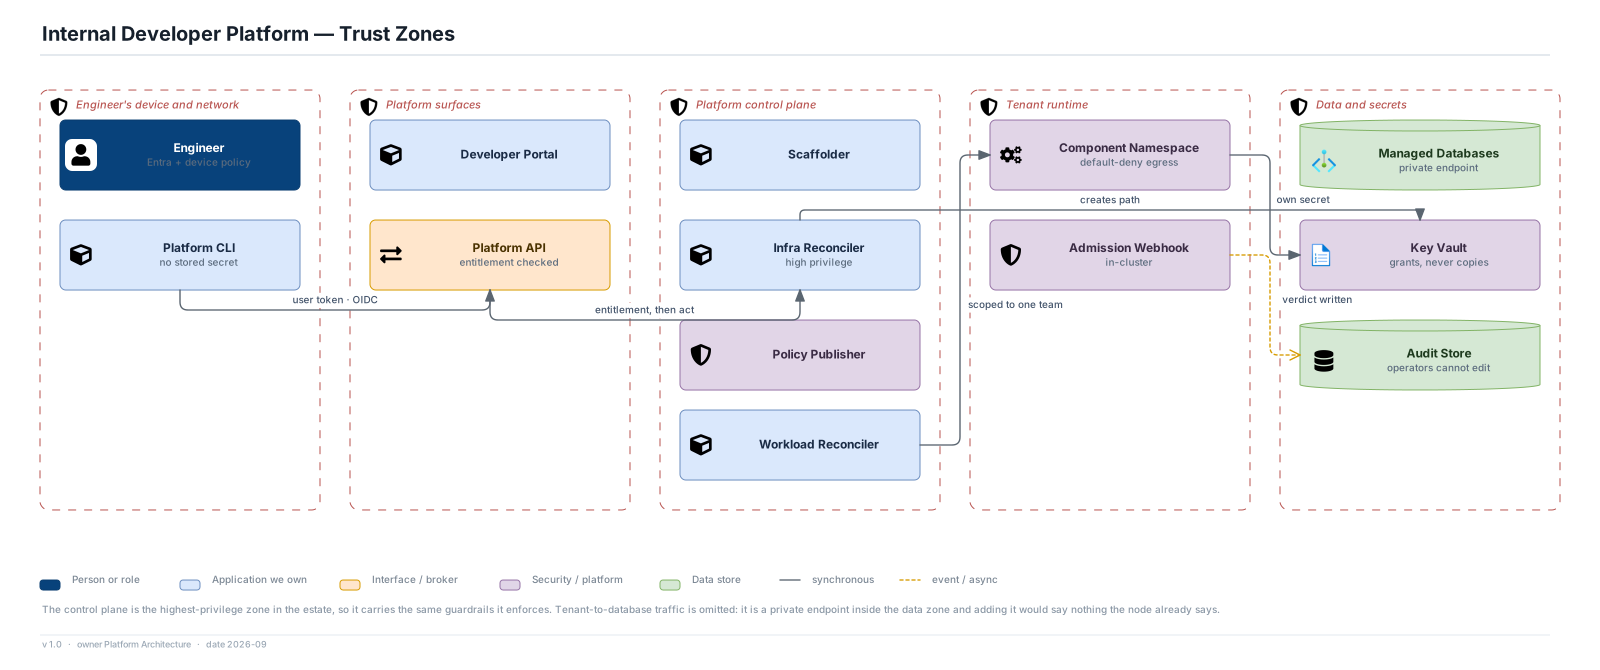
No long-lived static credential exists on any platform path. Workloads, pipeline runs and platform components authenticate by federated workload identity; a pipeline run's privileges are scoped to the component it is building. Secrets are brokered, never held: the platform creates a Key Vault path and binds an identity to it, and never reads secret material. The platform's own components are production systems under the same guardrails, the same change review and the same audit as tenants, and the entitlements to author policy, approve an exception and deploy are held separately.
How it is realised on Google Cloud
Entra workload identity federation for runners and workloads; ephemeral runners so build identity cannot outlive the build. Control-plane components deploy through the same reconciler and pass the same admission policy. Every privileged action — exception granted, policy changed, template published, ownership reassigned — is written to the append-only audit store.
Options weighed
  • ChosenFederated workload identity, brokered secrets, platform under its own controls: Costs the platform team the friction it imposes on others, which is also the mechanism that keeps the friction honest.
  • RejectedA platform service principal with broad rights: One credential that can do anything to anything, and a rotation everybody is afraid of.
  • RejectedPlatform components exempted from admission policy: Exempts the highest-privilege workloads in the estate from the only enforcement point that covers everything.
Consequences
What it buys
  • Nothing to rotate, leak or discover in a repository.
  • Compromising one component's build cannot deploy another team's component.
  • The platform team experiences its own controls, which is the fastest feedback loop on whether they are reasonable.
What it costs
  • Federation setup is per-workload work the platform must automate or it becomes the bottleneck it was built to remove.
  • Holding the control plane to its own policy occasionally blocks the platform team during an incident, and the exception path (ADR-08) is the answer rather than a bypass.
Choose differently when
A legacy system that cannot federate needs a static credential with a short lifetime and a named owner; the architecture should carry that as an explicit, expiring exception rather than pretend the rule is universal.
Why it holds up over time
Short-lived, workload-scoped identity replaced static secrets everywhere it became available, and will not be reversed. Holding the control plane to its own rules is older still.
LessonThe system that enforces the rules is the most valuable target in the estate. Exempting it from its own controls is how you find out.
Shown on views20 21

The runtime and the fleetThe tenancy boundary, and recovery that does not depend on the machinery that broke.

ADR-13

Rollback does not depend on the pipeline that produced the deploy

Accepted

What is the recovery path when the thing that deployed the change is itself the problem?

Context
The convenient rollback is a pipeline run: re-deploy the previous version through the same machinery. It works for the common case and fails at the worst one, because the population of incidents where rollback is needed overlaps heavily with the population where the build plane, the registry pull, or the pipeline's own credentials are implicated. An engineer at 03:00 then has two problems, and the second one has a queue.
Decision
Rollback is a single, always-available operation that reverts the workload reconciler to the previously converged state, using an artefact already present, without requiring a build, a pipeline run or a registry round trip to succeed. Progressive delivery triggers it automatically on a declared signal breach, and a human can invoke it directly from the CLI.
How it is realised on Google Cloud
Argo CD holds the previous desired state; images for the previous revision are already pulled on the nodes or present in the geo-replicated registry. Target ≤ 5 minutes p99 from initiation to serving the previous version. Automated rollback fires on canary analysis breach without waiting for a human.
Options weighed
  • ChosenReconciler-level revert, independent of the pipeline: One more path to keep working and test, and it is the one that has to work on the worst day.
  • RejectedRe-run the pipeline with the previous commit: Couples recovery to the machinery most likely to be involved in the failure, and adds build time to an incident.
  • RejectedForward-fix only: Defensible for some organisations. Not for one where the person on call did not write the change.
Consequences
What it buys
  • Recovery time is bounded by reconciliation, not by build time.
  • The on-call journey in view 06 has an action that works without understanding the failure first.
  • Automated rollback on a canary breach becomes credible, because the mechanism is simple enough to trust unattended.
What it costs
  • The previous artefact must remain available, which constrains registry retention and node image garbage collection.
  • A rollback that reverts intent can conflict with a fix already in flight, so the operation records itself in intent rather than mutating the cluster behind the reconciler's back.
Choose differently when
For a workload with irreversible data migrations, rollback is not a recovery strategy and the golden path for it must say so explicitly rather than offering a button that lies. That is a property of the path, not of the mechanism.
Why it holds up over time
Recovery machinery that shares fate with the failure is a recurring mistake rather than a technology-specific one. Independence of the recovery path outlives every deployment tool.
LessonTest your recovery path against the assumption that the thing you normally use is broken. That is the only case where it matters.
Shown on views06 17
ADR-14

Namespace per component in shared clusters, with staged fleet upgrades and a canary component per path

Accepted

Where does the tenancy boundary sit, and who absorbs the cost of the answer?

Context
Cluster per team is strongly isolated and multiplies fleet operations, upgrade toil and idle capacity by 140 against a twelve-person platform team. Shared clusters are cheap to operate and make every noisy neighbour, every cluster-scoped resource and every upgrade a shared-fate event. The honest question is not which is safer in principle but which failure the organisation can actually staff.
Decision
Namespace per component in shared clusters, separated by environment and by subscription rather than by team, with experimental workloads in a sandbox subscription. Isolation inside a cluster is enforced rather than conventional: required requests and limits, per-namespace quota, default-deny network policy, workload identity per component. Upgrades roll through the fleet in stages with automated tenant smoke checks and abort-and-hold on failure, and each golden path has a canary component that walks the whole path continuously.
How it is realised on Google Cloud
Production and non-production in separate workload subscriptions; uk-south primary with uk-west paired for the platform's own recovery. Three admission webhook replicas per cluster with a locally cached bundle so enforcement survives a control-plane outage.
Options weighed
  • ChosenShared clusters, namespace per component, enforced isolation: Operable by twelve people. Accepts shared fate on upgrades and answers it with staging rather than with more clusters.
  • RejectedCluster per team: Strong isolation the organisation cannot staff. 140 upgrade campaigns and 140 sets of idle capacity.
  • DeferredCluster per data classification or tier: The right answer if a workload appears whose isolation requirement the namespace boundary genuinely cannot meet. Designed for, not built.
Consequences
What it buys
  • A fleet small enough that upgrades are a planned operation rather than a permanent campaign.
  • Idle capacity is shared, which is most of the platform's cost advantage.
  • Enforced limits and default-deny networking make the namespace boundary a control rather than a convention.
What it costs
  • Cluster upgrades are shared-fate events and must be staged, smoke-checked and abortable.
  • A cluster-scoped resource conflict between tenants is possible and has to be policed by policy.
  • The highest-isolation workload in the estate sets the ceiling; if one arrives that the namespace cannot hold, the boundary has to move.
Choose differently when
A regulated workload with a hard physical or tenancy separation requirement flips this immediately for that workload — hence the deferred option rather than a rejected one. A platform team of 40 rather than 12 would also change the arithmetic.
Why it holds up over time
The boundary question — isolation against operability — recurs on every substrate. What this decision fixes is that the answer is chosen by what can be staffed, and that the alternative is designed for rather than argued away.
LessonIsolation you cannot operate is not isolation. Pick the boundary your team can actually maintain, and write down what would move it.
Shown on views16 18

Platform as a productThe decisions that only make sense if teams are allowed to say no.

ADR-03

Components track their golden-path template by default, and forking is a recorded, supported choice

Accepted

After scaffolding, does the generated code belong to the team, to the platform, or to both?

Context
Scaffold-and-forget is the simplest contract and the most expensive one. Within a year the estate holds 1,400 divergent copies of a pipeline, and a security fix in the template reaches none of them. The opposite — the platform owning generated code in the team's repository — makes updates shippable and makes every product repository contain code its owners may not change, which is the fastest way to make a platform resented. The real variable is not who owns the file but whether the platform can tell the difference, and whether the team made the choice deliberately.
Decision
Every scaffolded component declares whether it tracks its template or has forked from it. Tracking components receive automated update pull requests; forked components do not, and their departure is recorded with a stated reason. Drift is measured per component, published to the owning team, and a supported floor is enforced with a published deprecation window. The shared pipeline is consumed by reference rather than copied, so the most change-prone artefact is not part of the fork surface at all.
How it is realised on Google Cloud
`template_version` and `tracks_template` are columns on the component record, populated from the repository descriptor. The update bot opens one pull request per tracking repository. The pipeline is a referenced reusable workflow; forking it is possible and is exactly the act that shows up in the drift report.
Options weighed
  • ChosenTrack by default, fork as a recorded choice, pipeline by reference: Keeps the migration lever for the common case and keeps the exit open, at the cost of pull-request noise in product repositories.
  • RejectedFork always — the code is yours the moment it is generated: Maximum autonomy, and a platform that can never ship anything to its estate again. The end-of-support migration in view 05 becomes 1,400 conversations.
  • RejectedPlatform-managed files teams may not edit: Works until the first legitimate exception, which arrives in week three. Then it is either an exception process or a lie.
Consequences
What it buys
  • A template fix reaches most of the estate as automation rather than as a campaign.
  • The fork ratio becomes a measured number that predicts migration cost — the single most useful planning figure the platform has.
  • Leaving the paved road is legitimate and visible, which keeps adoption honest (ADR-12).
What it costs
  • Automated pull requests into product repositories need organisational consent and careful batching, or they become noise teams filter out.
  • The forked tail absorbs disproportionate platform-team effort — an assumed 16% of components in view 05.
  • Two supported template versions at a time is the practical ceiling for a twelve-person team; more is a commitment that will be broken.
Choose differently when
If the organisation adopted a mandate — every component must be on a current template — tracking could be assumed and the fork machinery would be waste. If automated pull requests proved culturally unacceptable, the fallback is a stronger by-reference boundary: move more of the template into consumed artefacts and generate less.
Why it holds up over time
The distinction between generated-and-owned and consumed-by-reference is older than any of this tooling and will outlive it. What changes is where the line sits, and the architecture is built so that line can move without redesign.
LessonGenerated code is a fork with good manners. Plan for the divergence at the moment you generate it, because the alternative is discovering the divergence when you need it not to exist.
Shown on views05 07 12 19
ADR-07

A thin abstraction with strong defaults, and an escape hatch that is a designed path

Accepted

How much of the underlying runtime should the golden path hide from the engineer who uses it?

Context
The highest abstraction gives the best first day: declare a service, get a service, never learn what a pod is. It leaks at the first incident, which is exactly when the person holding the pager has the least capacity to learn a substrate the platform has spent a year hiding. A thin abstraction costs every engineer the learning and traps nobody. The choice also decides whether the platform can change the substrate later without its tenants noticing — and who is expected to do the migration when it does.
Decision
The golden path presents a thin abstraction with strong, cost-aware defaults: the underlying runtime remains visible and addressable, and the platform supplies the configuration rather than concealing the model. Read access to the substrate for a component's owners is an entitlement-scoped, audited path, not an exception granted during an incident. What the platform hides is toil, not the model.
How it is realised on Google Cloud
Manifests are real and readable in the team's repository. The CLI grants scoped cluster read access derived from catalog ownership, with every access audited. The component page links directly to the runtime objects rather than paraphrasing them.
Options weighed
  • ChosenThin abstraction, strong defaults, designed escape hatch: Costs learning on day one and pays it back at 03:00. Also keeps the platform honest about what it is actually doing.
  • RejectedHigh abstraction that hides the runtime entirely: Best first day, worst incident. And the escape hatch gets built anyway — as an undocumented one, during an outage.
  • RejectedNo abstraction, just documentation and examples: Maximum honesty, no leverage. This is the state the platform was created to improve on.
Consequences
What it buys
  • The on-call journey in view 06 is survivable without a platform engineer.
  • Escape-hatch use is measurable, and a spike in it names the abstraction that is failing.
  • Teams can reason about cost and behaviour because they can see what actually runs.
What it costs
  • Every engineer carries more concepts than the highest-abstraction alternative would require.
  • Substrate migrations are visible to tenants and must be negotiated rather than performed silently.
  • The cognitive-load budget has to be stated and defended, because each golden path will want to add one more concept.
Choose differently when
With a junior-heavy engineering population, a dedicated platform on-call carrying tenant incidents, or a substrate the platform genuinely intends to replace, a higher abstraction becomes the better trade — and the escape hatch becomes the platform team's tool rather than the tenant's. This is the decision most likely to be revisited, and the requirement leaves it explicitly open.
Why it holds up over time
The tension between leverage and comprehensibility does not age. What changes is where the line sits; keeping the substrate addressable means the line can be moved later in either direction without a rewrite.
LessonAn abstraction is a promise about the good days and a debt on the bad ones. Price it at 03:00, not at the demo.
Shown on views03 06 16
ADR-12

The API is primary, and no platform component sits in the critical path of running production

Accepted

What may fail when the platform fails?

Context
A platform that is loved on good days and catastrophic on bad ones does not survive its first outage. The temptation is to make the portal the centre: it holds the session, it brokers the deploy, it proxies the runtime. Every one of those choices puts a convenience component into a path that must stay up when the platform is down. Separately, a capability that exists only in the portal cannot be scripted by the teams that most need it, cannot be tested, and cannot be replaced when the portal is.
Decision
The platform API is the primary surface; the portal and the CLI are clients of it, and a capability reachable only through one of them is a defect. No platform component is a dependency of serving production traffic: deploys, rollbacks and reconciliation continue when the portal is unavailable, and running workloads are never evicted because the platform cannot evaluate them (ADR-06). The platform publishes its own SLOs and error budget to its tenants.
How it is realised on Google Cloud
Portal and catalog read path ≥ 99.5% monthly; admission evaluation ≥ 99.95%; the portal carries RPO 24 hours because it holds no truth. The API is versioned with a published deprecation window, since its consumers include 140 teams' pipelines.
Options weighed
  • ChosenAPI primary, portal non-critical: Costs discipline — every feature must be expressible in the API first — and buys an outage that costs the ability to change rather than the ability to serve.
  • RejectedPortal as the centre, API as an afterthought: Faster to demonstrate. Makes a convenience component a production dependency for 1,400 services.
  • RejectedCLI-first with no portal: Fine for the platform team, poor for discovery. The portal is how someone finds the path in the first place.
Consequences
What it buys
  • A portal outage is an inconvenience with a known blast radius, and can be stated as such in advance.
  • Every capability is scriptable, which is what lets teams automate around the platform rather than through it.
  • The platform can replace its own portal without renegotiating with its tenants.
What it costs
  • Two clients to keep at parity, and a standing temptation to add portal-only behaviour under deadline.
  • A versioned API with a deprecation window is a commitment that constrains the platform's own pace of change.
Choose differently when
If the platform ever needed to sit in a request path — a runtime configuration lookup, say — that component would have to be designed to the availability of the thing it serves, and this decision would be restated for it rather than quietly broken.
Why it holds up over time
Keeping the control plane out of the data path is one of the few architectural rules that has never stopped being right. It survives every technology change because it is a statement about blast radius.
LessonDecide in advance what your outage is allowed to cost. If the answer includes other people's production traffic, you have built a dependency rather than a platform.
Shown on views09 16 18

Every package used, in one table

Eleven terms that carry specific meaning in this package. Several are used loosely in the wider platform-engineering literature; here they are the names of decisions.

PackageWhat it isWhat it does hereConsidered instead
Golden path An opinionated, end-to-end route from empty repository to production for one named kind of workload. A product a team may decline. Its adoption number is meaningful precisely because declining is allowed. A mandated standard, which guarantees coverage and destroys the feedback signal that says whether the path is any good.
Paved road The generation plane — templates, the scaffolder, the shared pipeline, the update bot. Everything the platform offers that a fork can remove. Conflating it with the guardrails, which is the failure this architecture exists to avoid.
Guardrail A control evaluated at admission into the runtime, from a signed policy bundle. Applies to every workload regardless of how it was created. Cannot be declined, only excepted with attribution and an expiry. A check inside a template, which is deleted by the fork that removes the template.
Intent The declaration in a team's repository of what should exist: catalog descriptor, deployment manifests, infrastructure declaration. The system of record. The platform reconciles towards it and never holds an authoritative copy. A row in the platform's database, which makes the platform the owner of every team's configuration.
Projection Anything the platform derives from intent plus observed runtime state — principally the catalog and the insight stores. Rebuildable, which is what lets it carry an RTO instead of a zero-loss obligation. Treating the catalog as truth, after which a catalog outage becomes an estate outage.
Template drift The distance between a component and the current version of the template that generated it. A measured, published per-component figure, and the input that makes a migration plannable. Not measuring it, and discovering the divergence when a security fix needs to reach the estate.
Shadow estate Production components deployed outside the platform's paths. The platform's own competitive metric. Guardrails still cover it; the paved road does not. Treating it as non-compliance, which hides the product failure it actually reports.
Advisory evaluation A policy verdict produced in the pull request and pipeline, from the same bundle as the binding one. Exists to explain and to be fast (≤ 90 s). Carries no authority of its own. A separate ruleset for CI, which diverges from the binding one within a quarter.
Binding evaluation The admission-time verdict, evaluated locally from a cached signed bundle within 250 ms p99. The only unbypassable point, and therefore the only place coverage can honestly be claimed. Trusting the pipeline, which covers only the population that already uses the pipeline.
Exception A named, expiring, separately approved departure from a binding guardrail for one component. The legitimate relief valve, published on a standing register so accumulation is visible. A quiet policy edit for the loudest team, which is the same relief with none of the evidence.
Cognitive load The number of systems, concepts and credentials an engineer must hold to ship on a golden path. A stated, defended budget. Each concept a path adds is a withdrawal the platform must justify. An aspiration in a vision document, which loses every argument against one more useful feature.
Open svg/<view>.svg or drawio/<view>.drawio in draw.io Desktop or at app.diagrams.net to edit. The SVG carries the diagram inside it, so it is both the picture and the source. This folder is self-contained — copy it whole and every link still resolves.