Feature Store · Solution Architecture v1.0 · Amazon Web Services · Data Platform Architecture · 2026-09 · 21 views · 14 architecture decision records
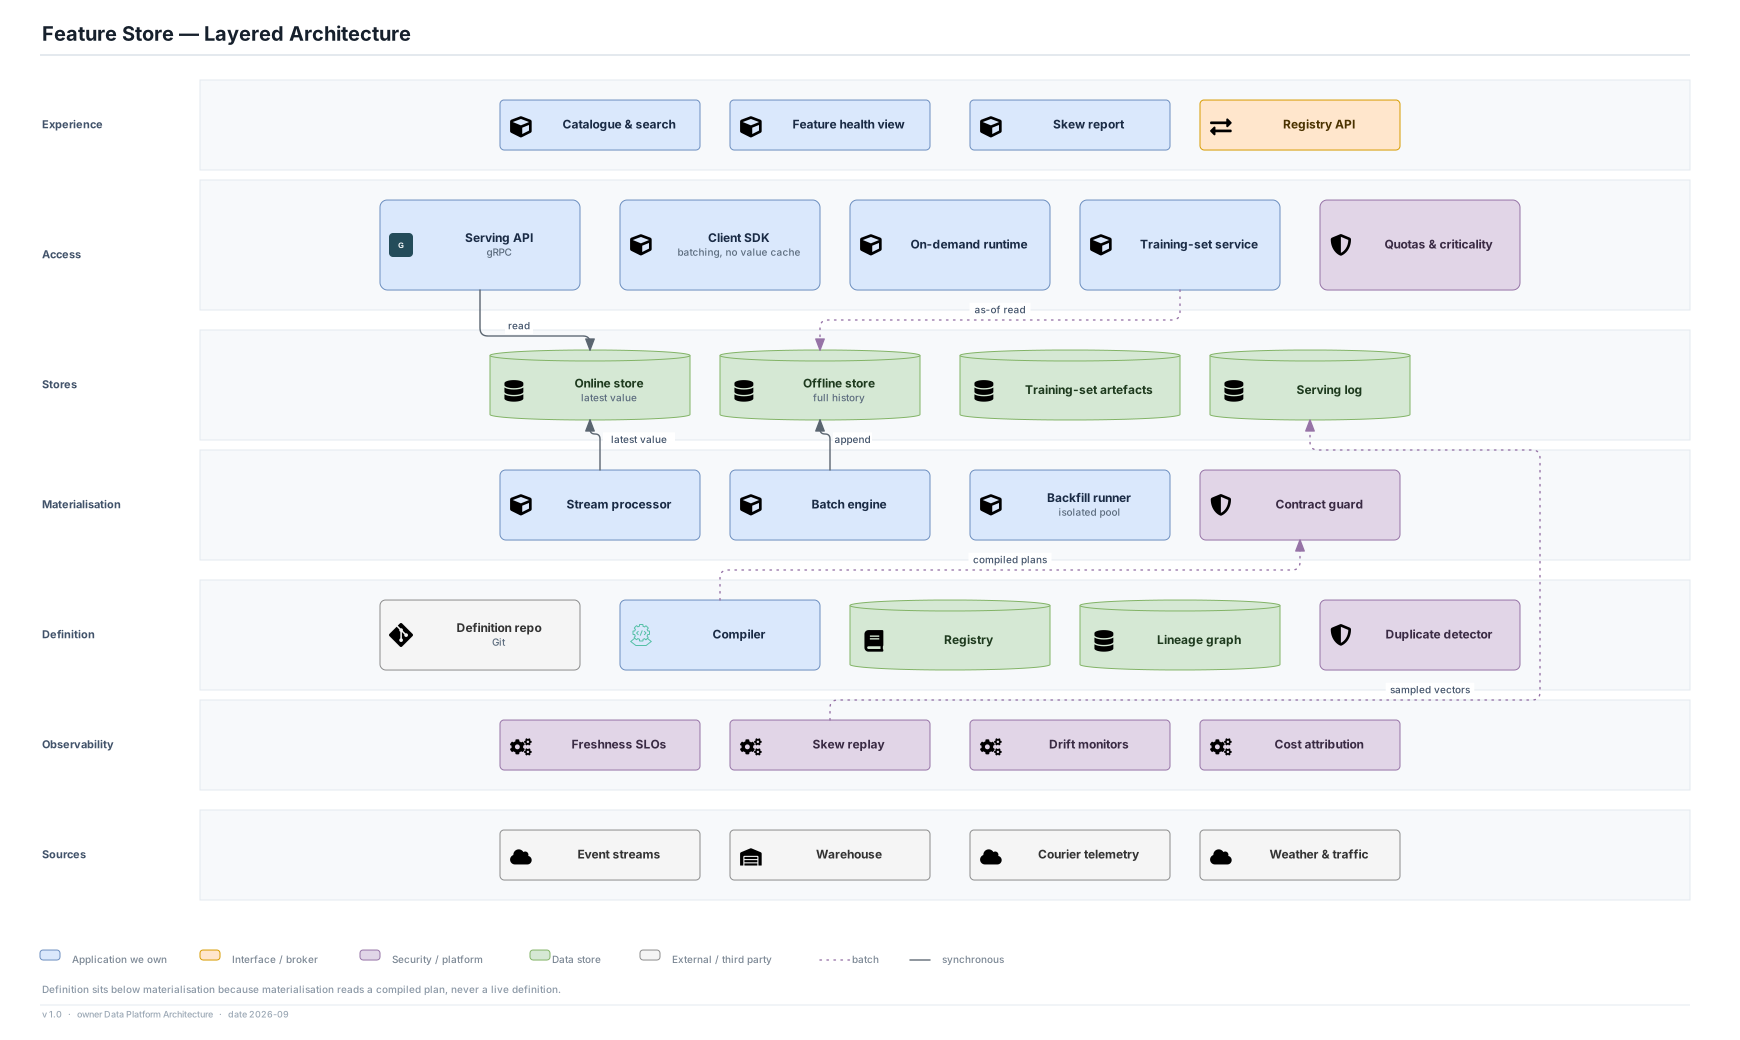
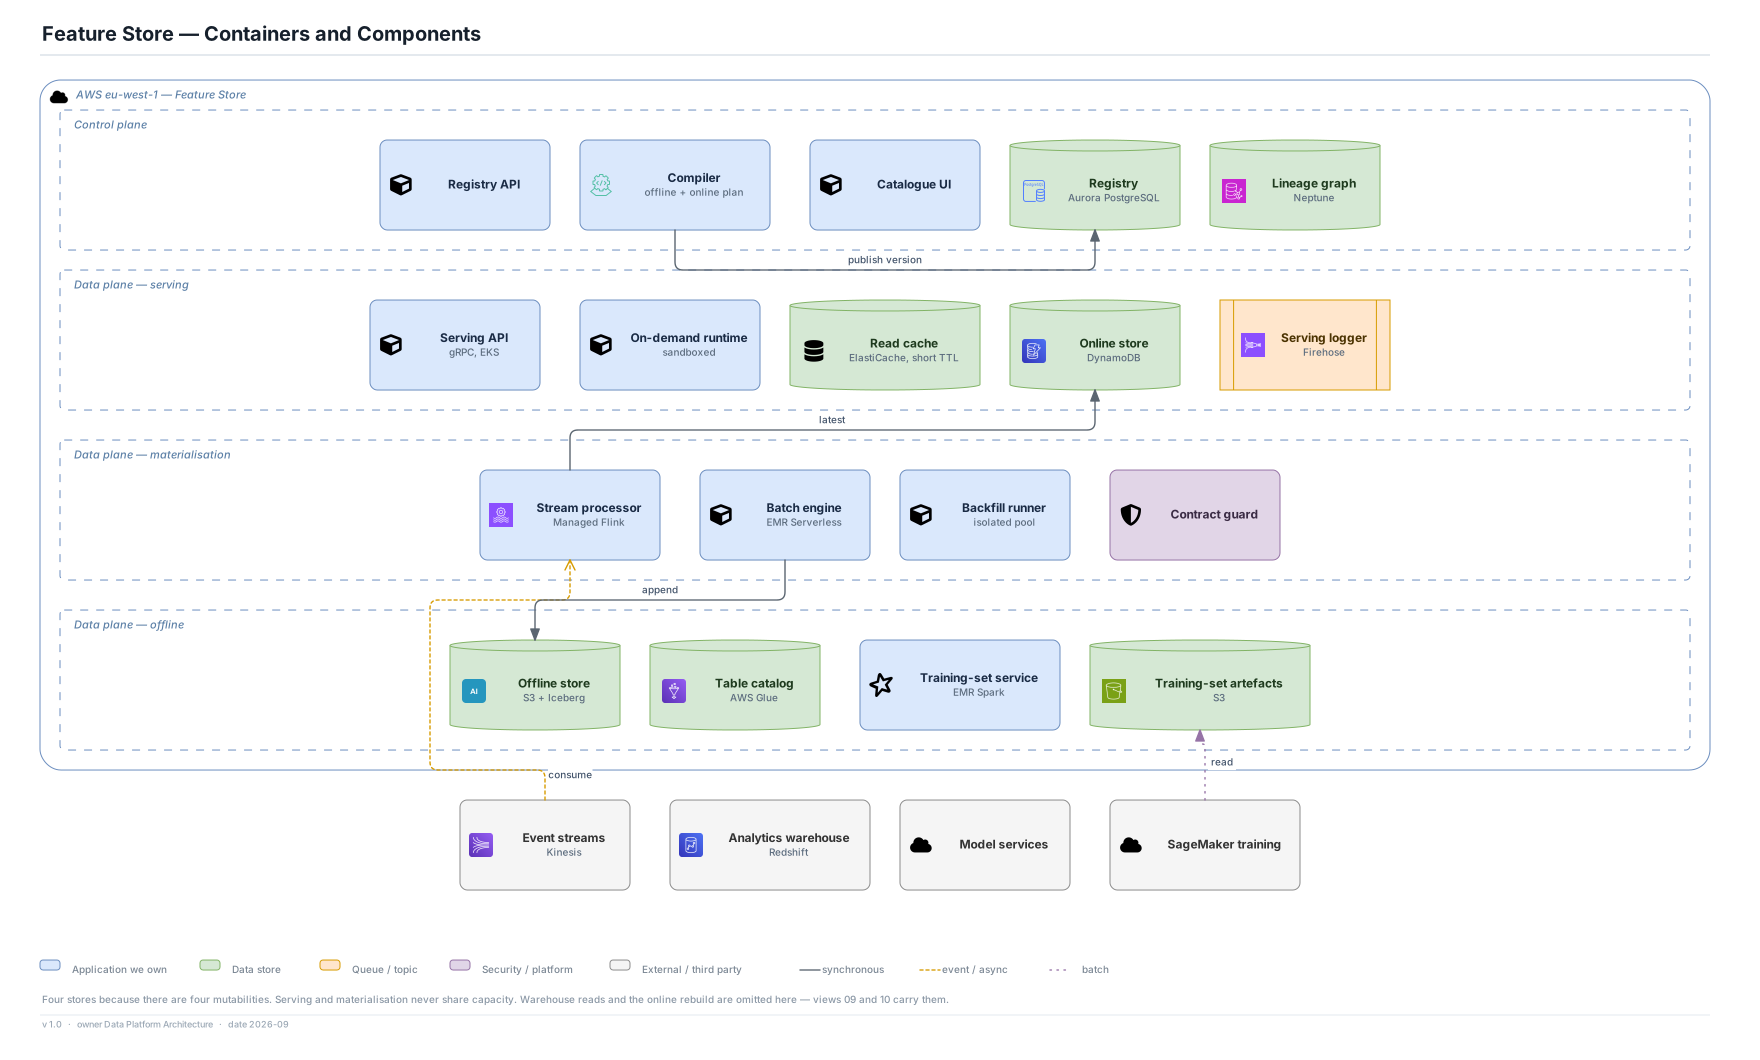
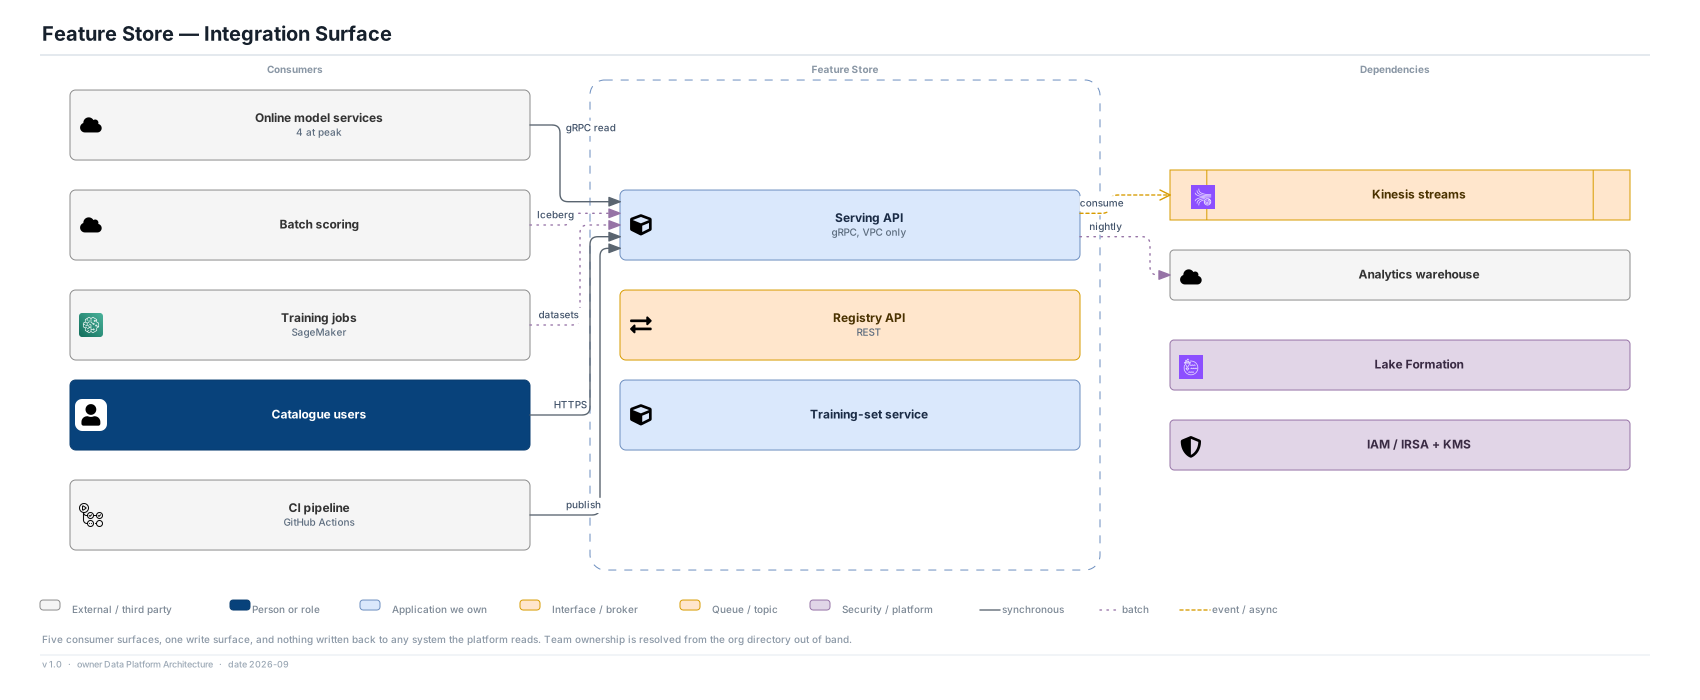
The argument these decisions serve is summarised in the Architecture One-Pager.
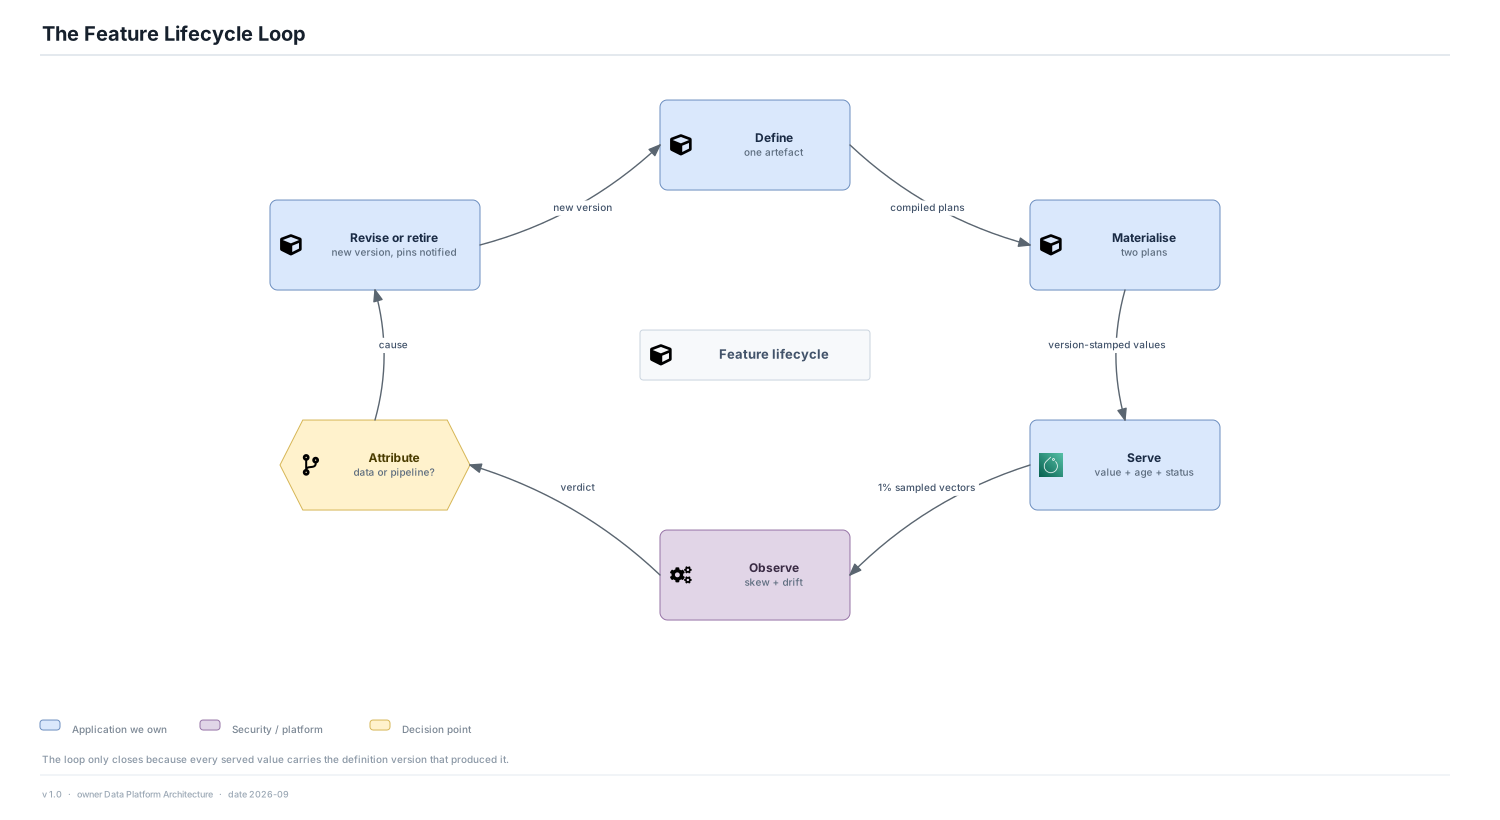
Seventeen decisions make up this architecture. Everything else across the twenty-one views is either a consequence of one of them or a detail that could be decided differently next quarter without anybody having to redraw the set. Each record carries more than the classic context / decision / consequences triple: the forcing question, how the decision is realised on AWS, the alternatives including the ones that are right for a different organisation, the conditions that would flip the choice, why it should still hold as scale and technology change, and the transferable lesson.
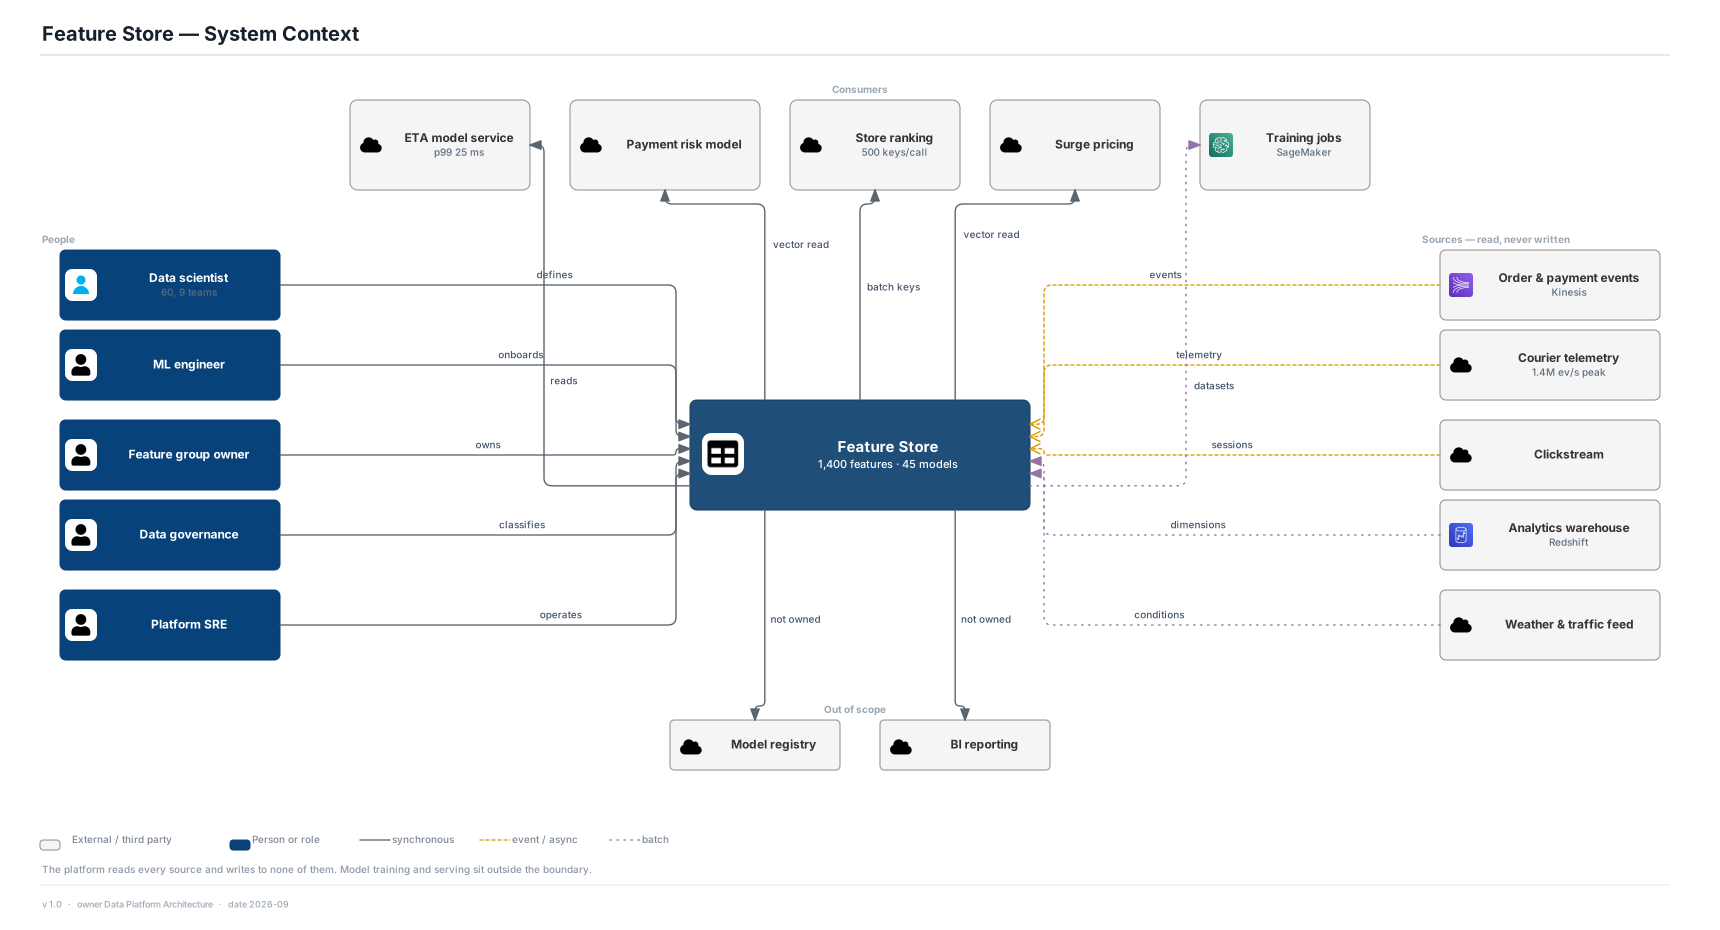
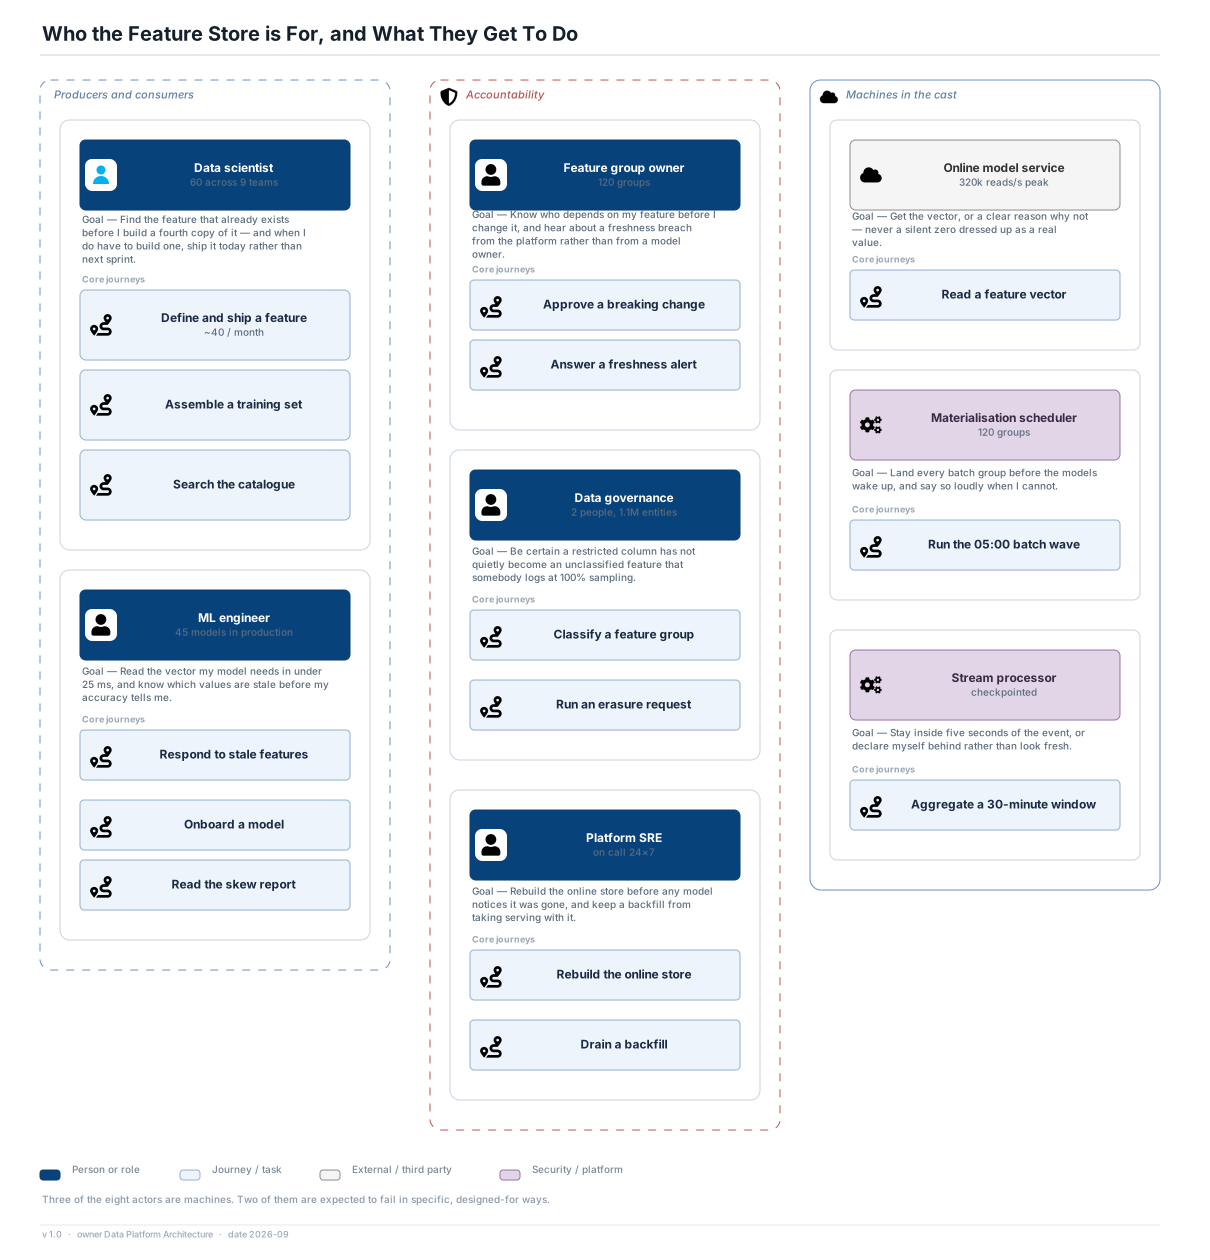
Status of this document. This is a design, not a report on a running system. Every rate, latency, threshold, tolerance and retention figure is a stated assumption chosen to be defensible and arguable rather than measured. The operating context assumed throughout is a consumer delivery marketplace: 40M monthly active users, 1.1M partner stores, 180k couriers, 2.2M orders a day peaking at 4,500 a minute, 45 models in production owned by 9 teams, and 1,400 features in 120 groups across 6 entity types. The named AWS services are the ones this exercise commits to; the requirement in ask.md stays vendor-neutral so it survives a change of cloud. A reviewer who disagrees with a number can follow it to the record that depends on it.
How to read a record
- Question: The forcing question: why a decision was needed at all.
- Context: The requirement, the scale and the constraint that make it hard.
- Decision: What this architecture does, stated so it can be checked.
- How it is realised on AWS: The concrete mechanism: which service or package, configured how, in which subscription.
- Options weighed: Chosen, rejected, deferred, or right elsewhere, with the reason for each.
- Consequences: What the choice buys and what it costs, both kept visible.
- Choose differently when: The conditions that would flip the decision for your system.
- Why it holds up over time: What keeps the decision right as scale, staff and technology change.
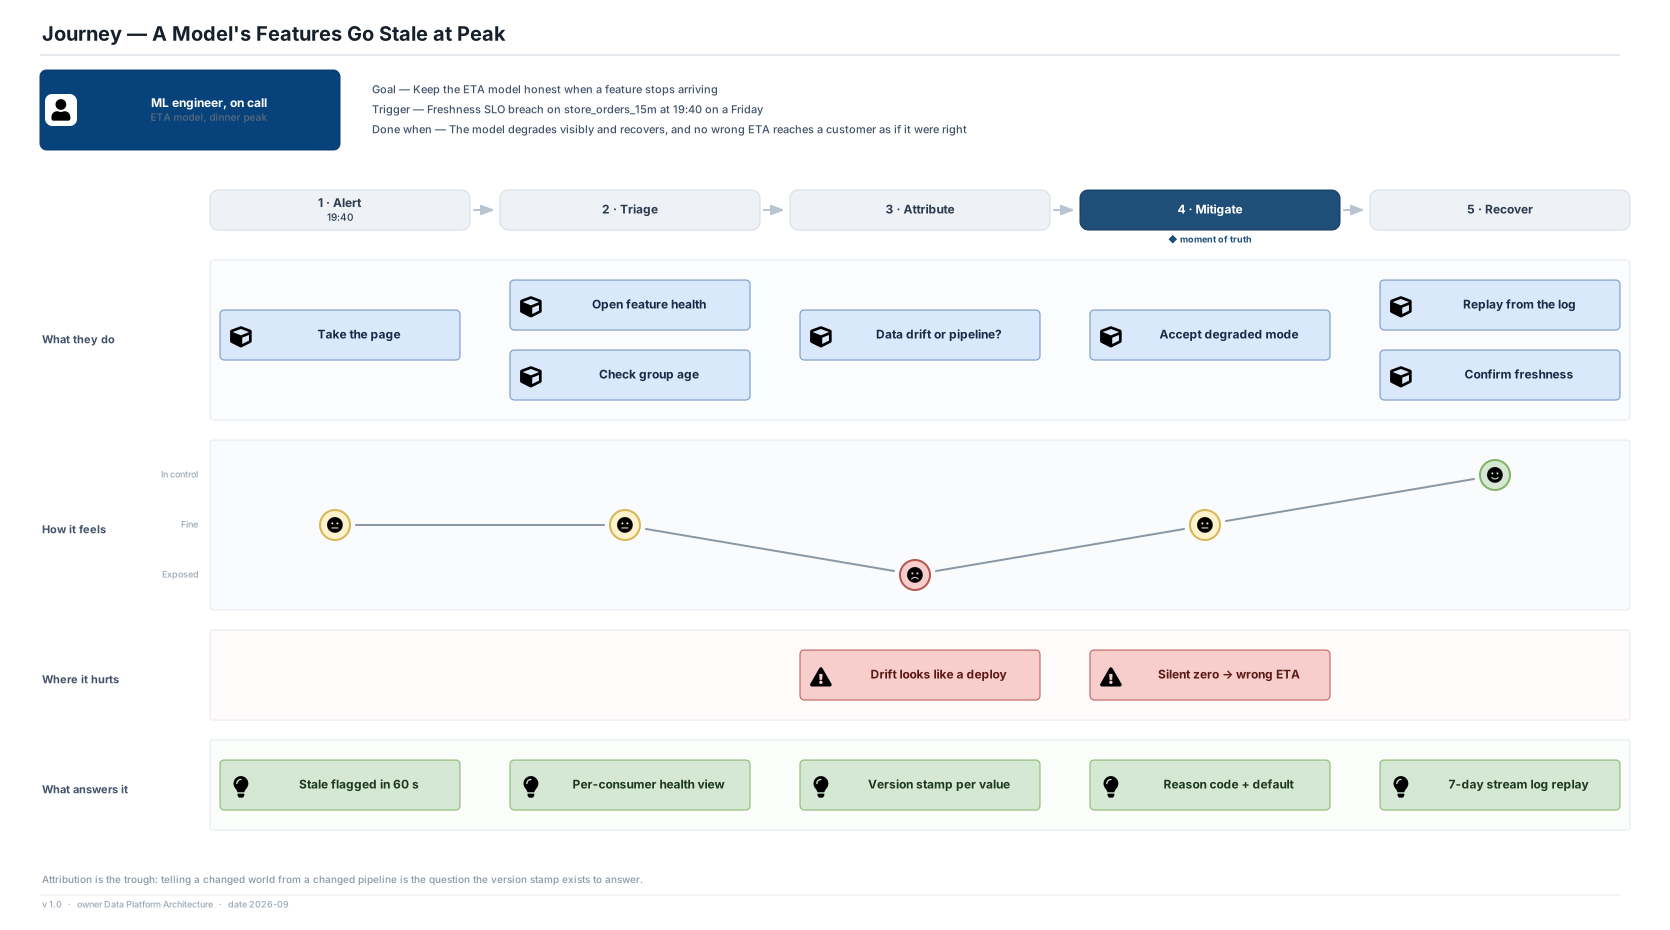
- Lesson: The principle that transfers beyond this platform.
Decision map
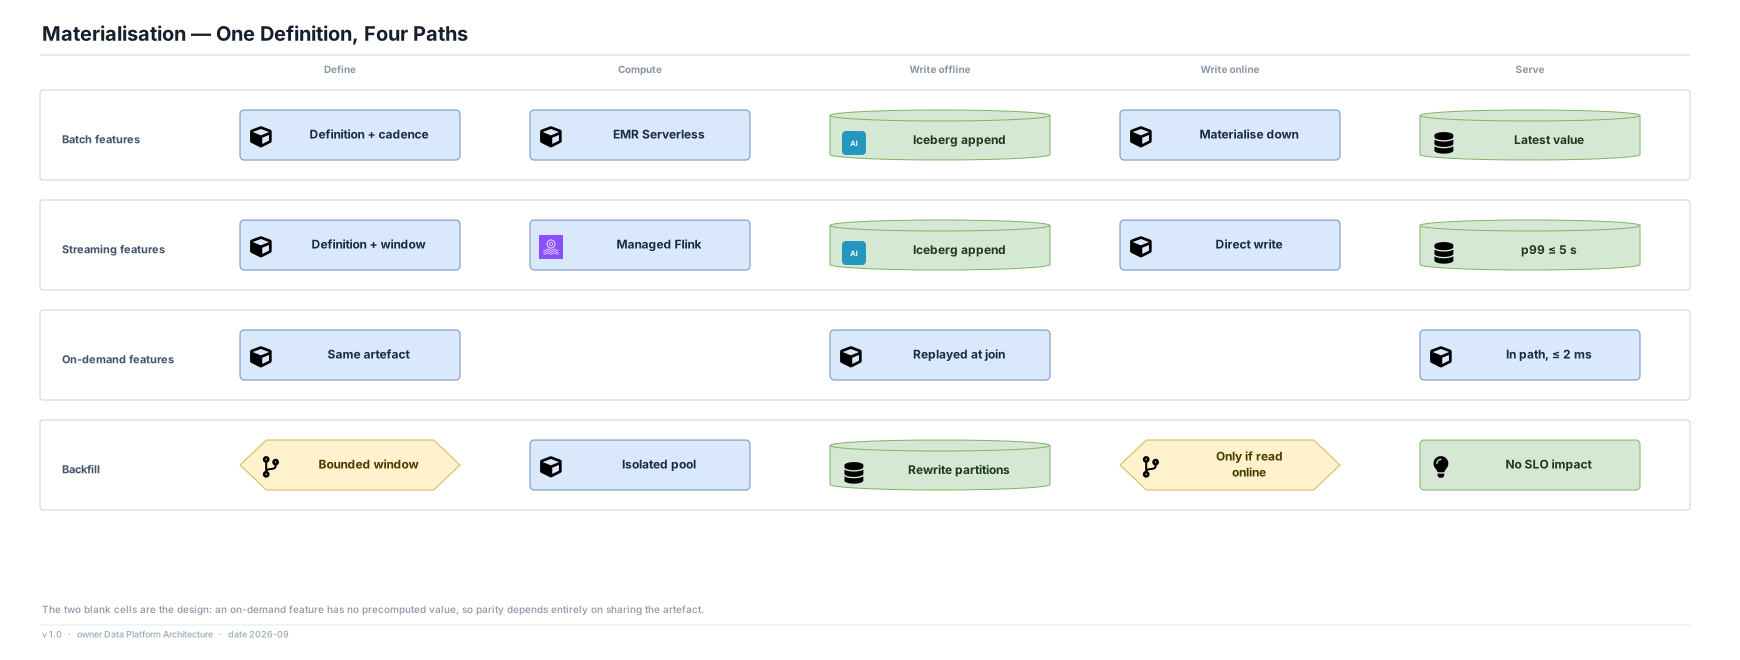
Parity — one definition, two materialisations: The decisions that make the value a model trains on and the value it is served the same number.
- ADR-01 · One definition artefact, compiled into both plans, or it does not publish
- ADR-02 · On-demand transformations run in the serving path, compiled from the shared artefact
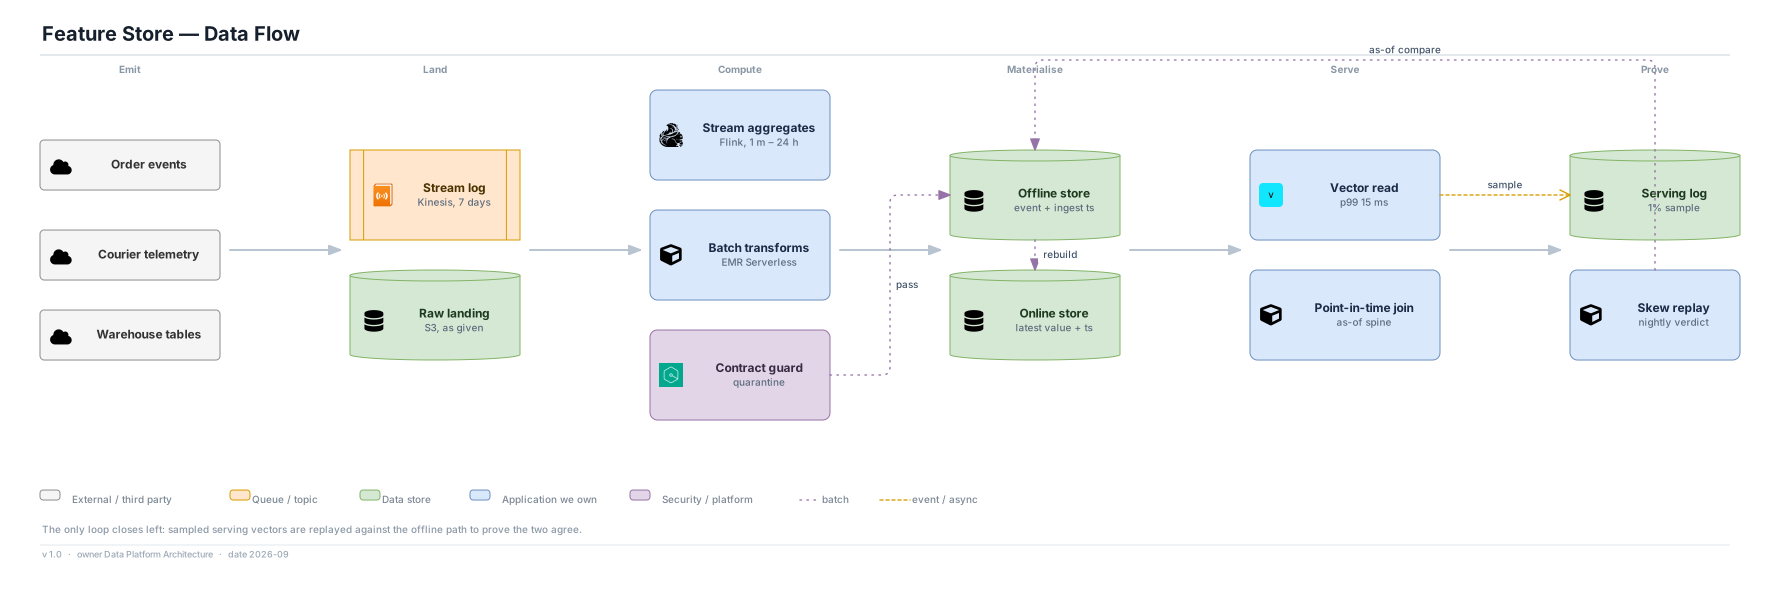
- ADR-03 · Streaming features dual-write from one computation; batch features materialise down from offline
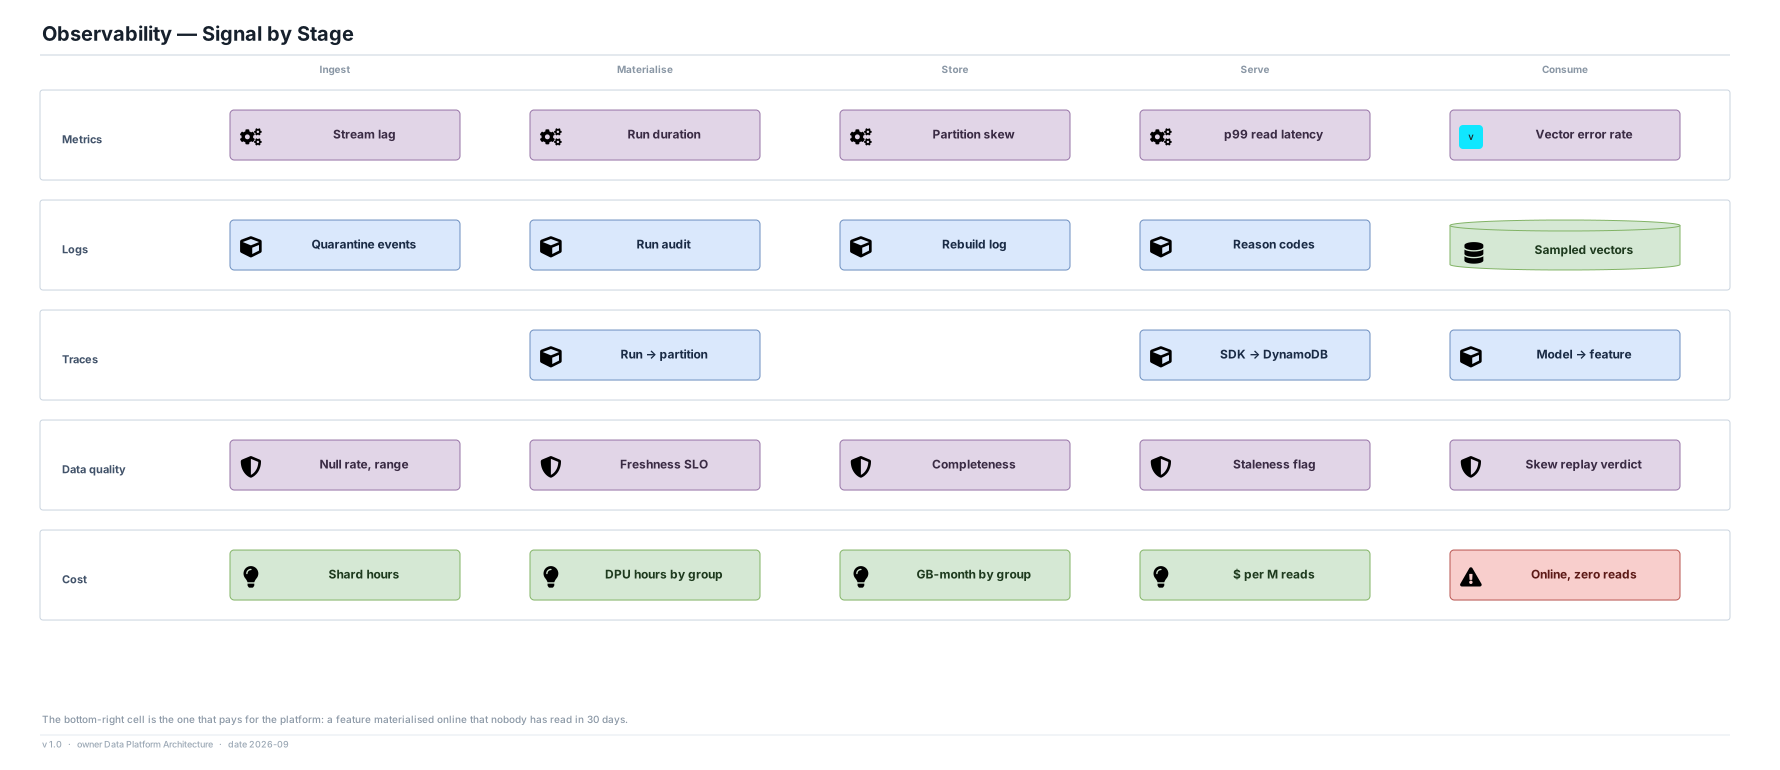
- ADR-04 · Skew is proven continuously by replaying sampled served vectors through the offline path
Correctness in time: Timestamps, as-of joins and late data — how the platform avoids training on the future.
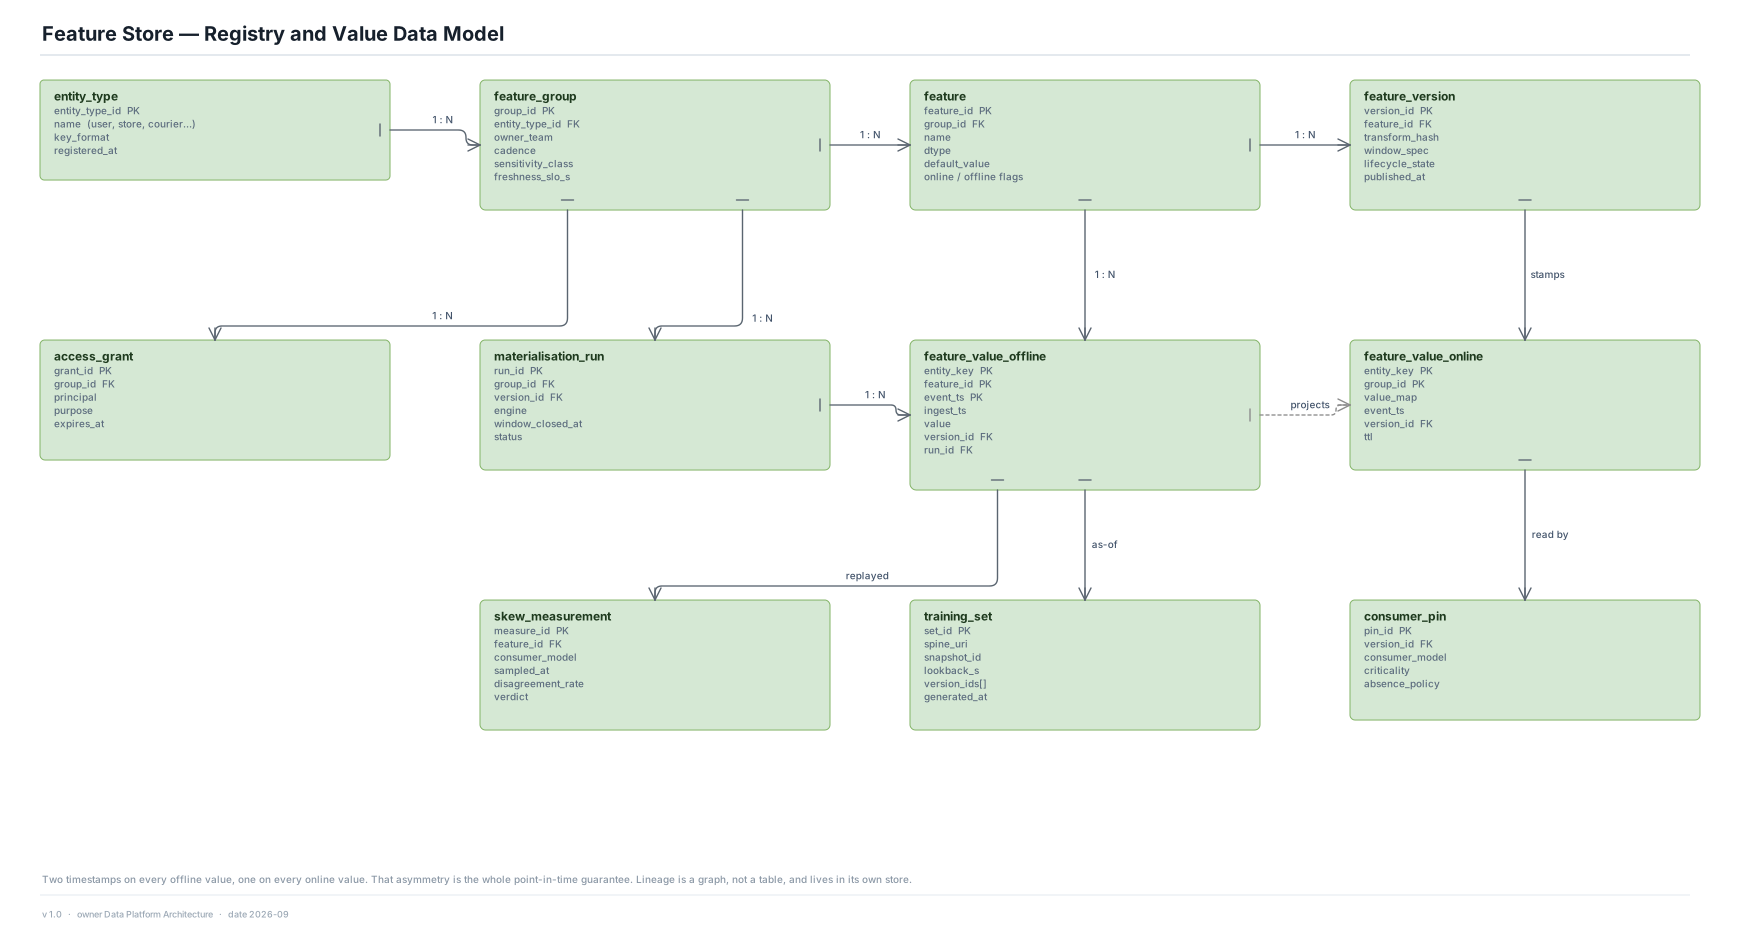
- ADR-05 · Every offline value carries event time and ingestion time; a feature without a reliable ingestion time is refused
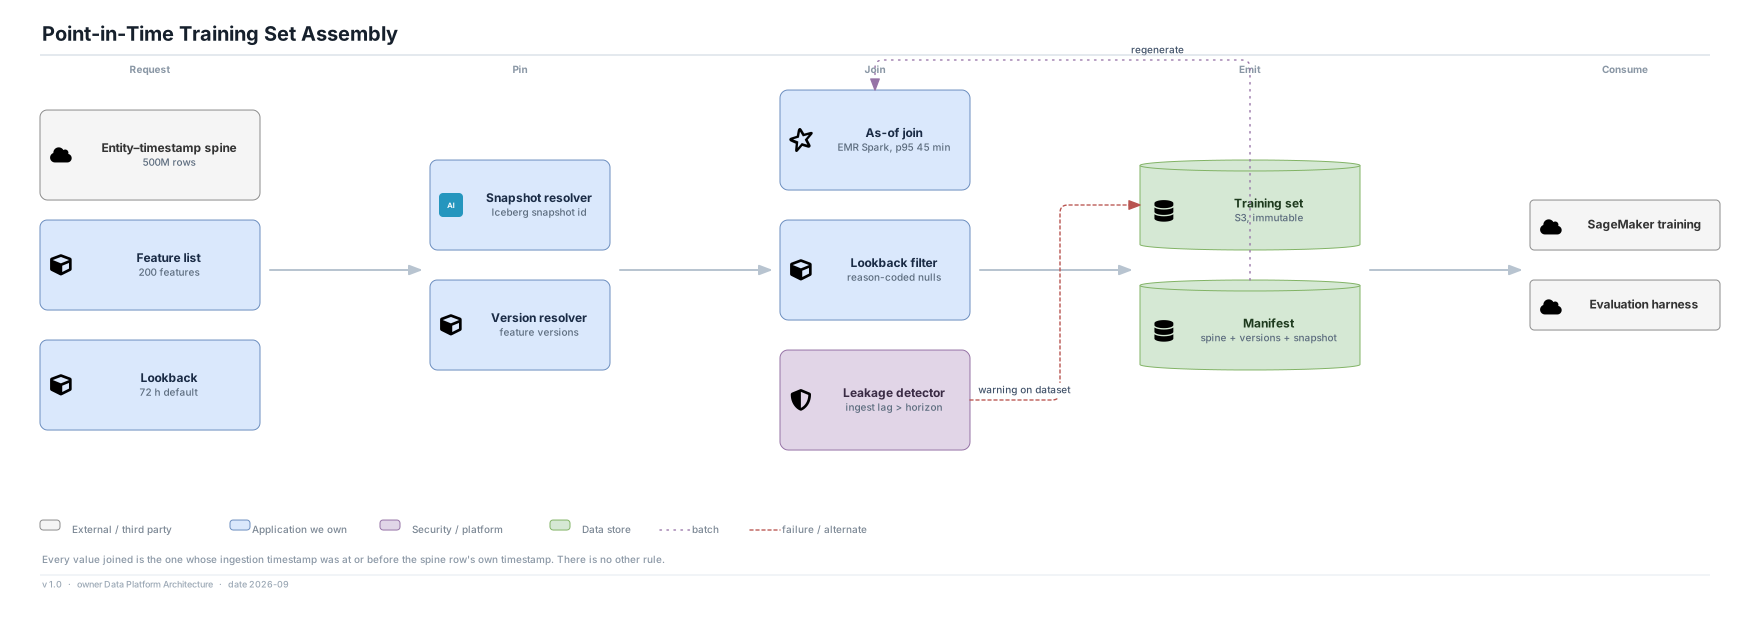
- ADR-06 · Point-in-time correctness lives in the table format's snapshots; lookback and tolerance live in the join engine
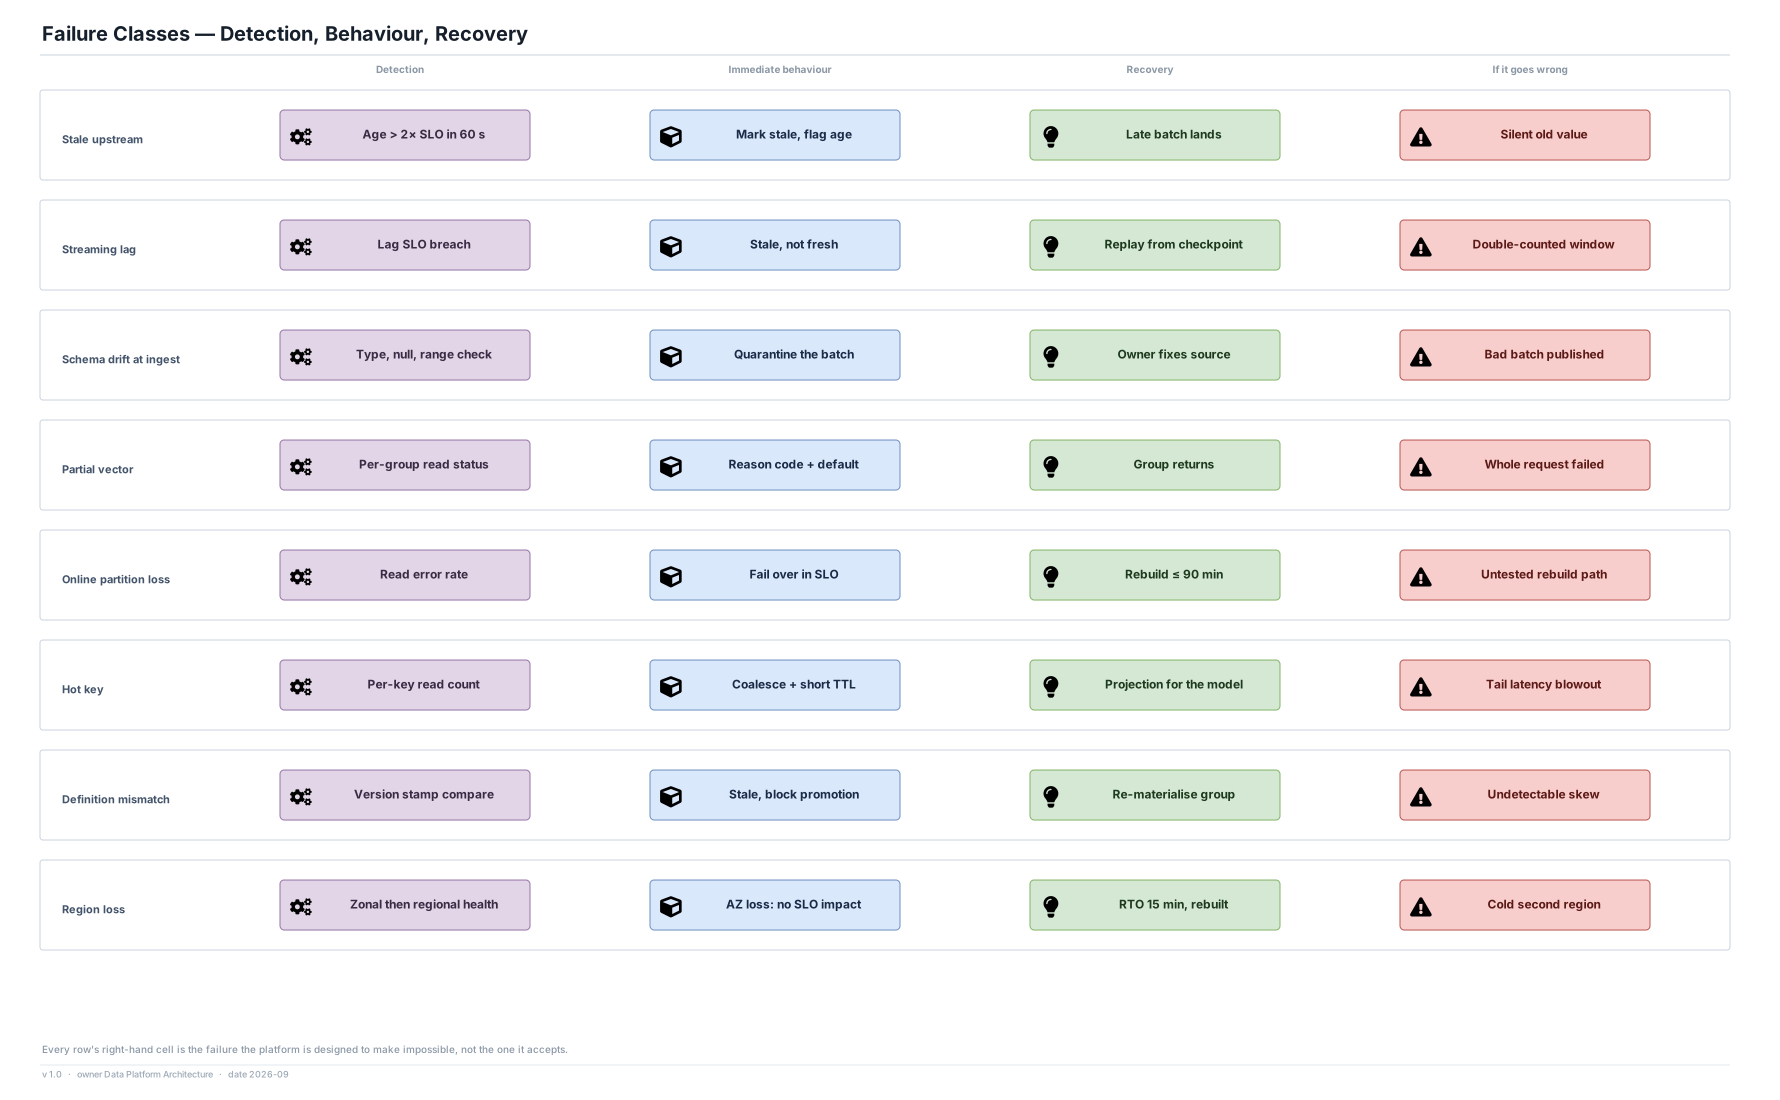
- ADR-07 · Late-arriving events are accepted and change future training sets, but never restate a generated one
Serving inside a request budget: What the online path holds, what it does when a value is missing, and how it stays inside 25 ms.
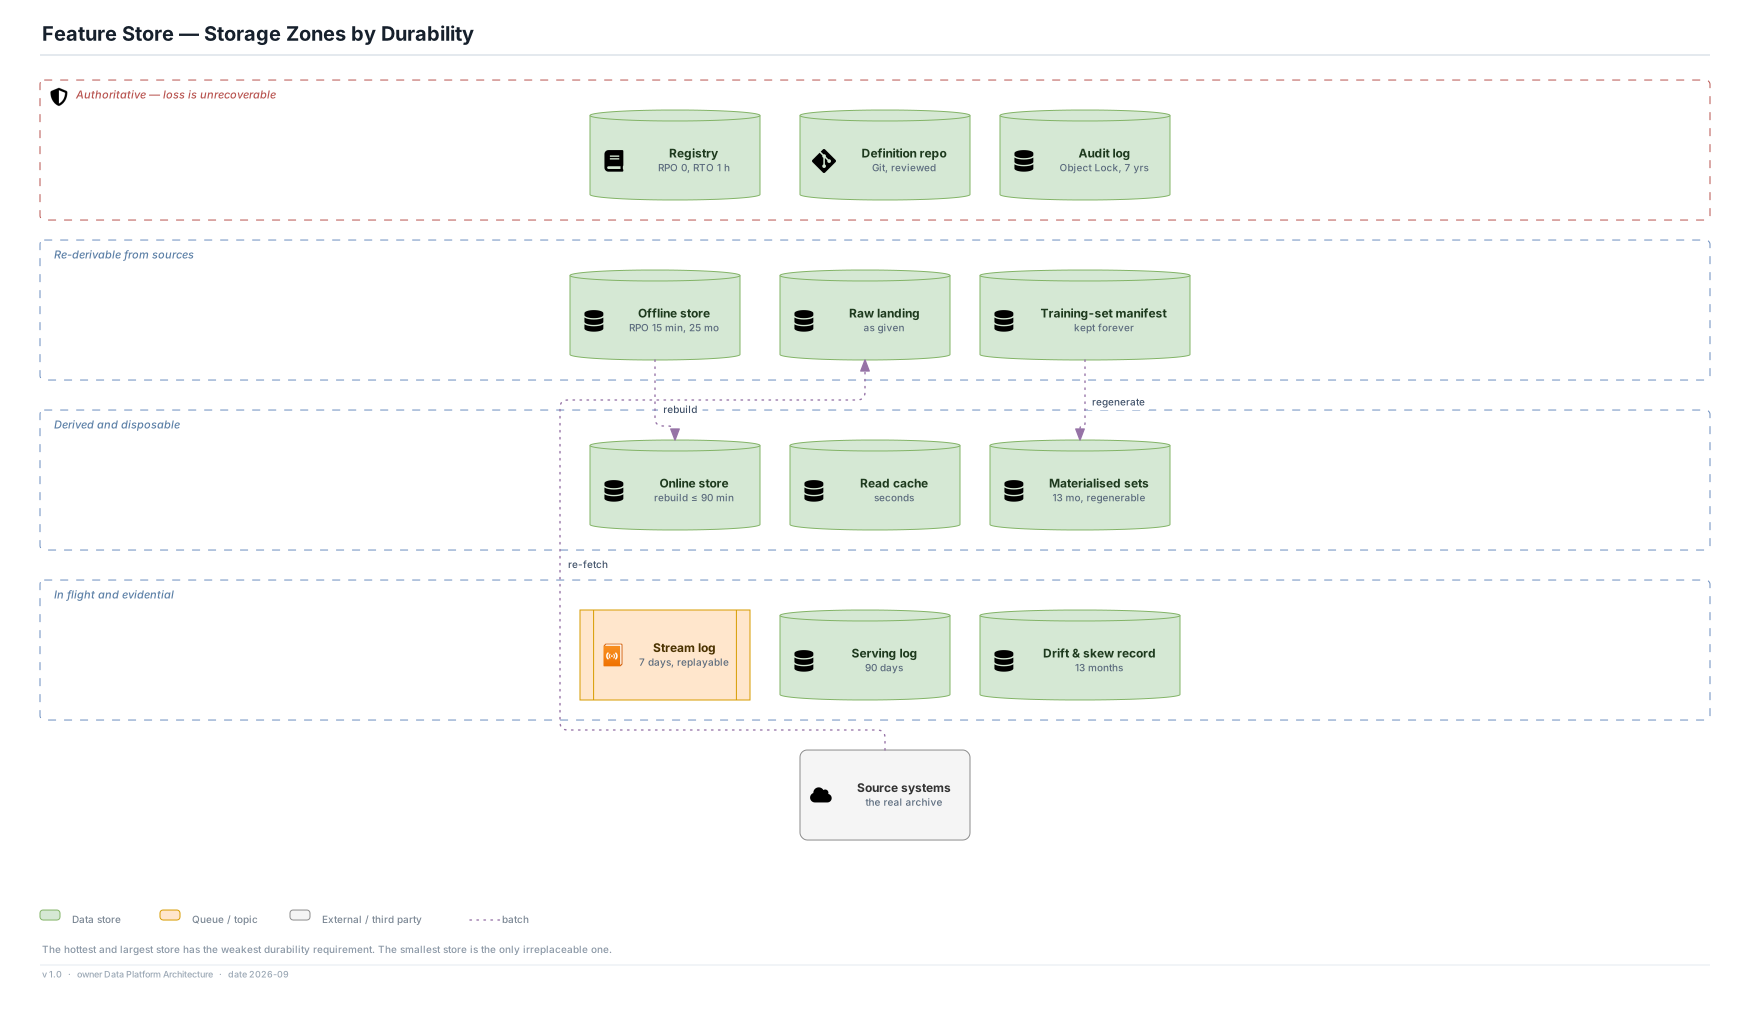
- ADR-08 · The online store holds latest value only, and is a derived, rebuildable projection
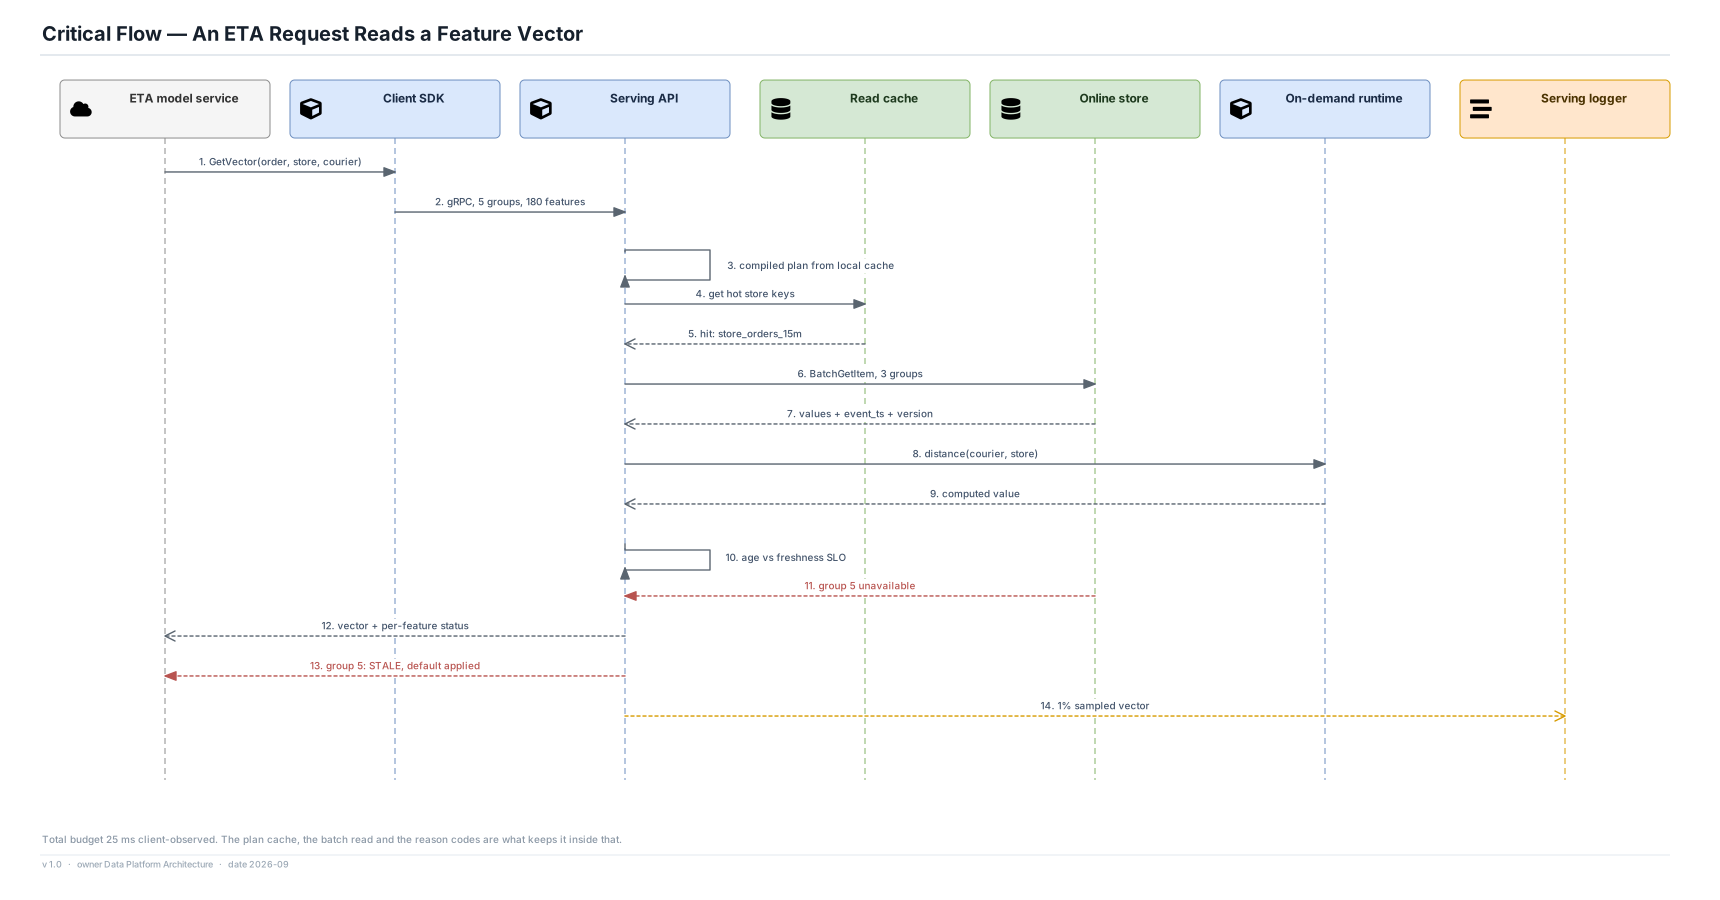
- ADR-09 · Absence is a value with a reason code; criticality and absence policy belong to the consumer
- ADR-10 · One shared online keyspace now; per-consumer projections only for the heaviest fan-out
Reuse, versioning and accountability: The decisions that decide whether nine teams share one definition or build nine.
- ADR-11 · The feature version is the unit of versioning, of pinning and of training-set provenance
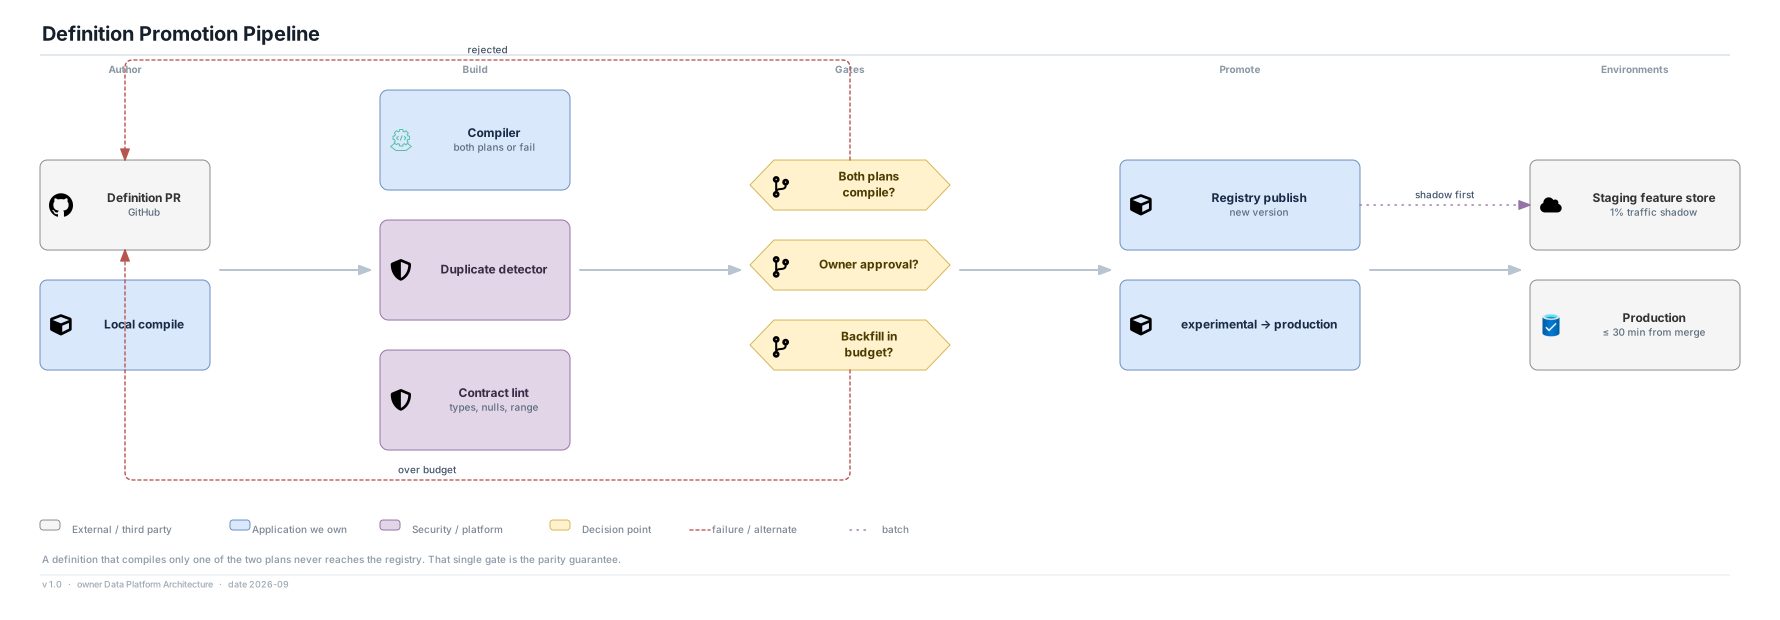
- ADR-12 · Definitions arrive only through reviewed source control, and near-duplicates are blocked at registration
- ADR-13 · Every group declares an owner and a freshness SLO, and staleness is marked rather than hidden
Durability, cost and recovery: What can be thrown away, what must not be, and what a backfill is allowed to disturb.
- ADR-14 · Backfill runs in an isolated, budgeted, pre-emptible pool and writes online only where a consumer reads online
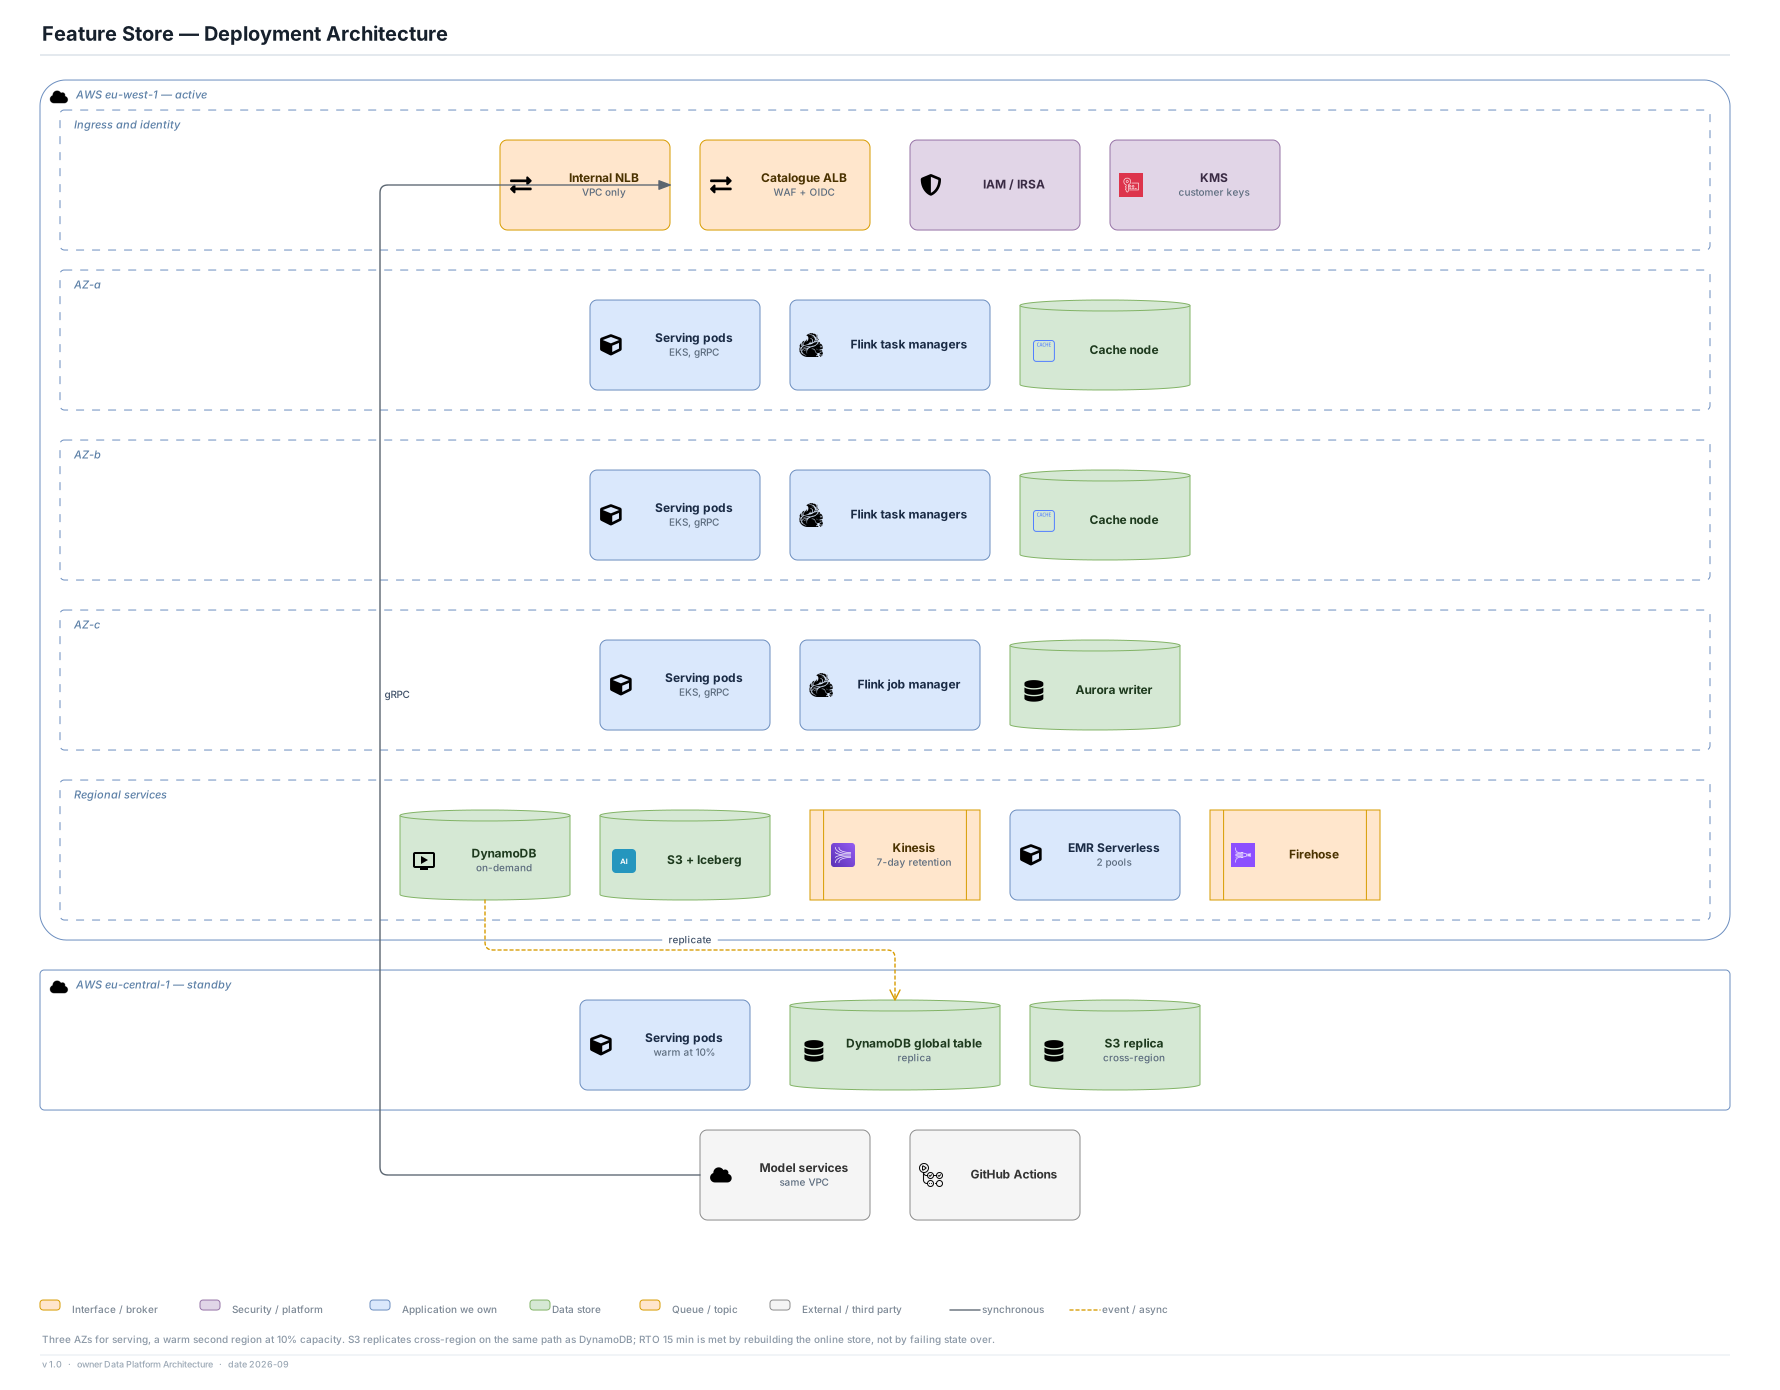
- ADR-15 · Region loss is met by rebuilding the online store in a warm second region, not by replicating serving state
Access and data protection: Who may read a feature, on what basis, and what happens to the evidence trail.
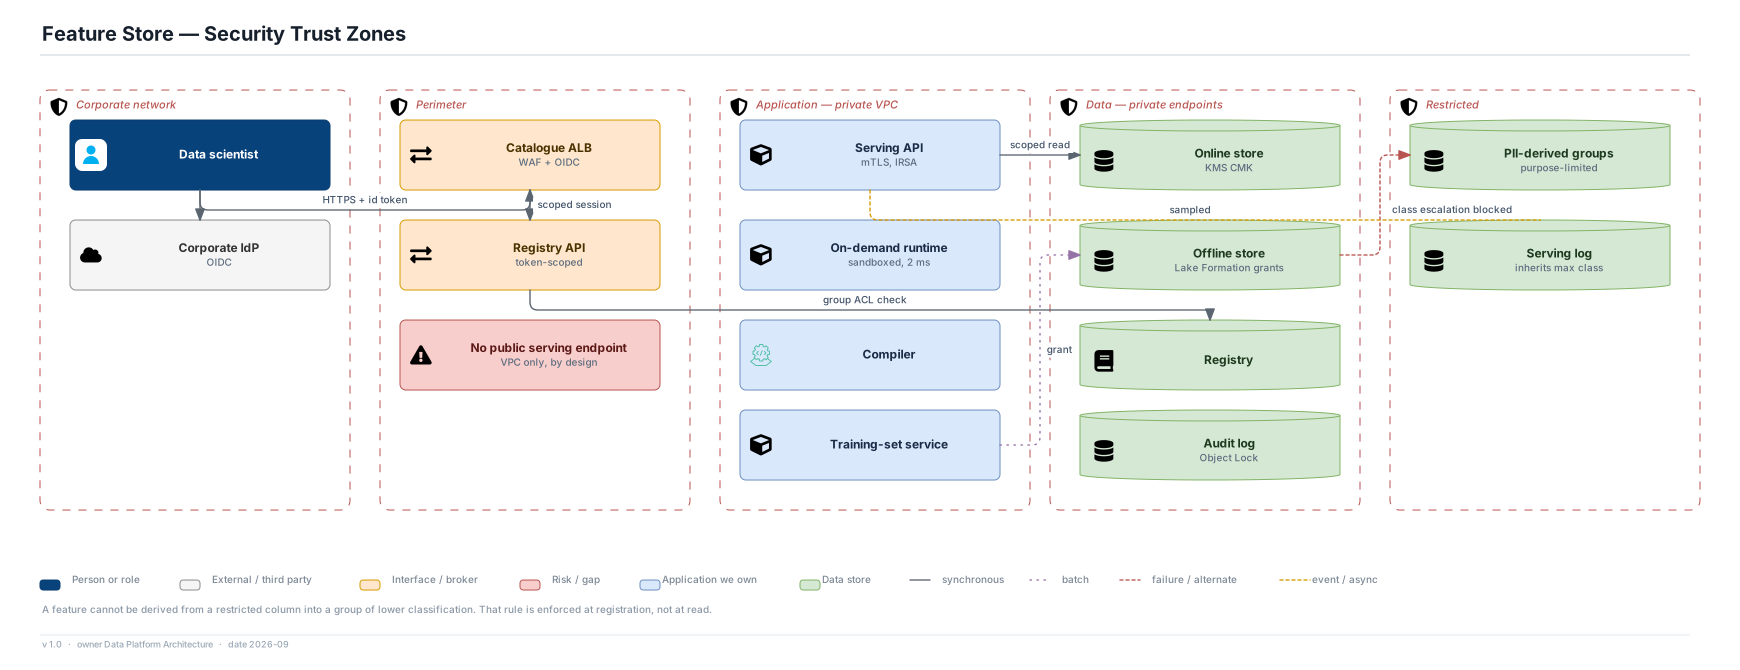
- ADR-16 · Sensitivity classification is enforced at registration, and the serving log inherits the highest class it contains
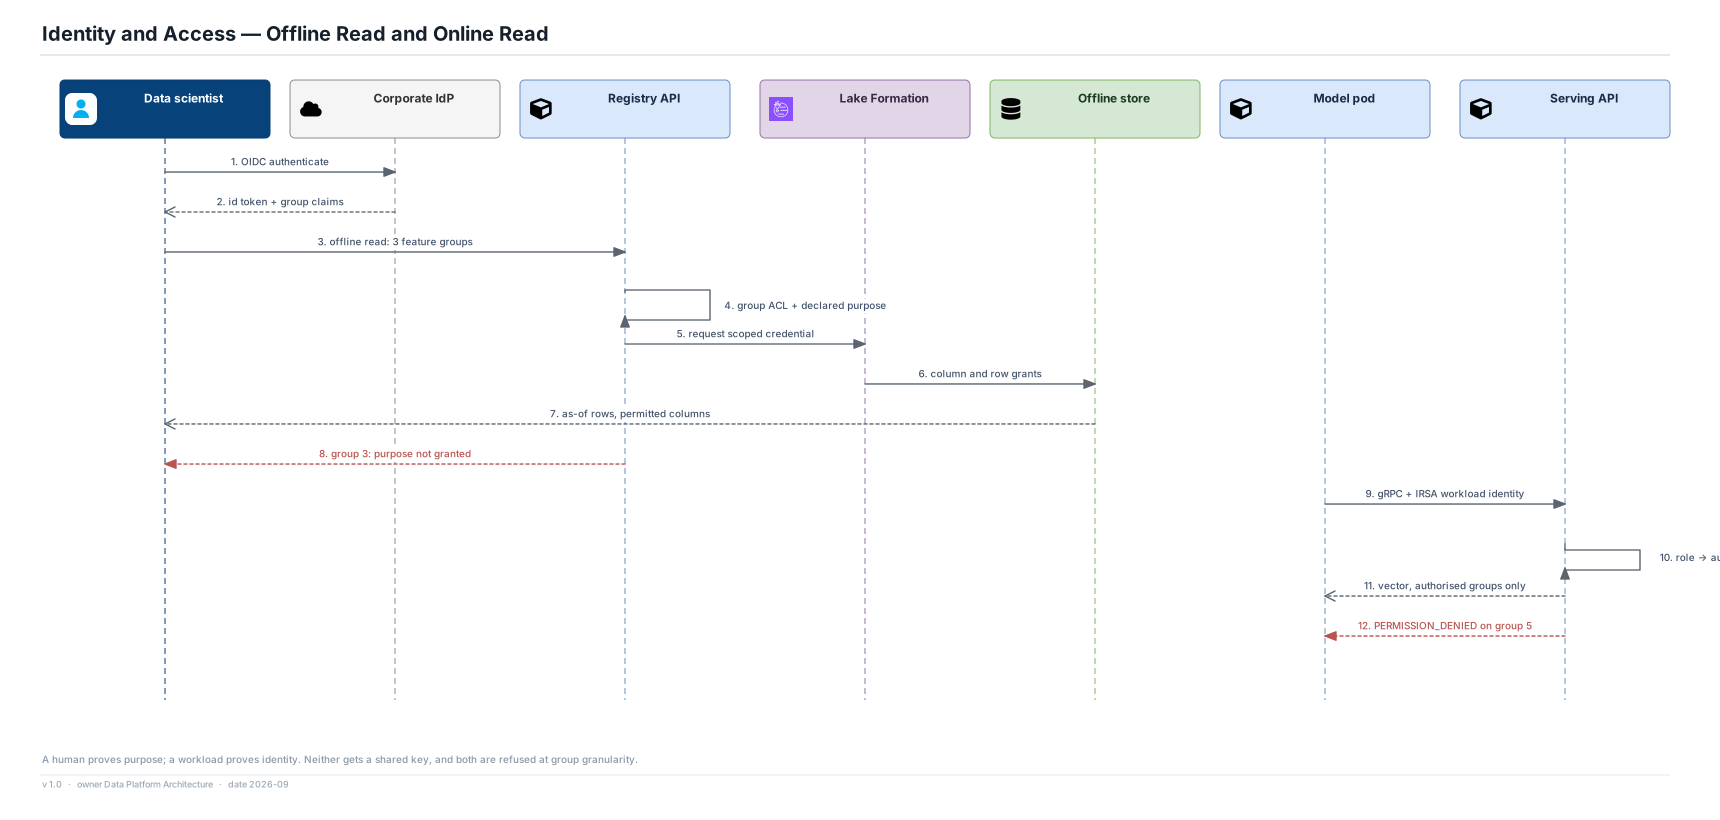
- ADR-17 · Workload identity for every caller, authorisation at feature-group granularity, no shared keys
Technology by capability
Amazon Web Services was chosen for this exercise deliberately rather than because the topic demands it. A feature store is not an AWS-shaped problem — the requirement in ask.md stays vendor-neutral throughout, and every decision above would hold on another cloud. AWS was picked because it is the least-used major cloud across this practice's recent use cases and had never carried a data-platform one, and because the offline/online split maps onto its services without a proprietary lakehouse in the middle. The table below is what this exercise commits to, what each choice would be replaced by elsewhere, and which decision record it serves.
| Capability |
Choice |
Origin |
Credible alternative |
Why this one |
Record |
| Offline store |
S3 with Apache Iceberg tables and the Glue Data Catalog |
AWS + open format |
Delta Lake on ADLS Gen2, or BigQuery with time travel |
Snapshot isolation lets a 45-minute training join read a stable view while materialisation commits, and the snapshot id becomes a pinnable input to the manifest |
ADR-06 |
| Online store |
DynamoDB, one item per entity and feature group, on-demand capacity |
AWS |
Cosmos DB, Bigtable, or self-hosted Cassandra / Redis |
Single-digit-millisecond reads at 320k/s with no capacity planning for the stated 3× burst, and cheap enough to treat as disposable |
ADR-08 |
| Stream log |
Kinesis Data Streams with 7-day retention |
AWS |
MSK / Kafka, Event Hubs, or Pub/Sub |
Retention is the replay window that every streaming recovery path in view 21 depends on; 7 days is the assumption the RPO rests on |
ADR-07 |
| Stream processing |
Managed Service for Apache Flink, checkpointed |
AWS + open engine |
Self-hosted Flink, Spark Structured Streaming, or Dataflow |
Windowed aggregates from 1 minute to 24 hours with exactly-once checkpointing, and a job graph the compiler can emit |
ADR-03 |
| Batch materialisation |
EMR Serverless, two pools |
AWS + open engine |
Databricks jobs, Glue, or Dataproc |
Separate pools give backfill its own capacity and pre-emption without a second cluster to keep warm |
ADR-14 |
| Registry |
Aurora PostgreSQL Serverless v2 |
AWS |
Azure SQL, Cloud SQL, or self-hosted PostgreSQL |
Small, strongly consistent and the only store whose loss is unrecoverable; relational because the model in view 11 is relational |
ADR-11 |
| Serving tier |
gRPC services on EKS behind an internal NLB, three AZs |
AWS + Kubernetes |
AKS, GKE, or ECS Fargate |
Stateless pods scaled independently of materialisation, with IRSA giving each caller a workload identity rather than a key |
ADR-17 |
| Hot-key cache |
ElastiCache with a short TTL, values immutable within their window only |
AWS |
Momento, Redis Enterprise, or an in-process cache |
Coalesces reads on a small number of very popular stores without becoming a second, undetectable staleness source |
ADR-10 |
| Serving log |
Kinesis Data Firehose to S3, partitioned by model and hour |
AWS |
Event Hubs Capture, or a direct async write to object storage |
Buffered, cheap, and classification-aware by prefix, which is what lets the log inherit the vector's maximum class |
ADR-16 |
| Offline access control |
Lake Formation column and row grants |
AWS |
Unity Catalog, Purview, or Ranger |
Scoped credentials for a human's offline read, so purpose and ACL are enforced before the data leaves the table |
ADR-17 |
| Definition pipeline |
GitHub with required review and GitHub Actions |
External |
GitLab CI, Azure DevOps, or CodeBuild |
Registration is a merge, so review, duplicate detection and the parity gate all happen where the author is already working |
ADR-12 |
| Observability |
Amazon Managed Prometheus and Managed Grafana, with CloudWatch for platform metrics |
AWS + open ecosystem |
Azure Monitor, Cloud Monitoring, or self-hosted Prometheus |
Freshness and lag are SLO series rather than logs, and they need to be queryable by feature group at 120-group cardinality |
ADR-13 |
| Encryption and keys |
KMS with customer-managed keys for restricted groups |
AWS |
Key Vault, Cloud KMS, or Vault |
A separate key per classification is the boundary that makes a classification more than a tag |
ADR-16 |
| Cross-region recovery |
S3 cross-region replication plus a DynamoDB global table replica |
AWS |
Paired-region storage replication with a rebuild job |
The offline replica is what the rebuild reads; the online replica shortens the rebuild rather than guaranteeing correctness |
ADR-15 |
The decisions, and the alternatives that lost
Parity — one definition, two materialisations
The decisions that make the value a model trains on and the value it is served the same number.
ADR-01 · One definition artefact, compiled into both plans, or it does not publish
Status: Accepted · Shown on views: 02, 16, 13
What stops the value a model trains on and the value it is served from being two different numbers computed by two different pieces of code?
Context. Training and serving have opposite shapes. Training wants full history over many entities, read once, in a columnar format; serving wants one entity's latest value, read three hundred thousand times a second. Almost every organisation therefore ends up with two implementations of the same feature — a GROUP BY in a notebook and a counter incremented by a service — and no mechanism that notices when they diverge. The resulting defect is uniquely expensive: the model scores well offline, performs badly in production, both numbers are individually plausible, and the training data no longer exists in the form that produced them. Reviewing the two implementations against each other does not work, because the divergence appears later, in a change to one of them.
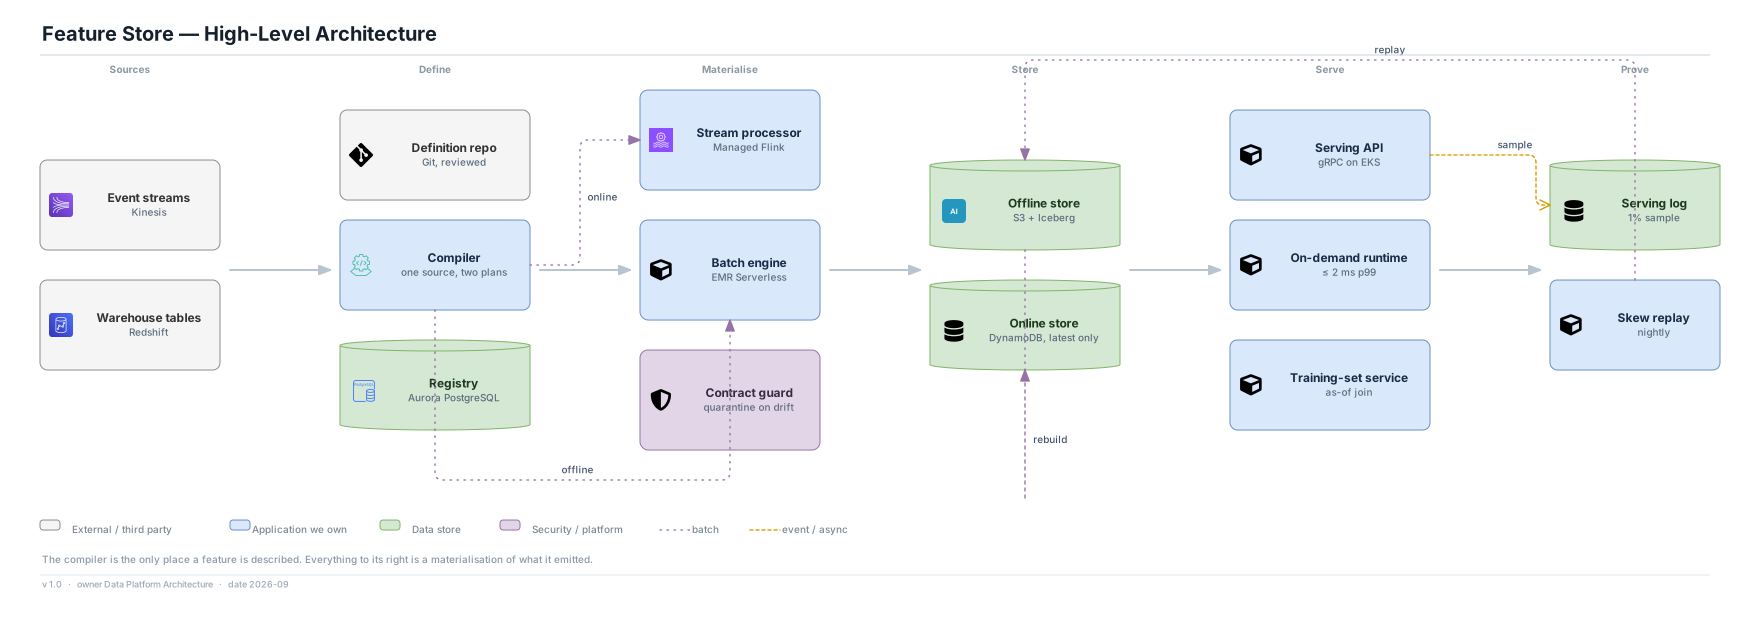
Decision. A feature exists only as a declarative definition artefact in reviewed source control. A compiler reads that artefact and emits two execution plans — an offline plan and an online plan — and the build fails if either cannot be expressed. Nothing reaches the registry, and therefore nothing is materialised, without both plans. Materialisation engines execute a compiled plan and never read a definition directly.
How it is realised on AWS. The definition lives in a Git repository; a GitHub Actions job runs the compiler, which validates the declaration against the registered entity types and emits a Flink job graph for the online plan and a Spark plan for the offline plan. Both are hashed into a version record written to Aurora PostgreSQL. EMR Serverless and Managed Flink are handed the compiled plan and its version id; neither has credentials to read the registry's definition tables.
| Option |
Verdict |
Reasoning |
| One artefact compiled into two plans, publish gated on both |
Chosen |
Makes divergence impossible to introduce rather than possible to detect |
| Two hand-written pipelines with a reconciliation report |
Rejected |
Cheapest to start and the defect it is supposed to catch is exactly the one that appears between reports |
| Serve from the offline store directly, one implementation only |
Rejected |
Perfect parity and cannot meet a 15 ms p99 on a single-entity read |
| A registry that catalogues pipelines teams already wrote |
Right elsewhere |
Right for an organisation retrofitting governance onto existing features; it documents parity rather than providing it |
What it buys
- Training–serving skew becomes a detectable defect with a named cause rather than an unexplained accuracy gap
- A feature's meaning is reviewable, because it exists in exactly one place and arrives through a pull request
- Engine choices become replaceable: a new stream processor is a new code generator, not a re-specification of 1,400 features
What it costs
- The platform becomes a gate on every new signal; a data scientist cannot compute a feature in a notebook and ship it
- Transformations the declaration cannot express are refused, which will be experienced as the platform being less capable than a notebook
- The compiler is now the most load-bearing component in the system, and a bug in it is a bug in every feature
Choose differently when. If one team owned every model and every feature, and features were rewritten rather than reused, the compiler would be pure overhead and two hand-written pipelines with a reconciliation job would be cheaper and faster. The decision is justified by the nine teams, not by the technology.
Why it holds up over time. The contract — one artefact, two materialisations, publish gated on both — is independent of every engine that implements it. Spark, Flink, a warehouse, or something that does not exist yet can each satisfy it, and every existing definition survives the substitution. This is the one decision in the set that should never need revisiting.
Lesson. When two systems are supposed to agree, do not build a detector for disagreement; build a generator that cannot produce it. A gate at compile time is worth more than any amount of monitoring downstream of it.
Status: Accepted · Shown on views: 12, 13
Where does a feature live that cannot be precomputed — the distance between this courier and this restaurant right now, the time since this user's last order?
Context. Some transformations depend on values only present in the request. They cannot be materialised, so they are computed somewhere at request time. The tempting answer is that this is the model service's business, and that is exactly where the worst skew historically comes from: a haversine distance implemented in Python in the training notebook and in Go in the serving path, with a different earth radius and a different rounding rule. These transformations are simultaneously the smallest part of a feature set and the largest contributor to skew, because they are the only ones where two implementations genuinely exist.
Decision. On-demand features are first-class platform features. They are declared in the same artefact, compiled by the same compiler, and executed by a sandboxed runtime inside the serving path with a hard budget of 2 ms p99. The identical compiled transformation is replayed by the training-set service when assembling history, so the training and serving values come from the same code.
How it is realised on AWS. The compiler emits the transformation as a restricted expression over a fixed input set — request payload fields plus already-fetched feature values — with no I/O and no unbounded loops. The serving API evaluates it in-process with a wall-clock ceiling enforced per call and a circuit breaker per feature. EMR Spark evaluates the same expression as a UDF during point-in-time assembly, reading the request payload from the spine.
| Option |
Verdict |
Reasoning |
| Platform-owned runtime, shared compiled artefact |
Chosen |
Buys parity exactly where skew is most likely, at the cost of consumer code in the serving failure domain |
| Leave request-time transformations to the model service |
Rejected |
Keeps the platform simple and leaves the largest source of skew entirely unaddressed |
| Precompute over a discretised grid and look up |
Rejected |
Works for distance and nothing else; a grid fine enough to be accurate is a table too large to materialise |
| A sidecar the model service calls, owned by the consumer |
Deferred |
Defensible isolation model; revisit if a transformation genuinely needs more than 2 ms |
What it buys
- The transformations most likely to skew are the ones where parity is strongest
- A model service stops carrying feature logic, so its deploy cadence stops being a feature release mechanism
- The point-in-time training set includes request-time features rather than approximating them
What it costs
- Consumer-authored code runs in the serving path's latency budget and failure domain
- The expression language is deliberately restricted, so some transformations will be refused as on-demand features
- The 2 ms budget is a real constraint that will push some logic back to the model service anyway
Choose differently when. If the on-demand surface were more than a small fraction of the feature set, or if the transformations needed I/O, the sandbox would become a general-purpose compute platform inside the serving path and the sidecar option would be right. Held to pure functions over a fixed input set, it stays a compiler feature rather than a runtime.
Why it holds up over time. The principle — the transformation most at risk of skew is the one that must share its implementation — survives any change in how the expression is evaluated. The specific restriction to pure functions may loosen as isolation technology improves, without changing the guarantee.
Lesson. Put the platform's strongest guarantee where the risk actually is, not where it is cheapest to provide. The features that are hardest to own are usually the ones worth owning.
ADR-03 · Streaming features dual-write from one computation; batch features materialise down from offline
Status: Accepted · Shown on views: 13, 09, 07
Is the online store written beside the offline store by the same job, or derived from the offline store after the fact?
Context. Two topologies are available and each fails differently. Dual-write — one computation, two sinks — gives the freshest online value and one code path, but has two sinks that can partially fail, leaving the paths silently divergent with no single place that noticed. Materialise-down — write offline, then project into the online store — makes the offline store unambiguously the source of truth and the online store trivially rebuildable, at the cost of added latency. The mistake is choosing one answer for the whole platform: a five-second freshness SLO on a kitchen-load feature cannot pay for a round trip through an Iceberg commit, and a nightly store-attributes feature has no reason not to.
Decision. Both, chosen per modality rather than per platform. Streaming features dual-write from the same Flink computation to the offline and online stores. Batch features are written to the offline store only, and the online store is materialised down from it as a separate step. Every written value carries its definition version, and nightly skew replay is the detector for the divergence that dual-write makes possible.
How it is realised on AWS. The Flink job writes an Iceberg append and a DynamoDB put from the same operator, with the offline write first so a crash between them loses the online value rather than the record. EMR Serverless writes batch groups to Iceberg; a following job reads the committed snapshot and writes the latest value per entity into DynamoDB. The materialise-down job is idempotent on snapshot id, so a retry is free.
| Option |
Verdict |
Reasoning |
| Dual-write for streaming, materialise-down for batch |
Chosen |
Freshness where it is required, provenance where it is affordable |
| Materialise-down for everything |
Rejected |
One topology, unambiguous truth, and cannot meet a 5 s streaming freshness SLO through a table commit |
| Dual-write for everything |
Rejected |
Uniform and fresh, and makes every batch group's online values as hard to reason about as the streaming ones |
| Online store as a cache populated by read-through from offline |
Rejected |
Simple and turns every cold read into a table scan at p99 |
What it buys
- Each modality gets the topology its freshness SLO can actually pay for
- Batch features — the majority — have a single unambiguous source of truth and a free rebuild
- The materialise-down job's idempotency makes the online store's rebuild path the same code as its normal path
What it costs
- Two write topologies to operate, reason about and document
- Streaming features carry a real partial-failure risk, detected after the fact rather than prevented
- The offline-write-first ordering means a streaming value can be in history before it is servable, which looks like staleness
Choose differently when. If the streaming freshness SLO relaxed to a minute, materialise-down for everything would be the right answer and this record would collapse into one topology. Conversely, if a table format offered second-scale commits with snapshot isolation at this write rate, the same simplification would follow.
Why it holds up over time. The reasoning — pick the write topology from the freshness requirement, not from a preference for uniformity — outlives both topologies. What will change is where the boundary sits, as commit latencies fall.
Lesson. Resist making one choice for the whole platform when the workloads have different requirements. Two topologies with a stated rule for which applies is simpler in practice than one topology that someone has to work around.
ADR-04 · Skew is proven continuously by replaying sampled served vectors through the offline path
Status: Accepted · Shown on views: 18, 17, 09
How does the platform know, today, that its two materialisations still agree?
Context. Every guarantee in ADR-01 and ADR-03 is a claim about code that was correct when it was written. Engines get upgraded, a Flink window's allowed lateness gets tuned, a batch job's partition predicate gets edited, and none of those changes announce that they moved a value. A platform whose central promise is parity and which has no continuous measurement of parity is asking to be trusted rather than earning it. The measurement has to come from production, because the failure is in the difference between production and the training path, not inside either.
Decision. One per cent of served feature vectors are logged with their request id, entity keys and timestamps, configurable to 100% per model. Nightly, those logged vectors are replayed through the offline path as an as-of read at the request's own timestamp, and each feature's served value is compared with the offline value. Disagreement beyond the feature's declared tolerance is a defect attributed to a definition version, and the aggregate is the platform's published skew number.
How it is realised on AWS. The serving API writes sampled vectors through Kinesis Data Firehose to S3, partitioned by model and hour. An EMR Serverless job reads the partition, joins each row against the Iceberg offline store as of the logged timestamp, and writes a skew_measurement row per feature and consumer model to Aurora. The version stamp on both the served value and the offline value is what turns a disagreement into a cause.
| Option |
Verdict |
Reasoning |
| Sampled serving log replayed nightly through the offline path |
Chosen |
The only proof that comes from production; cheap at 1% and exact at 100% |
| Unit tests comparing the two plans on synthetic inputs |
Rejected |
Necessary and insufficient — it tests the compiler, not the running materialisations |
| Compare aggregate distributions of served and training values |
Rejected |
Catches gross drift and misses a per-entity divergence, which is the failure that matters |
| Synchronous dual-read on every request, offline and online |
Rejected |
Exact and impossible inside a 15 ms p99 |
What it buys
- The platform's central claim carries a number, published per feature and per consumer
- A regression is dated and attributed to a definition version rather than argued about
- The serving log doubles as training data with exactly the inputs production used
What it costs
- Nightly cadence dates a regression to a day, not an hour, so this is a proof and not an alarm
- The serving log is a copy of feature values and inherits their sensitivity classification
- A 1% sample will not find a divergence confined to rare entities, which is the case sampling is worst at
Choose differently when. If serving traffic were small enough to log entirely and replay hourly, replay would become the alarm as well as the proof and the per-consumer health view would matter less. At 320,000 reads a second, 1% is already 3.2 million vectors a second sampled down to a manageable dataset.
Why it holds up over time. Replaying production inputs through the batch path to test agreement is a technique, not a product, and it will still be the cheapest available proof of parity a decade from now. The sampling rate and the cadence will change with the cost of compute.
Lesson. A guarantee without a continuous measurement is a hope. Decide early what number would falsify your central claim, and then pay to produce it every night.
Correctness in time
Timestamps, as-of joins and late data — how the platform avoids training on the future.
ADR-05 · Every offline value carries event time and ingestion time; a feature without a reliable ingestion time is refused
Status: Accepted · Shown on views: 11, 14, 09
When a training row says 19:42, which version of "orders in the last 15 minutes" should it see?
Context. The answer that feels obvious — the value whose event window ended at 19:42 — is wrong, and wrong in the direction that inflates offline accuracy. At 19:42 in production, the platform did not yet know the 19:42 value: the event was still in flight, the window had not closed, the batch had not landed. A training set built on event time alone therefore trains the model on information the serving path will never have, which is label leakage wearing the costume of a join condition. It is invisible in evaluation, because the evaluation set has the same leak.
Decision. Every value written to the offline store carries two timestamps: event time, when the fact became true in the world, and ingestion time, when the platform could first have read it. Point-in-time joins select on ingestion time. A feature whose source cannot supply a reliable ingestion time is refused registration for offline materialisation rather than approximated.
How it is realised on AWS. Iceberg tables carry event_ts and ingest_ts columns, with event date as a partition key for pruning and ingest_ts written by the materialising engine at commit time rather than derived from the payload. The as-of join predicate is ingest_ts <= spine_ts. The compiler refuses a definition whose source declaration does not establish how ingestion time is obtained.
| Option |
Verdict |
Reasoning |
| Both timestamps, join on ingestion time, refuse features that cannot supply it |
Chosen |
The only join that reproduces what production could actually read |
| Event time only |
Rejected |
Simplest schema and systematically leaks future information into training |
| Event time plus a fixed per-feature ingestion lag estimate |
Rejected |
Cheap approximation whose error is largest exactly when the pipeline is late, which is when it matters |
| Processing time only |
Right elsewhere |
Right for a platform whose features are all stream-computed with negligible lag; it cannot express a late-arriving fact |
What it buys
- A training row sees what production would have seen, which is the definition of point-in-time correctness
- Late arrival becomes representable rather than a source of silent error
- Leakage becomes a detectable condition — ingestion lag exceeding the spine's own horizon — rather than an unexplained accuracy drop
What it costs
- Storage and write cost for a second timestamp on 2.6 billion values a day
- Some features are refused, which will be read as the platform being obstructive
- Joining on ingestion time rather than event time defeats naive event-date partition pruning and makes the join more expensive
Choose differently when. If every source emitted into a single log with negligible and bounded lag, event time and ingestion time would be within milliseconds and one column would do. A marketplace with nightly warehouse dimensions and a third-party weather feed is nowhere near that, and never will be.
Why it holds up over time. The gap between when a fact becomes true and when a system can know it is created by physics and partitions, not by a vendor. Any platform that wants reproducible training data will need both columns, whatever it is built on.
Lesson. Model the difference between what was true and what was knowable. Systems that collapse the two produce training data that flatters them.
Status: Accepted · Shown on views: 14, 10, 11
Which layer is responsible for producing an as-of value — the store or the query?
Context. Two places can own it. A table format with snapshot isolation and time travel makes an as-of read native, cheap to get right and hard to bypass, but it answers "as of a commit" rather than "as of this row's timestamp", and it has no concept of a maximum lookback or a per-feature tolerance. A join engine above a plainer store can express all of that, and is portable across stores, but re-implements correctness on every query path and can be bypassed by anybody with read access to the bucket.
Decision. Split it. The table format owns snapshot isolation and the physical as-of read, so that a training job reads a stable view while materialisation writes, and so a snapshot id is a pinnable input. The join engine owns the semantics the format has no opinion on: the per-row as-of predicate, the declared maximum lookback, reason-coded nulls, and per-feature tolerance. Direct reads of the offline store are permitted for batch scoring but are not point-in-time joins and are not described as such.
How it is realised on AWS. Iceberg on S3 with the Glue Data Catalog provides snapshot isolation and time travel; the training-set service pins a snapshot id per table and records it in the manifest. EMR Spark executes the as-of join with ingest_ts <= spine_ts and a lookback floor of spine_ts minus the feature's declared window, emitting a reason code where no value falls inside it. Lake Formation grants govern the direct read path.
| Option |
Verdict |
Reasoning |
| Snapshots in the format, semantics in the engine |
Chosen |
Each layer owns what it can actually enforce |
| Everything in the join engine over plain Parquet |
Rejected |
Portable, and gives up snapshot isolation, so a long training job races a materialisation commit |
| Everything in the format, via as-of-commit reads only |
Rejected |
Cheapest and cannot express a per-row timestamp, a lookback or a tolerance |
| A dedicated point-in-time serving engine in front of the store |
Deferred |
Worth revisiting if join cost rather than join correctness becomes the constraint |
What it buys
- A training job and a materialisation run can proceed concurrently without a lock or a freeze window
- The snapshot id becomes a pinnable input, which is what makes a regenerated training set bit-identical
- Lookback and tolerance are declared per feature and enforced in one place
What it costs
- Two layers to understand when debugging a wrong training value
- The direct read path exists and is not point-in-time, which is a foot-gun that has to be documented and named
- Iceberg metadata growth at 2.6 billion writes a day needs its own compaction and expiry operation
Choose differently when. If the store offered per-row as-of semantics and a lookback predicate natively, the engine's role would shrink to reason codes and this would become one layer. If snapshot isolation were unavailable, the whole design would need a freeze window during training-set generation, which at 45 models would be unworkable.
Why it holds up over time. The split follows a durable rule: put a guarantee in the layer that can enforce it against every access path, and put policy in the layer that can express it. Table formats will keep absorbing semantics upward, which moves the line without changing the rule.
Lesson. When two layers could own a guarantee, ask which one can be bypassed. Physical isolation belongs where it cannot be, and policy belongs where it can be read.
ADR-07 · Late-arriving events are accepted and change future training sets, but never restate a generated one
Status: Accepted · Shown on views: 14, 11, 21
A courier's position from 19:38 arrives at 19:51, after values from 19:45 are already written. What happens to it, and to the training sets built in between?
Context. Late arrival is the normal case, not the exception: mobile networks partition, the weather feed batches, the warehouse lands at six in the morning. Three responses are available and two are wrong. Dropping the event loses real information and biases the history towards well-connected couriers. Rewriting history in place makes a training set silently different from the one that was evaluated, which destroys the reproducibility everything else in this design is built on. The third response — accept it, timestamp it honestly, and let it affect only what has not yet been produced — is the only one consistent with ADR-05.
Decision. A late event is accepted and written with its true event time and its true ingestion time. Because point-in-time joins select on ingestion time, it becomes visible to any training set generated after it landed and invisible to any generated before. Already-generated training sets are never restated. A generated set's manifest records the snapshot ids that produced it, so its exact content remains derivable.
How it is realised on AWS. Iceberg appends carry the late value into the event-date partition it belongs to, with ingest_ts set at commit. Flink is configured with bounded allowed lateness for window computation and routes later arrivals to the offline store only, so a closed window is not silently recomputed in the online store. No update or delete is issued against a historical value.
| Option |
Verdict |
Reasoning |
| Accept, timestamp honestly, affect only future sets |
Chosen |
Preserves both the information and the reproducibility |
| Drop events past the window's allowed lateness |
Rejected |
Simplest and biases history against exactly the entities whose connectivity is worst |
| Recompute affected windows and restate history in place |
Rejected |
Most accurate view of the past and makes every generated training set unreproducible |
| Versioned windows with an explicit restatement event |
Deferred |
Right for a platform with regulatory restatement duties; heavier machinery than a marketplace needs |
What it buys
- No information is discarded, and no already-published dataset changes underneath a model
- The mechanism is one rule rather than a special path: ingestion time does all the work
- A model retrained on the same spine a week later legitimately improves as history fills in
What it costs
- Two models trained a week apart on the same spine can differ, and that will be read as a bug
- A closed window in the online store can be less accurate than the same window offline
- Offline and online values for the same window can differ for legitimate reasons, which complicates skew interpretation
Choose differently when. If the platform owed regulatory restatement — a corrected figure must supersede a published one — versioned windows with explicit restatement events would be required and the no-restatement rule would be unacceptable. A marketplace's training data carries no such duty.
Why it holds up over time. The rule follows from ADR-05 rather than from any product, and it will hold as long as reproducibility is valued above retrospective accuracy. That trade is what makes model development possible at all.
Lesson. Immutability of what you have already published is usually worth more than accuracy of what you published. Let new information change the next answer, not the last one.
Serving inside a request budget
What the online path holds, what it does when a value is missing, and how it stays inside 25 ms.
ADR-08 · The online store holds latest value only, and is a derived, rebuildable projection
Status: Accepted · Shown on views: 10, 07, 15
Is the online store a database the platform must not lose, or a cache it can throw away?
Context. The online store is the most expensive and most read component in the platform: 45 million entities, 320,000 reads a second, inside a 15 ms p99. Treating it as a system of record is the default, and it is the decision that ages worst. It forces strong durability guarantees onto the hottest path, makes cross-region recovery a state-replication problem, makes every schema change a migration, and — most damagingly — makes the store's contents the answer to "what is this feature's value", which is a question the offline store and the definition should answer together.
Decision. The online store holds latest value plus event timestamp plus definition version, per entity and feature group, and nothing else. It is explicitly derived: fully rebuildable from the offline store and the retained stream log, with a rebuild path exercised on a schedule. Its RPO is best-effort and its correctness requirement is absolute.
How it is realised on AWS. DynamoDB with entity_type:entity_id as the partition key and one item per feature group, holding a value map, event timestamp, version id and a per-feature TTL. On-demand capacity absorbs the stated 3× burst. Rebuild is the materialise-down job of ADR-03 run over all groups, idempotent on snapshot id: all groups in 90 minutes, one group in ten.
| Option |
Verdict |
Reasoning |
| Derived latest-value projection, rebuildable |
Chosen |
Inverts the requirements on the hottest store: weak durability, absolute correctness |
| Online store as a durable system of record with history |
Rejected |
Familiar, and makes the most expensive store also the one that must never be lost |
| In-memory store with periodic snapshots |
Rejected |
Fastest reads and a cold-start problem measured in tens of minutes at 45M entities |
| Read-through cache in front of the offline store |
Rejected |
Minimal storage and turns a cold read into a table scan at exactly the wrong percentile |
What it buys
- Regional recovery is a rebuild rather than a state failover, which is why a 15-minute RTO is credible
- Online materialisation becomes a cost lever: a feature nobody reads online need not be stored online
- A partition loss is an availability event, never a data-loss event
What it costs
- The 90-minute rebuild is a hard dependency, and one that rots quietly unless it is run in anger
- Holding latest value only means the online path cannot answer any historical question, by design
- During a rebuild the platform is serving from a partially populated store, which must be visible to consumers as staleness
Choose differently when. If the offline store could not reconstruct the online state — features computed from a stream with retention shorter than the rebuild window, or from a source that cannot be replayed — the online store would be the only copy and would have to be treated as one. The seven-day stream log is what buys this decision.
Why it holds up over time. As long as the online store is a projection, its technology is an implementation detail and its loss is an inconvenience. That property is what makes the rest of the platform able to change stores without changing guarantees.
Lesson. Decide which of your stores you are allowed to lose, and then make sure the expensive one is on that list. Durability spent on derived state is durability taken from somewhere it was needed.
ADR-09 · Absence is a value with a reason code; criticality and absence policy belong to the consumer
Status: Accepted · Shown on views: 12, 21, 05
A feature group is unreachable at 19:40. Does the request fail, get a default, or get the last known value?
Context. All three are correct answers for different models. A payment-risk model would rather refuse to score than score without its velocity features. A store-ranking model would far rather rank slightly worse than show an empty screen. An ETA model can use a kitchen-load value that is four minutes old and cannot use one that is an hour old. The failure mode to design against is none of these three: it is the silent zero, where a missing value is substituted with a plausible number and the model's output changes with nothing in the system recording that anything happened. That is the single most expensive bug this platform can ship, because it is indistinguishable from the model being wrong.
Decision. Every feature response carries a per-feature status and, where a value is absent, a reason code and the feature's declared default — the same default the training path applies. Whether an absent feature degrades the model or fails the request is declared by the consumer per feature group as a criticality level, recorded as a consumer pin. The platform never substitutes a value without saying so.
How it is realised on AWS. The serving API's gRPC response is a value map plus a parallel status map with codes for OK, STALE, MISSING, QUARANTINED and DENIED, each carrying the value's age. Criticality and absence policy live in the consumer_pin table in Aurora and are resolved into the compiled plan the serving tier caches. A critical group's absence returns an error status for the whole call rather than a partial vector.
| Option |
Verdict |
Reasoning |
| Explicit status per feature, criticality declared per consumer |
Chosen |
The only option where the model owner chooses their own failure mode |
| Always fail the request on any missing feature |
Rejected |
Safest for correctness and turns one stale group into a platform-wide outage |
| Always substitute the declared default silently |
Rejected |
Highest availability and produces wrong answers nobody can attribute |
| Absence policy declared on the feature rather than the consumer |
Rejected |
Simpler to model and wrong, because the same feature is critical to one model and incidental to another |
What it buys
- A model owner chooses their own failure mode and can be held to it
- Degradation is observable end to end, so an accuracy change has a cause in the logs
- Applying the same default in training and serving removes a whole class of skew
What it costs
- The response contract is wider, and every consumer has to handle a status map rather than a value map
- Per-consumer policy has to be resolved into the serving path without the serving path becoming a policy engine
- A consumer that declares nothing gets the platform default, which may not be the right failure mode for it
Choose differently when. If every consumer shared one criticality profile, the policy would belong on the feature and this would be a simpler design. With a fraud model and a ranking model reading the same group, it does not.
Why it holds up over time. The contract — absence is a value, and the consumer chooses what it means — is independent of model architecture and of transport. It will outlive both the gRPC schema and the model generation reading it.
Lesson. Never let a system invent a value silently. An explicit null with a reason is worth more than a plausible number, because only one of the two can be debugged.
ADR-10 · One shared online keyspace now; per-consumer projections only for the heaviest fan-out
Status: Accepted · Shown on views: 12, 08, 17
Does every model read the same multi-tenant online store, or does each get the exact vector it needs under one key?
Context. A shared keyspace maximises reuse, minimises storage and means a new consumer costs nothing. It also means a model reading five feature groups performs five key lookups, and tail latency is the maximum of five rather than one. Per-consumer projections — one item holding precisely the vector one model wants — turn that into a single read and make p99.9 predictable, at the cost of write amplification proportional to the number of consumers, and a store whose physical shape follows the model roster, so every new model is a schema change.
Decision. The MVP serves every consumer from one shared keyspace, batching reads across groups in a single call. Per-consumer projections are deferred to phase 3 and introduced only for consumers whose measured fan-out and tail latency justify them, as an additional materialisation of the same definitions rather than a replacement for the shared store.
How it is realised on AWS. One DynamoDB table keyed on entity_type:entity_id with one item per feature group, read with BatchGetItem across the groups a request needs. Hot keys are handled by request coalescing and a short-TTL ElastiCache entry for values immutable within their window. A projection, when introduced, is a second table written by the same materialise-down job under a different plan.
| Option |
Verdict |
Reasoning |
| Shared keyspace with batched multi-group reads |
Chosen |
Reuse and simplicity first; buy predictability only where measurement says it is needed |
| Per-consumer projections from the start |
Rejected |
Best tail latency and makes the store's shape a function of the model roster on day one |
| One item per entity holding every feature |
Rejected |
One read per entity and a write amplification that makes any single feature update rewrite everything |
| Projections as the only store, no shared keyspace |
Right elsewhere |
Right for a platform with few, very high-traffic models; it gives up ad-hoc consumption entirely |
What it buys
- A new consuming model costs no storage and no new materialisation
- One definition, one physical representation, so there is one place a value can be wrong
- Projections remain available as an optimisation with evidence behind it
What it costs
- Tail latency for a wide-fan-out consumer is the maximum of its group reads, not the mean
- Hot keys concentrate across all consumers rather than per consumer, so one popular store affects everyone
- The phase-3 projection work is real and is being deferred rather than avoided
Choose differently when. If one model's fan-out reached ten groups, or if the p99.9 budget tightened below 40 ms, projections would move from phase 3 into the MVP. The decision is a measurement bet, and the measurement is the per-consumer read latency in view 17.
Why it holds up over time. The principle — start with the shared representation and buy a specialised one only with evidence — holds across store technologies. What changes is the fan-out at which the trade flips, which falls as multi-key reads get cheaper.
Lesson. Defer the optimisation that makes your storage layout depend on your consumer list. That coupling is easy to add later and very hard to remove.
Reuse, versioning and accountability
The decisions that decide whether nine teams share one definition or build nine.
ADR-11 · The feature version is the unit of versioning, of pinning and of training-set provenance
Status: Accepted · Shown on views: 11, 16, 18
When a definition changes, what exactly changed — the feature, the group it sits in, or the repository commit?
Context. Three granularities are available. Per-commit versioning is simplest and reproducible, and couples unrelated changes: one team's edit forces another team's re-validation, and a training set can only say "built at commit abc123", which is true and useless. Per-group versioning matches the materialisation unit and is too coarse — changing one feature's window reversions forty others. Per-feature versioning gives the smallest blast radius and the most honest consumer pin, at the cost of a group whose features are at different versions and therefore whose storage layout is heterogeneous.
Decision. The feature version is the unit. A change to a transformation, window or data type creates a new immutable version; the previous version stays published and consumers pinned to it stay there until they move. Every written value carries its version id, and a training set's manifest records the exact set of versions it was built from.
How it is realised on AWS. feature_version rows in Aurora hold the transform hash, window specification, lifecycle state and publication time. Both value tables carry version_id. The training-set manifest records the version id per feature alongside the Iceberg snapshot id, which together make a regeneration bit-identical. The registry refuses to retire a version with a live production pin.
| Option |
Verdict |
Reasoning |
| Per-feature immutable versions with consumer pins |
Chosen |
Smallest blast radius, honest provenance, heterogeneous group layout as the price |
| Per-commit versioning of the definition repository |
Rejected |
Trivial to implement and couples every team's changes to every other team's validation |
| Per-feature-group versioning |
Rejected |
Matches materialisation and forces forty unrelated features to reversion for one window change |
| Mutable definitions with an audit log of edits |
Rejected |
Simplest for authors and makes every historical training set unreproducible |
What it buys
- A change affects only its own consumers, so a breaking edit is a conversation with three teams rather than nine
- A training set can name exactly what produced it, which is what ADR-01's guarantee needs to be checkable
- The version stamp on every value is what makes the skew replay in ADR-04 able to attribute a cause
What it costs
- A feature group can hold features at several versions, so its physical layout is not uniform
- Multiple live versions of a feature multiply materialisation variants and therefore storage and compute
- Consumers can stay pinned to an old version indefinitely, which needs a deprecation process with teeth
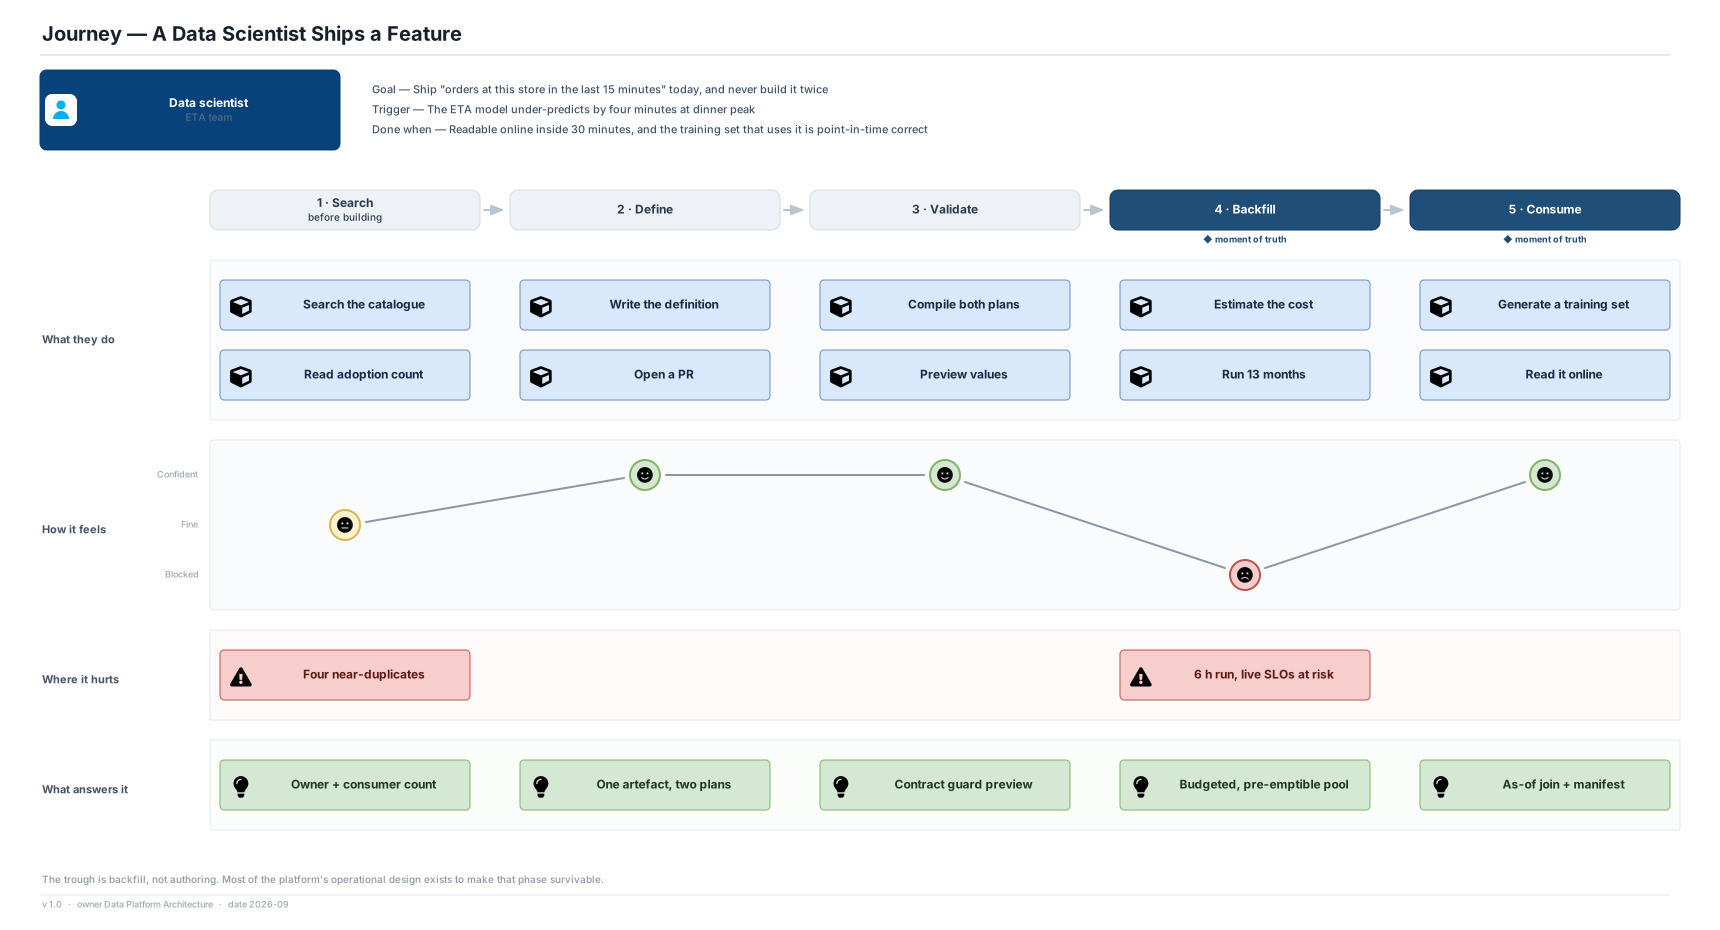
Choose differently when. If backfill were free, versions could be collapsed by re-deriving history whenever a definition changed, and pinning would be unnecessary. Backfill costs six hours per feature per thirteen months, which is precisely why the old version survives.
Why it holds up over time. Immutable versions with explicit consumer pins is the same pattern that governs published APIs and library releases. It has outlasted several generations of tooling and will outlast this one.
Lesson. Version at the granularity at which people actually consume. Coarser versioning makes unrelated teams each other's problem; finer versioning makes storage heterogeneous, which is the cheaper of the two.
ADR-12 · Definitions arrive only through reviewed source control, and near-duplicates are blocked at registration
Status: Accepted · Shown on views: 16, 03, 04
How does a feature get created, and what stops the fourth copy of "orders in the last 30 minutes"?
Context. The platform's organisational value is that nine teams share one definition of a signal. That value is destroyed quietly: a team cannot find the existing feature, or finds it and cannot tell whether its window matches, so they write their own. Six months later there are four features with the same name-ish, three owners, and no way to know which the ETA model is actually reading. A catalogue alone does not prevent this, because searching is optional and shipping is not. Nor does a creation API, which produces features with no review, no history and no duplicate check.
Decision. A feature is created by merging a definition into the repository, never by an API call. At registration the platform compares the definition against every existing one on entity, source and transformation equivalence, and a near-duplicate must be adopted, differentiated, or overridden with a recorded reason. Every group carries a named owning team resolved from the organisation directory, and an unowned group is not materialised.
How it is realised on AWS. GitHub with required review; a GitHub Actions job runs the compiler, the duplicate detector and the contract lint, and publishes to the registry on merge. The detector normalises the compiled offline plan and compares transformation hashes plus source and entity, surfacing candidates in the pull request. Ownership resolves against a nightly snapshot of the org directory, and a group whose owner no longer exists is flagged rather than silently orphaned.
| Option |
Verdict |
Reasoning |
| Source control only, duplicates blocked at registration |
Chosen |
Review and duplicate detection at the one moment the author is paying attention |
| Creation API with a catalogue for discovery |
Rejected |
Fastest authoring and no review, no history, no duplicate check |
| Catalogue plus periodic duplicate reports |
Rejected |
Finds duplicates after both are in production, when neither can be removed |
| Central team authors every feature |
Right elsewhere |
Right for a small platform with few features; at 40 new features a month it is a queue, not a service |
What it buys
- Reuse is enforced at the only moment it is cheap — before the second implementation exists
- Every feature has a review, a history and an author, so its meaning can be reconstructed
- Ownership is a precondition for materialisation, which is what makes a freshness alert reach a human
What it costs
- Authoring is slower than writing a query, and that gap is the platform's main adoption risk
- Transformation equivalence is undecidable in general, so the detector will produce false positives and be overridden
- Organisation directory drift will orphan groups after every reorganisation
Choose differently when. If features were disposable and rarely reused — a research platform where every model brings its own signals — review and duplicate detection would be friction with no return, and a creation API would be right. The nine teams are what make it pay.
Why it holds up over time. Definition-as-code with review has outlasted every generation of data tooling for the same reason it outlasted hand-configured servers: the artefact is diffable, attributable and replayable. Nothing about that depends on the current platform.
Lesson. Put the guardrail at the moment of creation, not in a report. A duplicate found at review is a conversation; a duplicate found in production is a migration nobody will fund.
ADR-13 · Every group declares an owner and a freshness SLO, and staleness is marked rather than hidden
Status: Accepted · Shown on views: 17, 21, 05
When a feature group stops being fresh, who finds out and what does a reader see?
Context. Staleness is this platform's characteristic failure, and it is dangerous precisely because it is not an error. The read succeeds, the value is well-formed and plausible, and the only thing wrong with it is that it describes a world four hours old. A model consuming it produces confidently wrong output, and the first signal anybody gets is a business metric moving. Detecting staleness requires knowing what fresh means for that group, which means somebody has to declare it — and acting on staleness requires a human who is accountable for that group, which means somebody has to own it.
Decision. Every feature group declares a freshness SLO and a named owning team at registration. The platform evaluates the SLO continuously; a group whose newest value exceeds twice its SLO is marked stale within sixty seconds, the marker is returned to every reader alongside the value's age, and the owner is alerted within five minutes. An unowned group is not materialised.
How it is realised on AWS. Freshness SLO is a field on feature_group in Aurora, evaluated by a controller against the newest event timestamp per group and published as an Amazon Managed Prometheus series. The stale marker is resolved into the serving path's cached plan and returned in the per-feature status of ADR-09. Alert routing resolves the owning team from the org directory snapshot.
| Option |
Verdict |
Reasoning |
| Declared SLO per group, staleness marked in the response, owner alerted |
Chosen |
Makes an invisible failure visible to both the reader and the accountable human |
| Platform-wide freshness threshold |
Rejected |
One number for a five-second stream aggregate and a nightly store attribute is no number at all |
| Alert the owner but serve the value unmarked |
Rejected |
The human finds out and the model does not, which is the wrong way round |
| Refuse to serve a stale value |
Rejected |
Correct in principle and converts a degradation into an outage; ADR-09 gives the consumer that choice instead |
What it buys
- The platform's most dangerous failure becomes observable to the code reading it, not just to a dashboard
- Alerts reach a team that can act, because ownership is a precondition rather than an aspiration
- Per-group SLOs let a nightly feature and a five-second feature coexist without one of them being permanently in breach
What it costs
- Every group needs a declared SLO at registration, which is one more thing an author must think about
- A group can be legitimately stale — a store that stopped trading — so the marker needs a TTL story to avoid permanent noise
- Org directory drift means the alert can route to a team that no longer exists
Choose differently when. If every feature were stream-computed with the same freshness expectation, a single platform threshold would be sufficient and the per-group declaration would be ceremony. A mix of 1-minute windows and nightly warehouse dimensions makes it necessary.
Why it holds up over time. Declared SLOs with per-reader visibility is the same pattern that made service reliability measurable. It transfers to data with no modification and is unaffected by the technology underneath.
Lesson. A failure that does not look like a failure needs a declared expectation before it can be detected at all. Ask for the number at creation time, when the author still knows it.
Durability, cost and recovery
What can be thrown away, what must not be, and what a backfill is allowed to disturb.
ADR-14 · Backfill runs in an isolated, budgeted, pre-emptible pool and writes online only where a consumer reads online
Status: Accepted · Shown on views: 13, 15, 04
A new feature needs thirteen months of history. What is that allowed to disturb, and what is it allowed to cost?
Context. Backfill is not an exceptional operation in a feature store; it is how every new feature and every changed definition becomes usable. It is also the largest single compute and write event the platform ever performs, and it is naturally unbounded: the author wants all of history, at full grain, now. Run on the same capacity as scheduled materialisation, it delays the morning batch wave; run without a cost estimate, it produces an invoice nobody approved; and written naively to the online store, it rewrites 45 million entities for a feature no model reads online yet.
Decision. Backfill runs in a resource pool separate from scheduled materialisation, pre-emptible by live jobs, over a declared and bounded window. Its cost is estimated and shown before execution and is gated against a budget at review time. It writes to the online store only for features a consumer actually reads online; offline-only features are backfilled offline only.
How it is realised on AWS. A second EMR Serverless application with its own capacity limits, submitted by the backfill runner with a declared partition range. The estimate is derived from partition counts and historical DPU-per-partition and surfaced in the pull request by the same job that runs the compiler. The online write is conditional on the feature's online flag and on a non-zero consumer pin count.
| Option |
Verdict |
Reasoning |
| Isolated, budgeted, pre-emptible pool; online write only where read |
Chosen |
Treats a routine operation as a first-class one with its own capacity and its own price |
| Backfill on the scheduled materialisation capacity |
Rejected |
No new infrastructure and one backfill delays every group's morning landing |
| Backfill only during a declared maintenance window |
Rejected |
Protects serving and turns a 30-minute time-to-production into a next-week promise |
| Backfill on demand at read time, lazily |
Rejected |
No upfront cost and makes the first training set over a new feature unboundedly slow |
What it buys
- A backfill can never take a dinner-peak read or a morning batch wave with it
- Cost is a review comment rather than an invoice, which changes the conversation before the spend
- Skipping the online write for offline-only features removes the largest avoidable write in the platform
What it costs
- A second compute pool to size, monitor and pay for even when idle
- Pre-emption means a long backfill can be interrupted and must be restartable at partition grain
- The cost estimate is a model and will be wrong, most likely on the features with the most skewed partitions
Choose differently when. If backfills were rare — a stable feature set with few definition changes — a maintenance window on shared capacity would be the right answer and the second pool pure cost. At forty new features a month, backfill is a daily operation.
Why it holds up over time. Isolating a bursty, low-priority, high-volume workload from a latency-critical one is a structural decision that survives any change of engine. What will change is the price of the isolated capacity, which is falling.
Lesson. The operation you treat as exceptional is the one that will take production down. If it happens weekly, give it its own capacity, its own budget and its own restart semantics.
ADR-15 · Region loss is met by rebuilding the online store in a warm second region, not by replicating serving state
Status: Accepted · Shown on views: 15, 10, 21
The serving region is gone. Where does the next feature vector come from, and how long does it take?
Context. The obvious answer is to replicate the online store and fail over, and for a system of record that would be right. Here it is expensive for the wrong reason: the online store is the largest and hottest component, so replicating it continuously doubles the platform's dominant cost to protect data that ADR-08 already established is derivable. The alternative extreme — a cold second region — cannot meet any credible RTO, because bringing up a serving tier and populating 45 million entities from scratch is measured in hours.
Decision. The second region runs warm at ten per cent of serving capacity, with the offline store replicated cross-region and the online store present as a replica that is not relied upon for correctness. On regional loss, the serving tier scales out and the online store is rebuilt or completed from the replicated offline state, targeting a fifteen-minute RTO with an explicit latency-SLO breach during the scale-out.
How it is realised on AWS. S3 cross-region replication carries the Iceberg data and metadata; a DynamoDB global table gives the second region a warm replica that shortens the rebuild rather than guaranteeing it. EKS node groups in the second region run at ten per cent with a scaling policy triggered by the failover event, and the materialise-down job of ADR-03 runs against the replicated snapshot to complete any gaps.
| Option |
Verdict |
Reasoning |
| Warm second region, online store rebuilt from replicated offline state |
Chosen |
Buys a credible RTO without doubling the most expensive tier |
| Active-active with fully replicated online state |
Rejected |
Best RTO and roughly doubles serving and storage cost for state that is derivable |
| Cold standby, infrastructure as code only |
Rejected |
Cheapest and cannot populate 45M entities inside any RTO worth stating |
| Accept single-region availability and degrade models to their defaults |
Right elsewhere |
Right where models are advisory; an ETA and a fraud score on the checkout path are not |
What it buys
- A 15-minute RTO on the read path without paying continuously for a second full-size online store
- The recovery path is the platform's normal materialise-down job, so it is exercised by ordinary operation
- The decision follows directly from ADR-08, so there is one reason the online store is cheap to lose rather than two
What it costs
- The first minutes after failover are served by a tier that is still scaling, so the latency SLO is breached before it is met
- Warm-at-ten-per-cent is a permanent cost for capacity that is almost never used
- The RTO depends on a rebuild whose measured duration must be tracked, not assumed
Choose differently when. If regulation required continuous multi-region availability with no degradation, active-active would be mandatory and the cost argument irrelevant. If the models were advisory rather than on the checkout path, cold standby would be defensible.
Why it holds up over time. Recovering derived state by recomputing it rather than replicating it gets cheaper every year as compute costs fall relative to storage and egress. The decision's economics improve with time rather than eroding.
Lesson. Before paying to replicate state, ask whether you could recompute it inside the same recovery objective. For derived data the answer is usually yes, and usually cheaper.
Access and data protection
Who may read a feature, on what basis, and what happens to the evidence trail.
ADR-16 · Sensitivity classification is enforced at registration, and the serving log inherits the highest class it contains
Status: Accepted · Shown on views: 19, 11, 20
What stops a restricted column becoming an ordinary feature that somebody logs at full sampling?
Context. A feature store is a machine for moving data from restricted places into convenient ones. A transformation over a table containing a card fingerprint or a home address produces a number, and a number does not look sensitive. Once that number is in a general-purpose group, it is readable by any consumer authorised for the group, materialised into a store with weaker controls, and copied into the serving log — which, at the default sampling rate, becomes an unclassified partial replica of restricted data. Checking this at read time is too late, because by then every copy already exists.
Decision. Every feature group carries a sensitivity classification declared at registration. The compiler refuses a definition that derives from a source column of higher classification than its target group. Features derived from personal data additionally declare a lawful basis and purpose, and a consumer must be authorised for the purpose and not merely for the group. The serving log inherits the classification of the most restricted group in the vector it sampled.
How it is realised on AWS. The compiler resolves source column classifications from the Glue Data Catalog and Lake Formation tags and fails the build on escalation. Restricted groups are encrypted with a customer-managed KMS key; Firehose writes the serving log to a prefix whose classification is set from the vector's maximum class, with its own KMS key and its own grants. Entity erasure removes online values within 24 hours and offline values within 30 days.
| Option |
Verdict |
Reasoning |
| Classification enforced at registration; log inherits maximum class |
Chosen |
Prevents the copy rather than governing it afterwards |
| Classification checked at read time |
Rejected |
Cheap to implement and every copy already exists by the time it fires |
| Manual review of definitions by data governance |
Rejected |
Correct in principle; two people cannot review forty definitions a month against 1.1M entities |
| Forbid features derived from restricted columns entirely |
Right elsewhere |
Right in a regulated setting where the model may not see the data at all; here it removes fraud detection |
What it buys
- Classification escalation becomes impossible to introduce rather than possible to discover
- The serving log stops being the platform's quiet privacy hole
- Erasure has a defined path through both stores and is reflected in future point-in-time joins
What it costs
- Source classification must be accurate in the catalogue, so the platform inherits someone else's metadata quality
- Restricted groups need their own keys and their own grants, which multiplies operational surface
- Offline erasure at 30 days means a join run on day 29 can still return an erased entity's values
Choose differently when. If every source were uniformly classified, the compiler check would be ceremony. If the platform had to prove erasure within 24 hours across both stores, offline erasure would need to become a rewrite-on-demand operation rather than a scheduled compaction.
Why it holds up over time. Enforcing a data-protection property at the point of creation rather than the point of access is the pattern that survives every change of regulation, because it removes the copies that the regulation is about.
Lesson. Governance applied after the copy exists is documentation. Applied at the moment the copy would be created, it is a control.
ADR-17 · Workload identity for every caller, authorisation at feature-group granularity, no shared keys
Status: Accepted · Shown on views: 20, 19, 08
How does the platform know which model is asking, and what is it allowed to see?
Context. A serving path taking 320,000 requests a second from four model services is the natural home of a shared secret: one API key per consumer, checked cheaply. That key is then in a config map, in a CI variable, in somebody's laptop history, and rotating it means coordinating four deployments. Worse, a shared key authenticates a deployment rather than a workload, so a compromised sidecar in an unrelated service can read every feature the model could. Meanwhile a human reading the offline store for training has an entirely different problem: they are authorised for a purpose, not just for a resource.
Decision. Every service-to-service caller authenticates as a workload identity, with no shared API keys anywhere in the platform. Authorisation is evaluated per feature group. A human's offline read is authorised on group ACL plus declared purpose, and the credential issued to them is scoped to the columns that survive both checks. A denied group is refused explicitly and by name, never silently dropped from the returned vector.
How it is realised on AWS. IRSA binds each model service's Kubernetes service account to an IAM role; the serving API resolves the role to an authorised group set held in the registry and caches it with the compiled plan. Human access is corporate OIDC to the registry API, which checks group ACL and purpose before asking Lake Formation for a scoped credential against the Iceberg tables. Grants expire and must be renewed.
| Option |
Verdict |
Reasoning |
| Workload identity per caller, group-granular authorisation, explicit denial |
Chosen |
No secret to rotate, and a narrower vector is never silent |
| Per-consumer API keys checked at the serving edge |
Rejected |
Fastest to build and puts a long-lived shared secret in four deployment pipelines |
| Authorisation per feature rather than per group |
Rejected |
Finer control and pushes access control into the read path and the data model at once |
| Network-level authorisation only, trusted VPC |
Rejected |
Cheapest and makes every workload in the VPC equivalent to every other |
What it buys
- There is no long-lived credential to leak or rotate on the serving path
- A model that loses authorisation for a group learns about it explicitly, so an accuracy change has a cause
- Human and machine access are governed by different checks, which matches the fact that they are different risks
What it costs
- Group granularity means authorising a consumer for a group authorises it for every feature in that group
- Splitting a group for access reasons makes the permissions model influence the materialisation unit
- Resolving purpose for human reads adds a control-plane dependency to a path that would otherwise be pure data
Choose differently when. If features carried genuinely per-feature access requirements, per-feature authorisation would be necessary and the read path would have to absorb the cost. Where that arises, the answer here is a new group, priced rather than hidden.
Why it holds up over time. Short-lived, platform-issued workload identity has replaced shared secrets everywhere it has been available, and the direction of travel is one-way. The mechanism will change; the absence of a shared key will not.
Lesson. Authenticate the workload, not the deployment, and refuse out loud. A silently narrower answer is worse than an error, because only the error gets investigated.
Every package used, in one table
The terms below are used precisely in this package. Several are used loosely in the wider feature-store literature, and the difference matters when reading the decision records.
| Package |
What it is |
What it does here |
Considered instead |
| Feature |
A named, typed signal about one entity, defined declaratively and materialised by the platform. |
The unit of definition, versioning and consumer pinning. |
A column in a training table, which is a feature's output rather than the feature. |
| Feature group |
A set of features sharing an entity key, a source and a refresh cadence. |
The unit of materialisation, authorisation, freshness SLO and ownership. |
A namespace, which carries none of those four responsibilities. |
| Offline store |
The full history of every materialised value, carrying both event and ingestion timestamps. |
The source of truth for batch features and the origin of every rebuild. |
A data warehouse, which holds the sources rather than the materialised features. |
| Online store |
Latest value per entity and group, plus event timestamp and definition version. |
A derived, disposable projection read inside a user-facing request. |
A cache, which implies a read-through path this design deliberately does not have. |
| Point-in-time correctness |
Every value in a training row is the one whose ingestion timestamp was at or before that row's timestamp. |
The property that makes a training set reflect what production could actually have read. |
An as-of-event-time join, which selects values the platform did not yet know and inflates offline accuracy. |
| Event time and ingestion time |
When the fact became true, and when the platform could first have read it. |
The two columns on every offline value; joins select on ingestion time. |
Processing time, which cannot represent a late-arriving fact. |
| Training–serving skew |
A difference between the value a model was trained on and the value it is served, beyond the feature's declared tolerance. |
The defect the whole architecture exists to make detectable and attributable. |
Data drift, which is the world changing rather than the platform disagreeing with itself. |
| Materialise down |
Writing the online store from a committed offline snapshot rather than from the original computation. |
The write path for batch features, and the rebuild path for every feature. |
Dual-write, which is the write path for streaming features only. |
| On-demand feature |
A transformation over request payload and fetched values, computed at read time from the shared definition artefact. |
The parity boundary: the features most likely to skew, and the ones where parity is strongest. |
A derived field in the model service, which is where this skew traditionally comes from. |
| Spine |
The entity-and-timestamp rows a consumer supplies to request a training set. |
The left side of every point-in-time join, and one of the three pinned inputs in the manifest. |
A label set, which is what the spine usually carries but is not what the platform needs from it. |
| Criticality |
A consumer's declaration of whether an absent feature degrades its model or fails its request. |
What decides between a partial vector and an error, per consumer and per group. |
A feature's importance, which is a modelling property and not a platform contract. |
| Backfill |
Materialising a new or changed feature over historical data in a bounded, budgeted window. |
A routine daily operation with its own capacity, not an exceptional one. |
A migration, which happens once; a backfill happens with every new feature. |