Discord Bot Platform · Solution Architecture v1.0 · Microsoft Azure · Integration Platform Architecture · 2026-10 · 19 views · 12 architecture decision records
The argument these decisions serve is summarised in the Architecture One-Pager.
Twelve decisions make up this architecture. Everything else across the nineteen views is convention, sizing or consequence. Each record states the forcing question, the context that makes it hard, what was decided, how it is realised on Microsoft Azure, the options weighed, what the choice buys and costs, the conditions that would flip it, why it should still be right in ten years, and the lesson worth carrying to a different system.
Status of this document. This is a design, not a report on a running system. It is modelled on the public Discord developer documentation, and every rate, latency, volume, retention and window is the requirement's stated assumption for a large consumer chat service — 150 M monthly users, 2.5 M bots online, 400,000 events per second delivered — invented to be defensible and arguable. They should be replaced with measured telemetry before build, and three in particular are the first numbers real data should overturn: the 120-second resume window, which decides per-session memory; the 10-second revocation lease, which decides registry load; and the 3-second acknowledgement, which the interaction product depends on.
How to read a record
- Question: The forcing question: why a decision was needed at all.
- Context: The requirement, the scale and the constraint that make it hard.
- Decision: What this architecture does, stated so it can be checked.
- How it is realised on Microsoft Azure: The concrete mechanism: which service or package, configured how, in which project.
- Options weighed: Chosen, rejected, deferred, or right elsewhere, with the reason for each.
- Consequences: What the choice buys and what it costs, both kept visible.
- Choose differently when: The conditions that would flip the decision for your system.
- Why it holds up over time: What keeps the decision right as scale, staff and technology change.
- Lesson: The principle that transfers beyond this platform.
Decision map
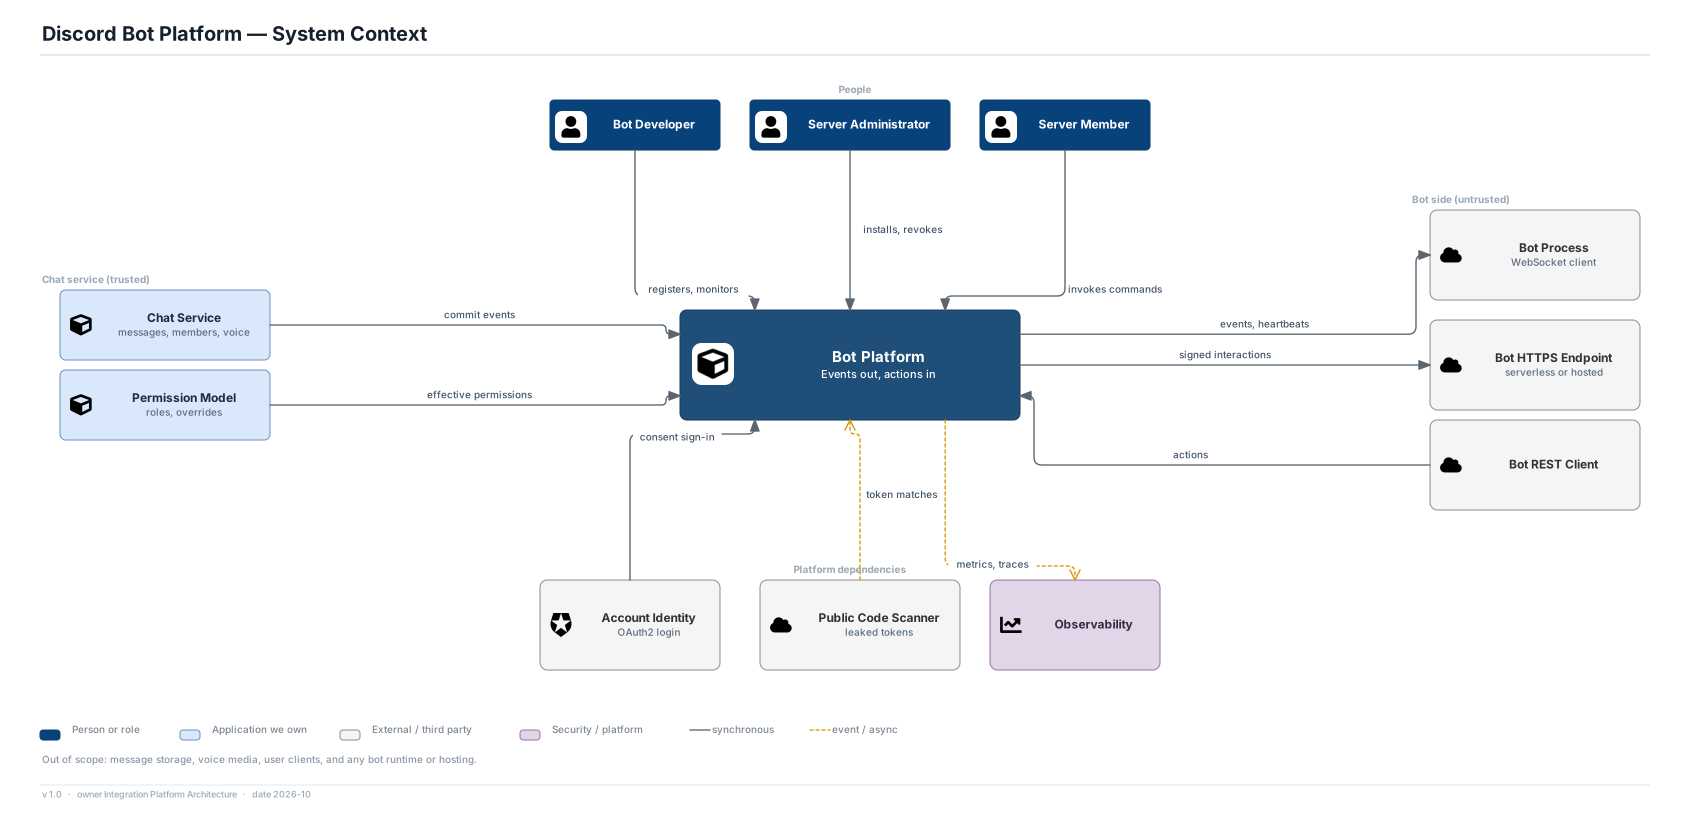
Trust boundary: Where the chat service stops depending on anything a bot does.
- ADR-01 · The chat service never waits on a bot
Fan-out: How an event finds the bots entitled to it, and how it is placed.
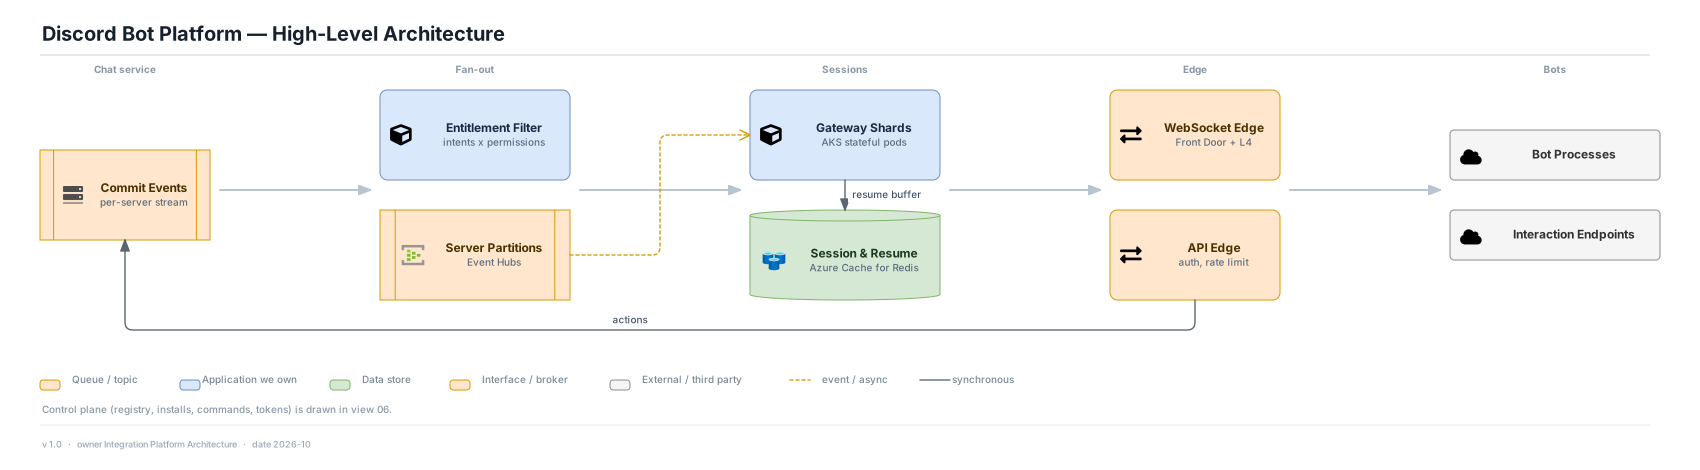
- ADR-02 · Entitlement is enforced before serialisation; the shard is a computed address
- ADR-05 · Partition by server, not by bot
Interactions: The three-second window and what happens when it expires.
- ADR-03 · A published three-second acknowledgement, with deferral
Delivery contract: What a bot may rely on, stated with its loss boundary.
- ADR-04 · At-most-once beyond 120 seconds, ordered at-least-once inside it, with bounded buffers
Authority: Who owns a grant, and when it is evaluated.
- ADR-06 · The server owns the installation, evaluated at request time
Resilience: How a fleet recovers without becoming the outage.
- ADR-07 · Reconnects are directed, jittered and throttled
Revocation: How a changed grant bites on an open session.
- ADR-08 · Revocation propagates by push, bounded by a short lease
API: How limits are expressed to bots.
- ADR-09 · Rate limits are per route bucket, and tell the client what to do
State: Which state is precious and which is rebuilt.
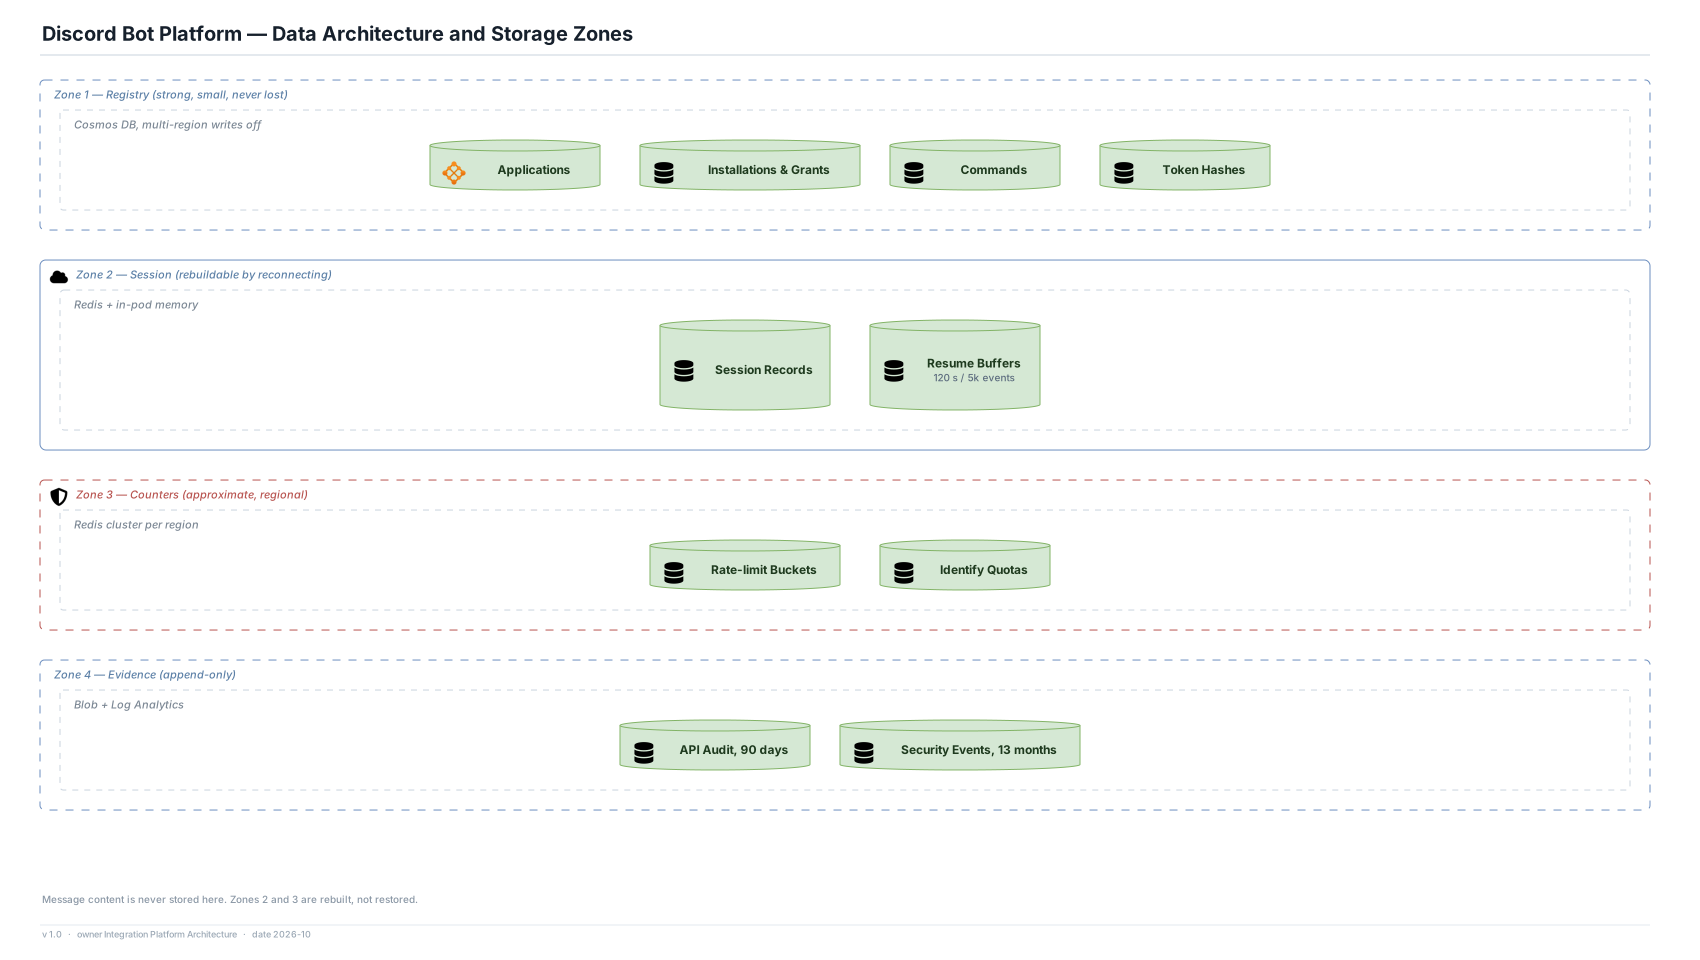
- ADR-10 · State is classed by how it can be lost
Egress: Calling stranger-chosen URLs safely.
- ADR-11 · Everything bot-supplied is hostile, and egress is its own zone
Identity: Credentials, scope and leaks.
- ADR-12 · Tokens are scoped, hashed and scanned for
Technology by capability
Every capability and what it is realised with, the origin of that choice, the alternative that was weighed, and the record that argues it. The requirement stays vendor-neutral; this table is where the architecture commits.
| Capability |
Choice |
Origin |
Credible alternative |
Why this one |
Record |
| Gateway sessions |
AKS StatefulSet, one pod group per shard range |
Azure |
Service Fabric or VMs |
Sockets are stateful and pinned to a shard; StatefulSet gives stable identity and graceful drain. |
ADR-02 |
| Event distribution |
Event Hubs, partitioned by server_id |
Azure |
Service Bus topics |
Ordered, partitioned, high-throughput log with consumer groups; topics lack the ordering and rate profile. |
ADR-05 |
| Registry |
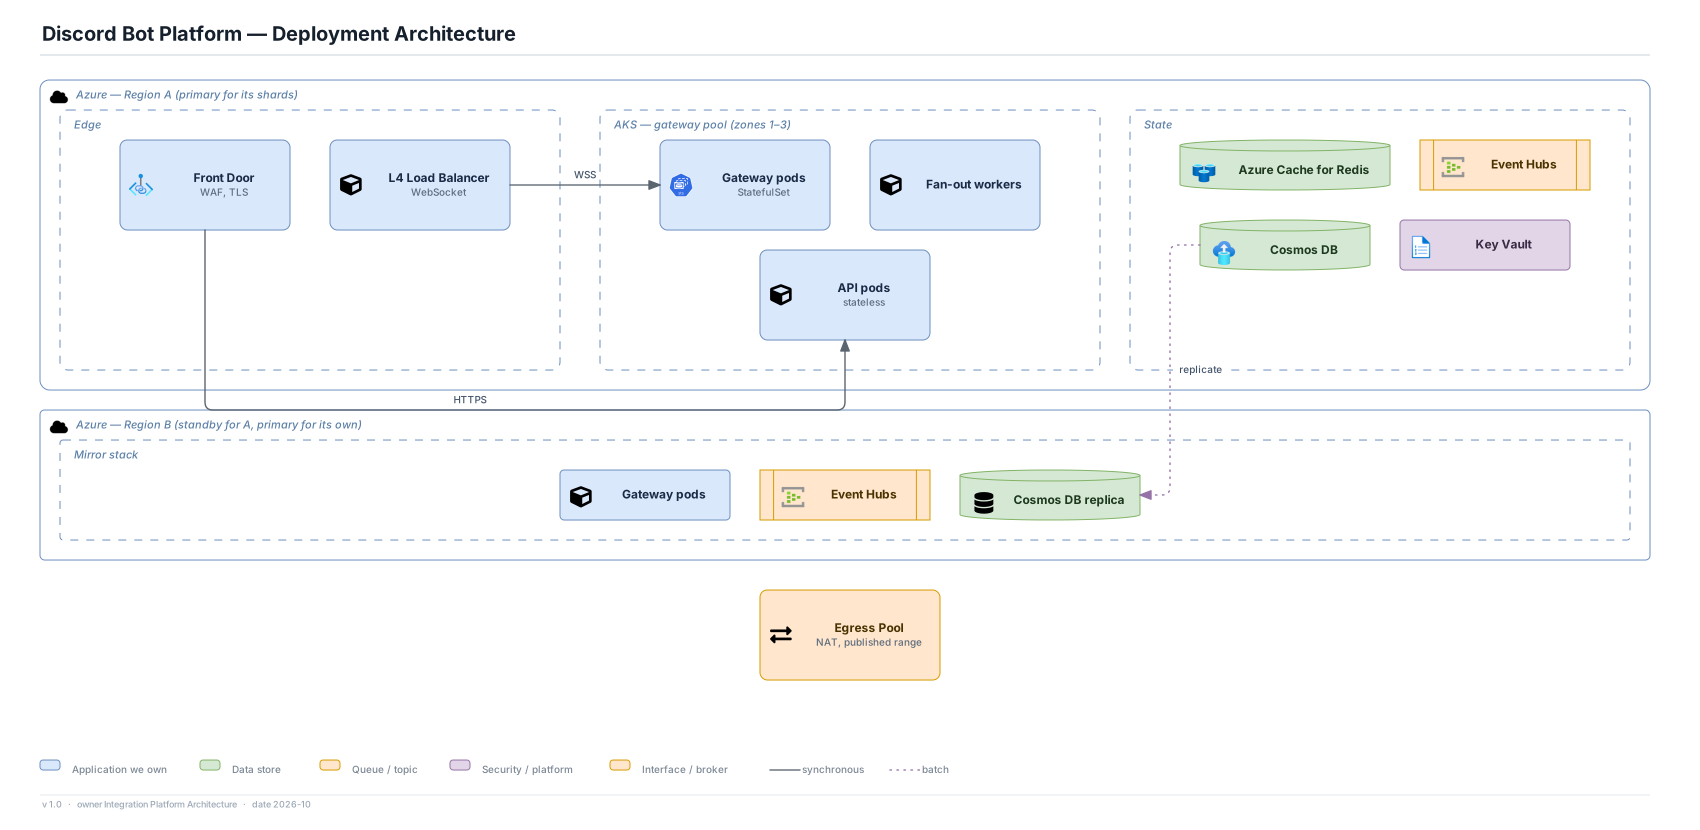
Cosmos DB, single-write region, zone redundant |
Azure |
Azure SQL |
Small, read-heavy, point-read dominated, globally replicable with a tunable consistency level. |
ADR-10 |
| Session and counters |
Azure Cache for Redis, regional, no cross-region replication |
Azure |
In-pod memory only |
Rebuildable state with sub-millisecond access; cross-region replication would add cost for state that is cheaper to rebuild. |
ADR-04 |
| Edge |
Front Door with WAF, L4 load balancer for WebSockets |
Azure |
Application Gateway |
Global entry and TLS offload for HTTPS; long-lived WebSockets need a layer-4 path. |
ADR-07 |
| Revocation fan-out |
Event Grid |
Azure |
Redis pub/sub |
Reliable push with retry and dead-lettering to every node; pub/sub loses messages on disconnect. |
ADR-08 |
| Token storage |
Key Vault, salted hashes |
Azure |
Application-level encryption |
Managed key custody and audit with no custom crypto. |
ADR-12 |
| Egress |
Dedicated AKS pool, NAT with fixed public IPs |
Azure |
Azure Firewall only |
Fixed range for allowlists and topological containment. |
ADR-11 |
| Evidence |
Blob storage plus Log Analytics |
Azure |
Cosmos DB audit container |
Append-only retention at low cost; query via Log Analytics. |
ADR-10 |
The decisions, and the alternatives that lost
Trust boundary
Where the chat service stops depending on anything a bot does.
ADR-01 · The chat service never waits on a bot
Status: Accepted · Shown on views: 01, 02, 06, 12
Does anything on the chat service's path depend on a bot being up, fast or correct?
Context. A bot is code the platform neither wrote nor hosts. It will be slow, offline, buggy, or malicious, and the platform has 150 M humans using a chat service whose latency does not care about any of that. The obvious integration calls bots inline: on a message, find the installed bots and notify them. Every variant that keeps bots on the path makes a human's message latency a function of a stranger's uptime.
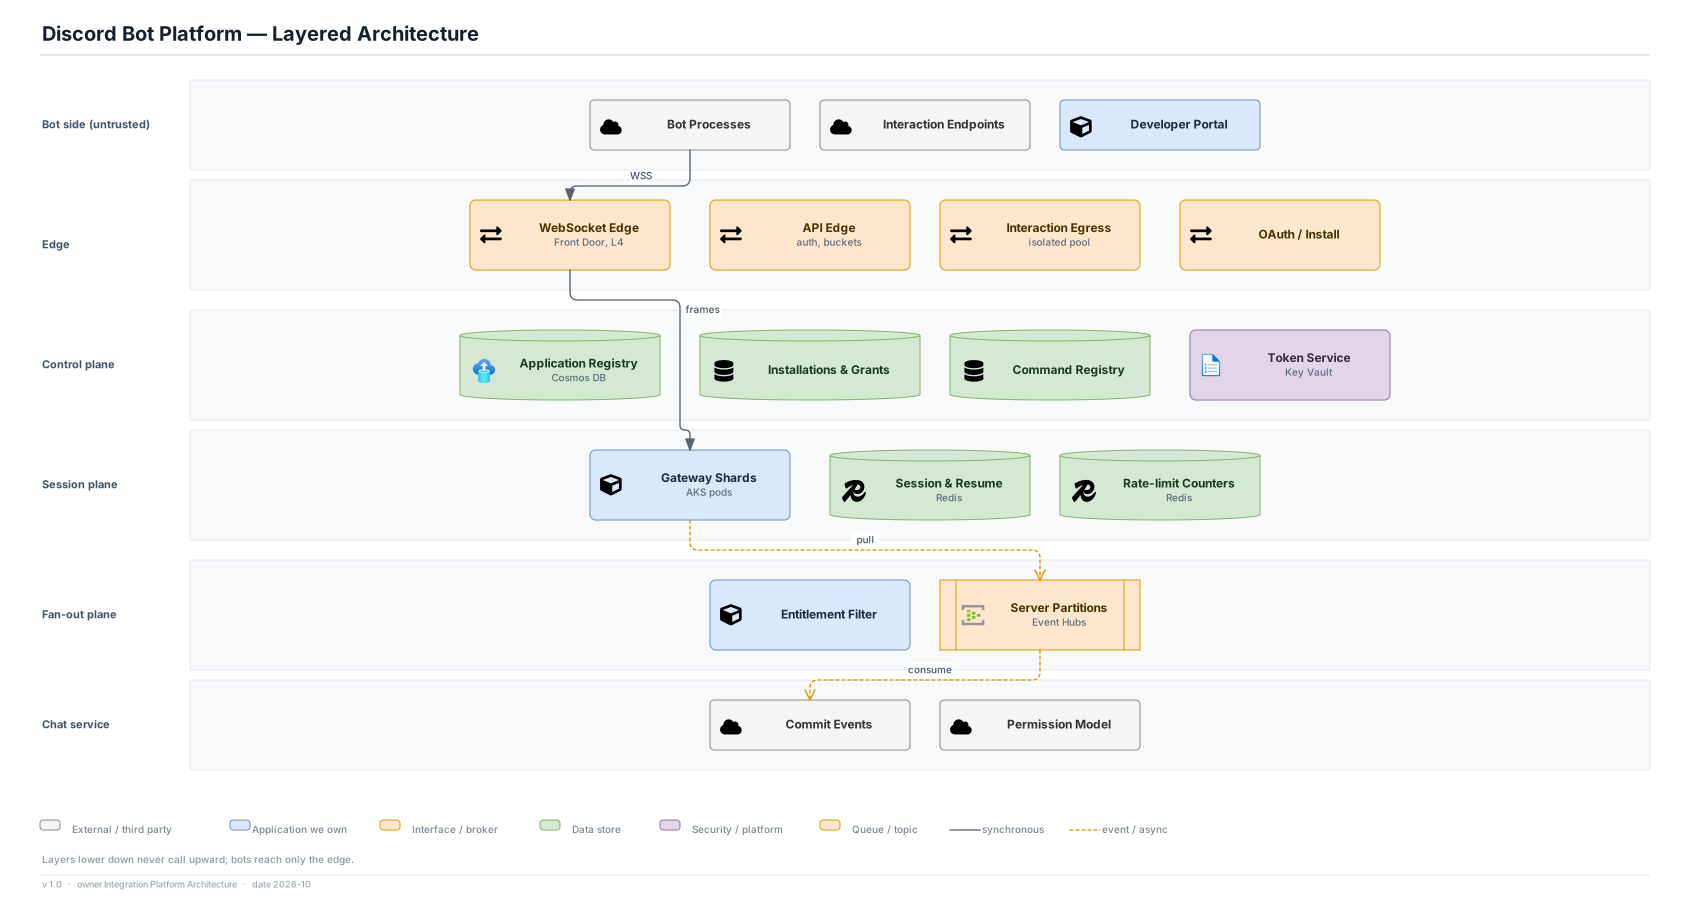
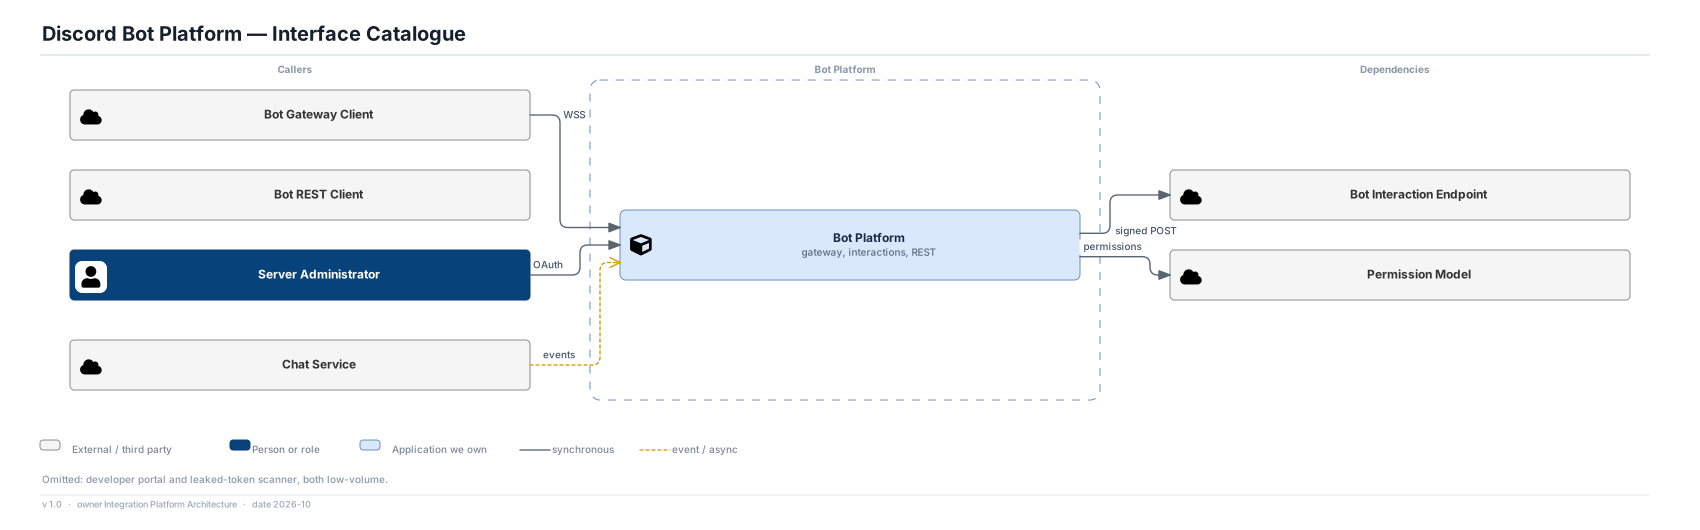
Decision. Bots are consumers on the far side of a one-way trust boundary. The chat service commits and emits an event; everything after that is the bot platform's own time. Bot actions return through a separate API edge and never through the event path. The chat service has no synchronous dependency on any bot-platform component.
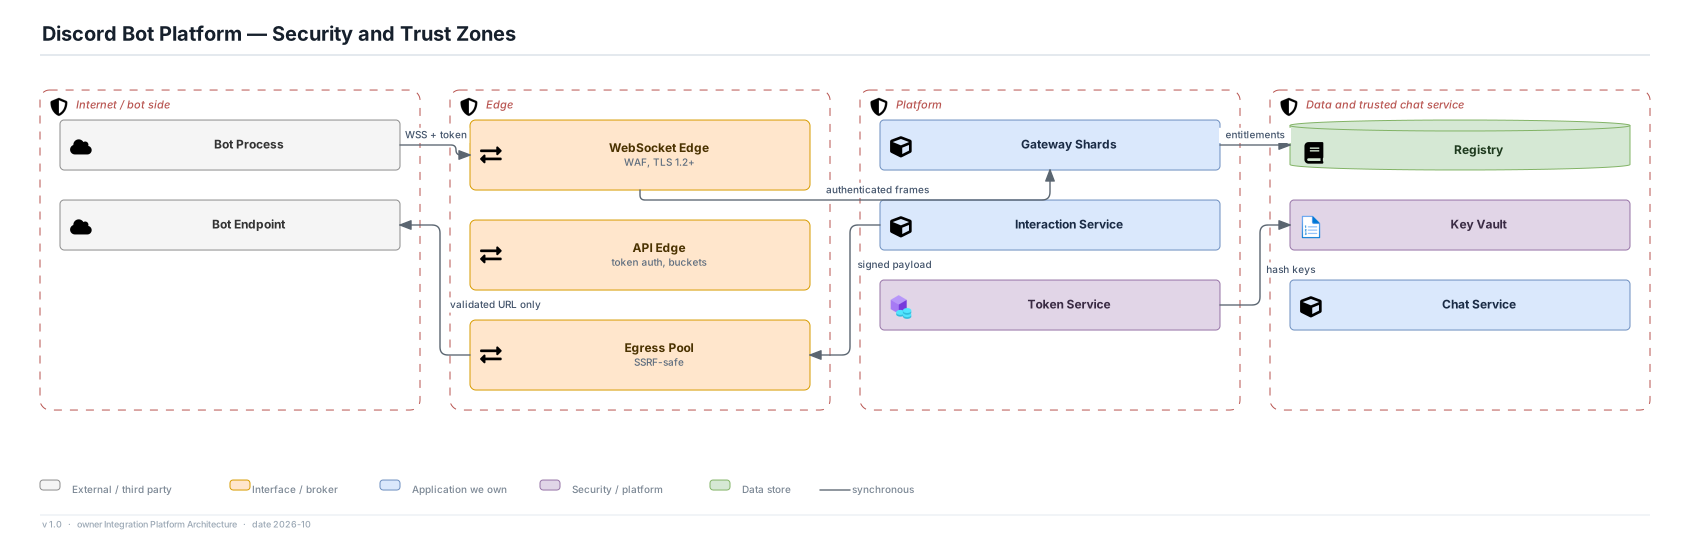
How it is realised on Microsoft Azure. Commit events are written to Event Hubs partitions keyed by server. The bot platform consumes them with its own consumer groups and checkpoints; no chat-service call blocks on delivery, and a stalled consumer group lags harmlessly. REST actions enter via a separate API edge that calls the chat service through its normal internal API, subject to its own rate limits.
| Option |
Verdict |
Reasoning |
| Event stream consumed asynchronously by the bot platform |
Chosen |
The chat service is indifferent to bot-platform health. Costs a hop, covered by the p99 800 ms delivery objective. |
| Inline notification to installed bots at commit |
Rejected |
Couples message latency to bot count and bot health. Fast in a demo, an incident at scale. |
| Bots poll a REST endpoint for new messages |
Right elsewhere |
Right for very small ecosystems or batch bots that tolerate delay; wasteful and slow at 2.5 M online bots. |
What it buys
- A total bot-platform outage degrades bots and nothing else.
- Chat-service releases and bot-platform releases are decoupled.
What it costs
- One extra hop before a bot sees an event.
- The bot platform must own its delivery guarantees, which is why the loss window is published (ADR-04).
Choose differently when. Inline notification would be defensible only for a single internal consumer on the same team, where the write is already slow enough to absorb one more call.
Why it holds up over time. This is the decision least tied to any technology on the page, and the most likely to be eroded by a feature request such as an official bot that blocks sending a message. Hold the boundary and make the exception a separate, explicitly synchronous product.
Lesson. Somebody else's uptime must never appear in your write path.
Fan-out
How an event finds the bots entitled to it, and how it is placed.
ADR-02 · Entitlement is enforced before serialisation; the shard is a computed address
Status: Accepted · Shown on views: 02, 07, 12
Where is an event filtered by what a bot may see, and how does an event find the right session?
Context. A bot receives only what its intents and the server's permissions allow. Filtering after the fact — send everything, let the client drop it — leaks data and burns bandwidth for 400,000 events per second. Routing is the other half: with millions of sessions, a lookup table from server to session is a hot, replicated structure that must itself be reliable.
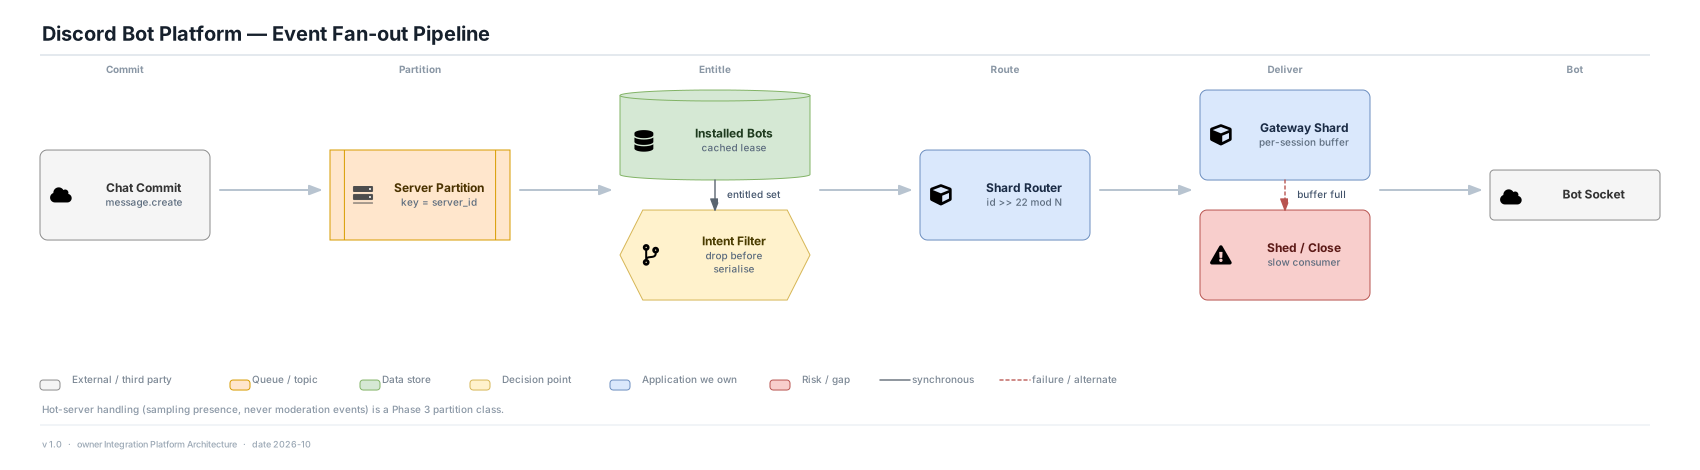
Decision. Filter by intents and permissions at the source, before the event is serialised for a bot; the unfiltered event is never produced. Shard assignment is a pure function: shard = (server_id >> 22) mod shard_count. Any gateway or fan-out node routes any server to any shard with no lookup.
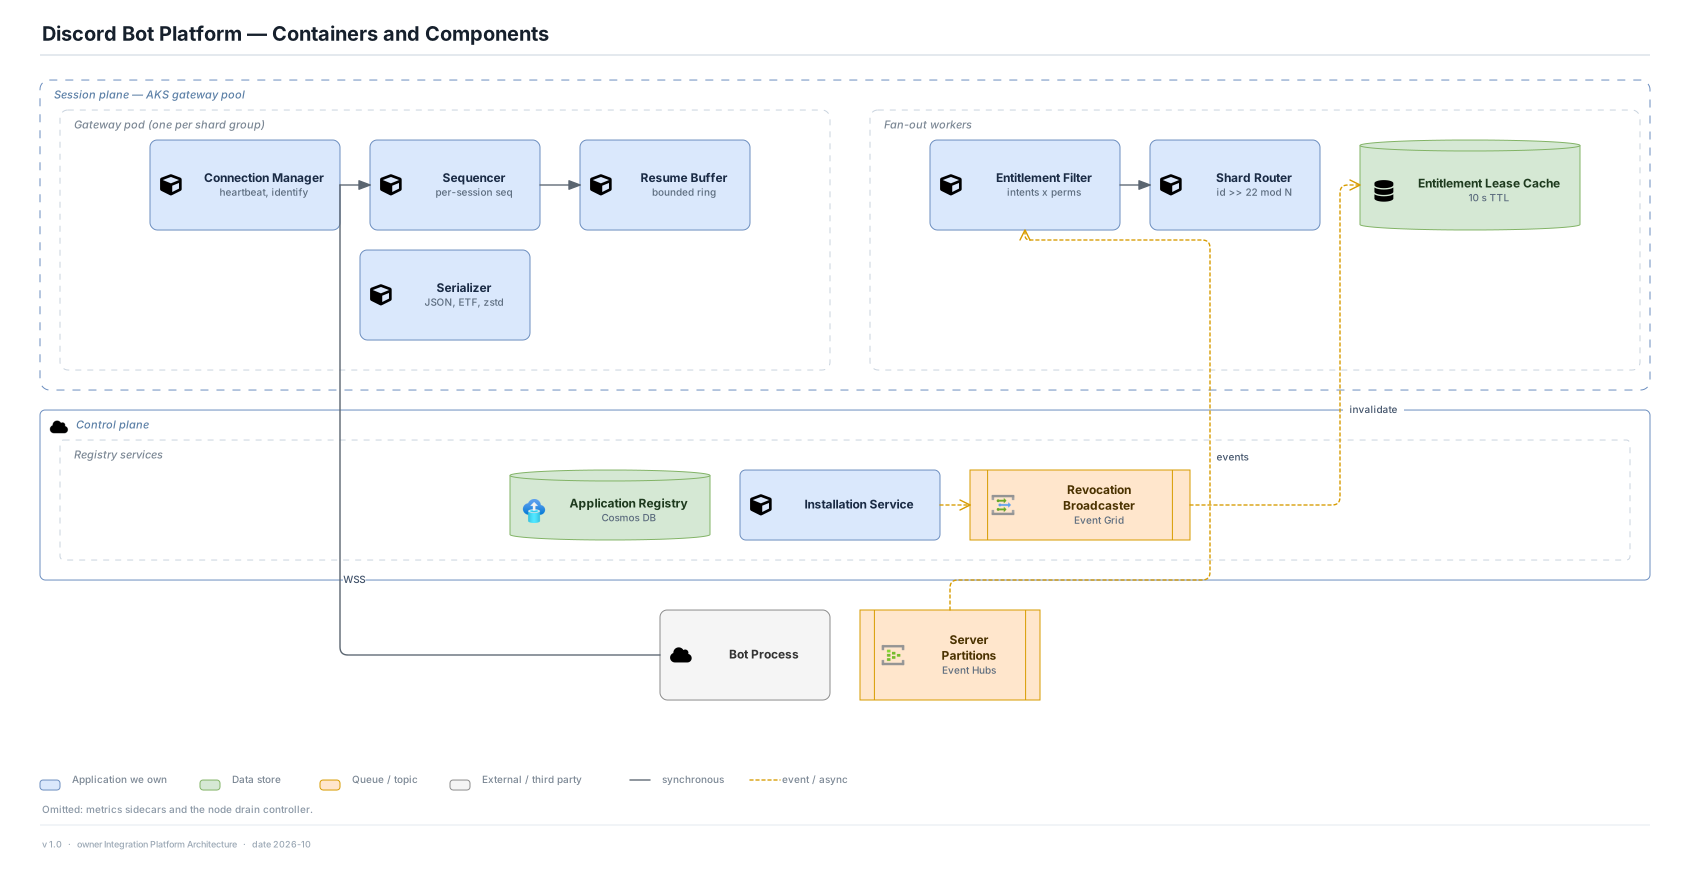
How it is realised on Microsoft Azure. The entitlement filter runs in fan-out workers on AKS, reading cached installation leases (10 s TTL) from Cosmos DB. The router computes the shard arithmetically and writes to that shard's Event Hubs partition group. Gateway shards own sockets for their shard number only.
| Option |
Verdict |
Reasoning |
| Filter at source; shard as arithmetic |
Chosen |
Nothing unentitled is produced; no routing table to keep consistent. Costs a filter evaluation per event per bot, mitigated by lease caching. |
| Send all, filter in the client |
Rejected |
Leaks data to untrusted code and multiplies egress. |
| Server-to-session routing table |
Right elsewhere |
Right when sessions must move between nodes often; here the shard count is fixed per bot, so arithmetic is cheaper and has no lookup outage. |
What it buys
- No unentitled byte ever reaches a bot.
- Routing needs no shared state and survives a registry outage.
What it costs
- Changing shard count re-maps servers, so re-sharding needs a bounded dual-delivery window.
- The filter is a hot path and must stay allocation-light.
Choose differently when. A routing table is justified if sessions must live-migrate for load balancing; with fixed shard counts per bot it is not.
Why it holds up over time. Arithmetic placement and filter-at-source are protocol-level and survive any infrastructure change. Changing the formula breaks every deployed bot, so treat it as public API.
Lesson. Compute the address; never look it up.
ADR-05 · Partition by server, not by bot
Status: Accepted · Shown on views: 06, 12
What is the unit of fan-out partitioning?
Context. A server with 2 million members and 40 bots generates events at a rate that varies by four orders of magnitude from the smallest server. If partitioning is by bot, a hot server's cost is multiplied by every bot in it and by every shard those bots run.
Decision. Events are partitioned by server identifier. Each event is produced once into its server's partition, filtered per installed bot, and routed to each bot's shard. Hot servers are isolated to their own partitions and can be given a dedicated class later.
How it is realised on Microsoft Azure. Event Hubs with server_id as partition key and consumer groups per fan-out worker pool. Partitions are provisioned in multiples with headroom; a hot-server partition class (Phase 3) uses dedicated throughput units.
| Option |
Verdict |
Reasoning |
| Partition by server |
Chosen |
One copy of each event; hot servers isolate naturally. Each bot subscribes via the filter, not via partition. |
| Partition by bot |
Rejected |
A hot server's cost is multiplied by every bot installed there. |
| Partition by channel |
Right elsewhere |
Finer, right if single channels become the hot unit; adds partitions and cross-channel ordering questions. |
What it buys
- Per-event cost does not grow with bots per server.
- A hot server cannot starve others.
What it costs
- Partition count must be provisioned ahead of growth.
- A single server's strict ordering is limited by one partition's throughput.
Choose differently when. By-channel partitioning if channels, not servers, prove to be the hot unit.
Why it holds up over time. Server-keyed partitioning mirrors how humans experience the service. It should hold until servers fundamentally change shape.
Lesson. Partition by the thing whose hotness you need to contain.
Interactions
The three-second window and what happens when it expires.
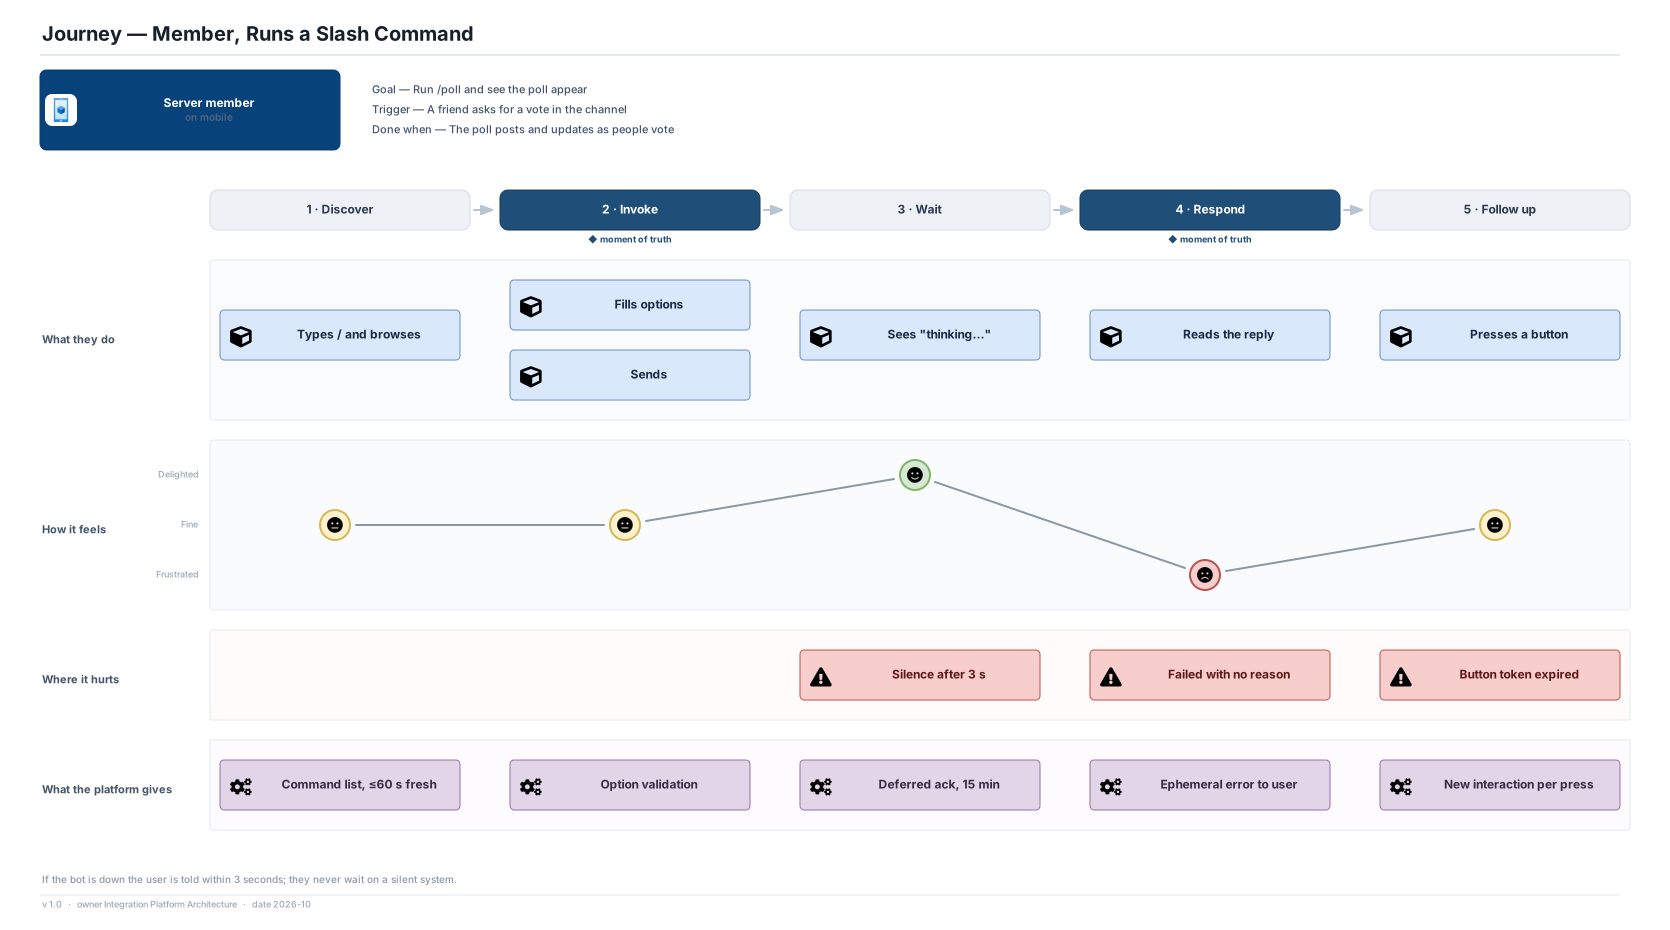
ADR-03 · A published three-second acknowledgement, with deferral
Status: Accepted · Shown on views: 04, 05, 11
How long does the platform wait on a stranger's endpoint, and what does the user see when it does not answer?
Context. Slash commands are a human clicking, then waiting on code the platform cannot see. Without a bound the user waits indefinitely; with an unbounded retry the platform queues work for dead endpoints. Serverless bots add cold starts that make p99 latency inherently unpredictable.
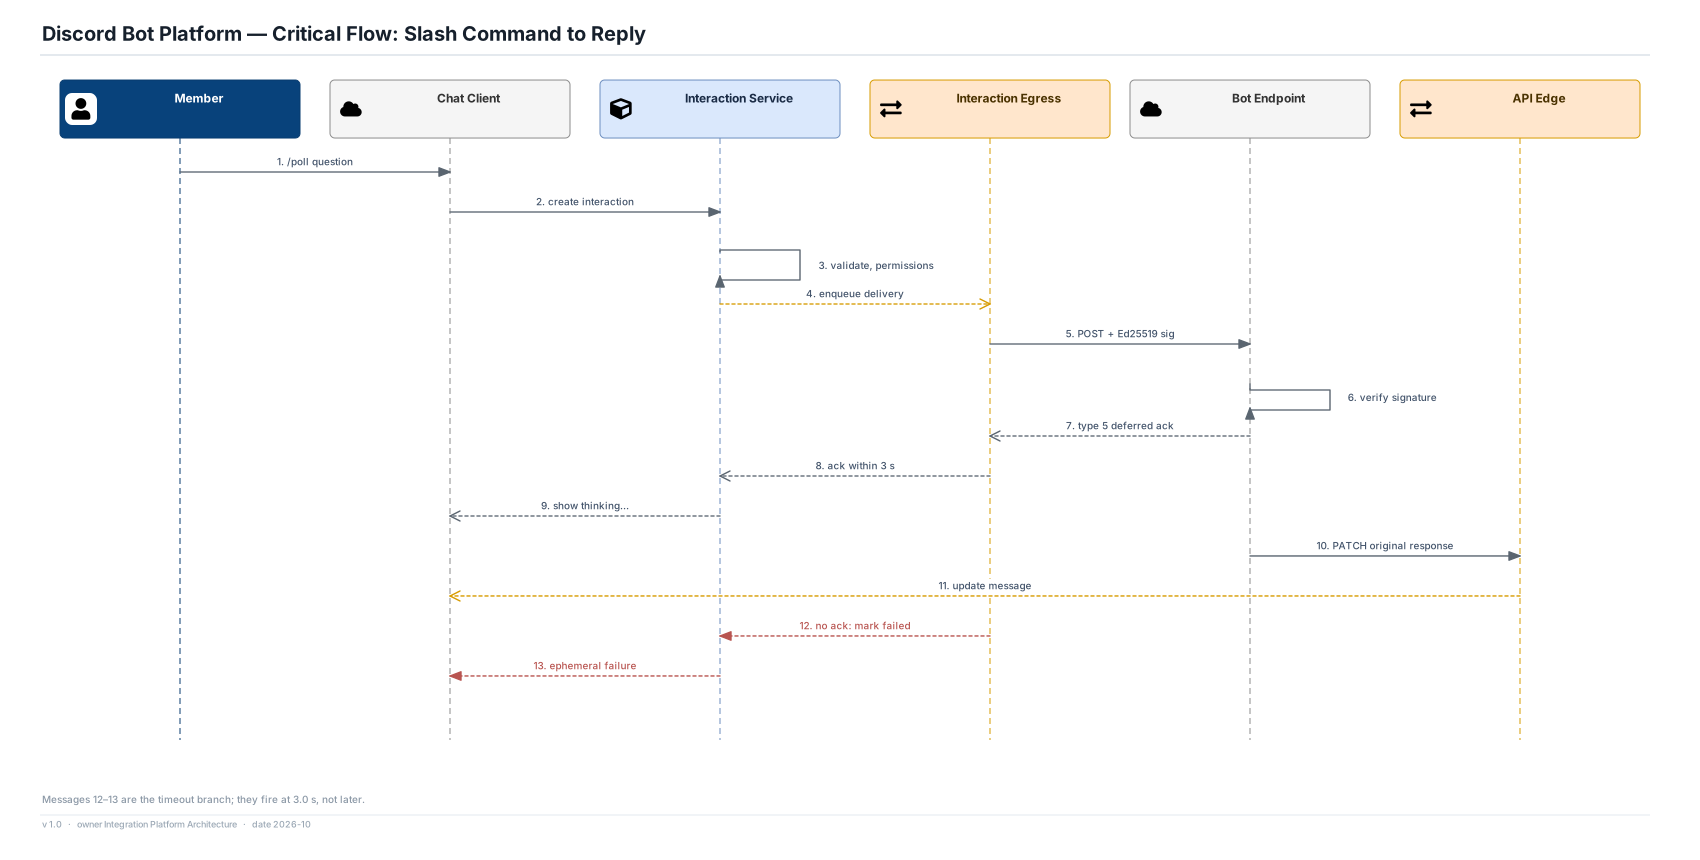
Decision. Each interaction must be acknowledged within 3 seconds or the platform shows the user a failure and counts the miss. A bot that needs longer sends a deferred acknowledgement immediately and responds within 15 minutes through a one-time token. Delivery is one POST with one retry inside the window.
How it is realised on Microsoft Azure. Interaction Service validates and enqueues; an isolated egress pool sends the signed POST. A timer per interaction fires at 3.0 s, writes an ephemeral failure, and increments the application's miss counter. Interaction tokens are single-interaction scoped and expire at 15 minutes.
| Option |
Verdict |
Reasoning |
| 3 s ack with deferral to 15 min |
Chosen |
Bounded wait for the user; long work still possible. Costs bots a protocol detail they must implement. |
| Wait until the bot responds |
Rejected |
A silent user experience and a queue that grows behind dead endpoints. |
| Always respond asynchronously |
Right elsewhere |
Fits chat-style bots already on sockets; worse UX for simple commands that could answer instantly. |
What it buys
- The user always sees an outcome within 3 seconds.
- Dead endpoints cost one bounded attempt, not a queue.
What it costs
- Bots must ack fast; cold-start-prone runtimes need keep-warm or deferral.
- A viral command converts bot p99 into user-facing failure rate.
Choose differently when. A longer window is right for a closed enterprise where every bot is vetted and hosted; a public ecosystem needs the hard bound.
Why it holds up over time. The number may change, the existence of a bound will not. What would break it is a product request for 'wait up to 30 s' that turns the user's click into an unbounded wait.
Lesson. Bound the wait you cannot control, and turn its expiry into a visible state.
Delivery contract
What a bot may rely on, stated with its loss boundary.
ADR-04 · At-most-once beyond 120 seconds, ordered at-least-once inside it, with bounded buffers
Status: Accepted · Shown on views: 12, 13, 17
What does the Gateway promise a bot that disconnects, and what happens to a bot that reads slowly?
Context. Reliable delivery to 2.5 M bots with arbitrary disconnections would need unbounded per-session buffering. A slow reader would grow memory without bound and hurt every session on its node. Promising exactly-once would be a claim the platform cannot keep.
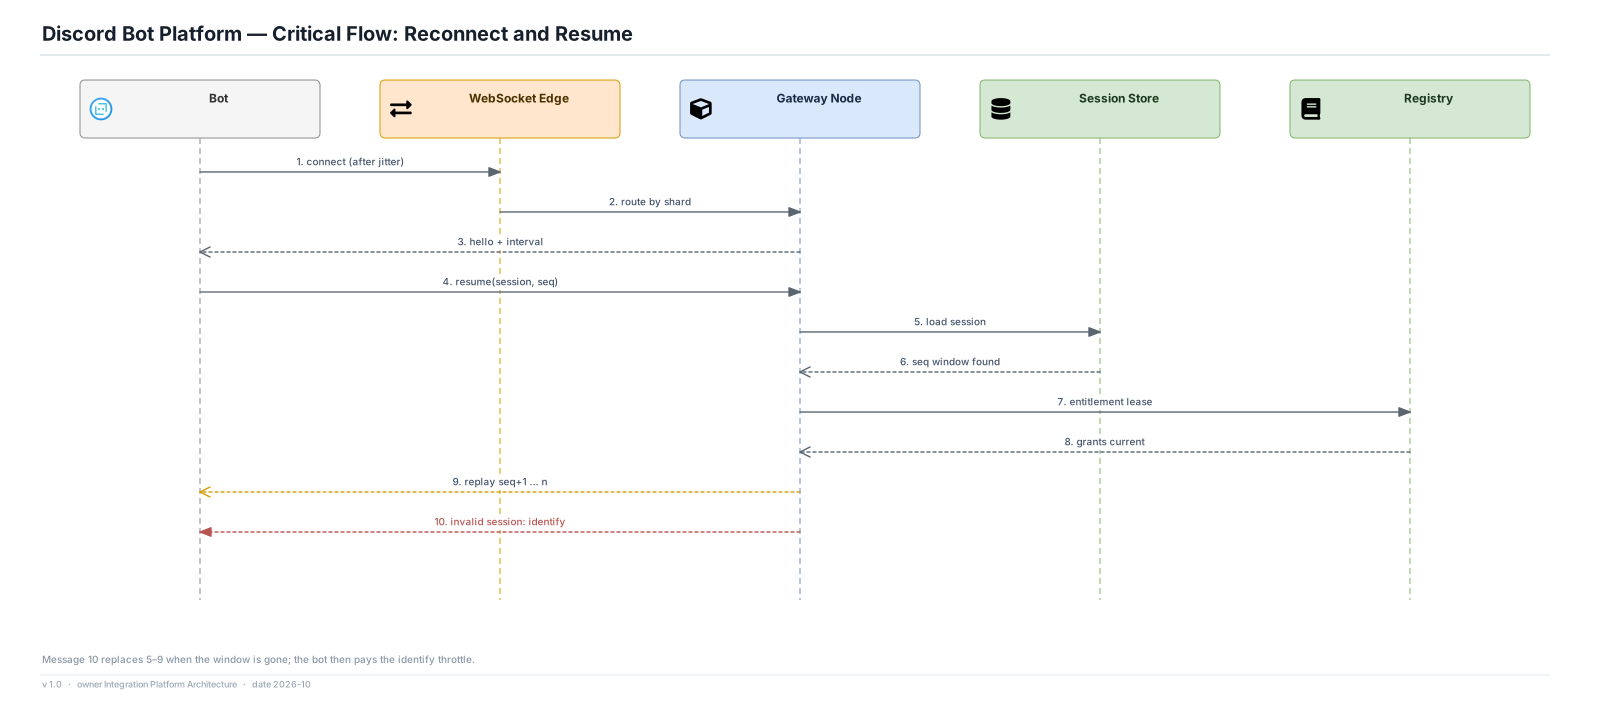
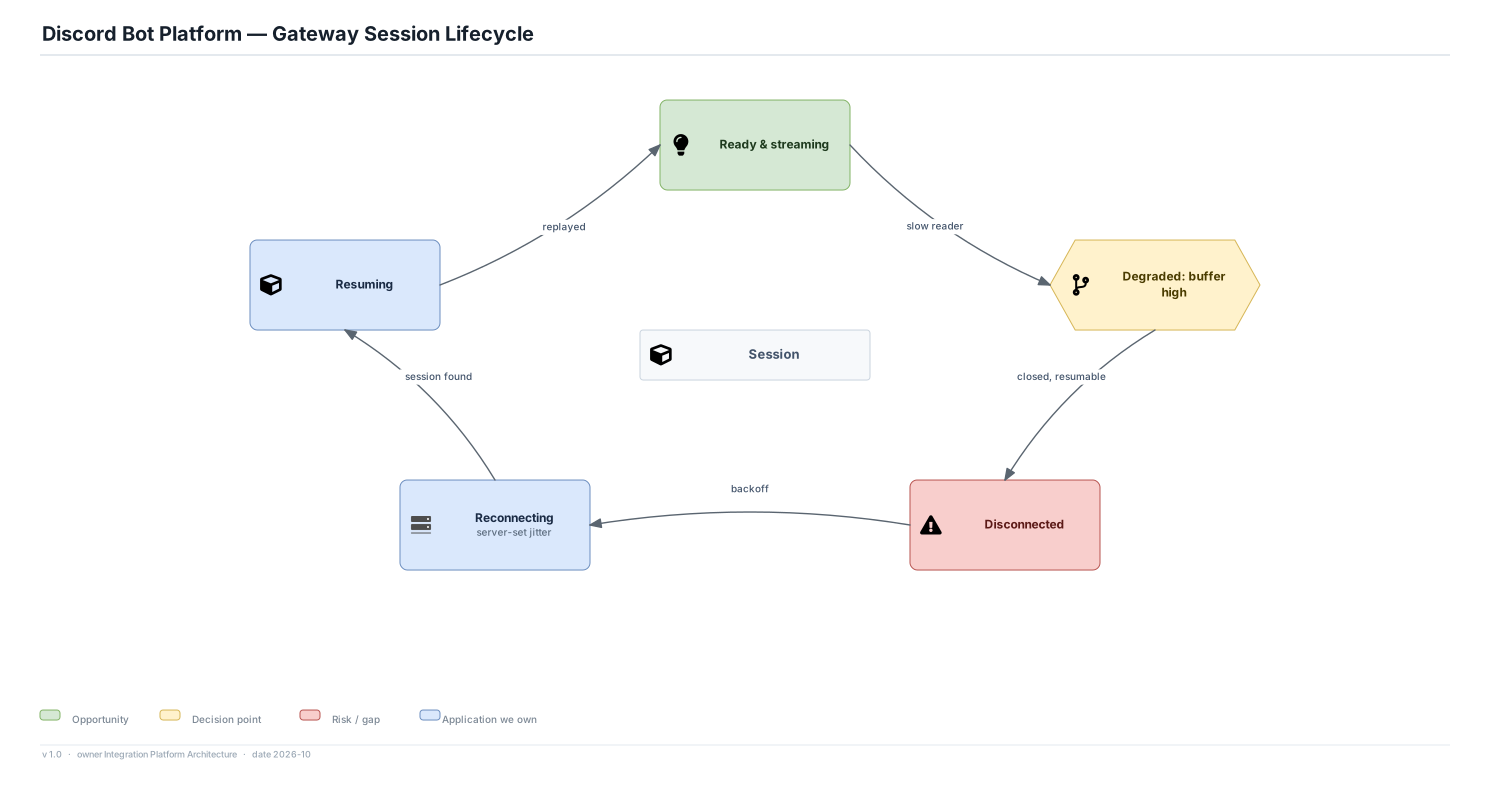
Decision. The contract is published: within a 120 s resume window, events are replayed in order from the bot's last sequence number; beyond it, the bot must start a fresh session and accept loss. Each session has a bounded send buffer; at the bound the session is closed with a resumable code rather than allowed to grow.
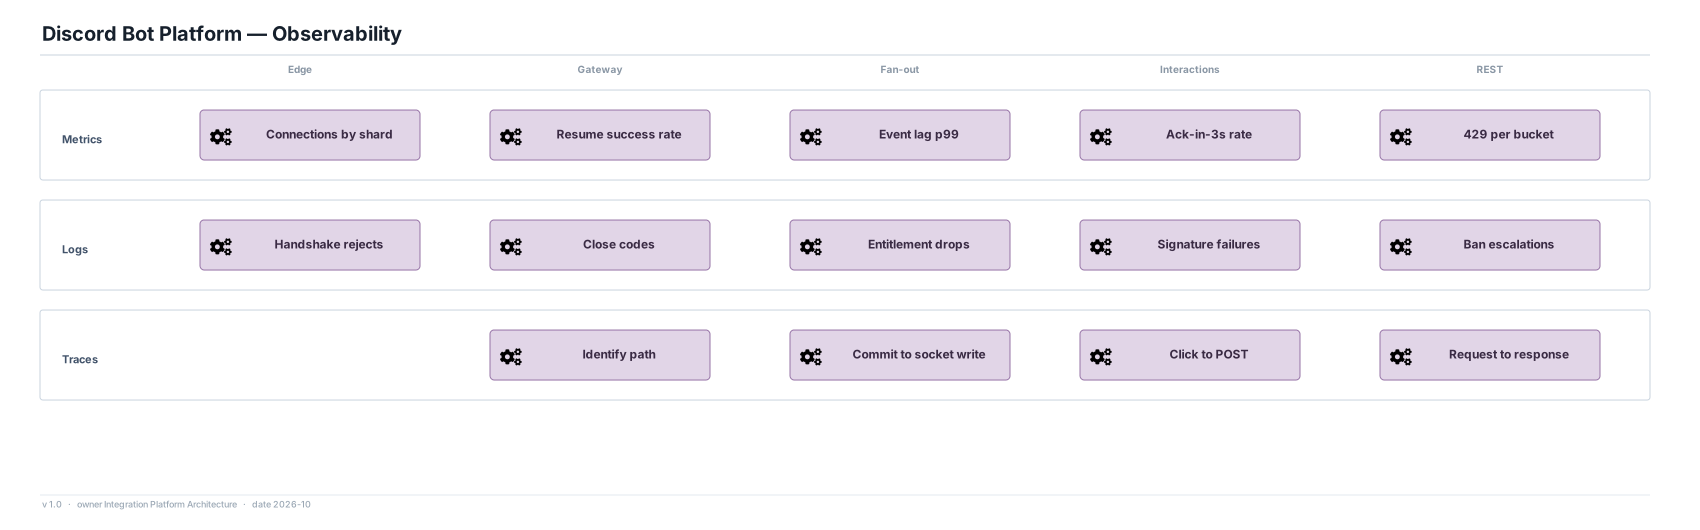
How it is realised on Microsoft Azure. Per-session ring buffers in gateway-pod memory (120 s or 5,000 events), with a replicated summary in Azure Cache for Redis for node-loss recovery. Close codes distinguish resumable from fatal. A buffer at 80 % emits a degraded metric visible in the developer dashboard.
| Option |
Verdict |
Reasoning |
| Bounded resume window with explicit loss |
Chosen |
Memory is proportional to sessions, not events. Costs bot authors a documented gap. |
| Unbounded durable per-bot queue |
Rejected |
Becomes a database per bot and a cost line nobody budgeted for. |
| Exactly-once delivery |
Rejected |
Not achievable across a network the platform does not control; the claim would only teach bots not to defend themselves. |
What it buys
- Memory is bounded and predictable.
- The gap is explicit, so bots can reconcile against REST after a long disconnect.
What it costs
- Long-offline bots miss events.
- Sizing resume buffers across millions of sessions is a real memory budget.
Choose differently when. Durable queues are right for paid, contractually-bound integrations; a free public ecosystem cannot afford them.
Why it holds up over time. The principle — bound everything a consumer can make grow — outlasts any specific numbers. The 120 s figure should be revisited with real reconnect-time data.
Lesson. A promise with an explicit boundary is worth more than a bigger promise with a hidden one.
Authority
Who owns a grant, and when it is evaluated.
ADR-06 · The server owns the installation, evaluated at request time
Status: Accepted · Shown on views: 03, 10, 19
Who owns a bot's grant, and when are permissions evaluated?
Context. If grants belong to the developer, deleting a developer account silently breaks hundreds of servers. If permissions are baked into the token at install, narrowing one needs a token reissue and some old tokens keep working.
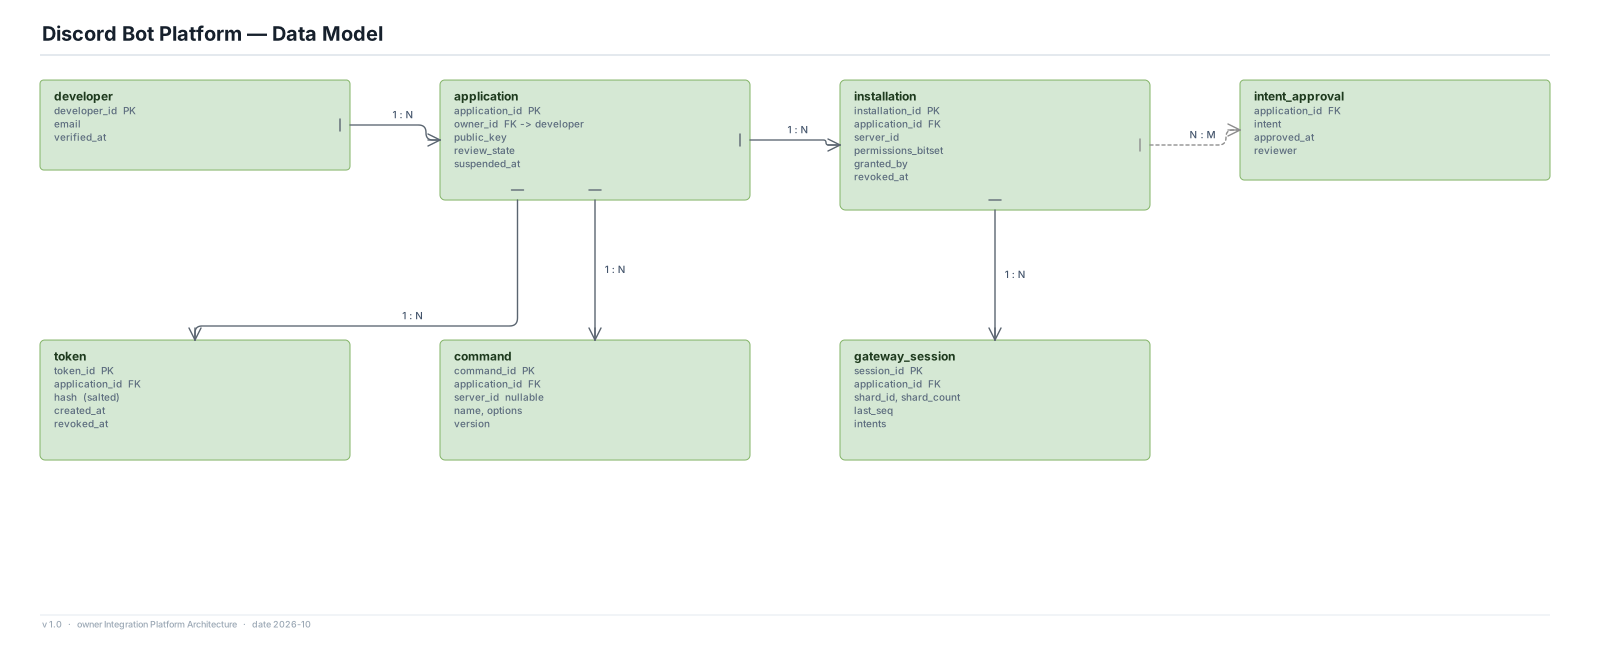
Decision. Installations belong to the server. A bot token identifies an application; what it may do is the installation's permission bitset intersected with the server's current roles and channel overrides, evaluated on every call.
How it is realised on Microsoft Azure. Installation records in Cosmos DB keyed by (server, application). The permission function is a shared library used by the API edge and the Gateway entitlement filter, so REST and events agree. Bot actions on higher-ranked members are refused regardless of the bitset.
| Option |
Verdict |
Reasoning |
| Server-owned installation; evaluate per request |
Chosen |
Revocation and narrowing are immediate and local to the server. Costs a lookup per call, mitigated by leases. |
| Permissions encoded in the token |
Rejected |
Narrowing needs reissue; stale tokens keep authority. |
| Developer-owned grants |
Rejected |
Developer churn becomes server outages. |
What it buys
- Server owners can narrow or revoke without touching the developer.
- REST and Gateway cannot disagree about authority.
What it costs
- A per-request permission evaluation is a hot-path cost.
- Cache staleness is bounded only by the lease TTL (ADR-08).
Choose differently when. Token-embedded permissions are fine for machine-to-machine integrations with a few long-lived installs.
Why it holds up over time. Ownership by the party whose data is at risk is a durable rule.
Lesson. Authority belongs to whoever bears the consequence.
Resilience
How a fleet recovers without becoming the outage.
ADR-07 · Reconnects are directed, jittered and throttled
Status: Accepted · Shown on views: 13, 15, 17
How is a fleet of 40,000 reconnecting bots prevented from taking down the registry?
Context. A gateway node dies, or a release drains it, and every bot on it reconnects at once. Identify is expensive: it hits the registry, validates the token, builds the session. Left alone, the fleet's own recovery behaviour is the outage.
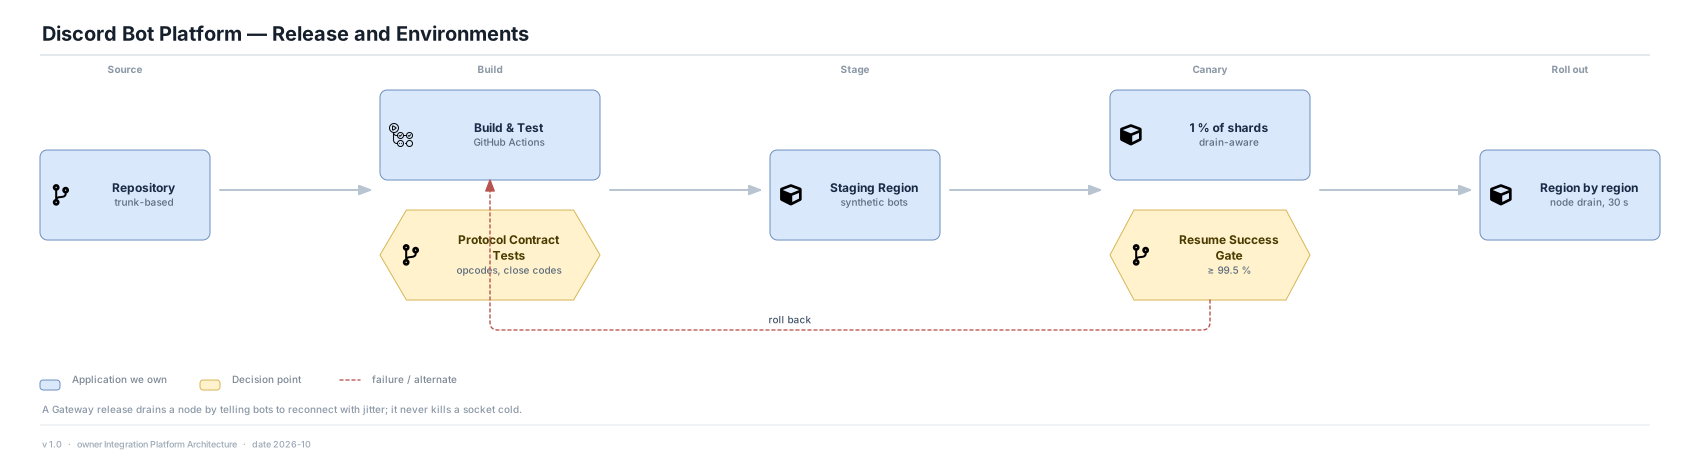
Decision. The server instructs reconnecting clients with a jittered delay, throttles identifies per bot and per shard bucket, and prefers resume, which is cheap, over identify. Releases drain nodes through the same mechanism.
How it is realised on Microsoft Azure. The Gateway sends a reconnect opcode with jitter; WebSocket Edge enforces max_concurrency per shard bucket and 1,000 identifies per 24 h per bot using Redis counters. Resume reads the session store and an entitlement lease, not the registry.
| Option |
Verdict |
Reasoning |
| Server-directed jitter plus identify throttle |
Chosen |
Smears the storm and protects the registry. Costs slower recovery for the largest fleets. |
| Clients choose their own backoff |
Rejected |
Clients are untrusted and many ignore advice. |
| Over-provision the registry for storms |
Right elsewhere |
Valid when storms are rare and registry cost is trivial; here the storm is the sizing driver. |
What it buys
- Node loss and releases do not become registry incidents.
- The same mechanism serves both failure and deployment.
What it costs
- Recovery time for large fleets is deliberately bounded below.
- Throttles need tuning against real storms.
Choose differently when. Over-provisioning is simpler if the registry were a cheap, linearly scalable store.
Why it holds up over time. Controlling reconnect behaviour from the server side is a lasting pattern for any persistent-connection fleet.
Lesson. Make the recovery path cheaper than the failure path.
Revocation
How a changed grant bites on an open session.
ADR-08 · Revocation propagates by push, bounded by a short lease
Status: Accepted · Shown on views: 07, 13, 19
How quickly does a revoked or narrowed grant bite on a session that is already open?
Context. Long-lived sockets cache who they are entitled to. If a grant is revoked at second 0 but the session keeps streaming events for an hour, the admin's action is a lie.
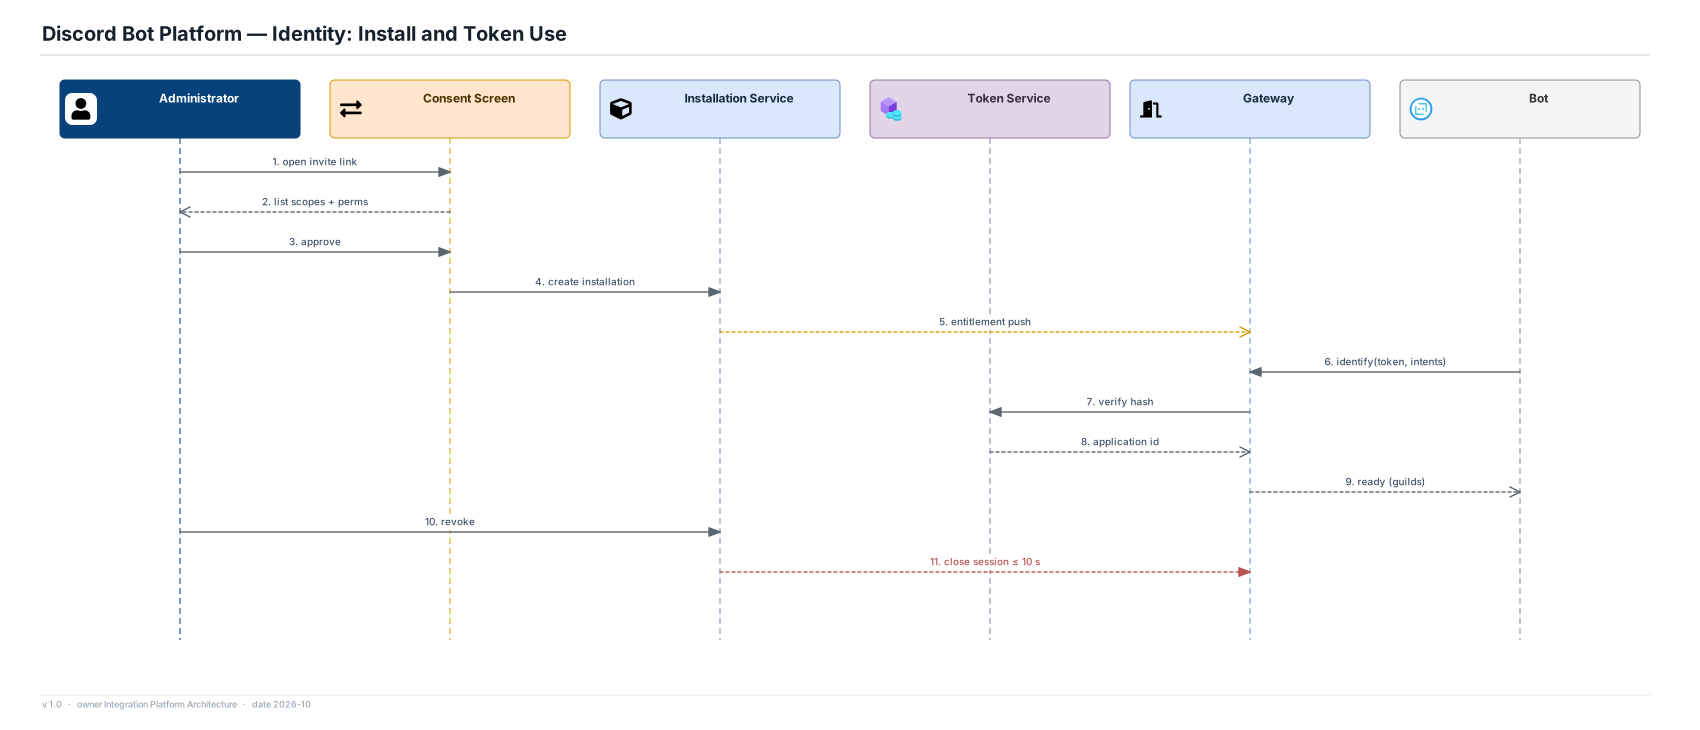
Decision. Revocation pushes an invalidation to every gateway node, and every session's entitlements are held as a lease with a 10 s TTL, so the worst case is the lease length even if the push is lost.
How it is realised on Microsoft Azure. Installation Service writes the change and publishes to Event Grid; gateway nodes invalidate the lease cache and close affected sessions. The lease renewal re-reads Cosmos DB; if the registry is unavailable, existing sessions continue for 5 minutes and new identifies are refused.
| Option |
Verdict |
Reasoning |
| Push invalidation plus short lease |
Chosen |
Prompt in the normal case, bounded in the failure case. |
| Check the registry per event |
Rejected |
Exact and unaffordable at 400k events/s. |
| Long-lived entitlements, revoke by reconnect |
Rejected |
Staleness is unbounded. |
What it buys
- Revocation has a number, 10 seconds.
- A lost push degrades to lease expiry.
What it costs
- Steady background load of lease renewals.
- Registry outage policy (fail closed for new, run for existing) is a judgement call.
Choose differently when. Per-event checks if the event rate were far lower.
Why it holds up over time. A bounded-staleness lease is a durable pattern. The TTL can be tuned.
Lesson. Revocation is not real until it has a deadline.
API
How limits are expressed to bots.
ADR-09 · Rate limits are per route bucket, and tell the client what to do
Status: Accepted · Shown on views: 08, 16
How are API limits expressed so well-behaved bots never need to guess?
Context. A single global limit punishes a bot for one hot route; per-endpoint secret limits make bots brittle. Bots that ignore limits are common and hostile traffic hides among them.
Decision. Limits are per route bucket and per major resource, with a global ceiling. Every response returns bucket id, remaining and reset time; 429 carries retry-after. Persistent violators are escalated to a timed token ban.
How it is realised on Microsoft Azure. API Edge keeps bucket counters in regional Redis, with local admission and periodic reconciliation. Counter loss gives a brief over-allowance, accepted. Invalid-request counts are tracked per token and per source address.
| Option |
Verdict |
Reasoning |
| Per-bucket limits with headers |
Chosen |
Predictable and self-documenting. Costs counter state per bucket per resource. |
| Single global limit |
Rejected |
Penalises hot routes and hides the cause. |
| Hidden limits with random 429s |
Rejected |
Teaches clients to hammer. |
What it buys
- Well-behaved clients never hit a limit unannounced.
- Escalation targets only the offender.
What it costs
- Counters are approximate, so brief overshoot is possible.
- Bucket naming becomes public API.
Choose differently when. Central exact counters if overshoot has a direct cost, for example metered billing.
Why it holds up over time. Machine-readable limits are a durable convention.
Lesson. A limit that cannot be read is a trap.
State
Which state is precious and which is rebuilt.
ADR-10 · State is classed by how it can be lost
Status: Accepted · Shown on views: 09, 10, 14
Which state is precious, and which is rebuilt?
Context. Treating all state as precious makes every store a database with replication, backup and failover. Treating all as disposable loses installations.
Decision. Three classes: registry (strong, small, RPO 0), session (rebuildable by reconnecting), counters (approximate and regional). Each class has its own store, durability and recovery story.
How it is realised on Microsoft Azure. Cosmos DB with zone redundancy and a replicated secondary for the registry; Azure Cache for Redis with replicas for session and counters, without cross-region replication; append-only evidence to Blob and Log Analytics.
| Option |
Verdict |
Reasoning |
| Three classes with distinct stores |
Chosen |
Recovery effort is proportional to loss cost. |
| One strongly consistent store for all |
Rejected |
Cost and latency on a path that does not need it. |
| Everything in memory |
Rejected |
Loses installations. |
What it buys
- A Redis failover is a reconnect, not a data loss.
- Registry sizing is small and predictable.
What it costs
- Three operational patterns to run.
- Class boundaries need discipline as features arrive.
Choose differently when. One store is fine for a small ecosystem.
Why it holds up over time. Classing by loss cost survives any technology swap.
Lesson. Decide how each kind of state may be lost before choosing where it lives.
Egress
Calling stranger-chosen URLs safely.
ADR-11 · Everything bot-supplied is hostile, and egress is its own zone
Status: Accepted · Shown on views: 14, 18
How does the platform call URLs strangers chose without becoming a request-forgery engine?
Context. Interaction endpoints, webhooks and embed images are all URLs a stranger picked. A worker that fetches them with internal network access is an SSRF vector aimed at the metadata service.
Decision. Egress runs in an isolated pool with no route into the platform. Addresses are resolved and validated immediately before connect; private ranges and metadata addresses are denied. The egress range is published so bots can allowlist it.
How it is realised on Microsoft Azure. A dedicated AKS node pool in egress-only subnets with NSG rules denying internal ranges, a NAT with a fixed public IP set, and a validating connect library. Redirects are re-validated.
| Option |
Verdict |
Reasoning |
| Isolated egress zone plus validation |
Chosen |
Containment holds even if validation has a bug. |
| Validation code only |
Rejected |
One bug away from the metadata service. |
| Customer-hosted relay |
Right elsewhere |
Right for regulated tenants who must control egress. |
What it buys
- A bug in validation cannot reach internal systems.
- Bots can allowlist a stable range.
What it costs
- A separate fleet and network to run.
- Changing the range is a breaking change for bots.
Choose differently when. A hosted relay if the platform must never originate traffic.
Why it holds up over time. Network containment ages better than any validation function.
Lesson. Contain by topology, not by cleverness.
Identity
Credentials, scope and leaks.
ADR-12 · Tokens are scoped, hashed and scanned for
Status: Accepted · Shown on views: 18, 19
How are credentials issued, stored and recovered when they leak?
Context. A bot token is long-lived and pasted into public repositories daily. A token with broad scope is a master key.
Decision. Tokens are salted hashes at rest, shown once, scoped to one application, with interaction tokens scoped to one interaction. Public code hosts are scanned for leaked tokens, which are reset within 5 minutes.
How it is realised on Microsoft Azure. Token Service stores hashes and keys in Key Vault; the scanner is fed by code-host partner programmes; reset invalidates the hash and closes sessions through the same path as revocation (ADR-08).
| Option |
Verdict |
Reasoning |
| Hashed, scoped tokens with leak scanning |
Chosen |
Limits the blast radius and shortens exposure. |
| Reversible stored tokens |
Rejected |
A database leak becomes a fleet compromise. |
| Short-lived tokens only |
Right elsewhere |
Right for machine-to-machine; hostile to hobbyist developers. |
What it buys
- A leak costs minutes, not days.
- The database holds nothing replayable.
What it costs
- A developer must save a token at creation.
- Scanning depends on partner programmes.
Choose differently when. Short-lived tokens if bots were all hosted by a managed runtime.
Why it holds up over time. Hashing and scoping do not age.
Lesson. Assume the credential will leak, and shorten the consequence.
Every package used, in one table
The terms this package uses in a specific way, and what each one is doing in the architecture.
| Package |
What it is |
What it does here |
Considered instead |
| Shard |
A numbered slice of a bot's servers, computed from server id and shard count. |
The unit of connection and of routing; no lookup needed. |
A routing table that must itself be reliable. |
| Intent |
A declared category of events a bot wants, some privileged and reviewed. |
Entitlement is enforced before serialisation. |
Filtering in the client. |
| Interaction |
A user-initiated command, button or modal delivered to a bot with a 3-second acknowledgement. |
Makes the stranger's latency visible and bounded. |
Unbounded waiting. |
| Resume window |
The 120 seconds in which a reconnecting session replays missed events. |
Defines the explicit loss boundary. |
Unbounded per-bot queues. |
| Installation |
A server's grant of permissions to an application. |
The unit of authority and revocation. |
A developer-owned grant. |