Distributed Job Scheduler · Solution Architecture v1.0 · Google Cloud · Platform Architecture · 2026-10 · 20 views · 16 architecture decision records
The argument these decisions serve is summarised in the Architecture One-Pager.
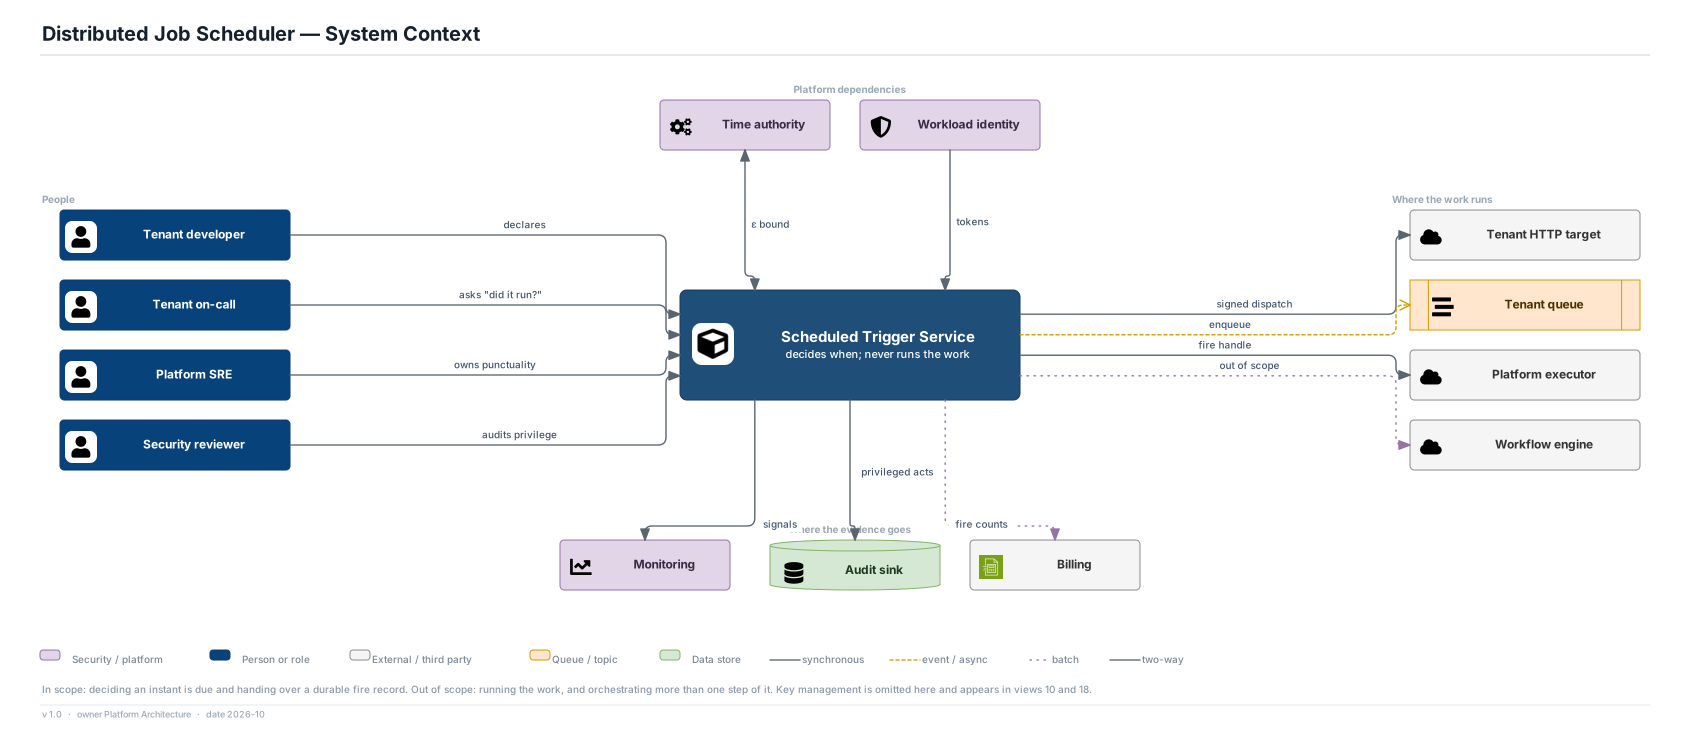
The architecture behind one small box in a developer platform's settings screen: "every weekday at 09:00". The one-pager is the argument in fifteen minutes; the decision record is the same argument with its working shown, sixteen decisions deep.
Status of this document. This is a design, not a report on a running system. Every rate, latency, ratio, threshold and retention figure is a stated assumption, chosen to be defensible and arguable rather than measured. The operating context assumed throughout is a developer platform with 50,000 tenants and 20 million active triggers, firing 500 million times a day at a mean of 5,800 fires a second, with 60% of all fires landing in the first second of a minute and the top of the hour carrying eight times the mean minute — a design peak of 45,000 fires a second for five seconds. Punctuality is assumed at p50 ≤ 1 s, p99 ≤ 5 s and p99.9 ≤ 30 s of lateness, with zero tolerance for earliness at any percentile; the clock uncertainty bound is assumed at ε ≤ 10 ms with leases shed above 100 ms; the residual duplicate dispatch rate is assumed at 1 in 10^6. Where a number came from nowhere, it is marked as an assumption in the view cards and in the records, and a reviewer should treat each of them as an invitation to disagree.
How to read a record
- Question: The forcing question: why a decision was needed at all.
- Context: The requirement, the scale and the constraint that make it hard.
- Decision: What this architecture does, stated so it can be checked.
- How it is realised on AWS: The concrete mechanism: which service or package, configured how, in which subscription.
- Options weighed: Chosen, rejected, deferred, or right elsewhere, with the reason for each.
- Consequences: What the choice buys and what it costs, both kept visible.
- Choose differently when: The conditions that would flip the decision for your system.
- Why it holds up over time: What keeps the decision right as scale, staff and technology change.
- Lesson: The principle that transfers beyond this platform.
Decision map
Decision and delivery: The boundary that defines the architecture, and the two decisions that follow from it directly.
- ADR-01 · The scheduler's durable output is a committed fire record, written before any dispatch attempt
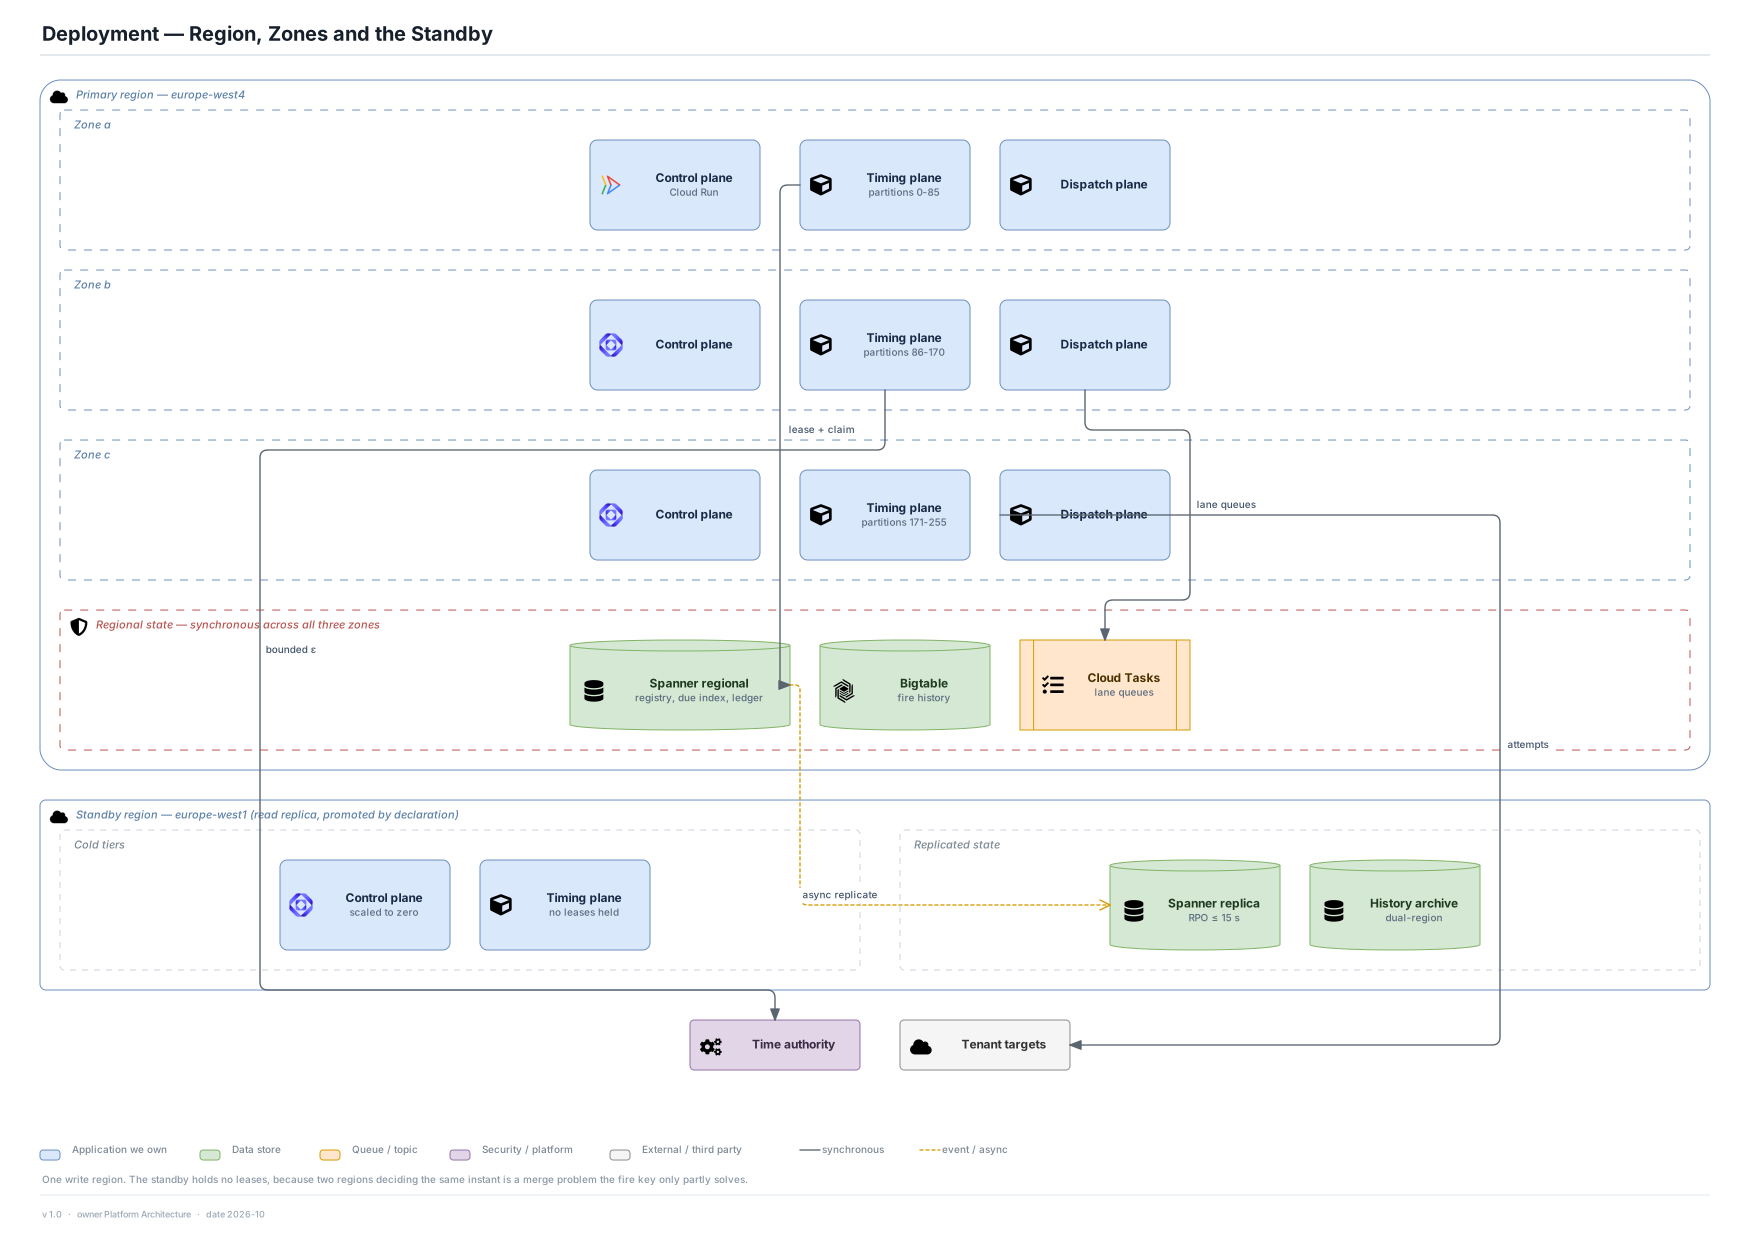
- ADR-02 · The control plane and the timing plane share only the state of record, and there is one write region
- ADR-03 · Idempotency lives in the data model: the fire's primary key is the idempotency key, and delivery is at-least-once
Time: What time it is, how wrong that might be, and what a wall-clock expression actually means.
- ADR-04 · The node clock is untrusted; dispatch waits out a bounded uncertainty interval, so lateness is a budget and earliness is a bug
- ADR-05 · Recurrences are recomputed each cycle from a versioned definition, not materialised ahead into the due index
- ADR-07 · Wall-clock recurrences resolve against a named zone with declared DST rules, and the time-zone database version is recorded on every fire
Policy after the outage: What a trigger does about the fires it missed — declared before it misses them, not decided during the incident.
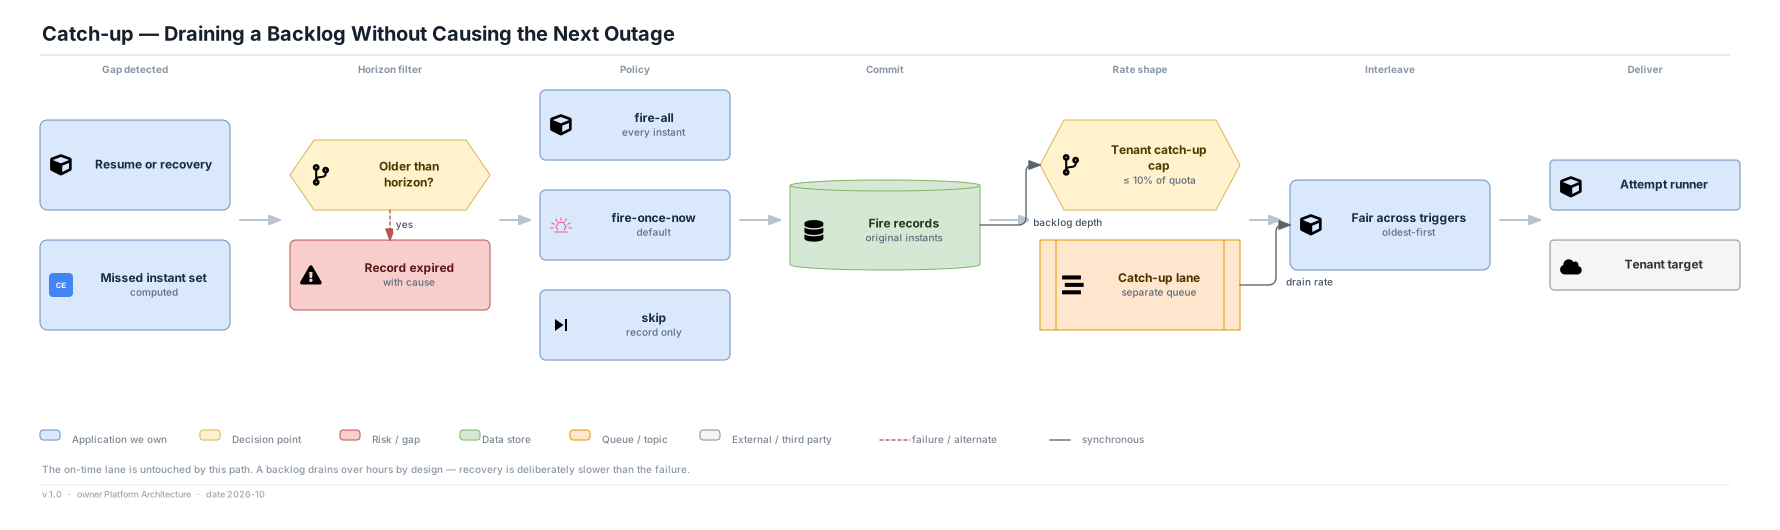
- ADR-06 · The missed-fire policy is declared per trigger before the outage, and defaults to firing once for the most recent missed instant
- ADR-08 · A catch-up horizon bounds every missed-fire policy, and the original scheduled instant travels with the fire
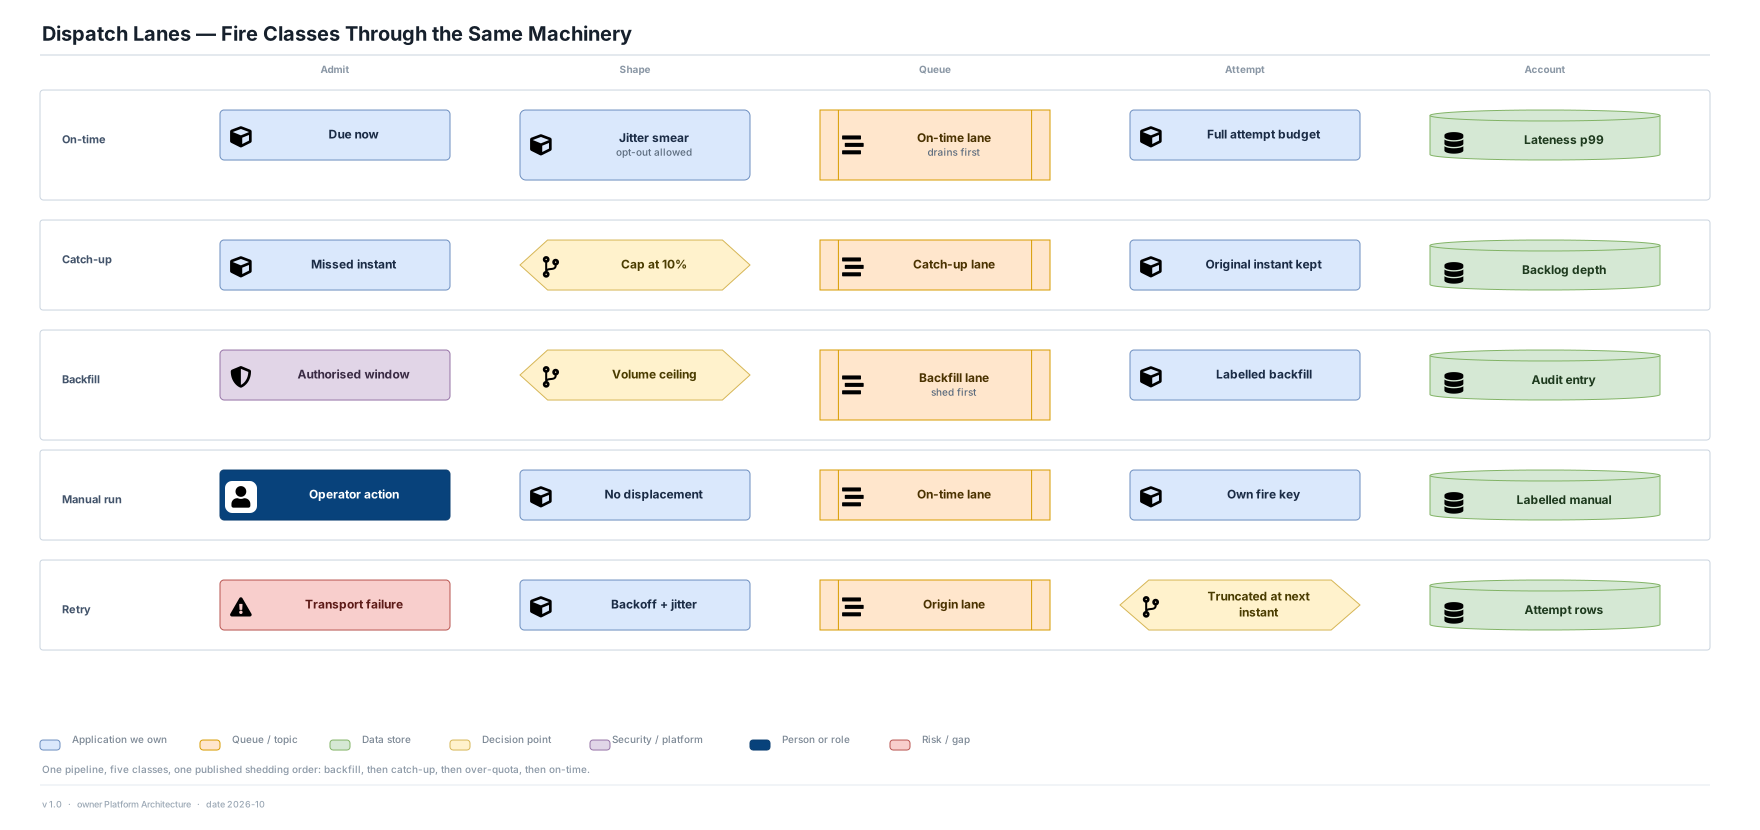
- ADR-09 · Catch-up, backfill and on-time fires use separate queues with a per-tenant catch-up cap and a published shedding order
- ADR-12 · Overlap is enforced against recorded outcome state, with
unknown as a first-class terminal state bounded by a window
Scale, cost and recovery: Absorbing the top-of-hour peak, and treating the due index as something rebuilt rather than restored.
- ADR-10 · The top-of-hour peak is absorbed by opt-out jitter smearing and the lateness budget, not by provisioned capacity
- ADR-11 · The due index is a rebuildable projection, verified continuously by a shadow rebuild rather than backed up
Evidence and trust: What the tenant can see, what a schedule is allowed to point at, and who is allowed to multiply work.
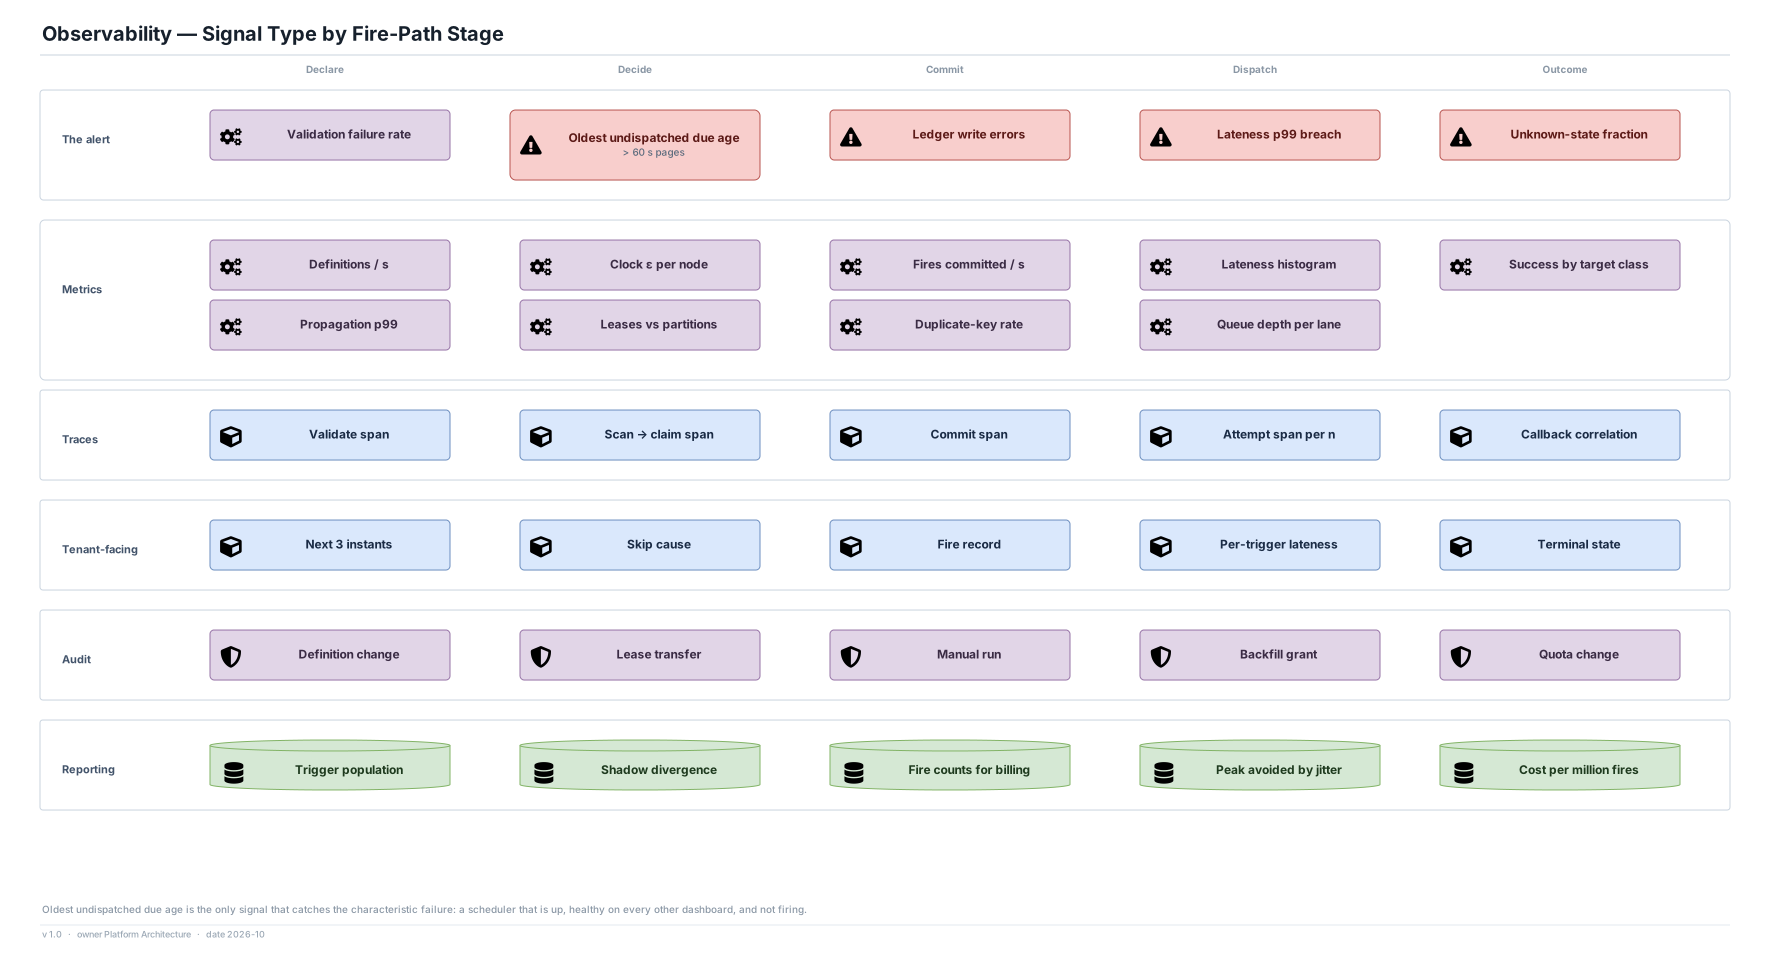
- ADR-13 · Fire history is a tenant-facing product surface, and the platform alert is oldest undispatched due age
- ADR-14 · A target must be verifiably owned by its tenant, no tenant request reaches the fire zone, and dispatch credentials are minted per attempt
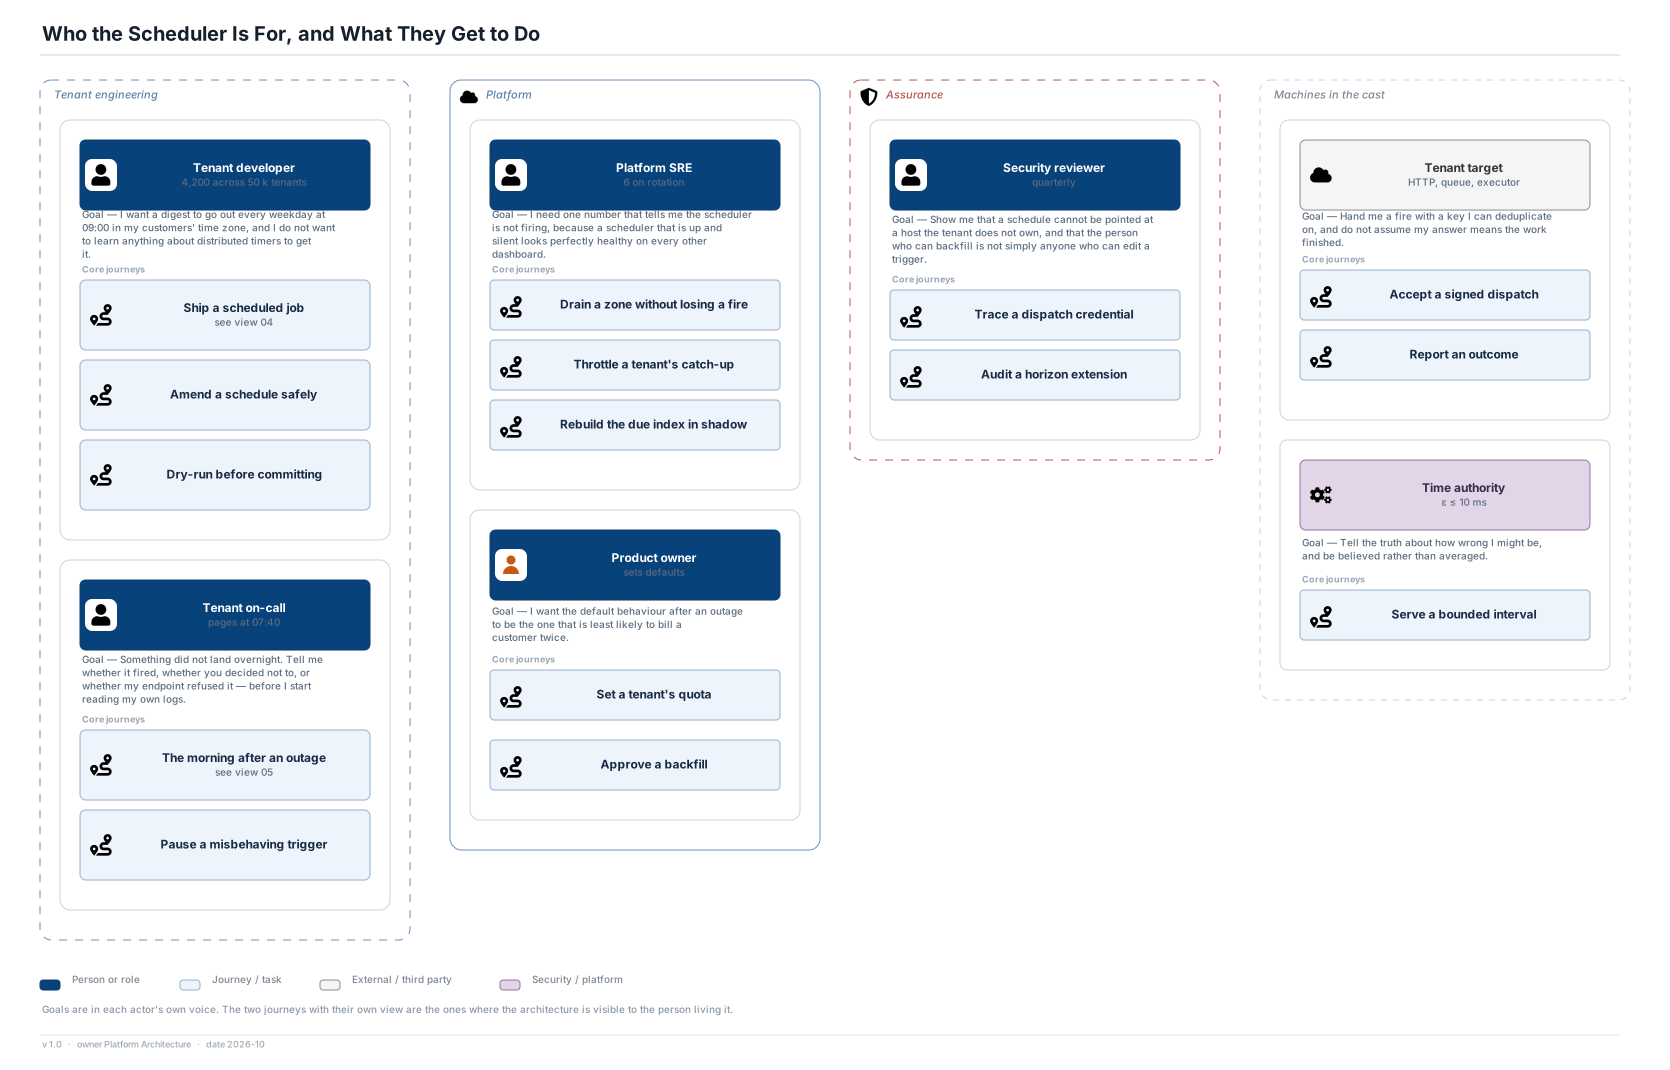
- ADR-15 · Backfill, horizon extension and quota change are grants separate from trigger authorship
- ADR-16 · Tenant payloads live only in the registry and the ledger, encrypted under a per-tenant key, and never in evidence or logs
Technology by capability
Google Cloud was chosen for this exercise for two reasons that point the same way. The first is rotation: across this repository's use cases Microsoft Azure and self-hosted open source dominate, with Amazon Web Services next, and Google Cloud carries the smallest share — six of forty-four packages before this one. Reaching for the same cloud each time teaches a service catalogue rather than architecture. The second reason is that this particular topic genuinely belongs here. A scheduler's hardest requirement is a defensible answer to "what time is it, and how wrong could that be", and this is the platform that exposes a bounded clock-uncertainty interval on a transactional store rather than asking the design to assume one. ADR-04 is the decision that depends on it, and it would read as hand-waving on a stack that cannot report its own clock error. Everything else below is replaceable; the requirement document deliberately stays vendor-neutral so that it survives a change of cloud.
| Capability |
Choice |
Origin |
Credible alternative |
Why this one |
Record |
| Trigger registry, due index, fire ledger |
Spanner regional instance, synchronous across three zones, commit timestamps as time authority |
Google Cloud |
CockroachDB or YugabyteDB self-hosted; DynamoDB with a separate time service; Azure Cosmos DB with strong consistency |
One store that enforces the fire key's uniqueness constraint and reports bounded clock uncertainty — the two properties ADR-01, ADR-03 and ADR-04 all depend on |
ADR-01 |
| Bounded-uncertainty time |
Platform time service plus Spanner commit timestamps, with per-node ε recorded at lease grant |
Google Cloud |
AWS Time Sync with clock bound; a self-run PTP fabric; chrony with a measured error estimate |
The decision to wait out ε rather than fire at the earliest permitted instant needs a source that reports its own error, not one that is merely accurate |
ADR-04 |
| Control, timing and dispatch planes |
Cloud Run services, separately deployed and scaled, with distinct service accounts |
Google Cloud |
GKE workloads; ECS or Fargate; Azure Container Apps |
Independent scaling and deployment is the mechanism of the plane split, and leases make long-lived instances unnecessary |
ADR-02 |
| Dispatch lanes |
Three Cloud Tasks queues per region with independent rate and concurrency |
Google Cloud |
SQS with separate queues; RabbitMQ with per-queue limits; Azure Service Bus |
Per-queue dispatch-rate control is exactly the throttle the catch-up cap needs, and it is enforced by the queue rather than by application code |
ADR-09 |
| Outcome events |
Pub/Sub for correlated outcome events from the platform executor |
Google Cloud |
Kafka; SNS and SQS; Event Hubs |
Decouples the executor's reporting from the dispatch path, so a slow reporter is not a slow dispatcher |
ADR-12 |
| Fire history |
Bigtable projection keyed tenant#trigger#instant with a 90-day TTL |
Google Cloud |
DynamoDB with TTL; Cassandra; Azure Table Storage |
500 million rows a day of append-mostly evidence with a prefix-scan read pattern and native expiry |
ADR-13 |
| History archive |
Cloud Storage, archive class, 13 months, dual-region |
Google Cloud |
S3 Glacier Instant Retrieval; Azure Blob archive tier |
Retention without query cost; the archive is for obligations, not for answering questions |
ADR-13 |
| Lateness and cost reporting |
BigQuery for lateness facts, shadow divergence and cost per million fires |
Google Cloud |
Snowflake; Redshift; ClickHouse self-hosted |
Keeps punctuality analysis entirely off the fire path, including during the incident it is being used to diagnose |
ADR-11 |
| Dispatch identity |
Workload identity tokens minted per attempt, scoped to the trigger, verified by the target's issuer check |
Google Cloud |
SPIFFE/SPIRE with short-lived SVIDs; AWS IAM Roles Anywhere; Azure managed identities |
A credential whose lifetime equals an attempt reduces a standing grant to a seconds-long one |
ADR-14 |
| Payload encryption |
Cloud KMS per-tenant keys, decrypted only in the dispatch path |
Google Cloud |
HashiCorp Vault transit; AWS KMS; Azure Key Vault with an HSM-backed key |
Per-tenant keys make deletion enforceable by key destruction rather than by trusting every copy to be found |
ADR-16 |
| Perimeter and egress |
VPC Service Controls around the data stores; egress only from the attempt runner |
Google Cloud |
AWS PrivateLink and SCPs; Azure Private Endpoints with a firewall |
One component with egress is an egress policy small enough to audit |
ADR-14 |
| Observability |
Cloud Monitoring for due-age and lateness, Cloud Logging with fire keys and no payloads |
Google Cloud |
Prometheus and Grafana; Datadog; Azure Monitor |
The alert is a derived measurement (oldest undispatched due age), so it needs a metric pipeline rather than a log search |
ADR-13 |
| Audit |
Append-only audit table with a Cloud Storage Object Lock export, 7 years |
Google Cloud |
S3 Object Lock; Azure immutable blob storage; an on-prem WORM appliance |
The acts worth auditing are the ones that multiply work, and their record has to survive the actor who performed them |
ADR-15 |
The decisions, and the alternatives that lost
Decision and delivery
The boundary that defines the architecture, and the two decisions that follow from it directly.
ADR-01 · The scheduler's durable output is a committed fire record, written before any dispatch attempt
Status: Accepted · Shown on views: 02, 07, 12
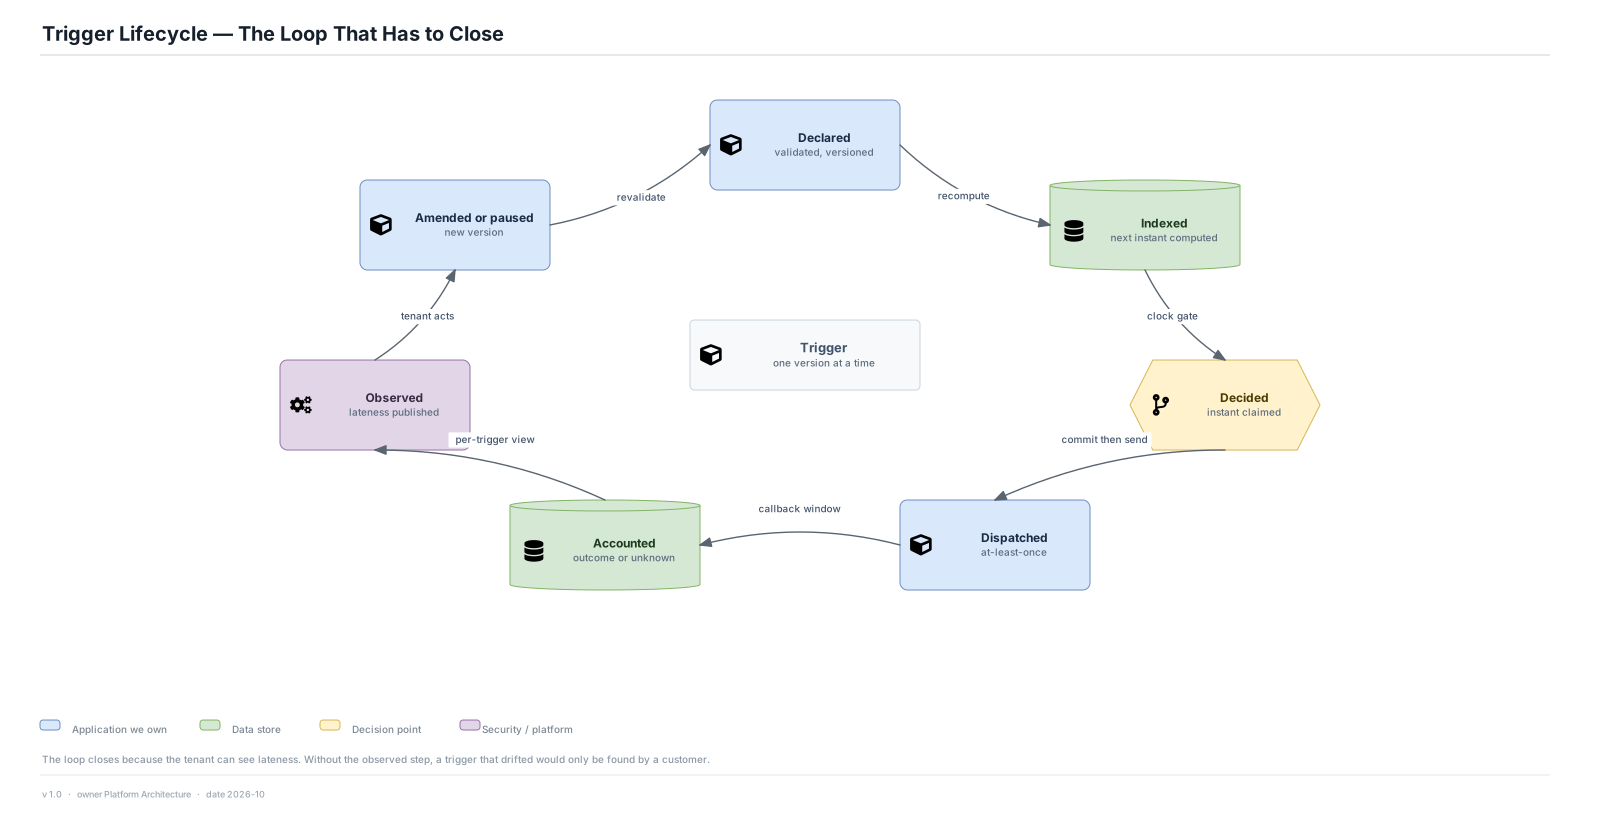
When a dispatcher dies holding a fire it has decided is due, what has been lost?
Context. The convenient implementation of a scheduler dispatches first and records afterwards: the timer fires, the HTTP call goes out, and a row is written when the call returns. It is one less write on the hot path and it reads naturally. It also has no answer to the question above. A dispatcher that dies after the call and before the write leaves a fire that happened and is not recorded — which means the next scheduler to look at that trigger will fire it again, and nothing in the system can tell the difference between that and the first fire. The inverse ordering has the opposite failure: a fire recorded and not dispatched, which is a retry. One of those is unrecoverable and the other is routine, and the ordering of two writes decides which one the system has.
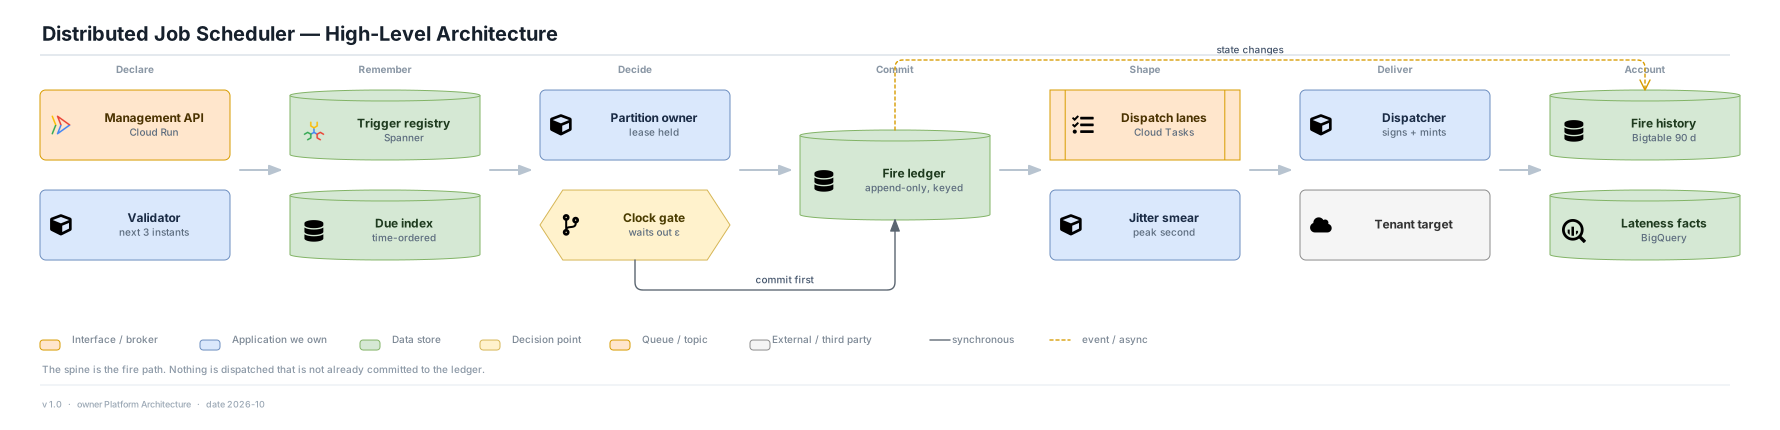
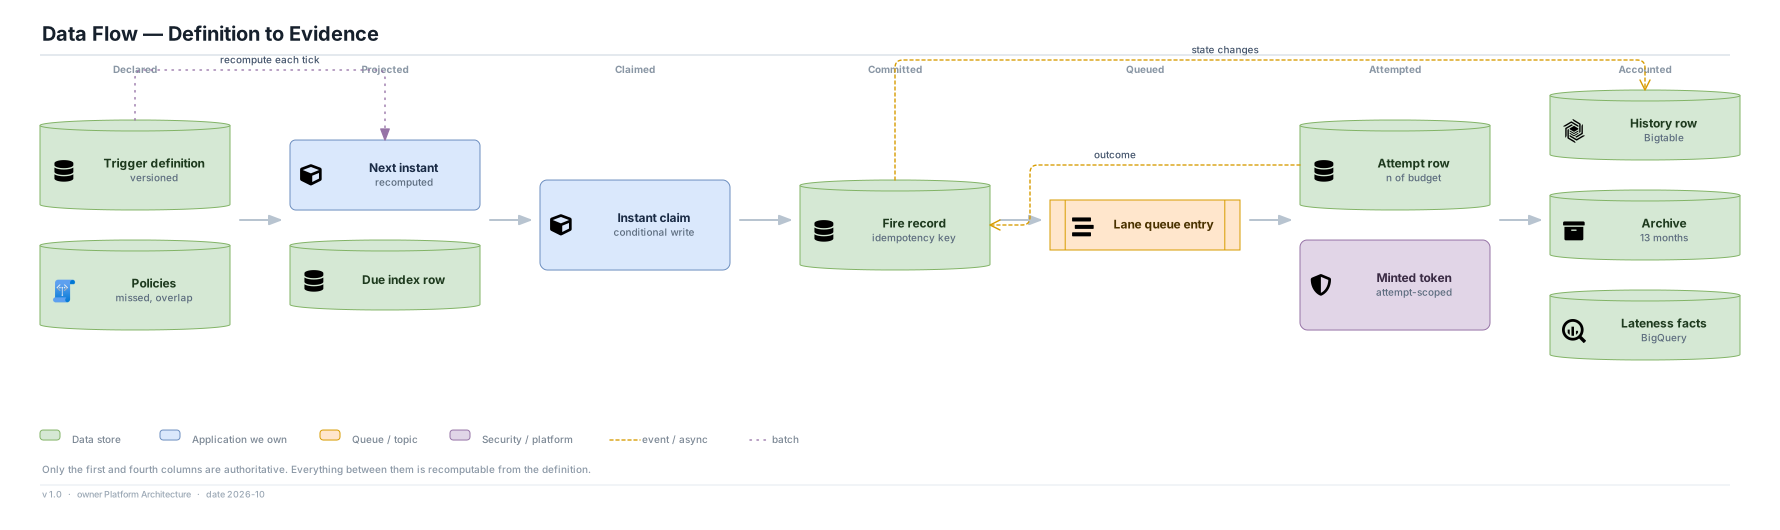
Decision. An immutable fire record — tenant, trigger, definition version, scheduled instant, deterministic idempotency key, attempt counter — is committed to a strongly consistent store before any dispatch attempt is made. The record, not the delivery, is the scheduler's durable product. Delivery is a retryable consequence of a record that already exists.
How it is realised on AWS. The fire ledger is a Spanner table whose primary key is (tenant_id, trigger_id, scheduled_instant, sequence). A partition owner that has decided an instant is due performs the insert inside the same transaction that advances the due index row, then enqueues onto a Cloud Tasks lane. The attempt runner reads the record, mints a per-attempt credential, signs the payload and dispatches; every attempt writes an attempt row against the same fire key. Nothing in the dispatch plane can create a fire.
| Option |
Verdict |
Reasoning |
| Commit the fire record, then dispatch |
Chosen |
Makes the unrecoverable failure impossible and the recoverable one routine; costs one transactional write per fire on the critical path |
| Dispatch, then record the outcome |
Rejected |
Cheaper and simpler; a crash between the two produces a fire that happened and cannot be proved, which is the one state the design cannot recover from |
| Write an intent record best-effort, reconcile later |
Rejected |
Reconciliation needs a source of truth to reconcile against, and the intent record was supposed to be it |
| Rely on the queue's own durability as the record |
Rejected |
A queue entry is not addressable by scheduled instant, cannot be queried by a tenant asking "did it run", and its retention is not the history retention |
What it buys
- A dispatcher can die at any point in an attempt and the worst outcome is a duplicate attempt under a key the executor already knows
- "Did it run" becomes a primary-key lookup rather than a log search, which is what makes fire history a product surface instead of a support tool
- Retry, catch-up, backfill and manual run are all the same operation — attempts against a record — rather than four code paths
What it costs
- One strongly consistent write per fire sits on the critical path, which at a 45,000/s design peak is the single largest capacity commitment in the system
- A ledger outage stops fires entirely rather than degrading them, which is deliberate (ADR-02) and is the hardest consequence to explain to a tenant
- The ledger grows at 500 million rows a day and needs a retention and partitioning story from day one rather than later
Choose differently when. If the work being triggered were idempotent by nature and cheap to repeat — a cache warm, a metrics scrape, a health probe — the unrecoverable failure would not matter and dispatch-then-record would be the right trade. The decision is justified by schedules that send money, email and statements, where a fire that cannot be proved is worse than a fire that is late.
Why it holds up over time. "The decision is the product" is a statement about where authority lives, not about which store holds it. Spanner, a successor nobody has shipped, or a different consistent store can each satisfy it, and everything downstream — the key as the deduplication mechanism, lanes as retries against records, history as a projection — survives the substitution unchanged. What would not survive is a move to an eventually consistent store for the ledger, because the uniqueness constraint is the whole mechanism.
Lesson. In any system that acts on the world on a timer, decide which of your two unavoidable failures is the recoverable one, and then order your writes so you only ever get that one.
ADR-02 · The control plane and the timing plane share only the state of record, and there is one write region
Status: Accepted · Shown on views: 06, 07, 15
If the API that creates schedules is down, should schedules still fire?
Context. A scheduler has two obviously different jobs. One is interactive, bursty, request-shaped and has a human waiting: create, amend, pause, dry-run, read history. The other is autonomous, continuous, deadline-driven and has nobody waiting: decide which instants are due and hand them over. Building them as one service is the default, and it means a deploy, a bad query, a traffic spike on the console or an authorisation dependency outage takes the fire path with it — the plane with a deadline is held hostage by the plane with a user. The same question repeats across regions: a second region that can also decide instants doubles write availability and introduces two authorities deciding the same overlap question, which the fire key deduplicates only after both have already decided.
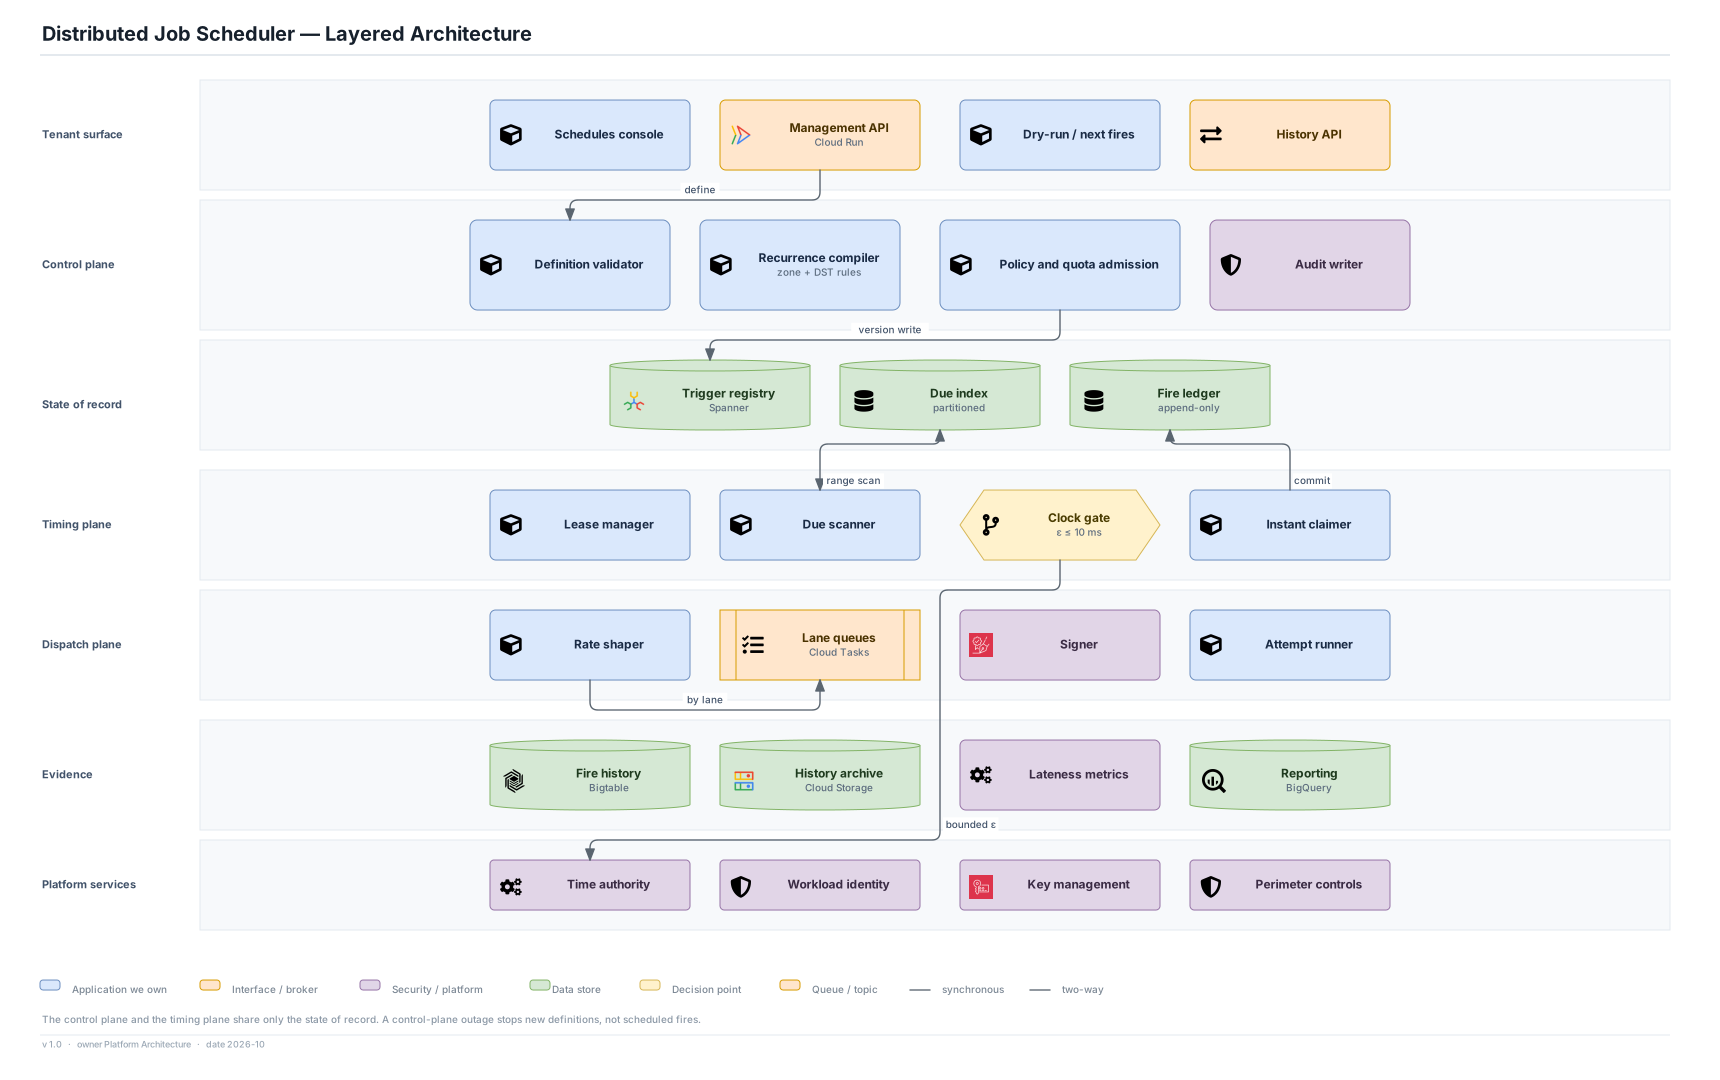
Decision. The control plane and the timing plane are separately deployed, separately scaled and separately available, sharing nothing but the strongly consistent state of record. A control-plane outage stops new and amended definitions; it does not stop scheduled fires. Scheduling authority lives in exactly one write region, with a standby region that replicates state and holds no partition leases.
How it is realised on AWS. Both planes run as independent Cloud Run services with separate service accounts, deployment pipelines and scaling policies, against one Spanner instance holding registry, due index and ledger. Partition leases are rows in that instance, so only a process with write access to the primary region can hold one. The standby region runs the same images scaled to zero with a read replica; promotion is a declared operation that moves the lease table's authority, not an automatic failover.
| Option |
Verdict |
Reasoning |
| Separate planes, one write region, cold standby |
Chosen |
Fire path survives control-plane failure; region loss is a declared promotion against a stated RPO |
| One service for both planes |
Rejected |
Simplest to operate and deploy; makes every console incident a punctuality incident |
| Active-active scheduling across two regions |
Rejected |
Best availability; two authorities decide overlap and concurrency independently, and the fire key cannot undo a decision already taken |
| Separate planes with the control plane in a second region |
Rejected |
Attractive for console availability; a definition written in region B that region A has not yet seen is a fire that silently did not happen |
What it buys
- Console traffic, a bad management deploy and an identity-provider outage are all latency incidents rather than missed fires
- The timing plane's dependency list is short enough to reason about: the state of record and the time authority
- Overlap and concurrency decisions have exactly one authority, which is what makes the
skip and queue policies in ADR-12 meaningful
What it costs
- Two deployments, two scaling policies and two on-call surfaces for one product
- Region loss costs up to the replication lag in decisions and a declared promotion rather than a transparent failover
- Control-plane availability is lower than the dispatch plane's, and tenants will experience that as the service being down
Choose differently when. If the scheduler served one tenant with a hundred triggers, the operational cost of two planes would dominate the availability it buys and one service would be right. At 50,000 tenants, the console is busy enough that treating its incidents as fire-path incidents is indefensible.
Why it holds up over time. The plane split is an availability-domain statement and outlives any runtime. Active-active scheduling stays rejected for a structural reason rather than a technical one: the fire key makes a duplicate fire harmless, but two regions independently evaluating "is the previous execution still running" produce two different answers, and no key reconciles those. That reasoning does not change if replication gets faster.
Lesson. Split a system where its deadlines differ, not where its nouns differ. A plane with a user and a plane with a deadline should never be able to take each other down.
ADR-03 · Idempotency lives in the data model: the fire's primary key is the idempotency key, and delivery is at-least-once
Status: Accepted · Shown on views: 11, 12, 20
Two schedulers both believe the same instant is due. What stops two fires?
Context. Every distributed scheduler eventually has two processes that believe they own the same trigger: a lease handover, a network partition, a paused process resuming, a clock disagreement. The usual responses are to make that impossible — a stronger lease, a consensus round, a global leader — or to detect it afterwards with a deduplication store keyed by some generated identifier. The first is expensive and still probabilistic, because a lease is a promise about time held by a process that may not know the time. The second adds a component on the critical path whose own availability becomes the fire path's availability, and whose retention window becomes the deduplication guarantee. Both are machinery built to compensate for an identifier that was chosen badly.
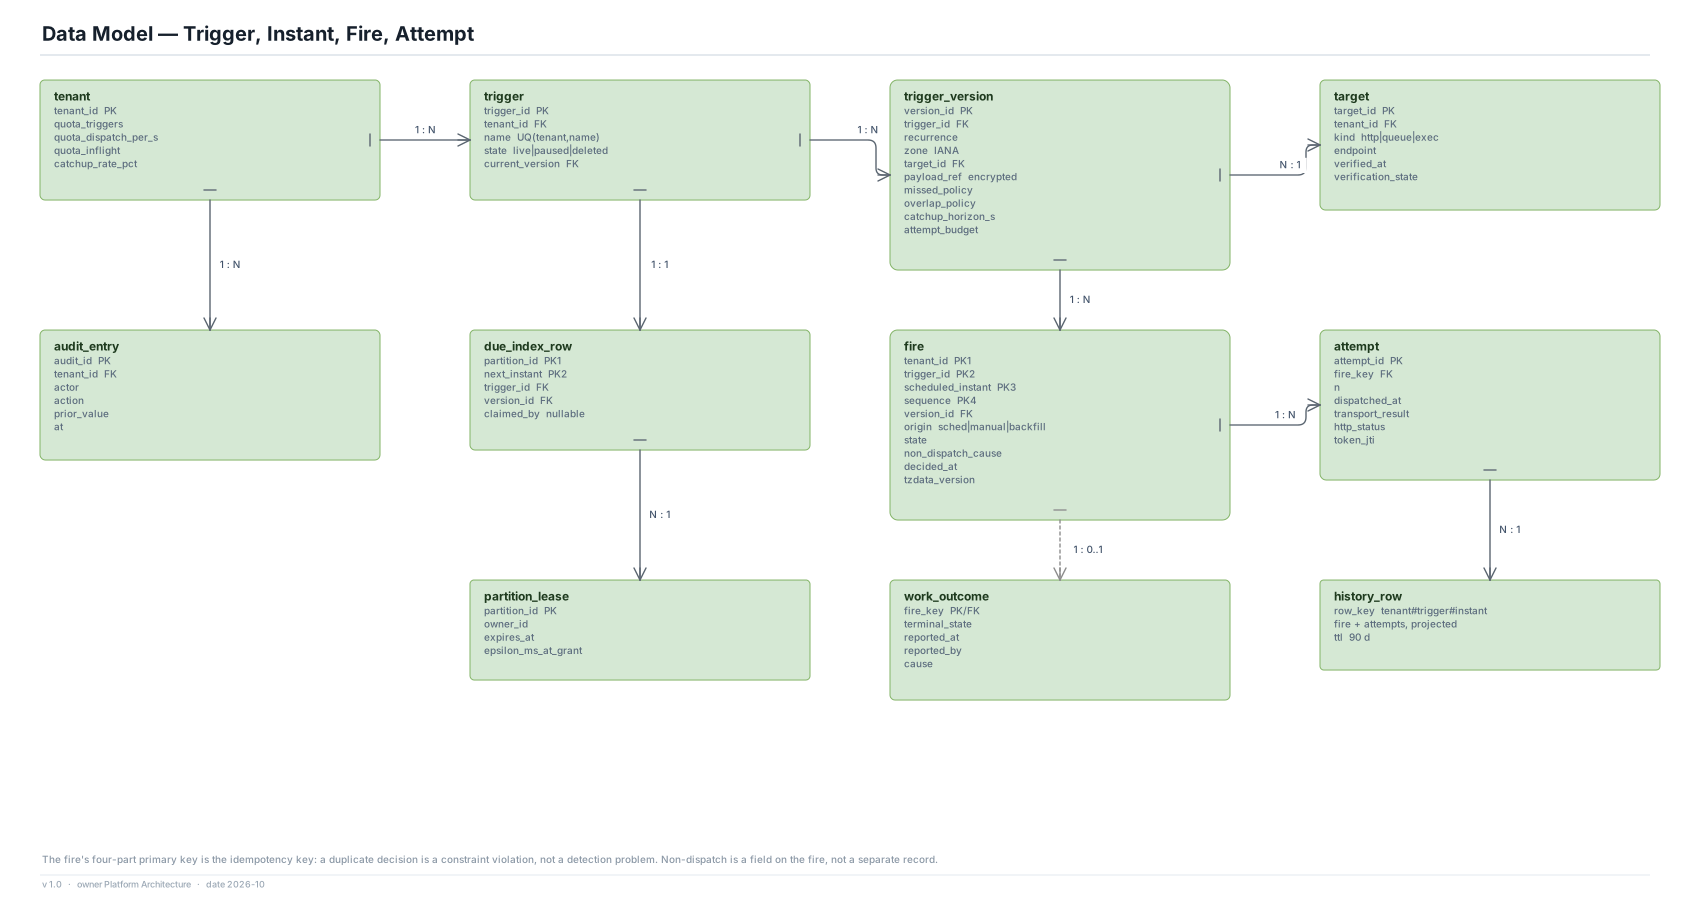
Decision. The fire's identity is derived deterministically from (tenant, trigger, scheduled instant, sequence within instant) and is the primary key of the fire ledger. Two processes that both believe an instant is due compute the same key, so the second insert fails on a uniqueness constraint. Delivery to the executor is at-least-once, the key travels with every dispatch, and the residual duplicate rate is published as a contract the executor must tolerate rather than concealed behind an exactly-once claim.
How it is realised on AWS. The ledger's Spanner primary key is the four-part tuple; the insert is a plain INSERT whose ALREADY_EXISTS is handled as a normal, expected return meaning "another owner decided this instant". The same key is sent in the dispatch payload and in a header, so an HTTP target, a queue consumer and the internal executor all deduplicate on the same value. Attempts are child rows under the fire key, so a retry can never create a second fire.
| Option |
Verdict |
Reasoning |
| Deterministic key as the ledger primary key |
Chosen |
Turns split ownership into a constraint violation; needs no extra component and no retention window |
| Generated UUID per fire with a deduplication store |
Rejected |
Works for transport retries; cannot deduplicate two independent decisions, because they generate different identifiers |
| Consensus round before every fire |
Rejected |
Strongest agreement; adds a round trip to a 45,000/s peak and still leaves the clock question open |
| Claim exactly-once delivery via transactional outbox to the executor |
Rejected |
Honest only where the platform owns the executor, which is one of four target forms |
What it buys
- Leader election is allowed to be imperfect, which means leases can be short and takeover fast (15 s) without risking correctness
- No deduplication component sits on the fire path, so there is one less thing whose outage is an outage
- The duplicate rate is a published number a tenant can design against rather than a property they discover
What it costs
- Every executor must deduplicate. A tenant target that cannot is a correctness gap the platform cannot close for them
- The sequence component of the key has to be decided by whoever decides an instant produces more than one fire, which is a subtlety in the catch-up path
- A monotonic key means hot-spotting on the ledger's key range at the top of the hour, mitigated by the tenant prefix leading the key
Choose differently when. If the platform owned every executor, a transactional handoff would make exactly-once honest and the published duplicate rate unnecessary. With tenant HTTP targets in the mix it is not achievable, and claiming it would be the more dangerous choice.
Why it holds up over time. Deterministic identity from the semantics of the event is the oldest reliable trick in distributed systems and does not depend on a store, a broker or a protocol. What could change is the willingness of executors to deduplicate; if that becomes unrealistic, the decision does not need replacing so much as supplementing with a platform-side suppression store — an addition, not a rewrite.
Lesson. Before building a deduplication service, ask whether the thing being deduplicated could have been given a name that makes duplicates impossible to express.
Time
What time it is, how wrong that might be, and what a wall-clock expression actually means.
ADR-04 · The node clock is untrusted; dispatch waits out a bounded uncertainty interval, so lateness is a budget and earliness is a bug
Status: Accepted · Shown on views: 06, 12, 20
A node believes it is 09:00:00. How wrong could it be, and which direction of wrongness is acceptable?
Context. A scheduler is a program whose entire output depends on the one value that distributed systems are worst at agreeing on. NTP-synchronised clocks in a datacentre are usually within a few milliseconds and occasionally wrong by seconds — a lost sync, a step correction, a virtualised clock after a live migration. The default implementation reads the system clock and fires when it passes the scheduled instant, which means a node whose clock runs fast fires early. Early is the dangerous direction: scheduled work overwhelmingly reads a window of data that is defined by the scheduled instant, so a job that fires before its instant reads a window that has not closed, produces a short report, and looks like it succeeded. Late work reads the right window and arrives inconveniently. These two failures are not symmetrical and should not share a budget.
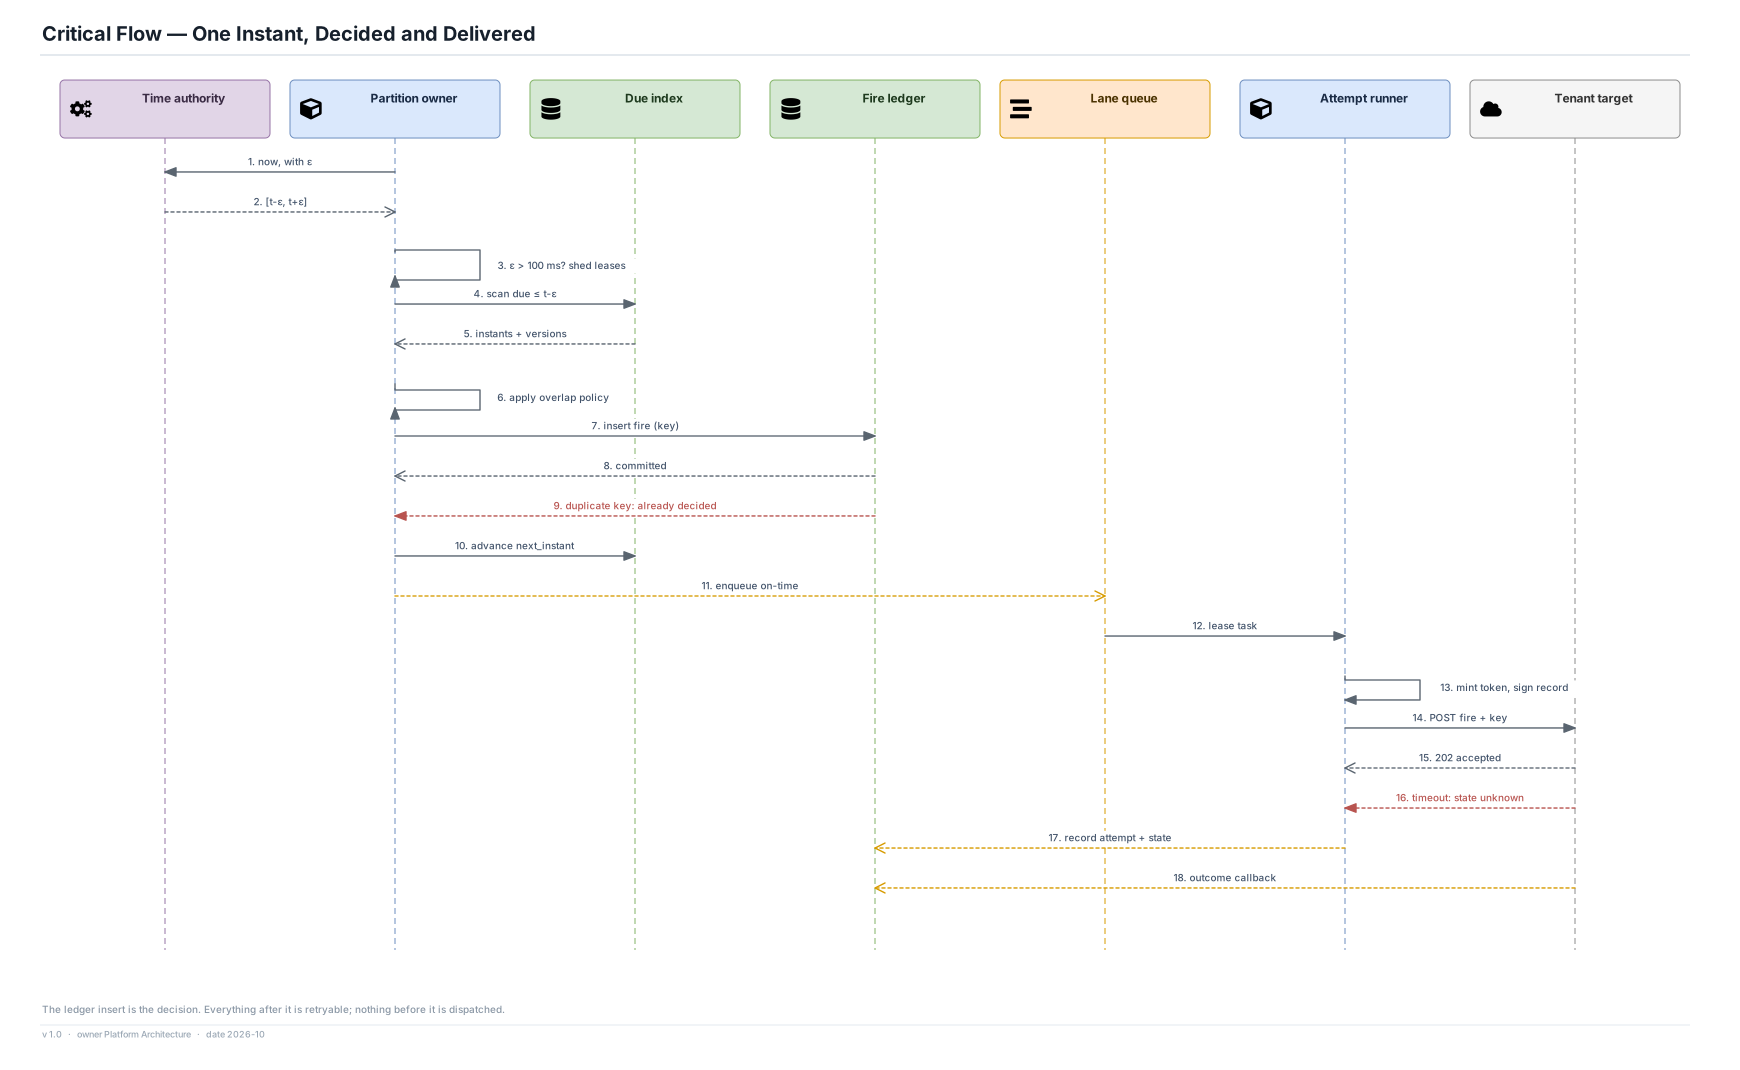
Decision. Dispatch decisions are taken only against a time source that reports a bounded uncertainty interval, and the scheduler waits out that interval rather than firing at the earliest instant it permits — scanning for instants due at or before t−ε. Lateness is measured, bounded and published; earliness has no acceptable rate at any percentile. A node whose reported uncertainty exceeds a declared ceiling sheds its partition leases and continues serving reads rather than firing on a clock it cannot justify.
How it is realised on AWS. The timing plane takes time from Spanner commit timestamps and the platform's bounded-uncertainty time service rather than from clock_gettime. The due scan selects instants <= now_lower_bound, so the scheduler is deliberately ε late. Each partition owner records the ε it observed at lease grant on the lease row; above 100 ms it releases the lease and the lease manager reassigns the partition. Clock ε is a per-node metric, not an aggregate, because a fleet-wide drift is invisible in an average.
| Option |
Verdict |
Reasoning |
| Bounded-uncertainty source, wait out ε, shed leases above a ceiling |
Chosen |
Guarantees no earliness for about 10 ms of deliberate lateness; needs a time service that reports its own error |
| Trust the NTP-synchronised system clock |
Rejected |
Free and usually fine; produces early fires exactly when a node is unhealthy, and no node can tell that it is the wrong one |
| Take time only from the store's commit timestamp |
Rejected |
Close to chosen and simpler; a read per scan cycle is acceptable but leaves no per-node signal with which to shed a bad clock |
| Fire at the midpoint of the uncertainty interval |
Rejected |
Halves the deliberate lateness and makes earliness a rate rather than an impossibility |
What it buys
- No fire is ever early, at any percentile, which removes an entire class of silent wrong answers from the work the scheduler triggers
- A bad clock is a detectable local condition with a local response, rather than a fleet-wide correctness problem
- Short leases become safe, which is what makes a 15 s takeover budget achievable (ADR-11)
What it costs
- Every fire pays ε of deliberate lateness — cheap at 10 ms, and the decision would not survive a bound of 500 ms
- The design depends on a platform capability (a clock that reports its own error) that is not available everywhere, which constrains portability
- A node sheds leases on a clock problem, so a correlated clock event reduces scheduling capacity exactly when nothing is wrong with the schedulers
Choose differently when. If the scheduler only triggered work whose correctness did not depend on its instant — notifications, cache warms, retries — earliness would be harmless and the simplest clock would do. The decision is justified by work that reads a window the scheduled instant defines.
Why it holds up over time. The rule survives every change of clock technology, because it is a statement about which direction of error is acceptable rather than about how accurate the clock is. If clocks get better, ε shrinks and the deliberate lateness disappears; if they get worse, the ceiling catches it. What would break the decision is a platform with no bounded-error time source at all, which would force the weaker commit-timestamp variant above.
Lesson. When a system's output depends on a measurement, ask which direction of measurement error is survivable, and spend the error budget entirely in that direction.
ADR-05 · Recurrences are recomputed each cycle from a versioned definition, not materialised ahead into the due index
Status: Accepted · Shown on views: 09, 11, 17
Should the next thousand fire instants be computed now and stored, or computed each time they are needed?
Context. A calendar recurrence is a function of an expression, a time zone, a time-zone database and a validity window. Materialising its instants weeks ahead makes the due index trivially cheap to scan: it is already a sorted list of absolute times. It also creates a cache that four separate events invalidate — an amendment, a pause, a time-zone database update, and a change to the validity window — and the invalidation has to find every materialised instant for one trigger among many millions. Recomputing instead costs CPU on every scan cycle, proportional to the trigger population rather than to the instants actually due, and it makes the correct answer the only answer the system can give.
Decision. The due index holds exactly one row per live trigger, carrying its single next instant, recomputed and advanced when that instant is claimed. The recurrence is evaluated against the trigger's named zone at the moment of computation. A definition is immutable once fired against; an amendment creates a new version and the index row is recomputed under it, so the instant the scheduler uses is always derived from the rules currently in force.
How it is realised on AWS. The recurrence compiler is a pure function in the control plane and the timing plane, shared as one library and exercised by dry-run on the production path, so the next three instants shown to a developer are the instants the scheduler will use. The due index row carries trigger_id, version_id and next_instant; claiming an instant and advancing the row happen in the transaction that inserts the fire (ADR-01). An amendment writes a new trigger_version and recomputes the row within the 5-second propagation budget.
| Option |
Verdict |
Reasoning |
| One next instant per trigger, recomputed on advance |
Chosen |
Always correct under the current rules, with no invalidation to get wrong; costs a compiler call per fire and per amendment |
| Materialise instants weeks ahead |
Rejected |
Cheapest possible scan; four separate invalidation paths, each of which silently produces a fire at an instant the current rules disagree with |
| Materialise a short horizon, say one hour |
Rejected |
A real middle ground and the most likely future revision; still needs invalidation, and buys little while the scan is per-partition |
| In-memory timer wheels per partition |
Rejected |
Lowest dispatch latency; makes the authoritative structure non-durable, so a restart re-derives it anyway |
What it buys
- A time-zone database update, an amendment and a pause are all picked up with no invalidation sweep, because nothing was stored to invalidate
- Dry-run is exact rather than indicative, which is what makes it useful at the moment a developer commits a schedule
- The due index stays small — one row per trigger — so a partition scan is proportional to what is due rather than to history
What it costs
- Recurrence evaluation sits on the scan path, so a slow or pathological expression is a scheduling cost rather than a one-off authoring cost
- A trigger population of 20 million means 20 million index rows kept current, which is a write rate proportional to the fire rate
- There is no cheap way to answer "show me every fire in the estate next Tuesday", which a materialised index would give for free
Choose differently when. If recurrence evaluation were expensive — tenant-supplied predicates against business calendars, say, as the ask defers to Phase 3 — the balance would move towards a short materialised horizon with explicit invalidation. For three fixed recurrence forms it does not.
Why it holds up over time. The decision is really about where correctness lives: in a recomputation, or in a cache plus its invalidation. That trade does not change with hardware. If evaluation cost ever dominates, the short-horizon variant is a localised change to the due index's contract and leaves the ledger, the key and the lanes untouched.
Lesson. A cache of derived values is a commitment to invalidate it correctly on every input that feeds it. Count those inputs before you build the cache.
ADR-07 · Wall-clock recurrences resolve against a named zone with declared DST rules, and the time-zone database version is recorded on every fire
Status: Accepted · Shown on views: 09, 11, 20
What does "every day at 02:30" mean on the day 02:30 happens twice, and on the day it does not happen at all?
Context. A calendar recurrence in a named zone has two days a year where it is ambiguous or impossible, and a scheduler must have an answer for both. Worse, the mapping from wall-clock to absolute instant is not fixed: time-zone databases are updated several times a year, and a government changing its rules moves a future instant that the scheduler may already have told a tenant about. Storing instants in UTC and forgetting the zone makes the system immune to this and also wrong — a tenant who asked for 09:00 local means 09:00 local after the rules change, not 08:00. Any system that does not record which rules it used cannot explain, six months later, why a fire landed where it did.
Decision. Calendar recurrences store the wall-clock expression plus the IANA zone and resolve against the zone at the moment of computation. A wall-clock time that does not exist on a given day fires at the instant the clock jumps to; a wall-clock time that occurs twice fires on the first occurrence only. Both outcomes are visible in history as such. The time-zone database version used is recorded as a column on every fire record.
How it is realised on AWS. The recurrence compiler pins a tzdata version per deployment and writes it to the trigger_version row and to every fire. The two DST rules are implemented once in the shared compiler, so dry-run shows the same substitute instant production will use. A tzdata upgrade is a deliberate deployment that re-resolves future instants; the version on past fires explains any instant a tenant disputes.
| Option |
Verdict |
Reasoning |
| Expression + zone, resolved at computation, version recorded |
Chosen |
Means what the tenant asked; the recorded version is what makes a disputed instant explainable |
| Convert to UTC at authoring time |
Rejected |
Immune to rule changes and simple; silently wrong for the tenant twice a year and permanently wrong after a rule change |
| Fire on both occurrences of an ambiguous time |
Rejected |
Defensible for monitoring work; produces a double billing run once a year |
| Skip a non-existent wall-clock time entirely |
Rejected |
Honest, and means a daily job silently does not run one day a year — the failure nobody notices until the month-end total is short |
What it buys
- The tenant's expression means what they think it means, including after their government changes the rules
- The two hard days a year have a declared, testable, documented behaviour rather than whatever the library did
- A disputed instant is explainable from data, because the rules in force are recorded alongside the fire
What it costs
- A tzdata upgrade is a change to future behaviour and needs treating as a deploy with a review, not a dependency bump
- Zone resolution on every computation adds cost to the scan path (ADR-05 already pays for recomputation)
- The "first occurrence only" rule will surprise someone whose job genuinely wanted both
Choose differently when. If every tenant were in one zone with no daylight saving, the whole decision would collapse into storing UTC. It is justified by a multi-tenant platform whose tenants' customers are the ones whose local morning matters.
Why it holds up over time. Time-zone rules will keep changing and the IANA database will keep being the way to track them. Recording the version used is a general principle — any derived value computed from an external ruleset should carry the ruleset's version — and it does not depend on anything in this stack.
Lesson. If a value is computed from rules that someone else can change, store the version of the rules alongside the value, or you will one day be unable to explain your own output.
Policy after the outage
What a trigger does about the fires it missed — declared before it misses them, not decided during the incident.
ADR-06 · The missed-fire policy is declared per trigger before the outage, and defaults to firing once for the most recent missed instant
Status: Accepted · Shown on views: 04, 13, 17
Who decides what a trigger does about the fires it missed, and when is that decision taken?
Context. After any interruption — a platform incident, a long pause, a trigger resumed after a weekend — there is a set of instants that should have fired and did not, and three defensible things to do with them. Fire all of them in order, fire once for the most recent, or record them as skipped and fire nothing. Which is correct depends entirely on what the work means, and the platform cannot know that: a billing run and a cache warm have opposite correct answers and look identical from the scheduler's side. The alternative to the tenant declaring it is an operator deciding during the recovery, across 50,000 tenants at once, under pressure, with no information about any of them — a decision that is guaranteed to be wrong for most of the estate.
Decision. Every trigger declares its missed-fire policy at definition time from a closed set — fire-all, fire-once-now, skip — and the platform default is fire-once-now. The policy is part of the versioned definition, so the decision exists before the outage that needs it, and the recovery executes a declaration rather than improvising one.
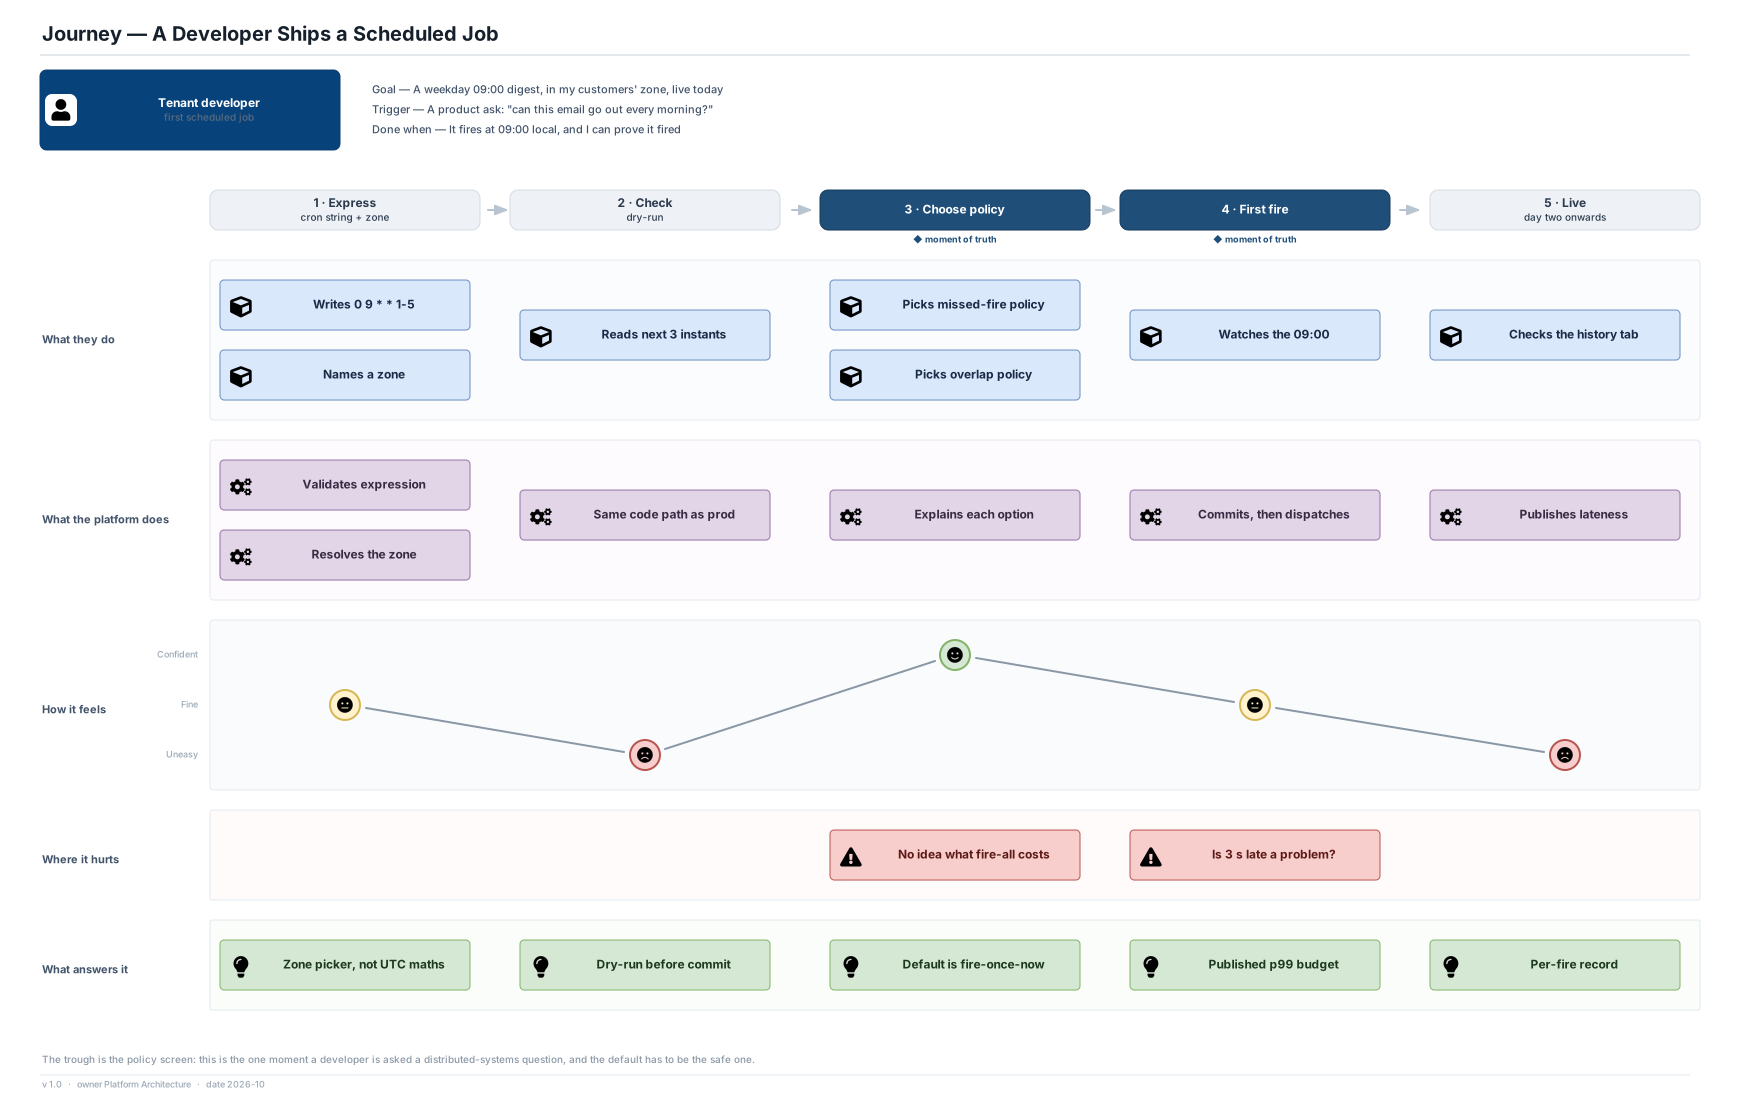
How it is realised on AWS. The policy is a column on trigger_version, surfaced on the authoring screen as the one distributed-systems question a developer is asked, with each option's consequence stated in a sentence. The catch-up path in view 13 applies the horizon filter first (ADR-08) and the policy second. Dry-run shows what a policy change would have done to the last recorded gap, so a tenant can change it with evidence.
| Option |
Verdict |
Reasoning |
| Per-trigger declaration, default fire-once-now |
Chosen |
Puts the decision with the only party who knows what the work means; costs one question at authoring time and a default that will be wrong for some |
| Platform-wide policy |
Rejected |
Nothing to configure and nothing to get wrong; guarantees the wrong behaviour for a large share of the estate |
| Operator decision during recovery |
Rejected |
Maximum flexibility exactly when there is no capacity to use it, and no information to use it with |
| Infer from the trigger's recent behaviour |
Rejected |
Plausible and seductive; a scheduler guessing whether work is idempotent is a scheduler that will be wrong about money |
What it buys
- Recovery is deterministic and rehearsable: the behaviour after an outage is a property of the definition, not of who was on call
- The default is the one least likely to duplicate billable work, which is the failure a tenant will escalate
- A tenant who needs
fire-all declares it, and the declaration is visible to reviewers in their infrastructure code
What it costs
- Every tenant is asked a question most of them would rather not answer, at the moment they least want friction
- A tenant who accepted the default and wanted
fire-all loses work they expected; the cause is recorded but the work is gone
- Three policies × the horizon × the overlap policy is a behaviour matrix that documentation has to make legible
Choose differently when. If the platform owned the work as well as the timer — a managed job runner where every job declared its own idempotency — the platform could infer the policy and the question would be unnecessary. With opaque tenant payloads behind opaque tenant endpoints, it cannot.
Why it holds up over time. "Declare the recovery behaviour before the failure" is a general property of operable systems and does not depend on this stack. The specific default might move: if telemetry shows most tenants override it, the default is wrong and should change. The closed set of three is the part worth defending, because an open-ended policy language here would be a scripting surface on the fire path.
Lesson. If a system will have to make a decision during an incident that it cannot make correctly without information it does not have, collect that information before the incident and call it configuration.
ADR-08 · A catch-up horizon bounds every missed-fire policy, and the original scheduled instant travels with the fire
Status: Accepted · Shown on views: 05, 13, 14
A trigger is resumed after a month. How much work does it owe?
Context. The missed-fire policy (ADR-06) answers what to do with missed instants but not how many of them there can be. A minute-schedule paused for a month and resumed under fire-all owes 43,200 fires; the tenant who clicked resume expected a job to start running again, not a month of history to arrive. The same unbounded set appears after a long incident and after an authorised backfill. Separately, work triggered late almost always reads a window of data defined by its scheduled instant: a statement run for 1 March that executes on 3 March must still report February. A fire that only knows when it was dispatched cannot do that.
Decision. Every trigger carries a catch-up horizon — default 1 hour, maximum 24 hours — and an instant older than the horizon is recorded as expired with its cause and never dispatched, whatever the missed-fire policy says. This is the one place the platform overrules the tenant's declaration. Every caught-up fire carries its original scheduled instant, distinct from its dispatch instant, and both are visible in history.
How it is realised on AWS. The horizon filter runs before the policy in the catch-up path, writing a fire row in expired state with a cause so the tenant can see the decision rather than a gap. The fire's scheduled_instant is part of its primary key and is what the dispatch payload carries; dispatched_at lives on the attempt row. Horizon extension beyond the default is a privileged operation (ADR-15).
| Option |
Verdict |
Reasoning |
| Platform-enforced horizon, original instant preserved |
Chosen |
Bounds the worst case absolutely; costs a tenant some work they may have wanted |
| Unbounded catch-up under the tenant's policy |
Rejected |
Most faithful to the declaration; one resume becomes a self-inflicted denial of service against the tenant's own endpoint |
| Horizon as a soft limit with a warning |
Rejected |
Keeps the tenant in control; a warning nobody reads is an unbounded catch-up with extra steps |
| Dispatch with the dispatch instant only |
Rejected |
Simpler payload; makes every late fire produce work about the wrong window |
What it buys
- The worst case after any interruption is bounded by a number the tenant can see and reason about
- Late work is still correct work, because the window it reads is defined by the instant it was scheduled for
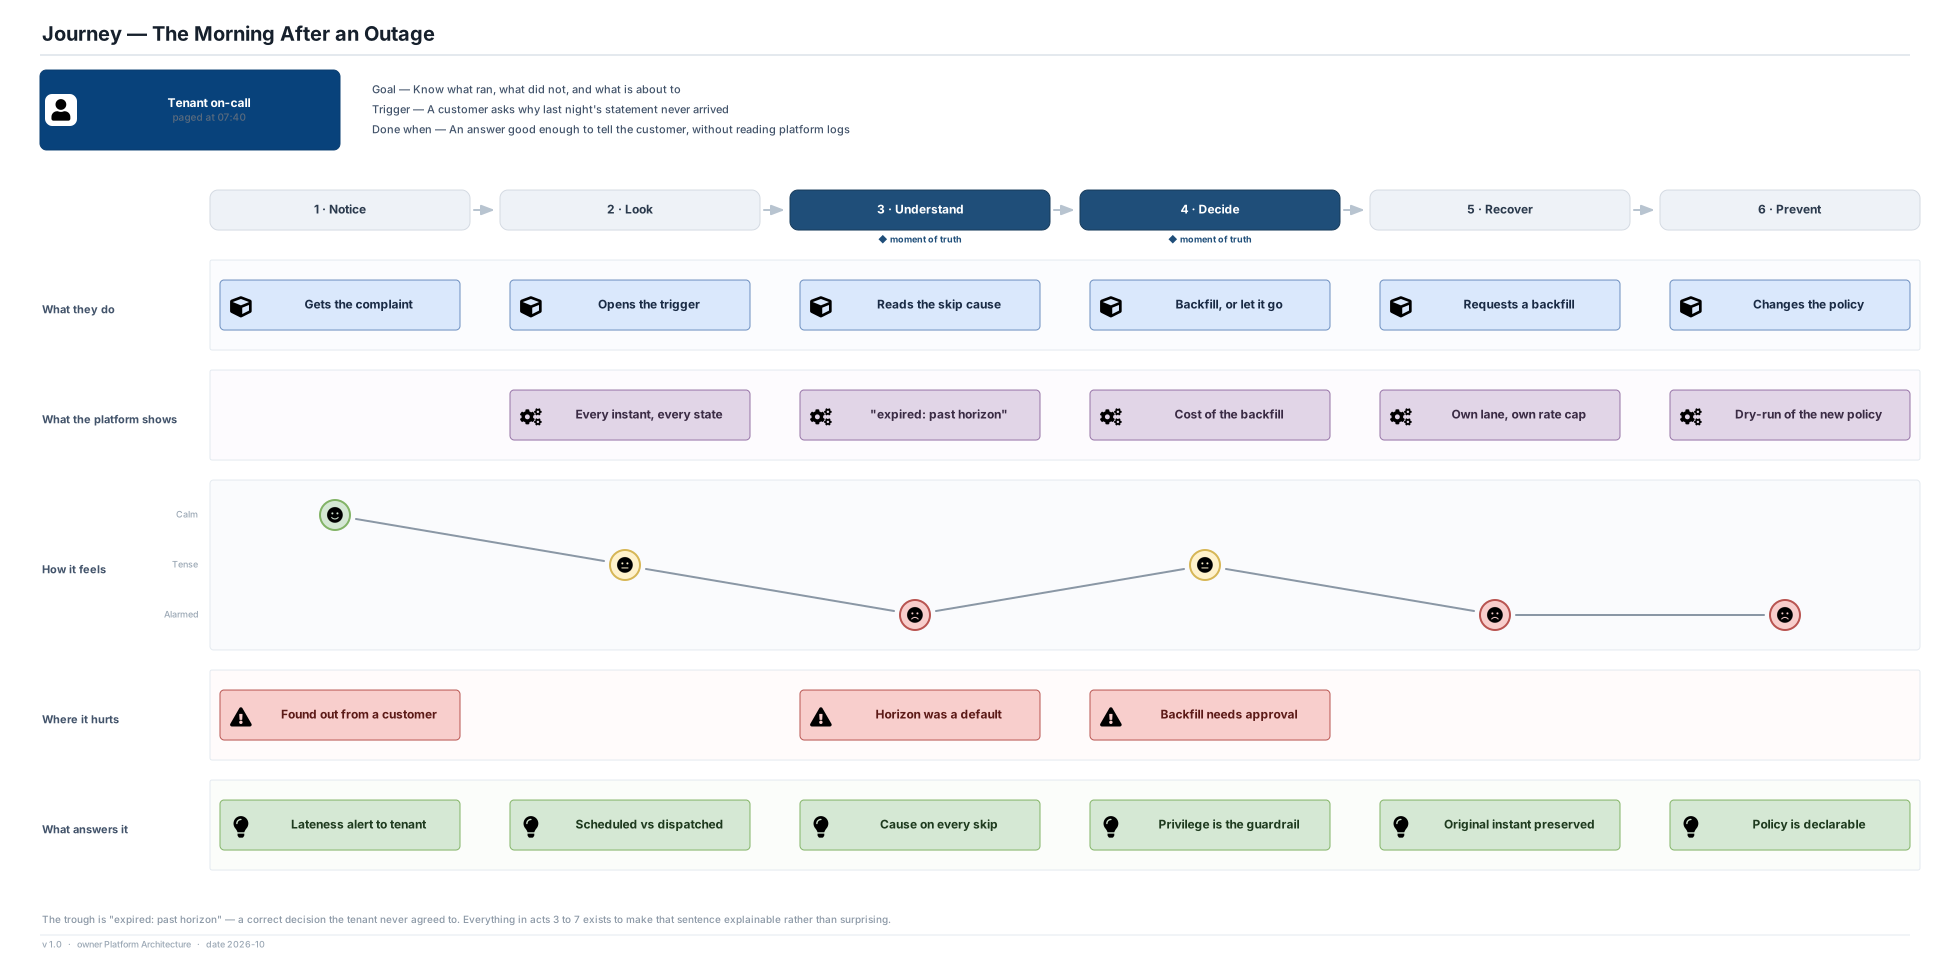
- An expired instant is a visible decision with a cause rather than a silent absence, which is what makes view 05's journey recoverable
What it costs
- A tenant who genuinely needed a month of catch-up must request a backfill, which is a privileged, approved operation
- The horizon is a default and defaults are not read; the first time it matters is during an incident (view 05's trough)
- Two timestamps on every fire is a payload and documentation cost that tenants will initially get wrong
Choose differently when. If the triggered work were always idempotent and cheap, an unbounded catch-up would be harmless and the horizon would be needless friction. The horizon is justified by work that costs money or sends mail every time it runs.
Why it holds up over time. A bound on the recovery set is a general requirement of any system that accumulates obligations while it is down, and the principle survives any implementation. The specific defaults are the arguable part and should move with observed data — which is why they are stated as assumptions rather than constants.
Lesson. Any queue that fills while a system is down needs a stated maximum age, decided before the outage. Without one, recovery is unbounded by construction.
ADR-09 · Catch-up, backfill and on-time fires use separate queues with a per-tenant catch-up cap and a published shedding order
Status: Accepted · Shown on views: 07, 13, 14
A backlog is released. What stops its drain from being the next outage?
Context. Recovery is the most dangerous moment in a scheduler's operation, and it looks like success while it happens. Fires that have been accumulating are suddenly all due, and the natural behaviour — dispatch them as fast as the pipeline allows — turns a scheduling incident into an incident for every executor downstream, including the ones that had nothing to do with it. A single shared queue with priorities does not help as much as it appears to: priorities decide ordering, but a saturated pipeline is saturated for everyone, and the lane that should have been throttled is competing with the lane that should not have been.
Decision. On-time, catch-up and backfill fires are dispatched through separate queues with independent drain rates. A tenant's catch-up dispatch is capped at a fraction of its steady-state quota — assumed at 10% — so a backlog drains over hours rather than minutes. The shedding order is published: backfill first, then catch-up, then over-quota steady-state traffic, and only then on-time fires. Recovery is deliberately slower than the failure that caused it.
How it is realised on AWS. Three Cloud Tasks queues per region, each with its own dispatch rate and concurrency, fed by the rate shaper. Catch-up drains oldest-first within a trigger and interleaves fairly across a tenant's triggers, so no single trigger's backlog starves the rest. A retry stays in the lane its fire came from, and its attempt budget is truncated at the next scheduled instant. A tenant whose targets are systematically failing has its retry volume charged to its own quota.
| Option |
Verdict |
Reasoning |
| Separate queues per class, per-tenant catch-up cap, published shedding order |
Chosen |
Makes the throttle structural rather than a tuning value; costs three queues to operate and a long drain the tenant must accept |
| One queue with priorities |
Rejected |
Fewer moving parts; under saturation the priority decides order, not whether the backlog is throttled |
| Unthrottled drain with autoscaling |
Rejected |
Fastest recovery for the platform; moves the incident to every tenant executor at once |
| Withhold the decision so the backlog never materialises |
Rejected |
A real alternative (Question 5 in the ask); keeps the ledger smaller but makes the backlog invisible and un-queryable |
What it buys
- An outage's recovery cannot become a second outage, and the limit is a published number rather than an operator's judgement
- The shedding order means degradation is a decision taken in advance, which is what lets an SRE predict what will happen under load
- A tenant with a failing endpoint pays for its own retries instead of consuming shared dispatch capacity
What it costs
- A one-hour backlog takes roughly ten hours to drain, which is a long time to tell a tenant their work is still coming
- The oldest-undispatched-due-age alert is loud for the whole drain, because the backlog is deliberately visible
- Three queues, three sets of capacity and three sets of saturation behaviour to operate and to reason about
Choose differently when. If every executor were elastic and owned by the platform, an unthrottled drain with autoscaling would recover faster at no external cost. With opaque tenant endpoints of unknown capacity, the conservative drain is the only responsible default.
Why it holds up over time. "Recovery slower than failure" is a control-theory statement about a system with a feedback loop into its own dependencies, and holds regardless of queue technology. The cap's value is the arguable part; the existence of a cap and of a published order is not.
Lesson. Size your recovery path for the capacity of whoever has to absorb it, not for the capacity of the system doing the recovering.
ADR-12 · Overlap is enforced against recorded outcome state, with unknown as a first-class terminal state bounded by a window
Status: Accepted · Shown on views: 11, 14, 17
The previous execution has not reported back. Is it still running?
Context. A trigger whose work sometimes takes longer than its interval will eventually be due again while the previous run is still going, and three behaviours are defensible: run anyway, skip, or queue one. Enforcing skip or queue requires the scheduler to know whether the previous execution has finished — which means depending on a signal it does not control, from an executor it does not own. When that signal never arrives, there are exactly two choices and both are bad. Treat the missing callback as finished and risk genuine concurrent execution; treat it as still running and withhold every subsequent fire indefinitely, which is a silent outage that looks like a working trigger with no fires.
Decision. Overlap policy is declared per trigger (allow, skip, queue) and enforced against recorded outcome state, bounded by the trigger's outcome window. A previous fire still in unknown state at the end of its window is treated as finished for overlap purposes, and that decision is recorded. unknown is a first-class terminal state, not an absence. A dispatch attempt that times out is recorded as unknown rather than failed, because the target may have accepted it. Under queue, at most one pending fire is held; a newer instant discards and records the older one.
How it is realised on AWS. work_outcome is a 1:0..1 child of the fire; the absent row is the unknown state. The timing plane's overlap check reads the previous fire's state and its age against the outcome window before claiming the next instant, and writes the resulting skip with a cause when it declines. The outcome window is a column on the trigger version.
| Option |
Verdict |
Reasoning |
| Outcome state with a bounded window, unknown treated as finished |
Chosen |
Bounds the silent-outage failure, which is the one a tenant cannot see; accepts occasional concurrent execution |
| Treat unknown as still running |
Rejected |
Never allows concurrency; a single lost callback stops a trigger forever and looks healthy while doing it |
| Delegate overlap entirely to the executor |
Rejected |
Architecturally cleanest — the scheduler stays stateless about executions; leaves every tenant to build the same lock |
| Hold a lease for the execution's duration |
Rejected |
Strongest mutual exclusion; makes the scheduler's lease lifetime depend on tenant work it cannot bound |
What it buys
- A lost callback costs at most one window of uncertainty rather than a permanently stopped trigger
- Every overlap decision is recorded with a cause, so a tenant sees "skipped: previous still running" instead of a gap
- A timed-out attempt is honestly recorded as unknown, which keeps the duplicate-tolerance contract (ADR-03) coherent
What it costs
- The scheduler is now stateful about executions it does not run, which is a dependency on a signal it cannot guarantee
- Under a systematically missing callback,
skip degrades towards allow, and the tenant may not notice the degradation
- The outcome window is another per-trigger value to choose badly
Choose differently when. If every executor reliably reported terminal state — a platform-owned runner, not a tenant endpoint — unknown would be rare enough that treating it as still running would be the safer default. With tenant HTTP targets it is not.
Why it holds up over time. The forced choice between risking concurrency and risking silence is structural: it exists whenever one system's decision depends on another system's unreliable report, and no technology removes it. What a future change could do is shrink the unknown population, which would make the window shorter without changing the rule.
Lesson. When a decision depends on a signal that may never arrive, name the missing signal as a state, bound how long you will wait for it, and write down which of the two bad outcomes you chose.
Scale, cost and recovery
Absorbing the top-of-hour peak, and treating the due index as something rebuilt rather than restored.
ADR-10 · The top-of-hour peak is absorbed by opt-out jitter smearing and the lateness budget, not by provisioned capacity
Status: Accepted · Shown on views: 02, 14, 16
Sixty per cent of all fires land in the first second of a minute. Do we buy capacity for that second?
Context. Scheduled work clusters on human-legible instants: the top of the minute, the top of the hour, midnight, midnight UTC, 09:00. At an assumed 5,800 fires a second mean, the design peak is around 45,000 a second for five seconds at the top of the hour — roughly 8× the mean minute. Provisioning the dispatch tier for that peak means paying for capacity that is idle 99.9% of the time; the alternative is to accept that a fire is a little late. The question is which fires genuinely care about their exact instant, and the honest answer is that most do not: a digest email at 09:00:03 is indistinguishable from one at 09:00:00, while a market-open task at 09:00:03 may be worthless.
Decision. Fires colliding on a popular instant are smeared within a declared jitter window, with per-trigger opt-out where the instant is externally significant. The peak is absorbed by the jitter window, a dispatch queue with a declared drain rate, and the published lateness budget — not by capacity provisioned for the peak second. The peak capacity avoided by smearing is reported, so the trade is visible rather than assumed.
How it is realised on AWS. The rate shaper applies a deterministic per-trigger offset within the window, so a given trigger's smear is stable rather than randomly different each hour — which matters because a tenant watching their own fires should see a consistent pattern. Opt-out is a flag on the trigger version. The avoided-peak figure is a BigQuery report alongside cost per million fires.
| Option |
Verdict |
Reasoning |
| Opt-out jitter smearing plus the lateness budget |
Chosen |
Removes the peak as a capacity problem; costs instant exactness for triggers that silently cared |
| Provision the dispatch tier for the peak |
Rejected |
Exact instants for everyone; pays for 8× capacity used five seconds an hour |
| Opt-in jitter |
Rejected |
Safest for correctness; almost nobody opts in, so the peak remains and the mechanism is dead weight |
| Queue at the peak with no smearing |
Rejected |
Half of the chosen option, and the one that makes the whole peak arrive as lateness on the unlucky triggers rather than spread across all of them |
What it buys
- Steady-state capacity is sized for the mean rather than the peak, which is the single largest cost lever in the design
- The smear is deterministic per trigger, so a tenant sees a stable pattern rather than jitter that looks like instability
- The avoided peak is reported, so the decision can be revisited with a number instead of an argument
What it costs
- Triggers whose instant mattered and that did not opt out are late by up to the window, and nobody finds out until it matters
- The opt-out is discoverable mainly by reading the per-trigger lateness distribution, which not every tenant will do
- "Scheduled for 09:00" is now a statement about a window, which has to be documented honestly
Choose differently when. If the service's tenants were predominantly financial — market opens, settlement windows, regulatory cut-offs — the exactness would be the product and provisioning for the peak would be the right answer. For a general developer platform it is not.
Why it holds up over time. The trade between buying peak capacity and spending a latency budget is permanent and technology-independent; only the prices move. If serverless dispatch capacity became genuinely instantaneous and free at the margin, provisioning for the peak would win, and the jitter window could be set to zero without touching anything else in the design.
Lesson. Before buying capacity for a peak, find out how many of the requests in that peak actually care about arriving in it.
ADR-11 · The due index is a rebuildable projection, verified continuously by a shadow rebuild rather than backed up
Status: Accepted · Shown on views: 07, 10, 15
The due index is corrupt. Do we restore it, or recompute it?
Context. The due index is the structure the scheduler scans, and it is derived entirely from the trigger registry: for each live trigger, the next instant its recurrence produces. Backing it up treats it as data; recomputing it treats it as a function. The second is obviously correct and is also the claim that quietly stops being true — a recompute path that is never exercised is a restore procedure with better marketing, and the first time it runs is during the incident that needed it. The same applies to partition reassignment: a takeover path exercised only during failures is a path nobody has confidence in at the moment they need it most.
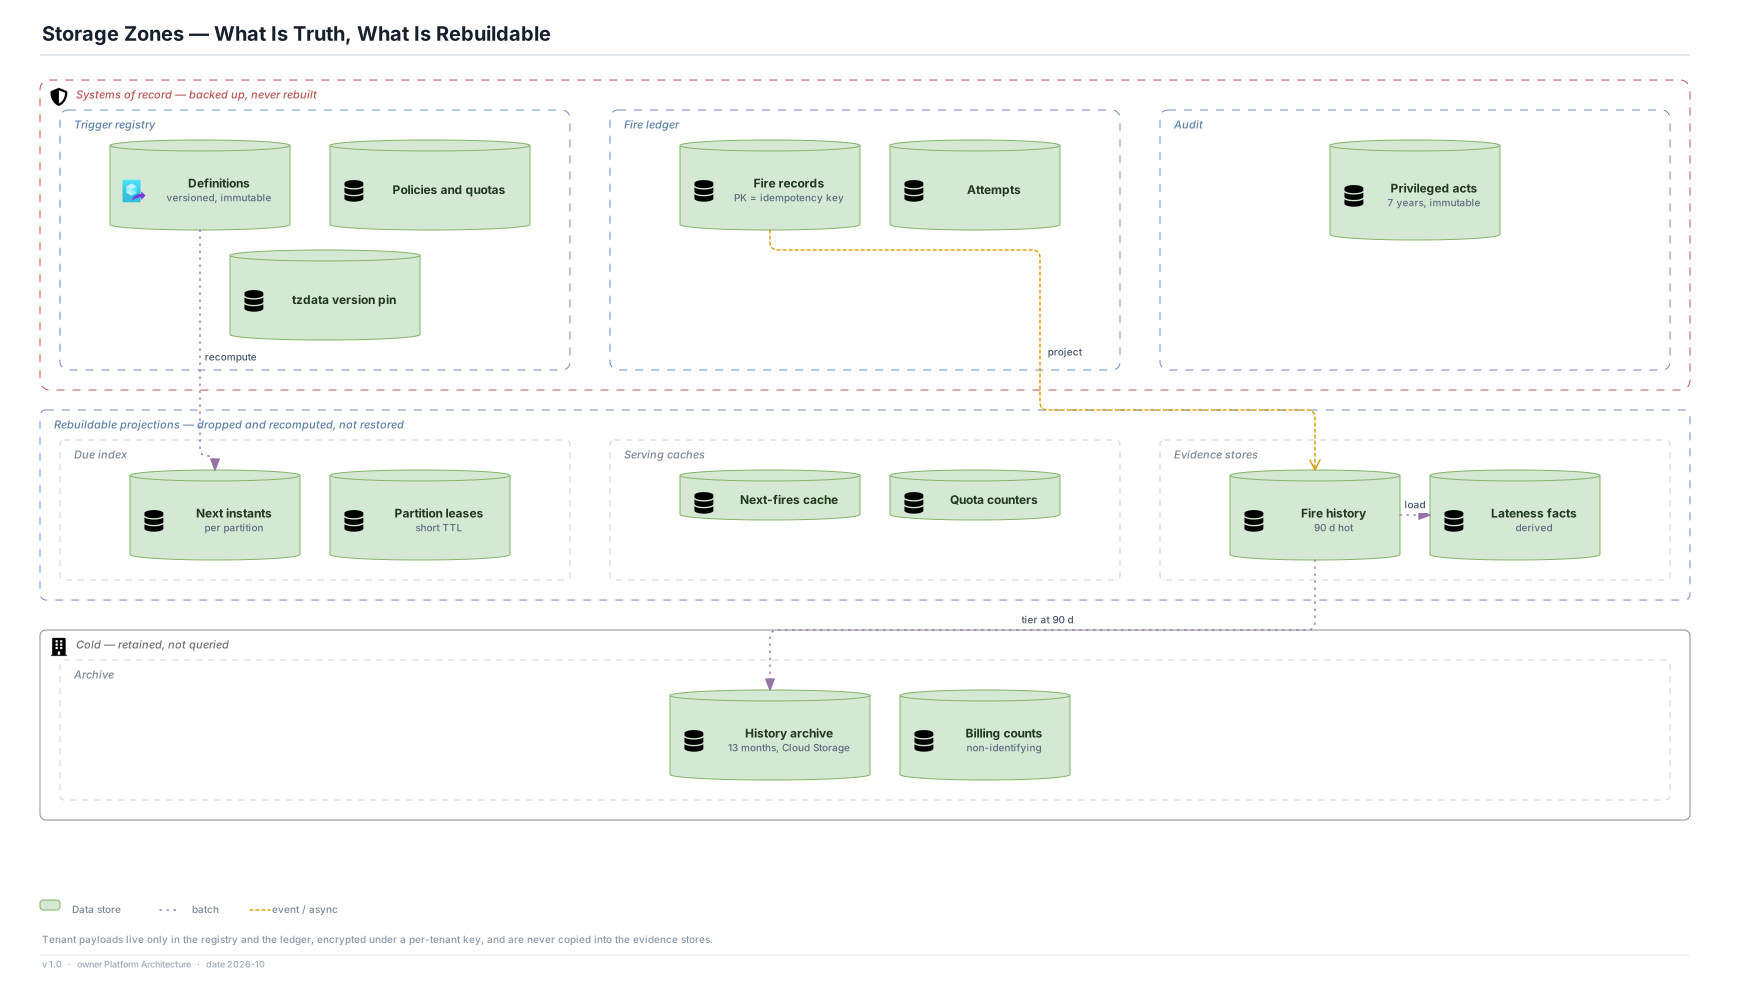
Decision. The due index, the partition leases and every cache are rebuildable projections of the registry and are not backed up. The rebuild is exercised continuously: a shadow rebuilder recomputes a partition's instants from the registry and compares them against the live index, and any divergence is treated as an incident. Partition ownership moves routinely in production rather than only during failure, so the takeover path is the common path.
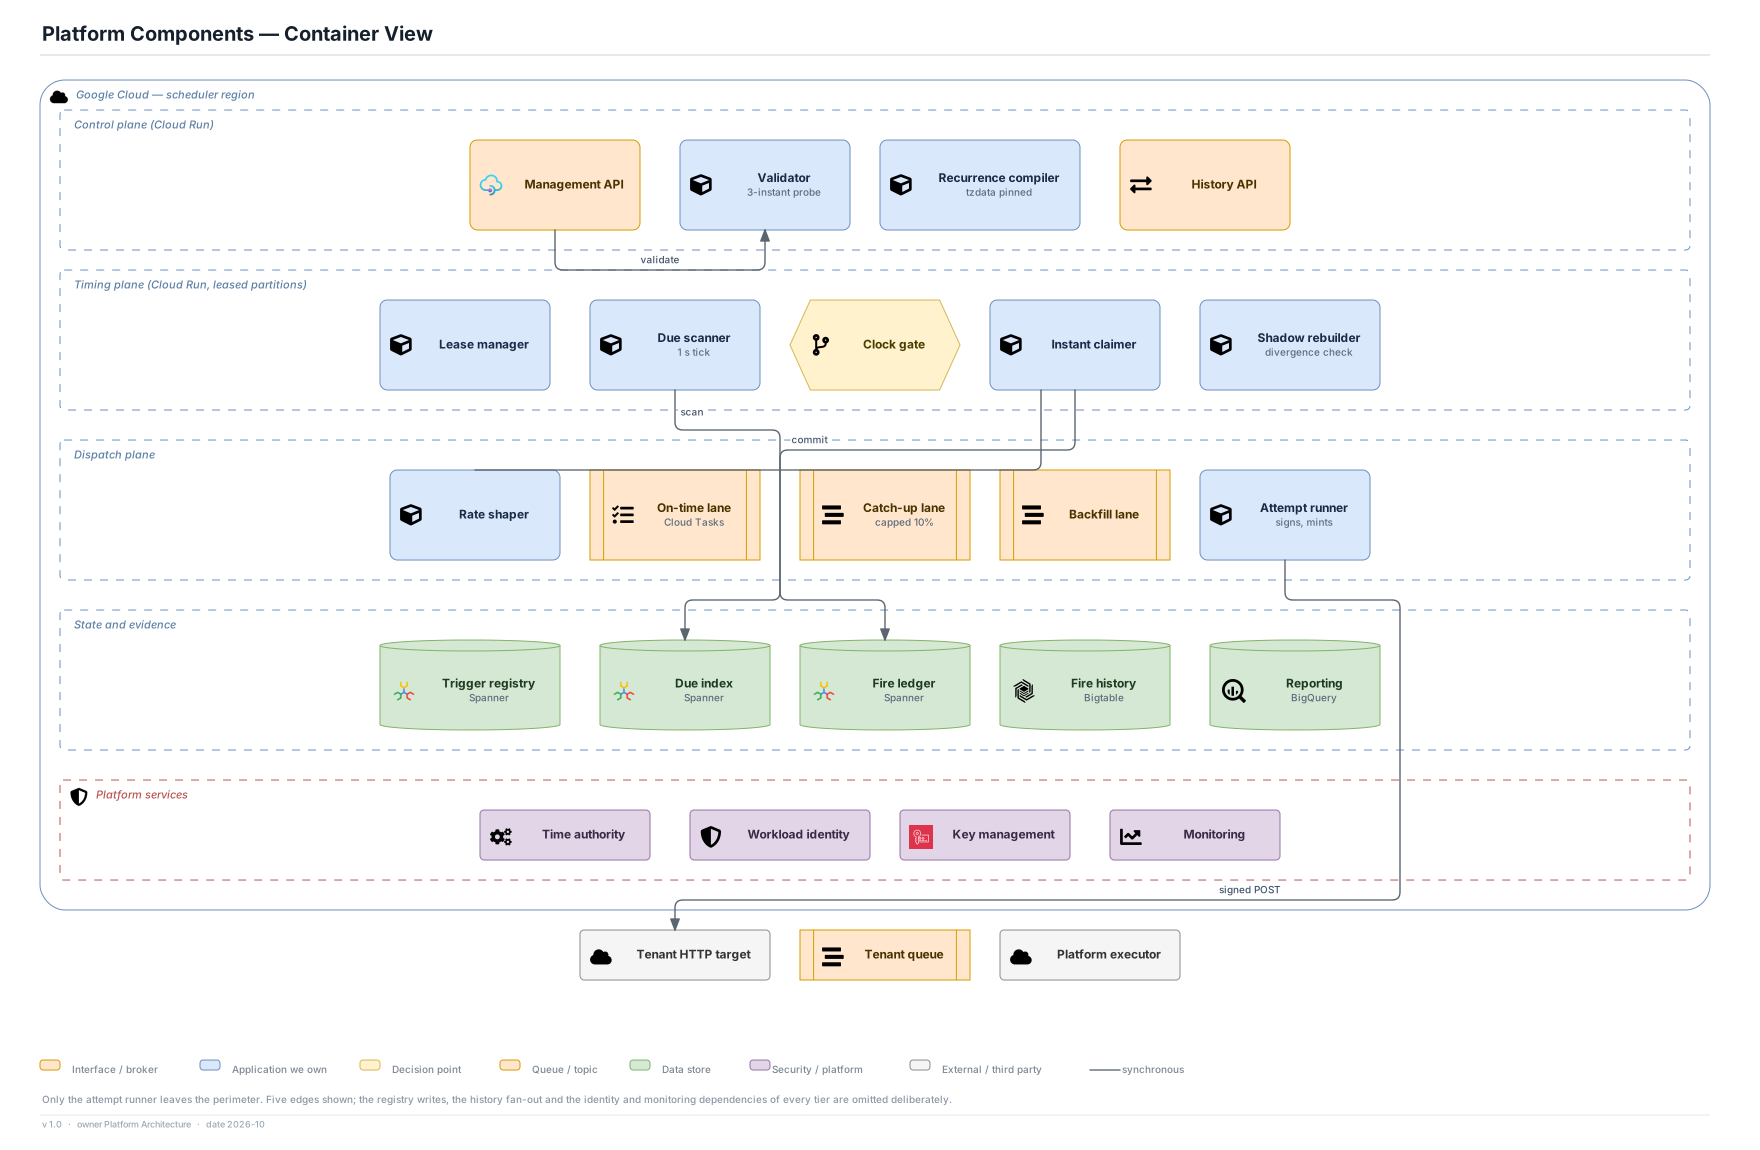
How it is realised on AWS. The shadow rebuilder is a component in the timing plane (view 07), not a script. It walks partitions on a rota, recomputes next instants with the same shared compiler the scan path uses, and reports divergence to BigQuery. Lease reassignment is driven on a schedule as well as by expiry, so the 15-second takeover budget is measured continuously rather than estimated. Only the registry, the ledger and the audit store are backed up.
| Option |
Verdict |
Reasoning |
| Rebuildable, verified by continuous shadow rebuild, routine reassignment |
Chosen |
Makes recoverability a measured property; costs a permanent component and the compute it consumes |
| Back up the due index |
Rejected |
Familiar and cheap to set up; restores a point in time, which for a derived structure is strictly worse than recomputing the current one |
| Rebuildable, with rebuild tested in a lower environment |
Rejected |
The common compromise; tests the code, not the production data, which is where the divergence will be |
| Rebuild on demand, no verification |
Rejected |
Correct in principle; the claim decays silently and is discovered false during an incident |
What it buys
- A corrupt or lost due index is a recompute rather than a recovery procedure, and the recompute has been running all along
- Takeover is the common path, so the 15-second reassignment budget is a measurement rather than a hope
- The backup surface is three stores instead of eight, which makes the backup story small enough to actually verify
What it costs
- A permanent component and its compute, spent entirely on verifying something that is supposed to be true
- Shadow divergence is reported rather than alerted in the MVP, so there is a window where the claim is unverified
- Routine reassignment means the fleet is always mid-handover somewhere, which makes duplicate-key rejections normal traffic rather than an anomaly
Choose differently when. If the due index were expensive to recompute — materialised instants for 20 million triggers weeks ahead, as ADR-05 rejected — rebuild would stop being cheaper than restore and the decision would invert. The two decisions are linked: recomputation is affordable because the index holds one row per trigger.
Why it holds up over time. "Derived data is rebuilt, not restored" is a property of the data's relationship to its source and survives any storage technology. The part that needs continued investment is the verification, because the claim is the kind that decays. If the shadow rebuilder is ever switched off for cost, the decision has quietly become the rejected fourth option.
Lesson. A recovery path you do not run is a recovery path you do not have. If something is rebuildable, rebuild it on a schedule and compare.
Evidence and trust
What the tenant can see, what a schedule is allowed to point at, and who is allowed to multiply work.
ADR-13 · Fire history is a tenant-facing product surface, and the platform alert is oldest undispatched due age
Status: Accepted · Shown on views: 05, 16, 17
How does anyone find out that the scheduler has stopped firing?
Context. A scheduler's characteristic failure is unique among services: it is up, serving its API, passing its health checks, consuming no unusual resources, and not firing. Every dashboard says healthy. CPU, memory, error rate, request latency and queue depth are all normal, because the absence of work produces no signal. The same blindness applies to the tenant: a job that did not run generates nothing — no error, no log line, no alert — so the first notification is usually a customer. Both problems are the same problem viewed from two sides, and both are solved by measuring the gap between what should have happened and what did.
Decision. The platform's paging alert is oldest undispatched due instant age per partition, not process health. Fire history is a tenant-facing product surface recording, per fire: scheduled, decided and dispatched instants, attempt outcomes, terminal state, the cause of any non-dispatch, the definition version and the tzdata version — with each trigger's recent lateness distribution published so a tenant sees punctuality degrade before it becomes an incident.
How it is realised on AWS. Fire history is a Bigtable projection of the ledger keyed by tenant#trigger#instant with a 90-day TTL and a 13-month Cloud Storage archive. Oldest undispatched due age is computed per partition from the due index and alerts above an assumed 60 seconds. The History API is a separate service from the Management API (view 08) so a history query never competes with authoring, and the per-trigger lateness view is derived in BigQuery.
| Option |
Verdict |
Reasoning |
| Due-age alerting plus tenant-facing per-fire history and lateness |
Chosen |
Catches the invisible failure from both sides; costs a projection, an archive and a product surface |
| Health and resource alerting |
Rejected |
Standard and cheap; blind to the one failure that matters most here |
| Alert on fire rate dropping below a baseline |
Rejected |
Useful as a secondary signal; a legitimate quiet period and a stalled scheduler look identical |
| Platform-internal history only, support answers tenant questions |
Rejected |
Less to build; makes every "did it run" a support ticket and leaves the tenant's on-call blind (view 05) |
What it buys
- A stalled scheduler pages within a minute rather than being discovered by a tenant's customer
- "Did my job run last night" is answerable by the tenant, with a cause, which is what makes view 05's journey recoverable
- Three separately recorded instants per fire turn ambiguous complaints into specific ones
What it costs
- The due-age alert is loud for the whole of a legitimate catch-up drain, which is the price of a visible backlog (ADR-09)
- 500 million fires a day of history is a storage and query cost that is pure evidence and produces no fires
- A per-fire record for work the platform did not run invites tenants to read "dispatched" as "succeeded"
Choose differently when. If the scheduler only served platform-internal callers with their own observability, the tenant-facing surface would be unnecessary and the alert alone would do. The product surface is justified by tenants who have no other way to see the gap.
Why it holds up over time. "Alert on the gap between intended and actual, not on the health of the thing in between" is a general principle for any system whose failure mode is silence, and it outlasts any monitoring stack. The specific alert threshold should move with measured data.
Lesson. For any system whose failure produces no output, make the alert the distance between what should have happened and what did. Health checks cannot see absence.
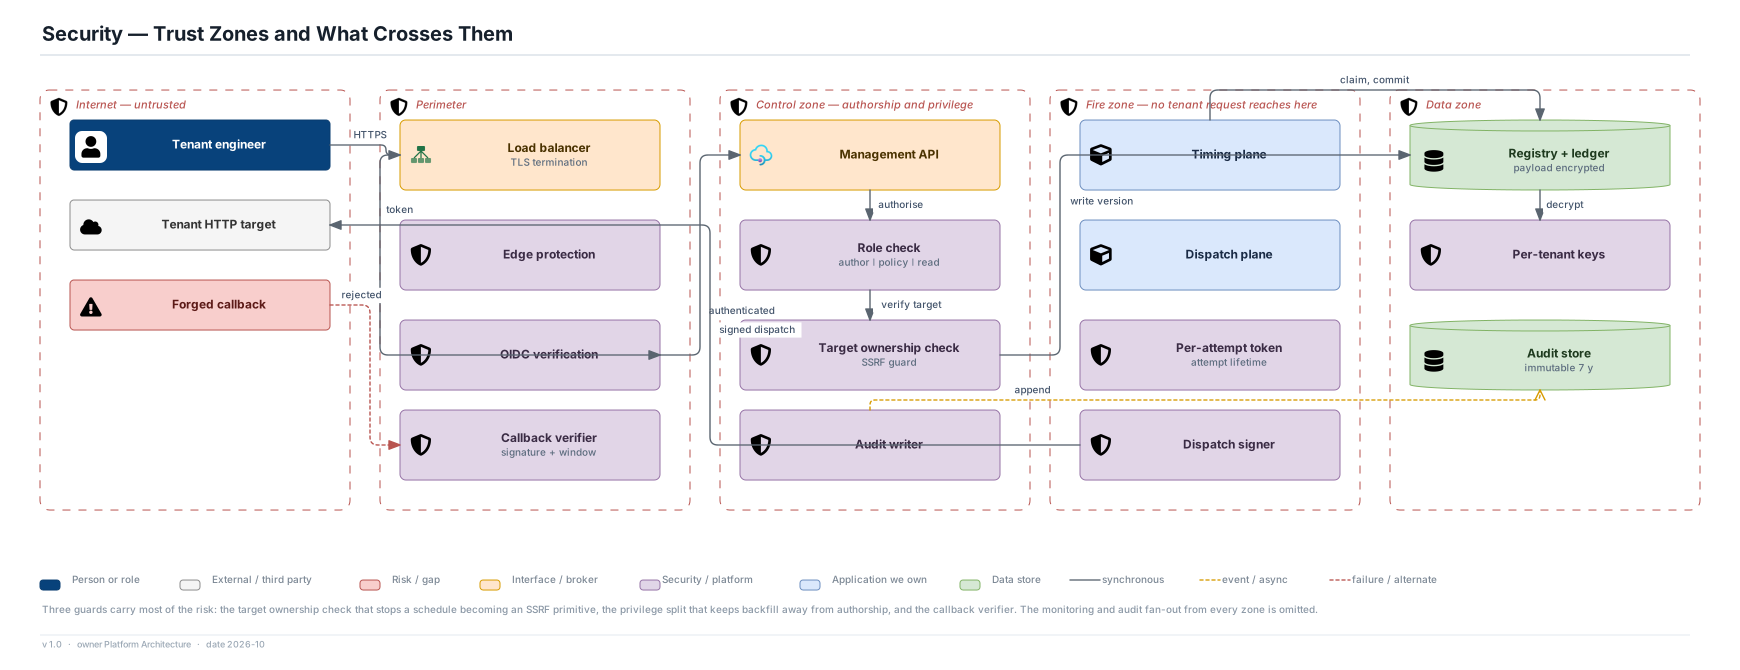
ADR-14 · A target must be verifiably owned by its tenant, no tenant request reaches the fire zone, and dispatch credentials are minted per attempt
Status: Accepted · Shown on views: 08, 18, 19
What stops a schedule from being a timer-driven request forgery primitive aimed at someone else?
Context. A scheduler that will make an authenticated HTTP request to any URL a tenant names, repeatedly, on a timer, with a retry budget, is a remarkably convenient attack tool. It has outbound network access, it is inside the platform's perimeter, it holds credentials, and it is designed to keep trying. The same properties make the dispatch credential valuable: a long-lived platform identity captured from a dispatch grants the holder whatever that identity can do, for as long as it lives. Both problems come from treating the dispatch target as data rather than as a privilege.
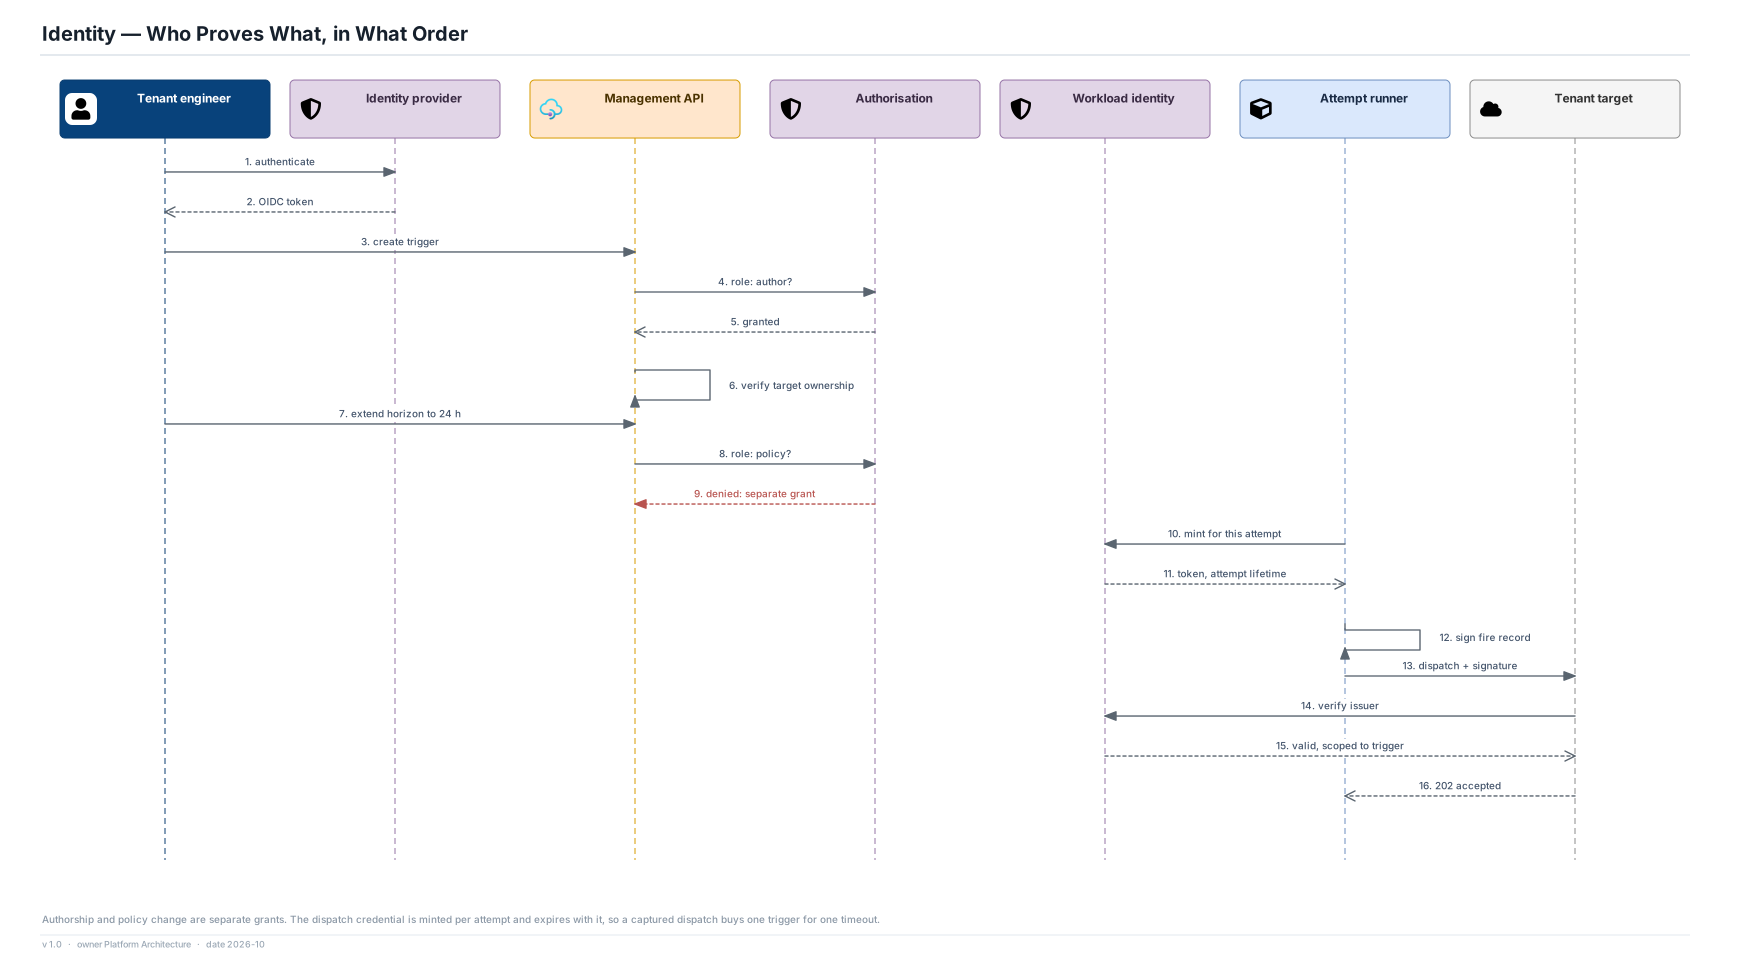
Decision. A target must be a registered endpoint on a domain the tenant has verified, or a queue the tenant owns, checked at definition time and again at dispatch time. No tenant request reaches the timing or dispatch planes: both are reachable only from inside the perimeter, and the only component with egress is the attempt runner. Dispatch credentials are minted per attempt with a lifetime no longer than the attempt timeout, and every dispatch is signed with a timestamped, replay-resistant signature over the fire record and payload. Inbound outcome callbacks are verified by the same signature within a short window.
How it is realised on AWS. Target verification is a separate target entity with its own verification state (view 11), referenced by the trigger version rather than embedded as a URL. The attempt runner mints a workload-identity token scoped to the trigger for each attempt, so a captured dispatch buys one trigger for one timeout. The callback verifier sits at the perimeter (view 18) and rejects a stale signature rather than logging it.
| Option |
Verdict |
Reasoning |
| Verified target entity, perimeter isolation, per-attempt credentials, signed both ways |
Chosen |
Closes the forgery path and bounds credential capture; costs tenants a domain verification step |
| Allow any HTTPS URL with an allowlist of blocked ranges |
Rejected |
Lowest friction; a denylist of internal ranges is a game the defender loses eventually |
| Long-lived per-tenant dispatch credential |
Rejected |
Simpler to operate and to debug; a captured credential is a standing grant |
| Egress through a tenant-supplied proxy |
Rejected |
Pushes the problem to the tenant and is right for some enterprises; too much setup for a general platform |
What it buys
- A schedule cannot be pointed at a host the tenant does not demonstrably control, so the service is not an amplifier
- A captured dispatch credential expires with the attempt, which reduces a standing grant to a seconds-long one
- One component has egress, so the egress policy is small enough to audit
What it costs
- Domain verification is friction at exactly the moment a developer wants to ship (view 04)
- Verification is point-in-time: a target legitimately owned at definition and later reassigned is a residual risk mitigated only by re-checking at dispatch
- Per-attempt minting adds a call to the dispatch path at 45,000/s peak, which has to be cached carefully without defeating the point
Choose differently when. If the scheduler only dispatched to queues and executors inside the platform, target verification would be unnecessary and the perimeter would do the whole job. The tenant HTTP target is what makes this decision load-bearing.
Why it holds up over time. "A dispatch target is a privilege, not a parameter" survives any identity technology, and per-attempt credentials get cheaper as token minting does. What may change is the verification mechanism — domain verification is a convention, not a law — but the requirement that ownership be proved does not.
Lesson. Any feature that lets a user name an outbound destination is a request-forgery feature until ownership of that destination is proved. Treat the destination as a privilege with a lifecycle.
ADR-15 · Backfill, horizon extension and quota change are grants separate from trigger authorship
Status: Accepted · Shown on views: 08, 18, 19
Should the person who can create a schedule also be able to make it emit a month of work?
Context. Most operations on a scheduler are small: create a trigger, amend it, pause it, read its history. Three are not. Backfill generates fires for a declared past window. Extending the catch-up horizon turns a bounded recovery into a larger one. Raising a quota lifts the cap on dispatch rate and in-flight concurrency. Each of them multiplies real work — mail sent, money moved, endpoints called — and each of them is most attractive at the moment judgement is worst, which is during or just after an incident. Bundling them with authorship means the blast radius of a routine role is the blast radius of the largest operation in the system.
Decision. Trigger authorship, policy change (catch-up horizon, overlap window, quota) and read-only history access are three separately grantable roles, and backfill is its own privileged operation with its own API surface. Every privileged act is written to an append-only, tamper-evident audit record with actor and prior value. An author who can create a trigger cannot widen its blast radius.
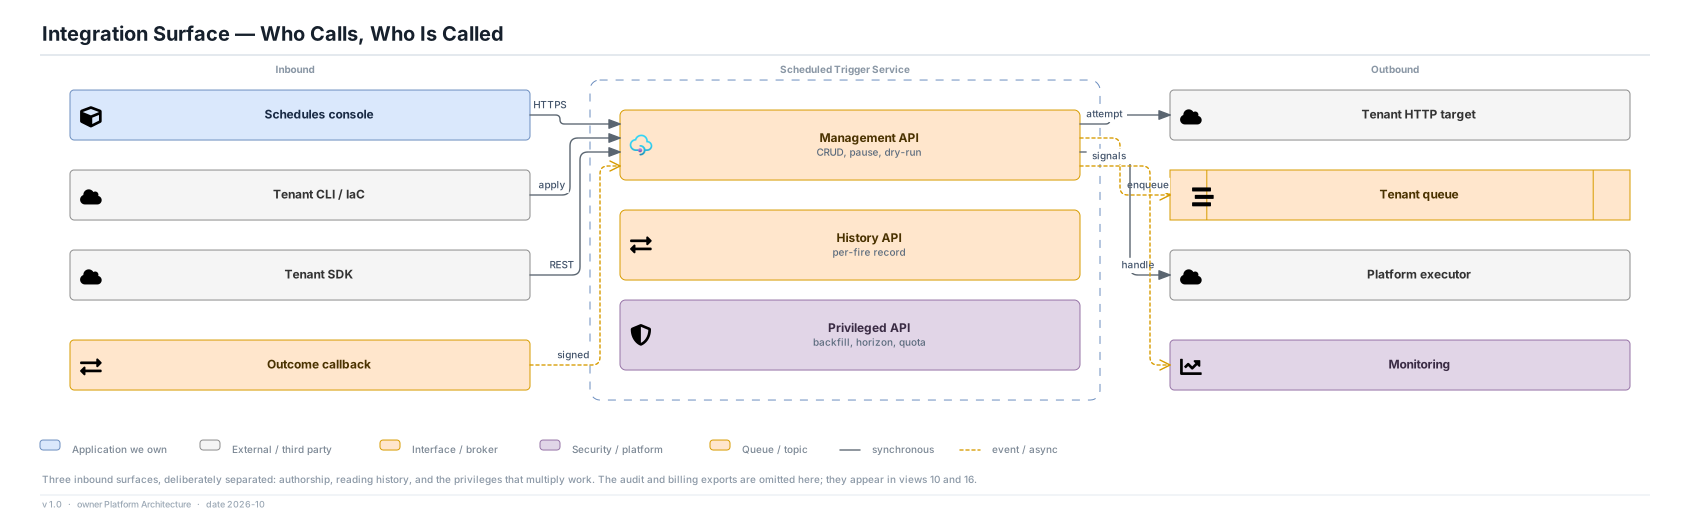
How it is realised on AWS. Three inbound APIs (view 08) rather than one, so the authorisation story is visible in the surface rather than buried in a handler. View 19 draws the horizon extension being denied to an author, because the split is only real if the refusal happens. Backfill is additionally rate-capped in its own dispatch lane (ADR-09) and bounded by a declared maximum volume per operation.
| Option |
Verdict |
Reasoning |
| Separate grants for authorship, policy and privilege, with audit |
Chosen |
Bounds the routine role to routine damage; costs an approval step during incidents |
| One role for everything a tenant can do |
Rejected |
Simplest to grant and to explain; makes every trigger author able to emit a month of billing runs |
| Approval workflow for every change |
Rejected |
Safest; makes ordinary authoring slow enough that tenants route around the platform |
| Rate limits instead of privileges |
Rejected |
Bounds the volume but not the intent, and a limit high enough to be useful is high enough to hurt |
What it buys
- The routine role's worst case is a badly scheduled trigger, not a month of duplicated work
- An audit trail with prior values makes a bad backfill explainable and attributable afterwards
- The separation is visible in the API surface, so a security reviewer can check it without reading handler code
What it costs
- Recovery needs an approver, which adds minutes to the moment a tenant most wants to act (view 05)
- A tenant that grants the policy role to everyone with the author role recreates the problem; audit detects it and nothing prevents it
- Three roles and one privileged surface is more to document and more to get wrong in a tenant's own access model
Choose differently when. If backfill were cheap and harmless — regenerating a derived view, say — the separation would be needless ceremony. It is justified by backfill emitting the same work as a real fire, indistinguishable at the executor.
Why it holds up over time. Separating the privilege to do a thing from the privilege to multiply it is a general access-control principle and does not depend on this identity provider. The specific split of three roles may be refined; the principle that recovery operations are privileged should not be.
Lesson. Find the operations in your system that multiply work rather than performing it, and make each one a separate grant. They are the ones that will be used under pressure.
ADR-16 · Tenant payloads live only in the registry and the ledger, encrypted under a per-tenant key, and never in evidence or logs
Status: Accepted · Shown on views: 10, 11, 18
The scheduler carries an opaque blob it never interprets. Where is that blob allowed to exist?
Context. The tenant payload is the one piece of data in the system the platform cannot reason about. It is opaque by design — the scheduler does not interpret it — which also means the platform cannot know whether it contains a customer identifier, an account number, a webhook secret or a medical record. Every piece of machinery the service has wants to copy it: a dispatch log for debugging, a fire history row for the tenant's own view, an error message when a dispatch fails, a metric label for cardinality analysis, a reporting table for cost attribution. Each copy is a place that now carries unknown sensitive data under a different retention and a different access policy.
Decision. A tenant payload exists in exactly two places — the trigger registry and the fire ledger — encrypted at rest under a per-tenant key, and is never written to fire history, reporting, metrics, traces or logs. It is passed to the executor and nowhere else. On tenancy termination, definitions, payloads and history are deleted within 30 days while non-identifying fire counts are retained for billing.
How it is realised on AWS. The payload is stored by reference (payload_ref) on the trigger version and resolved only in the dispatch path, where the attempt runner decrypts it under the tenant's key immediately before signing and sending. History rows (view 10) carry the fire key, timestamps, states and causes, and never the payload. Error messages carry the fire key, so a debugging path starts from an identifier rather than from content.
| Option |
Verdict |
Reasoning |
| Two stores, per-tenant key, never in evidence |
Chosen |
Keeps the unknown-sensitivity blob inside one small boundary; makes debugging start from a key rather than from content |
| Payload in history for tenant convenience |
Rejected |
Genuinely useful for a tenant diagnosing a bad fire; puts unknown sensitive data under a 90-day analytics retention |
| One platform key for all payloads |
Rejected |
Much simpler key management; removes crypto-shredding as a deletion mechanism and makes one key the whole estate's boundary |
| Reject payloads entirely; tenants fetch their own parameters |
Rejected |
Cleanest privacy position; makes every trigger need a config lookup the tenant must build |
What it buys
- The sensitive-data surface is two stores with one retention story, which is small enough to actually review
- A per-tenant key makes deletion enforceable by key destruction rather than by trusting every copy to be found
- Debugging conventions start from the fire key, which is a habit that keeps content out of logs by default
What it costs
- A tenant cannot see the payload a fire carried, which makes some diagnosis harder than it needs to be
- A decrypt per attempt on the dispatch path at peak, which is a real cost and a dependency on the key service
- Per-tenant keys at 50,000 tenants is key lifecycle work the platform now owns
Choose differently when. If payloads were constrained to a declared schema the platform validated — identifiers only, no free text — the sensitivity would be known and history could safely carry them. Opacity is what forces the strict boundary.
Why it holds up over time. "Data whose sensitivity you cannot assess gets the strictest boundary you have" is a principle rather than a mechanism, and survives any change of key management. The arguable part is the opacity itself: a future schema-validated payload would legitimately reopen the decision.
Lesson. If your system carries data it does not interpret, it also cannot classify it — so give it the handling you would give the most sensitive thing it could be.
Every package used, in one table
These terms are used precisely in this package. Several are used loosely in the wider literature on schedulers and cron services, and the difference matters when reading the decision records.
| Package |
What it is |
What it does here |
Considered instead |
| Scheduled instant |
The absolute UTC instant a recurrence resolves to, derived from the expression, the named zone and a recorded time-zone database version. |
The thing the fire is identified by, ordered by, and measured against. |
"Fire time", which is usually used for the moment a dispatch actually left — the quantity this package calls the dispatch instant. |
| Fire record |
An immutable row committed before any dispatch attempt, carrying the tenant, trigger, definition version, scheduled instant and a deterministic key. |
The scheduler's durable product and the system of record for "was this instant decided". |
A "job run", which implies work happened; a fire record says only that a decision was taken. |
| Idempotency key |
The fire's four-part primary key (tenant, trigger, scheduled instant, sequence), computed rather than generated. |
Makes a duplicate decision a uniqueness violation instead of something to detect, and gives the executor something to deduplicate on. |
A generated request identifier, which deduplicates transport retries but cannot deduplicate two independent decisions. |
| ε (clock uncertainty) |
The half-width of the interval a bounded time source reports around the current instant. |
The quantity the scheduler waits out, which is what converts clock skew into lateness rather than earliness. |
"Clock skew", which usually names the error itself rather than a reported bound on it. |
| Lateness |
Dispatch instant minus scheduled instant, measured per fire and published per trigger as a distribution. |
The budget the design spends; it is the measure of availability for the dispatch plane. |
"Latency", which in a request-shaped service means time to respond rather than distance from a deadline. |
| Missed-fire policy |
A per-trigger declaration — fire-all, fire-once-now or skip — of what to do with instants that should have fired and did not. |
Moves the post-outage decision from the incident to the definition. |
"Misfire instruction" in some scheduler libraries, usually with the same three options and no horizon. |
| Catch-up horizon |
The maximum age of a missed instant that may still be dispatched; beyond it the instant is recorded as expired. |
The platform's bound on how much work any interruption can accumulate, overriding the tenant's policy. |
A "grace period", which usually means how long a late fire is still considered on time. |
| Catch-up storm |
A backlog of missed instants released at once by a recovery, a resume or a backfill. |
The expected failure mode of a scheduler, and the thing the lane split and the rate cap exist for. |
A "thundering herd", which names simultaneous arrival generally rather than the self-inflicted recovery case. |
| Overlap policy |
A per-trigger declaration — allow, skip or queue — of what to do when a fire comes due while the previous execution has not reported terminal. |
The only control the scheduler has over concurrency in work it does not run. |
"Concurrency policy", which in some systems bounds parallel runs numerically rather than deciding what to do about one. |
| Unknown (terminal state) |
The recorded state of a fire whose outcome never arrived inside its outcome window, including a dispatch attempt that timed out. |
Prevents the scheduler withholding every later fire on a missing callback, at the price of occasional concurrent execution. |
"Failed", which asserts the work did not happen — a claim the platform cannot make about a timeout. |
| Backfill |
An authorised generation of fires for a declared past window, labelled as such and rate-capped in its own lane. |
The recovery path for work lost beyond the horizon, and a privilege separate from authorship. |
A "replay", which in event systems means re-delivering records that already exist rather than creating new ones. |
| Partition lease |
A short-TTL claim on a range of the trigger keyspace, recording the ε observed at grant. |
The unit of mutual exclusion in the timing plane — deliberately imperfect, because the fire key makes imperfection survivable. |
"Leader election", which implies one authority per service rather than one per partition. |
| Due index |
One row per live trigger holding its single next instant, partitioned and scanned in time order. |
The structure the scheduler reads; a rebuildable projection of the registry, not a system of record. |
A "timer wheel", which is an in-memory structure with the same purpose and no durability. |
| Oldest undispatched due age |
The age of the oldest instant that is due and has not yet been dispatched, measured per partition. |
The paging alert, because it is the only signal that distinguishes a healthy scheduler from a silent one. |
"Queue depth", which counts work waiting without saying how long the oldest item has been waiting. |