Spot Capacity Orchestrator · View 29 of 32 · 6 · Operations
Proof first
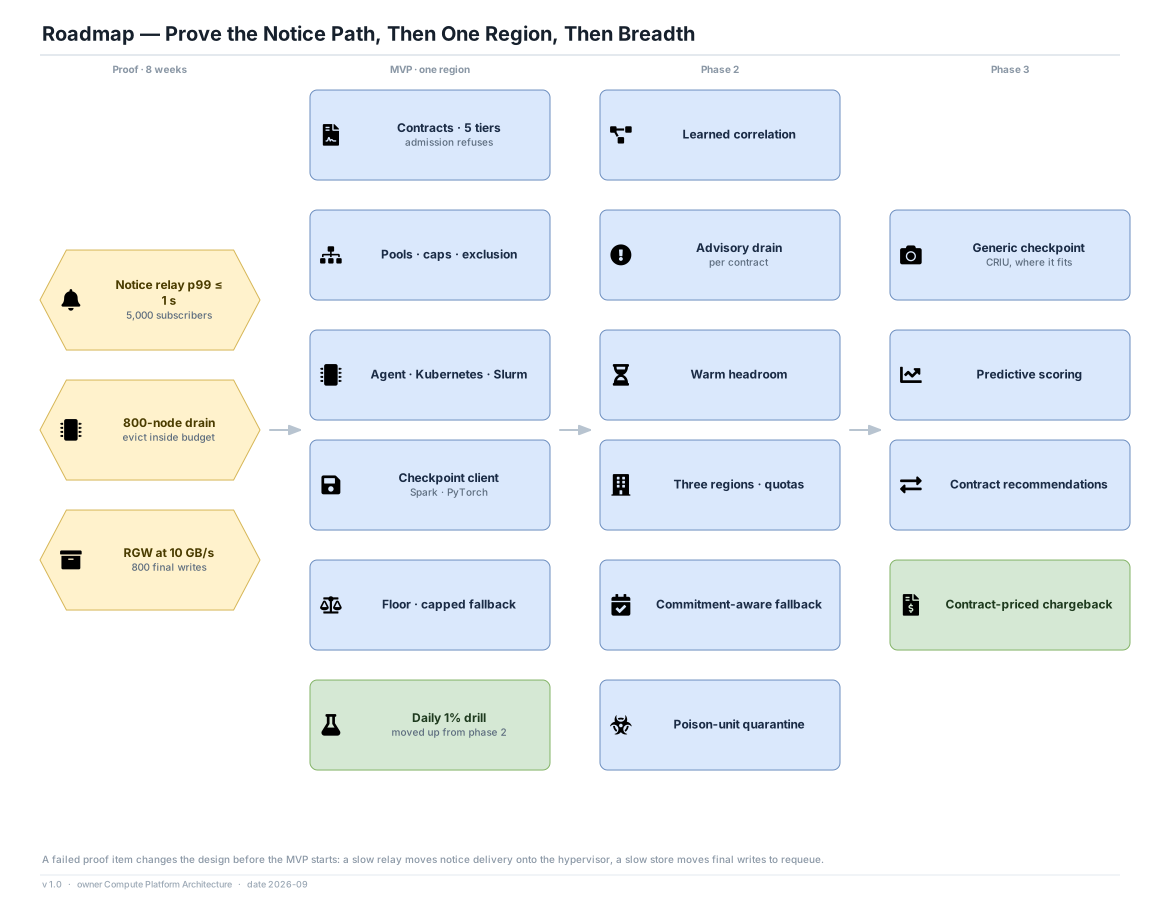
- Notice delivery at 5,000 subscribers inside 1 s, an 800-node drain inside the budget on real Kubernetes and Slurm clusters, and 10 GB/s of final checkpoints into RGW. Each of them is a physical limit the architecture depends on, not a feature.
Departures from the requirement
- The daily reclamation drill moves from Phase 2 into the MVP. It uses the provider's own reclaim API and costs about 1% of reclaimable node-hours in extra churn, and it is the only way to show fail-static and drain behaviour are still true on an ordinary Tuesday.
- Everything else follows the requirement's phasing.
What a failed proof changes
- A relay too slow at fleet scale moves notice delivery to a per-hypervisor channel. A checkpoint store that cannot absorb the burst changes tier-1 contracts from final-write to more frequent periodic checkpoints and requeue.