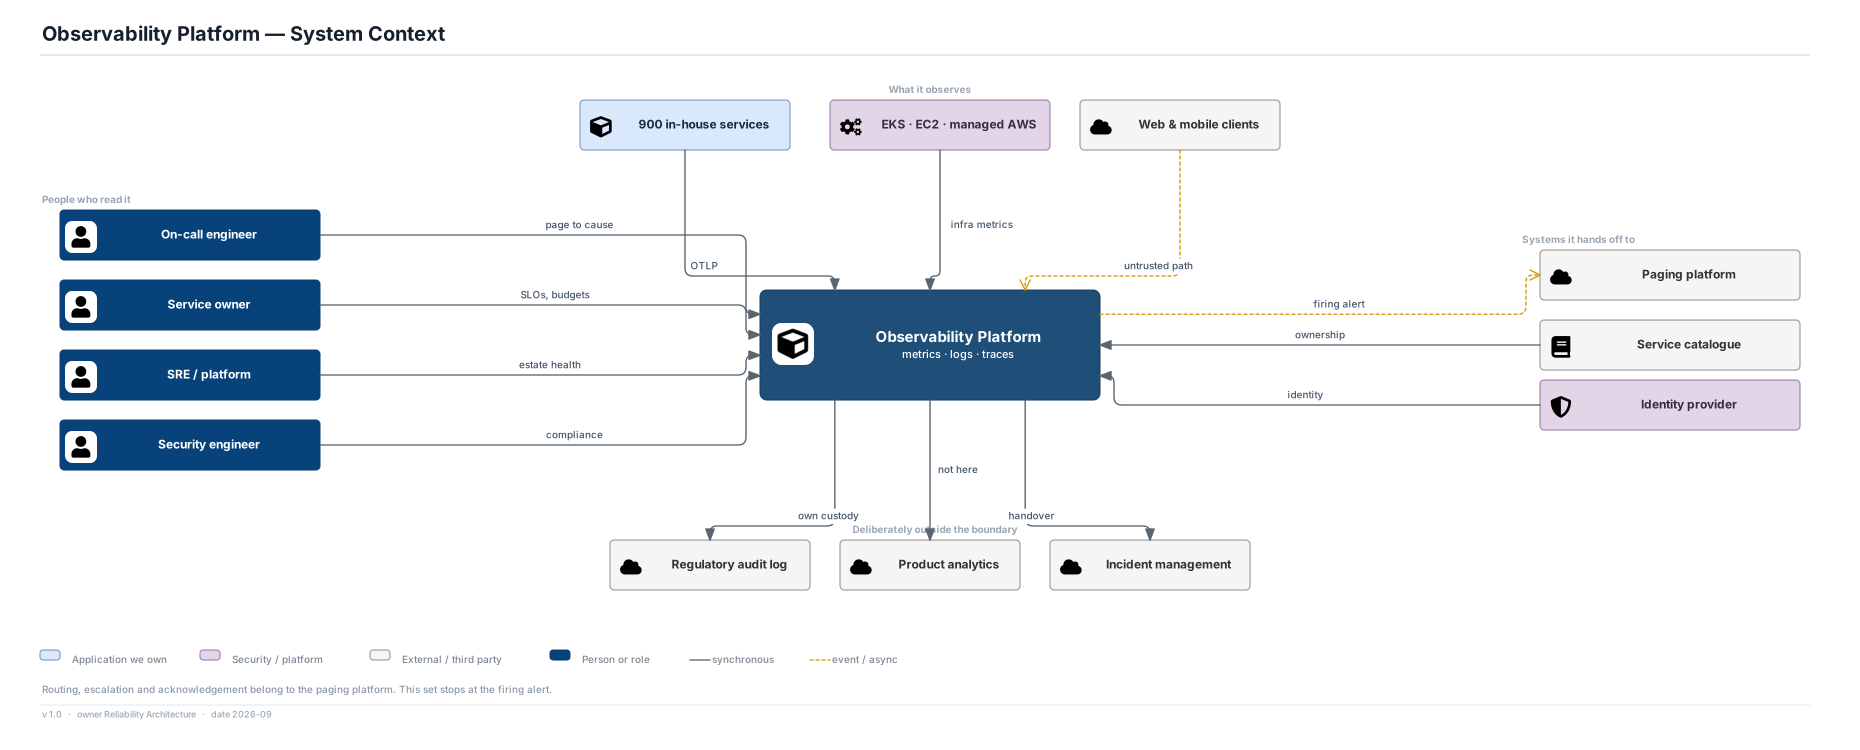
Observability Platform · View 01 of 25 · Context and scope
Decisions
- The platform stops at the firing alert. Routing, escalation, on-call schedules and acknowledgement belong to the paging platform, which is a separate product with a separate availability argument.
- Product analytics and the regulatory audit log are named as out of scope on the diagram rather than left unmentioned, because both get pushed into an observability platform by default and both make an operational store expensive and slow.
- Untrusted client telemetry (web and mobile) enters through its own path and is drawn as an external producer, not as another service.
Assumptions
- 900 in-house services, 12,000 hosts, 40,000 containers, three AWS regions, 70 owning teams, ~450 engineers.
- A service catalogue already exists and is authoritative for ownership. Without it, the tenancy model in view 08 has no source of truth and the platform gains a manual onboarding step it cannot scale.
Risks
- The platform runs on the estate it observes. That circular dependency is answered in views 19 and 21 and nowhere else; if the self-telemetry account is descoped for cost, the platform can be blind and report itself healthy.
- Four reader groups with genuinely different questions is the usual way an observability console becomes unusable for all of them.