Cost Allocation & Showback Platform · Solution Architecture v1.0 · Microsoft Azure · Cost & Efficiency Architecture · 2026-09
The argument these decisions serve is summarised in the Architecture One-Pager.
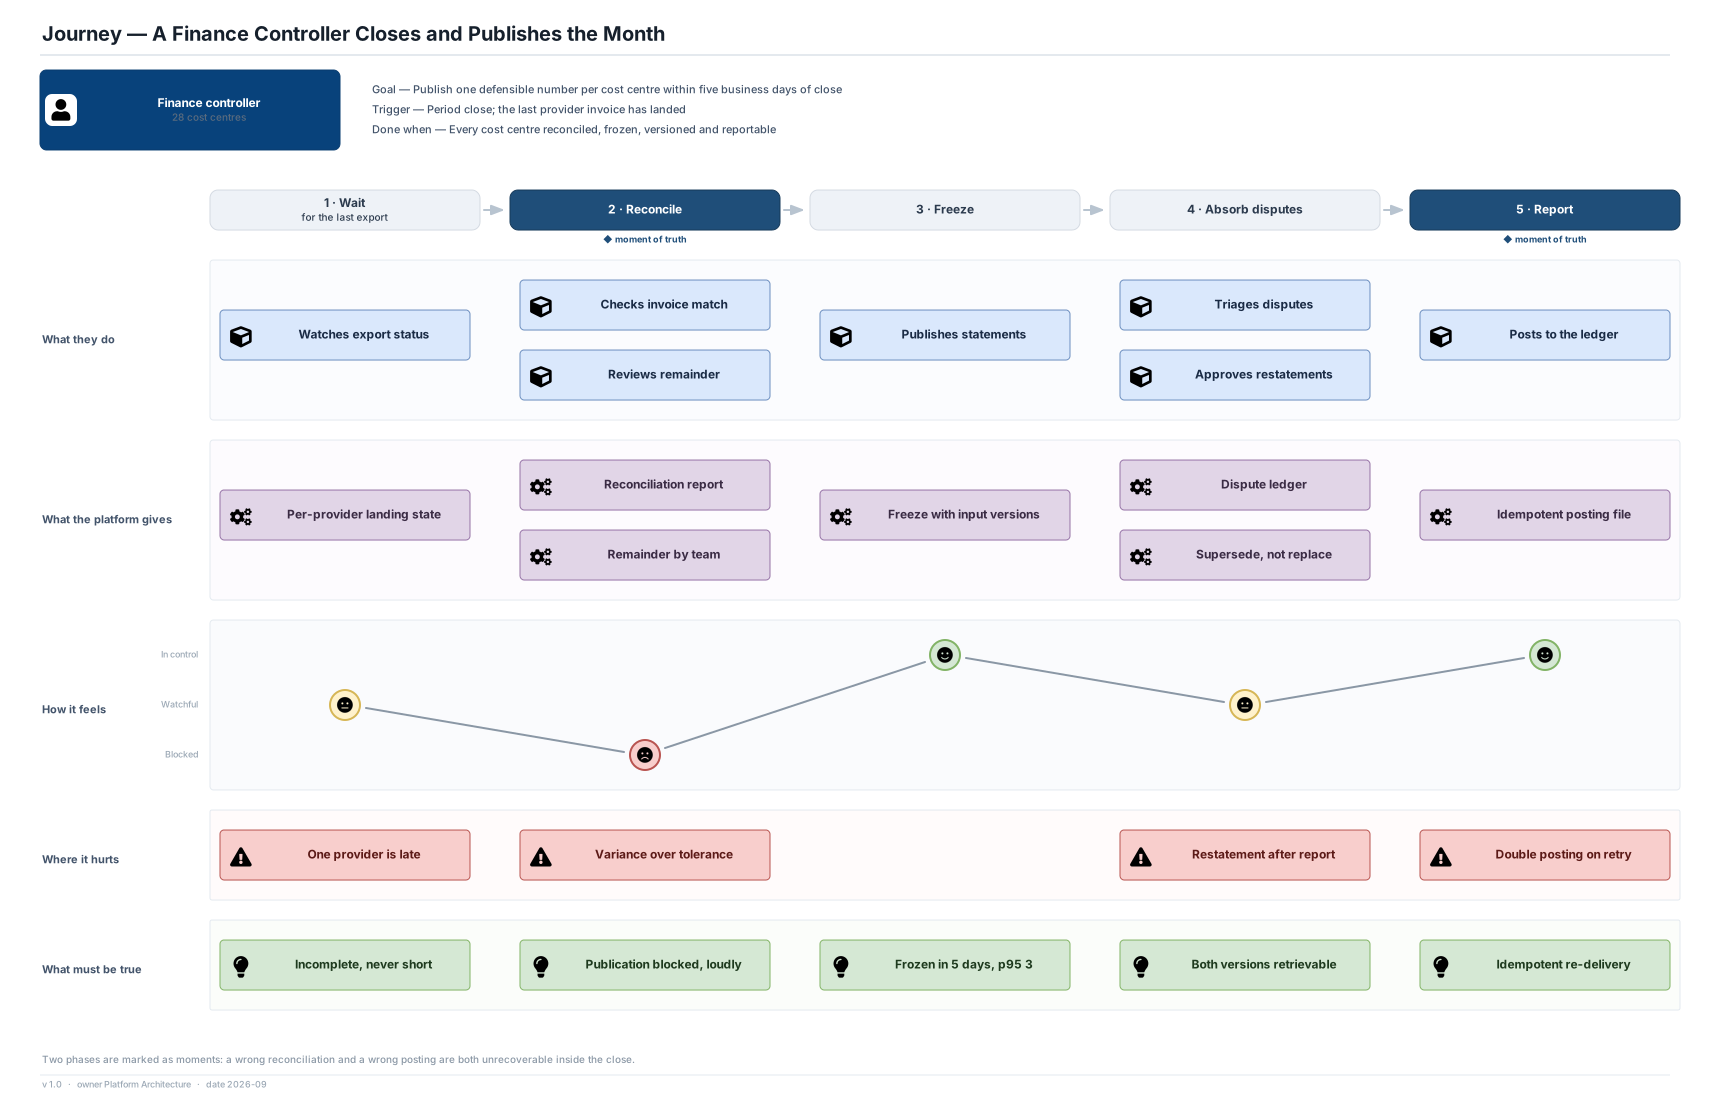
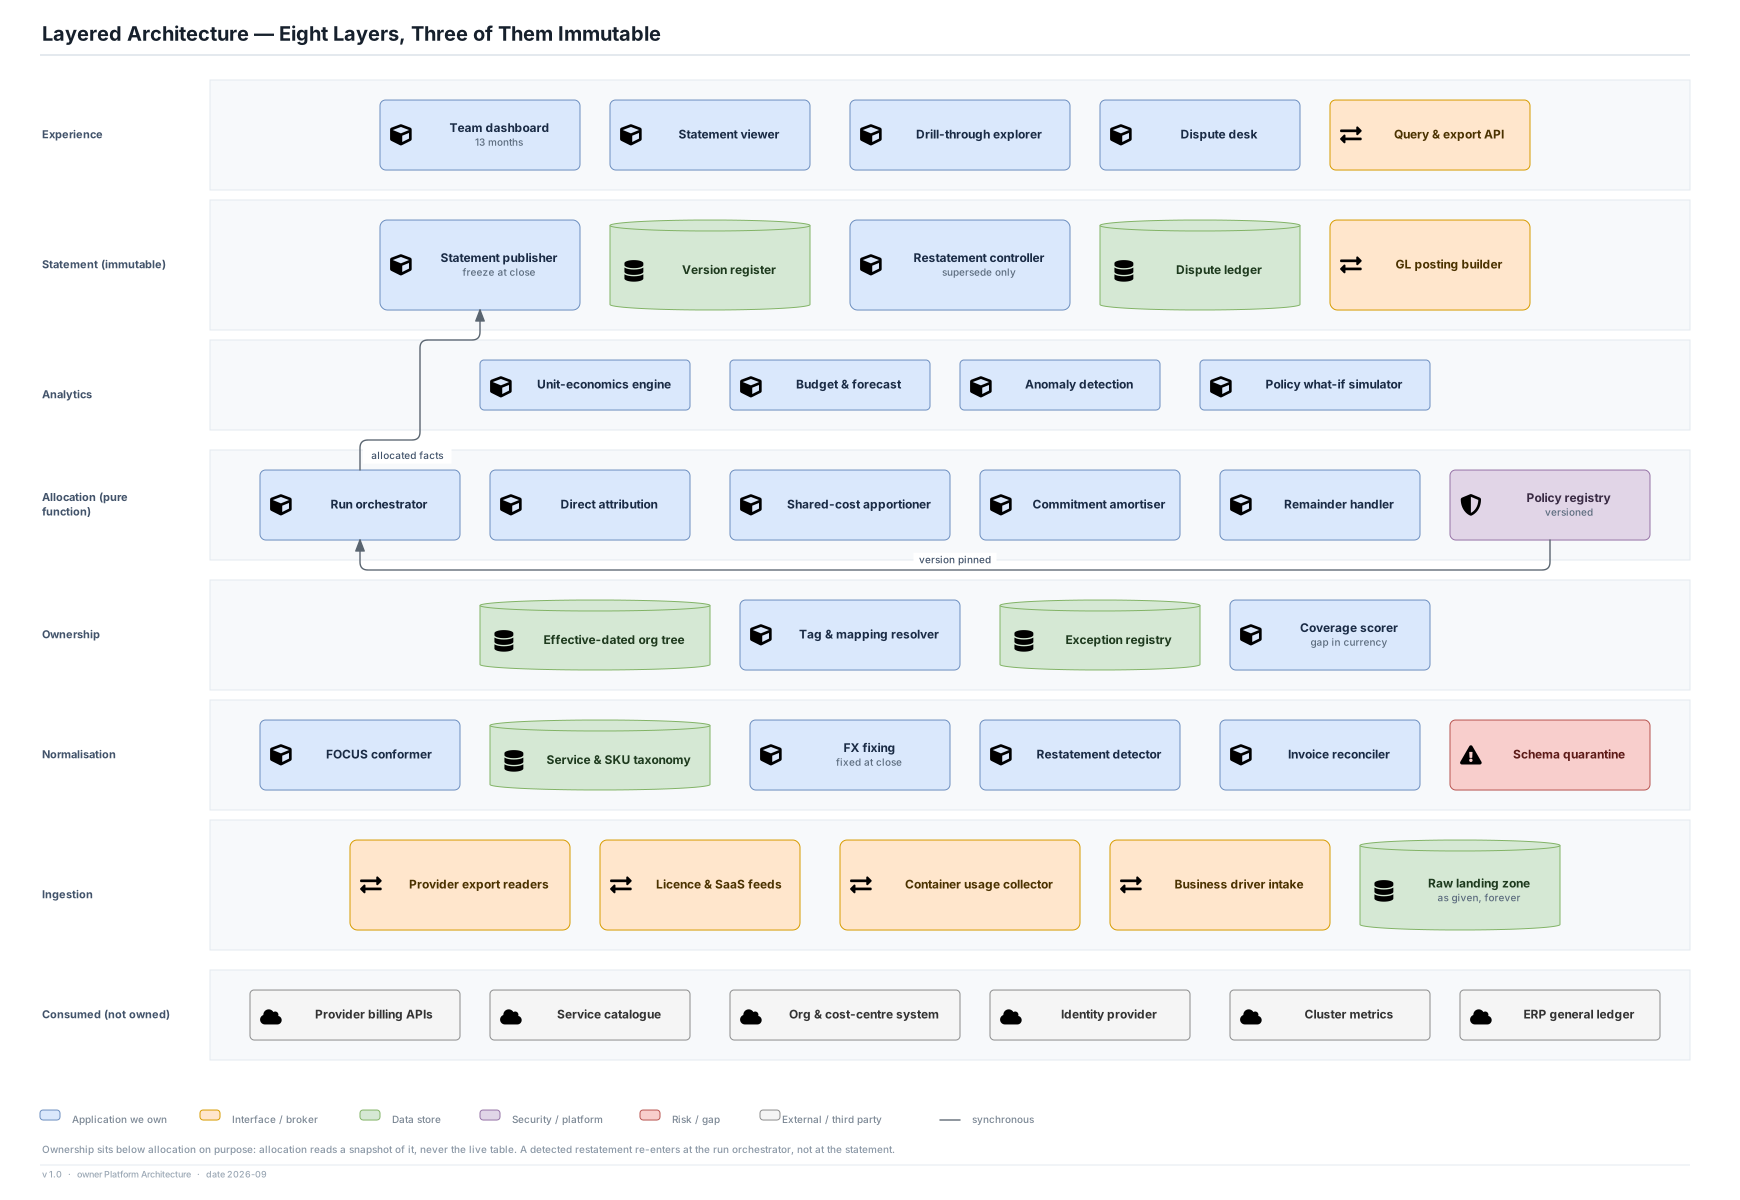
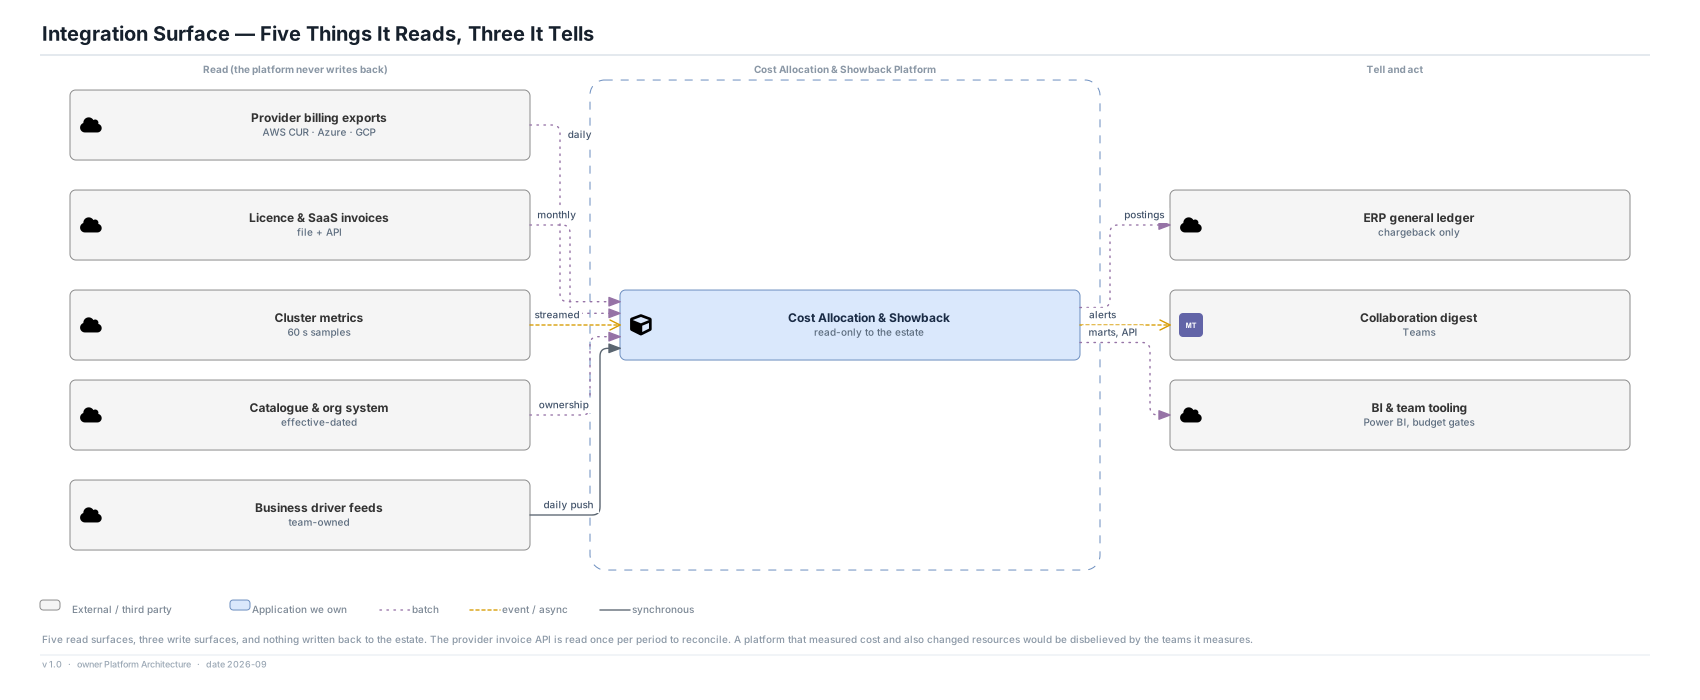
Sixteen decisions make up this architecture. Everything else across the twenty-two views is either a consequence of one of them or a detail that could be decided differently next quarter without anybody noticing. Each record states the question as it was actually open, the options that were weighed, what was chosen, how it is realised on Azure, what the choice costs, and the conditions under which a different answer would be right.
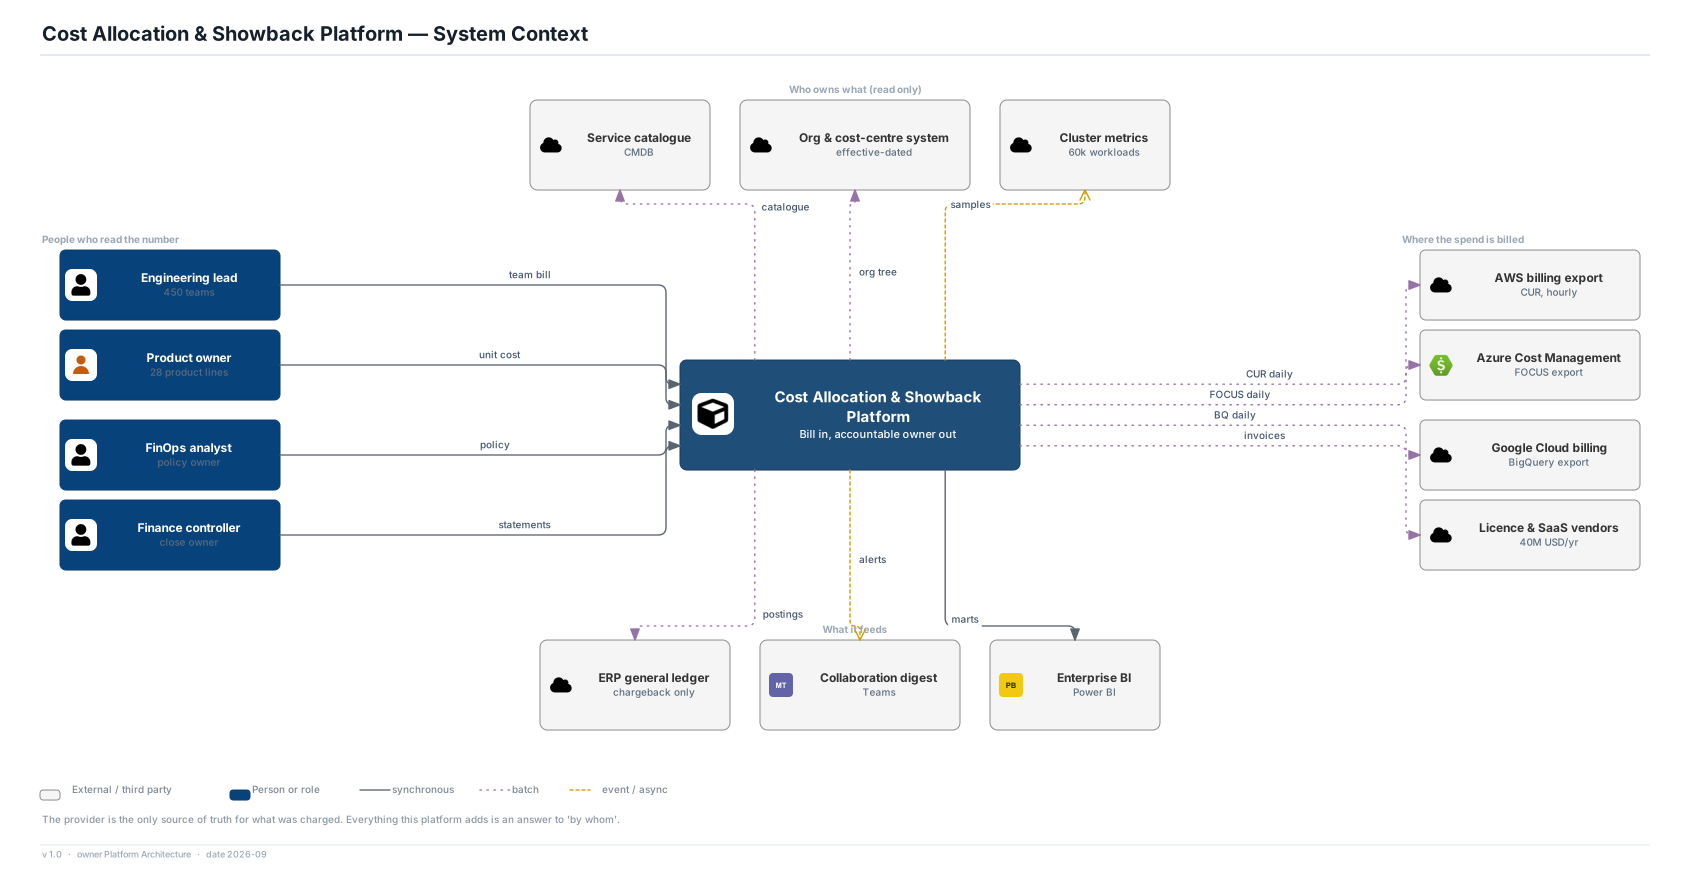
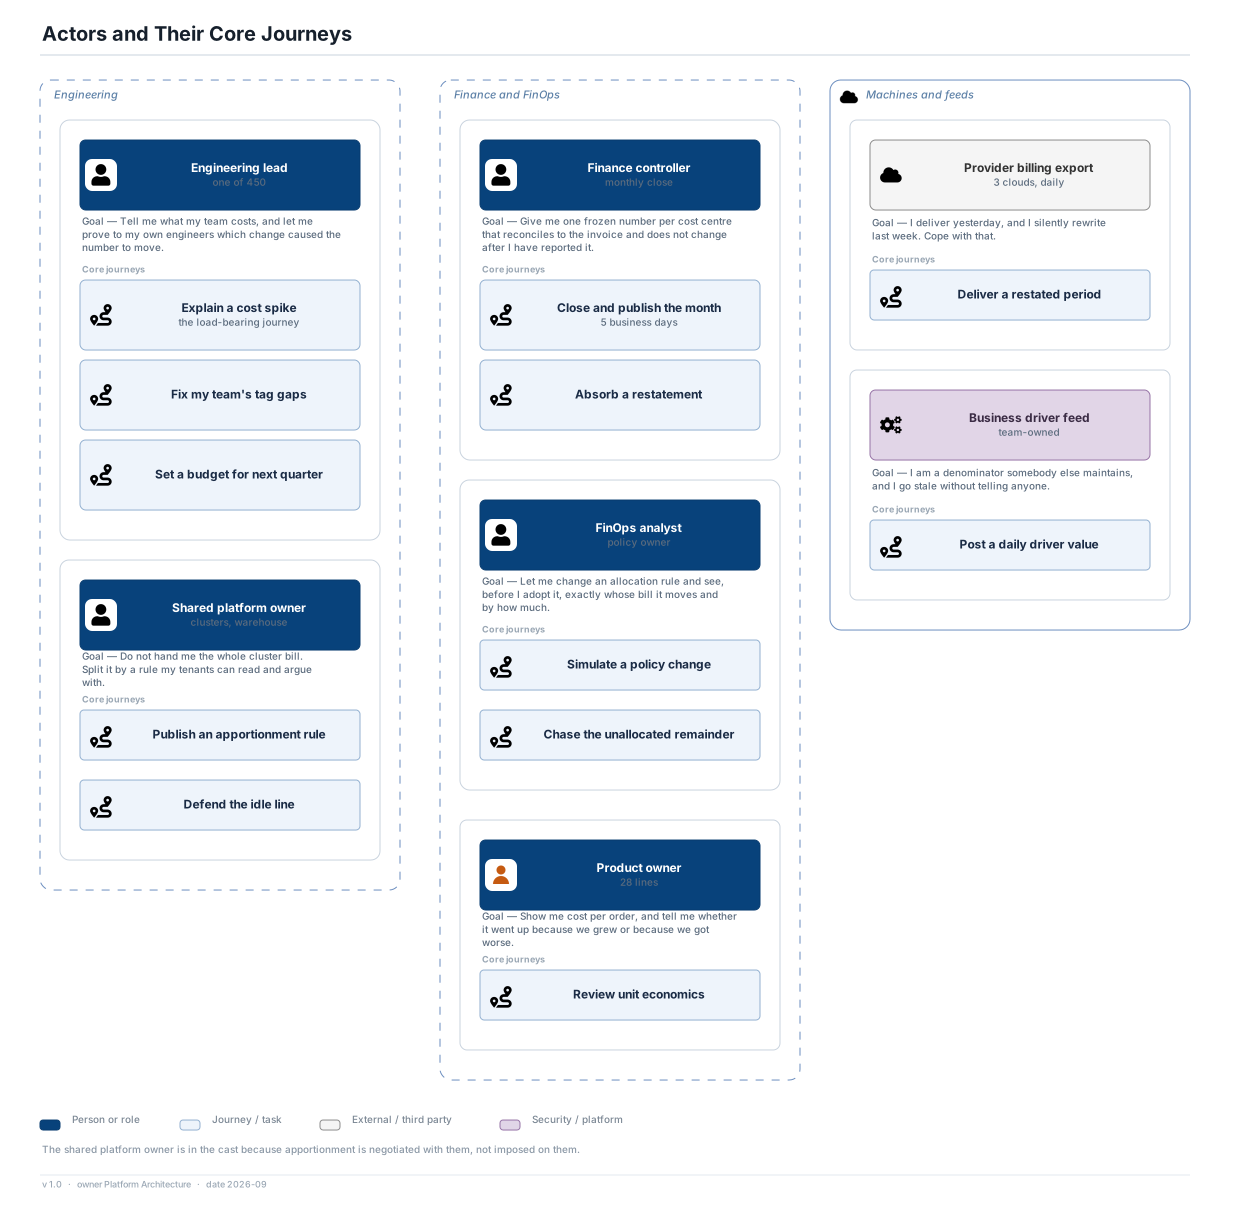
Status of this document. This is a design, not a report on a running system. Every rate, latency, tolerance, threshold and retention figure is a stated assumption chosen to be defensible and arguable rather than measured — the operating context is an estate of three clouds, roughly 1,200 billing scopes, 40,000 active resources, 450 engineering teams, and about $180M a year of cloud spend plus $40M of licence and SaaS spend, which is itself an assumption. Where a number is load-bearing it is named in the record that depends on it, so a reviewer can change the number and see which decisions move with it.
How to read a record
- Question: The forcing question: why a decision was needed at all.
- Context: The requirement, the scale and the constraint that make it hard.
- Decision: What this architecture does, stated so it can be checked.
- How it is realised on Azure: The concrete mechanism: which service or package, configured how, in which subscription.
- Options weighed: Chosen, rejected, deferred, or right elsewhere, with the reason for each.
- Consequences: What the choice buys and what it costs, both kept visible.
- Choose differently when: The conditions that would flip the decision for your system.
- Why it holds up over time: What keeps the decision right as scale, staff and technology change.
- Lesson: The principle that transfers beyond this platform.
Decision map
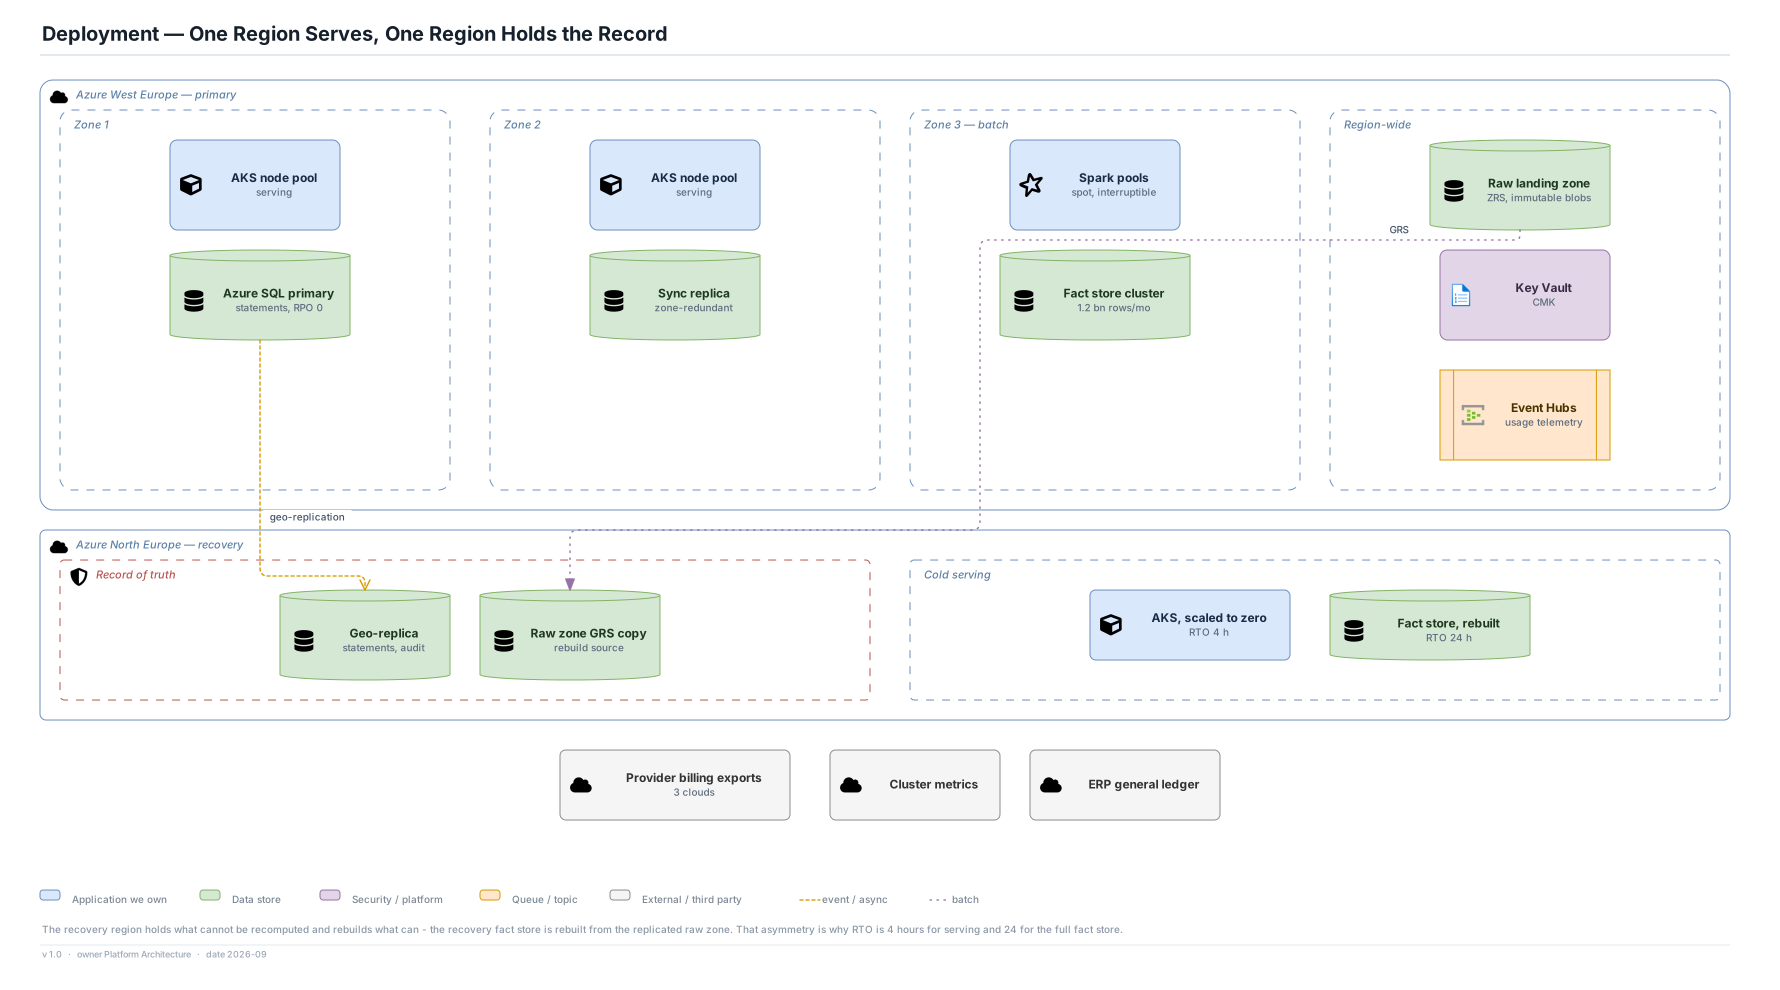
Reproducibility and the ledger: The decisions that make a published number defensible while its source data is still moving.
- ADR-01 · Allocation is a pure function of three pinned, versioned inputs
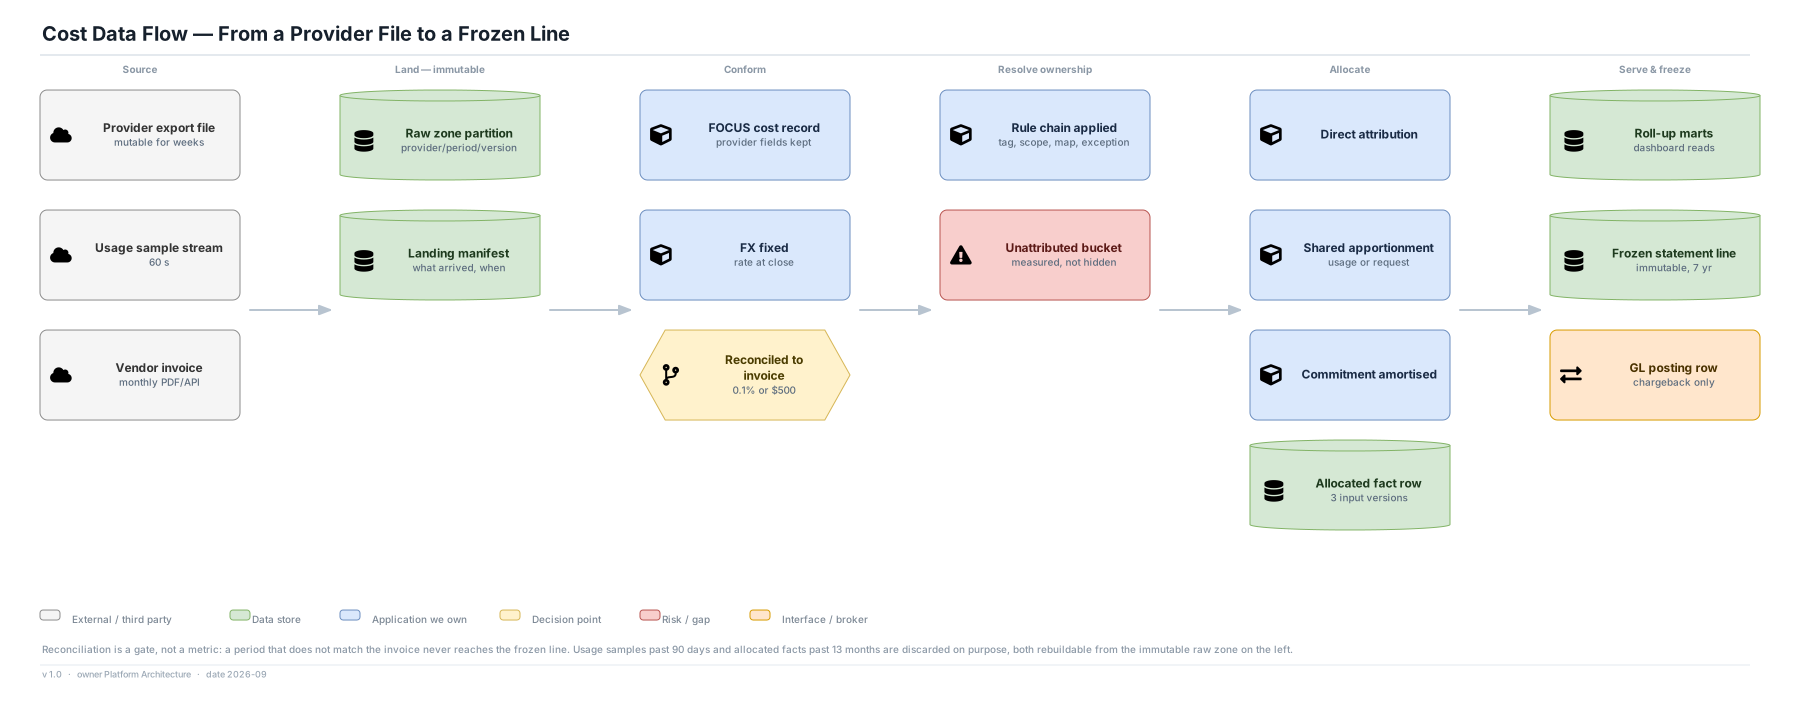
- ADR-02 · The bill is landed exactly as given, immutably, and normalised beside it
- ADR-03 · Allocated facts are materialised per run, not resolved at query time
- ADR-04 · Restatement supersedes, and is the normal path run a second time
Ownership and attribution: How a cost record acquires an accountable owner, and what happens to the ones that do not.
- ADR-05 · Ownership is effective-dated and resolved by a declared precedence chain
- ADR-06 · A mid-period ownership change is effective-dated, not retroactive
- ADR-07 · The unallocated remainder is a named line charged to an accountable owner
- ADR-08 · Inferred attribution is marked, and excluded from chargeback
Shared cost and commitments: Splitting what nobody incurred alone, and deciding where a discount lands.
- ADR-09 · Shared compute is apportioned on max(request, usage), with idle to the platform owner
- ADR-10 · Commitment savings go to the consumer, with both amortised and cash views published
Publication and disputes: Freezing, restating, disputing and posting — the lifecycle of a number people act on.
- ADR-11 · Reconciliation to the provider invoice gates publication
- ADR-12 · One pipeline, two labels: the current period is an estimate, never a statement
- ADR-13 · Disputes never block publication, and close by correction or reasoned rejection
Scale, storage and cost: What is kept, for how long, at what grain, and what the platform is allowed to cost.
- ADR-14 · Full grain is kept in the raw zone; allocated facts are kept 13 months and are disposable
- ADR-15 · Serving and batch are separate tiers, and batch runs on interruptible capacity
Access and confidentiality: Who may see whose bill, and why estate-wide cost data is sensitive.
- ADR-16 · Scope is resolved server-side from the org tree; out-of-scope reads are answered at aggregate grain
Technology by capability
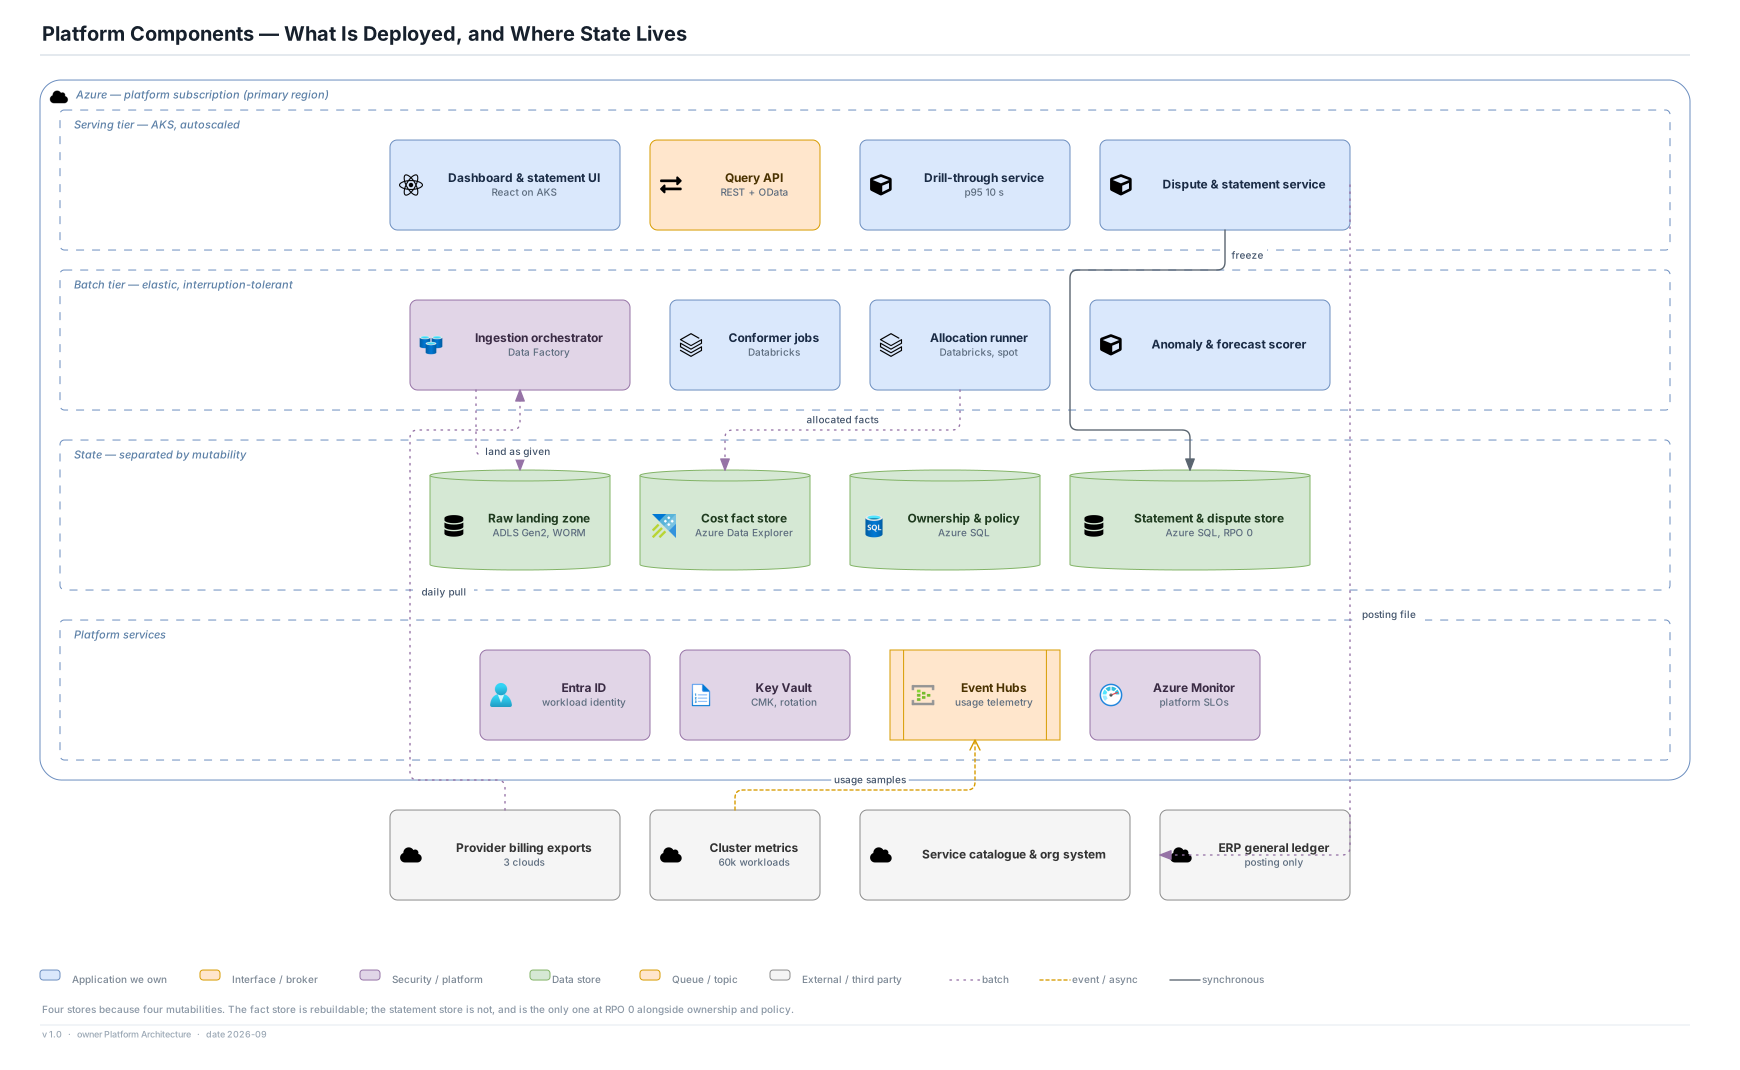
Azure was chosen for this exercise deliberately rather than because the topic demands it: a showback platform is inherently multi-cloud in its inputs and has to run somewhere, and the recent use cases in this practice have leaned on Google Cloud and on open-source on-premises stacks. Every requirement in ask.md is vendor-neutral; the table below is one defensible realisation of it. The load-bearing property of each choice is named, so a reader on another cloud can substitute the equivalent without losing the architecture.
| Capability |
Choice |
Origin |
Credible alternative |
Why this one |
Record |
| Raw landing zone |
ADLS Gen2 with immutable blob policy and lifecycle tiering |
Azure |
S3 with Object Lock, or GCS with bucket retention |
Write-once semantics enforced by the platform rather than by convention, and tiering to archive without changing the path |
ADR-02 |
| Cost fact store |
Azure Data Explorer, partitioned by period and provider |
Azure |
Synapse dedicated pools, BigQuery, Snowflake, or Delta on Databricks SQL |
Columnar scan over a 13-month window with materialised roll-ups, and cheap partition drop for retention |
ADR-03 |
| Allocation engine |
Azure Databricks, partition-parallel, on spot node pools |
Azure |
Synapse Spark, EMR, Dataproc, or a warehouse-native SQL pipeline |
Deterministic partitioned execution with checkpointing, which is what makes a pure re-run affordable on interruptible capacity |
ADR-15 |
| Ingestion orchestration |
Azure Data Factory with per-provider pipelines |
Azure |
Airflow, Step Functions, or Cloud Composer |
Declarative per-source scheduling with landing manifests and a clear cutoff-and-escalate semantic |
ADR-11 |
| Ownership, policy and statements |
Azure SQL Database, zone-redundant, geo-replicated |
Azure |
PostgreSQL Flexible Server, Aurora, or Cloud SQL |
Temporal tables for effective dating, synchronous commit for RPO 0, and transactional publication of a frozen statement |
ADR-05 |
| Policy registry |
Git repository as the source, versions pinned in Azure SQL |
Open source + Azure |
A policy table with an approval workflow, or OPA bundles |
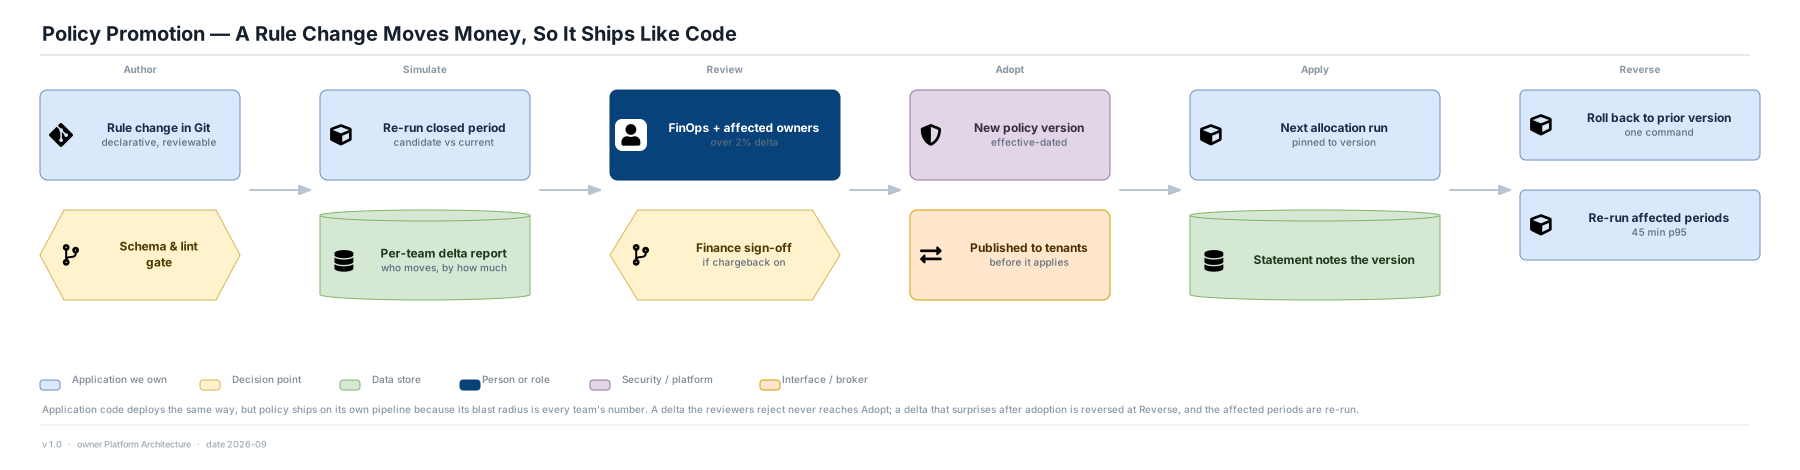
Review, history and rollback come free; the pinned version id is what the allocation run actually reads |
ADR-01 |
| Usage telemetry transport |
Event Hubs with downsampling on ingest |
Azure |
Kafka, Kinesis, or Pub/Sub |
2.6 bn samples a month at bounded retention, with a consumer that can fall behind without losing the window |
ADR-09 |
| Serving tier |
AKS across availability zones, autoscaled |
Azure |
App Service, Cloud Run, or ECS |
Serving isolated from batch so no interactive request ever queues behind an allocation run |
ADR-15 |
| Identity |
Entra ID with workload identity and enforced MFA |
Azure |
Okta with OIDC, or any IdP issuing group claims |
Short-lived machine credentials with no static keys, and group claims that name the person rather than their scope |
ADR-16 |
| Key management |
Key Vault with customer-managed keys and rotation |
Azure |
KMS, Cloud KMS, or HashiCorp Vault |
Rotation without re-ingestion, which matters when the raw zone is immutable and 37 months deep |
ADR-16 |
| Provider billing access |
Per-provider export-read-only credentials in Key Vault |
Multi-cloud |
Any least-privilege billing reader role |
Credentials that read the bill cannot reach the workloads, which is what makes estate-wide access acceptable |
ADR-16 |
| Billing schema |
FOCUS-conformed cost record, provider fields retained |
FinOps Foundation |
A bespoke internal schema |
One vocabulary across three clouds, with the provider-native columns kept so nothing is lost in translation |
ADR-02 |
| Dashboards and marts |
Pre-aggregated roll-ups served to Power BI and the platform UI |
Azure |
Looker, QuickSight, or Superset |
Bounded query cost per team, with full-grain reads reserved for drill-through |
ADR-03 |
| Observability |
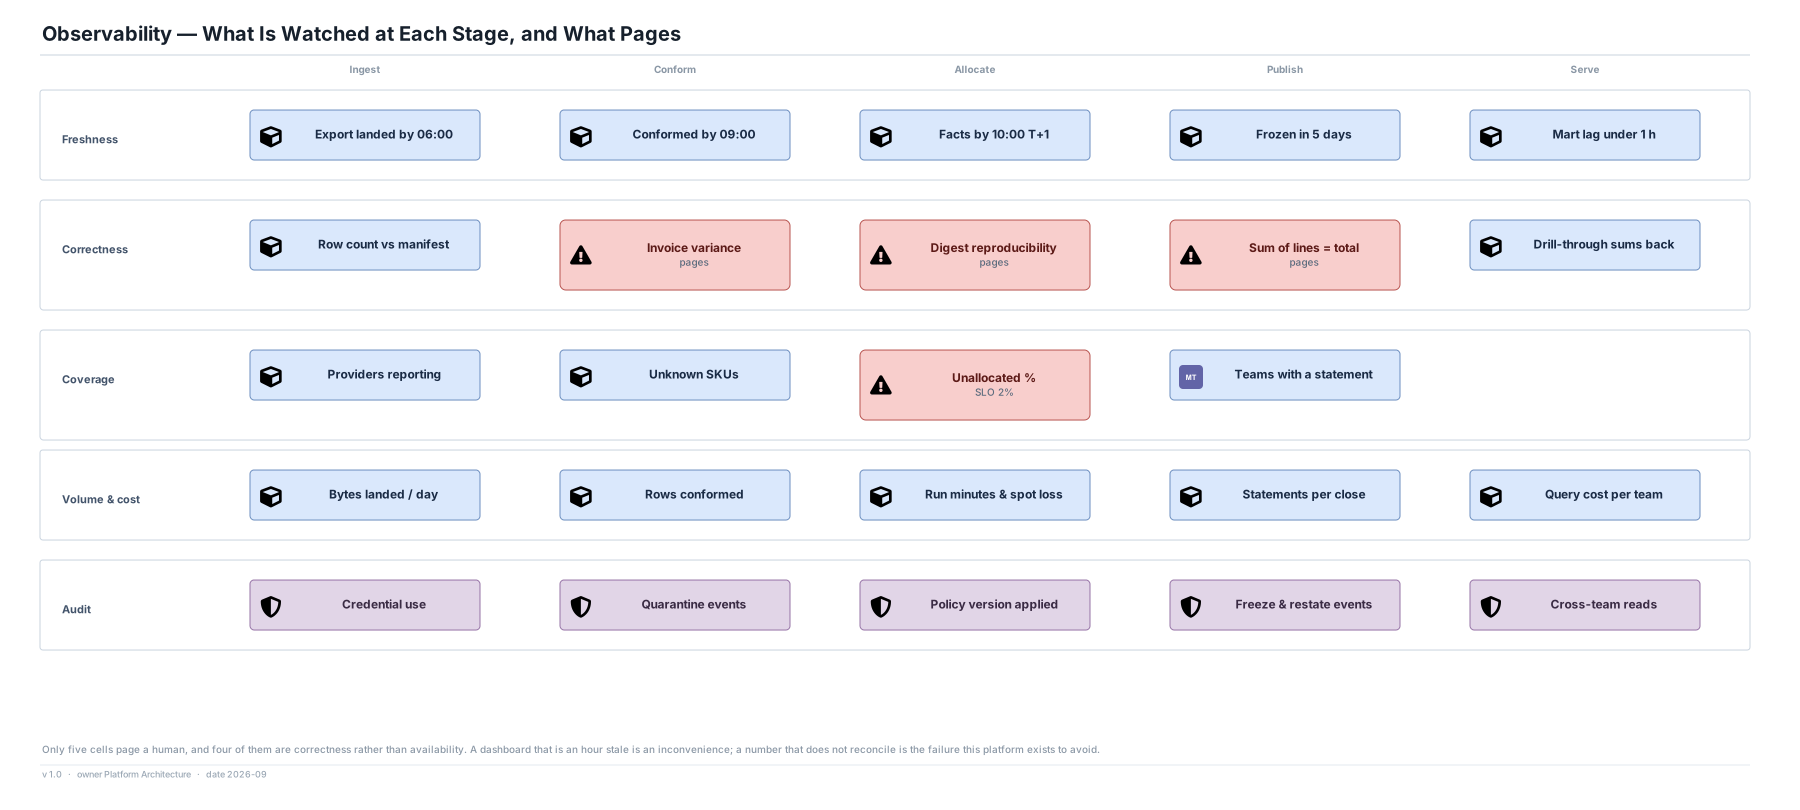
Azure Monitor, alerting on correctness rather than availability |
Azure |
Prometheus and Grafana, or any SLO tooling |
For a measurement platform, being wrong is worse than being late, and the alert policy has to say so |
ADR-11 |
The decisions, and the alternatives that lost
Reproducibility and the ledger
The decisions that make a published number defensible while its source data is still moving.
Status: Accepted · Shown on views: 02, 12, 11
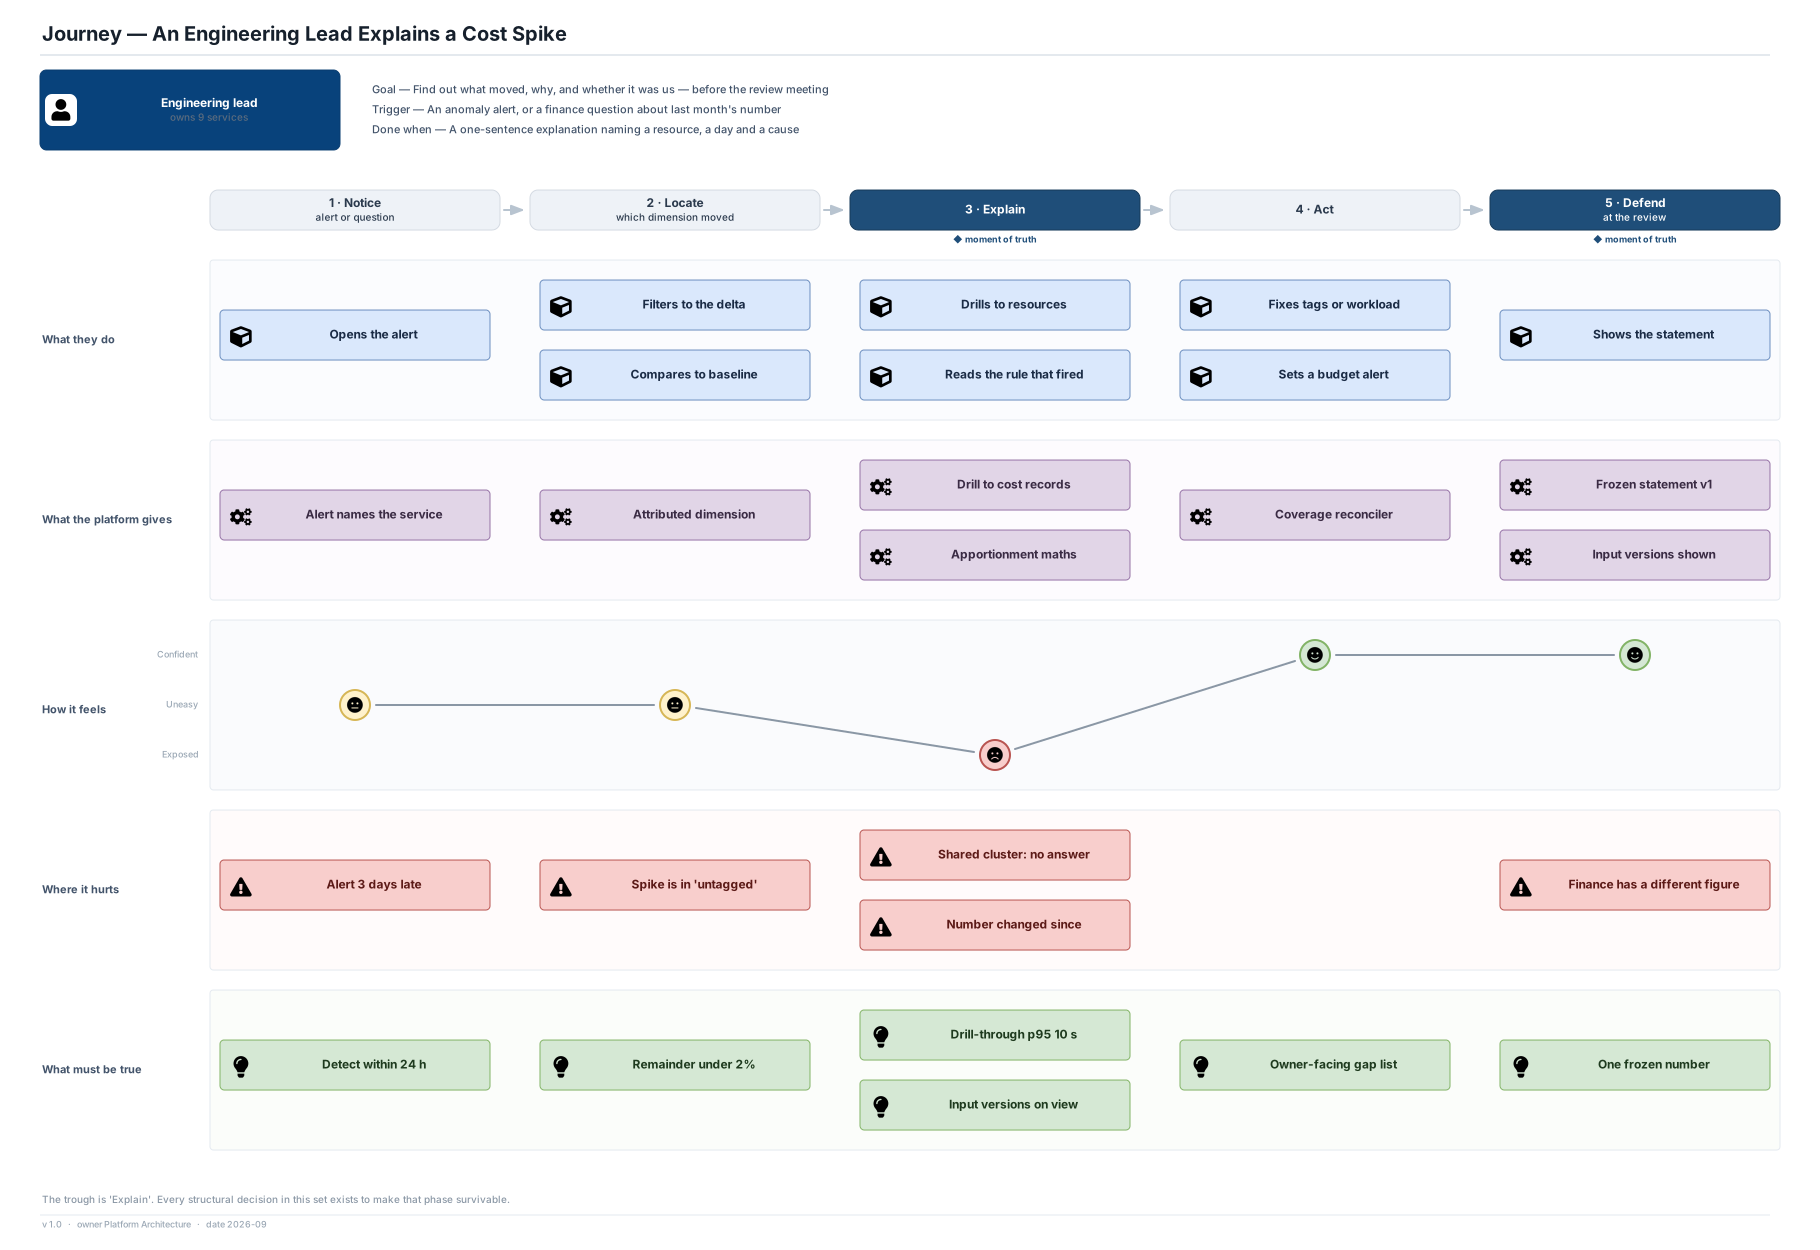
When someone asks why their cost number changed between yesterday and today, what does the architecture allow us to say?
Context. Three things move independently and continuously. Provider billing data is restated for weeks after the usage occurred, by credits, commitment reallocation and provider corrections. The organisation changes: teams split, resources change hands, cost centres are renamed. And the allocation rules themselves are argued over and revised, because they encode a negotiation rather than a fact. A platform that resolves attribution by reading the current state of all three produces a different answer to the same question on consecutive days, with no mechanism for explaining the difference. Every showback programme that loses credibility loses it here, and a ledger nobody can reproduce can never be promoted to chargeback.
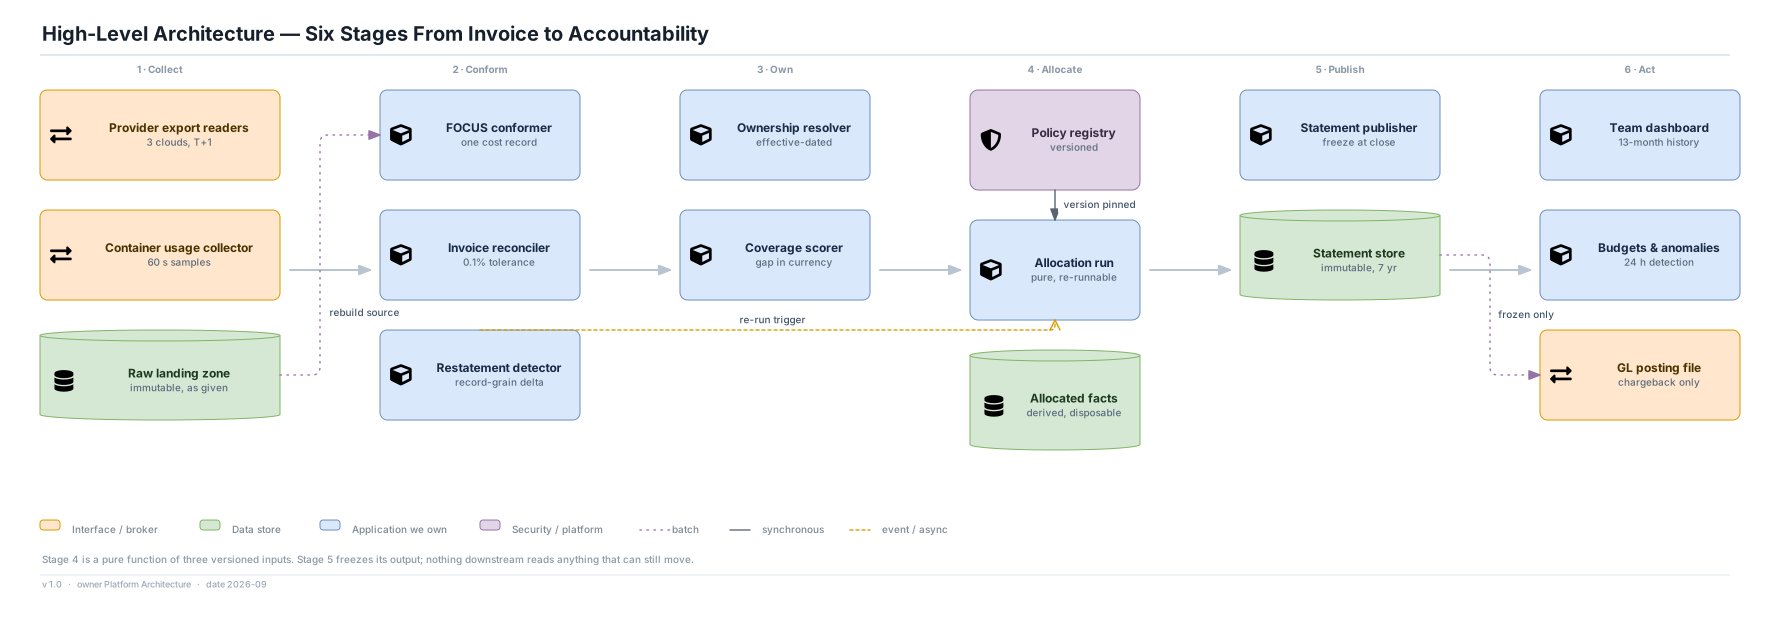
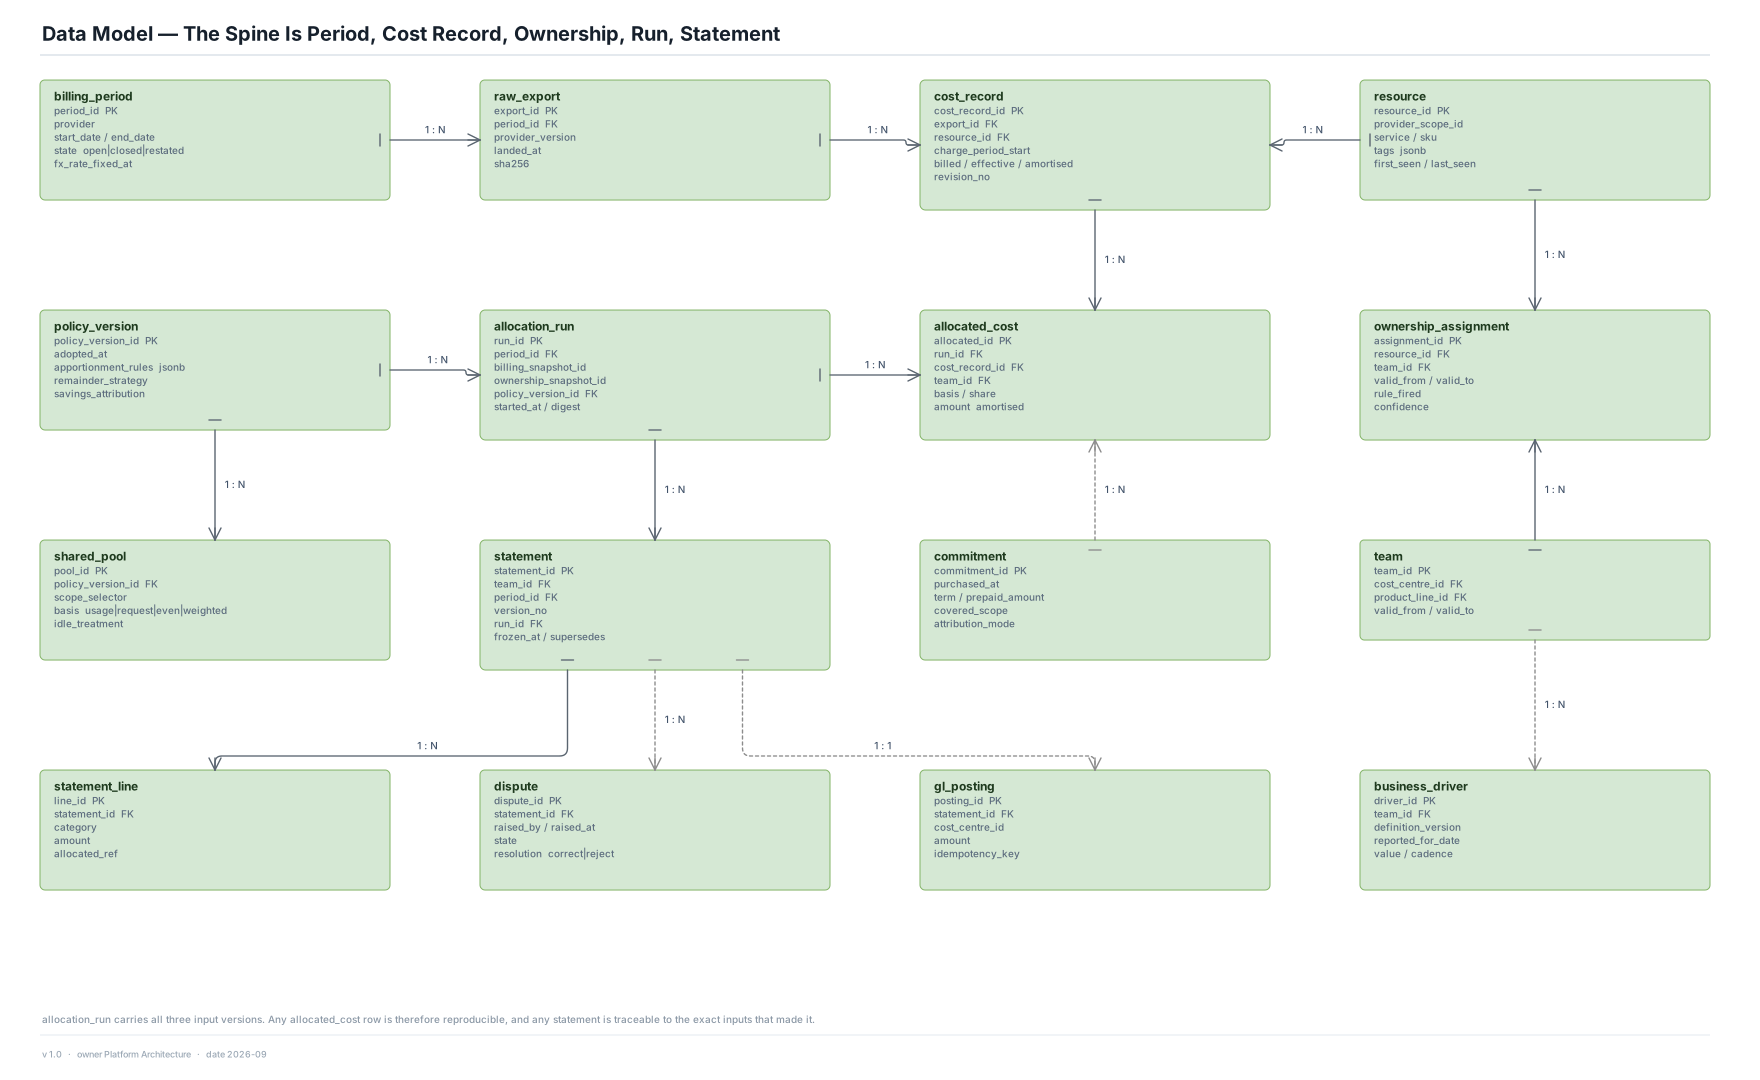
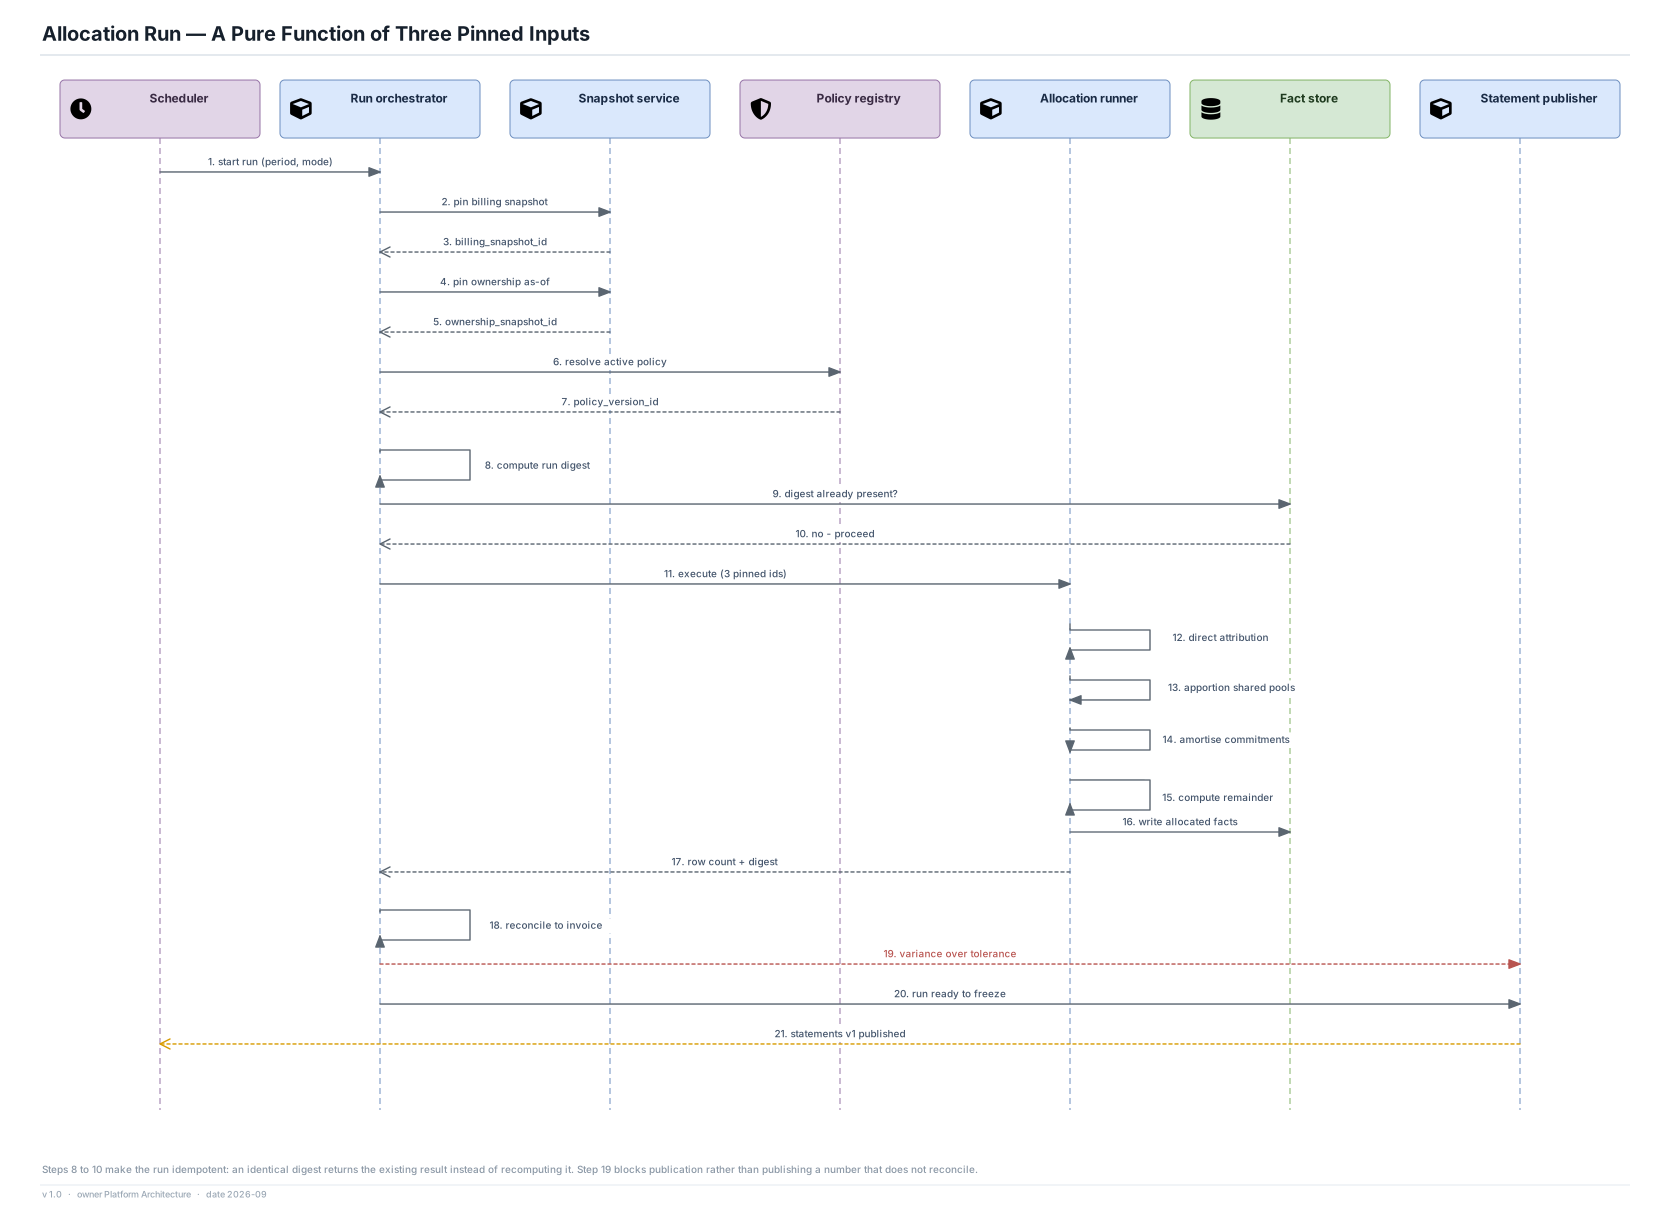
Decision. Allocation is defined as a pure function over exactly three immutable, separately versioned inputs: a billing snapshot, an ownership snapshot taken as of a point in time, and an allocation policy version. The three are resolved and pinned before any arithmetic happens, hashed into a run digest, and recorded on every allocated row and every published statement. A run with a digest that already exists returns the existing result rather than recomputing it. Nothing is allocated in place, and no published figure is ever a live query.
How it is realised on Azure. The run orchestrator resolves the three ids and writes an allocation_run row in Azure SQL before dispatching. Databricks jobs read the pinned billing snapshot from the Azure Data Explorer fact store by version predicate, the ownership snapshot as an as-of query against the effective-dated tables, and the policy document at its pinned version from the registry. The digest is a hash of the three ids plus the engine version; allocated rows carry run_id, and statements carry the three ids directly so they are visible on screen.
| Option |
Verdict |
Reasoning |
| Pure function of three pinned inputs |
Chosen |
Reproducible, explainable, and makes restatement a re-run rather than a special case |
| Resolve attribution against current state on each run |
Rejected |
Cheapest to build and cannot answer the only question that matters — why the number moved |
| Pin billing only, read ownership and policy live |
Rejected |
A reorganisation or a rule change silently rewrites closed periods |
| Event-sourced ledger of allocation decisions |
considered |
Fully auditable and considerably more machinery; the snapshot model gets the same guarantee with a table and a hash |
What it buys
- Any past figure can be reproduced exactly, years later, from data the platform still holds
- 'Why did it change?' has a one-sentence answer: which of the three inputs moved
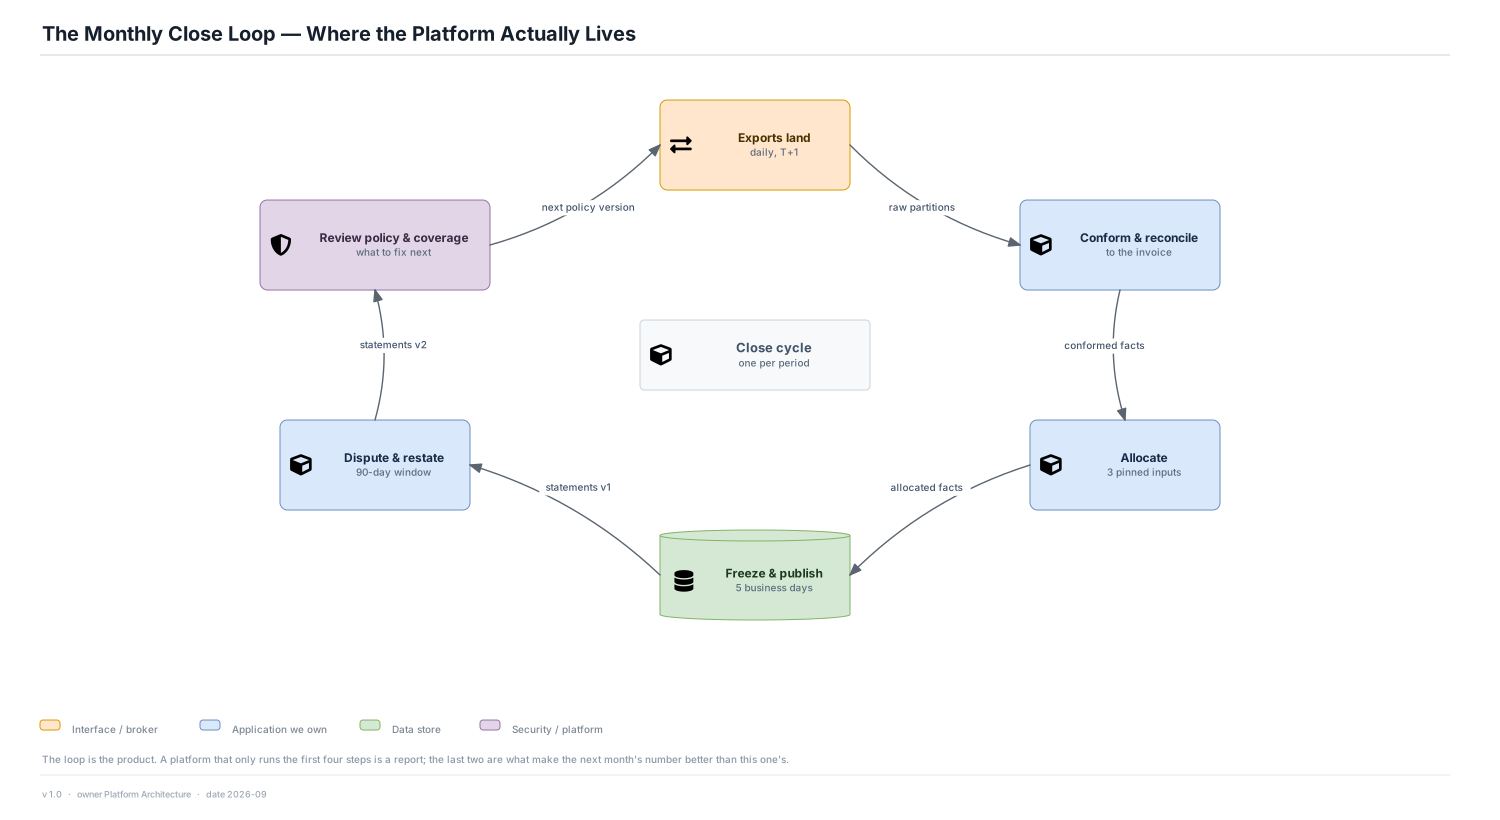
- Restatement stops being an exception path and becomes the normal path executed again
- A policy change can be simulated against a closed period, because the other two inputs can be held constant
What it costs
- Ownership and policy must both be modelled as versioned, as-of-queryable data rather than current-state tables
- Snapshot resolution adds a step and a failure mode to every run
- Storage of superseded versions grows monotonically, bounded only by retention policy
Choose differently when. If the organisation were static, the provider bill immutable once issued, and the allocation rules fixed by regulation, the pinning machinery would be pure overhead and a current-state query would be correct. Nothing in a real cloud estate meets any of those three conditions.
Why it holds up over time. The contract — identical inputs produce identical output — is independent of the engine that enforces it. Spark, a warehouse or a technology that does not yet exist can each satisfy it, and every historical period stays reproducible across that change. This is the one decision in the set that should never need revisiting.
Lesson. When the inputs to a calculation are mutable and the output is something people act on, version the inputs rather than trying to stabilise them. Explaining a change is a design property, not a reporting feature.
ADR-02 · The bill is landed exactly as given, immutably, and normalised beside it
Status: Accepted · Shown on views: 09, 10, 13
Where does the platform's record of what the provider charged actually live, and can it survive a change to the way we interpret it?
Context. Provider billing schemas change: columns are added, SKUs are renamed, charge categories are retired, and the FOCUS specification itself is revised. A platform that transforms on ingest and keeps only the transformed result cannot re-derive history when its interpretation turns out to be wrong, and cannot prove to a disputing team what the provider actually said. The raw export is also the cheapest thing in the estate to store and the only thing that is genuinely irreplaceable at the point of ingestion, because a provider's detailed export is not indefinitely re-fetchable.
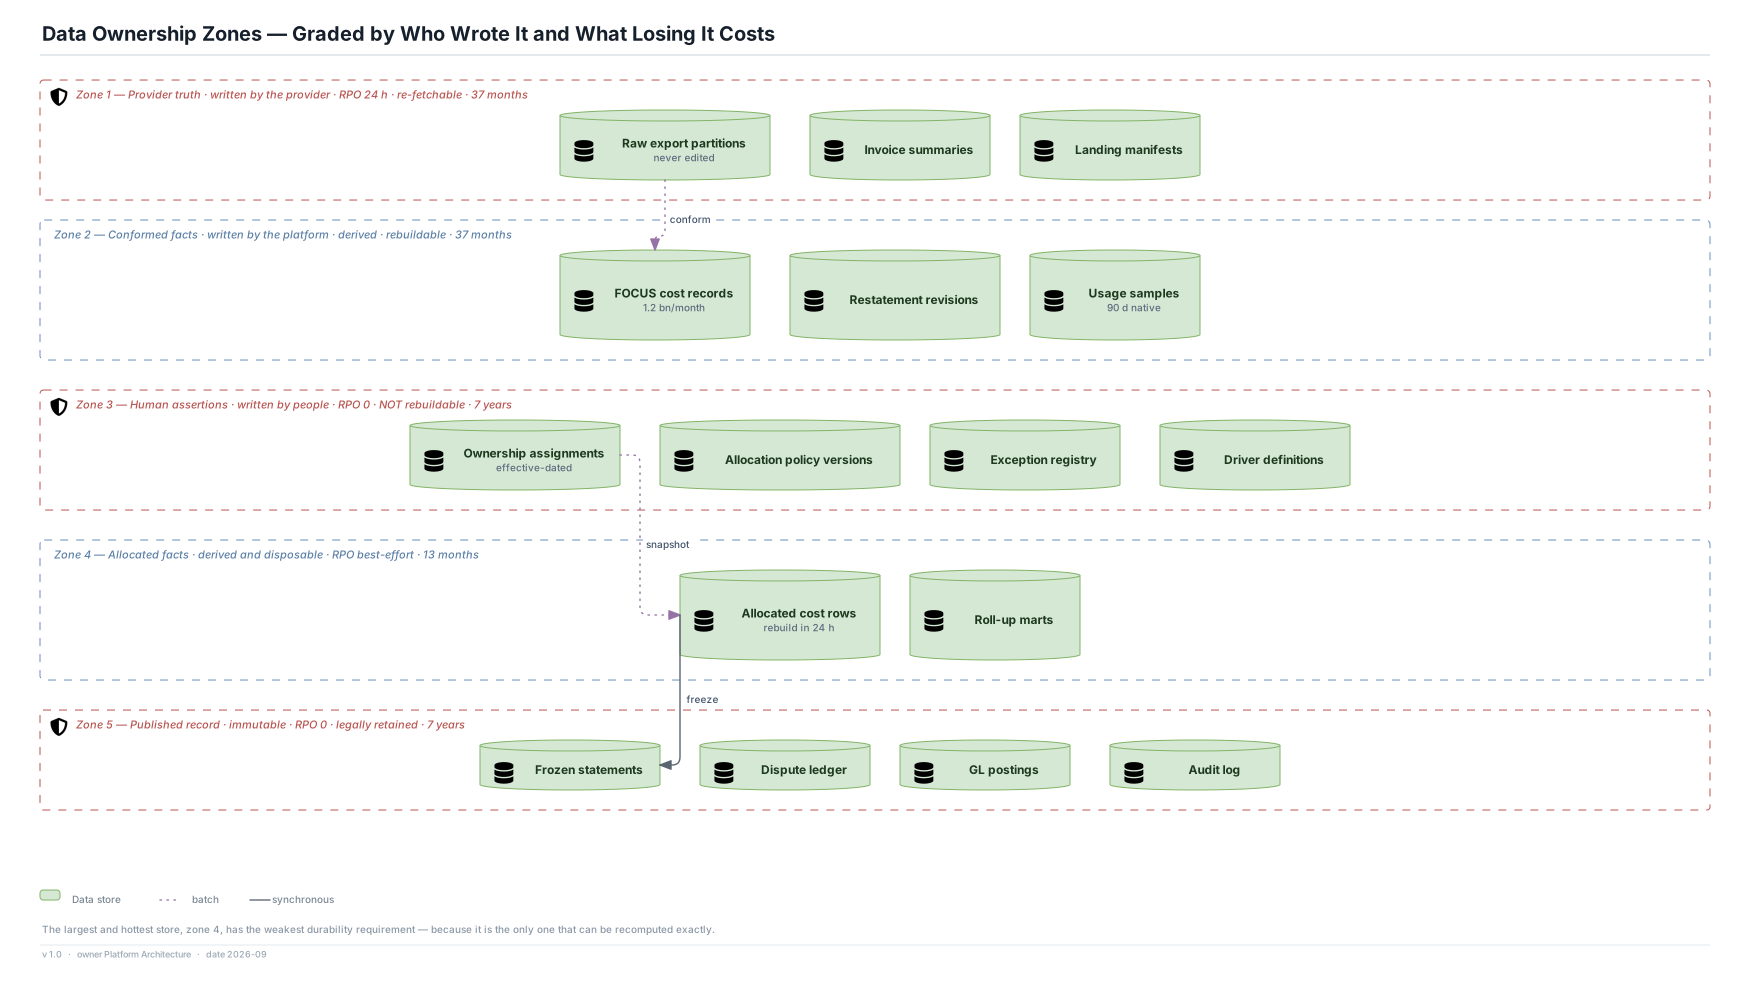
Decision. Every provider export is written to an immutable raw zone exactly as received, partitioned by provider, billing period and export version, with a manifest recording hash, row count and landing time. Normalisation to the conformed FOCUS cost record happens beside the raw form, never over it, and preserves provider-native fields alongside the conformed ones. Every downstream store is derived from the raw zone and can be rebuilt from it.
How it is realised on Azure. ADLS Gen2 with an immutable blob policy and a lifecycle rule moving partitions beyond 13 months to archive tiers. Data Factory writes the partition and the manifest in one activity; a partition is never rewritten, only superseded by a new export version. The conformer runs on Databricks and writes to the Azure Data Explorer fact store, which is explicitly a derived store.
| Option |
Verdict |
Reasoning |
| Immutable raw zone as the source of everything |
Chosen |
Cheap, complete, and the only thing that makes a re-interpretation of history possible |
| Transform on ingest, keep the conformed result only |
Rejected |
Saves a few per cent of storage and makes every schema mistake permanent |
| Raw zone as a staging area, cleared after load |
Rejected |
The common warehouse pattern; it removes the archive of record and the dispute evidence in one step |
| Keep raw, but only for the current fiscal year |
considered |
Reasonable if audit retention were shorter; here the statement retention of seven years sets the floor |
What it buys
- A revised conformer re-derives all history instead of losing it
- A disputing team can be shown exactly what the provider said, byte for byte
- The raw zone doubles as the archive of record, which is what makes the fact store disposable (ADR-14)
- Schema drift can be made a loud failure rather than a silent coercion
What it costs
- 37 months of full-grain exports across three clouds is the second-largest storage line in the platform
- Two representations of the same data must be kept consistent in meaning, if not in shape
- Immutability makes deleting genuinely mis-delivered data an administrative exercise
Choose differently when. If a provider guaranteed indefinite re-fetch of detailed billing at original grain, the raw zone could become a cache rather than a record. No provider offers that today, and the detailed export retention windows are shorter than the seven-year statement retention this platform must meet.
Why it holds up over time. Billing formats will change repeatedly inside the life of this platform. Keeping the unmodified original is what turns each of those changes into a re-derivation rather than a discontinuity in the history.
Lesson. Keep the thing you were given, separately from the thing you made of it. The cost is storage; the alternative is that every interpretation error is permanent.
ADR-03 · Allocated facts are materialised per run, not resolved at query time
Status: Accepted · Shown on views: 03, 09, 12
Does attribution get computed once into a wide fact table, or resolved on demand from raw cost plus policy?
Context. This is the first genuinely open question in the requirement. Query-time resolution is appealing: policy iteration becomes nearly free, history can never be stale, and there is no multi-billion-row rewrite when a rule changes. But a statement that is computed on read has no physical existence, which means there is nothing to freeze, nothing to point at during a dispute, and no bound on the cost of a query over thirteen months. Materialising inverts every one of those trade-offs.
Decision. Each allocation run materialises allocated facts into a versioned fact store keyed by run_id. Dashboards read pre-aggregated roll-ups derived from those facts; drill-through reads the facts themselves. A policy change does not rewrite existing rows: it produces a new run, and statements supersede rather than update.
How it is realised on Azure. Azure Data Explorer holds allocated facts partitioned by billing period and run, with roll-up materialised views for the dashboard grain. A re-run writes a new run partition; the previous run's partition is retained until its statements are superseded and the 13-month allocated-fact retention expires.
| Option |
Verdict |
Reasoning |
| Materialise per run |
Chosen |
Gives the statement a physical existence to freeze and bounds query cost |
| Resolve attribution at query time |
Rejected |
Free policy iteration, unbounded query cost, and nothing that can be frozen or disputed |
| Hybrid: materialise closed periods, resolve the current one live |
considered |
Attractive, and it creates two code paths that will disagree — see ADR-12, which solves the same problem with one path and two labels |
What it buys
- Dashboard latency is predictable over the full 13-month window
- A statement is an artefact that exists and can be handed to an auditor
- Drill-through is a read, not a recomputation, which is what makes the 10-second target achievable
What it costs
- Every policy correction costs a full re-run of the affected periods, budgeted at 45 minutes p95
- The fact store is the largest and most expensive store in the platform
- Multiple runs of the same period coexist until retention expires
Choose differently when. If policy changed weekly rather than a few times a year, or if the estate were small enough that a full-grain query over 13 months were cheap, query-time resolution would win. At 1.2 billion records a month and a handful of policy changes a year, materialising is the cheaper side of the trade.
Why it holds up over time. The decision is really about where the statement lives, and statements are a governance artefact rather than a technology one. As query engines get faster the balance shifts, but the need for a frozen artefact does not.
Lesson. A number people will argue about needs a physical existence. Computation on read is elegant until someone asks you to produce the version they saw last month.
ADR-04 · Restatement supersedes, and is the normal path run a second time
Status: Accepted · Shown on views: 13, 15, 20
What happens when the provider changes an amount for a period that has already been published?
Context. Cloud billing is mutable for weeks: credits land late, commitment coverage is reallocated, usage arrives out of order, and providers issue corrections. Most platforms treat this as an exception and build a separate correction workflow, which then has its own bugs, its own permissions and its own divergence from the main path. The alternative is to notice that a restatement is nothing more than a new billing snapshot, and that a pure allocation function can simply be run again.
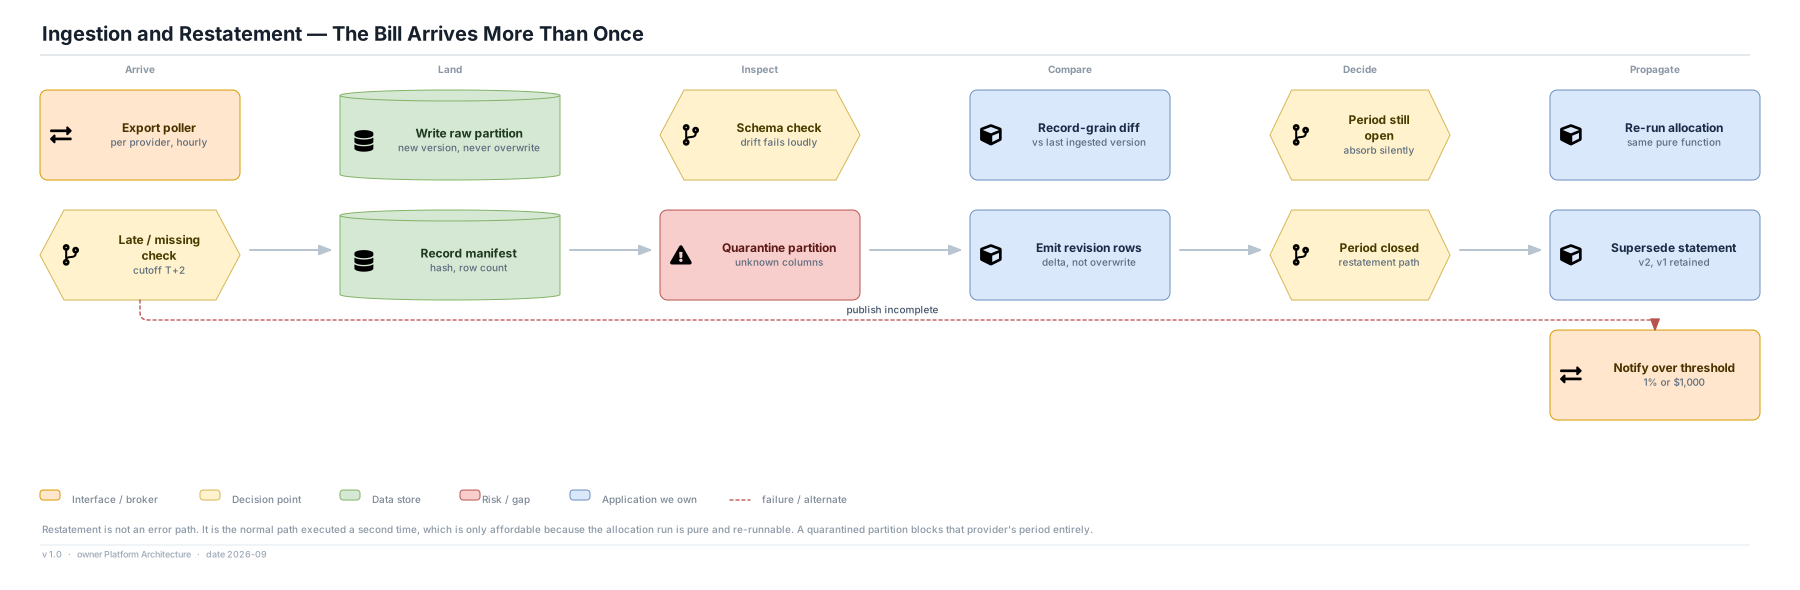
Decision. A re-issued export is landed as a new raw version, diffed at record grain into explicit revision rows, and — if the period is still open — absorbed silently. If the period is closed, the same allocation function is re-run against the new billing snapshot, producing a new statement version that supersedes rather than replaces its predecessor. Both versions remain retrievable for seven years, and a delta exceeding 1% or $1,000 of a team's period total notifies the owner within one business day.
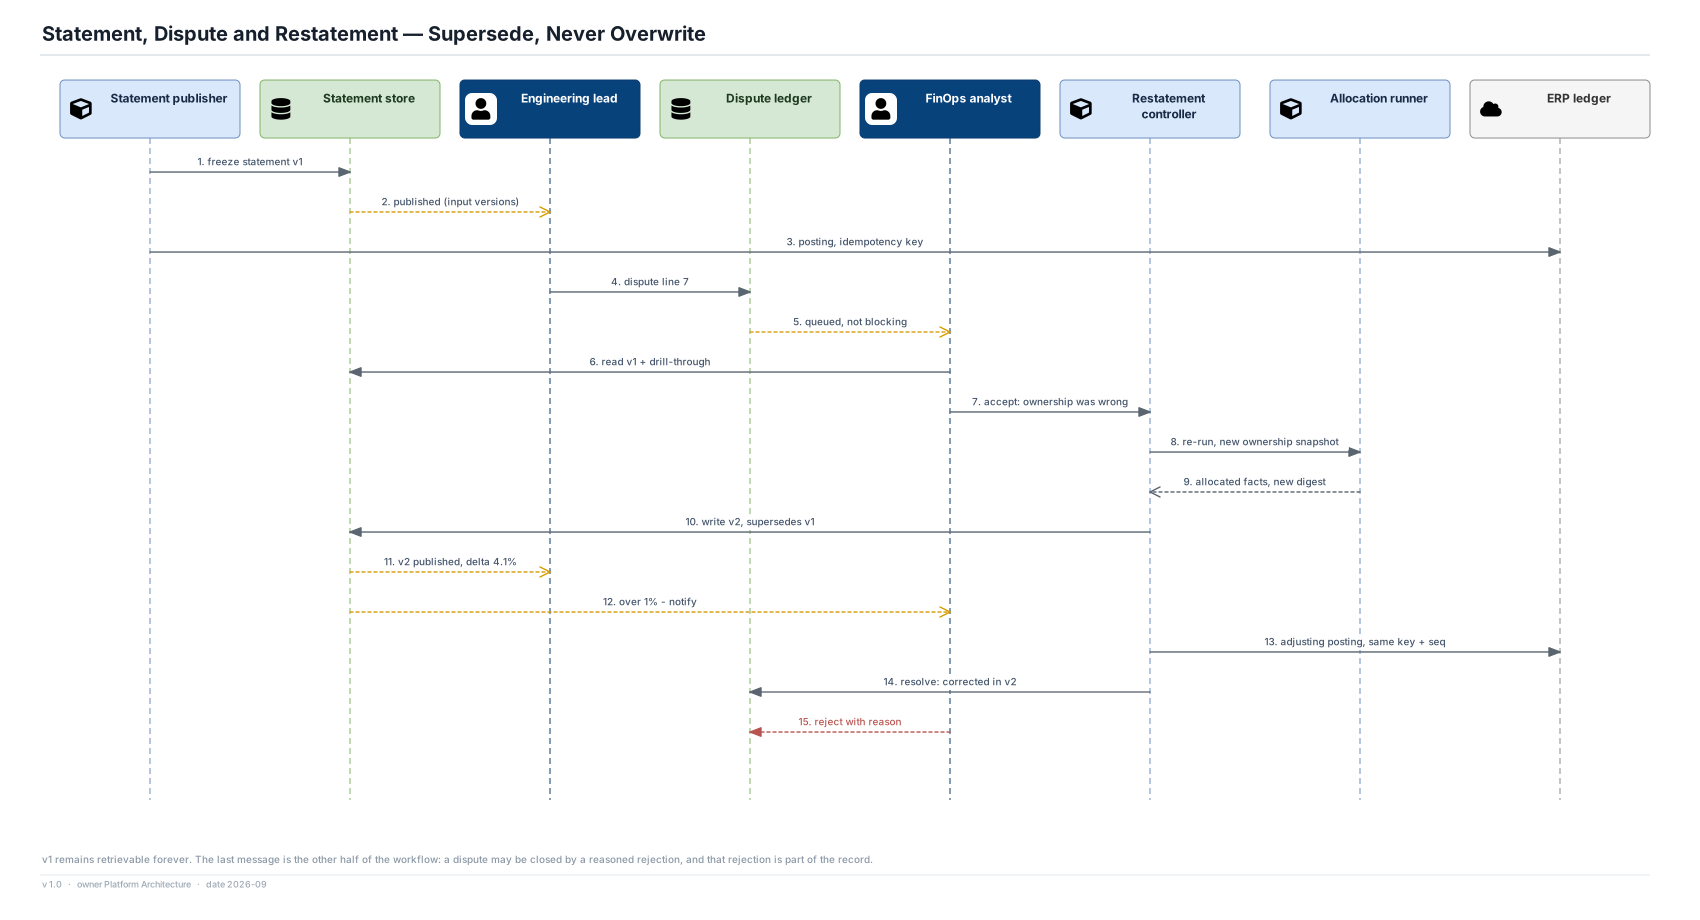
How it is realised on Azure. The restatement detector compares the incoming export against the last ingested version by record key and emits revision rows into the conformed store. The restatement controller invokes the ordinary run orchestrator with the new billing snapshot id; the statement publisher writes version n+1 with a supersedes pointer in Azure SQL. The GL adjusting posting reuses the original idempotency key with a sequence suffix.
| Option |
Verdict |
Reasoning |
| Supersede via a re-run of the same function |
Chosen |
No second code path, and the correction is as reproducible as the original |
| In-place correction of the published statement |
Rejected |
Destroys the version somebody already read and reported |
| Carry the delta forward into the next open period |
considered |
What the platform does for restatements arriving past the 90-day window; wrong as a default because it misattributes the period |
| Refuse restatement after publication |
Rejected |
Finance's number and the provider's invoice then diverge permanently |
What it buys
- One code path, exercised every month, rather than an exception path exercised rarely and trusted blindly
- The full history of what was believed when remains available for audit
- A restatement's cause can be attributed, which is what feeds the close-loop review
What it costs
- Statement storage grows with every restatement, retained for seven years
- Downstream consumers must handle superseding versions rather than a single row per team and period
- Compute for re-runs is a recurring, not exceptional, cost
Choose differently when. If providers issued immutable invoices with no post-issue corrections, restatement would be a genuine exception and a lighter mechanism would do. Within a 90-day window that is not the world any cloud customer lives in.
Why it holds up over time. Provider billing will remain mutable because the underlying commercial mechanisms — commitments, credits, negotiated discounts — are settled after the fact. Treating that as normal rather than exceptional is a property of the domain, not of this decade's tooling.
Lesson. If something happens every month, it is not an exception. Build the main path so it can absorb it, rather than a second path that will rot.
Ownership and attribution
How a cost record acquires an accountable owner, and what happens to the ones that do not.
ADR-05 · Ownership is effective-dated and resolved by a declared precedence chain
Status: Accepted · Shown on views: 11, 09, 22
What is the authoritative statement that a resource belongs to a team, and how does it survive the organisation changing shape?
Context. Tags are granular, correctable by the team that owns the resource, and perpetually incomplete. The provider's own account hierarchy is enforced and reliable, but reorganising it is a migration project. An external mapping table is instantly correctable and instantly divergent from reality. In practice a large estate needs all three, and needs to know which one answered. It also needs to answer as of a date, because teams split, merge and dissolve continuously and a closed period's meaning must not change when they do.
Decision. Ownership resolves by a declared precedence chain — resource tag, then parent-scope tag, then account or subscription mapping, then an explicit exception entry — evaluated as of a point in time, with the rule that fired recorded on every resolved record. The whole model, including the org tree above it, is effective-dated: every assignment carries valid_from and valid_to.
How it is realised on Azure. Azure SQL holds ownership_assignment, team, cost_centre and product_line as effective-dated tables with as-of query support. The resolver runs as part of the ownership snapshot step and writes rule_fired and confidence onto each assignment. The exception registry is a first-class table with its own approval workflow, because entries in it override the cloud's own metadata.
| Option |
Verdict |
Reasoning |
| Precedence chain over effective-dated tables |
Chosen |
Uses each source where it is strongest and records which one answered |
| Tags only, enforced at creation |
Rejected |
Correct in principle, and no large estate has ever achieved it retroactively |
| Account hierarchy only |
Rejected |
Reliable and far too coarse: a subscription rarely maps to one team |
| External mapping table only |
considered |
Easiest to correct and diverges from reality the moment nobody maintains it |
| Current-state ownership with no effective dating |
Rejected |
A reorganisation then rewrites what every closed period meant |
What it buys
- A closed period keeps its meaning across reorganisations
- The rule that fired is visible, so a disputed attribution is arguable rather than mysterious
- Metadata quality becomes measurable per source, which directs the coverage backlog
What it costs
- Every ownership query is temporal, which complicates both the schema and the queries against it
- The exception registry needs governance, because it can override the cloud's own truth
- Four sources must be kept from contradicting each other in ways that confuse rather than resolve
Choose differently when. If tag policy could be enforced at resource creation across the whole estate and back-filled, the chain would collapse to one rule. That is worth pursuing and is not a reason to design for a state the estate is not in.
Why it holds up over time. The one thing certain to recur is organisational change. A model that stores ownership as of a time rather than as of now does not need rebuilding each time it happens.
Lesson. When several imperfect sources each know part of the answer, rank them explicitly and record which one answered. An unrecorded precedence chain is indistinguishable from a guess.
ADR-06 · A mid-period ownership change is effective-dated, not retroactive
Status: Accepted · Shown on views: 11, 15, 22
A resource changes hands on the fourteenth of the month. Who pays for the first thirteen days?
Context. Three answers are available and all three are defensible. Applying the change retroactively to the period start is trivial to compute and rewrites a statement someone may already have read. Deferring it to the next period is easy to explain and is straightforwardly wrong for a month. Splitting the period at the moment of change is correct and makes the ownership dimension time-varying in every query that touches it. The right answer depends on how often the organisation actually changes, and at 450 teams it changes constantly.
Decision. Ownership changes take effect from the moment recorded, and a period is split across the owners in force during it. Statements show the split explicitly as separate lines rather than a blended total, so that a team that owned a resource for half a month can see that it did.
How it is realised on Azure. ownership_assignment carries valid_from and valid_to; the allocation join is a temporal join between the cost record's charge_period_start and the assignment's validity interval. Where a change is recorded retrospectively, the effective date is the recorded business date, not the entry date, and the entry date is retained for audit.
| Option |
Verdict |
Reasoning |
| Effective-dated, period split across owners |
Chosen |
Correct, and honest about a real handover |
| Retroactive to period start |
Rejected |
Simplest join and it rewrites history that has already been read |
| Deferred to the next period |
Rejected |
Easy to explain and wrong for a whole month, every time |
| Effective-dated with a same-day cut-off grace window |
considered |
Reduces line-splitting noise; adds a rule with no principled boundary |
What it buys
- Handovers are visible rather than smoothed away, which is what makes them negotiable
- Closed statements never move because of a change recorded after they were frozen
- The audit trail distinguishes when something became true from when it was recorded
What it costs
- Every ownership join is temporal, and temporal joins are the most expensive part of the allocation run
- Statements carry more lines, and a team that handed a resource over mid-month sees two partial entries
- A retrospectively recorded change inside the correction window triggers a restatement (ADR-04)
Choose differently when. In an organisation that reorganised once a year, retroactive application would be simpler and almost always right. At 450 teams with continuous change, almost always is not often enough.
Why it holds up over time. The decision follows from effective dating (ADR-05) rather than standing alone, so it is as durable as that model is.
Lesson. When a fact has a time at which it became true and a time at which it was recorded, store both. Systems that store only one end up unable to explain either.
ADR-07 · The unallocated remainder is a named line charged to an accountable owner
Status: Accepted · Shown on views: 09, 16, 20
Some spend has no owner. Does the platform spread it, pool it, or charge it to somebody?
Context. Three strategies exist. Proportional spread balances the books to one hundred per cent and makes the gap invisible, which is precisely why tag coverage never improves in organisations that use it: nobody experiences the cost of bad metadata. A central pool keeps every team's number clean and quietly funds the mess out of a budget nobody defends. Charging it to a named owner creates pressure to fix the metadata, and also creates a person who will dispute the line every month. The choice is really about whether the platform exists to balance the books or to change behaviour.
Decision. The unallocated remainder is computed and published as its own line, in currency, in every view at every level of aggregation, before any absorption strategy is applied. The configured default strategy charges it to a named accountable owner — normally the platform or cloud-governance function — rather than spreading it. Teams see their own contribution to the remainder in a ranked reconciliation surface.
How it is realised on Azure. The remainder handler runs as the last step of the allocation run and writes remainder rows tagged with the reason (untagged, orphaned, unmatched egress, unresolved scope). The coverage scorer aggregates them per team, account and service, and the owner-facing reconciliation surface ranks them by cost so the most valuable fix is the obvious one.
| Option |
Verdict |
Reasoning |
| Named accountable owner, remainder always visible |
Chosen |
Creates the pressure that actually improves coverage |
| Proportional spread across allocated spend |
Rejected |
Balances to 100%, hides the gap, and guarantees the gap persists |
| Central pool, unallocated |
considered |
The honest interim position while coverage is still poor; it funds the mess without naming it |
| Refuse to publish until fully allocated |
Rejected |
Publishes nothing for the first year and teaches nobody anything |
What it buys
- The cost of bad metadata is felt by somebody who can act on it
- Coverage becomes a measurable, ranked backlog rather than an aspiration
- The 2% target is enforceable because the number is on every screen
What it costs
- The named owner disputes the line, and that dispute recurs until coverage improves
- Teams' totals do not sum to the estate total without the remainder line, which reads as untidy
- It requires someone senior enough to be given an unpleasant number and expected to shrink it
Choose differently when. If tag coverage were consistently above 99%, the remainder would be noise and a proportional spread would be the pragmatic choice. Below that, spreading is how an organisation guarantees it never gets there.
Why it holds up over time. The incentive argument is independent of technology. As long as metadata is maintained by humans under deadline, visibility of the gap is what keeps it small.
Lesson. Do not make a measurement balance at the cost of making it useless. A visible gap is a backlog; a hidden gap is a permanent condition.
ADR-08 · Inferred attribution is marked, and excluded from chargeback
Status: Accepted · Shown on views: 09, 11, 16
The platform can often guess an owner from a naming convention or the identity that created a resource. Should it?
Context. Heuristic attribution is tempting because it lifts coverage quickly and the guesses are often right. It is also the fastest way to destroy trust: a team billed on the strength of a name pattern will find the one case where the pattern was wrong, and will then disbelieve every other number on the statement. But refusing to guess at all leaves a larger remainder than necessary and hides information the platform genuinely has.
Decision. The platform may infer an owner from a heuristic, but every inferred assignment is marked as inferred with a stated confidence, is shown as such in every view, and is excluded from chargeback postings. Inferred attribution counts towards showback coverage and is capped: no more than 2% of spend at close may be inferred.
How it is realised on Azure. ownership_assignment.confidence carries the inference strength and rule_fired names the heuristic. The GL posting builder filters on confidence = asserted. The dashboard renders inferred lines with an explicit marker rather than silently blending them into the team's total.
| Option |
Verdict |
Reasoning |
| Infer, mark, exclude from chargeback |
Chosen |
Uses the information without betting money on it |
| Never infer |
considered |
Purest, and it throws away a signal that genuinely narrows the remainder |
| Infer silently and treat as asserted |
Rejected |
Buys coverage this quarter and credibility for ever |
What it buys
- Coverage improves without the platform ever billing a guess
- The marker itself is a prompt to fix the underlying tag
- Showback and chargeback can legitimately report different completeness figures, with the reason visible
What it costs
- Two coverage numbers must be explained: attributed, and attributed with confidence
- The cap needs enforcement, or inference quietly becomes the primary mechanism
- Heuristics need maintenance as naming conventions drift
Choose differently when. If chargeback were never going to be enabled, the distinction would carry no weight and inference could be treated as ordinary attribution. The requirement's explicit path to chargeback is what makes the separation load-bearing.
Why it holds up over time. The principle — do not bill a guess, but do not discard it either — is unaffected by how good the guessing gets. Better inference raises coverage; it does not change what may move money.
Lesson. Mark estimates as estimates at the point they are created, not at the point somebody asks. A confidence field costs nothing and is impossible to retrofit honestly.
Shared cost and commitments
Splitting what nobody incurred alone, and deciding where a discount lands.
Status: Accepted · Shown on views: 14, 10, 16
A Kubernetes cluster costs what its nodes cost. Forty namespaces run on it. How is the bill split, and who pays for the headroom nobody used?
Context. Measured usage is fair to the bursty and rewards nobody for right-sizing: a team that reserves four cores and burns one pays for one. Declared requests reward right-sizing and make a team's bill predictable, but leave the reserved-but-unused capacity homeless, and that gap is frequently a third of the cluster. A blend is defensible and much harder to explain, and an apportionment nobody can follow is one nobody accepts. Underneath the arithmetic is a governance question: who is accountable for the cluster having more capacity than its tenants asked for?
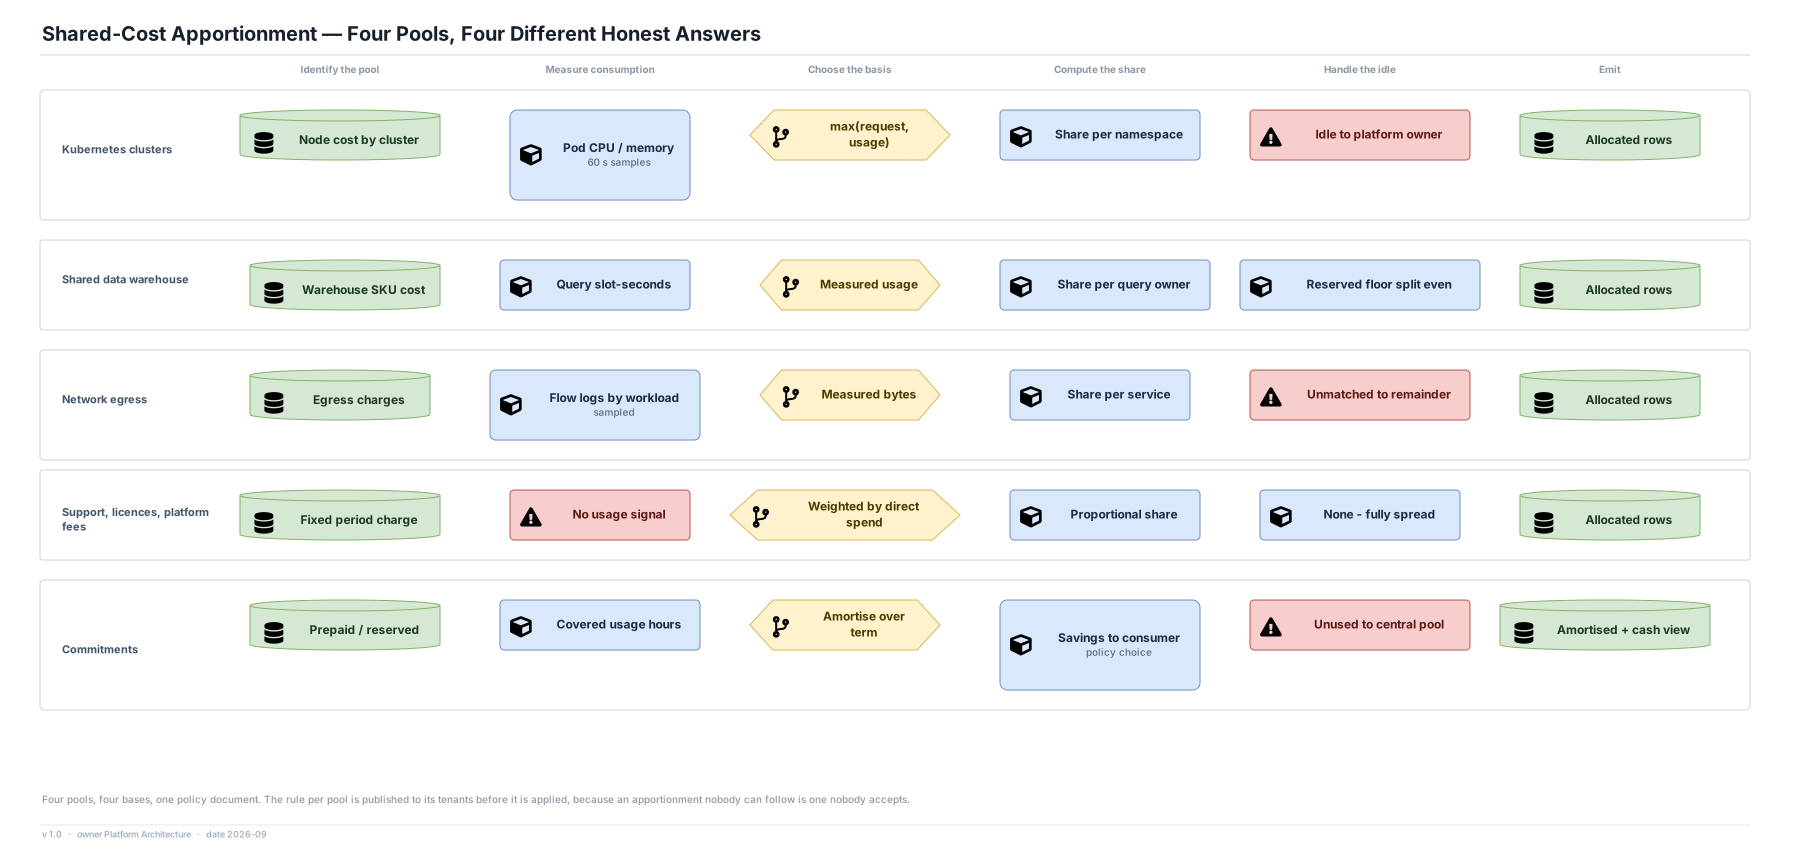
Decision. Shared compute is apportioned on max(request, usage) per workload per interval, so a team pays for what it reserved or what it consumed, whichever is larger. The remaining cost — capacity that was neither requested nor used — is attributed to the platform owner who sized the cluster, as a named idle line rather than spread across tenants.
How it is realised on Azure. The usage collector streams per-pod CPU and memory requests and usage at 60-second resolution through Event Hubs, downsampled to five minutes on ingest. The apportioner joins those intervals to node cost from the conformed cost record for the same cluster and window, computes per-namespace shares, and emits the residual as an idle row owned by the platform team. A telemetry gap applies the last known-good ratio and marks the affected allocations degraded.
| Option |
Verdict |
Reasoning |
| max(request, usage), idle to the platform owner |
Chosen |
Rewards right-sizing, and puts headroom on the only party that can change it |
| Measured usage only |
Rejected |
Under-charges reserved capacity and leaves a large unallocated residual |
| Declared requests only |
considered |
Most predictable for tenants; ignores a team that consistently overruns its request |
| Even split across namespaces |
Rejected |
Trivial to explain and actively rewards the heaviest tenant |
| Idle spread proportionally across tenants |
Rejected |
Balances the cluster and removes the platform owner's incentive to size it correctly |
What it buys
- Right-sizing has a visible financial reward for the team that does it
- Cluster headroom becomes a line somebody owns and is asked about
- The rule is explainable in one sentence, which is what makes it survive a negotiation
What it costs
- Requires a second, high-volume telemetry stream that the provider bill does not supply
- The platform owner receives an unpleasant number every month and will contest it
- A telemetry gap degrades allocations, which excludes them from chargeback
Choose differently when. If clusters were provisioned exactly to aggregate requests with no headroom, idle would be negligible and pure request-based apportionment would be right. If tenants could not set requests at all, usage-only would be the only honest basis.
Why it holds up over time. The specific basis may be renegotiated; the structural claim — that the residual belongs to whoever chose the capacity — holds for any shared resource, including warehouses, queues and networks.
Lesson. Apportion to the party who can act, not to the party who is easiest to charge. An allocation that nobody can respond to is a tax, not a signal.
ADR-10 · Commitment savings go to the consumer, with both amortised and cash views published
Status: Accepted · Shown on views: 14, 11, 09
A central team buys three years of reserved capacity. Whose bill gets the discount?
Context. Crediting the central buyer means teams see on-demand rates, over-estimate their own cost, and make architecture decisions against prices the organisation does not actually pay. Crediting the consuming workload produces a number that swings on a coverage allocation the team did not control and cannot predict. Publishing a fixed blended rate is stable and predictable and severs the link between a team's choices and its bill. Finance also needs the cash view for planning, which is a different shape from the view an engineer needs.
Decision. Commitment savings are attributed to the consuming workload at amortised rates, so teams see the price the organisation actually pays. Both an amortised view and a cash view are published for every period from the same ledger. Unused commitment coverage is held in a named central pool owned by the buyer, never spread across consumers.
How it is realised on Azure. The amortiser spreads prepaid and reserved purchases across the periods they cover and joins coverage to the underlying usage hours from the conformed cost record. Statements carry both amortised and cash totals as separate lines; the GL posting uses the amortised figure, since that is what the accounting policy recognises. Unused coverage is emitted as a central-pool row.
| Option |
Verdict |
Reasoning |
| Savings to the consumer at amortised rates |
Chosen |
Teams see real prices, which is what makes their architecture decisions correct |
| Savings to the central buyer |
Rejected |
Teams optimise against list prices the organisation never pays |
| Fixed published blended rate |
considered |
Most predictable for a team; hides which workloads are actually covered |
| Cash view only |
Rejected |
A three-year prepayment lands entirely on one month and one team |
What it buys
- Architecture decisions are made against prices the organisation actually pays
- Finance gets its cash view without a separate pipeline or a separate truth
- Unused coverage is visible to the person who bought it, which is how buying improves
What it costs
- A team's unit cost moves when central coverage is reallocated, through no action of its own
- Two totals per period must be explained and never confused
- Amortisation schedules add state that must survive a commitment being exchanged or refunded
Choose differently when. If commitments were bought by the consuming teams themselves rather than centrally, the attribution question largely disappears. If coverage churned so often that team unit costs became unpredictable, a published blended rate would be the more useful lie.
Why it holds up over time. Commercial mechanisms will keep changing name — reserved instances, savings plans, committed use, flexible commitments — but the structural question of where a centrally purchased discount lands does not.
Lesson. Show people the price they actually pay, even when it is harder to compute. Optimising against a price nobody pays produces decisions nobody wants.
Publication and disputes
Freezing, restating, disputing and posting — the lifecycle of a number people act on.
ADR-11 · Reconciliation to the provider invoice gates publication
Status: Accepted · Shown on views: 12, 19, 05
The ingested total does not match the provider's invoice. Does the platform publish anyway and flag it?
Context. A variance means one of several things: an export is incomplete, a charge category was dropped in conformance, currency conversion is wrong, or the provider issued something the pipeline does not understand. None of these is knowable in advance, and all of them make the per-team numbers wrong in ways that are not visible per team. Publishing with a warning banner feels cooperative and, in practice, means the wrong numbers are read, quoted and acted on, and the banner is ignored by the second month.
Decision. A period whose ingested total differs from the provider's invoice or billing summary by more than 0.1% or $500, whichever is larger, does not publish statements for that provider and period. Showback may be late; it may not be quietly short. The variance is escalated with the affected provider, period and magnitude named.
How it is realised on Azure. The invoice reconciler runs after conformance and writes a reconciliation result per provider and period. The statement publisher reads it as a precondition. A blocked provider publishes the period as visibly incomplete, naming the provider, rather than publishing a total that omits it.
| Option |
Verdict |
Reasoning |
| Block publication on variance |
Chosen |
Being late is recoverable; being quietly wrong is not |
| Publish with a warning banner |
Rejected |
Banners are read once and ignored thereafter |
| Publish and post an adjusting line for the variance |
considered |
Reasonable when the variance is understood; useless when it is not, and it is not by definition |
| Reconcile asynchronously after publication |
Rejected |
Guarantees the wrong number gets quoted before the right one exists |
What it buys
- A published statement has a provable relationship to what the provider actually charged
- Variance investigation happens before the number is read, not after it is disputed
- The reconciliation result is itself a retained artefact on the statement
What it costs
- A single misbehaving provider can delay a whole close
- The tolerance is a judgement call and will be argued over
- It puts an operational dependency on a provider API that is outside the platform's control
Choose differently when. If per-provider statements were acceptable to finance, a variance could block one provider without delaying the rest of the close — which is in fact what the design does at provider granularity. A single blended statement would make the blocking cost much higher.
Why it holds up over time. For any system whose output is a number people act on, correctness gates beat correctness metrics. That holds regardless of what the pipeline is built from.
Lesson. Decide in advance whether being late or being wrong is worse, and encode the answer as a gate. Systems that leave it to a dashboard have chosen 'wrong' without saying so.
ADR-12 · One pipeline, two labels: the current period is an estimate, never a statement
Status: Accepted · Shown on views: 12, 16, 04
Engineers need today's number; finance needs a number that does not move. Is that one system or two?
Context. The current period is provably incomplete: usage is still arriving, amounts are still being restated, and commitment coverage has not been applied. Serving it from a separate fast path gives engineers a daily number and guarantees it will disagree with the monthly statement that follows, at which point both are disbelieved. Serving it from the same path raises the risk that a reader cannot tell which kind of number is on screen — which is the same failure by a different route.
Decision. Current-period figures are produced by the same pipeline and the same allocation function as closed periods, from the partial billing snapshot available at the time, and are labelled as estimates everywhere they appear. An estimate and a frozen figure are never combined into one number, never appear in the same chart series without distinction, and the estimate carries the timestamp of the snapshot it came from.
How it is realised on Azure. The daily incremental run writes allocated facts tagged with period_state = open. The serving layer renders open-period figures with an explicit estimate marker and the snapshot time; the statement viewer refuses to render an open period at all. Export and API responses carry period_state so downstream tooling cannot lose the distinction.
| Option |
Verdict |
Reasoning |
| One pipeline, explicit labels |
Chosen |
One set of bugs, and the distinction is carried in the data rather than in the reader's memory |
| Separate fast estimate path |
Rejected |
Two truths that will disagree, and the disagreement destroys both |
| Closed periods only, no current view |
Rejected |
Makes the platform useless for the journey that carries its value |
| Current view from raw provider totals, unallocated |
considered |
Cheap and fast, and it cannot answer 'is it my team' — which is the whole question |
What it buys
- The daily number and the monthly number are produced the same way, so they converge rather than diverge
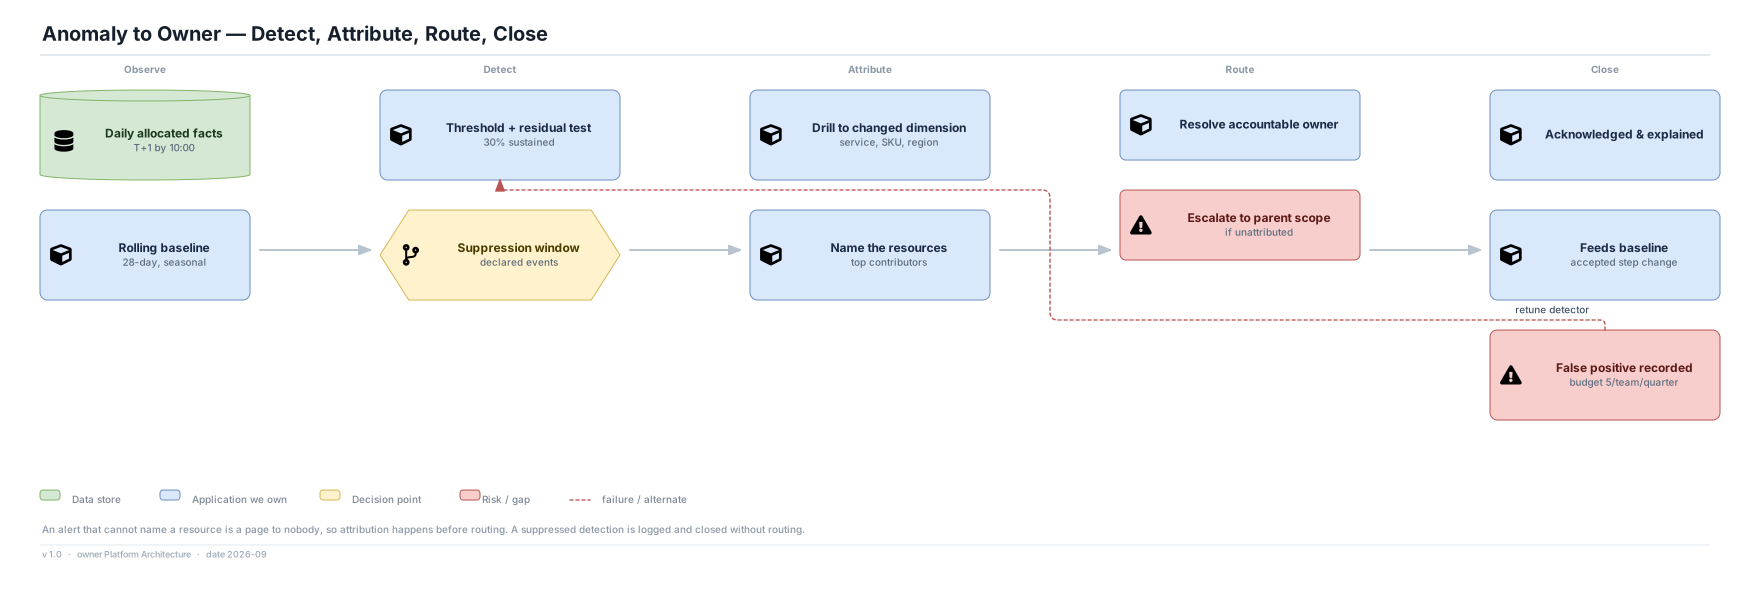
- Anomaly detection runs on the same allocated facts, so an alert already has an owner
- There is only one allocation implementation to test, tune and trust
What it costs
- Every surface must carry and render the estimate distinction, including exports and API responses
- Daily incremental runs add compute that a month-end-only design would not need
- An estimate that moves materially before close still generates questions, even when correctly labelled
Choose differently when. If the organisation only ever consumed monthly figures, the current-period path could be dropped entirely and the design would simplify considerably. The anomaly-detection requirement alone makes that untenable.
Why it holds up over time. The tension between fresh and final is permanent in any system over late-arriving data. Solving it with labels rather than with a second pipeline is what keeps the two from drifting apart over years.
Lesson. When two audiences want different properties from the same number, change the label and the contract, not the pipeline. Two pipelines become two truths faster than anyone expects.
ADR-13 · Disputes never block publication, and close by correction or reasoned rejection
Status: Accepted · Shown on views: 15, 05, 20
A team says their line is wrong. What happens to the close?
Context. Allowing a dispute to hold publication gives any team a veto over the whole organisation's close, and at 450 teams that veto will be exercised. Resolving disputes by editing the published figure destroys the reproducibility the whole architecture is built on. And closing a dispute by simply declining it, with no recorded reason, guarantees the same dispute returns next month and the month after.
Decision. A dispute is recorded against a specific statement version and never blocks publication. It closes in exactly one of two ways: a correction, which is a restatement producing a superseding version (ADR-04), or a reasoned rejection, which records why the figure stands. Both outcomes are retained with the statement for seven years.
How it is realised on Azure. The dispute ledger in Azure SQL holds dispute rows keyed to statement_id and version, with state, raiser, resolution and reason. The statement service exposes the dispute alongside the line it concerns, so a reader of v1 sees that it was contested and how that ended.
| Option |
Verdict |
Reasoning |
| Non-blocking, closed by correction or reasoned rejection |
Chosen |
The close completes and the disagreement is still on the record |
| Dispute blocks publication of the affected statement |
Rejected |
Hands every team a veto over the organisation's close |
| Resolve by editing the figure in place |
Rejected |
Destroys reproducibility to save a version row |
| Track disputes in the ticketing system instead |
considered |
Less to build; the dispute then is not attached to the version it concerns and is lost to the audit trail |
What it buys
- The close is predictable regardless of how many disputes are open
- Rejections are recorded, so the same argument does not recur every period
- Dispute causes are classifiable, which is what feeds the policy and coverage backlog
What it costs
- A team may act on a figure that is later superseded
- Someone must own reasoned rejection, which is an unpopular job
- Dispute volume becomes an operational load that scales with the number of teams
Choose differently when. In a small organisation where a dispute is rare, blocking publication until it is resolved would be reasonable and simpler. At 450 teams it is a guaranteed deadlock.
Why it holds up over time. Disagreement about an allocated number is structural, not transitional: the rules encode a negotiation. A workflow that assumes disputes are temporary will be rebuilt within two years.
Lesson. Record the rejections as carefully as the corrections. An organisation's memory of why a decision stands is what stops it being relitigated every cycle.
Scale, storage and cost
What is kept, for how long, at what grain, and what the platform is allowed to cost.
ADR-14 · Full grain is kept in the raw zone; allocated facts are kept 13 months and are disposable
Status: Accepted · Shown on views: 10, 17, 09
At 1.2 billion cost records a month growing 40% a year, what is actually retained, at what grain, and for how long?
Context. Full-grain hourly resource-level detail is the only thing that answers 'which resource, on which day' during a dispute, and it is simultaneously the dominant cost and the dominant scale problem in the platform. Rolling up at ingest makes the platform cheap and makes some disputes unanswerable. The useful observation is that the raw zone already holds complete, immutable, full-grain detail on cheap tiered storage, which means the expensive query-optimised store does not have to be the archive of record.
Decision. Raw exports and conformed cost facts are retained 37 months, tiering to archive beyond 13. Allocated facts are retained 13 months at full grain and are explicitly derived and disposable, rebuildable within 24 hours from the raw zone plus the pinned ownership and policy versions. Published statements, disputes and audit are retained seven years. Container usage telemetry is kept 90 days at native resolution and 13 months downsampled hourly.
How it is realised on Azure. ADLS Gen2 lifecycle rules move raw partitions to cool and then archive; Azure Data Explorer retention drops allocated partitions past 13 months; the statement and audit stores in Azure SQL are geo-replicated and never pruned inside the retention window. A historical query beyond 13 months is served by re-running allocation for that period rather than by keeping the rows hot.
| Option |
Verdict |
Reasoning |
| Full grain in the raw zone, 13 months hot for allocated facts |
Chosen |
The cheap immutable store is the archive; the expensive store holds only what is queried |
| 37 months of allocated facts hot |
Rejected |
Triples the largest cost line to serve queries that are almost never made |
| Roll up at ingest beyond 90 days |
Rejected |
Makes historical disputes unanswerable and cannot be undone |
| Keep everything hot and revisit later |
Rejected |
A measurement platform that cannot meet its own cost target has an obvious credibility problem |
What it buys
- The platform's own cost stays inside the 0.5% target it publishes about itself
- A retention decision remains reversible, because nothing irreplaceable lives in the store being pruned
- Historical questions are answerable, just not instantly
What it costs
- A query older than 13 months takes a re-run rather than a read, measured in tens of minutes
- The rebuild path must be exercised regularly or it will not work when needed
- Two retention windows must be explained to auditors and to teams
Choose differently when. If historical full-grain queries turned out to be frequent rather than rare, or if storage costs fell far enough that the distinction stopped mattering, keeping the full 37 months hot would be simpler. Instrumenting how often deep history is actually retrieved is the way to find out.
Why it holds up over time. The structural insight — that the immutable source can serve as the archive, freeing the query store to hold only what is queried — survives any change in storage pricing. Only the boundary moves.
Lesson. Retention is not one decision. Separate what must be kept from what must be fast, and the expensive store gets much smaller.
ADR-15 · Serving and batch are separate tiers, and batch runs on interruptible capacity
Status: Accepted · Shown on views: 07, 17, 12
Allocation runs are large, bursty and not latency-critical. Dashboards are small, constant and latency-critical. Do they share infrastructure?
Context. Sharing one elastic pool is operationally simpler and means a month-end allocation run competes with an engineering lead trying to open a dashboard on the same morning — which is exactly the morning the dashboard matters most. Separating them costs a second deployment and a second set of scaling rules. Because no allocation run is latency-critical inside its window, the batch tier can also take interruptible capacity, which is the single largest saving available to a platform that must justify its own cost.
Decision. Serving and batch are separate tiers with separate scaling. The serving tier runs zone-redundant and autoscaled on demand; the batch tier runs on spot capacity with per-partition checkpointing, so an interruption re-runs a partition rather than a period. No interactive request ever waits on an allocation run.
How it is realised on Azure. AKS with separate node pools and workload scheduling constraints for serving; Databricks job clusters on spot instances with on-demand fallback for the driver. Allocation partitions are keyed by provider and day, checkpointed on completion, so a lost worker resumes from the last committed partition.
| Option |
Verdict |
Reasoning |
| Separate tiers, spot batch |
Chosen |
Protects the latency path and takes the largest available saving |
| One shared elastic pool |
Rejected |
Simplest, and it degrades the dashboard exactly when it is most read |
| Separate tiers, on-demand batch |
considered |
Removes interruption handling; pays a large premium for a workload with a long window |
| Serverless query engine for both |
considered |
Attractive operationally; costs of a full-grain monthly re-run become hard to bound |
What it buys
- Dashboard latency is unaffected by close-week batch load
- Batch compute cost falls substantially, which is what makes the 0.5% target reachable
- Interruption handling forces partition-level idempotency, which the re-run model needs anyway
What it costs
- Two deployment topologies, two sets of scaling rules, two on-call surfaces
- Spot reclamation lengthens the tail of a run, so the 45-minute p95 carries a 90-minute ceiling
- Checkpointing adds write amplification to every partition
Choose differently when. If allocation became latency-critical — a real-time showback requirement, say — the batch tier would need on-demand capacity and the whole cost argument would change. Nothing in this requirement asks for that.
Why it holds up over time. The separation of a latency-critical read path from a throughput-oriented compute path is one of the oldest stable patterns there is, and nothing about cloud billing is likely to dissolve it.
Lesson. Interruptibility is cheap when the work is already idempotent. Designing for a pure, re-runnable function bought the spot discount for free.
Access and confidentiality
Who may see whose bill, and why estate-wide cost data is sensitive.
ADR-16 · Scope is resolved server-side from the org tree; out-of-scope reads are answered at aggregate grain
Status: Accepted · Shown on views: 21, 22, 10
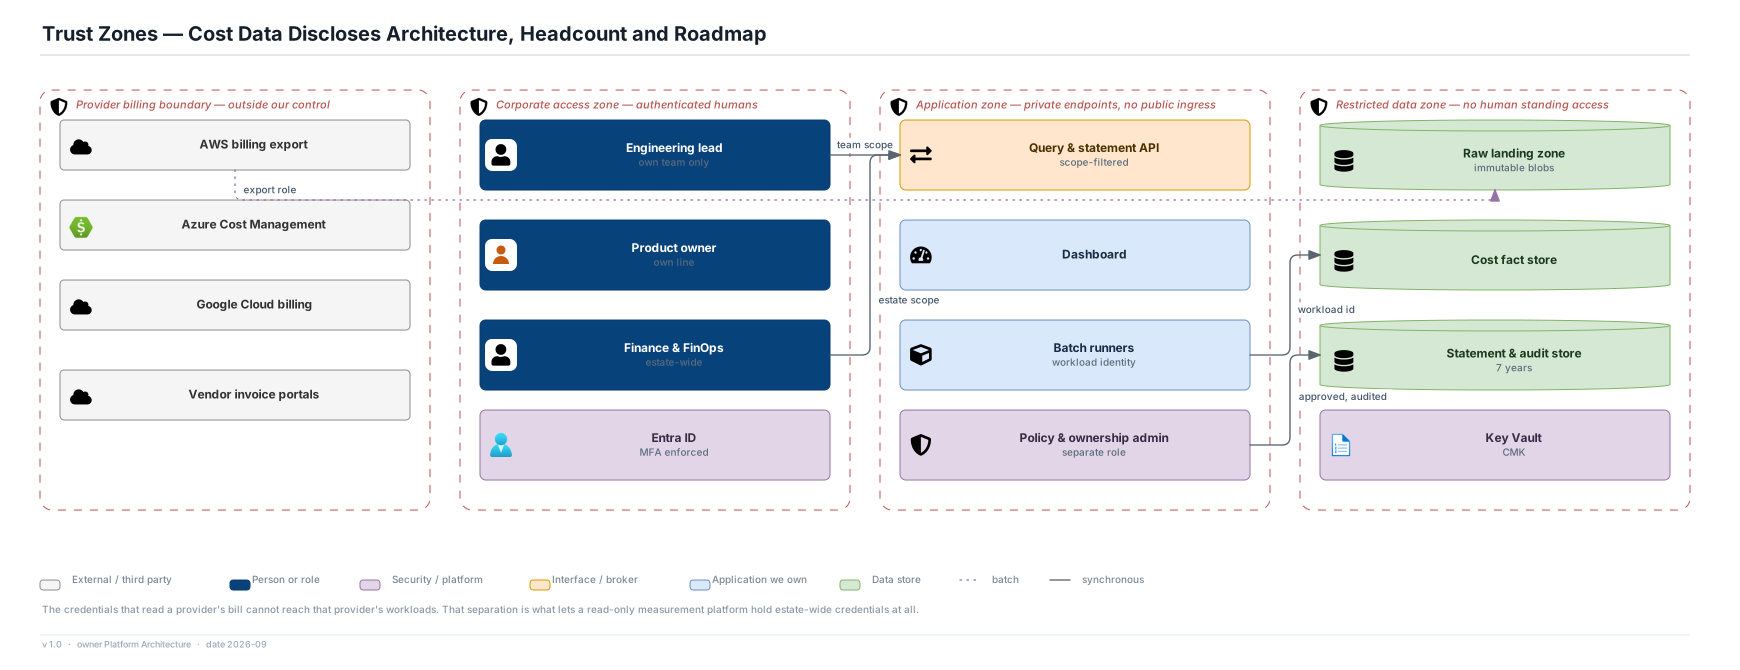
Cost data discloses architecture, headcount, vendor terms and roadmap timing. Who may see whose, and what happens when someone asks for more?
Context. Estate-wide cost detail at resource grain is one of the more revealing datasets an organisation holds: it exposes which products are growing, which teams are large, what was negotiated with which vendor, and when something new started being built. At the same time, a platform that refuses every cross-team question drives people to exported spreadsheets, which is strictly worse for confidentiality than answering carefully. Scope also has to be temporal, or a reorganisation retroactively opens or closes access to closed periods.
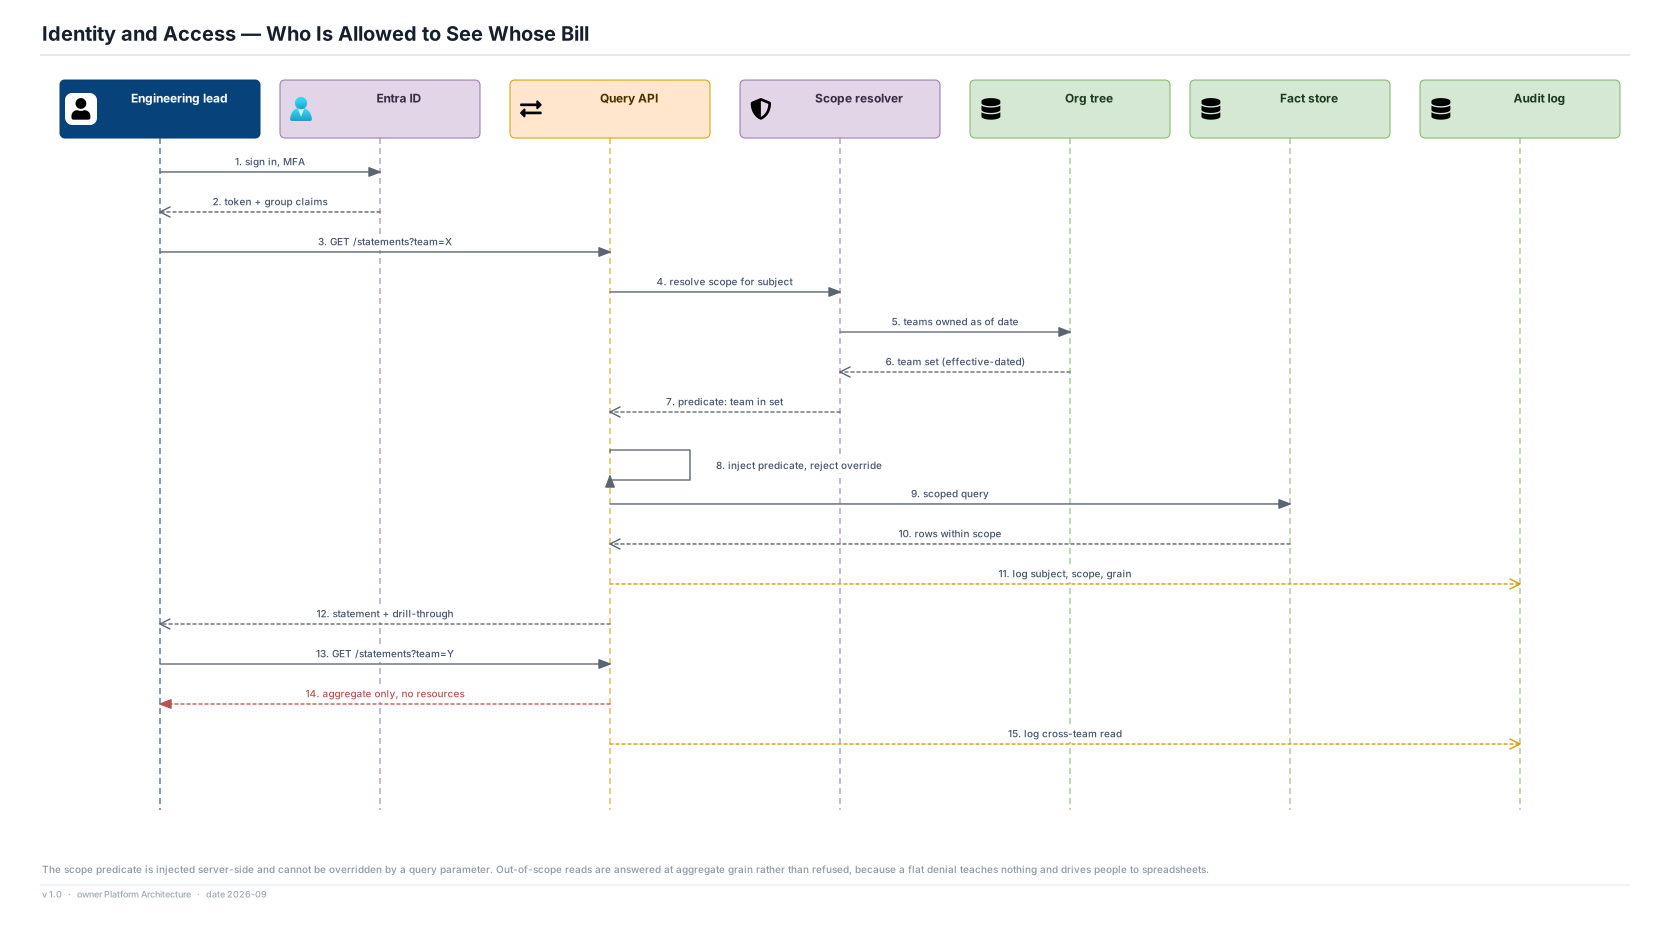
Decision. Read scope is resolved server-side from the effective-dated org tree as of the period being read, and injected into every query as a predicate that a request parameter cannot widen. A team lead sees their team's detail, a product owner their line, finance and FinOps the estate. An out-of-scope read is answered at aggregate grain — totals without resources — rather than refused, and every cross-team read is logged. Write access to ownership and to allocation policy is a separate role from read access.
How it is realised on Azure. Entra ID issues group claims naming the person; the scope resolver derives the team set from the org tree rather than from the claim, so a group membership cannot itself grant cost visibility. The query API injects the predicate before execution and rejects any attempt to override it. Audit rows are written for policy changes, ownership changes, publication, restatement, dispute actions, bulk exports and cross-team reads, retained seven years.
| Option |
Verdict |
Reasoning |
| Server-side scope from the org tree, aggregate answer out of scope |
Chosen |
Least privilege without pushing people into spreadsheets |
| Hard denial outside scope |
Rejected |
Teaches nothing and creates a strong incentive to exfiltrate |
| Scope from IdP group claims |
Rejected |
Makes cost visibility a side effect of group membership nobody is reviewing for that purpose |
| Open estate-wide read for all engineers |
considered |
Excellent for a culture of ownership; unacceptable for vendor terms and pre-announcement workloads |
What it buys
- Confidential detail stays with the people accountable for it
- Benchmark questions are answerable without disclosing another team's architecture
- Scope is correct for closed periods even after a reorganisation
What it costs
- Every query carries a temporal scope resolution, which adds latency and complexity
- The aggregate-answer rule needs care so that repeated narrow queries cannot reconstruct detail
- A separate admin role for ownership and policy means more roles to govern
Choose differently when. In an organisation with a genuinely open cost culture and no vendor-confidentiality constraints, estate-wide read would be simpler and better for behaviour. Vendor terms and unannounced products are what remove that option here.
Why it holds up over time. What cost data reveals does not change with technology. As long as spend correlates with headcount, product investment and vendor negotiation, it will be commercially sensitive.
Lesson. Answer the question at a grain you can safely disclose, rather than refusing it. A refusal does not remove the need; it removes your visibility into how it gets met.
Every package used, in one table
The terms below are used precisely in this package. Several of them are used loosely in the wider FinOps literature, and the difference matters when reading the decision records.
| Package |
What it is |
What it does here |
Considered instead |
| Showback |
Reporting allocated cost to an accountable owner for information, without moving budget. |
The platform's initial operating mode; the ledger must be trusted here before it is allowed to bill. |
Chargeback, where the same figure moves real budget through the general ledger. |
| Allocation |
The attribution of a cost record to an accountable owner, including any apportioned share of a shared resource. |
The pure function at the centre of the architecture, over three pinned inputs. |
Tagging, which is one of several inputs to allocation rather than a synonym for it. |
| Apportionment |
Splitting the cost of a resource nobody incurred alone across the parties that consumed it, by a declared basis. |
Applies to clusters, warehouses, egress and fixed fees; the basis is per pool and versioned in policy. |
Direct attribution, where a single owner is identifiable without a split. |
| Amortisation |
Spreading a commitment purchase across the periods it covers, rather than the period it was paid in. |
Produces the amortised view engineers should optimise against; the cash view is published alongside. |
Cash view, which recognises the payment when it was made. |
| Restatement |
A re-issued provider export changing amounts for a period, and the superseding statement version that follows. |
Handled as the normal path run a second time, not as an exception workflow. |
Correction in place, which this architecture does not permit. |
| Statement |
A frozen, versioned artefact per team and period, carrying the three input versions that produced it. |
The unit of publication and the thing a dispute is raised against. |
The estimated current-period view, which is never a statement. |
| Remainder |
Spend with no resolved accountable owner at the point of allocation. |
Published as its own line at every level before any absorption strategy is applied; target ≤ 2%. |
Proportional spread, which balances to 100% and hides the same quantity. |
| FOCUS |
The FinOps Foundation's open specification for a common cloud billing record. |
The conformed internal cost record, with provider-native fields retained alongside. |
A bespoke internal billing schema. |
| Effective dating |
Storing a fact with the interval during which it was true, separately from when it was recorded. |
Applies to ownership, the org tree and policy, and is what lets a snapshot be taken as of any instant. |
Current-state modelling, where a reorganisation rewrites the meaning of closed periods. |
| Run digest |
A hash over the three pinned input ids plus the engine version. |
Makes an allocation run idempotent and proves that two results came from identical inputs. |
A run timestamp, which proves only when something happened. |
| Unit economics |
Allocated cost divided by a team-reported business driver, at the driver's own grain. |
Separates volume change from efficiency change, which a raw cost trend cannot. |
Absolute spend trend, which cannot distinguish growth from waste. |
| Idle |
Shared capacity neither requested nor consumed by any tenant in an interval. |
Attributed to the platform owner who sized the resource, as a named line. |
Overhead spread, which averages it across tenants who cannot act on it. |