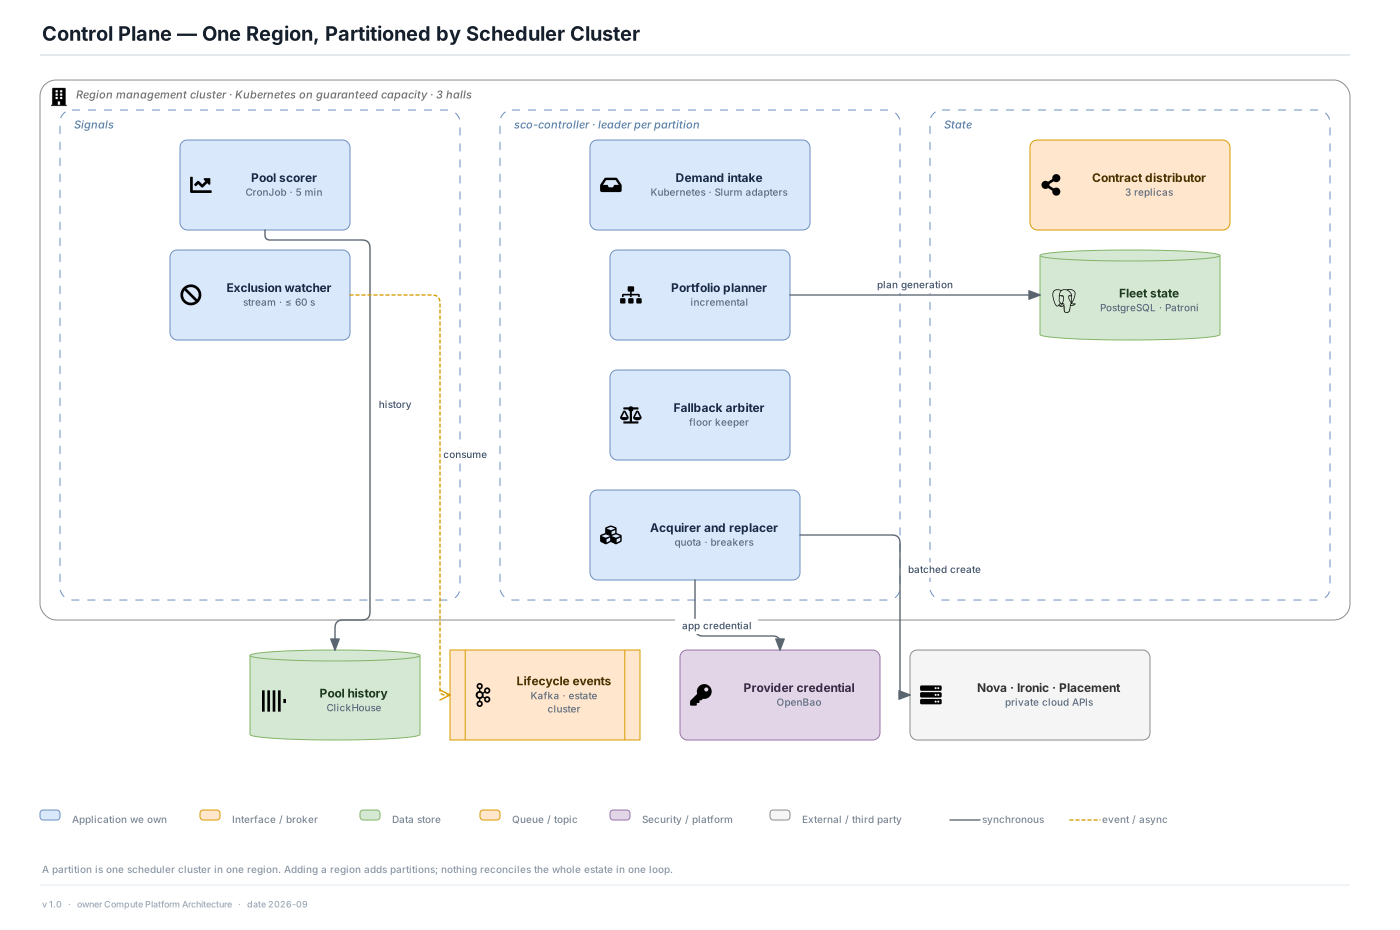
Spot Capacity Orchestrator · View 09 of 32 · 3 · Structure
Decisions
- One controller binary, sharded by partition, with a leader per partition elected through Kubernetes leases. A partition is one scheduler cluster in one region, so a bug or a stuck loop affects one cluster's capacity, and adding a region never grows a loop.
- Level-triggered reconciliation rather than a workflow engine. The provider's view of what exists is authoritative, so each cycle compares desired plan with observed instances and acts on the difference; there is no in-flight workflow state to lose or replay.
- Scoring runs every 5 minutes as a batch job; exclusion runs continuously on the event stream. Two clocks, because a pool going bad cannot wait for the next ranking.
Numbers
- Placement decision ≤ 10 s p99. Exclusion within 60 s of the threshold. Control plane ≥ 99.9% monthly. State RPO ≤ 30 s (synchronous replica makes it effectively 0), RTO ≤ 10 min.
Risks
- The provider credential is the most powerful secret here. It is fetched from OpenBao for an hour at a time and can act only in the orchestrator's own OpenStack projects (view 30).