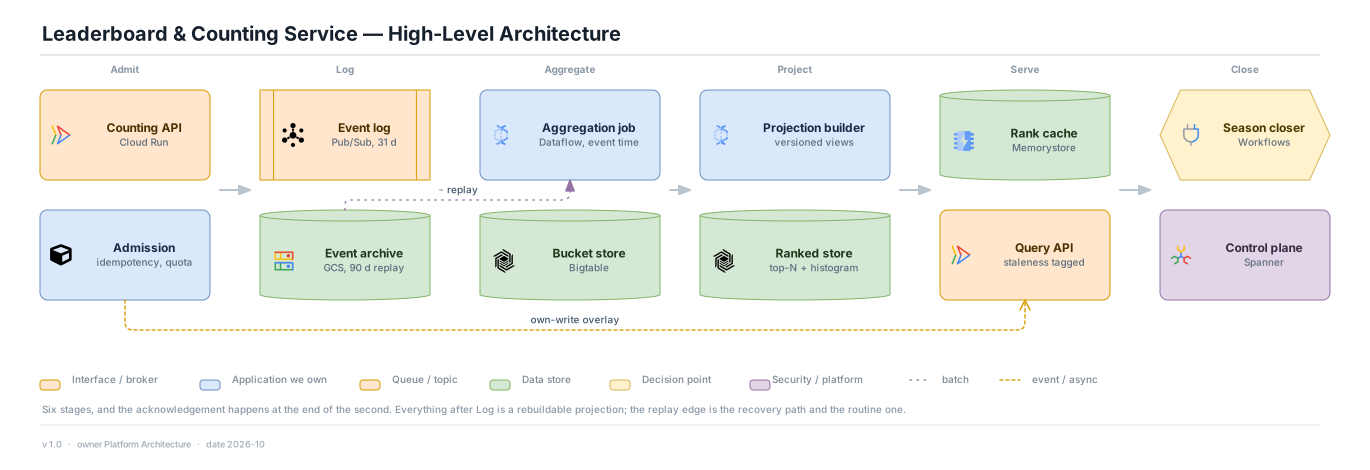
Leaderboard & Counting Service · View 02 of 21 · Context and scope
Decisions
- The write is acknowledged when the event is durable in the log, not when it has been counted. Everything after Log is allowed to be behind.
- Aggregate, Project and Serve are three separate stages because they fail separately: a stalled pipeline widens staleness, a bad projection build is rolled back by version, a lost cache is a latency event.
- Close is a stage, not a scheduled script. A season that can be silently rewritten was never a result.
Why the replay edge is drawn
- Replay from the archive is the recovery path and the routine one — exercised on a schedule, not discovered during an incident.
- Because it exists, a corrupt partition, a wrong tie-break rule and a late-discovered fraud campaign have the same remedy: rebuild.
Risks
- Staleness is now a product property. A screen that implies live truth will be wrong, so every response carries its as-of and the product must show it.
- The log must be retained long enough and replay fast enough to rebuild the largest leaderboard inside the RTO. That is a throughput commitment, not a backup.