CI/CD Platform · View 04 of 22 · People and journeys
The finding
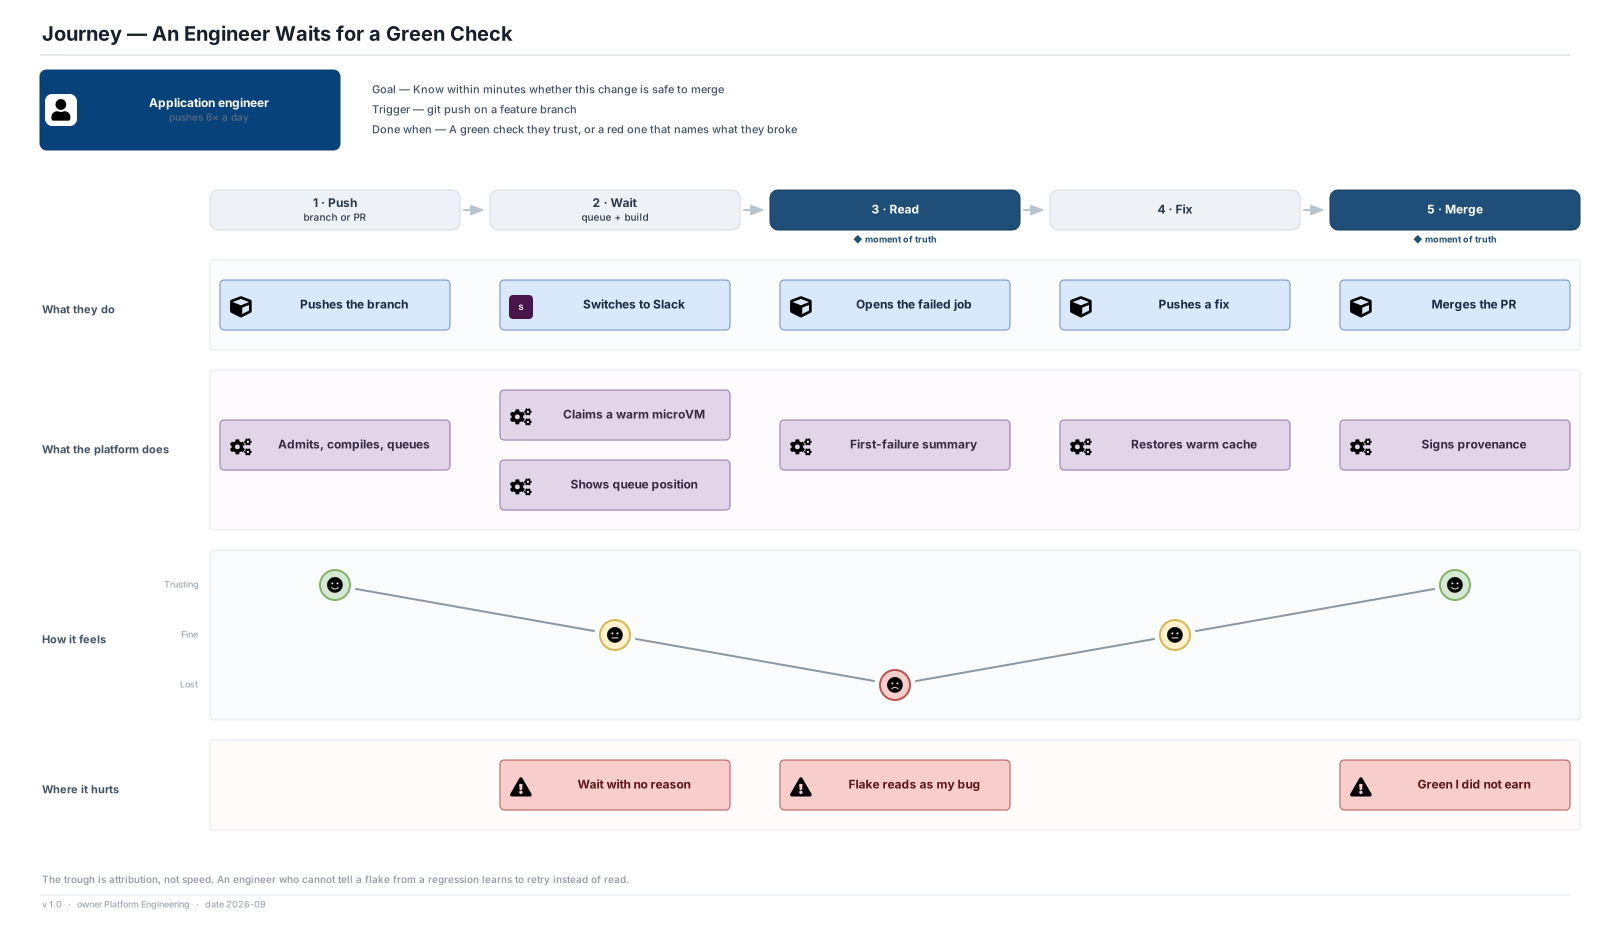
- The trough is Read, not Wait. Engineers tolerate a two-minute queue; they do not tolerate a red check they cannot attribute.
- A flake that reads as the engineer's own bug trains them to retry rather than read, and after that every genuine failure is retried too.
- That is why platform failure and user failure are separate outcomes in the requirement, and why flake rate is measured even though it is not bounded.
What the architecture owes this journey
- Queue position and estimated wait, so an unexplained wait stops being indistinguishable from an outage.
- A first-failure summary, so the failing step and the log region around the first error arrive without opening the full log.
- Retry only on platform failure, with the cause recorded, so a green check is never the product of a silent re-run.
Assumptions
- Six pushes per engineer per day; queued to first step p95 ≤ 25 s inside entitlement; median job 3m 10s.