Search Indexing Service  ·  View 16 of 21  ·  Operations

Deployment Architecture

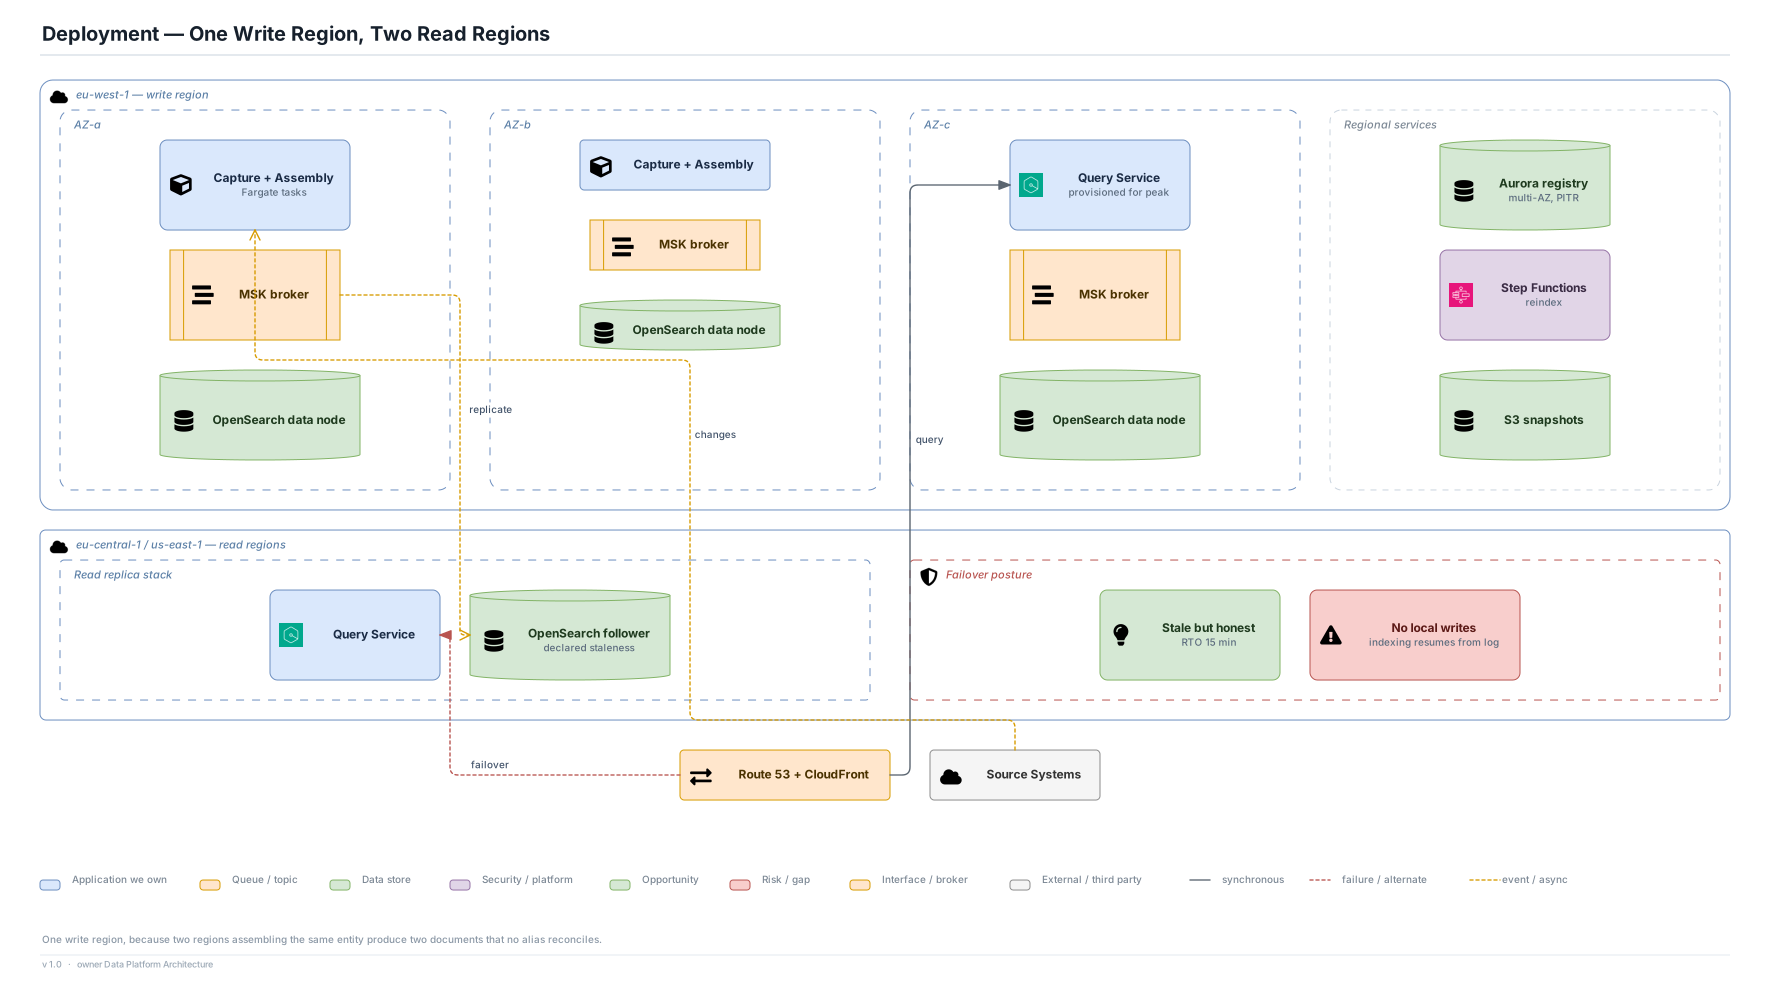
One write region across three zones, and read regions that are honest about being behind.

Editable source SVG draw.io All views
eu-west-1 — write region AZ-a Capture + Assembly Fargate tasks MSK broker OpenSearch data node AZ-b Capture + Assembly MSK broker OpenSearch data node AZ-c Query Service provisioned for peak MSK broker OpenSearch data node Regional services Aurora registry multi-AZ, PITR Step Functions reindex S3 snapshots eu-central-1 / us-east-1 — read regions Read replica stack Query Service OpenSearch follower declared staleness Failover posture Stale but honest RTO 15 min No local writes indexing resumes from log Route 53 + CloudFront Source Systems query failover changes replicate Deployment — One Write Region, Two Read Regions Application we own Queue / topic Data store Security / platform Opportunity Risk / gap Interface / broker External / third party synchronous failure / alternate event / async One write region, because two regions assembling the same entity produce two documents that no alias reconciles. v 1.0 · owner Data Platform Architecture

Decisions

  • One write region. Two regions assembling the same entity produce two documents that no alias reconciles, and nothing in this design makes that reconciliation cheap.
  • Read regions serve a follower index with a declared staleness and take no local writes; on failover, indexing resumes from the log rather than from the follower.
  • The query tier is provisioned for the dinner-hour peak rather than scaled into it, because autoscaling latency is visible inside a 250 ms p99.
  • Reindex orchestration is regional and stateful in the registry, so an interrupted rebuild survives a task replacement.

Assumptions

  • Three availability zones, 3× MSK brokers, OpenSearch data nodes per zone with two replicas; RTO 15 min to serve from a read region.
  • Cross-region replication lag is a published number on the response, not an internal metric.